Author: Elsa Ji

  • 4 Free GEO Score Checkers: What Each One Actually Measures

    4 Free GEO Score Checkers: What Each One Actually Measures

    Most SEOs searching for a GEO score checker grab the first free tool that shows up and run a quick audit. The problem isn’t finding a tool. It’s not knowing what the score actually reflects.

    These four tools each measure a different dimension of the same problem. Frase focuses on structural extraction. SnowSEO prioritizes trust signals. Keywordly embeds GEO into a full SEO workflow. Readdy flags the technical barriers that block AI crawlers entirely. They’re not interchangeable. And depending on what you’re trying to fix, picking the wrong one means you’re optimizing for the wrong layer.

    Here’s a clear breakdown of what each tool actually does, and where each one stops.

    Last Year’s GEO Playbook No Longer Explains AI Visibility

    A year ago, “GEO optimization” largely meant cleaning up your headings and adding a few statistics. That still matters. But it doesn’t explain why brands that rank #1 on Google are consistently ignored by ChatGPT and Perplexity.

    Research from Princeton University and Georgia Tech found that specific structural interventions can boost generative engine visibility by 30-40%. But they also surfaced a more uncomfortable finding: only about 12% of links cited in AI-generated responses also appear in the top 10 traditional search results. The two channels are operating on separate logic.
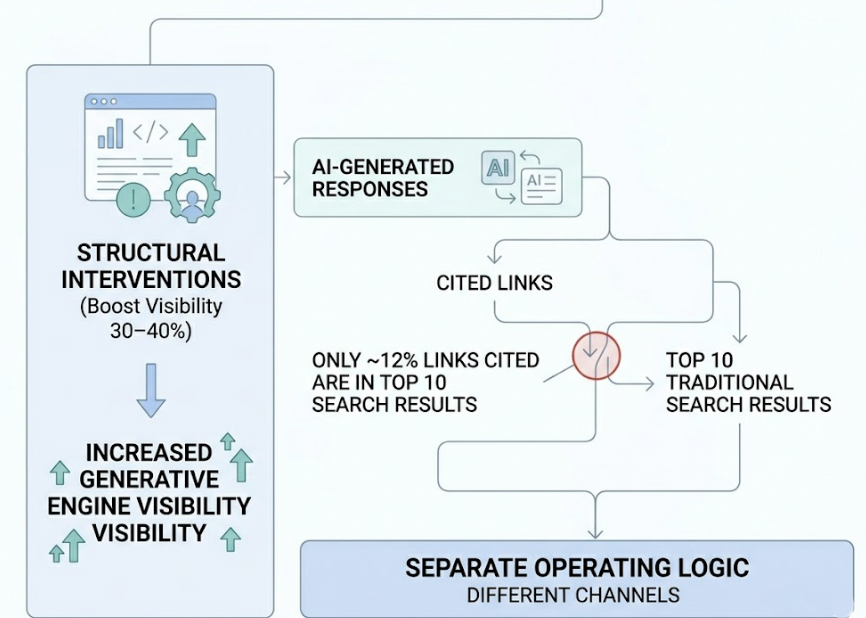
    That’s the shift most free GEO checkers haven’t caught up to yet.

    Generative engines run content through three distinct filters before a source ever gets cited. First, they parse the structure. Then, they evaluate credibility signals. Finally, and this is the layer most tools skip entirely, they check whether your brand has broader consensus across the web. A perfect score on layer one doesn’t protect you if layer three is empty.

    The 4 Free GEO Score Checkers, Side by Side

    ToolGEO Score FocusE-E-A-T AnalysisFull SEO WorkflowBrand AI Citation MonitoringFree Tier
    FraseStructural + citation-readinessLimited (sourcing check)Research to BriefNoYes
    KeywordlyMulti-factor (0-100)Moderate (Pillar 1 of 3)Full SEO integrationNoYes
    SnowSEOE-E-A-T-centricComprehensive (28 signals)Audit to Fix PlanNoYes
    ReaddyTechnical extraction + crawlabilityMinimalInstant diagnosticNoYes
    Topify GEO Score CheckerBrand + content layer combinedConsensus-basedCitation to PipelineYesYes

    The “Brand AI Citation Monitoring” column is empty for the first four tools. That’s not a gap in their features. It’s a different product category. Content-layer checkers and brand-layer trackers solve different problems. The rest of this article explains both.

    Frase: Built for Writers Who Need to Know If Their Content Will Get Cited

    Frase scores your content against what a generative engine’s parser is actually looking for. Its free GEO checker produces five sub-scores: Citability (unique, quotable facts), Content Structure (heading hierarchy and modularity), Clear Definitions (explicit explanations designed for direct extraction), Key Takeaways (summary sections AI can pull verbatim), and Data & Citations (grounding in external research).

    What makes Frase useful in practice is its competitive SERP layer. It identifies “content gaps,” questions that your competitors answer but your content doesn’t. Generative engines tend to skip thin pages that only partially cover a topic. Frase quantifies exactly how thin yours is.

    Its limitation is scope. Frase audits what’s on your page. It has no view into whether AI engines are actually recommending your brand in live queries. For content editors doing pre-publish checks, it’s the right call. For teams troubleshooting why a well-ranked page isn’t appearing in AI answers, it stops short.

    Keywordly Treats GEO as the Natural Next Step After SEO

    Keywordly’s GEO Score Analyzer outputs a 0-100 rating across three pillars: Authority, Credibility, and Structure. It’s the most SEO-native tool in this comparison, built for teams that don’t want to manage a separate GEO workflow alongside their existing content operations.

    Its standout feature is “fan-out query” detection. When a generative engine processes a prompt, it typically generates sub-questions to build a more complete answer. Keywordly identifies those latent queries, so writers can optimize for the full “prompt universe” around a topic rather than a single keyword. That shift from keyword-matching to semantic coverage is exactly how LLMs decide whether a page is comprehensive enough to cite.

    The trade-off is depth on the GEO scoring side. Because Keywordly is integrating GEO into a broader SEO workflow, its brand visibility signals are moderate rather than comprehensive. It’s the right tool for volume-focused content teams making the transition to AI-first search. It’s not the right tool for diagnosing why your brand specifically isn’t appearing in ChatGPT responses.

    SnowSEO Checks 28 E-E-A-T Signals. Most Tools Check Three.

    SnowSEO is the most rigorous free option for brands where trust is a strategic requirement, including healthcare, finance, legal, and any YMYL category where AI models apply extra scrutiny to their sources.

    Its GEO-Score audit runs across 22 factors grouped into 4 pillars, with a prioritized fix plan showing which signals to address first. The 28 individual E-E-A-T checks include author credentials and bylines, content freshness, non-stock imagery, and implementation of llms.txt, the machine-readable file that functions as a direct directive to AI crawlers for more efficient site-wide understanding.

    SnowSEO also captures something important about how generative engines evaluate sources at scale. If a site has inconsistent entity definitions or outdated facts across multiple pages, the AI’s confidence in that domain drops across the board. A single optimized pillar page isn’t enough. SnowSEO flags the inconsistencies that undermine site-wide trust.

    For editorial teams and regulated publishers, it’s the most thorough free audit available. For marketing teams troubleshooting brand-level AI visibility, it answers a different question than the one they’re actually asking.

    Readdy Finds the Technical Blocks That Everything Else Ignores

    Readdy’s GEO Score Checker focuses on a problem the other tools assume isn’t there: whether AI crawlers can actually access your site in the first place.

    Their research found that approximately 30% of websites block AI crawlers including GPTBot, ClaudeBot, and PerplexityBot due to outdated robots.txt directives. A brand could score 92/100 on Frase and still be completely invisible to generative engines because the infrastructure never let them in. Readdy checks for that before anything else.

    It’s the fastest option in this comparison. No account required, instant results, clear output. What it doesn’t offer is editorial depth. It won’t tell you whether your content is well-structured or whether your E-E-A-T signals are strong. It tells you whether the door is open.

    Use Readdy as the first check in any technical SEO audit. Use one of the other tools for what comes after.

    Your Content Score and Your Brand Visibility Are Two Separate Numbers

    Here’s the finding that most content audits miss entirely.

    A brand can score 87/100 on Frase. Clean structure, good fact density, no crawl blocks. And Topify’s tracking shows 0% Share of Voice across 40 category-level prompts in their industry. The content is optimized. The brand isn’t visible. Those are two different problems.

    The reason is how generative engines actually select sources. According to data from AI citation analysis, consensus across third-party platforms has a predictive correlation of 0.664 with AI visibility. Brand search volume correlates at 0.334. Domain authority and backlinks? Between 0.08 and 0.18. Traditional authority metrics are poor predictors of AI citation behavior.
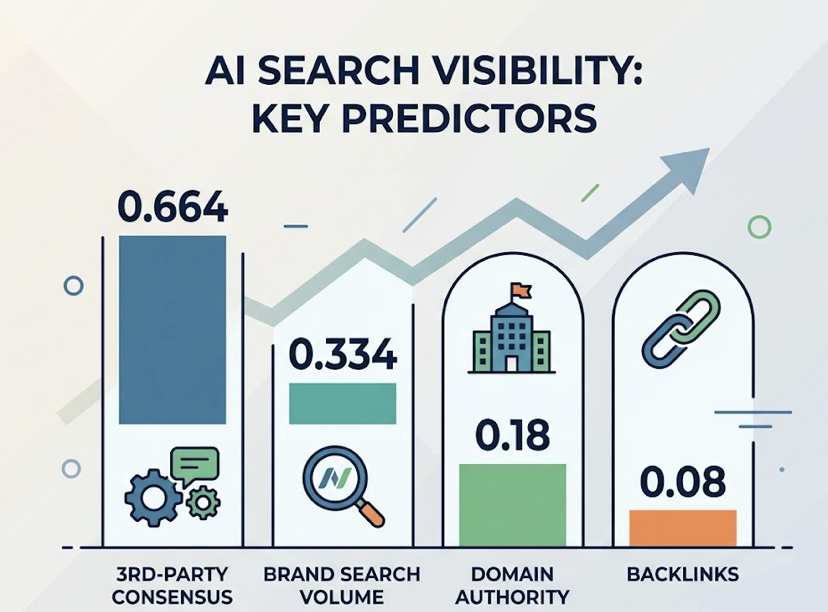
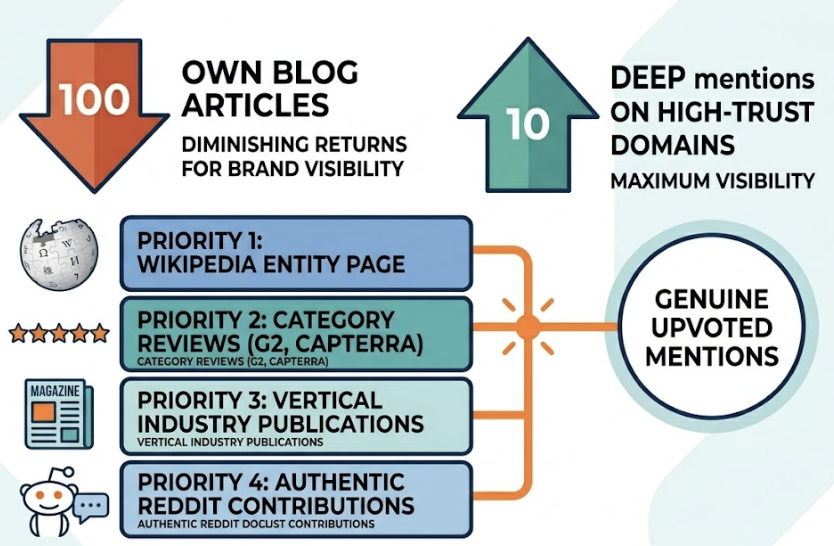
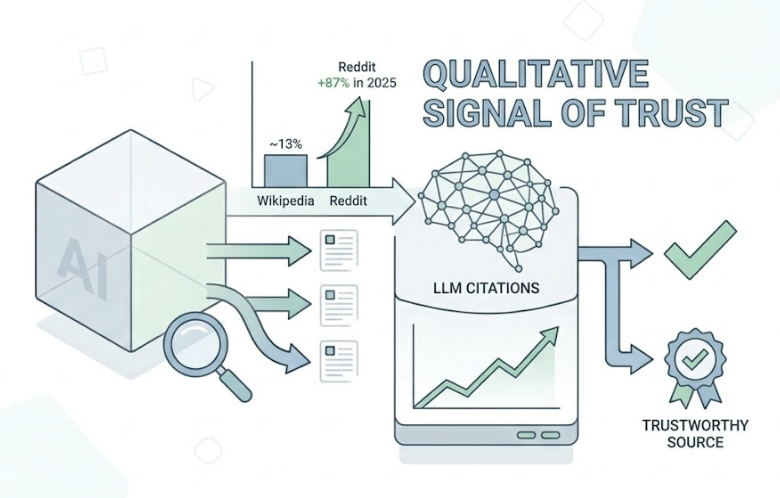
    Generative engines prioritize sources that have demonstrated consensus across the web, Reddit threads, niche review sites, news coverage, and third-party comparisons. That’s not content GEO. That’s brand GEO. And no structural audit tool measures it.

    Topify’s GEO Score Checker is where that layer becomes measurable. It tracks actual brand mentions in generative responses across ChatGPT, Gemini, Perplexity, and other major AI platforms, calculating Share of Voice for specific buying-intent prompts. It also runs Sentiment Analysis alongside visibility, because a brand cited frequently in negative contexts (described as “expensive” or “complex”) suffers in recommendation environments even when the mention count is high.
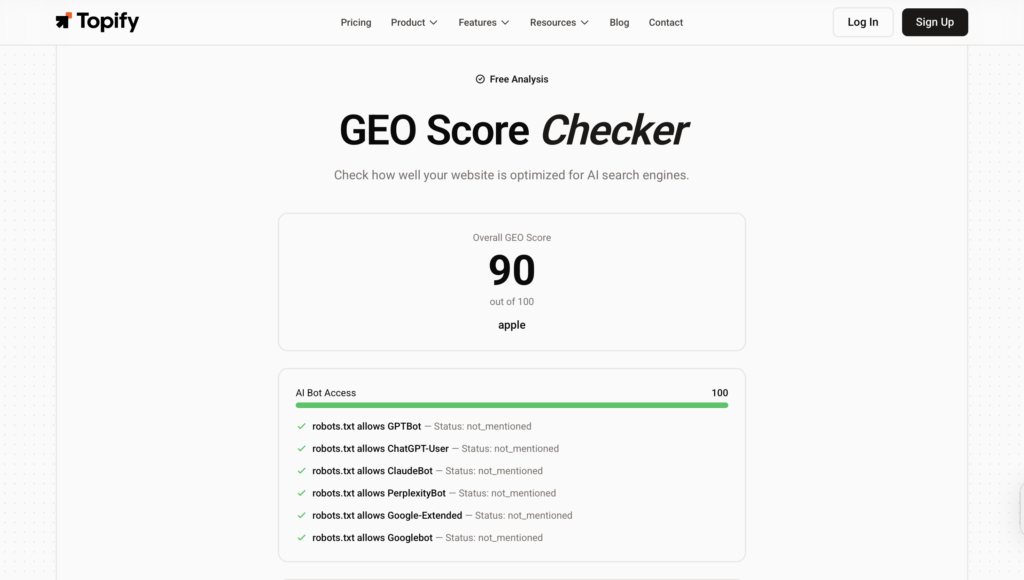
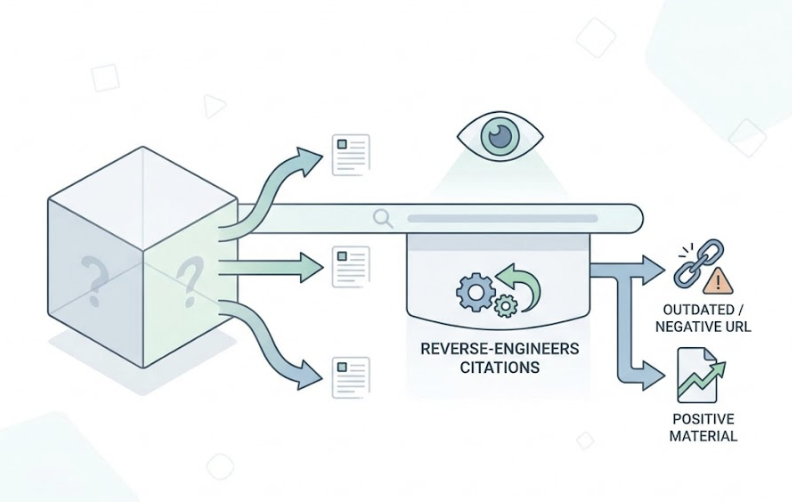
    The Topify platform also reverse-engineers citations, showing exactly which third-party domains AI models pull from when recommending brands in your category. That tells you where your brand needs to show up in the broader web ecosystem, not just on your own site.

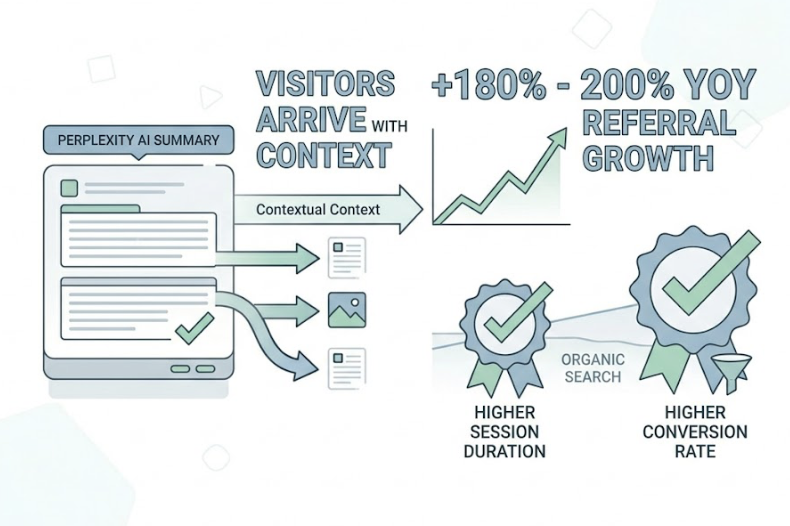
    Early data suggests AI referral visitors convert at roughly 5x the rate of traditional search traffic. The brands that capture that channel aren’t necessarily the ones with the highest content GEO scores. They’re the ones with the strongest brand-layer presence.

    Which Tool Should You Start With?

    The right starting point depends on what you’re actually trying to diagnose.

    ScenarioRecommended Tool
    Pre-publish audit on a single URLFrase or Readdy
    Suspected crawl block or technical barrierReaddy first
    GEO integrated into existing SEO content workflowKeywordly
    YMYL content or E-E-A-T is your primary concernSnowSEO
    Diagnosing why AI doesn’t recommend your brandTopify GEO Score Checker
    Ongoing brand visibility tracking across AI platformsTopify

    In practice, most teams need more than one. Readdy and Frase cover the pre-publish content layer. Keywordly fits teams scaling content production with GEO built in. SnowSEO is the authority on trust signals. And Topify covers the dimension none of the others touch.

    High content GEO scores are table stakes. Brand-level AI citation is the actual outcome.

    Conclusion

    The four free GEO score checkers in this comparison are all useful. They’re also measuring different things. Frase scores citation-readiness. Keywordly builds GEO into your SEO workflow. SnowSEO audits E-E-A-T at depth. Readdy catches the crawl blocks that silently exclude your site from AI discovery.

    What none of them track is whether your brand actually appears when users ask AI engines to recommend a solution in your category. That’s the Topify GEO Score Checker’s purpose, and it’s a different data layer entirely.

    Start with the tool that matches your bottleneck. Then ask the question the content scores don’t answer: when someone asks ChatGPT what to use, does your brand come up?

    FAQ

    What is a GEO score? 

    A GEO score rates how well your content is positioned to be extracted and cited by generative AI engines like ChatGPT, Gemini, and Perplexity. Most tools score factors like structural clarity, factual density, and E-E-A-T signals. Scores above 70 are generally considered solid; above 85 is strong. Below 60 usually means the content needs structural work before it’s citation-ready.

    Is a GEO score the same as an SEO score? 

    No. An SEO score evaluates keyword relevance and backlink signals for traditional ranking. A GEO score evaluates “citable potential,” how easily an AI can extract and verify a specific fact from your content. A page can rank #1 on Google with a low GEO score, and vice versa. The two metrics reflect two separate algorithmic systems.

    Can a high GEO score guarantee AI visibility? 

    No. A high score means your content is structurally eligible for citation. Actual visibility depends on the brand citation layer, whether the AI’s training data and web-consensus signals identify your brand as trustworthy. You can have a perfect content GEO score and zero AI recommendations if your brand lacks third-party consensus.

    Do I need a paid tool to check my GEO score? 

    Free tools work well for auditing specific pages. Frase, SnowSEO, Readdy, and Keywordly all offer free tiers that cover content-layer analysis. Daily tracking across 100+ prompts, historical trend data, and sentiment monitoring typically require a paid platform.

    What’s the difference between content GEO and brand GEO? 

    Content GEO is the structural and factual optimization of your own pages. Brand GEO is how your brand appears across the broader web, including news coverage, Reddit discussions, and third-party reviews. AI models weight consensus heavily when deciding what to recommend. You need both layers to be visible in generative search.
    Read More

  • Improve Your GEO Score: 5 Changes That Actually Work

    Improve Your GEO Score: 5 Changes That Actually Work

    You ran a GEO score check. The number came back somewhere in the 40s or 50s. Now you’re staring at a dashboard and wondering what, exactly, you’re supposed to do with that information.

    That’s the gap most optimization content doesn’t fill. Knowing your score is step one. Knowing which specific changes will actually move it — and in what order — is where most teams get stuck. Research has a clear answer on this. Pages that hit a GEO score of 0.70 or above, covering at least 12 signal dimensions, achieve a 78% cross-platform AI citation rate. The three factors that drive the most of that outcome aren’t content volume or keyword density. They’re metadata freshness, semantic HTML structure, and structured data.

    Here’s what to fix, and why it works.

    Your GEO Score Isn’t One Metric — It’s a Weighted System

    Most teams treat GEO score like a single number to push upward. It’s not. It’s a composite of 12 signal dimensions that reflect how ready a page is for AI retrieval and citation.

    According to Geoptie’s framework, these dimensions span technical infrastructure, content architecture, authority signals, and monitoring practices. The weighting matters here: “AI interpretability” and “semantic richness” together account for more than 55% of the total score. That’s why brands can have strong content but still score in the 40–60 range — they’ve invested in the wrong dimensions.

    The practical implication is that improving your GEO score isn’t about doing everything at once. It’s about identifying which of the 12 dimensions are dragging your weighted average down. In most cases, three categories explain the majority of the gap.

    The 3 Factors Behind 78% of AI Citation Rate

    Research by Arlen Kumar and Leanid Palkhouski, conducted at UC Berkeley and the Wrodium Research Center, audited 1,702 citations across Brave Summary, Google AI Overviews, and Perplexity. The finding that stands out isn’t just the 78% citation rate at G ≥ 0.70 — it’s the threshold effect. Citation probability doesn’t increase linearly with quality. It jumps once a page crosses the 0.70 line.

    The three factors with the highest correlation coefficients in the logistic regression were:

    FactorCorrelation (r)Primary Mechanism
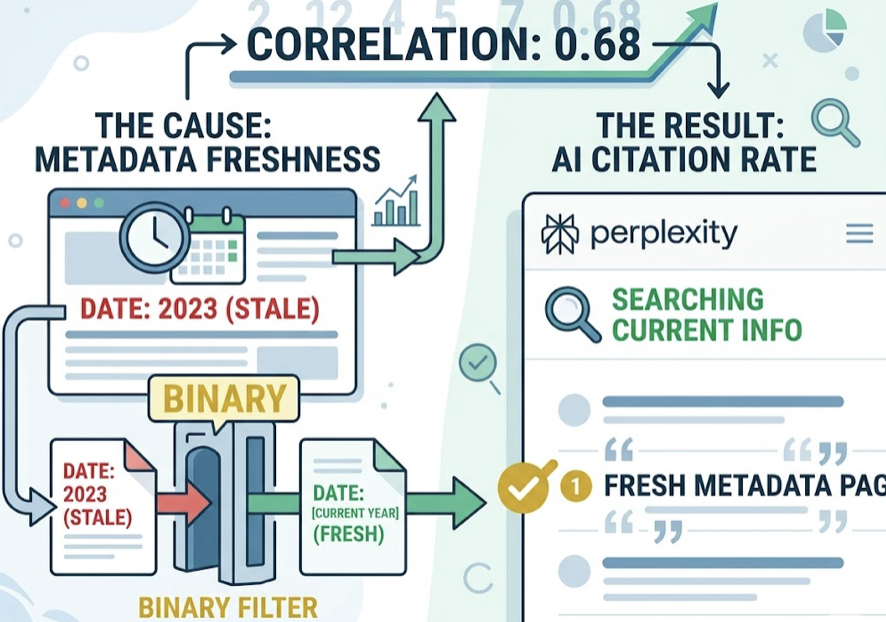
    Metadata Freshness0.68Addresses RAG time-decay bias
    Semantic HTML Structure0.65Reduces extraction noise
    Structured Data (Schema)0.63Accelerates entity recognition

    These aren’t arbitrary rankings. Each one directly resolves a specific obstacle in the Retrieval-Augmented Generation (RAG) pipeline that AI engines use to pull and synthesize content. A page that scores well on all three gives an AI model cleaner data, clearer context, and more confidence that the content is current.

    High-scoring pages are 4.2 times more likely to be cited than low-scoring pages. That’s the odds ratio from the same study. The asymmetry is significant enough that fixing these three factors should come before anything else.

    Change #1: Refresh Your Metadata Before You Touch Anything Else

    Metadata freshness has a correlation coefficient of 0.68 with AI citation rate — the highest of the three. The reason is straightforward: AI engines with real-time retrieval capability, like Perplexity, are trained to prioritize current, accurate information. Stale metadata acts as a binary filter. A page whose timestamp still reads 2023 can get excluded from the candidate pool before an AI even evaluates its content.

    The data on this is concrete. Content updated within the past 60 days is cited 1.9 times more often than older content. That’s not a marginal improvement — it’s nearly double the citation rate for pages that simply signal recency.

    The operational fix is more specific than just “updating content.” Three fields matter most:

    Last-Modified header: This needs to appear in both the HTTP response header and the HTML source. It should be a machine-readable timestamp, not a visible date string.

    Meta description: AI-optimized meta descriptions should be 50–100 words and state the page’s core conclusion directly. The traditional click-bait format doesn’t serve AI retrieval — a concise, factual summary does.

    OG tags: These are often overlooked. If your Open Graph tags reference an old version of a headline or image, AI systems pulling cached data will work with outdated information.

    For fast-moving industries, a monthly metadata audit is worth building into the content calendar. For evergreen content, quarterly is sufficient.

    Change #2: Rebuild Your Page Structure with Semantic HTML

    The correlation between semantic HTML structure and AI citation rate is 0.65. That’s because AI retrieval systems don’t read pages the way humans do — they parse them. A page built with generic <div> containers creates extraction noise. A page with proper semantic markup gives the retrieval model a clear map.

    Research shows that clear H1–H3 heading hierarchies allow AI models to achieve 85% chunking accuracy during text parsing. Without semantic structure, content gets fragmented or loses context during extraction — meaning even good content can get cited incorrectly or not at all.

    Five structural changes with the highest GEO impact:

    <article> and <section> tags: These define content boundaries. When a retrieval system encounters these tags, it treats the content inside as a discrete information block — which is exactly how you want your content to be indexed and vectorized.

    <header> and <main> tags: These help crawlers separate navigation and sidebar content from the page’s actual substance. Without them, irrelevant sidebar text can get weighted alongside your core argument.

    Strict H1–H3 hierarchy: H2 for primary sections, H3 for supporting points. This creates a natural summary-to-detail relationship that AI can use to generate accurate, structured answers.

    <table> with <thead>: Tabular data gets cited at 2.5 times the rate of plain-text equivalents. If you’re making comparisons or presenting data, a table isn’t just visually cleaner — it’s structurally superior for AI extraction.

    <cite> and <blockquote>: When your content references expert sources, these tags explicitly signal attribution. That transparency raises the page’s authority score in AI evaluation.

    The underlying principle: a “clean” HTML architecture is the physical prerequisite for G ≥ 0.70. You can’t compensate for structural chaos with better content.

    Change #3: Add Structured Data — and the Right Kind

    If semantic HTML is about making content extractable, JSON-LD structured data is about making it understandable. It converts natural language into machine-readable fact sheets that AI engines can use to verify, categorize, and confidently cite information.

    Pages with structured data show 43–44% higher visibility in AI responses. The mechanism is direct: when a RAG pipeline matches a query to a page with Schema markup, the AI’s confidence in generating an accurate answer increases. That confidence translates into citation.

    Four Schema types that move the needle most:

    FAQPage: This is the highest-leverage Schema type for GEO. Since generative search is fundamentally a question-answering system, FAQ structure allows AI to directly extract a question and its verified answer. Even pages that have lost Google SERP visibility can gain AI citation volume through FAQPage markup.

    Article: Defines content type, author identity, and publication date. This is the primary input for E-E-A-T evaluation — the set of signals AI uses to assess whether an author and publisher are credible.

    Organization: Establishes your brand as a distinct entity. This is what allows AI systems to aggregate information about your brand from multiple sources and attribute it correctly.

    HowTo: For procedural queries, structured step data gets extracted more reliably than long-form prose. If your content explains a process, HowTo Schema turns it into a format AI can use directly.

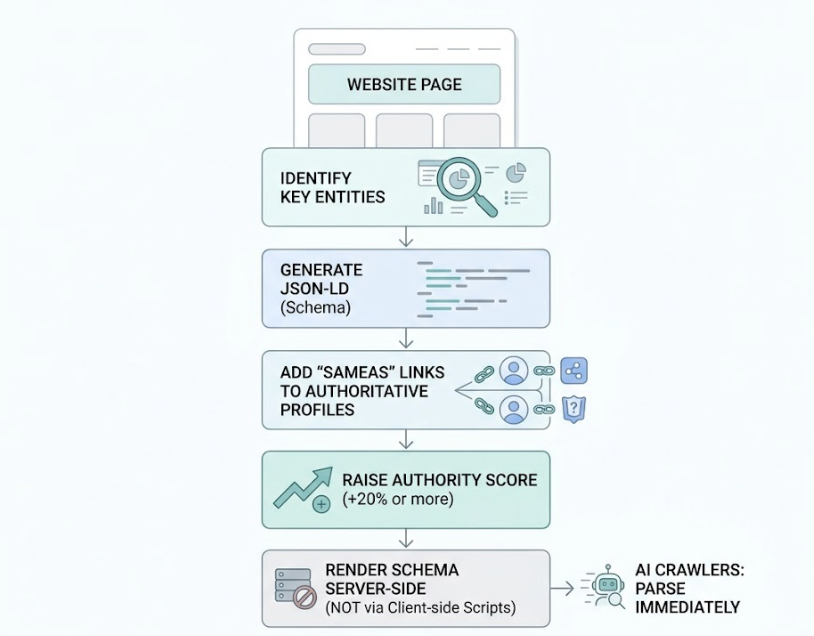
    The fastest path to implementation: identify the key entities on each page, generate JSON-LD using a Schema generator, and add SameAs properties that link your entities to authoritative third-party profiles. That linkage alone has been shown to raise authority scores by 20% or more. One non-negotiable: render Schema server-side, not via client-side scripts. AI crawlers need to parse it immediately.

    Changes #4 and #5: The Last Mile to 0.70

    Once the technical foundation is in place, two more factors determine whether a page can reach and hold a score above 0.70. These are less about infrastructure and more about content depth.

    Change #4: Strengthen Authority Signals

    In the 12-dimension GEO scoring model, authority signals carry high weight. Research from Princeton (Aggarwal et al., 2023) confirmed that specific authority-building interventions produce measurable citation gains.

    Adding concrete statistics to a page improves AI visibility by 40%. Not approximate ranges — specific numbers. AI engines treat quantitative data as a verification anchor. If your content can make a claim and back it with a precise figure, it becomes more citable than a page making the same claim without evidence.

    Including expert quotations lifts visibility by 30% or more. AI interprets direct attribution as a signal of industry consensus and depth of sourcing.

    The counterintuitive one: citing high-authority external sources within your content. This doesn’t dilute your page’s value — it positions the page as a knowledge hub. Pages that actively cite credible external references have shown visibility gains of 115% in AI responses for Tier 5 sites. The logic is that AI models view outbound links to authoritative sources as a sign that the content is well-researched and contextually accurate.

    Change #5: Optimize for Answer Density

    AI models have a finite context window. They’re looking for pages that deliver the highest information-to-token ratio. A page that answers a question directly, with minimal setup and no filler, is more likely to be selected as a source.

    Content written at a Flesch-Kincaid grade level of 6–8 gets cited 31% more often than content at higher complexity levels. That’s not about dumbing down — it’s about removing friction from the extraction process. Short sentences and direct statements are faster for AI to parse and verify.

    Each paragraph should orbit one central fact. Transitional throat-clearing (“As we’ve seen so far…”) consumes token space without adding information. Cut it.

    There’s also a credibility angle: content that explicitly acknowledges trade-offs or presents multiple perspectives is 1.7 times more likely to be cited than single-viewpoint content. AI models appear to weight intellectual honesty — admitting what a recommendation doesn’t cover — as a quality signal.

    You’ve Optimized. Now Track Whether AI Actually Notices.

    These five changes will move your GEO score. But here’s what most teams discover next: they don’t know if it worked.

    AI citation is probabilistic. The same prompt can produce different results across ChatGPT, Perplexity, Gemini, and Claude — and can shift week to week as models update. A one-time score check tells you where you started. It doesn’t tell you whether your brand is being cited now, what language AI is using to describe you, or which competitors just moved ahead of you in AI recommendations.

    That’s the problem Topify is built to solve. The GEO Score Checker gives you a baseline — and ongoing monitoring across major AI platforms shows you what happens after you’ve made the changes. You can track visibility by prompt, monitor sentiment in AI-generated descriptions, and analyze which source URLs AI platforms are actually citing when they answer questions in your category.

    Top brands in competitive categories reach 12% AI visibility on relevant prompts. The average is 0.3%. The gap between those two numbers isn’t just about content quality — it’s about whether a brand is iterating on real citation data or guessing.

    Optimization without measurement is a one-time event. Measurement turns it into a system.

    Conclusion

    A GEO score below 0.70 typically means a page has structural gaps, not content gaps. The three highest-leverage changes — metadata freshness, semantic HTML architecture, and structured data — address the retrieval and comprehension bottlenecks that prevent AI from citing even well-written content.

    Changes #4 and #5 close the gap for pages already near the threshold. Authority signals and answer density are what separate a page that sometimes gets cited from one that consistently does.

    Start with a GEO score check to know which dimensions are pulling your score down. Fix the technical layer first — metadata, HTML, Schema. Then add the content-level authority signals. And build a monitoring system that tells you whether the citations are actually coming in.

    The research is clear on what the threshold is. Whether you’ve hit it is a measurement question, not a guessing one.


    FAQ

    Q: What is a good GEO score for AI citations?

    A: A score of 70 or above is generally considered the baseline for entering the AI citation pool. Pages at this level have sufficient semantic structure and metadata to be included in multi-engine retrieval. To hit the 78% cross-platform citation rate identified in the Kumar et al. research, you’d want to push toward 85+. Most current websites score in the 40–60 range, so exceeding 70 already represents a significant competitive advantage.

    Q: How long does it take to see GEO score improvements after optimization?

    A: Technical changes — Schema markup, metadata updates, HTML restructuring — typically register within 1–2 weeks, once AI crawlers re-index the page. Longer-term authority signals like E-E-A-T improvements can take 3–6 months to shift how AI models represent your brand in non-RAG contexts, where the underlying knowledge base needs time to update.

    Q: Does improving my GEO score also help traditional SEO rankings?

    A: Yes, and the correlation is strong. Around 80% of AI citations already come from pages that rank in Google’s top 10. The technical requirements for GEO — structured data, fast load times, semantic markup, quality external links — are the same signals Google’s ranking algorithm rewards. Improving your GEO score is, in practice, a reinforcement of the same content quality and technical health that drives traditional SEO.

    Q: Which Schema type has the biggest impact on GEO score?

    A: FAQPage Schema tends to have the highest GEO impact because generative search is fundamentally a question-answering system. AI engines can directly extract the question and its answer from FAQPage markup, which is cleaner and more reliable than parsing a long-form paragraph for the same information. Article and Organization Schema are also high-priority additions, particularly for establishing entity identity and E-E-A-T signals.


    Read More

  • GEO Score vs SEO Score: They’re Not the Same

    GEO Score vs SEO Score: They’re Not the Same

    You’ve spent years building domain authority. Your DA is 75. You rank on page one for a dozen competitive keywords. Then someone asks ChatGPT to recommend the top tools in your category, and your brand doesn’t appear once.

    That’s not a bug. That’s the gap between SEO Score and GEO Score, and it’s costing brands more visibility than they realize.

    Your Domain Authority Means Nothing to ChatGPT

    Here’s the thing most marketers still haven’t fully processed: large language models don’t consult your backlink profile when deciding what to cite. They don’t check your DA, your PageRank, or your Core Web Vitals. Those signals were built for crawler-based engines. Generative AI operates on a completely different logic.

    What AI models look for is “topical entity density” and “information gain.” A niche site with focused, data-rich content and frequent citations within its field can outrank a DA-80 domain in AI-generated answers. High domain authority is a Google signal. It’s not a GEO signal.

    That’s the foundational misread most brands make: they assume GEO is just SEO with a new name. It’s not. They measure entirely different capabilities.

    What SEO Score Actually Measures

    SEO Score reflects a page’s potential to rank in traditional search results. Tools like Moz, Ahrefs, and SEMrush evaluate it across a few consistent dimensions: technical health (Core Web Vitals, mobile-friendliness, HTTPS), content relevance (keyword alignment, heading structure), backlink profile, and crawlability.

    The underlying logic is simple. Help Google or Bing determine whether this page deserves a top-10 position for a given query. SEO Score is the answer to that question, expressed as a number.

    Its strengths are real. Organic traffic growth, click-through rate optimization, keyword ranking maintenance: these are all downstream of a healthy SEO Score. But SEO Score tells you nothing about whether an AI will cite you. That’s a separate question entirely.

    What GEO Score Actually Measures

    GEO Score measures the probability that your content gets cited in an AI-generated answer. It’s a machine-readability metric, not a human-popularity metric.

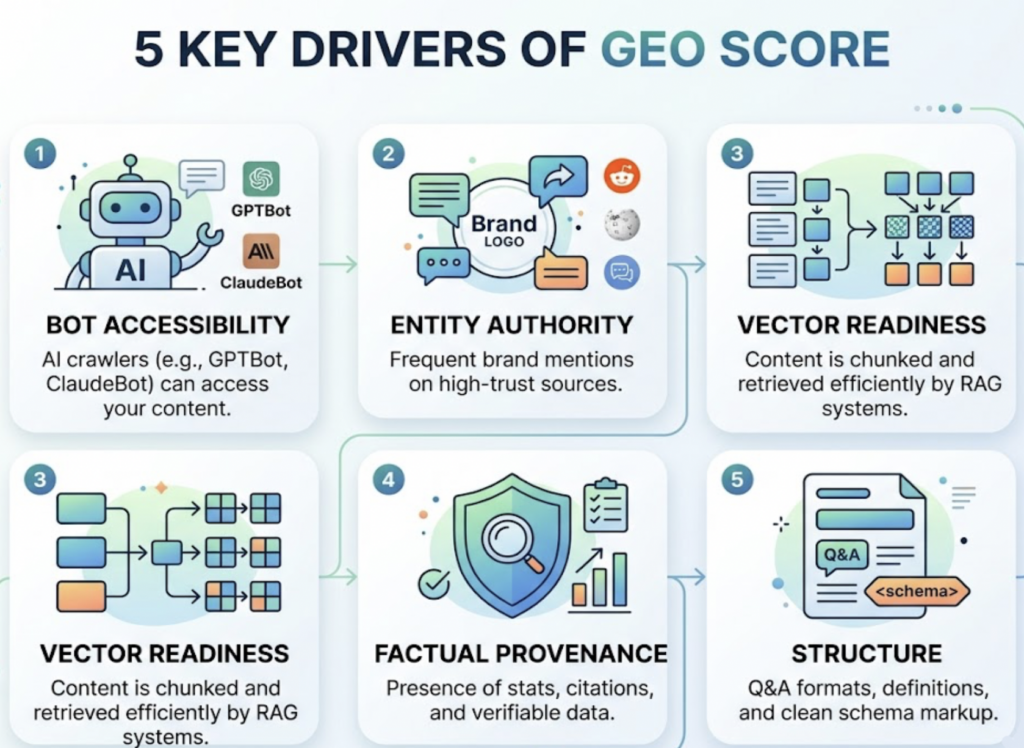
    The specific signals that drive GEO Score fall into five categories. Bot accessibility: whether AI crawlers like GPTBot and ClaudeBot can actually access your content. Entity authority: how frequently your brand is mentioned across high-trust sources like Reddit, Wikipedia, and niche forums. Vector readiness: how well your content can be chunked and retrieved by RAG (Retrieval-Augmented Generation) systems. Factual provenance: the presence of statistics, authoritative citations, and verifiable data. Structure: whether you’re using Q&A formats, clear definitions, and schema markup that AI parsers can extract without friction.

    Princeton University research confirmed the weight of these signals. Across 10,000 queries, content that cited authoritative sources saw a 40% boost in AI visibility. Adding statistics drove a 37% increase. Expert quotations added 30%. The research also found that websites ranked fifth in traditional search saw a 115% visibility jump when they applied citation-based GEO tactics, while top-ranked sites that ignored GEO actually lost ground.

    That’s the equalizer effect. GEO doesn’t care who had the most backlinks five years ago.

    You can get an immediate baseline read on where your site stands with Topify’s GEO Score Checker. It runs a multi-dimensional analysis and gives you a starting point before you touch anything else.

    Side by Side: What Separates the Two Scores

    DimensionSEO ScoreGEO Score
    MeasuresSearch engine ranking potentialProbability of AI citation
    Core signalsBacklinks, DA, keyword densityContent structure, entity authority, factual density
    Optimization goalTop 10 “blue links”Cited as source in AI-generated answers
    Primary toolsMoz, Ahrefs, SEMrushGEO Score Checker, Topify
    Conversion mechanismClick on a ranked linkClick on a citation inside an AI response
    StabilityRelatively stableHighly dynamic, shifts with model updates
    Strategic focusTechnical health + authorityInformation gain + machine-readability

    One more difference worth calling out: AI-referred visitors convert at approximately 14.2%, compared to 2.8% for traditional organic search. That’s a five-fold gap. Users who click a citation in a ChatGPT or Perplexity response have already been pre-qualified by the AI’s synthesis. They’re not browsing. They’re deciding.

    Why “Both” Is Not Optional in 2026

    Some teams have responded to the rise of AI search by pivoting fully to GEO. That’s the wrong move, and the data makes it clear why.

    As of early 2026, AI search tools have captured between 12% and 15% of global search market share, up from roughly 5% at the start of 2025. Gartner projects that traditional search volume will decline 25% by the end of 2026. That’s a real and measurable shift. But 75-85% of queries still go through traditional engines.

    More importantly, the two channels are technically interdependent. ChatGPT sources approximately 87% of its citations from the top 10 Bing organic results. Google’s Gemini AI Overviews primarily cites pages that already rank in the top 10 on Google. If your site doesn’t have basic SEO health, it may never enter the retrieval pool that generative models draw from.

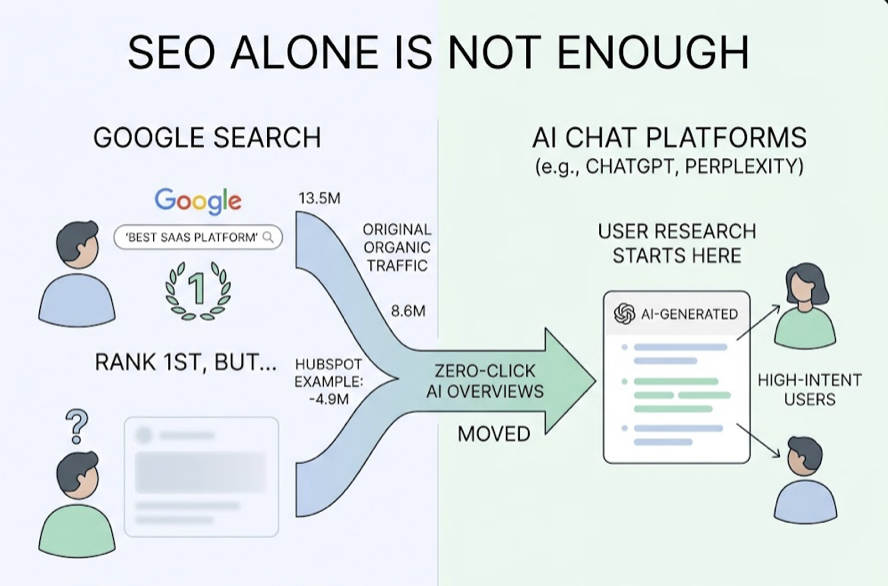
    On the flip side, SEO alone won’t save you. A brand can rank first on Google for a competitive keyword and remain completely invisible in ChatGPT or Perplexity, platforms where an increasing share of high-intent users are starting their research. The HubSpot case made this concrete: the company saw organic traffic drop from 13.5 million to 8.6 million as top-of-funnel informational queries were captured by zero-click AI overviews. The traffic didn’t disappear. It moved channels.

    The bottom line: SEO Score and GEO Score aren’t competing metrics. They’re parallel ones. Ignoring either means you’re leaving a meaningful portion of your addressable market on the table.

    GEO Score Is a Baseline, Not a Monitoring System

    Here’s where a lot of teams get stuck. They run a GEO Score check, feel good about the number, and move on. But a GEO Score is a static snapshot. It reflects your content’s cite-worthiness at a single point in time.

    The actual AI citation landscape is volatile. The same prompt that surfaces your brand today may surface your competitor tomorrow if they publish fresher data or a more concise answer. AI platforms update their retrieval logic. New prompts emerge. Competitors optimize in real time.

    That’s the limitation the score can’t solve on its own.

    The brands that are pulling ahead in 2026 are treating GEO as a continuous monitoring problem, not a one-time audit. That means tracking not just whether you have a high score, but whether you’re actually appearing in AI responses, how often, where in the response, and with what sentiment.

    Topify tracks exactly that across ChatGPT, Perplexity, Gemini, DeepSeek, and other major AI platforms using seven core metrics: Visibility Rate (how often you appear across relevant prompts), Position Score (where in the recommendation order), Sentiment Score (tone of the AI’s description), Intent Coverage (spread across informational, comparative, and transactional queries), Source Citation Frequency (which of your URLs are being pulled), Share of Voice benchmarked against competitors, and Conversion Visibility tied to referral traffic.

    The workflow that makes sense right now: use a GEO Score Checker to establish your content baseline, then use Topify to track whether that baseline is translating into actual citations, and where those citations are shifting over time.

    Most brands currently have an AI citation rate near zero. Reaching 10-12% citation frequency across relevant category queries is considered top-tier performance for 2026. You can’t close that gap if you don’t know where you’re starting from or how it’s moving.

    Conclusion

    GEO isn’t SEO rebranded. It’s a separate measurement of a separate capability: can an AI find your content, understand it, trust it, and cite it in the answers it generates for your potential customers?

    The misunderstanding that GEO is just “SEO 2.0” is exactly what lets more agile brands with smaller domains outrank legacy players in AI-generated responses. You don’t need ten years of link building to win on Perplexity. You need factual density, structural clarity, and consistent presence across the right information channels.

    Check your GEO Score first with Topify’s GEO Score Checker to see where you stand today. Then build the monitoring layer to track where you’re moving, because in a landscape where AI models update their retrieval logic without announcement, a one-time score is just the starting line.

    FAQ

    Q: Is GEO Score the same as AEO (Answer Engine Optimization) score?

    They’re closely related but not identical. AEO focuses on becoming the direct answer: featured snippets, voice assistant responses, zero-click results. GEO is broader. It covers how AI models perceive and recommend your brand across conversational interactions generally, including the technical RAG pipeline that governs retrieval. Think of AEO as a subset of GEO, focused on format and conciseness.

    Q: Can I have a high GEO Score but a low SEO Score?

    Yes. A site with excellent, well-structured, data-rich content can score well on GEO while having a thin backlink profile that limits Google rankings. That brand might get cited regularly by Perplexity or Claude, while remaining invisible in Google’s AI Overviews, which skews heavily toward existing top-10 organic results. The scores measure different things and don’t move in lockstep.

    Q: How often should I check my GEO Score?

    A static GEO Score check is worth doing at least monthly. But in competitive sectors like SaaS, fintech, or B2B software, monthly snapshots aren’t enough to catch shifts in citation patterns as they happen. Real-time monitoring through a platform like Topify is the more useful setup for brands where AI visibility directly affects lead generation.

    Q: What’s a good GEO Score to aim for?

    There’s no universal benchmark, but context matters: most brands are currently at near-zero AI citation rates. Reaching 10-12% citation frequency across relevant category prompts puts you in the top tier for 2026. The GEO Score tells you whether your content is structurally ready to be cited. Hitting that citation rate is a function of ongoing optimization.

    Q: Does improving my SEO Score automatically improve my GEO Score?

    Not necessarily. Building more backlinks improves your Google rankings but doesn’t make your content more machine-readable. If your top-ranked pages are dense, unstructured text without statistics, clear definitions, or cited sources, your GEO Score will stay low regardless of your domain authority. The two scores require distinct optimization work.

    Read More

  • Low GEO score? Fix These 3 Things First in 2026

    Low GEO score? Fix These 3 Things First in 2026

    You ran a GEO score checker on your site. The number came back lower than expected, maybe a 32 or a 38, and now you’re trying to figure out what it actually means.

    Here’s the thing: a low GEO score isn’t a verdict on your content. It’s a diagnostic. It tells you that somewhere between how you write, what you cite, and how you structure information, there’s friction that’s stopping AI engines from extracting and quoting your pages.

    The research is clear on this. According to analysis of over 12,500 queries, 83% of citations in AI Overviews now come from pages outside the traditional organic top 10. Legacy domain authority matters less than it used to. Structure and extractability matter more. That’s what your GEO score is actually measuring.

    This guide breaks down the three failure modes by score range, with specific fixes for each one, and shows you how to verify that your changes are actually working.

    A Low GEO Score Means AI Can’t Use Your Content

    Before diving into fixes, it helps to understand the mechanism.

    Generative engines like ChatGPT, Perplexity, and Google AI Overviews don’t read your articles the way a human does. They scan for “citable units”: passages they can extract, attribute, and drop into a synthesized answer. If your content doesn’t yield clean snippets, it gets skipped, regardless of how good the ideas are.

    A score below 40 typically reflects one of three problems: the writing is too complex to parse, the source isn’t trusted enough to cite, or the content can’t be extracted in pieces. These aren’t vague quality issues. They’re mechanical failures with specific fixes.

    The score range tells you which failure you’re dealing with.

    Score 0-25: Your Writing Is Working Against You

    At this level, the core problem is linguistic. AI retrieval systems struggle to summarize content when sentences are long, passive voice is overused, or a single paragraph covers multiple ideas without a clear anchor.

    Research by Princeton and IIT Delhi found that simplifying language boosts citation rates by 15-30% because it reduces the cognitive load on the LLM’s summarization layer. The data behind this is specific: sentence length under 20 words correlates with citation success at r=0.68, while pronoun ambiguity (using “it” or “they” without a clear antecedent) correlates at r=-0.71, one of the strongest negative signals in the dataset.

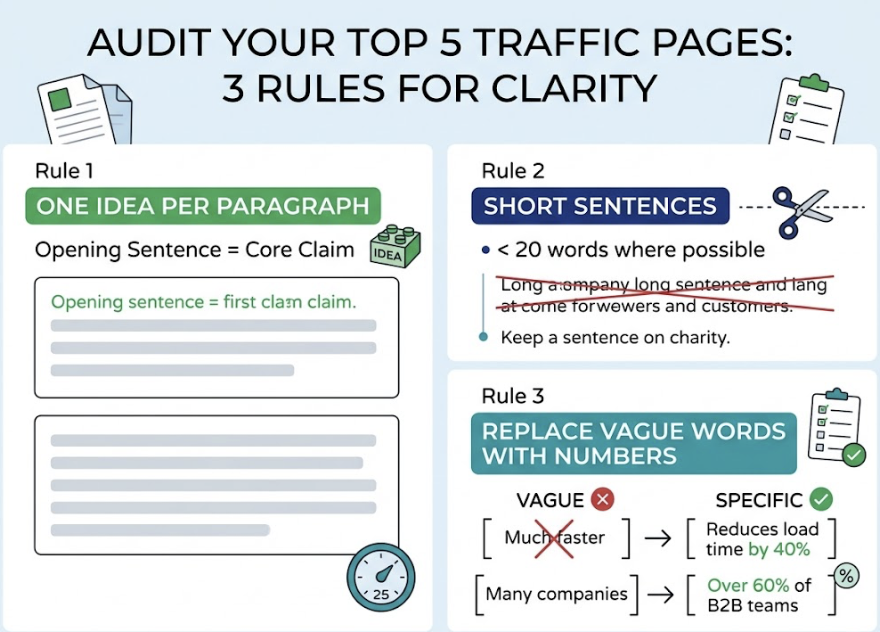
    The fix: Audit your top five traffic pages and apply three rules. First, one idea per paragraph, with the core claim in the opening sentence. Second, cut sentences to under 20 words where possible. Third, replace vague language with numbers. “Much faster” becomes “reduces load time by 40%.” “Many companies” becomes “over 60% of B2B teams.” Content that can’t maintain at least one verifiable fact per 200 words is frequently filtered out during the reranking phase of the RAG pipeline.

    That last point is worth repeating.

    A paragraph full of assertions AI can’t verify isn’t just weak, it’s often invisible.

    Score 25-40: AI Doesn’t Trust Your Sources

    Content in this range is usually well-written. The problem is different: the engine can read it, but it doesn’t feel confident citing it.

    Generative engines are under constant pressure to avoid hallucinations. One way they manage this is by prioritizing sources that cite other credible sources. If your content makes claims without pointing to academic papers, industry reports, or named expert opinions, the engine treats those claims as unverified and moves on.

    The lift from fixing this is significant. Adding authoritative citations to otherwise well-optimized pages yields up to a 115% improvement in citation probability. Peer-reviewed research carries the highest trust signal, followed by industry benchmarks from firms like Gartner or McKinsey, then named expert quotes. Generic phrases like “studies show” without attribution actually reduce citation probability by 15%.

    There’s a recency factor here too. Around 50% of content cited in AI answers is less than 13 weeks old. Stale statistics, even accurate ones, get deprioritized as engines favor fresher takes on the same topic.

    The fix: Go through your content and find every claim that isn’t anchored to a named source. Replace “research shows” with a specific citation. Link out to .gov, .edu, or established industry reports. Add one direct quote from an internal subject matter expert or named industry figure per article. Also run an entity audit: check that your brand is described consistently across LinkedIn, G2, Crunchbase, and Wikipedia. Contradictory information across these platforms creates “entity ambiguity” that quietly drags down your trust score.

    Score 40-60: Your Content Can’t Be Extracted in Pieces

    This range is the most frustrating because you’re close. The writing is clear, the sources are credible, but the content still isn’t getting cited at the rate it should.

    The issue is structure. A passage that makes sense in context but falls apart when read in isolation won’t be extracted. AI engines pull chunks, not articles. Each H2 and H3 section needs to be able to stand alone as an answer.

    The format you use matters a lot here. Data tables lead to 4.1 times more citations than standard narrative prose. FAQ format achieves a 65% citation probability compared to 18% for regular paragraphs. The heading hierarchy also matters: 68.7% of pages cited in ChatGPT responses follow a strict H1→H2→H3 structure. Vague headings like “More Information” or “Other Considerations” prevent the retrieval system from matching sections to queries.

    The fix: Start each H2 section with a direct, self-contained answer sentence. Think of it as an “answer capsule”: a sentence that fully satisfies a specific question even if it’s read without any surrounding context. For example, instead of opening with “When it comes to content structure, there are several things to consider,” write “Content structured with one claim per paragraph and a direct opening sentence is extracted by AI engines at significantly higher rates.” Add FAQ blocks at the end of key articles with explicit question-and-answer formatting. Convert any in-paragraph comparisons to tables.

    Fix These in the Right Order

    Most teams try to fix everything at once. That makes it impossible to know which change actually moved the needle.

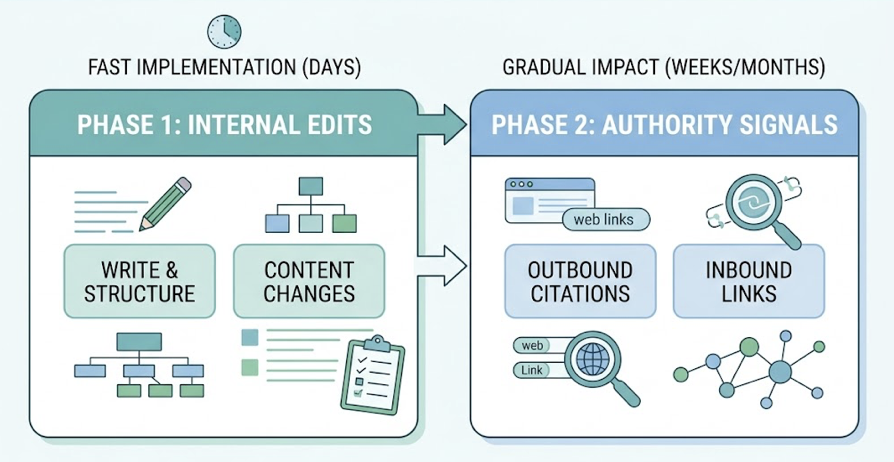
    The more effective approach is sequential. Start with writing and structure changes, those are internal edits that can go live within days and have no dependencies. Authority signals take longer because they require outbound citations to be indexed and inbound links to propagate. Running both in parallel just creates noise.

    A two-week sprint works well here. In week one, focus on the top five pages by traffic: rewrite sentence structure, add answer capsules to each H2, implement FAQ and Article schema markup. In week two, audit your content for unsupported claims and replace them with specific data points, add at least two external citations per article, and clean up your entity profiles across third-party platforms.

    This sequence mirrors what the underlying GEO scoring formula rewards. Across 16 optimization pillars, the strongest individual correlations with citation belong to metadata freshness (r=0.68), semantic HTML (r=0.65), and structured data (r=0.63). The quick wins in week one address all three.

    After You Fix It, You Need to Verify It

    Here’s the gap most teams run into: they make the changes, and then they have no idea whether it worked.

    Traditional analytics tools like Google Search Console don’t track AI citations. They can’t tell you whether ChatGPT started mentioning your brand more often, whether Perplexity is pulling from your updated pages, or whether your authority signals are being recognized by AI indexes. You’re essentially optimizing blind.

    The practical starting point is running your URLs through a GEO score checker before and after each round of edits. This gives you a baseline and a delta. A score improvement from 33 to 51 in two weeks tells you the structural changes are working. A score that stays flat tells you to look elsewhere.

    For ongoing visibility beyond the score itself, Topify tracks how your brand actually appears inside AI responses across ChatGPT, Gemini, and Perplexity. It monitors mention frequency, sentiment, and position within synthesized answers, the signals that tell you whether optimization is translating to real-world AI visibility. The Source Analysis feature goes one level deeper, showing you exactly which domains AI engines are citing in your category, so you can spot gaps and target the right external placements.

    The GEO score is the diagnostic. Continuous monitoring is how you close the loop.

    Conclusion

    A low GEO score is specific. It points to one of three problems: writing that AI can’t parse, sources AI doesn’t trust, or structure AI can’t extract. Each has a defined fix, and the fixes have a logical order. Start with clarity, then credibility, then structure.

    The harder part is knowing whether it’s working. Use a GEO score checker to track before-and-after deltas, and use continuous monitoring to verify that your changes are showing up inside actual AI responses. The brands that close that feedback loop are the ones building durable visibility in the AI search era.

    FAQ

    What is a good GEO score?

    Scores of 61-85 indicate solid optimization with reliable authority signals. Scores above 86 are considered excellent and consistently generate AI citations across multiple platforms. Scores below 60, particularly below 40, point to structural or credibility issues that need to be addressed before expecting consistent citation.

    How long does it take to improve a GEO score?

    Writing and formatting changes can produce new citation appearances within weeks as crawlers update. Building topical authority through external citations and backlinks typically takes three to six months to compound. The two-week sprint framework covers the fast-moving fixes first.

    Does a high GEO score affect ranking in ChatGPT?

    Yes, but differently from SEO. A higher GEO score increases the likelihood that ChatGPT’s browser agent selects your page as a candidate source during synthesis. It doesn’t guarantee placement, but it improves the probability significantly.

    Can I improve my GEO score without rewriting all my content?

    Adding schema markup, updating metadata for freshness, and strengthening your outbound citation profile can all move the score without a full rewrite. That said, structural changes at the paragraph level tend to produce the largest single improvements.

    How often should I check my GEO score?

    Monthly for established pages in stable niches. Weekly for competitive industries, since citation patterns shift based on model updates and competitor content changes.

    Read More

  • How to Check Your GEO Score for Free

    How to Check Your GEO Score for Free

    Your domain authority is solid. Your keyword rankings are holding. But none of that tells you whether ChatGPT is recommending your competitor instead of you the next time someone asks for a tool in your category.

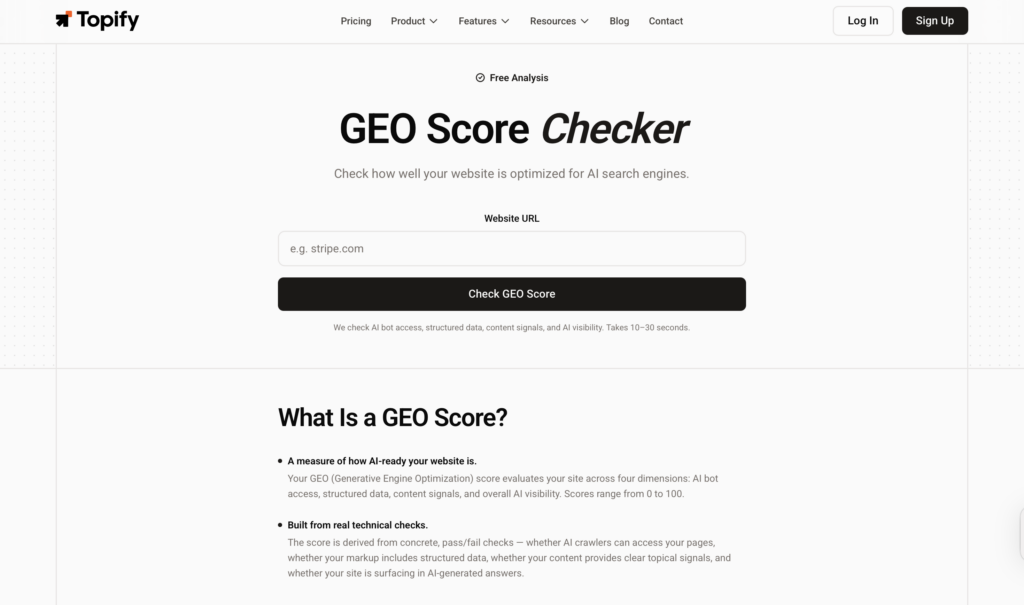
    That’s the gap a GEO score is built to expose. And the good news: you don’t need a paid platform to run your first diagnostic. A handful of free tools can generate a baseline report in under 10 minutes. Here’s exactly how to use them.

    Your Google Rankings Don’t Predict Your GEO Score

    Only about 12% of URLs cited by ChatGPT and Perplexity actually come from the Google Top 10. That number should stop most SEO teams in their tracks.

    Traditional search was built for the “ten blue links” model. Success meant backlinks, keyword density, and crawlability. Generative engines work differently. When someone asks ChatGPT a question, the model runs a synthesis process, pulling segments from multiple sources and reassembling them into a single answer. It’s looking for content that’s “extractable,” not just authoritative.

    The result is a visibility paradox: a brand can rank at position zero on Google and still be completely invisible in AI responses. That’s why a GEO score exists as a separate metric, and why checking it starts with a different diagnostic process entirely.

    What a GEO Score Actually Measures

    A GEO score is a composite metric that evaluates how “citable” and “extractable” your content is for large language models. Most free checker tools score across six distinct dimensions.

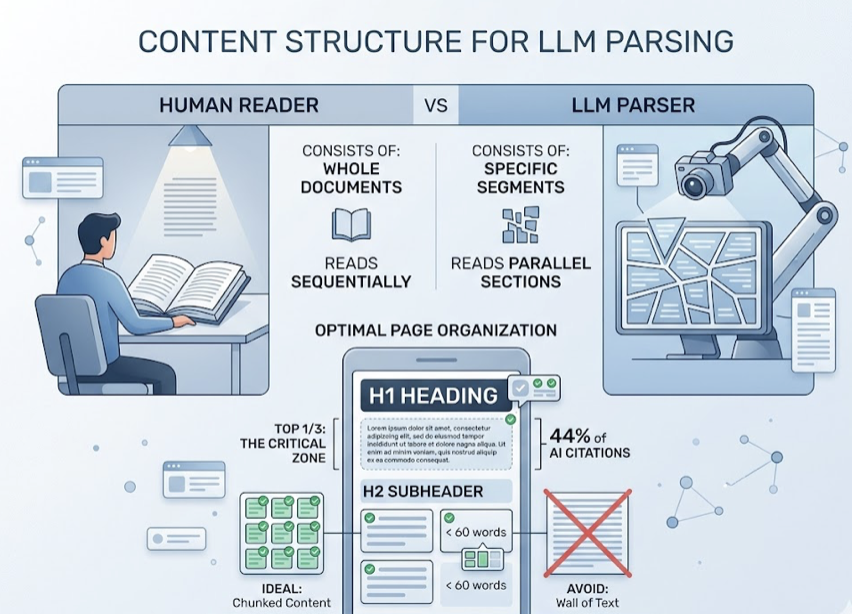
    Content Structure measures how well your page is chunked for machine reading. LLMs don’t consume pages as whole documents. They parse sections and pull specific segments. Short declarative paragraphs under 60 words, with a clear heading hierarchy (H1-H4), score significantly higher than walls of text. Research shows that 44% of AI citations are drawn from the top third of a page, making that first scroll the most critical zone.

    Schema Markup is the machine-readable bridge between your content and the AI’s interpretation of it. Pages with comprehensive JSON-LD schema are cited approximately 89% more often than those without it. FAQ, Article, HowTo, and Organization schema are the highest-impact implementations.

    Authority Signals (E-E-A-T) reflect whether your content demonstrates verifiable expertise. AI engines are risk-averse. They prefer citing sources with explicit author bylines, linked professional profiles, and clear organizational credentials. Generic content without a byline is a structural liability.

    Semantic Clarity evaluates how precisely your content defines concepts. Vague marketing language actively lowers this score. Direct factual language, with clearly stated definitions and a summary section, gives the LLM a ready-made synthesis to extract.

    Competitive Positioning measures your Share of Voice relative to competitors across the AI’s response universe. LLMs are 6.5 times more likely to cite a brand through an external authoritative source than through the brand’s own domain. If competitors dominate Reddit threads and industry publications, your content score won’t offset that gap.

    Factual Density is often cited as the most influential dimension. The Princeton and Georgia Tech research (Aggarwal et al., 2023) found that adding statistics to content can improve AI visibility by up to 40%. Specific data points, verifiable figures, and expert quotations make content far more “quotable” to a synthesis engine.

    Step 1: Pick Your Free GEO Score Checker

    Four tools cover the main diagnostic needs without requiring a paid account.

    ToolWhat It ChecksFree TierBest For
    RateMyGEO5-metric report scored against ChatGPT, Claude, PerplexityFully free, no signupBeginners wanting a complete first report
    Geoptie6-dimension holistic audit (technical + content)Free standalone audit, no signup requiredTechnical SEOs and SMBs
    FraseContent structure and semantic coverageLimited scansContent writers focused on citability
    HubSpot AEO GraderBrand sentiment and recognition across 3 AI models100% free, brand name inputMarketing leads tracking brand perception

    For a first-time GEO audit, RateMyGEO is the clearest starting point. It’s built for tactical execution and generates actionable recommendations rather than just scores. Geoptie is the better choice if your priority is technical validation, specifically crawlability and structured data compliance.

    Step 2: Run Your First GEO Audit in Under 10 Minutes

    The process is faster than most traditional SEO audits because GEO checkers focus on a single page’s “answer-readiness” rather than site-wide crawl data.

    Using RateMyGEO:

    Open the tool and paste your target URL. The focus should be a specific landing page or blog post, not your homepage. The tool simulates how bots like PerplexityBot or GPTBot actually perceive the page, which is why URL-level analysis matters more than domain-level.

    The scan takes roughly 60-90 seconds. While it runs, the tool checks for three high-impact signals specifically: the presence of FAQ sections with clear question-answer pairs, author credentials linked to a biographical schema, and statistical evidence within the first 200 words.

    Once complete, you’ll see a composite score from 0 to 100, broken down by dimension.

    Using Geoptie for Technical Validation:

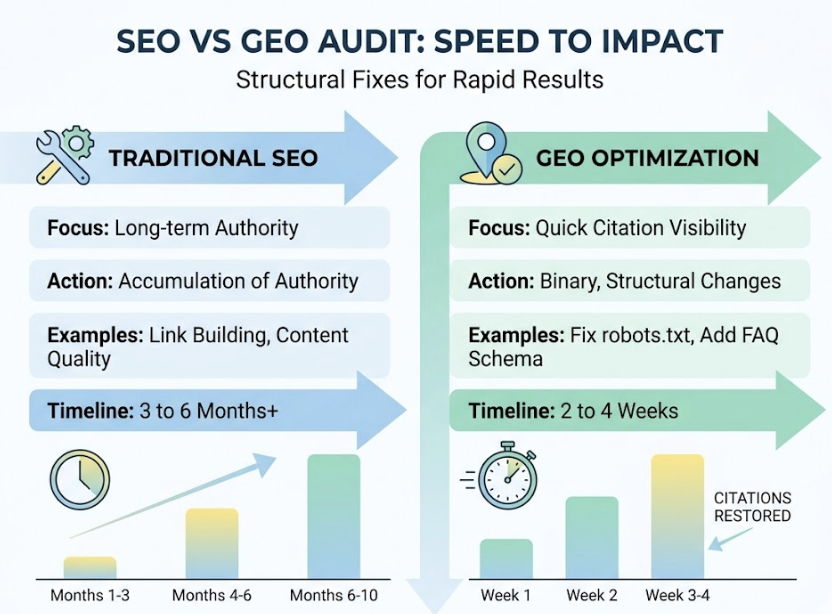
    Geoptie is worth running in parallel for its technical layer. Paste the same URL. The tool specifically checks whether AI crawlers are blocked (robots.txt issues), whether your schema is correctly implemented, and whether the content passes the “interpretability” threshold. These are binary fixes if you find failures, and they tend to have the fastest ROI of any GEO improvement.

    Step 3: Read the Report Without Getting Lost

    Score ranges follow a consistent threshold across most GEO diagnostic tools.

    86-100 (Excellent): Your content is already structured for AI citation. The priority here is recency. About 50% of content cited by generative engines is less than 13 weeks old. A high score doesn’t mean passive management works.

    61-85 (Good): You’re AI-ready but likely losing ground on competitive positioning or factual density. These aren’t structural failures. They’re optimization gaps that require targeted content engineering rather than a rebuild.

    Below 60 (At-Risk): Content in this range is often invisible to generative engines. The most common causes are long paragraphs without H2/H3 hierarchy, missing or broken schema, and a complete absence of external citations or author authority signals.

    Decoding specific low scores:

    If your Structure score is low, the fix is usually linguistic. Break paragraphs into 2-3 sentences. Add a bulleted “Key Takeaways” section at the top of the page. The “Cite Sources” approach identified in Princeton’s research produced a 115.1% visibility boost for lower-ranked websites. That’s the gold standard for this dimension.

    If your Schema score is low, it’s a technical fix that can often be deployed via a plugin like Rank Math. Implement Article and FAQ schema first. It’s a binary change with immediate machine-readability gains.

    If your Authority score is low, the issue is external footprint. Generic content without author attribution, expert quotes, or links to academic or government sources loses the credibility signal LLMs rely on. Citing a named expert with a title is more effective than citing an unnamed study.

    One Blind Spot Free Tools Can’t Catch

    Here’s what every GEO score checker measures: the quality of your content as an input to AI systems.

    Here’s what none of them measure: whether AI is actually mentioning your brand in live responses.

    These are two separate questions. A brand can have a score of 85 on RateMyGEO and still have a mention rate of zero. That happens when the external footprint is weak: your content is technically AI-ready, but competitors dominate the Reddit threads, press coverage, and industry reports that LLMs actually pull from. Since AI models trust third-party authoritative sources 6.5 times more than your own domain, a high content score doesn’t guarantee your brand appears when the query is asked in real time.

    The calculation is: Visibility Rate = (Queries mentioning the brand / Total queries in the test set) × 100. Free checkers don’t run that calculation.

    That’s where Topify’s GEO Score Checker fills the gap. While tools like RateMyGEO analyze what your content looks like to AI, Topify tracks what AI actually says about your brand across ChatGPT, Gemini, Perplexity, and other platforms in real time. It monitors Sentiment (is AI recommending you or merely mentioning you as a budget alternative?), Position (where do you rank in AI responses relative to competitors?), and Source Analysis (which third-party domains are shaping how AI describes your brand?).

    Content score and mention rate are two legs of the same diagnostic. You need both to understand where you actually stand.

    Turn Your Score Into a 3-Tier Action Plan

    Not all GEO improvements deliver the same return. Prioritize by effort-to-impact ratio.

    Tier 1: High ROI, Low Effort (fix this week)

    Schema markup is the fastest lever. Implementing Article and FAQ schema is often a one-hour technical task that immediately improves interpretability. Also check robots.txt to confirm GPTBot and PerplexityBot aren’t accidentally blocked. That’s a binary fix with massive implications for your mention rate.

    Tier 2: High ROI, Moderate Effort (content engineering)

    Factual enrichment is the “gold standard” for citation likelihood. Go through your highest-traffic pages and systematically add specific statistics, named expert quotes, and data-backed claims. Rewrite section intros to lead with a direct answer in the first 40-60 words. That “answer-first” structure is what RAG systems pull most reliably.

    Tier 3: Long-Term Investment (authority building)

    Your external footprint determines your competitive positioning score. Industry publications, guest contributions, and presence in community discussions (Reddit, forums, Quora) are the sources LLMs trust most. This dimension can’t be optimized overnight, but it’s the one that protects your mention rate from competitors who are actively building it.

    Conclusion

    A GEO audit isn’t a one-time project. It’s the starting point for a new measurement discipline. Free tools like RateMyGEO and Geoptie give you the content-layer baseline: what your pages look like to AI bots, where the structural and technical gaps are, and which fixes will move the needle fastest.

    That said, content score and brand visibility aren’t the same metric. Checking your GEO score is step one. Understanding whether AI is actually recommending you, and how often, is step two. The brands building durable AI visibility are running both diagnostics. Start with the free audit, fix the quick wins, then layer in the mention-rate tracking to close the loop.

    FAQ

    What’s a good GEO score? 

    Scores above 85 are considered excellent across most diagnostic frameworks, indicating content that is best-in-class for AI citation. Scores between 61 and 85 are solid but require competitive optimization. Anything below 60 typically signals structural or technical issues that make the content invisible to generative engines.

    How often should I check my GEO score? 

    Run a comprehensive GEO audit quarterly. Because models like Perplexity and ChatGPT exhibit a recency bias (50% of cited content is under 13 weeks old), citation performance can shift faster than traditional SEO rankings. For core high-intent queries, tracking brand mention frequency weekly is worth the overhead.

    Do GEO score checker tools work for all content types? 

    Yes. Free checkers can analyze blog posts, landing pages, service pages, and e-commerce product pages. AI Overviews are increasingly triggered for commercial and transactional queries, not just informational ones, so GEO optimization applies across the full content funnel.

    Is GEO score the same as AI search visibility? 

    No, and this distinction matters. A GEO score measures the quality of your content as an input to AI systems. AI search visibility measures whether your brand actually appears in AI responses. You need both diagnostics to get a complete picture. Free tools typically cover the former; platforms like Topify cover the latter.

    Can I check a competitor’s GEO score? 

    Yes. Most URL-based tools like Geoptie accept any public URL, so competitive benchmarking is possible. Understanding why a competitor scores higher in Structure or Schema often reveals specific technical improvements you can replicate quickly.

    Read More

  • Claude 4.7 vs GPT-5.5: Who Actually Wins in 2026?

    Claude 4.7 vs GPT-5.5: Who Actually Wins in 2026?

    Both launched within a week of each other. Both offer a 1,000,000-token context window. Both charge $5.00 per million input tokens. On paper, the spec sheet makes the choice look like a coin flip.

    It isn’t.

    Beneath the pricing parity, a measurable performance gap has emerged across benchmarks, real-world coding tasks, and total cost of ownership. The difference between choosing the right model and the wrong one isn’t bragging rights — for teams running high-volume agentic workflows, it can translate to a cost variance of over 300% in production.

    Here’s what the data actually shows.

    The Claude 4.7 vs GPT-5.5 Spec Sheet: What Parity Looks Like (and Where It Ends)

    Claude Opus 4.7 launched on April 16, 2026. GPT-5.5 followed seven days later on April 23. Both arrived with identical context windows and the same entry-level API rate.

    SpecificationClaude Opus 4.7GPT-5.5
    Release DateApril 16, 2026April 23, 2026
    Context Window1,000,000 tokens1,000,000 tokens
    Max Output128,000 tokens128,000 tokens
    Input ModalitiesText, Image, PDF, CodeText, Image, Audio, Code
    Core ArchitectureAdaptive ThinkingAgentic Reasoning (“Spud”)

    The surface-level similarity is intentional. Both Anthropic and OpenAI have converged on the same frontier spec as a baseline. The actual differentiation lives in architecture, and that difference shows up fast when you push either model into production.

    Benchmark Scores: Where Claude 4.7 Leads and Where GPT-5.5 Pulls Ahead

    The 2026 benchmark landscape reveals a pattern of “specialized dominance” rather than one clear winner across all tasks. Claude Opus 4.7 holds a consistent edge in hard scientific reasoning and precision engineering. GPT-5.5 dominates in autonomous tool use and terminal-based orchestration.

    BenchmarkClaude Opus 4.7GPT-5.5Winner
    GPQA Diamond94.2%93.6%Claude (+0.6%)
    HLE (no tools)46.9%41.4%Claude (+5.5%)
    HLE (with tools)54.7%52.2%Claude (+2.5%)
    SWE-Bench Pro64.3%58.6%Claude (+5.7%)
    FinanceAgent v1.164.4%60.0%Claude (+4.4%)
    Terminal-Bench 2.069.4%82.7%GPT (+13.3%)
    τ²-Bench (Telecom)88.6%98.0%GPT (+9.4%)
    ARC-AGI-268.3%83.3%GPT (+15.0%)
    OSWorld-Verified78.0%78.7%GPT (+0.7%)
    MMMU (Vision)91.5%~92.4%GPT (slight)

    The margin that matters most for engineering teams: SWE-Bench Pro at 64.3% for Claude vs. 58.6% for GPT-5.5 is a 5.7-point gap in real-world codebase navigation. For autonomous tool orchestration, GPT-5.5’s Terminal-Bench 2.0 score of 82.7% versus Claude’s 69.4% is a 13-point lead that compounds across every automated pipeline run.

    Neither model is universally superior. The question is which benchmark reflects your actual workflow.

    Claude 4.7’s “Adaptive Thinking” vs GPT-5.5’s “Spud” Architecture

    Claude Opus 4.7 introduces Adaptive Thinking, a mechanism that dynamically allocates internal reasoning tokens based on prompt complexity. In practice, it pauses on ambiguous architectural decisions rather than charging forward with a potentially destructive assumption.

    GPT-5.5’s “Spud” architecture is optimized for momentum. It’s designed to keep tasks moving as an autonomous agent, which makes it faster at execution but more likely to miss edge cases that require deliberate internal verification.

    On ARC-AGI-2 — a test of novel out-of-distribution reasoning — GPT-5.5 scores 83.3% vs Claude’s 68.3%. That’s a meaningful lead in “cold start” logic. For multi-step architectural refactoring that requires domain knowledge already in context, Claude’s thoroughness pays off.

    The Real Pricing Comparison: Why $5/MTok Tells Half the Story

    Both models list at $5.00 per million input tokens. That number is accurate and also almost irrelevant for high-volume users.

    Pricing DimensionClaude Opus 4.7GPT-5.5Impact
    Input (per 1M tokens)$5.00$5.00Parity on short context
    Output (per 1M tokens)$25.00$30.00GPT is 20% higher per output token
    Long Prompt Surcharge2x above 200K tokensNoneClaude: $10/MTok input, $37.50/MTok output
    Prompt Caching90% savingsAvailable (variable)Critical for RAG/coding agents
    Batch Discount50%50%Standard for async workflows
    Tokenizer Efficiency1.0x–1.35x baseline~0.6x (optimized)GPT is ~2x more efficient per string

    Claude 4.7’s new tokenizer improves accuracy but reduces token density. For the same Python code or English text, Claude can consume between 1.0x and 1.35x more tokens than its previous generation. GPT-5.5 runs in the opposite direction: it produces 72% fewer output tokens than Claude 4.7 for identical tasks.

    That efficiency gap compounds fast. A software engineering agent running 500 tasks per day hits an estimated monthly cost of ~$4,050 on Claude Opus 4.7 without caching. The same workload on GPT-5.5, factoring in token efficiency and the absence of long-prompt surcharges, comes in significantly lower.

    One important offset: Claude’s 90% prompt caching discount is aggressive. For RAG workflows or agentic loops with high context reuse, that discount can partially close the efficiency gap.

    Speed and Reliability: The Latency Gap That Shapes User Experience

    Time-to-first-token (TTFT) has split into two separate metrics in 2026: one for interactive experiences, one for background automation. Claude and GPT-5.5 are optimized for opposite ends of that spectrum.

    Claude Opus 4.7 streams its first token in approximately 0.5 seconds. For live customer support, real-time coding assistance, or chat interfaces, that speed creates a near-instant response feel. GPT-5.5’s TTFT baseline sits around 3.0 seconds — acceptable for background agents, but noticeably sluggish for interactive use cases.

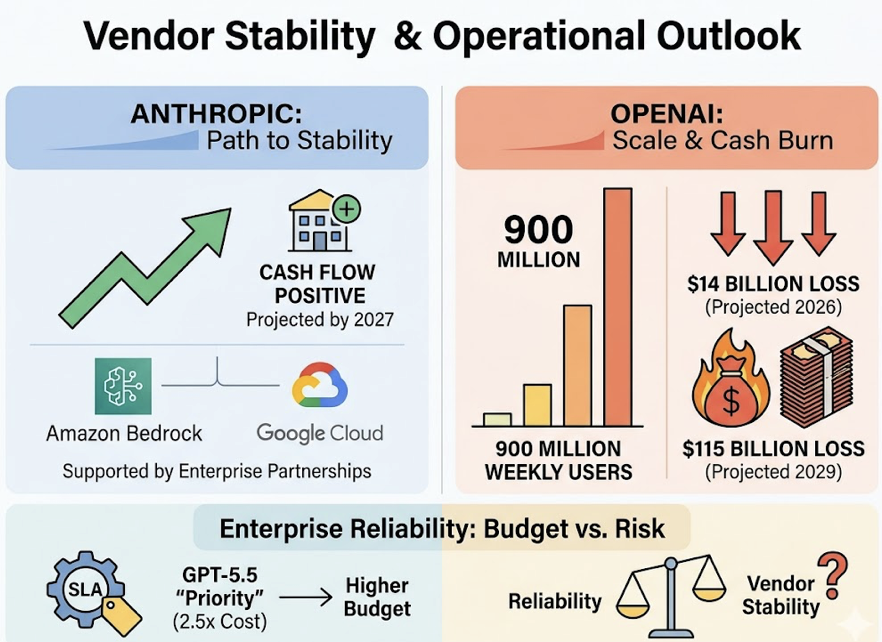
    For enterprises concerned about vendor stability: Anthropic is projected to reach positive cash flow by 2027, backed by enterprise partnerships via Amazon Bedrock and Google Cloud. OpenAI serves 900 million weekly active users but is projected to burn $14 billion in 2026, with cumulative losses potentially reaching $115 billion by 2029. GPT-5.5’s “Priority” tier (at 2.5x standard cost) provides SLA-backed reliability for mission-critical workloads — but that’s an additional budget line worth factoring into enterprise procurement decisions.

    Where Claude 4.7 Wins: The Case for Precision Over Speed

    Claude Opus 4.7 is the better tool when the cost of a mistake is high.

    Its 64.3% score on SWE-Bench Pro makes it the most reliable option for multi-file architectural changes where a single regression bug can block a release. It maintains stronger coherence for projects exceeding 10,000 lines of code, with higher retrieval accuracy for context buried in the middle of long files.

    For legal and financial analysis, Claude’s self-verification mechanism — double-checking citations and logic before finalizing a response — measurably reduces hallucination rates compared to the more execution-forward GPT-5.5.

    For content and marketing teams, Claude 4.7 holds an edge in long-form writing. It maintains structural integrity for documents exceeding 1,500 words and adheres more reliably to “negative constraints” — if you tell it not to use certain terms or writing styles, it sticks to those instructions with greater fidelity than GPT-5.5.

    Its 3.75-megapixel vision input also makes it the stronger choice for extracting data from dense financial charts, medical diagrams, or complex architectural blueprints.

    Where GPT-5.5 Wins: The Case for Velocity and Scale

    GPT-5.5 is the better tool when throughput matters more than thoroughness.

    Its 82.7% on Terminal-Bench 2.0 is the benchmark that defines agentic workflow performance in 2026. For data pipelines, server maintenance, and multi-step web research with browsing tools, GPT-5.5 is the safer operator. Its native integration with Google Sheets and Excel allows it to function as a junior analyst — building workbooks, linking formulas, and generating dashboards without human intervention.

    The token efficiency advantage is compounding at scale. For teams running millions of tokens per day in background loops, Claude’s long-prompt surcharge and higher tokenizer density make GPT-5.5 the only economically viable option for large production pipelines. Paying 20% more per output token is manageable at low volume; it becomes a budget problem at enterprise scale.

    For audio input workflows, GPT-5.5’s native audio modality support is also a structural advantage Claude 4.7 doesn’t yet match.

    Which Model to Use: A Decision Guide by Team Type

    The right choice depends on what you’re optimizing for: precision or throughput, interactive latency or batch efficiency, vendor stability or ecosystem depth.

    For developers and technical teams: Default to GPT-5.5. Its speed, token efficiency, and tool orchestration performance make it the better general-purpose operator for coding agents and CI/CD pipelines. Switch to Claude 4.7 for architectural refactors, security audits, or any multi-file reasoning where a single mistake has downstream costs.

    For marketing and content teams: Default to Claude 4.7. Its long-form writing quality, negative constraint adherence, and deep document analysis are currently ahead of GPT-5.5 for whitepaper-grade content. Use GPT-5.5 for high-volume data analysis, competitor research synthesis, or spreadsheet automation.

    For enterprise IT procurement: Claude 4.7 carries lower long-term vendor risk, given Anthropic’s financial trajectory and Constitutional AI safety framework. If your organization is already deep in the OpenAI ecosystem and needs high-throughput consumer-facing access, GPT-5.5 Priority remains viable — but budget the 2.5x premium.

    The optimal strategy for 2026 isn’t picking one. Leading engineering teams are implementing model routing layers: GPT-5.5 for execution and information gathering, Claude 4.7 for review and high-stakes logic verification. The two models are increasingly used as complements, not competitors.

    Your Brand’s Visibility Across Both Models: The Metric You’re Not Tracking

    Choosing between Claude 4.7 and GPT-5.5 is a model selection decision. But there’s a separate question most teams aren’t asking yet: which model is recommending your brand, and how?

    AI engines like ChatGPT and Claude are now responsible for over 50% of B2B software research in 2026. A brand may be the default recommendation in GPT-5.5 because it has strong structured directory presence, while being ignored by Claude 4.7 because it lacks narrative clarity in long-form sources. That visibility gap is invisible to traditional SEO dashboards.

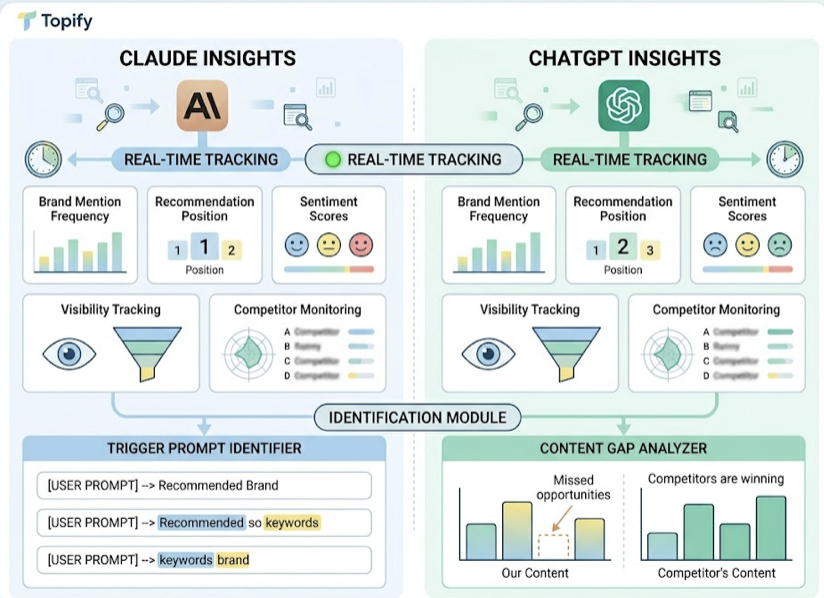
    Topify tracks brand mention frequency, recommendation position, and sentiment scores across both Claude and ChatGPT in real time. Its Visibility Tracking and Competitor Monitoring features let marketing teams identify exactly which trigger prompts lead to a recommendation and which content gaps are causing Claude or GPT to surface a competitor instead.

    As both models continue to iterate, their recommendation maps shift. Monitoring both separately gives teams the data to close the visibility gap before it becomes a revenue gap.

    Conclusion

    The 2026 model decision isn’t about which system has the better MMLU score. It’s about matching architecture to workload. GPT-5.5’s token efficiency, tool orchestration, and execution speed make it the engine for automated, high-volume pipelines. Claude 4.7’s reasoning depth, self-verification, and long-form precision make it the right tool for work where a single error carries real cost.

    For most teams, the answer is both: GPT-5.5 as the operator, Claude 4.7 as the reviewer. The next layer of competitive advantage isn’t choosing between them — it’s tracking how each model presents your brand to the millions of users who now start their research in AI search rather than Google.

    FAQ

    Q: Is Claude 4.7 better than GPT-5.5 for coding? 

    A: It depends on the task type. Claude 4.7 leads in code review, architectural refactoring, and catching subtle edge cases (SWE-Bench Pro: 64.3% vs 58.6%). GPT-5.5 is the stronger operator for high-velocity feature builds, tool orchestration, and automated pipelines (Terminal-Bench 2.0: 82.7% vs 69.4%). For most engineering teams, the optimal approach is using both in sequence.

    Q: Which model has lower API costs in 2026? 

    A: Both start at $5/MTok input, but GPT-5.5 is significantly cheaper for long-context and high-volume workloads. It produces 72% fewer output tokens for identical tasks and carries no surcharge for prompts over 200K tokens. Claude 4.7 applies a 2x premium on long prompts ($10/MTok input, $37.50/MTok output), which becomes a major budget factor in large codebases or document-heavy workflows.

    Q: Can I use both Claude 4.7 and GPT-5.5 in the same workflow? 

    A: Yes, and it’s increasingly standard practice. The 2026 best-practice pattern is model routing: GPT-5.5 handles information gathering, drafting, and execution; Claude 4.7 handles final logic verification, architectural review, and polishing. The two models’ complementary strengths make them more effective in combination than either is alone.

    Q: How do I know which AI model recommends my brand more often? 

    A: Platforms like Topify track brand mention frequency and recommendation position across both Claude and ChatGPT separately, providing real-time visibility scores and sentiment analysis. This data is not available through traditional SEO tools, which don’t measure how generative models present your brand in their answers.

    Read More

  • What Is a GEO Score? Your 0-100 AI Visibility Rating

    What Is a GEO Score? Your 0-100 AI Visibility Rating

    Your content ranks on Google. Your domain authority is solid. And yet ChatGPT, Perplexity, and Gemini never mention your brand.

    That’s not a content quality problem. That’s a measurement problem.

    You’ve been optimizing for a system that no longer controls the majority of high-intent discovery, and until now, you haven’t had a number that tells you exactly how far behind you are. The GEO Score fixes that.

    GEO Score Is Not an SEO Metric. Here’s What Makes It Different.

    A GEO Score is a 0-100 composite rating that measures how likely AI search engines are to cite your content when generating answers. It’s built specifically for generative engines like ChatGPT, Claude, Perplexity, and Gemini, which operate on fundamentally different logic than traditional search.

    Here’s the gap most marketing teams don’t see: roughly 73% of brands ranking on Google’s first page have zero mentions in AI-generated responses for the same queries. Only 17% of AI Overview citations overlap with top-tier organic rankings. High SEO performance and high AI visibility are not the same thing.

    The core difference comes down to how each system decides what to show. Traditional SEO ranks a list of links based on keyword matching and backlink graphs. Generative engines don’t produce ranked lists. They select one authoritative answer. If you’re not in that answer, you’re functionally invisible, regardless of where you sit in organic results.

    DimensionTraditional SEOGEO
    Primary GoalRank pages in a link list to drive clicksBe selected and cited as a source in an answer
    Success MetricPosition, impressions, CTRCitation frequency, brand mention rate, Share of Voice
    Visibility ModelGradient (Position 1 beats Position 5)Binary: included in the answer or excluded
    Trust SignalBacklink volume and domain authorityEntity clarity, factual density, consensus verification
    User InteractionClicks to external websitesAnswers consumed within the AI interface

    That binary nature is exactly what the GEO Score measures: not your position in a list, but your probability of being selected as a source at all.

    The 4 Dimensions That Make Up Your Score

    The 0-100 rating is built from four dimensions. Each reflects a different stage of how AI engines evaluate and use your content.

    Technical Foundation

    AI crawlers like GPTBot and PerplexityBot don’t browse the way humans do. They need explicit access in your robots.txt, fast load times, and content that renders without JavaScript dependencies. Pages with a Largest Contentful Paint above 4 seconds are 72% less likely to be cited due to retrieval timeouts alone. Schema markup in JSON-LD acts as a direct feed to RAG engines, reducing the AI’s cognitive load and cutting hallucination risk.

    AI Readability

    Generative models favor what researchers call “atomic knowledge blocks”: self-contained passages of 150 to 300 words that make sense even when extracted out of context. Leading with a direct answer in the first 40 to 60 words improves citation probability by 27%, according to a Princeton study. Clear H2/H3 hierarchies and comparison tables give AI models structured data they can efficiently reassemble.

    Content Quality

    For an LLM, quality isn’t about writing style. It’s about the ratio of verifiable data points to filler. The leading benchmark is one cited fact per 80 words of prose. The original GEO research found that adding statistics and expert quotations was the single most reliable strategy to boost AI visibility, achieving a 30 to 40% improvement across all tested models. Replacing vague statements with statistical anchors is the difference between content that gets cited and content that gets skipped.

    Authority and Trust

    AI models evaluate trustworthiness through E-E-A-T signals: Experience, Expertise, Authoritativeness, and Trustworthiness. In 2026, 96% of AI citations originate from sources with demonstrably strong E-E-A-T. Brand mentions on platforms like LinkedIn, YouTube, and Wikipedia are 3x more predictive of AI citations than traditional backlinks. Consistent entity data across the web reinforces recognition.

    Content quality and AI readability together typically account for more than half the composite score.

    Scoring Below 70? That Number Isn’t Random.

    The 70 mark reflects the statistical threshold at which consistent citation across major AI engines becomes likely. It’s the single most actionable benchmark in a GEO audit.

    Scores between 0 and 49 indicate fundamental structural or technical problems. AI systems generally treat brands in this range as unrecognizable or untrustworthy. Common causes: blocking AI crawlers in robots.txt, or producing purely narrative content with no extractable facts.

    Scores between 50 and 69 represent fragmented presence. The site has a foundation, but significant gaps remain. Citation is sporadic. A brand might appear in some query runs and disappear in others, often because entity signals are inconsistent across third-party platforms.

    Scores between 70 and 89 cross the visibility threshold. Content is well-optimized, factual density is solid, and AI engines recognize the brand as an authority. Minor updates like refreshing data every 30 days are typically enough to push toward dominance.

    Scores of 90 and above reflect best-in-class optimization. AI engines treat these sources as “grounding sources” and tend to surface them first or second.

    The stakes are concrete. Research into AI shortlists shows that 71% of all product recommendations go to the top 3 brands identified by the model. Brands below the 70-point threshold get eliminated from consideration before a user ever visits their website.

    Invisible to AI means invisible to the decision.

    ChatGPT Has 900M Weekly Users. Are You in Their Answers?

    The urgency around GEO Scores isn’t driven by speculation. It’s driven by adoption numbers that have already restructured how people find information.

    ChatGPT reached 800 to 900 million weekly active users, doubling its scale in under a year. Perplexity processed 780 million queries monthly, a 239% increase in volume over ten months. Google AI Overviews now engage 2 billion monthly users across 200 countries, appearing in 25 to 50% of all searches.

    The result is a zero-click reality. 93% of queries in Google’s AI Mode and 82% of ChatGPT Search interactions end without a click to an external website. If your brand isn’t cited in the generated response, the user never sees you.

    The B2B numbers are especially stark. 73% of B2B buyers now use AI tools throughout their purchase research process. 47% of consumers say AI-generated summaries influence which brands they trust first. 25% of B2B buyers already use generative AI over traditional search for early-stage vendor research.

    Brands that wait until AI search accounts for most of their traffic to start measuring GEO will be years behind in building the citation authority required to compete.

    How to Check Your GEO Score in Under 30 Seconds

    The GEO Score Checker is the fastest way to get a full AI visibility diagnostic. Enter a URL, and the tool runs live LLM API queries and vector analysis to evaluate your content the same way AI models do.

    Within 30 seconds you get a composite 0-100 score, granular breakdowns across all four dimensions, a priority improvement roadmap with specific fixes ranked by impact, and a competitor benchmarking comparison against 3 to 5 rivals.

    Unlike traditional SEO audits that surface dozens of low-priority issues, the results are designed around what actually moves citation rates. Correcting a robots.txt error or adding FAQ schema can restore citation visibility within a single crawl cycle: often 2 to 4 weeks for real-time engines like Perplexity. That’s one of the key practical advantages of GEO work. Many of the highest-impact changes are structural and binary, not the slow accumulation of authority over months.

    Your GEO Score Is a Snapshot. AI Visibility Isn’t.

    Checking your score once is a useful starting point. Treating it as a stable truth is where teams go wrong.

    Only 30% of brands stay visible from one AI answer to the next for the same prompt. 40 to 60% of cited domains change within a single month, a pattern researchers call “citation drift.” Over six months, that drift rate climbs to 70 to 90%.

    A score of 82 this week doesn’t mean you’ll hold that position next month. Competitors publish fresher data. AI model weights shift. Third-party sources that once anchored your authority get displaced by newer content.

    That’s the gap between knowing your score and maintaining AI visibility. Topify addresses this with cross-platform brand monitoring that runs rolling tracking across prompt libraries rather than one-time audits. The platform tracks sentiment shifts over time (the difference between “reliable enterprise choice” and “cost-effective but slow” carries real positioning weight), surfaces competitor displacement alerts when a rival captures your citation position, and runs source attribution analysis to identify which third-party domains are shaping how AI models describe your brand.

    Knowing your GEO Score is step one. Making sure your brand keeps appearing in AI recommendations as the landscape shifts is the ongoing work.

    Conclusion

    A GEO Score gives you something that’s been missing from most marketing stacks: a number that reflects how AI engines actually see your brand. Not how you rank in a list, but whether you’re selected as a trusted source in the answers that now drive discovery and purchasing decisions.

    The 70-point threshold is where AI visibility becomes consistent. Below it, your brand’s presence is sporadic at best. Above it, you’re in contention for the AI shortlists that 71% of product recommendations flow through.

    Check your score with the GEO Score Checker. Understand which of the four dimensions is holding you back. Then build toward the monitoring cadence that keeps you visible as AI recommendations continue to shift.

    FAQ

    What’s a good GEO score? A score of 70 or higher is the threshold for consistent AI visibility. Scores above 85 are typical of category leaders who publish definitive data and structured, extraction-ready content. Market leaders in 2026 generally maintain averages above 85 across their target prompt sets.

    How is a GEO score different from domain authority? 

    Domain authority measures backlink strength to predict search ranking potential. GEO Score measures content clarity, factual density, and structural extractability to predict citation probability in AI-generated answers. There’s often a negative correlation between the two: high-DA sites frequently score poorly on GEO because they’re built for click-through, not AI extraction.

    How often should I check my GEO score? 

    Monthly is the minimum. Weekly automated tracking is the recommended cadence in competitive categories, given that 40 to 60% of cited domains shift within a single month. A one-time audit tells you where you stand today, not where you’ll be when your competitor refreshes their data next week.

    Can a high GEO score guarantee AI citation? 

    No. LLM outputs are probabilistic by nature, and no tool can guarantee a specific outcome. A high GEO Score maximizes the probability of selection and helps ensure that when your brand is cited, the information presented is accurate and favorable.

    What’s the fastest way to improve a low GEO score? 

    Technical and structural fixes offer the highest return. Rewriting the first 100 words of a page to lead with a direct, fact-dense answer and implementing FAQPage schema typically restore citation visibility within weeks. Unblocking AI crawlers in robots.txt is often the single highest-impact binary fix, with results visible within one crawl cycle.

    Read More

  • Your Brand Ranks #1 on Google. Claude Ignores It.

    Your Brand Ranks #1 on Google. Claude Ignores It.

    Your domain authority is 72. Your top keyword holds position one. You’ve earned backlinks from TechCrunch, G2, and a dozen industry blogs. Then a prospect types “what’s the best [your category] tool?” into Claude — and gets a list of five recommendations. Your brand isn’t one of them.

    That’s not an SEO failure. It’s a different problem entirely. And the gap between a strong Google presence and solid Claude AI brand visibility is wider than most marketing teams realize — because the two systems don’t share the same logic, the same inputs, or the same definition of “authority.”

    Google and Claude Don’t Read the Same Playbook

    Google is, at its core, a retrieval engine. It crawls, indexes, and ranks web pages based on measurable signals: backlink quality, keyword relevance, domain authority, page speed, structured data. The goal is to surface the most relevant URL for a given query. Success means ranking on page one.

    Claude works differently. It doesn’t retrieve URLs — it synthesizes conclusions. Using a combination of its pre-trained parametric knowledge and real-time Retrieval-Augmented Generation (RAG), it constructs a response based on what it has learned about a topic and what it can verify in the moment. The output isn’t a list of links. It’s a recommendation.

    That distinction creates a structural gap. A page optimized for Google’s crawler — tight keyword density, internal linking, clean schema markup — isn’t automatically useful to Claude’s reasoning layer. Claude is looking for something else: dense factual claims, consistent entity signals across multiple sources, and evidence that the broader internet agrees a brand is credible.

    The metrics that predict Google rankings and the signals that drive Claude AI brand visibility overlap by roughly 54%. That leaves a 46% gap that no amount of traditional SEO addresses.

    What Claude Actually “Sees” When Someone Asks About Your Category

    Claude’s recommendations aren’t random. They emerge from two layers of knowledge working in parallel.

    The first is parametric knowledge — everything Claude absorbed during pre-training. This includes structured sources like Wikipedia, archived news, industry whitepapers, Reddit threads, and books. Brands that appeared frequently and consistently in high-quality training data carry a significant advantage. Wikipedia, in particular, carries outsized weight in Claude’s authority evaluation due to its structured, human-verified format.

    The second layer is real-time retrieval. When Claude searches the web to supplement its response, it doesn’t use Google. Research analysis shows that Claude’s cited results overlap with Brave Search’s top 15 organic results at a rate of 86.7%. Brave runs its own independent index, with a crawl bias toward original content over aggregator sites, and lower dependence on traditional backlink signals.

    That’s a critical implication. Brands optimizing purely for Google’s index may not appear in the information layer Claude actually reads.

    On top of this, Claude’s Constitutional AI framework applies a reliability filter to every source it considers. Content that appears overstated, inconsistently sourced, or commercially self-serving gets deprioritized. Brands that acknowledge limitations and trade-offs in their own content are cited at 1.7x the rate of brands that don’t — because Claude treats intellectual honesty as a proxy for credibility.

    5 Reasons Your SEO Content Doesn’t Land in Claude’s Answers

    Your content is optimized for keywords, not citations

    Traditional SEO rewards keyword density and topical clusters. Claude’s RAG layer is looking for “atomic facts” — compact, verifiable claims that can be extracted in a 200–400 word chunk and used as supporting evidence. Keyword-heavy content often reads as noise to the extraction layer. According to Princeton’s GEO research, keyword stuffing produces a negative effect on AI citation rates — as much as -10%.

    Your brand mentions live in low-authority training sources

    AI citation weight follows a power-law distribution. Mentions on low-DA directories, press release distribution platforms, or unmoderated forums carry minimal signal. Claude gravitates toward what researchers have called “aristocratic domains” — Wikipedia, Reddit, YouTube, G2, Capterra, and established news publishers. If your brand’s external footprint is mostly thin citations from sources Claude doesn’t trust, your entity lacks the social consensus needed to appear in recommendations.

    Competitors own the narrative in third-party review sites and forums

    When Claude synthesizes a recommendation, it looks for multi-source corroboration. A competitor with fifty substantive Reddit threads, detailed G2 reviews with specific use cases, and independent comparisons from credible blogs reads as the established category leader — regardless of which brand ranks higher on Google. A single high-upvote Reddit thread with genuine detail can carry more weight for Claude’s reasoning than ten commercial backlinks from high-DA domains.

    You have no presence in the sources Claude trusts most

    For high-stakes queries — enterprise SaaS, B2B tools, healthcare, finance — Claude applies stricter source requirements. It looks for academic citations, government references, analyst reports, and verified industry publications. Brands whose content strategy focuses entirely on how-to tutorials and product pages don’t establish the “trust layer” Claude requires for serious recommendations.

    Your structured data helps Google crawlers, not LLM reasoning

    Schema.org markup, JSON-LD tags, and FAQ schema make pages eligible for Google’s rich results. Claude doesn’t read JSON-LD tags. It reads prose. When a page is structured around satisfying schema requirements rather than delivering dense, logically sequenced information, Claude’s chunking process treats it as low-signal content and moves on.

    The Brands Claude Does Recommend — What They Have in Common

    Tracking Claude AI brand visibility across thousands of prompts reveals a consistent pattern among brands that appear regularly. None of these characteristics are traditional SEO signals.

    Semantic consistency across the full entity footprint. High-visibility brands maintain the same positioning across their own site, third-party coverage, and community mentions. If a brand is described as “lightweight CRM for SMBs” internally but as “enterprise-grade platform” on third-party sites, Claude’s entity resolution creates conflicting associations and the brand gets deprioritized.

    A large “digital cushion” of third-party content. The most-recommended brands have a disproportionate share of their citations coming from earned media — independent reviews, editorial coverage, forum discussions. Analysis from Beamtrace’s 2026 AI Search Report shows that third-party earned media accounts for roughly 48% of Claude’s brand citations, while official commercial pages account for about 30%, and owned blog content about 22%. Brands that rely primarily on owned content to establish their reputation face a structural ceiling.

    High information density with specific, verifiable claims. The pages Claude cites most often contain precise data: conversion rates, time-to-value benchmarks, cost comparisons, customer counts. Vague superlatives (“world-class solution,” “leading platform”) contribute nothing to Claude’s reasoning. Specific figures and named evidence do.

    Claude AI Brand Visibility Is a Measurable Metric, Not a Guessing Game

    The phrase “AI visibility” isn’t abstract. It maps to a set of trackable metrics that brands can monitor and improve over time.

    Visibility Rate measures how often a brand appears in Claude’s responses to a standardized set of category-level prompts — essentially, Share of Voice in AI answers.

    Position-Adjusted Word Count (PAWC), a metric developed in Princeton’s GEO research, weights not just whether a brand is mentioned but where in the response it appears. A brand cited first in a list carries substantially more influence than one mentioned as an afterthought.

    Sentiment Quotient tracks whether Claude’s mentions are neutral, positive, or flagged with caution. A brand can have high visibility but negative sentiment — which is often worse than being invisible.

    Source Coverage measures what percentage of Claude’s brand citations come from third-party domains versus owned content. A 100% own-site citation rate signals that the brand’s external reputation hasn’t been established.

    Topify tracks all of these metrics simultaneously across Claude, ChatGPT, Perplexity, and Gemini — running hundreds of category-level prompts at scale and mapping where brands appear, in what position, and with what sentiment. For teams that have been operating with only Google Search Console data, the gap between what they think their brand looks like and what AI systems actually say about it is often significant.

    Closing the Gap: Where to Start If Claude Doesn’t Know Your Brand

    Build citation-worthy content that third-party sources want to reference

    The core unit of GEO content isn’t an article — it’s a claim. Each piece of content should contain proprietary data, named frameworks, or specific benchmarks that other sources would quote. Implementing a Bottom Line Up Front (BLUF) structure — where the key insight appears in the first 40–60 words of each section — dramatically improves how Claude’s RAG layer extracts and cites the content.

    If your brand doesn’t have original research, commission a narrow study. A single survey with a clear finding (“72% of SEO professionals track keyword rankings but don’t monitor AI mentions”) creates a quotable data point that third-party publications will reference. Once that statistic circulates across multiple credible sites, Claude starts associating it with your brand as the originating entity.

    Expand brand presence on the domains Claude trusts

    Publishing one hundred articles on your own blog produces diminishing returns for Claude AI brand visibility. Ten deep, substantive mentions on high-trust domains produce more. The priority list: Wikipedia entity pages (correct any gaps or inaccuracies in your brand’s entry), top-tier category review platforms like G2 and Capterra, vertical industry publications, and authentic Reddit contributions in relevant subreddits. The goal on Reddit isn’t marketing — it’s substantive participation that results in genuine upvoted mentions of your brand in comparison threads.

    Also verify that your site is being crawled by Brave’s bots, not just Googlebot. Submitting your domain to Brave’s Web Discovery Project is a direct step toward improving indexing in the layer Claude actually queries.

    Monitor who Claude recommends in your category — then close the gap systematically

    This is where measurement becomes strategy. Topify’s Source Analysis feature reverse-engineers which domains Claude is citing when it recommends competitors in your category. The output is a concrete list of citation gaps: specific publications or platforms where your competitor has earned coverage and you haven’t. That’s an actionable PR and content list, not a vague directive to “build more backlinks.”

    Topify’s Competitor Monitoring tracks real-time shifts in visibility and sentiment — so when a competitor’s Claude AI brand visibility spikes after a major press mention or product review, you can identify what triggered the change and respond. The platform’s One-Click Execution layer then lets you generate GEO-structured content drafts targeting those specific gaps and deploy them without a multi-week content production cycle.

    The upstream question — why is Claude recommending them and not you? — now has a traceable answer.

    Conclusion

    Google rankings and Claude AI brand visibility solve different problems. One determines whether people can find your website when they search. The other determines whether AI systems recommend your brand when people ask for advice. In 2026, traffic from AI recommendations converts at roughly 6x the rate of standard search traffic — which means the visibility gap has direct revenue implications.

    Strong SEO is still worth building. It keeps the door open when users are navigating. But GEO is what gets you into the conversation when users are asking for a recommendation and trusting AI to give them one. Both matter. Only one of them most teams are actually measuring.

    Get started with Topify to see where your brand stands in Claude’s answers today.


    FAQ

    Q: Does good SEO automatically help with Claude AI brand visibility?

    A: Partially. Research suggests roughly 54% correlation between Google rankings and Claude citation rates — meaning strong SEO does provide some lift. But the remaining 46% is driven by factors SEO doesn’t address: third-party earned media density, multi-source entity consistency, Brave Search indexing, and the kind of factual content specificity that makes your brand citable by an LLM rather than just rankable by a crawler.

    Q: How often does Claude update its knowledge about brands?

    A: Claude operates on two update cycles. Its parametric knowledge (baked into model weights at training) updates with new model releases — roughly every six to twelve months. Its real-time retrieval layer updates near-continuously through RAG. If a brand gets covered in a high-authority source that Brave indexes, Claude can start citing that information within hours. Newer brands with no pre-training presence need to rely heavily on this real-time layer.

    Q: Can I track whether Claude mentions my brand?

    A: Not with standard tools. Google Search Console doesn’t capture impressions from Claude responses. Tracking Claude AI brand visibility requires a purpose-built GEO platform that runs structured prompt sets across AI engines and measures Share of Voice, position, sentiment, and source attribution. Topify provides this across Claude, ChatGPT, Perplexity, and Gemini from a single dashboard.

    Q: What’s the fastest way to improve Claude AI brand visibility?

    A: Prioritize “authority node coverage” over volume. Getting a substantive brand mention in one trusted domain — a top-tier industry review publication, a high-upvote Reddit thread with genuine detail, a Wikipedia entity update — typically moves the needle faster than publishing additional owned content. Pair this with a BLUF rewrite of your core product pages so Claude’s extraction layer can actually parse and cite your key claims.


    Read More

  • Claude, ChatGPT, or Perplexity: Pick Your Visibility Play

    Claude, ChatGPT, or Perplexity: Pick Your Visibility Play

    A practical 2026 guide to where your brand actually gets found, and what to do about each platform.

    Most brands treating AI visibility as a single channel are already behind.

    ChatGPT, Claude, and Perplexity don’t work the same way. They don’t pull from the same sources, they don’t serve the same users, and they don’t reward the same types of content. Treating them as interchangeable is how you end up spreading budget thin and seeing results from none of them.

    Here’s what actually separates the three, and how to decide where to focus first.


    Three Platforms. Three Different Users. Three Different Logics.

    Before you optimize for anything, understand who’s on each platform and why they’re there.

    ChatGPT has scale. It processes somewhere between 2.5 and 3 billion prompts per day, with daily active users reaching around 190 million. Users come for task execution: drafting, coding, brainstorming. The average session is 16 minutes. It’s conversational and high-frequency.

    Claude skews toward depth and decision-making. Its user base sits at roughly 19 million, which sounds modest until you see that 70% of Fortune 100 companies have it embedded in their workflows. Software development, financial services, legal, and healthcare are its home turf. Users aren’t browsing. They’re analyzing.

    Perplexity sits closest to a search replacement. Its 33 million monthly active users are researchers, professionals, and knowledge workers who want verified answers with visible sources. Every response comes with numbered citations. The referral traffic it drives has an average session time of 3 minutes 30 seconds and a bounce rate of just 32%.

    Different platforms, different stakes.


    Where Claude AI Brand Visibility Actually Comes From

    Claude’s citation behavior is more conservative than any other major AI platform. That’s not a bug. It’s a direct result of Anthropic’s Constitutional AI framework, which prioritizes accuracy and harm avoidance over comprehensiveness.

    Claude uses Brave Search for its web retrieval. That matters more than most brands realize. Research shows Claude’s citations overlap with Brave search results at a rate of 86.7%. If your brand doesn’t rank in Brave, it’s effectively invisible to Claude’s retrieval layer.

    But search indexing is only half the story. Claude performs internal cross-validation, which means a single factual error on your site (an outdated price, a feature description that doesn’t match G2) can get your entire domain flagged as unreliable.

    The content formats that earn Claude citations aren’t blog posts. Troubleshooting guides, tool and utility pages, and how-to tutorials average 5 or more citation appearances per page across 4 to 5 platforms. Standard blog articles average fewer than 1. That’s a 30 to 50x gap depending on format and depth.

    For B2B brands, there’s also a structural advantage most are ignoring. Claude Enterprise supports custom connectors via Model Context Protocol (MCP), which allows your product data, pricing, and case studies to surface in real time when an enterprise buyer is doing vendor research inside Claude. That’s not passive indexing. That’s embedded visibility.

    The bottom line for Claude: depth, accuracy, and structure aren’t optional. They’re the admission ticket.


    ChatGPT Still Has the Volume. But It’s Harder to Crack.

    ChatGPT is where most brands want to be first. It’s also where most brands fail to show up.

    Here’s the problem: ChatGPT’s recommendation logic is probabilistic and inconsistent. One study ran the same B2B software prompt 100 times and got 44 different brands mentioned across those responses. Only about 5 of them, roughly 11%, appeared in more than 80% of responses. Those brands weren’t just well-optimized. They had Wikipedia entries, thousands of third-party citations, and years of authority signals baked into ChatGPT’s pretraining data.

    That’s the entity gap. New or mid-market brands often lack the historical signal density that ChatGPT needs to classify them as trustworthy. The platform doesn’t surface brands it can’t verify, and its verification logic is heavily weighted toward pretraining data from 2022 and earlier.

    That said, there are real levers. ChatGPT’s search mode relies heavily on Bing, so activating Bing Webmaster Tools instant indexing is a concrete first step. Building presence on G2, Reddit, and high-authority vertical publications creates the third-party validation ChatGPT needs to start trusting you. The goal isn’t just content. It’s entity establishment.

    ChatGPT is worth targeting. Just don’t expect fast wins unless you’re already a recognized name.


    Perplexity Rewards Sources, Not Just Brands

    Perplexity is the most transparent AI platform operating at scale today.

    Its scoring system weighs three factors: factual accuracy (verified across multiple sources), recency (especially for fast-moving categories), and third-party corroboration from Reddit, forums, and specialist publications. It’s not just checking your website. It’s checking whether other credible voices confirm what your website says.

    This creates a genuinely different competitive environment. A well-researched article from a niche SaaS blog can outrank a Fortune 500 landing page if it’s more accurate, more recent, and more frequently cited externally. Perplexity doesn’t have the same large-brand bias baked into its pretraining because it retrieves in real time.

    The referral traffic quality reflects this. Perplexity’s year-over-year referral traffic growth has been running at 180 to 200%. More importantly, those visitors arrive with context: they’ve already read a structured AI summary of your product or topic before clicking through. That’s why session durations and conversion rates run higher than organic search.

    Plus, Perplexity’s Publisher Program launched in early 2026 added a revenue-sharing layer. When your content gets cited in an ad-supported response, you earn a cut. That’s a fundamentally different ROI model than any other AI platform offers.

    For brands with strong content assets but limited authority budgets, Perplexity is the fastest path to measurable visibility.


    The Priority Matrix: Which Platform Should You Go After First?

    Not every brand should prioritize the same platform. Here’s how to think about it:

    Brand TypePrimary PlatformSecondary PlatformWhy
    B2B SaaS / TechClaudePerplexityLong decision cycles favor depth and technical validation
    B2C / Consumer RetailChatGPTGeminiHigh-volume, broad awareness, emotional resonance
    Agencies / ConsultanciesChatGPTClaudeSpeed, creative variation, structured output
    FinTech / HealthcarePerplexityClaudeFact accuracy and source transparency are non-negotiable
    Early-stage / New BrandsPerplexityChatGPT SearchReal-time RAG bypasses pretraining bias against unknown brands

    The logic is consistent across all five: match the platform’s retrieval mechanism to your content strengths, not to where you think the most users are.


    You Can’t Prioritize What You Can’t Measure

    Here’s the thing that breaks most AI visibility strategies before they start: brands make platform decisions without any data on where they’re actually being mentioned, at what sentiment, and against which competitors.

    B2B buyers complete roughly 70% of their purchase decision before talking to sales. And 89% of those buyers use generative AI tools during their research phase. If your brand isn’t in those AI-generated answers, you’re not losing the final comparison. You’re being cut before the shortlist forms.

    Topify is built to close that measurement gap. It tracks brand visibility across ChatGPT, Claude, Perplexity, Gemini, and other major AI platforms simultaneously, running structured prompt sampling at scale to surface where your brand appears, how it’s described, and where competitors are outranking you.

    The seven core metrics it monitors: visibility share, sentiment score, position ranking, AI search volume, mention count, intent alignment, and CVR (Conversion Visibility Rate). That’s not a dashboard of vanity metrics. It’s the data layer that tells you which platform is worth doubling down on and which is underperforming despite your content investment.

    When Topify detects a visibility drop on a high-value prompt, it doesn’t just flag it. It reverse-engineers which sources are currently getting cited and surfaces specific fixes, whether that’s restructuring your above-the-fold answer, adding a comparison table, or correcting a pricing discrepancy flagged on a third-party review site.

    That’s the difference between guessing and compounding.


    Conclusion

    Claude, ChatGPT, and Perplexity each represent a different theory of how AI should answer questions. ChatGPT bets on breadth and scale. Claude bets on depth and verification. Perplexity bets on transparency and recency.

    Your brand doesn’t need to win on all three simultaneously. It needs to win first where its content strengths match the platform’s retrieval logic.

    The priority matrix gives you a starting point. The data from a tool like Topify tells you whether that starting point is actually working.

    Start measuring. Then prioritize.


    FAQ

    Is Claude AI growing faster than ChatGPT for brand mentions?

    In enterprise and professional contexts, yes. Claude’s enterprise market share grew from 12% to 32% between early 2025 and late 2025. For B2B brand mentions tied to vendor evaluation, technical documentation, and compliance use cases, Claude’s growth trajectory is outpacing ChatGPT’s in those specific segments.

    Does Perplexity actually drive traffic compared to ChatGPT?

    It drives significantly higher-quality traffic. ChatGPT tends to be a knowledge endpoint: users get their answer and don’t click through. Perplexity’s interface is built around source attribution, and its referral traffic grew 180 to 200% year-over-year. Visitors who arrive from Perplexity typically stay over 3 minutes and convert at rates that beat organic search benchmarks.

    How do I track my brand visibility across all three AI platforms at once?

    Use a dedicated AI visibility platform like Topify. It runs prompt sampling across ChatGPT, Claude, and Perplexity simultaneously, calculating sentiment, mention frequency, citation source, and competitive position from a single dashboard. Manual monitoring across three platforms isn’t scalable, and the data you’d collect wouldn’t be statistically reliable.

    Should smaller brands focus on one platform or spread efforts equally?

    Start with Perplexity. ChatGPT and Claude both carry significant pretraining bias toward established brands. Perplexity’s real-time RAG retrieval evaluates content on current accuracy and recency, not historical authority accumulation. A well-structured, fact-dense piece published this quarter can outperform content from established brands if it’s better sourced. Build your citation footprint there first, then use those authority signals to start penetrating the other platforms.


    Read More

  • Why Claude AI Recommends Some Brands Over Others

    Why Claude AI Recommends Some Brands Over Others

    The signals behind Claude AI brand visibility, and what you can do to change your position

    Your brand has a website. You publish content. You rank on Google. And yet, when someone asks Claude to recommend tools in your category, your name doesn’t come up.

    That’s not a SEO problem. It’s a different problem entirely.

    Claude doesn’t work the way Google does. The logic behind its recommendations is separate, and misunderstanding that gap is exactly why most brands stay invisible in AI-generated answers.

    Here’s what’s actually happening.

    Claude Isn’t Pulling from a Search Index

    When Claude responds to a recommendation request, it’s not querying a live database or crawling the web in real time. It’s synthesizing a response from what researchers call “parametric memory,” the patterns and associations encoded into the model’s neural weights during training.

    Think of it as sediment. Every piece of content that existed before Claude’s training cutoff left a trace. The more a brand appeared across credible, consistent sources, the deeper that trace.

    This architecture has a direct implication for brand teams: your brand’s weight in Claude’s responses was largely determined before you started optimizing for it. Claude 3.7 Sonnet’s reliable knowledge ends around October 2024. Claude 4.5 extends to January 2025. Newer models add real-time search in certain configurations via Retrieval-Augmented Generation (RAG), but even then, the base model’s pre-trained biases influence how it interprets what it retrieves.

    You’re not competing in a keyword auction. You’re competing for space in a model’s learned reality.

    The 3 Signals That Actually Shape Claude AI Brand Visibility

    Claude doesn’t rank brands by advertising spend or domain authority. Its recommendation logic reconstructs from three learned patterns.

    Mention Frequency on Trusted Third-Party Sources

    The correlation between brand mentions and AI citation probability is 0.664. The same correlation for traditional backlinks is 0.218. That gap tells the whole story.

    Claude treats a mention on a high-authority domain as a qualitative signal of trust, not just a navigational pointer. Wikipedia currently accounts for roughly 13% of AI model citations. Reddit’s share grew 87% in 2025 and now represents over 10% of ChatGPT citations, with similar patterns showing in Claude’s responses for community-driven queries.

    The implication: it’s not about how many pages your brand owns. It’s about how many credible, independent sources reference you, and in what context.

    Contextual Consistency Across Sources

    If your brand is described as “an enterprise data integration platform” on your website but “a workflow automation tool” on G2 and “an ETL solution” on Reddit, Claude’s model faces conflicting signals. The result is lower confidence in any recommendation.

    This is what researchers call “entity blending,” where the model either avoids citing the brand altogether or misattributes its features to a competitor. Consistent category language across LinkedIn, Crunchbase, review platforms, and media coverage reduces that ambiguity significantly.

    Schema alignment matters here too. Implementing structured data that mirrors your visible content gives the model a cleaner extraction surface.

    Category Association and Prompt Relevance

    Claude maps brands to topic clusters based on their relationship to adjacent concepts in the training data. If your brand is consistently co-mentioned with “zero-trust architecture” and “enterprise cybersecurity” in technical publications and forum discussions, Claude learns to surface you when those prompts appear.

    This is niche positioning at the model level. And it explains why a smaller brand with precise topical coverage can outperform a much larger competitor relying on broad, generic positioning.

    Being Online Is Not the Same as Being Recommended

    This is the finding most brand teams find uncomfortable: 73% of brands have zero mentions in AI-generated responses despite ranking on page one of traditional search results.

    It’s not a measurement error. It’s a structural gap.

    Traditional SEO satisfies crawlers. Claude’s recommendation logic satisfies a different standard: semantic authority. The degree to which a brand is treated as the definitive answer to a problem across independent digital discourse.

    The core issue is the over-reliance on owned media. Your website, your blog, your branded content. Claude’s Constitutional AI training actively filters for commercial bias, which means self-promotional content is processed with skepticism built in.

    The data confirms this. Promotional tone in content has a -26.19% correlation with citation probability. That means typical marketing copy, the kind most brands default to, is actively working against AI visibility.

    On the flip side, third-party sources account for 80-85% of AI citations. Your own domain contributes 15-20% at most, and primarily for technical specifications, not authority signals.

    Why Competitor Brands Keep Showing Up Instead

    When a user asks Claude for a recommendation, the model typically surfaces three to five brands. Not ten. Not twenty.

    That compression is important. The “ten blue links” of Google become a winner-take-all scenario in generative responses. If your competitor is in that shortlist and you’re not, you don’t just lose visibility. You effectively don’t exist for that user’s decision.

    Competitors who dominate these responses typically share one characteristic: a stronger external signal network. More “best of” list inclusions. More independent comparison coverage. More community discussion with their brand name attached to specific use cases.

    Research by Stacker in 2026 found that distributed earned media is 5.3x more likely to be the sole source of a brand’s AI visibility than the brand’s own domain. Syndicating structured content through credible publishers can triple cross-platform coverage across Claude, ChatGPT, and Perplexity simultaneously.

    That’s not a PR strategy. That’s a model-level visibility strategy.

    You Can’t Improve What You Can’t See

    Here’s the practical problem: Claude’s conversations are private. Traditional analytics can’t track what the model says to users about your brand, whether it’s recommending you, misrepresenting your product, or citing a three-year-old negative review.

    That black box is where most optimization efforts stall.

    Topify was built specifically to make that black box visible. Its Source Forensics capability reverse-engineers the citations Claude generates, identifying the exact URLs influencing its recommendations. If the model is citing outdated or negative coverage, you know which URL to target for a content refresh or to dilute with higher-authority positive material.

    Topify’s Sentiment Velocity tracking goes further: it monitors not just what Claude says about your brand today, but the direction that sentiment is moving over time. A static score tells you where you stand. Velocity tells you where you’re heading.

    Hallucination Alerting flags in real time if Claude starts generating false claims about your product, giving PR teams the window to flood the ecosystem with corrective, verified data before the misrepresentation compounds.

    The platform also tracks Entity Confidence, measuring how cleanly Claude distinguishes your brand from competitors or generic category terms. Low entity confidence is often the hidden cause of “brand invisibility,” where Claude knows your category but can’t reliably surface your specific name.

    4 Things That Actually Move the Needle

    Strategy matters less than execution sequence here. These four levers are statistically validated to increase citation probability and recommendation frequency.

    Seed high-weight third-party domains. Digital PR in tier-1 publications like TechCrunch or Forbes, combined with community presence on Reddit and detailed outcome-specific reviews on G2 or Capterra, builds the external signal network Claude’s model treats as authority evidence. This is mention-building, not link-building.

    Unify your descriptive language. Synchronize how your brand is described across Wikipedia, LinkedIn, Crunchbase, and your website. Pick clear category language and commit to it across every surface. The goal is a “clean signal” the model can decode without ambiguity.

    Map content to specific prompt scenarios. Don’t write for broad topics. Write for specific problems. Content that directly answers “How to fix data pipeline latency?” with a proprietary framework gives Claude something extractable and citable. Comparison pages that acknowledge product limitations, counterintuitively, earn higher model trust than pages that claim universal superiority.

    Monitor continuously, not annually. Adding factual statistics to content increases AI visibility by 40%. Citing authoritative sources adds another 40%. Expert quotations add 28%. Keyword stuffing reduces it by 10%. These numbers shift as model versions update. Weekly or bi-weekly tracking of share of voice and sentiment across Claude, ChatGPT, and Perplexity turns optimization from a one-time project into a compound advantage.

    Conclusion

    Claude’s recommendation logic rewards accuracy, external validation, and descriptive clarity. It penalizes promotional language, inconsistent positioning, and over-reliance on owned media.

    That’s a different game than SEO. The brands winning AI visibility today aren’t necessarily the ones with the biggest budgets or the longest domain histories. They’re the ones with the most reliable, consistent, and independently verified footprint across the digital commons.

    The gap between “being online” and “being recommended” is real. It’s also measurable, and it’s closeable. But only if you can see it first.

    FAQ

    Does Claude AI update its brand knowledge in real time? 

    Generally, no. Claude’s core recommendations come from parametric memory with fixed training cutoffs. Some implementations add real-time search via RAG, but even then the base model’s pre-trained weights shape how new data gets interpreted. Core brand knowledge typically changes only when the model is retrained, which happens every few months to a year.

    Is Claude AI brand visibility the same across different Claude versions? 

    No. Different versions have different training cutoffs and reasoning behaviors. A brand that launched in late 2024 may be invisible to Claude 3.5 Sonnet but recognized by Claude 4.5 or 4.7. Newer models also apply Constitutional AI filters more rigorously, which can result in more neutral or cautious brand recommendations across the board.

    How long does it take to see changes after optimizing for Claude? 

    Core parametric knowledge updates with model retraining, which takes months. But if Claude is using agentic search tools or RAG in a given deployment, high-authority third-party content published and indexed by search engines can start influencing responses within days to a few weeks.

    Can smaller brands compete with established names in Claude’s recommendations? 

    Yes, and often more effectively than in traditional search. Claude prioritizes specific match quality and factual density over broad name recognition. A smaller brand that answers a niche problem with precision and earns validation on a few high-trust sources, such as specialized Reddit communities or industry journals, can consistently outrank a larger competitor relying on generic marketing content.

    Read More