Blog

  • Why Your Brand Is Missing from Claude Opus 4.8

    Why Your Brand Is Missing from Claude Opus 4.8

    Your content team has been publishing consistently. Your SEO authority is solid. Then a potential buyer opens Claude, types “best tool for [your category],” and gets a confident, well-structured answer — featuring three of your competitors and zero mention of you.

    That’s not a fluke. It’s a structural problem, and it predates your last content sprint by months.

    Claude Opus 4.8 Isn’t Just a Better Chatbot

    Most coverage of Claude Opus 4.8 focuses on benchmark scores and reasoning improvements. Those upgrades matter, but not in the way most marketers think.

    What changed isn’t just capability. It’s selectivity. Opus 4.8 introduced enhanced multi-step reasoning, scoring significantly higher on GPQA Diamond and agentic benchmarks than its predecessors. That sounds like a good thing until you realize it means the model is now a stricter filter on what it considers worth including in an answer.

    On “High Effort” settings — which more sophisticated users are increasingly applying — Opus 4.8 spends additional compute to synthesize a definitive, authoritative response. That environment heavily favors brands with deep, structured, verifiable documentation over those with polished marketing copy.

    If your brand’s digital presence is mostly promotional, Opus 4.8 is less likely to trust it.

    The Gap Between SEO Visibility and Claude Opus 4.8 Visibility

    Here’s the core problem: Google and Claude don’t read the web the same way.

    Google rewards pages that match keyword intent, earn backlinks, and load fast. Claude builds answers by synthesizing statistical associations from its training data and grounding those answers against live sources it considers authoritative. Your Google rank doesn’t transfer.

    AI search visibility differs from traditional SEO in a specific, measurable way: what matters isn’t whether a page ranks, but whether the content on that page is the kind that AI systems cite and encode. A brand can dominate page one and remain completely invisible in Claude’s outputs.

    This isn’t a gap most teams are set up to see. Their analytics track clicks, rankings, and traffic. None of those metrics capture what Claude is saying about them.

    Why Claude Opus 4.8 Skips Your Brand Specifically

    Three structural factors typically explain brand invisibility in AI answers.

    Low citation authority on AI-trusted domains. Claude’s underlying corpus weights specific types of sources more heavily than generic web content: analyst reports, practitioner forums, G2-style review platforms, trade publications, and technical documentation. If your brand lacks a presence on these nodes, it fails an implicit authority check, regardless of your domain rating.
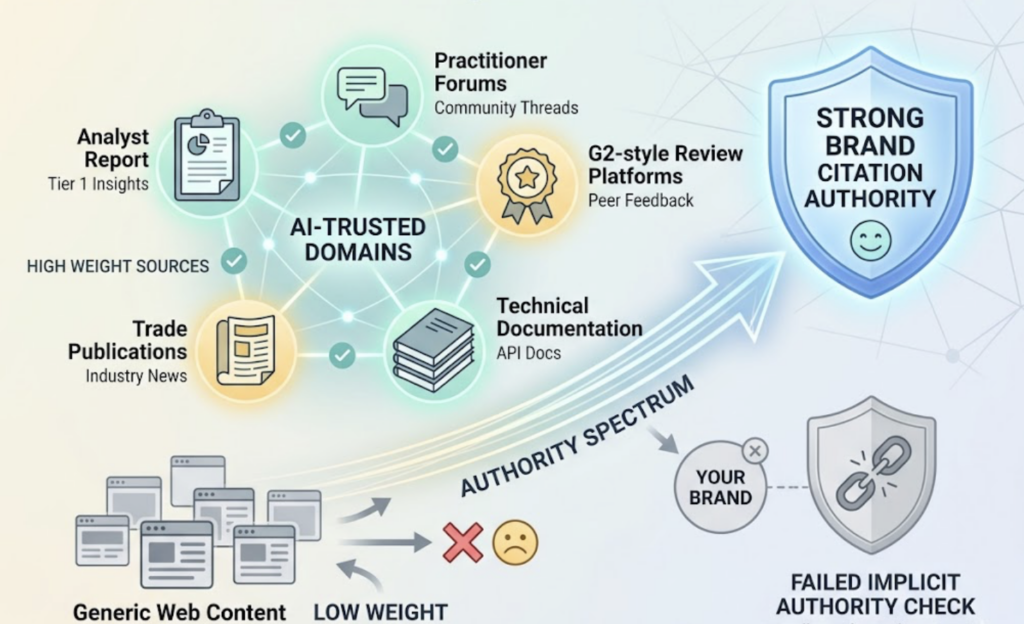
    Semantic ambiguity in how your brand is defined. Claude identifies brands as entities. If your homepage describes you as a “CRM platform,” your press releases call you an “automation tool,” and your blog categories suggest you’re an “analytics solution,” the model can’t cleanly map your brand to a specific problem or outcome. Inconsistent self-description gets resolved as exclusion. The model prefers to omit rather than hallucinate.

    Lack of AI-readable structure. According to research on how LLMs choose which brands to recommend, models process information best when it’s structured in extraction-friendly formats: tables, clearly bounded FAQ sections, schema-marked entity definitions. Narrative-heavy content that works well for human readers is harder for the model to parse and trust under reasoning pressure.

    These three factors compound. A brand with inconsistent positioning, no third-party citations on authoritative domains, and unstructured content is effectively invisible to Claude Opus 4.8, even if it publishes excellent material daily.

    What Claude Actually Uses to Build Its Answers

    Understanding the mechanism matters more than chasing workarounds.

    Claude Opus 4.8 draws on two knowledge sources simultaneously. The first is internalized training data: massive historical snapshots of the public web that have been compressed into statistical associations within the model’s weights. If your brand was consistently mentioned alongside a specific problem or outcome across diverse, credible sources, that association is now encoded in the model. If it wasn’t, the baseline is zero.

    The second source is Retrieval-Augmented Generation (RAG): live grounding that retrieves current content at query time. When a user asks Claude about a category, the model may pull fresh content from domains it treats as high-authority. Whether your domain makes that shortlist depends on the same citation-authority logic above.

    The practical implication: AI citation tracking isn’t just about knowing if your brand appears. It’s about understanding which sources Claude is citing instead of you, and why those sources rank higher in the model’s internal trust hierarchy.

    That’s information most brands don’t have.

    You Can’t Fix What You Can’t See

    Brand managers often discover the Claude Opus 4.8 problem the wrong way: a sales rep gets asked about an AI recommendation that didn’t include them, or a prospect mentions they heard about a competitor “from AI research.” By that point, the visibility gap has been open for months.

    The reason it goes undetected is simple. Standard analytics don’t capture AI answer data. Traffic reports, keyword rankings, and backlink audits measure what happened on your website. They don’t measure what Claude says when your product category comes up.

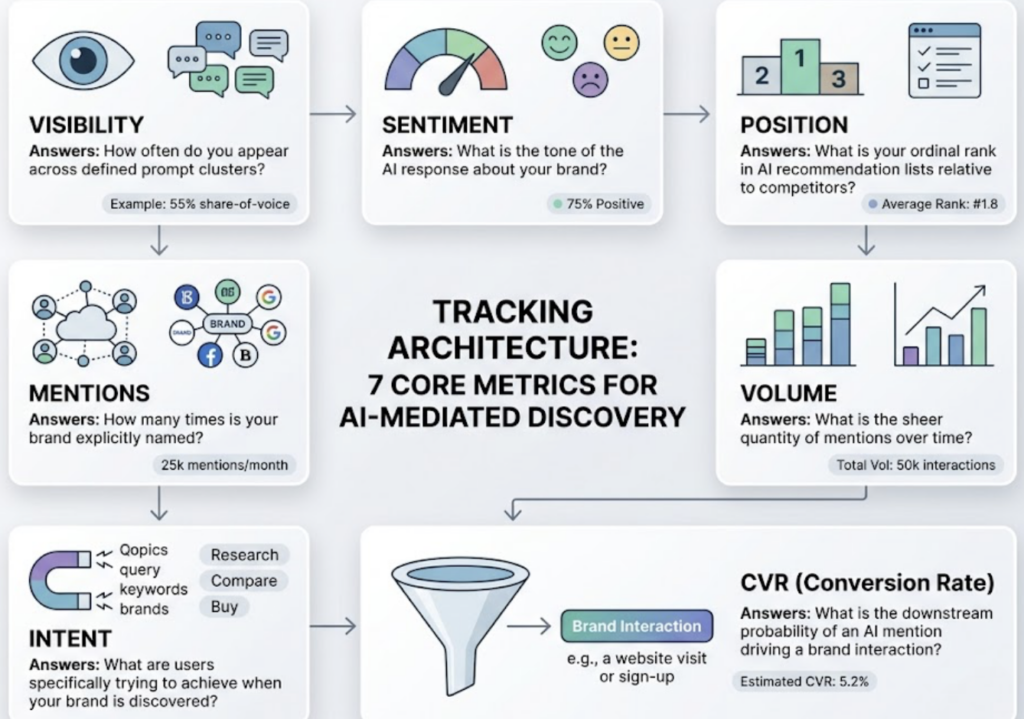
    This is where Topify directly addresses the measurement gap. It tracks brand visibility across ChatGPT, Perplexity, Google AI Overviews, and other major AI platforms at the prompt level — returning seven key metrics: Visibility Score, Sentiment, Position Rank, Volume, Mentions, Intent, and CVR (Conversion Visibility Rate).

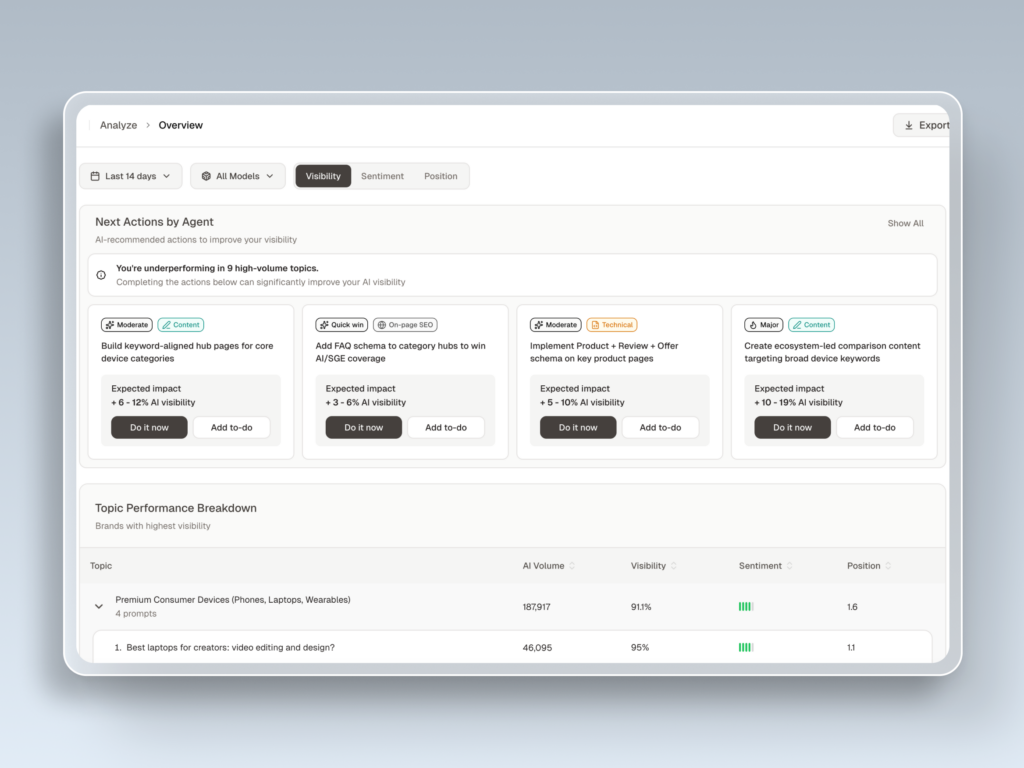
    What makes this actionable is the Source Analysis layer. Topify’s platform identifies exactly which domains AI systems are citing when they answer prompts in your category. If Claude is consistently pulling from three competitor-adjacent publications and ignoring your domain, you can see that pattern in the dashboard and respond with a targeted content or PR strategy.

    For brands currently invisible in Claude Opus 4.8, the starting point is always the same: run a prompt audit across your target category queries to establish a baseline. You need to know your current Position Rank relative to competitors before you can measure whether any change you make is working.
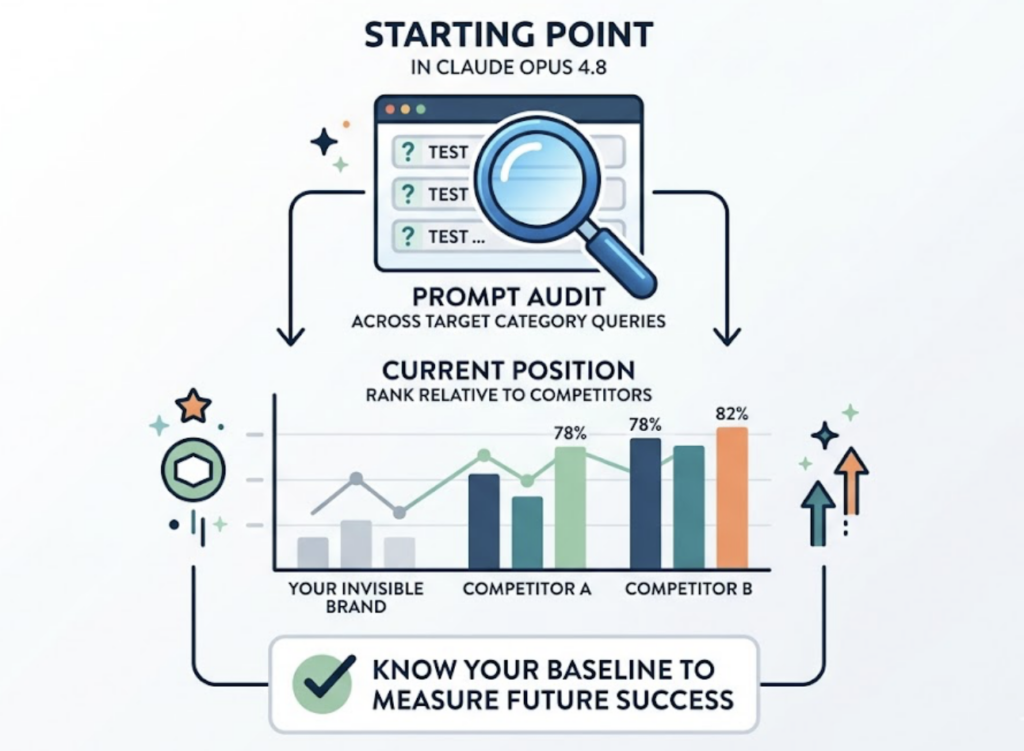
    Three Moves That Actually Get Brands Into Claude Opus 4.8’s Answers

    These aren’t shortcuts. They’re structural changes that alter how Claude encodes your brand.

    Audit which prompts trigger your category. High-intent prompts in your vertical are generating answers right now, and you need to know where you stand in each of them. Tools like Topify’s prompt discovery feature surface high-volume AI prompts critical to your brand, including queries you might not be monitoring. This is the foundation for everything else.

    Build content that AI platforms cite. The research on GEO tactics for Claude visibility points to a consistent pattern: original data, practitioner-authored content, and structured documentation earn third-party citations more reliably than SEO-optimized blog posts. A single original study cited by four industry publications is worth more to your AI visibility than forty keyword-targeted articles. Also consider your llms.txt file configuration, an emerging standard that helps Claude identify which sections of your site are most authoritative and AI-relevant.

    Implement entity grounding across your site. Use structured data markup (Organization, Product, and Person schema) to give the model an unambiguous digital identifier for your brand. This directly addresses the semantic ambiguity problem. When Claude encounters consistent, schema-marked entity definitions, it can map your brand to a specific category with confidence, rather than excluding you to avoid a hallucination risk.

    Claude Opus 4.8 Will Keep Updating. So Will the Rankings.

    The competitive calculus here is different from traditional SEO because AI models aren’t static.

    As Anthropic releases updates and Opus 4.8 continues to evolve, the model will re-process its internal associations and recalibrate which brands it trusts. What gets your brand into Claude’s answers this quarter is not a permanent solution. Brands that treat AI visibility as a one-time optimization project will lose ground every time the model updates.

    What actually works long-term is what the research on AI visibility continuity describes: systematic presence across diverse, high-trust digital channels, maintained continuously. Not single-platform dominance. Not a quarterly content sprint. A structured process for monitoring where you stand, identifying which sources Claude is prioritizing, and updating your strategy accordingly.

    The brands that will consistently appear in Claude Opus 4.8’s answers are the ones tracking it as a live channel, not treating it as a fixed result.

    Conclusion

    The core issue isn’t that Claude Opus 4.8 is unfair to your brand. It’s that the model is working exactly as designed — synthesizing answers from the most coherent, credible, citation-supported signals available. If your brand isn’t generating those signals, the model’s silence is accurate feedback, not an error.

    The fix starts with visibility into where you actually stand. Audit your AI answer presence, identify which sources Claude is citing in your category, and build a content strategy that earns authority on those specific nodes. Get started with Topifyto run a prompt audit across your target queries and get a baseline before the next model update shifts the rankings again.

    FAQ

    Q: Does Claude Opus 4.8 use real-time web search to generate answers?

    A: It depends on the user’s setup. Claude Opus 4.8 can operate in two modes: relying on internalized training data, or performing live RAG grounding against current web sources. Enterprise users and API deployments often enable real-time retrieval. In both cases, the authority of the sources being cited matters more than recency alone.

    Q: How is AI visibility different from SEO rankings?

    A: SEO rankings measure where a page appears in a results list. AI visibility measures whether a model includes your brand in a synthesized answer. A page can rank highly in Google and be completely absent from Claude’s outputs — because the two systems prioritize different signals. SEO rewards keyword relevance and backlink authority. Claude rewards citation authority on AI-trusted domain types, entity clarity, and structured content.

    Q: How do I check if my brand appears in Claude Opus 4.8’s answers?

    A: The manual approach is to run a series of prompts in your product category directly in Claude and record the results. The systematic approach is to use an AI visibility monitoring platform like Topify, which tracks brand mentions, Position Rank, and Source data across multiple AI platforms automatically, so you’re not relying on manual spot checks.

    Q: Can I optimize for Claude specifically, or do I need a general AI strategy?

    A: The underlying factors that drive visibility in Claude — citation authority, entity coherence, structured documentation — are largely the same factors that drive visibility across ChatGPT, Perplexity, and Gemini. A platform-specific tactic (like llms.txt configuration) can help with Claude directly, but most high-impact GEO work improves your standing across AI platforms simultaneously. Start with a cross-platform audit to identify where your gaps are largest before prioritizing.
    Read More

  • Why Claude Opus 4.8 Picks Some Brands Over Others

    Why Claude Opus 4.8 Picks Some Brands Over Others

    Your domain authority is solid. Your keyword rankings are where they should be. But none of that tells you whether Claude Opus 4.8 is recommending your competitor when a user asks, “What’s the best tool for [your category]?”

    That’s the gap most brands haven’t measured. And with Claude Opus 4.8 now handling a growing share of AI-assisted decisions, the cost of being invisible to it is no longer hypothetical.

    Claude Opus 4.8 Isn’t a Search Engine. It’s a Referee.

    Most marketers assume Google rankings translate directly to AI search visibility. They don’t.

    Search engines index, rank, and surface links. Claude Opus 4.8 does something fundamentally different: it synthesizes patterns from its training data and reconstructs what it “knows” about your brand from memory. There’s no real-time crawl, no live index, no backlink graph to climb.

    According to Anthropic’s Claude Opus 4.8 technical system card, the model was built with a strong emphasis on honesty and agentic reasoning. That means it’s designed to be more selective—and more skeptical—about which sources and brands it cites. If your brand doesn’t have a strong enough footprint in the data it was trained on, it’s not downranked. It’s simply absent.

    That’s a meaningful distinction. An absent brand gets no second chance from a better meta description.

    The 4 Signals Claude Opus 4.8 Uses to Decide on a Brand

    Research into how Claude AI chooses brands points to four core signals that shape which names the model surfaces and how confidently it cites them.

    Source Authority: The Anchor Signal

    Claude Opus 4.8 shows a strong preference for brands that appear in authoritative, editorial sources—industry journals, established tech publications, credible documentation sites.

    These aren’t just “high-DA” domains in the SEO sense. They’re sources that humans have historically trusted to provide accurate information, which means the model treats them as grounding anchors when forming its understanding of a category.

    A brand mentioned once in a roundup post on a niche blog carries far less weight than a brand cited in a Gartner analysis, a Product Hunt discussion thread with hundreds of upvotes, or a well-referenced Wikipedia entry.

    Mention Density: Statistical Weight Across the Web

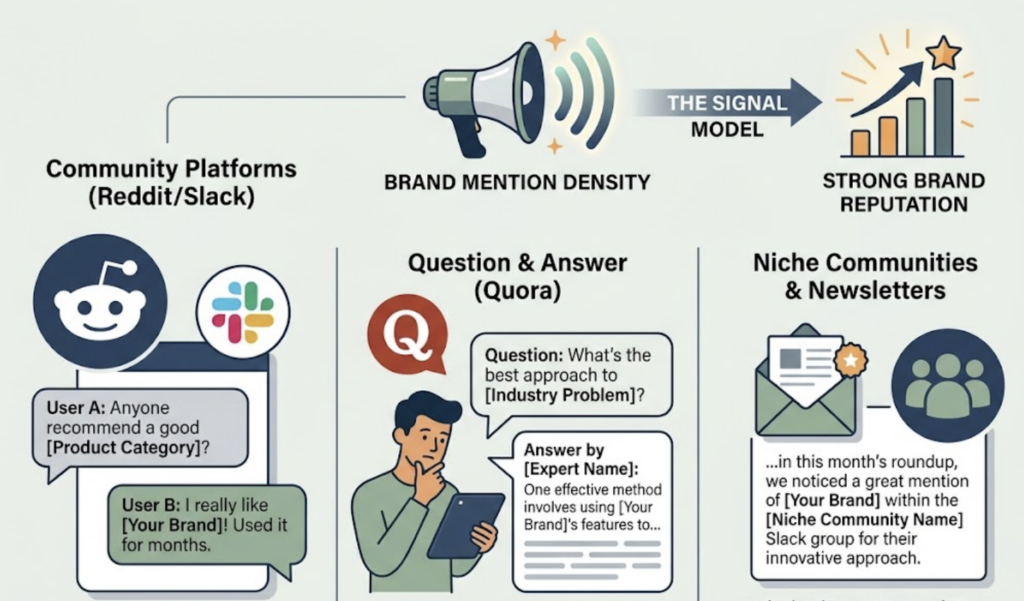
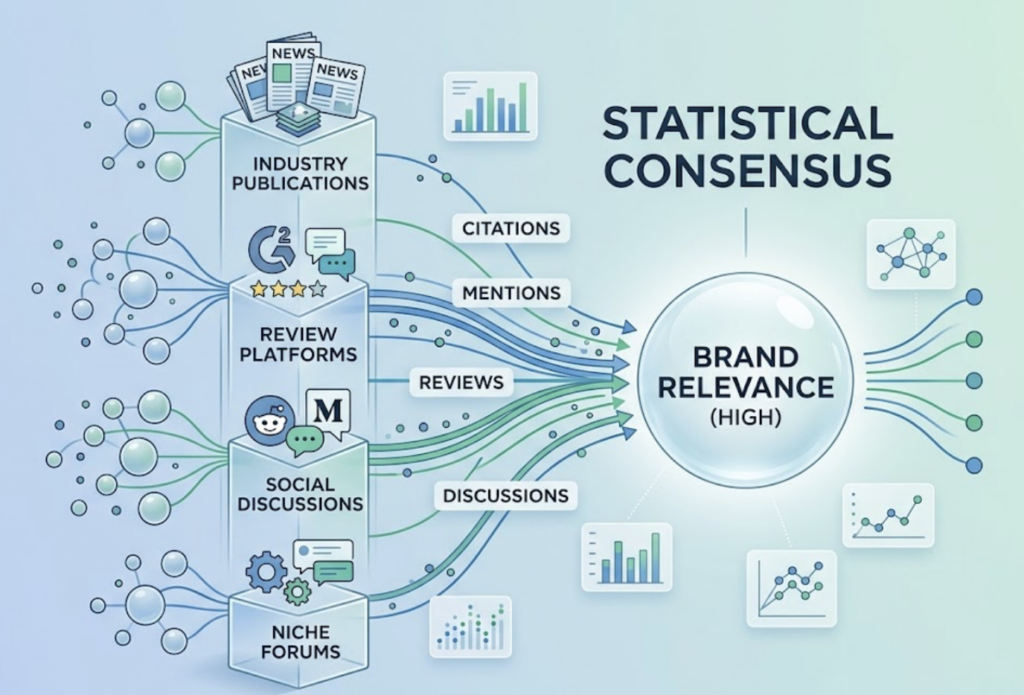
    Frequency acts as a proxy for relevance. If your brand appears across hundreds of independent, contextually relevant sources—Reddit threads, G2 reviews, Medium posts, industry newsletters, niche community forums—the model registers a statistical consensus.

    Research on training data frequency and brand citation patterns confirms that mention density across diverse platforms is one of the most consistent predictors of LLM recall. It’s not about one high-profile placement. It’s about breadth.

    Sentiment Consistency: Narrative Stability

    Claude Opus 4.8 is specifically tuned for what Anthropic calls “honesty calibration.” According to analysis of Opus 4.8’s agentic capabilities, the model reports a 4x reduction in unsupported claims compared to prior versions.

    In practice, that means the model is more likely to avoid citing brands that have contradictory descriptions across different sources. If your product is described as “enterprise-grade” on your site but “a budget alternative” in third-party reviews, the model may hedge—or skip your brand entirely to avoid making an unsupported claim.

    Consistent messaging across all digital touchpoints isn’t just a brand strategy concern. It’s now an AI visibility concern.

    Category Dominance: Semantic Association

    The model must be able to map your brand clearly to a category and a problem. Not vaguely—specifically.

    Think: “Brand X is a leading CRM for mid-sized teams” or “Brand Y is the go-to platform for AI search visibility tracking.” That kind of explicit category-to-brand association, repeated across multiple credible sources, is how Claude builds the semantic connection needed to recommend you by name when a user asks a category-level question.

    Generic positioning kills this. If your brand is described differently depending on the channel, the model can’t establish a clean association.

    Why Your Brand Might Be Invisible to Claude Right Now

    Three patterns account for most of the brand invisibility cases in Claude Opus 4.8.

    First: missing high-authority citations. If your brand is primarily mentioned in self-published content or low-signal platforms, the model doesn’t have enough grounding material to cite you with confidence.

    Second: brand name ambiguity. If your product name is also a common word or shares a name with another product, the model may consistently resolve the ambiguity toward the more established entity.

    Third: fragmented content presence. A brand that publishes strong content but only on its own domain hasn’t built the cross-source footprint that LLMs use to establish credibility.

    Claude doesn’t rank you. It remembers you.

    And if it can’t remember you clearly, it won’t cite you at all.

    What Changed in Claude Opus 4.8 That Brands Need to Know

    The upgrade from earlier Claude versions to Opus 4.8 isn’t just a capability improvement. It changes how the model evaluates the quality of information it synthesizes.

    Anthropic’s release notes for Opus 4.8 introduced effort-control settings that let users configure how deeply the model reasons through a query. On default “High Effort” settings, the model is designed to think more carefully rather than pattern-match to shallow content.

    The practical effect: keyword-stuffed content and generic marketing copy are increasingly filtered out by the model’s reasoning process. Content that provides specific, verifiable, actionable information gets prioritized. Content that makes unsupported claims gets deprioritized or ignored.

    That’s a meaningful shift. What worked as SEO content in 2023 may now actively hurt your chances of being cited by Claude Opus 4.8—not because the content is penalized, but because it doesn’t meet the model’s threshold for credibility.

    Brands that have invested in technical documentation, documented case studies, and third-party validation are better positioned in this environment than brands relying on volume-based content strategies.

    The Brands Claude Opus 4.8 Tends to Recommend

    The brands that appear most consistently in Claude Opus 4.8’s recommendations aren’t always the largest or most heavily funded. They share a different profile.

    According to research on the psychology of brand mentions and training data signals, the common thread is what researchers call “Semantic Certainty”: the model has encountered the brand often enough, across credible enough sources, with consistent enough messaging, that it can cite the brand without risking an unsupported claim.

    In practical terms, that means:

    • Cited in at least a handful of authoritative sources (not just self-published)
    • Mentioned across multiple independent platforms with similar descriptions
    • Clearly associated with a specific problem or category in the model’s training data
    • Described in a way that holds up under the model’s honesty calibration

    The bar isn’t impossible. But it requires a systematic approach, not a one-off PR push.

    How to Track Whether Claude Opus 4.8 Is Recommending Your Brand

    Here’s the problem: Claude doesn’t provide a rank tracker. There’s no search console equivalent for LLM visibility. You can’t log into a dashboard and see “Your brand appeared in 34% of relevant Claude queries this month.”

    That gap is exactly where Topify operates. Topify’s AI search visibility platform tracks how brands appear across major AI engines—ChatGPT, Gemini, Perplexity, Claude, and others—at the prompt level.

    The key metrics Topify surfaces for teams trying to understand their Claude visibility:

    Visibility Score: How often your brand appears in response to category-level prompts, across tracked AI platforms. A drop in this score often signals a change in how training data or citation patterns are shifting.

    Share of Model: Your brand’s relative presence compared to competitors across the same set of prompts. This is the AI equivalent of share of voice—and it’s the metric that tells you whether Claude is recommending you or your competitor.

    Source Analysis: Which domains Claude and other AI engines are pulling from when they cite brands in your category. If a specific forum or third-party review site consistently appears as a citation source for your competitors, that’s your next content target.

    Position Rank: Where your brand appears in AI-generated recommendation lists. Being mentioned is different from being mentioned first.

    Because each AI model is trained on a different corpus, cross-platform monitoring matters. A brand can have strong visibility in ChatGPT and near-zero presence in Claude Opus 4.8 if the training sets diverge. Topify’s AI search visibility tracking covers this cross-platform gap in a single view.

    Three Things You Can Change This Week

    Most brands can’t rewrite their entire content strategy overnight. But there are three moves that have an outsized effect on LLM brand visibility, and none of them require a full GEO overhaul.

    Audit your citation sources. Use Topify’s Source Analysis to identify which domains AI engines are pulling from in your category. Then cross-reference your brand’s presence on those exact platforms. If you’re not there, that’s your gap. Getting a mention on a site the model treats as authoritative is worth far more than ten mentions on low-signal platforms.

    Standardize your brand description. Pull your brand’s descriptions from your own site, G2, Capterra, Reddit, and any major review or community platform. Look for contradictions in how your product is positioned. Resolve them. Consistency across sources is a direct input into the model’s confidence when citing you.

    Build a presence on independent platforms. Owned content matters, but the model’s sense of your brand comes from sources it treats as independent. Reddit threads where users recommend your product, thoughtful answers on Quora, community mentions in niche Slack groups or newsletters—these build the “mention density” signal in a way that your own blog cannot.

    Get started with Topify to run a baseline visibility check across AI platforms before you make changes. You can’t optimize what you haven’t measured.

    Conclusion

    Claude Opus 4.8’s brand recommendation logic isn’t opaque—it follows a consistent pattern of source authority, mention density, sentiment consistency, and category association. What’s changed with the Opus 4.8 release is that the model’s honesty calibration now makes it more demanding. Generic content and thin citation footprints get filtered out. Brands with documented credibility across independent sources get surfaced.

    The monitoring infrastructure to track this didn’t exist a few years ago. It does now. The teams that build a baseline understanding of their Claude visibility in 2026 will have a significant head start on the ones still measuring success purely through Google Search Console in 2027.


    FAQ

    Q: Does Claude Opus 4.8 update its brand knowledge in real time?

    A: No. Claude Opus 4.8 generates responses based on patterns from its training data, which has a fixed cutoff date. It doesn’t crawl the web or update citations in real time. This means brand visibility in Claude is a function of what was present in training data—and why monitoring your current presence across AI platforms requires dedicated tooling, not a one-time check.

    Q: Can I “optimize” my brand for Claude the way I optimize for Google?

    A: Not in the same way. There’s no equivalent of on-page SEO for LLMs. What you can influence is the footprint your brand has across sources the model weights as credible: authoritative publications, independent review platforms, community discussions, and technical documentation. That’s the GEO equivalent of link building—it takes time, but it compounds.

    Q: How is Claude Opus 4.8 different from ChatGPT in recommending brands?

    A: The core mechanism is similar—both models synthesize brand knowledge from training data—but they’re trained on different corpora and have different calibration priorities. Claude Opus 4.8’s emphasis on honesty and reduced unsupported claims means it’s generally more conservative in its brand citations than GPT-based models. A brand that appears frequently in ChatGPT responses may have lower visibility in Claude if the underlying sources differ.

    Q: What’s the fastest signal I can improve to get picked by Claude?

    A: Sentiment consistency tends to have the highest leverage for most brands in the short term. Auditing and aligning how your brand is described across third-party platforms—especially high-authority review and community sites—removes a key reason Claude might avoid citing you. It doesn’t require new content creation, just cleanup and coordination across existing touchpoints.


    Read More

  • Claude Opus 4.8: What Marketers Actually Need to Know

    Claude Opus 4.8: What Marketers Actually Need to Know

    Most marketers track Google rankings. A few track ChatGPT mentions. Almost none are watching what Claude does with their brand, even as Claude Opus 4.8 quietly becomes the engine behind more AI-generated answers across the platforms their customers actually use.

    That gap is getting expensive.

    What Claude Opus 4.8 Actually Is (and Where It Sits in the AI Landscape)

    Claude is Anthropic’s flagship AI model family, and it runs on a three-tier architecture. Haiku handles speed and low-cost tasks. Sonnet balances performance and efficiency. Opus is the top tier, designed for deep reasoning, nuanced judgment, and complex multi-step tasks.

    Claude Opus 4.8, released May 28, 2026, is the most capable model in that tier to date. It’s not a speed upgrade or a cost cut. The defining changes are behavioral: the model is better at knowing when it’s wrong, better at executing long autonomous workflows, and more precise when calling external data sources.

    For the average marketer, the translation is simple. Opus 4.8 is the AI version of a senior analyst who won’t bluff through uncertainty and won’t cut corners on complex research.

    The 4.8 Upgrades That Change How AI Reads Your Brand

    Five changes in 4.8 have direct implications for brand visibility. Not all of them are obvious.

    Honesty calibration. According to Anthropic’s launch announcement, Opus 4.8 is approximately 4x less likely than 4.7 to let errors in its own output go unremarked. It flags uncertainty rather than filling gaps with confident-sounding guesses. In practice, this means your brand content either holds up under factual scrutiny or gets quietly omitted from AI-generated answers.

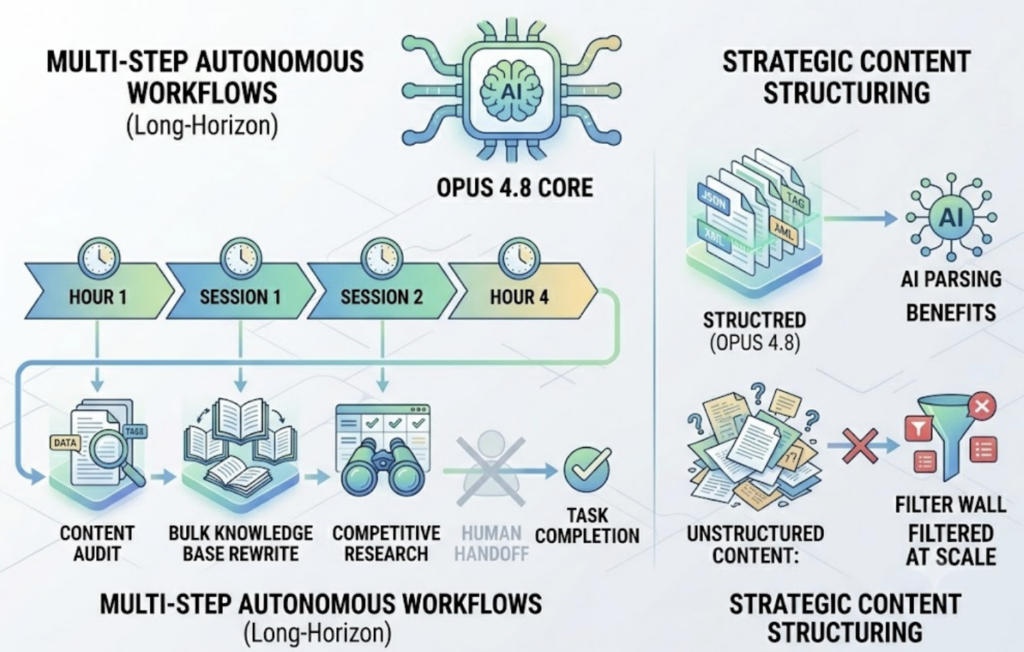
    Agentic reliability. Opus 4.8 is built for “long-horizon” tasks: multi-step autonomous workflows that can run across hours or multiple sessions. Content audits, bulk knowledge base rewrites, and competitive research are now tasks the model can complete end-to-end without human handoffs. Brands that structure their content for AI parsing will benefit; those that don’t will get filtered out at scale.

    Effort dial on claude.ai. Users now have explicit control over how much “thinking” the model applies to a task. High effort is the default. This means Opus 4.8 will spend more tokens evaluating a query before answering, which translates to more selective citation behavior and fewer hallucinated brand facts.

    Fast mode efficiency. A new fast mode is 2.5x faster and roughly 3x cheaper than previous versions. This lowers the barrier for customer-facing AI applications powered by Claude, which means more consumer touchpoints where brand recommendations get generated.

    Tool-calling precision. Opus 4.8 is more accurate at retrieving external data in real time. Brands with structured, API-accessible content have a new advantage: the model can pull and cite their data directly, rather than relying solely on training-time knowledge.

    Where Claude Opus 4.8 Shows Up in the Real World

    Claude isn’t just Claude.ai. The model powers a growing stack of products and integrations that your potential customers use daily: Perplexity’s Pro mode, enterprise AI deployments via Amazon Web Services, developer tools built on Anthropic’s API, and third-party AI assistants across B2B SaaS.

    Every time a user asks one of these products for a vendor recommendation, a product comparison, or a solution to a business problem, Opus 4.8 is potentially generating that answer. And generating it with less tolerance for ambiguity than its predecessors.

    That’s the part most marketing teams haven’t fully internalized yet.

    Why a More “Honest” Claude Changes What Gets Cited

    The relationship between AI model quality and brand visibility isn’t linear. Better models don’t just cite more brands. They cite more selectively.

    Opus 4.8’s honesty calibration creates a higher bar for what counts as a citable source. Content that is structured clearly, factually consistent, and backed by third-party validation tends to survive this filter. Content that is vague, marketing-heavy, or contradicted by external sources tends to get dropped.

    AIWiz UK’s analysis of the 4.8 release describes this shift as AI models becoming increasingly sensitive to “conflicting or unsupported information.” The implication for content strategy: keyword density matters far less than factual scaffolding. If your product page says one thing and your support docs say another, Opus 4.8 will notice.

    Clear HTML structure also plays a role. The model performs best when content is organized into distinct sections, whether that’s benefit grids, feature lists, or structured product statements. Unstructured marketing prose is harder for the model to extract, summarize, and cite accurately.

    3 Things Marketers Should Do Before the Next Model Update

    Model updates happen faster than most content calendars move. Waiting for the dust to settle is no longer a viable strategy. Here’s where to start.

    Audit how AI currently describes your brand. Pull up Claude, Perplexity, and ChatGPT. Ask each one to describe your product, compare it to competitors, and recommend it for a specific use case. Document what you find. If the descriptions are inaccurate, generic, or missing key differentiators, your web presence likely lacks the structured documentation AI models need to generate accurate answers.

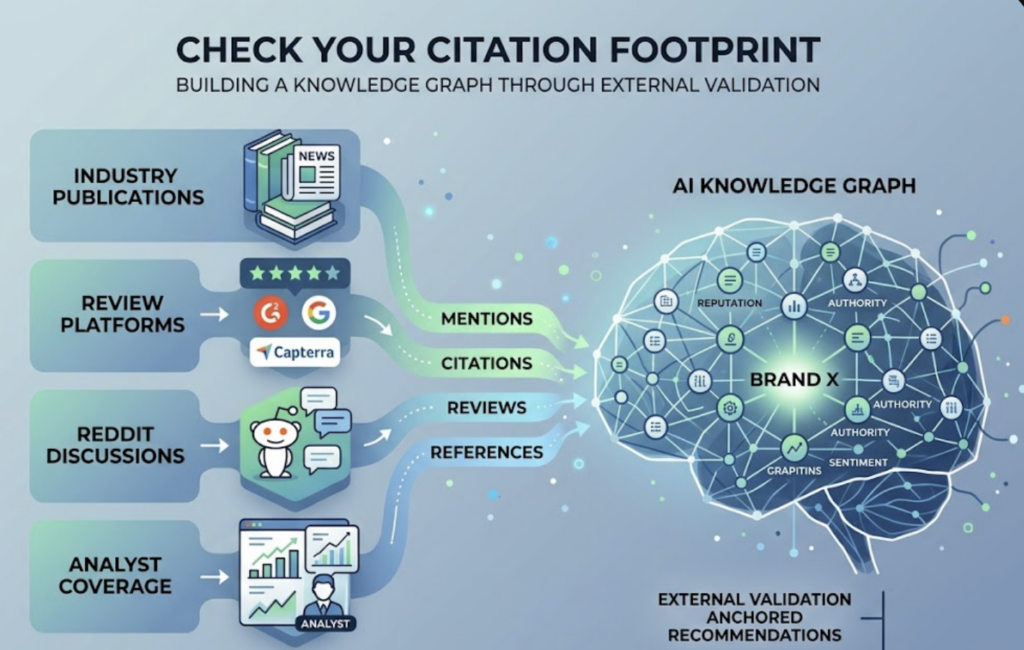
    Check your citation footprint. AI models build their “knowledge graph” of a brand through third-party references: industry publications, review platforms like G2 and Capterra, Reddit discussions, and analyst coverage. If your domain isn’t appearing in these high-authority contexts, the model has little external validation to anchor its recommendations. One of the most practical first steps is running a source analysis to see which domains AI platforms are citing in your category and whether yours is on the list.

    Build a monitoring system, not a one-time audit. Opus 4.8 is not the last version. Anthropic will ship 4.9, or 5.0, and each update will recalibrate citation behavior. Static audits give you a snapshot. What you need is a live view of how AI models are representing your brand week over week.

    How to Track Brand Visibility Across Claude and Other AI Platforms

    Manual testing across Claude, ChatGPT, Perplexity, and Google AI Overviews doesn’t scale. Running the same prompts across four platforms, logging the outputs, and tracking changes over time is a full-time job for a team, not a monthly checklist item.

    Topify is built specifically for this problem. It monitors brand performance across major AI platforms using seven metrics: Visibility Score, Sentiment Score, Position Rank, AI Volume, Mentions, Intent alignment, and CVR (Conversion Visibility Rate). Rather than showing you raw AI outputs, it surfaces what changed, what caused the change, and what to do about it.

    The Source Analysis feature is directly relevant to the Opus 4.8 shift. It tracks which domains AI platforms are citing in your category, giving you a clear signal about where your citation footprint is strong and where it’s missing. That data feeds directly into content strategy decisions: which third-party sites to target for coverage, which product pages need structural cleanup, and which competitor sources are being cited instead of yours.

    For marketing teams already stretched across SEO, paid, and social, Topify’s one-click agent execution means you can deploy a GEO optimization strategy without building a manual workflow from scratch. Define your goals, review the proposed strategy, and let the system handle execution.

    Basic plans start at $99 per month, covering 100 prompts and 9,000 AI answer analyses across ChatGPT, Perplexity, and AI Overviews. For teams managing multiple brands or clients, the Pro tier at $199 per month expands to 250 prompts and 22,500 analyses.

    Conclusion

    Claude Opus 4.8 isn’t just a better AI. It’s a stricter one. It hallucinates less, cites more carefully, and runs longer autonomous workflows that touch more of the customer journey than any previous version.

    For marketing teams, that means the window for passive brand visibility is closing. AI models are getting better at ignoring content that doesn’t hold up to scrutiny, and better at surfacing brands that have built real citation authority across the web. The brands that understand this now, and build monitoring and optimization into their regular workflow, will have a structural advantage that compounds with every model update. The ones that wait will keep asking why they’re not showing up in AI answers and keep not finding the answer in their SEO dashboards.

    Get started with Topify to see where your brand stands across the AI platforms your customers are already using.


    FAQ

    Q: Is Claude Opus 4.8 available to the public?

    A: Yes. Claude Opus 4.8 is accessible via claude.ai for Claude Pro subscribers and through Anthropic’s API for developers and enterprise customers. It’s also available through cloud providers including Amazon Web Services.

    Q: Does Claude Opus 4.8 affect traditional SEO rankings?

    A: Not directly. Opus 4.8 doesn’t change how Google indexes or ranks web pages. What it does affect is how your brand appears in AI-generated answers on Claude, Perplexity, and any application built on Anthropic’s API. Those are separate from SERP rankings and require different tracking and optimization approaches.

    Q: How is Claude Opus 4.8 different from ChatGPT for marketers?

    A: Both generate brand recommendations, but their citation behavior and training data differ. Claude Opus 4.8’s emphasis on honesty calibration makes it particularly sensitive to content accuracy and source quality. ChatGPT and Claude will often surface different brands for the same query, which is why monitoring both matters. Relying on one platform’s behavior to predict the other is a common mistake.

    Q: Should I create separate content optimized specifically for Claude?

    A: Not exactly. The content signals Claude Opus 4.8 responds to, clear structure, factual accuracy, third-party citation authority, are the same signals that improve performance across all major AI platforms. A GEO strategy optimized for these fundamentals tends to lift visibility across ChatGPT, Perplexity, and Claude simultaneously rather than requiring platform-specific content.


    Read More

  • Claude Opus 4.8 vs GPT-5.5: Which Should You Optimize For?

    Claude Opus 4.8 vs GPT-5.5: Which Should You Optimize For?

    You just ran a brand audit. Your SEO metrics look solid. Then you ask ChatGPT, “What’s the best tool for [your category]?” and read through the response. Your brand isn’t mentioned. You switch to Claude and ask the same question. Different answer, different brands, same problem: you’re invisible on both.

    The real question isn’t which AI model is smarter. It’s which one your buyers actually use when they’re deciding, and whether your content is doing anything to show up in either.

    Two Models, Two Ways of Recommending Brands

    Claude Opus 4.8 and GPT-5.5 don’t just process queries differently. They have fundamentally different recommendation logics, and that gap matters for any brand trying to optimize its AI search visibility.

    Anthropic’s Opus 4.8 is built for high-effort, multi-step reasoning. Internally, it’s been called a “deliberate researcher.” It prioritizes dense, technical content: whitepapers, detailed documentation, decision-making frameworks. If your content explains why something works, not just what it does, Claude Opus 4.8 is more likely to surface it.

    GPT-5.5 operates differently. It’s designed for speed and decisiveness. It weights historical conversation context heavily and tends to favor brands with established “top-of-mind” digital authority. If you’re a well-known brand with broad presence across mainstream publications and forums, GPT-5.5 will find you more readily.

    That’s the core asymmetry: Claude rewards depth, GPT rewards reach.

    Where Each Model’s Users Actually Live

    Market share matters for GEO decisions. According to Brand24’s 2026 market usage report, ChatGPT holds over 70% of the AI assistant market. That number alone makes GPT-5.5 the default priority for most consumer-facing brands.

    But user demographics tell a more nuanced story.

    DimensionClaude (Claude.ai)ChatGPT (ChatGPT.com)
    Primary AudienceDevelopers, researchers, enterprise (deep work)General consumers, creatives, mass-market B2B
    Where They CongregateGitHub, technical forums, SlackNews outlets, social media, general web
    Decision-Making StyleDeliberate, research-heavyFaster, outcome-first
    Market ShareNiche but highly engagedMainstream (~70%+ share)

    If your buyer’s journey involves technical evaluation, RFP processes, or high-stakes B2B purchasing, Claude’s audience skews heavily toward that segment. If your category depends on mass-market awareness or fast consumer decisions, GPT-5.5 is where the volume is.

    Neither model’s audience is wrong for you. The question is which one matches where your buyers currently spend their AI research time.

    What GEO Actually Means for Model-Specific Optimization

    Generative Engine Optimization is not SEO with a new name. Evertune and SearchEngineLand’s 2026 GEO industry reports make the distinction clear: SEO targets click-through rates, GEO targets citation frequency and inclusion rates.

    That shift in measurement changes what good content looks like.

    Three factors drive citation frequency across both models:

    Content Extractability. AI models reassemble information, not pages. Clean HTML structure with clear headings and lists makes it easier for both Claude and GPT to identify the “answer” within your content. Buried insights in walls of text rarely get cited.

    Entity Clarity. Explicitly define your brand, product category, and target use case. Both models perform better when they can map a brand to a specific entity in their knowledge graph. Vague positioning hurts visibility on both platforms.

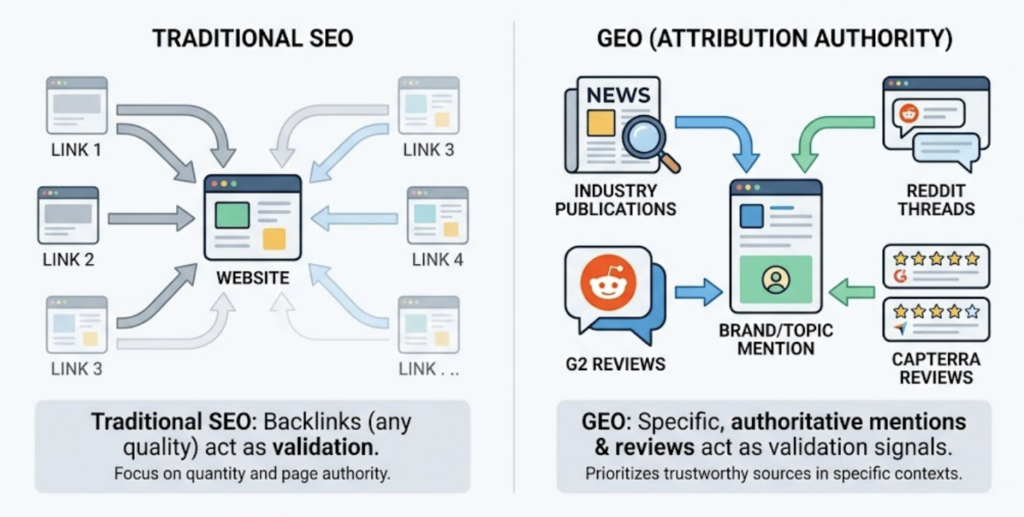
    Attribution Authority. Unlike traditional SEO, where any backlink helps, GEO favors authoritative sourcing. Mentions in industry-specific publications, Reddit threads, and G2 or Capterra reviews act as validation signals. Both models weight these, though Claude tends to favor technical and academic citations more heavily.

    The execution, though, diverges significantly by platform.

    5 Signals That Tell You Which Engine to Prioritize

    Before you allocate resources, run through these five signals. They’re faster than intuition and more reliable than guessing.

    Signal 1: Your natural mention baseline. Use an AI monitoring tool to check which engine already mentions your brand in organic queries. The platform where you already have traction is worth reinforcing before building from scratch on the other.

    Signal 2: Competitor dominance. If your main competitors have locked down GPT-5.5 recommendations through years of content investment, the cost of entry is higher. Claude may offer a lower-competition path to authority, especially in technical verticals. Tools like Topify‘s Competitor Monitoring track where rivals rank across platforms, giving you a clearer picture of where the territory is still open.

    Signal 3: Content format alignment. Your existing content signals which platform you’re naturally suited for. Long-form technical content, whitepapers, and in-depth how-to guides align with Claude’s citation preferences. Short, outcome-focused FAQs and conversational copy align with GPT’s. Don’t force a mismatch.

    Signal 4: Industry vertical. Does your industry live on developer platforms, technical forums, or GitHub? Claude’s user base concentrates there. Is your audience on mainstream news outlets, Instagram, or general search? That’s GPT territory.

    Signal 5: Keyword “ask” frequency. The phrasing of queries tells you a lot. “How to build…” and “Why does X work…” skew toward Claude’s user behavior. “Best tool for…” and “Top [category] recommendations” skew toward GPT’s conversational style. Match your content strategy to the question format your audience is actually using.

    The Case for Starting With Claude Opus 4.8

    Some brands should go Claude-first. Not because it has more users, but because its audience is more aligned with how those brands get evaluated.

    According to Anthropic’s positioning for Opus 4.8, the model is tuned for high-effort tasks and “proactive error-flagging.” That means it actively evaluates the quality and nuance of the content it cites. If your brand sells a complex product with long sales cycles, technical documentation that explains decision-making frameworks will consistently outperform generic marketing copy in Claude’s recommendation outputs.

    The practical implication: invest in content that provides decision support, not just awareness. Technical whitepapers, integration guides, and deep-dive comparison articles give Claude Opus 4.8 something to work with. For teams that want to monitor how their technical content is being cited, Topify’s Source Analysis tracks the exact domains Claude and other AI platforms reference, making it easier to identify which content is being picked up and which isn’t.

    Claude-first makes sense for: B2B SaaS, developer tools, enterprise software, professional services, and any category where the buyer conducts research before engaging sales.

    The Case for Starting With GPT-5.5

    For most consumer brands and general B2B companies, GPT-5.5 is the right starting point. The user volume is simply too large to ignore.

    OpenAI’s framing for GPT-5.5 Instant emphasizes personalization and prompt guidance. The model is designed to be decisive, favoring content that mirrors natural conversational queries. That creates a specific optimization target: your FAQ architecture.

    A brand that builds a robust FAQ section reflecting exactly how buyers phrase their purchase-stage questions (“What’s the best [category] for small teams?”, “How does [your brand] compare to [competitor]?”) creates more citation surface area for GPT-5.5 than a brand that publishes polished brand journalism nobody is actually asking about.

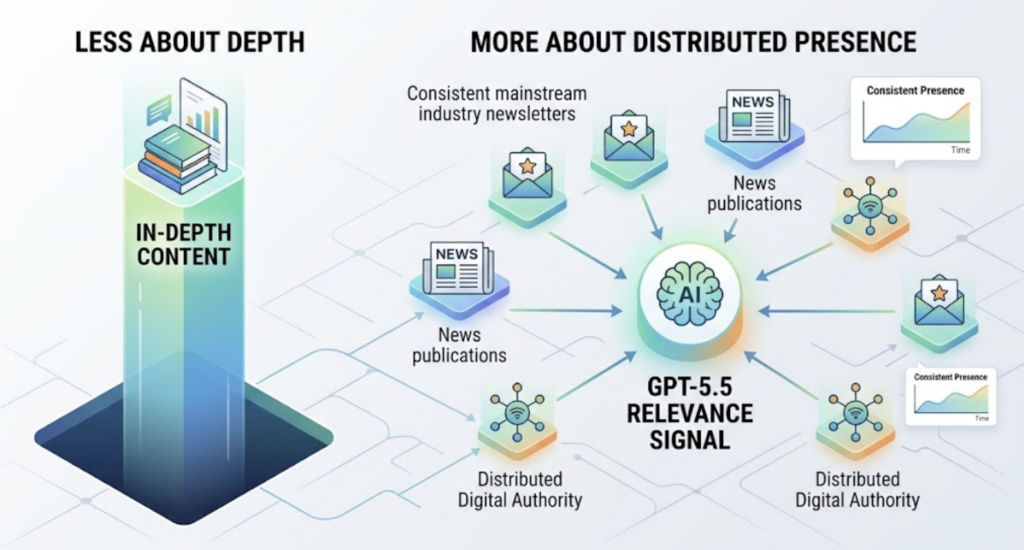
    Brand salience also matters more here than on Claude. Consistent presence in mainstream industry newsletters and news publications builds the kind of broad digital authority that GPT-5.5 uses as a relevance signal. It’s less about depth, more about distributed presence.

    GPT-first makes sense for: ecommerce, consumer tech, SMB-focused SaaS, content media brands, and any category where buyers make faster decisions with less technical evaluation.

    You Don’t Have to Guess: Track Both, Prioritize One

    The five signals above give you a starting point. But AI recommendation patterns shift faster than most content strategies can react to. What Claude Opus 4.8 cites this quarter may look different from what it prioritizes after a model update. GPT-5.5’s weighting on brand authority isn’t static.

    That’s why the practical answer isn’t “optimize for one and ignore the other.” It’s “pick your primary platform based on where your audience is, then monitor both so you know when that changes.”

    Topify’s cross-platform visibility tracking covers ChatGPT, Claude, Perplexity, Gemini, and other major AI platforms simultaneously. Its AI search monitoring dashboard maps your Visibility Score, Sentiment, and Position Rank across platforms, so you can see at a glance whether your GEO efforts are moving the needle on the engine you’re targeting, without losing visibility into the one you’re not. If you want to benchmark where you currently stand across both platforms before deciding, Topify offers a free GEO score check that doesn’t require a signup.

    The brands that will win in AI search over the next two years won’t be the ones that picked the right model. They’ll be the ones that measured fast enough to respond when the models changed.

    Conclusion

    Claude Opus 4.8 rewards depth, technical authority, and content that helps users make complex decisions. GPT-5.5 rewards reach, brand salience, and content that mirrors how buyers talk when they’re close to choosing. Both matter. Your buyer’s behavior tells you which one to build first.

    Start with the platform where your audience already researches. Build content that matches how that platform cites information. Then measure the results before you expand to the other. That’s not a hedge. That’s how you avoid spending six months optimizing for an audience that isn’t yours.

    FAQ

    Q: Is Claude Opus 4.8 better than GPT-5.5 for brand visibility?

    A: Neither is universally better. Claude Opus 4.8 tends to favor technical, in-depth content and serves a more engaged enterprise and developer audience. GPT-5.5 has broader reach and weights brand salience and conversational content more heavily. Which performs better for your brand depends on your audience, content format, and industry vertical.

    Q: Can I optimize for both Claude and GPT-5.5 at the same time?

    A: Yes, but the strategies diverge enough that splitting focus too early often produces mediocre results on both platforms. A better approach is to prioritize the platform where your audience is most active, build a clear GEO footprint there first, then expand. Monitor both from the start so you have baseline data when you’re ready to scale.

    Q: How do I know which AI engine my target audience uses most?

    A: Start with your buyer persona’s professional context. Technical buyers, developers, and enterprise researchers skew toward Claude. General consumers and SMB buyers skew toward ChatGPT. Beyond persona assumptions, AI visibility monitoring tools can show you which platform already generates natural mentions for your brand or your competitors, giving you concrete data rather than educated guesses.

    Q: Does GEO strategy differ between Claude and GPT-5.5?

    A: Significantly. For Claude Opus 4.8, GEO strategy centers on content depth: whitepapers, technical documentation, decision-making frameworks, and authoritative citations in industry publications and forums. For GPT-5.5, strategy focuses on conversational FAQ architecture, broad brand presence across mainstream channels, and short-form content that mirrors how buyers phrase purchase-stage questions. The underlying GEO principles (entity clarity, content extractability, attribution authority) apply to both, but the content format and distribution channel priorities are different.

    Read More

  • Best AI Query Tracking Tools in 2026

    Best AI Query Tracking Tools in 2026

    Search “best AI query tracking tool” and you’ll find dozens of platforms promising full visibility across every AI engine. Dig deeper and most of them only cover one platform, usually ChatGPT, and only count how many times your brand was mentioned. Only 22% of marketers are currently tracking AI visibility and traffic, which means the market is early. But early also means most of the tools haven’t caught up to what “tracking” actually requires in 2026. Exposure Ninja

    The same brand can see citation volumes differ by 615x between Grok and Claude, proving that single-platform tracking isn’t just incomplete — it’s actively misleading. The gap between what most tools measure and what brands actually need is wider than their dashboards suggest. Superlines

    Why Most AI Query Tracking Tools Only Solve Half the Problem

    The core problem isn’t a lack of tools. It’s that most tools were built around the wrong question.

    They ask: “How often is our brand mentioned?” The right question is: “When a high-intent user asks an AI about our category, do we show up, where, with what sentiment, and why?”

    Mention counts are a vanity metric. They don’t tell you your position relative to competitors, the sentiment accuracy of how the AI describes your brand, which third-party sources the AI is pulling from, or whether your visibility is holding steady or quietly eroding. That’s not tracking. That’s scorekeeping without context.

    There’s also the platform silo problem. AI engines have fundamentally different retrieval preferences. Perplexity prioritizes real-time, community-validated sources like Reddit and niche directories. Gemini leans on the Google ecosystem, including Maps and Business Profiles. ChatGPT favors high-trust consensus sources like Wikipedia and third-party review platforms. A tool that only monitors one of these gives you a partial picture at best.

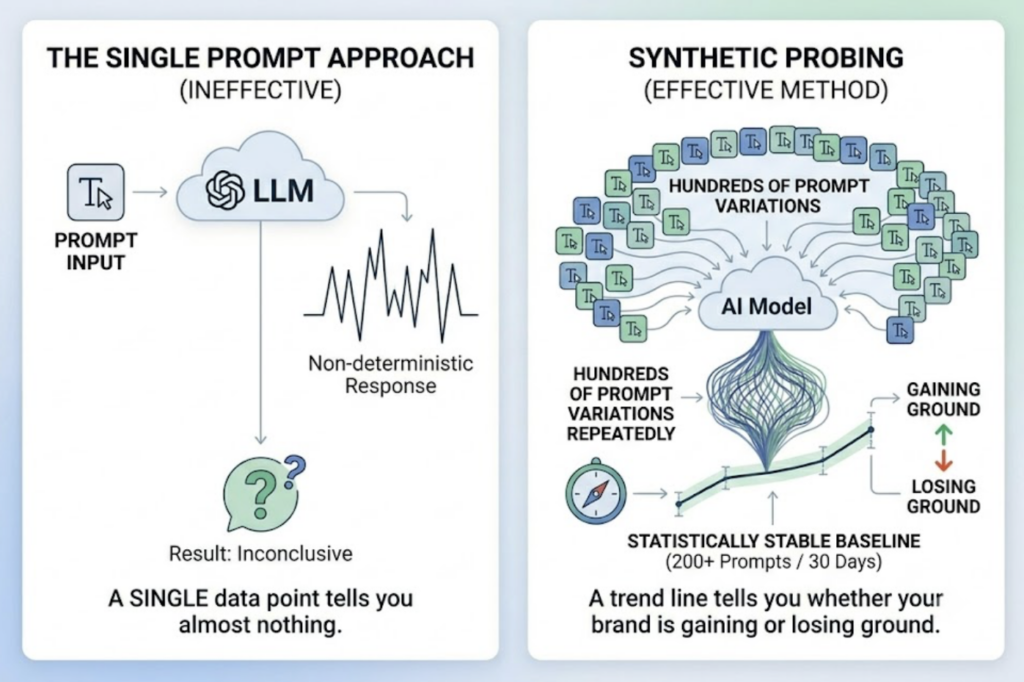
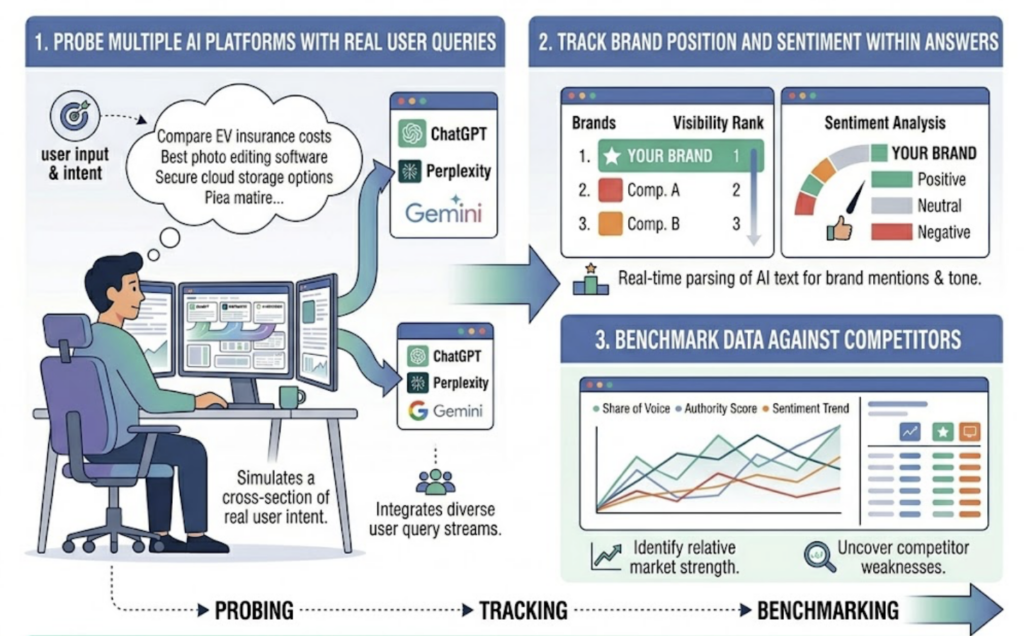
    Real AI query tracking has to happen at the prompt level. Because LLM responses are non-deterministic, you need synthetic probing — running queries across multiple engines at scale to build a statistically meaningful baseline. Without that, you’re not measuring visibility. You’re measuring a random sample.

    The 6 Best AI Search Tracking Tools in 2026

    ToolPlatform CoveragePrimary StrengthBest For
    TopifyChatGPT, Gemini, Perplexity, DeepSeek, Qwen + moreFull-spectrum GEO + actionable executionEnterprises and agencies at scale
    Profound AIMulti-modelSynthetic journey simulationEnterprise competitive benchmarking
    Peec AIMulti-modelHigh-level visibility statsRapid status monitoring
    BrandlightMulti-modelSentiment and reputation monitoringBrand management teams
    Semrush AI ToolkitGoogle AI OverviewsTraditional + AI SEO integrationExisting Semrush users
    Ahrefs Brand RadarWeb mentions + AIGeneral brand mention trackingContent teams

    #1 Topify: Full-Spectrum AI Query Tracking Across Every Major Platform

    Most AI tracking tools tell you that something changed. Topify tells you why, and then shows you what to do about it.

    The difference starts with platform coverage. Topify tracks brand performance across ChatGPT, Gemini, Perplexity, DeepSeek, Doubao, Qwen, and other major AI engines — not just the obvious one. That matters because citation rates, sentiment, and brand mention patterns vary up to 615x across AI platforms, and you can’t optimize what you can’t measure. Superlines

    The tracking architecture runs on seven core metrics: Visibility, Sentiment, Position, Volume, Mentions, Intent, and CVR. Each one answers a different question your brand should be asking. Visibility shows how often you appear across defined prompt clusters. Position tracks your ordinal rank within AI recommendation lists relative to competitors. CVR estimates the downstream probability of an AI mention driving a brand interaction.

    Source Analysis is where Topify separates from the pack. It reverse-engineers the specific domains and URLs that AI platforms are citing in your category. In practice, this means you can identify exactly which third-party publications, review platforms, or directories are shaping your AI presence — and which ones your competitors are dominating that you haven’t touched.

    The Competitor Monitoring layer automates detection of rival citation strategies. You don’t have to guess why a competitor is getting cited instead of you. The data surfaces it directly.

    What makes the platform genuinely different is the One-Click Execution layer. Most tracking tools stop at the dashboard. Topify takes the visibility gap data and translates it into deployable GEO actions — structured content, FAQ sections, Schema updates — that teams can launch without manual workflow setup.

    Topify’s pricing starts at $99/month (Basic) with 100 prompts and 9,000 AI answer analyses per month, scaling to $199/month (Pro) for 250 prompts and 22,500 analyses. Enterprise plans start at $499/month with dedicated account management.

    #2–#6: Other AI Search Tracking Tools Worth Knowing

    Profound AI focuses on synthetic journey simulation — modeling how a decision-maker researches a buying decision across multiple AI touchpoints. It’s strong for enterprise competitive benchmarking but tends to be heavyweight for teams that need faster operational insight.

    Peec AI offers clean high-level visibility stats across multiple models. It works well for rapid status checks and suits teams that want a quick read on brand presence without deep analytics. Coverage and granularity are more limited than enterprise-grade platforms.

    Brandlight centers on sentiment and reputational monitoring. Its strength is tracking how AI engines describe your brand emotionally and factually. A good fit for brand management teams focused on narrative accuracy, less so for teams that need prompt-level query tracking or competitive positioning data.

    Semrush AI Toolkit integrates AI Overview monitoring into the broader Semrush platform. Its main advantage is that existing Semrush users don’t need a new workflow. Coverage is heavily weighted toward Google’s ecosystem, which is a real limitation given how fragmented AI search has become.

    Ahrefs Brand Radar tracks brand mentions across web and AI surfaces. It’s designed for content teams monitoring general brand buzz rather than teams building a structured AI visibility strategy. Prompt-level granularity and competitive citation analysis are not its core focus.

    What to Look for in an AI Query Tracking Tool

    The selection criteria matter more than the feature list. Here’s what actually separates tools worth using from tools that generate reports nobody acts on.

    Prompt-level granularity. Can you define the exact queries your target audience is asking? 88.1% of AI Overview queries are informational, which means the prompts driving AI answers are highly specific. Generic brand monitoring misses most of them. Search Influence

    Platform diversity. ChatGPT Search processes 250–500 million weekly queries and Perplexity around 50 million. These aren’t fringe platforms — they’re where your audience is forming opinions about your category. Your tracking tool needs to cover both, plus Gemini and the platforms growing in your vertical. Digital Applied Team

    Actionability. Only 14% of marketers currently use AI citation tracking, despite 43% naming AI search optimization as a core 2026 strategy. That gap exists because most tools deliver data without direction. The better tools close the loop: visibility gap identified, content action recommended, change deployed. GoodFirms

    Synthetic probing. Real tracking runs queries continuously, not in spot checks. Non-deterministic LLM responses mean any single query result is statistically unreliable. Look for platforms that run queries at scale, across un-cached browser sessions, to build a valid baseline.

    Competitor citation tracking. Knowing your own visibility score is table stakes. Knowing why a competitor ranks above you in AI answers — and which sources are driving that — is where the competitive edge lives.

    Conclusion

    Referral traffic from ChatGPT achieves a 14.2% conversion rate, dramatically surpassing the 2.8% rate from conventional organic search. That’s not a reason to abandon traditional SEO — it’s a reason to build a parallel system that tracks what traditional tools can’t see. Sedestral

    AI query tracking in 2026 isn’t optional for brands competing on information-driven queries. The tools that get you there aren’t the ones with the most impressive dashboards. They’re the ones that cover more platforms than you think you need, go deeper than mention counts, and connect visibility data to executable strategy.

    For most teams, Topify offers the most complete path from measurement to action. Get started here to see where your brand stands across AI platforms today.


    FAQ

    Q: What is AI query tracking? A: AI query tracking is the process of using synthetic probing to measure how AI engines — ChatGPT, Perplexity, Gemini, and others — respond to high-intent user prompts relevant to your brand, products, or category. It goes beyond basic mention counting to track citation quality, position, sentiment, and source attribution at the prompt level.

    Q: How is AI query tracking different from traditional SEO monitoring? A: Traditional SEO tracks your position on a static ranked list of links. AI query tracking monitors the probability of being cited by an LLM inside a synthesized answer — a fundamentally different visibility surface that standard tools like Google Search Console don’t measure.

    Q: Which AI platforms should I track my brand on in 2026? A: At minimum, ChatGPT (general consensus authority), Perplexity (source-heavy real-time discovery), and Gemini (Google-integrated search). Given that citation volumes can vary dramatically between platforms, multi-platform tracking is the baseline standard, not an advanced feature.

    Q: What’s the best AI search tracking tool for small teams? A: Look for platforms that offer prompt-level synthetic probing on entry-level plans. Topify’s Basic plan ($99/month) covers 100 prompts and 9,000 AI answer analyses per month — enough to build a statistically reliable visibility baseline without an enterprise budget.


    Read More

  • AI Query Tracking: Tools, Metrics, and How It Works

    AI Query Tracking: Tools, Metrics, and How It Works

    Search “best AI tracking platform” and you’ll find a dozen tools, each claiming to tell you how your brand performs in AI search. Most dashboards show you a mention count and call it visibility. The difference between a number and an insight is whether the platform can tell you which prompts triggered that mention, where in the AI’s answer your brand appeared, and what sources the model relied on to decide you were worth naming.

    That gap is exactly where most evaluations go wrong.

    What AI Query Tracking Actually Measures

    AI query tracking monitoring is not keyword rank tracking with a new name. It’s a fundamentally different discipline.

    Traditional SEO tools measure positions in a static index. AI query tracking measures how language models respond to specific user prompts, across multiple platforms, on a recurring basis. The same query can produce different answers on ChatGPT, Perplexity, and Gemini, and those answers can shift week over week as models update.

    Because LLM responses are non-deterministic, effective tracking requires what researchers call synthetic probing: submitting hundreds of prompt variations repeatedly to build a statistically stable baseline. A single data point tells you almost nothing. A trend line built from 200+ prompts over 30 days tells you whether your brand is gaining or losing ground in AI-mediated discovery.

    Why Standard SEO Tools Miss This Entirely

    Ahrefs and Semrush are built on a crawl-based model. They index pages, track backlinks, and measure URL positions in search engine result pages. That architecture cannot capture what happens when a user asks ChatGPT a conversational question and never clicks a link.

    The problem isn’t that traditional tools are bad. It’s that they were designed for a fundamentally different environment. AI search is a zero-click environment where the AI synthesizes an answer and the user’s intent is satisfied without visiting a single page. Traffic-to-ranking correlation models break completely here.

    There’s also a contextual sensitivity issue. LLM responses are affected by conversation history, model versioning, and even the phrasing of a question. An AI query tracking system has to simulate real user inquiry patterns, not just check whether a URL is indexed.

    That’s a different architecture entirely.

    The 5 Metrics That Matter in AI Query Monitoring

    Before evaluating any AI query tracking tool, you need to know what you’re measuring.

    Visibility Score is the frequency at which your brand appears across a core cluster of category-relevant prompts. It’s your baseline: are you being mentioned at all?

    Position Tracking goes one layer deeper. It measures where your brand appears in an AI-generated list or synthesis, whether you’re the first recommendation, a buried afterthought, or absent entirely. Position matters because AI users rarely scroll past the first two or three names in a generated answer.

    Sentiment Score evaluates the narrative framing. Is your brand presented as the category leader, a niche option, or a budget fallback? If an AI consistently describes your enterprise software as “great for small teams,” that’s a positioning problem your marketing team needs to know about.

    Source and Citation Analysis is the most strategically valuable metric. It identifies which domains the AI relies on as evidence when it mentions your brand. Knowing which content sources feed the model’s recommendations lets you reverse-engineer your inclusion in the RAG (Retrieval-Augmented Generation) pipeline and target the gaps.

    Conversion Visibility Rate (CVR) tracks the downstream impact: correlating AI visibility spikes with branded search volume and direct site traffic. It connects AI search performance to revenue outcomes.

    These five metrics are not interchangeable. A platform that only tracks mentions is giving you visibility without position, sentiment, or source context. That’s like knowing your ad ran without knowing whether anyone saw it.

    How to Evaluate an AI Query Tracking Platform

    The evaluation criteria most teams use are too shallow. “Does it track ChatGPT?” is a starting question, not a final answer.

    Platform coverage matters because each AI engine uses different training data and citation logic. A platform tracking only ChatGPT will miss what Perplexity (which surfaces cited research links) and Gemini (integrated with Google’s knowledge graph) are saying about your brand. At minimum, your AI query tracking software should cover all three.

    Prompt volume capacity separates serious platforms from lightweight tools. Single-prompt testing produces unreliable data due to LLM non-determinism. Look for platforms that support hundreds of prompt variations per tracking cycle. The research standard is running prompts on a recurring basis to build statistically stable trend data.

    Competitor benchmarking is table stakes for any brand-level decision. You need Share of Voice data: how often your brand appears relative to competitors across the same prompt set, not just your own mention count in isolation.

    Execution capability is the dividing line between a reporting tool and a visibility platform. Does the platform stop at data, or does it tell you what to do? The most useful AI query tracking solutions map citation gaps directly to content actions and can generate structured data or FAQ content to fill them.

    One more thing worth checking: how fresh is the data? AI citation patterns shift as models update. A platform that refreshes weekly is meaningfully less useful than one running continuous monitoring.

    Topify: Built for Prompt-Level AI Visibility

    Topify was built specifically for AI search intelligence. It covers ChatGPT, Gemini, Perplexity, DeepSeek, Doubao, Qwen, and other major platforms from a single dashboard, which matters because brand performance varies significantly across engines.

    The Visibility Tracking feature runs synthetic probing across your defined prompt set and surfaces trends over time, not just snapshots. You can see whether your brand’s mention rate is rising or falling and trace the inflection point to a specific event, such as a competitor publishing a new comparison article that the AI started citing.

    Competitor Monitoring auto-detects which brands appear alongside yours in AI answers and gives you a side-by-side view of Visibility Score, Sentiment, and Position. In practice, this means you can spot a competitor pulling ahead in Perplexity recommendations before it shows up in your traffic data.

    Source Analysis is where Topify’s architecture separates it from most alternatives. It traces the exact domains and URLs that AI platforms cite when mentioning your brand or your competitors. That’s the fastest path to understanding why the AI recommends what it recommends, and what content you need to publish or earn coverage on to shift that equation.

    One-Click Execution closes the loop. You can state your optimization goal in plain language, review the proposed strategy, and deploy it with a single click. No manual content workflow required.

    Topify’s Basic plan starts at $99/month for 100 prompts across 9,000 AI answer analyses. The Pro plan at $199/month expands to 250 prompts. For teams running a high-volume AI query tracking system, the Enterprise plan starts at $499/month with dedicated account management.

    Search Atlas and Other Tools: What They Track (and What They Don’t)

    The AI visibility market currently splits into two categories: legacy SEO platforms that have added LLM tracking modules, and native GEO platforms built specifically for AI search intelligence.

    Search Atlas falls in the first category. It’s a capable multi-channel marketing platform with strong traditional SEO infrastructure. Its LLM visibility module is a meaningful addition for teams already managing SEO, PPC, and local search from one place. The trade-off is depth: these modules tend to extend existing keyword-ranking logic rather than run the synthetic probing infrastructure that native GEO platforms use for granular diagnostics.

    Semrush has taken a similar approach with its AI Toolkit. Ahrefs has added AI Overview tracking. Both are useful for teams that need a single platform across all marketing channels and are willing to accept shallower AI-specific data.

    Native GEO PlatformLegacy Platform + AI Module
    Prompt volume capacityHigh (hundreds of prompts/cycle)Typically lower
    Synthetic probingCore architectureExtension of crawl model
    Source/citation analysisDeepLimited
    Execution capabilityOne-click content actionsManual
    Traditional SEO featuresFocused on AI searchComprehensive
    Best forAI-first brands, GEO specialistsTeams consolidating channels

    The right choice depends on your primary use case. If AI search visibility is your top priority and you’re running a serious GEO program, a native platform is the better fit. If you need one tool managing your entire marketing stack and AI tracking is secondary, a legacy platform with an AI module may be enough.

    Conclusion

    AI query tracking monitoring is no longer a niche capability. It’s becoming a standard part of how brands measure and manage their presence in AI-mediated search. The gap between teams that track this and teams that don’t is widening every quarter.

    The metrics matter, the platform coverage matters, and execution capability matters. Start with the five metrics covered here, check whether your current toolset covers them, and get started with Topify if it doesn’t. Your competitors are already running prompt-level tracking. The question is whether you know what they’re seeing.

    FAQ

    Q: What is an AI query tracking tool? 

    A: It’s a software system that submits user queries to AI platforms like ChatGPT, Perplexity, and Gemini on a recurring basis, then monitors whether and how your brand appears in the generated answers. It tracks mention frequency, position, sentiment, and the sources the AI cites as evidence.

    Q: How is AI query tracking different from traditional rank tracking? 

    A: Traditional rank tracking measures URL positions in search engine result pages, a static index model. AI query tracking measures the semantic presence and recommendation behavior of language models, which generate answers on the fly, don’t always link to sources, and can describe your brand differently on different platforms or even different days.

    Q: Which AI platforms should I track my brand on? 

    A: At minimum, ChatGPT (broadest user base, strong general recommendations), Perplexity (citation-heavy, surfaces source links), and Gemini (integrated with Google’s search infrastructure). Depending on your market, platforms like DeepSeek or Qwen may also be relevant, particularly for global brands.

    Q: What’s the difference between an AI query tracking software and an AI visibility platform? 

    A: Tracking software focuses on data collection and reporting, showing you what’s happening. A visibility platform combines tracking with actionable optimization, telling you what to do about it. The latter typically includes source analysis, competitor benchmarking, content recommendations, and execution tools. That’s the difference between a dashboard and a strategy system.

    Read More

    

  • AI Search Visibility: What It Is and How to Improve It

    AI Search Visibility: What It Is and How to Improve It

    Your domain authority is solid. Your content calendar is full. Your Google rankings look fine. Then a potential customer opens Perplexity, types “best [your category] platform,” and gets a detailed recommendation list. Your brand isn’t on it. Not ranked low, not mentioned in passing. Completely absent.

    Traditional SEO metrics won’t show you that gap. They weren’t built to.

    AI Search Visibility Isn’t the Same as Google Rankings

    Most marketers assume that strong Google rankings translate into AI search visibility. They don’t, and the gap between the two is wider than most teams realize.

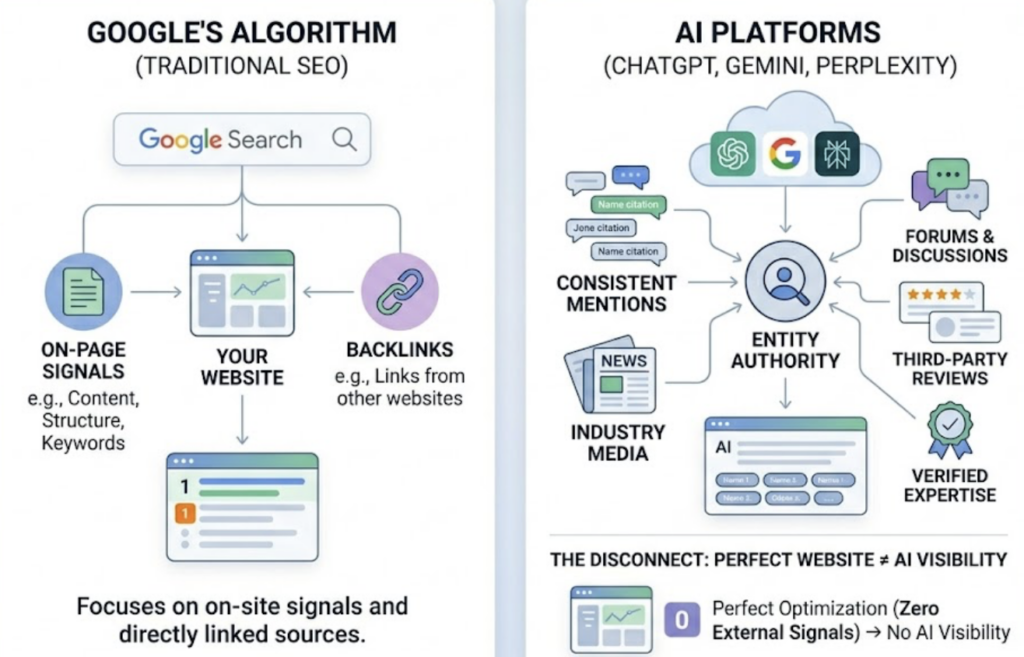
    Traditional SEO optimizes for URL position on a Search Engine Results Page. AI search visibility is a different game entirely: it’s about whether an LLM includes your brand in its synthesized, natural-language answer to a query. There’s no ranked list of blue links. There’s one response, and either your brand is part of it or it isn’t.

    The underlying logic is also different. Google’s algorithm weighs backlinks and on-page signals. AI platforms like ChatGPT, Gemini, and Perplexity rely on entity authority: a cross-platform signal built from consistent mentions across industry media, forums, third-party reviews, and verified expertise. A brand can have a perfectly optimized website and near-zero AI visibility if it hasn’t built that external signal layer.

    That’s the structural shift. AI SEO isn’t an upgrade to traditional SEO. It’s a parallel discipline with different inputs and different measurement systems.

    The 5 Metrics That Define AI Search Visibility

    Tracking AI search visibility starts with understanding what “visible” actually means in an AI-generated response. There are five dimensions worth measuring:

    Visibility Score captures how frequently your brand appears across a representative set of high-intent prompts compared to competitors. It’s the closest equivalent to an overall “ranking,” but applied to AI responses rather than SERPs.

    Mention Rate tracks how often your brand name shows up in AI answers, even without a direct citation link. Some platforms reference brands extensively in text without crediting a source.

    Citation Share measures the percentage of AI-generated answers that explicitly credit your domain as a source. This is particularly relevant for Google AI Overviews and Perplexity, both of which surface source links alongside responses.

    Sentiment Score reveals the narrative framing an AI uses when describing your brand. An AI might mention you first but describe you as “a budget option” when your positioning is enterprise-grade. That disconnect matters.

    Position refers to where in the answer your brand appears. Being the first recommended solution in a list has different commercial value than appearing fifth.

    These five metrics together form what AI search analytics practitioners call a visibility matrix. No single number tells the full story.

    Why Most Brands Score Zero Without Knowing It

    Here’s the problem: absence is invisible. A brand with poor Google rankings can see its position. A brand with zero AI visibility typically has no idea.

    Research into AI search behavior in 2026 shows that 37% of consumers now initiate searches via AI tools, often completing their research without ever clicking through to a website. That’s a significant share of discovery happening in a channel most brands aren’t tracking at all.

    Several structural issues cause brands to fall out of AI answers entirely. Poor content extraction is one: AI engines prioritize content with clear headers and direct answers. Material buried under long introductions rarely gets cited. The owned-site trap is another. Brands that rely exclusively on their own website for authority signals tend to underperform. Approximately 85% of AI brand mentions originate from third-party sources like Reddit, G2, industry publications, and YouTube, not the brand’s own domain.

    There’s also a technical failure most teams don’t catch: robots.txt misconfiguration. Some brands accidentally block crawlers like GPTBot and ClaudeBot, effectively making themselves unreachable to the retrieval processes that feed AI knowledge bases. And content that hasn’t been refreshed in 90 days or more is significantly more likely to lose citation status as models favor fresher evidence.

    None of these failures show up in a standard SEO report. That’s the core challenge with AI brand visibility: you can’t fix what you can’t see.

    How to Measure AI Search Visibility (Step by Step)

    Measuring AI search visibility requires a different toolkit than traditional SEO. Here’s a practical approach:

    Step 1: Define your prompt universe. Identify 20 to 50 high-intent prompts your target audience is likely to enter into AI platforms. These should reflect real buying queries, comparison questions, and category exploration prompts, not just branded searches.

    Step 2: Run systematic queries across platforms. Citation behavior varies by over 600x between ChatGPT and Perplexity for the same brand. Manually running queries on a single platform gives you a partial, misleading picture. Multi-platform probing is non-negotiable.

    Step 3: Track all five metrics. Log whether your brand appeared, where it appeared, what language was used to describe it, and which sources the AI cited.

    Step 4: Monitor for drift. AI citation patterns shift. A brand that appeared in 80% of relevant responses last month might be at 40% this month due to model updates or competitor content gains.

    For teams that need this at scale, Topify automates this entire workflow. Its Visibility Tracking module runs continuous probes across ChatGPT, Gemini, Perplexity, and other major AI platforms, consolidating Visibility, Sentiment, and Position data into a single view. Source Analysis shows which domains the AI is citing to build authority in your category, so you can identify exactly where your content footprint is thin.

    6 Proven Ways to Improve Your AI Search Visibility

    Improving AI search visibility isn’t about gaming algorithms. It’s about building the signals that AI systems trust. These six approaches have clear logic behind them:

    1. Answer-first content architecture. Lead every section with a direct, one-sentence answer to a potential user query. Use H2 and H3 headers as question prompts. AI systems extract content that’s easy to synthesize. Dense, essay-style writing gets skipped.

    2. Build third-party authority. Your own site is not enough. Pursue coverage on industry publications, forums, G2, and YouTube. The majority of AI brand mentions trace back to third-party domains. A mention in a credible industry roundup often does more for AI visibility than a fully optimized blog post on your own site.

    3. Implement structured data and entity markup. Schema markup that clearly defines your brand entity, its services, and its relationships to key topics helps AI systems place you correctly in their internal knowledge representation. This is especially important for brands with ambiguous category positioning.

    4. Keep content fresh. Content older than 90 days loses citation priority as models preference more recent evidence. A content refresh strategy specifically targeting your highest-priority AI search prompts is worth building into your editorial calendar.

    5. Monitor competitor positioning. AI visibility is relative. Knowing your Visibility Score matters less than knowing whether you’re gaining or losing ground against specific competitors. Topify’s Competitor Monitoring module tracks competitor position, sentiment, and citation share automatically, so you don’t have to run manual comparisons.

    6. Use Sentiment Score to catch narrative drift. AI systems sometimes develop inconsistent or inaccurate framings of brands, especially when third-party sources are contradictory. Regular Sentiment monitoring lets you identify when the AI narrative diverges from your actual positioning, so you can address the content gaps causing it.

    This is what AI search optimization looks like in practice: systematic, data-driven, and iterative.

    Choosing the Right AI Visibility Platform

    The selection criteria for an AI visibility platform matter more than most buyers initially realize. Here’s a comparison of what differentiates purpose-built tools from legacy SEO platforms that have added AI features:

    CapabilityLegacy SEO Tools (AI Add-ons)Purpose-Built AI Visibility Platforms
    Platform coverageTypically 1-2 AI engines4+ platforms including ChatGPT, Gemini, Perplexity
    Metrics trackedMention frequency onlyVisibility, Sentiment, Position, Citation Share, CVR
    Source analysisLimited or absentFull domain-level citation breakdown
    Competitor monitoringBasicReal-time comparative tracking
    Execution supportReporting onlyActionable optimization with one-click deployment
    Prompt discoveryManualAutomated high-intent prompt surfacing

    For teams serious about AI search intelligence, the core question is whether the platform bridges the gap between data and action. Reporting that shows your visibility dropped doesn’t help unless it also tells you why, and gives you a clear path to fix it.

    Topify’s One-Click Execution feature addresses this directly. You define your optimization goals in plain language. The platform proposes a strategy and deploys it. No manual workflow required.

    Pricing starts at $99/month for the Basic plan (100 prompts, 4 AI platforms, 9,000 AI answer analyses per month), with Pro at $199/month for growing teams that need 250 prompts and broader seat access. Enterprise plans start at $499/month with dedicated support. You can review full plan details here.

    AI Search Visibility Checklist Before You Start

    Before running your first visibility audit, confirm these fundamentals are in place:

    AreaChecklist ItemStatus
    TechnicalGPTBot and ClaudeBot are not blocked in robots.txt
    TechnicalCore pages load without JavaScript rendering issues
    ContentH2/H3 headers are structured as question prompts
    ContentEach section leads with a direct one-sentence answer
    ContentKey content pages were refreshed within the last 90 days
    AuthorityBrand is mentioned on 3+ third-party domains (G2, Reddit, media)
    AuthorityStructured data / schema markup is implemented for brand entity
    MeasurementPrompt universe of 20+ queries is defined
    MeasurementBaseline visibility data has been captured across 2+ AI platforms
    OptimizationCompetitor visibility data is available for benchmarking

    Running through this list before your first AI search visibility audit will save you from chasing metric improvements while a technical issue is quietly canceling your gains.

    Conclusion

    AI search visibility isn’t coming. It’s already shaping how buyers discover, compare, and shortlist brands. The gap between brands that appear in AI answers and those that don’t will only get harder to close as AI systems accumulate citation history and authority signals.

    The starting point is measurement. You can’t improve a number you’re not tracking, and absence doesn’t announce itself in your existing analytics. Once you know where you stand across platforms and against competitors, the optimization path becomes concrete. Get started with Topify to run your first AI visibility audit and see exactly where your brand stands.

    FAQ

    Q: What is AI search visibility? 

    A: AI search visibility refers to how frequently and favorably your brand appears in responses generated by AI platforms like ChatGPT, Gemini, and Perplexity. Unlike traditional search rankings, it measures whether your brand is cited, recommended, or described in AI-synthesized answers, not just whether you have a high URL position on a results page.

    Q: How do I measure AI search visibility? 

    A: Measurement requires defining a set of high-intent prompts relevant to your category, running those prompts across multiple AI platforms, and tracking five key metrics: Visibility Score, Mention Rate, Citation Share, Sentiment Score, and Position. Tools like Topify automate this process at scale, providing cross-platform data without manual querying.

    Q: How does AI search visibility work differently from traditional SEO? 

    A: Traditional SEO optimizes for URL ranking on Google’s SERP. AI search visibility optimizes for inclusion in an LLM’s synthesized response. The inputs are different too: AI systems weight entity authority built through third-party mentions, not just backlinks and on-page signals. A brand can rank well on Google and score zero in AI search, and vice versa.

    Q: What’s a realistic timeline for improving AI search visibility? 

    A: Content and technical fixes like robots.txt corrections and answer-first restructuring can show results in 4 to 8 weeks. Building third-party authority takes longer, typically 3 to 6 months for meaningful citation share gains. AI visibility is closer to a brand-building effort than an overnight ranking change.

    Read More

  • AI Query Tracking Dashboard: 6 Tools Ranked

    AI Query Tracking Dashboard: 6 Tools Ranked

    Search “AI query tracking dashboard” and you’ll find a dozen platforms claiming to monitor your brand in AI answers. Half of them show you a single number: mentions. The other half cover one platform, usually ChatGPT, and call it coverage. Meanwhile, 37% of consumers now initiate searches via AI-powered interfaces like ChatGPT, Perplexity, and Gemini, and your traditional dashboard can’t tell you anything about what happens there.

    The real problem isn’t finding a tool. It’s finding one that tracks at the query level, across multiple platforms, with enough depth to actually act on the data.

    Most AI Query Tracking Tools Only Measure One Platform. That’s a Serious Gap.

    Here’s what most dashboards miss: they track brand mentions, not query performance. Those aren’t the same thing.

    Brand mention tracking is passive. It captures where your name appeared. AI query tracking is synthetic and active. It monitors how an AI model responds to a specific, high-intent user prompt, like “What’s the best project management tool for remote teams?” or “Which CRM should a SaaS startup use in 2026?” That distinction determines whether your dashboard is giving you awareness data or decision-making data.

    The gap matters because AI platforms use Retrieval-Augmented Generation (RAG) to synthesize unique, conversational answers every time. There’s no static ranking to scrape. Tools that rely on crawling miss this entirely.

    A professional AI query tracking dashboard needs to do at least three things: probe multiple AI platforms with real user queries, track your brand’s position and sentiment within those answers, and benchmark that data against competitors. Most tools on the market do one of the three.

    That’s why choosing the right platform starts with knowing what to look for, not which brand you’ve seen in a LinkedIn ad.

    The 6 Best AI Query Tracking Dashboards in 2026

    Quick comparison before diving in:

    ToolPlatforms CoveredCore StrengthBest ForStarting Price
    TopifyChatGPT, Gemini, Perplexity, DeepSeek, Doubao, Qwen + moreFull-stack: 7-metric dashboard + One-Click ExecutionMarketing teams, agencies$99/mo
    NightwatchChatGPT, Claude, Gemini, Google AIOHybrid SEO + GEO trackingSEO-first teamsCustom
    Otterly AIChatGPT, Perplexity, Gemini, ClaudeUser-friendly prompt trackingSmall teams, solo foundersCustom
    Knowatoa AIMulti-modelDeep sentiment analysisBrand perception focusCustom
    Profound AIMulti-modelSynthetic journey simulationEnterpriseCustom
    Peec AIMulti-modelCompetitive benchmarkingShare of voice analysisCustom

    #1 Topify: The Most Complete AI Query Tracking Platform

    Topify is built around one premise: visibility data is only useful if it tells you what changed, why, and what to do next.

    The dashboard tracks seven core metrics in a single view: visibility score, sentiment, position rank, AI search volume, brand mentions, user intent, and CVR (Conversion Visibility Rate). Most platforms stop at mentions and position. CVR, which estimates how likely an AI-generated response is to drive a user toward your brand, is a metric most competitors don’t offer.

    Platform coverage is the broadest available in 2026. Topify monitors ChatGPT, Gemini, Perplexity, DeepSeek, Doubao, Qwen, and several others, covering both Western and Chinese AI ecosystems. That matters because the 30.6 percentage point gap in brand mention rates between Chinese and international models means your visibility profile looks very different depending on which platforms you’re measuring.

    At the query level, Topify doesn’t just check whether your brand appears. It runs thousands of prompt variations per platform to capture how different phrasings change AI recommendations. A query like “best CRM for startups” and “top CRM tools for early-stage companies” may produce different brand lists. Topify surfaces that variance.

    The One-Click Execution feature closes the loop between tracking and action. You define your optimization goal in plain English, review the proposed strategy, and deploy. No manual workflow required.

    Pricing: Basic at $99/mo (100 prompts, 4 AI platforms, 9,000 AI answer analyses). Pro at $199/mo (250 prompts, 22,500 analyses). Enterprise from $499/mo with a dedicated account manager.

    Best for: Marketing teams and agencies that need a unified AI query tracking dashboard with cross-platform coverage, competitive monitoring, and execution capability in one tool.

    #2 Nightwatch

    Nightwatch sits at the intersection of traditional SEO and GEO tracking. It covers ChatGPT, Claude, Gemini, and Google AI Overviews, and its standout feature is letting users view keyword rankings and AI Overview citations side by side. For SEO teams that don’t want to abandon their existing workflow, that parallel view is genuinely useful.

    The trade-off: depth at the query level is more limited compared to purpose-built GEO platforms. It works well for teams entering AI tracking who want continuity with their SEO stack.

    #3 Otterly AI

    Otterly AI focuses on prompt and mention tracking across ChatGPT, Perplexity, Gemini, and Claude. The interface is clean and accessible, making it a reasonable starting point for smaller teams or solo founders who want visibility data without a steep setup curve.

    Coverage is solid across the major Western platforms. Where it falls short is in advanced analytics: sentiment scoring and competitive gap analysis are less developed than in Topify or Profound.

    #4 Knowatoa AI

    Knowatoa differentiates itself with a proprietary “BISCUIT” framework for brand perception analysis. The platform goes deep on how AI models frame your brand’s identity, positioning, and associations, making it particularly useful for brand managers concerned about narrative drift in AI-generated descriptions.

    It’s a strong choice if sentiment monitoring is your primary use case. Less suited for teams that need query-level tracking across a large prompt set.

    #5 Profound AI

    Profound targets enterprise teams with synthetic customer journey simulation. It models how a prospective buyer would encounter your brand across multiple AI-assisted touchpoints, from initial discovery to consideration. That end-to-end view is valuable for larger organizations running multi-stage campaigns.

    The platform’s depth comes with a complexity cost. Smaller teams typically don’t need journey-level simulation and may find the interface heavier than required.

    #6 Peec AI

    Peec AI’s strength is competitive benchmarking via Share of Voice dashboards. You can see at a glance how your brand’s AI presence compares to specific competitors across queries. For teams whose primary question is “are we ahead of or behind Competitor X in AI answers,” Peec provides a clear answer.

    It’s a monitoring tool rather than an optimization platform, which suits teams at an earlier stage of GEO maturity.

    What a Real AI Query Tracking Dashboard Should Show You

    The six metrics that define meaningful AI query tracking analytics:

    1. Visibility Score: How frequently your brand appears across a representative sample of high-intent prompts. This is your baseline, the number everything else is measured against.

    2. Citation Share: The percentage of AI-generated responses that explicitly reference your domain as a source. High citation share means AI is pulling from your content to construct its answers.

    3. Position Rank: Where your brand appears within an AI-generated list. Being mentioned first carries far more commercial value than being mentioned fifth, and this metric tracks that gap precisely.

    4. Sentiment Score: How the AI frames your brand, the specific language it uses, the attributes it associates with you, and how that compares to your positioning. A brand ranked #2 with positive sentiment often outperforms a brand ranked #1 with neutral or negative framing.

    5. Competitor Citation Gap: Queries where a competitor is cited but your brand isn’t, despite offering the same or better solution. This is where the highest-value optimization opportunities live.

    6. CVR (Conversion Visibility Rate): The downstream impact of AI mentions on branded search volume and direct traffic. Traffic from AI-influenced searches carries strong buying intent: a 23x conversion lift has been observed in AI-influenced search traffic.

    For teams tracking Google specifically: AI Overviews now appear in roughly 47 to 64% of search queries, and when they do, the traditional #1 organic position sees CTR drop to just 8 to 12%, compared to 28 to 34% on non-AIO queries. The best tools for monitoring AI Overviews, including Topify’s dedicated AIO module, track citation sources, sentiment inaccuracies, and competitor pairings within those overviews from a single dashboard.

    Why Your Existing SEO Dashboard Can’t Track AI Queries

    Your GA4, Ahrefs, or SEMrush instance wasn’t built for this.

    Traditional SEO platforms rely on web crawling and backlink analysis. That approach works well for static ranking environments. AI search doesn’t have one. As the research report notes, “AI does not rank URLs; it generates answers.” There’s no position to crawl.

    The zero-click reality compounds the problem. AI summaries resolve user intent without requiring a click, which means a significant portion of high-intent queries never generate a referral visit. Your analytics show zero traffic from those interactions, not because your brand wasn’t mentioned, but because the user got their answer before clicking.

    Entity clarity is the third gap. AI models map relationships between brands and topics. If your brand lacks structured entity signals, schema markup, clear definitions, and FAQ headers, the AI may fail to associate you with your core category even if you rank #1 on Google. An AI query tracking software built for GEO surfaces that disconnect. A traditional SEO tool doesn’t.

    The practical recommendation: keep your existing SEO stack for what it does well. Layer a dedicated AI query tracking solution on top. They’re complementary, not competing.

    How to Set Up an AI Query Tracking Dashboard in Under 30 Minutes

    The setup process is faster than most teams expect.

    Step 1: Define your prompt clusters. Identify 50 to 100 natural language queries your target audience asks AI models. Include brand category queries (“best [category] tool for [use case]”), problem-framing queries (“how to solve [problem]”), and competitor comparison queries (“X vs Y for [scenario]”). This is your tracking foundation.

    Step 2: Establish your baseline. Run your prompt clusters across ChatGPT, Perplexity, and Gemini to capture your current Visibility Score and Competitor Citation Gap. In Topify, this step is built into onboarding. You’ll also want to note your starting Sentiment Score so you have a reference point for future drift.

    Step 3: Set up competitor monitoring. Add your top three to five competitors to the dashboard. The most valuable data isn’t your absolute visibility score. It’s the gap between yours and theirs across the same query set.

    Step 4: Configure alerts. Set notifications for Visibility Score drops below a defined threshold, Sentiment Score changes, and new competitors appearing in your tracked queries. AI models update their training data continuously, and a position you hold today can shift without a visible trigger. Automated alerts are the difference between catching drift early and finding out three months later.

    Get started with Topify on the Basic plan to run this setup in under 30 minutes with 100 tracked prompts across four AI platforms.

    Conclusion

    Tracking AI queries isn’t a future capability. It’s a current gap in most marketing stacks, and the cost of that gap compounds quietly. Every week you’re not monitoring which prompts your competitors are winning, they’re building visibility you’ll need to reclaim.

    The tools exist. The data is accessible. The only question is whether your dashboard is built for search as it works now, or search as it worked two years ago.


    FAQ

    Q: What is an AI query tracking dashboard? A: An AI query tracking dashboard is a platform that monitors how AI systems like ChatGPT, Perplexity, and Gemini respond to specific user prompts, tracking metrics like brand visibility, position, sentiment, and citation share across those answers. It’s distinct from traditional SEO dashboards, which track static keyword rankings and web crawl data rather than synthesized AI responses.

    Q: How is AI query tracking different from traditional SEO tracking? A: Traditional SEO tracking measures where your URLs rank in a crawlable index. AI query tracking measures how AI models reason about your brand when generating a response. AI doesn’t rank URLs; it synthesizes answers, which means there’s no static position to monitor. Specialized AI query tracking software uses synthetic probing, querying models at scale to identify patterns in how your brand is recommended, described, and positioned.

    Q: What’s the best tool for monitoring AI Overviews? A: For teams focused specifically on Google AI Overviews, Topify’s dedicated AIO module tracks citation sources, sentiment accuracy, and competitor pairings within overviews over time. It also flags when your brand drops out of an overview and correlates that with changes in source citations. Nightwatch is a solid option for teams that want AIO tracking integrated into an existing SEO workflow.

    Q: How many prompts should I track to get meaningful data? A: 50 to 100 prompts is a practical starting point for most brands. Prioritize high-intent category queries, problem-framing queries, and competitor comparison queries. Topify’s Basic plan supports 100 tracked prompts, which is enough to establish a solid baseline and identify your most significant Competitor Citation Gaps before expanding coverage.


    Read More

  • AI Search Visibility: What It Is and How to Win It

    AI Search Visibility: What It Is and How to Win It

    Most SEO dashboards show you impressions, clicks, and rankings. None of them tell you whether ChatGPT recommended your brand this morning.

    That’s not a data gap. That’s a visibility gap.

    As AI systems handle more discovery queries, the game has fundamentally changed. Users don’t just Google anymore. They ask ChatGPT, Perplexity, or Gemini. They get a synthesized answer. They act on it. And if your brand isn’t in that answer, it doesn’t exist to that user at that moment.

    That’s what AI search visibility is about. And getting it right requires a different playbook than traditional SEO.

    Your Brand Might Be Invisible Where It Matters Most

    Think about how you found your last software tool, hotel, or B2B vendor. Increasingly, that journey starts with a question typed into an AI interface, not a search bar.

    Perplexity, ChatGPT, Gemini, and Google’s AI Overviews are now functioning as decision-making layers. They synthesize research, compare options, and present recommendations. The brands they recommend get considered. The ones they skip get bypassed entirely.

    Unlike a SERP, there’s no page 2. AI gives you one answer. Either you’re in it, or you’re not.

    That’s the new competitive reality. And most brands haven’t built a system to track it yet.

    What AI Search Visibility Actually Means

    AI search visibility is the measurable frequency, prominence, and sentiment with which an AI system references your brand when responding to relevant user prompts.

    It’s not a ranking. It’s not a traffic metric. It’s a question of whether AI engines recognize your brand as a trustworthy, citable entity within your category.

    Here’s how that works technically. Modern AI search systems use a process called Retrieval-Augmented Generation (RAG). Instead of pulling from a static index, they retrieve information from a curated set of web sources in real time, synthesize it based on the prompt’s intent, and generate a natural language answer. The brands that show up are the ones the AI recognizes as authoritative within their category’s knowledge graph.

    Authority here doesn’t mean domain authority in the traditional sense. It means entity recognition: Is your brand consistently mentioned on trusted third-party sources? Does your content answer questions clearly and directly? Are the right authoritative domains citing you?

    That’s what determines inclusion. Not keyword density. Not backlink volume.

    The Metrics That Actually Tell You Where You Stand

    You can’t improve what you don’t measure. AI search visibility breaks down into five core indicators, each capturing a different dimension of your performance.

    Visibility Score measures how often your brand appears across a defined cluster of relevant prompts. If you’re tracking 100 prompts in your category and showing up in 34 of the AI responses, your visibility score is 34%. That’s your baseline.

    Citation Share captures the percentage of responses where AI platforms explicitly credit your brand as a primary source. This matters especially on Perplexity, which surfaces footnoted citations. High citation share means the AI isn’t just mentioning you but pulling from your content.

    Position tells you where in the response you appear. Being the third brand listed in a recommendation answer is very different from being the first. Both count as “visible.” Only one drives clicks.

    Sentiment Score tracks the framing. AI might mention your brand as “feature-rich but complex” or as “the go-to solution for enterprise teams.” Those framings influence decisions differently. Ignoring sentiment drift is one of the most common oversights in brand monitoring.

    Share of Model compares your visibility against competitors across specific AI platforms. You might dominate Perplexity and underperform on Gemini. That split tells you where to prioritize.

    Topify tracks all five of these, plus two more: an AI Volume metric that surfaces high-intent prompt opportunities, and a CVR (Conversion Visibility Rate) that estimates how likely an AI response is to drive a user toward your brand. Together, that’s a seven-metric matrix that gives marketing teams actual signal, not vanity stats.

    What Good AI Visibility Looks Like in Practice

    Concrete examples make this easier to grasp.

    A project management SaaS company starts monitoring 80 prompts like “best tools for remote team collaboration” and “how to manage engineering sprints in 2026.” After three months of GEO work, their Visibility Score on those prompts climbs from 18% to 41%. ChatGPT now lists them in the top two positions across most recommendation queries. Their organic sign-up rate from AI-referred traffic increases noticeably.

    An e-commerce brand selling ergonomic office equipment starts appearing in Perplexity answers to “best standing desk setups for home offices.” The AI cites a detailed buying guide they published on a third-party tech review site. Source Authority, not their own product page, drove the citation.

    A B2B consulting firm gets mentioned in Gemini’s response to “top strategy consultants for supply chain optimization.” The mention is positive but vague. After running a Sentiment Analysis, they find the AI is pulling from outdated case study content. They update their positioning across key citation sources. Sentiment improves within six weeks.

    In each case, the signal was invisible before AI visibility tracking. The opportunity only became actionable once the right metrics were in place.

    Why Most Teams Are Getting This Wrong

    Most brands aren’t losing AI visibility because they’re doing the wrong things. They’re losing it because they haven’t started doing the right things yet.

    The most common mistake is treating AI search as an extension of traditional SEO. Keyword rankings, meta descriptions, and backlink profiles don’t translate directly to AI citation rates. The rules are different enough that the same optimization playbook often produces no measurable GEO impact.

    The second mistake is the “owned-site fallacy.” Brands pour resources into their own domain and expect AI systems to follow. LLMs weight third-party validation heavily. Mentions in industry directories, analyst reports, trade media, and review platforms are what cross-reference trustworthiness in an AI’s knowledge graph. Your homepage alone won’t get you cited.

    Third is optimizing for keywords instead of prompts. Traditional keyword tools capture “standing desk” or “project management software.” But AI systems respond to natural language questions like “what’s the best standing desk for someone with back pain who works long hours?” Those are fundamentally different targets, and they require fundamentally different content.

    Fourth is ignoring machine-readability. Content written for engagement or keyword density often lacks the “answer-first” structure that LLMs need to extract and cite efficiently. Clear FAQs, structured data, and direct answer formats make content far more extractable.

    That last one is fixable quickly. The others require a strategic shift.

    A Practical Strategy to Improve Your AI Search Visibility

    There’s no shortcut, but there is a repeatable framework. The industry standard is a cyclical Audit → Optimize → Monitorprocess.

    Step 1: Map your prompts. Identify the 50 to 100 most critical questions your target customers ask in your category. These aren’t keywords. They’re the actual conversational queries that trigger AI summaries. Topify’s prompt discovery feature surfaces high-volume AI prompts continuously, so your list stays current as search behavior shifts.

    Step 2: Run a baseline audit. Before optimizing anything, benchmark where you actually stand. How often does your brand appear in responses to these prompts? What position? What sentiment? What are your top competitors scoring? Without this baseline, you’re guessing.

    Step 3: Build citation-worthy content on the right sources. Focus on the specific domains that AI models repeatedly pull from in your category. That typically includes industry analyst sites, established review platforms, trade publications, and forums with high engagement. A single well-placed article on a high-authority source often outperforms ten new pages on your own domain.

    Step 4: Monitor weekly. AI search visibility isn’t static. Competitor content gets published. AI training data shifts. Sentiment can drift in either direction. Weekly tracking with Topify’s Visibility Tracking and Competitor Monitoring keeps you responsive instead of reactive.

    Step 5: Execute with iteration. This is where most teams stall. Topify’s One-Click Execution lets you define your goals in plain English and deploy a structured GEO strategy without building manual workflows. You set the direction. The system handles the execution cycle.

    The teams that win at AI search visibility aren’t the ones with the biggest budgets. They’re the ones with the tightest feedback loops.

    The AI Search Visibility Checklist

    Use this as a starting point before your first GEO review.

    Setup

    •  Define your prompt cluster (minimum 50 prompts across your key categories)
    •  Identify the AI platforms your audience uses most (ChatGPT, Perplexity, Gemini, AI Overviews)
    •  Set up baseline tracking across Visibility Score, Position, Sentiment, and Share of Model

    Content

    •  Audit your top pages for answer-first structure and structured data (FAQ schema, How-to schema)
    •  Identify the third-party domains AI cites most in your category
    •  Publish or pitch content to those high-citation-weight sources

    Competitor Monitoring

    •  Map your top 3 to 5 competitors’ current AI visibility scores
    •  Track which prompts they’re appearing on that you’re not
    •  Monitor competitor sentiment for positioning gaps you can exploit

    Ongoing

    •  Review visibility and sentiment weekly
    •  Refresh content on high-citation sources quarterly
    •  Expand your prompt cluster as new AI search behaviors emerge

    Tools Built for AI Search Visibility

    The tools market has matured significantly in the past 12 months. A few platforms now offer genuine AI visibility tracking. When evaluating any GEO tool, four capabilities matter: multi-model probing across separate AI platforms, source analysis that shows you which domains drive citations, competitor benchmarking with Share of Model data, and execution features that go beyond just reporting.

    Topify covers all four. It tracks brand performance across ChatGPT, Gemini, Perplexity, DeepSeek, and AI Overviews simultaneously, running prompts through each platform’s separate RAG pipeline. The Source Analysis feature shows exactly which domains AI engines are pulling from when they reference brands in your category. Competitor Monitoringprovides real-time benchmarking against rivals across all tracked platforms. And One-Click Execution moves you from insight to action without manual workflow overhead.

    Topify’s pricing is structured around team size and prompt volume:

    PlanPricePromptsAI Answer Analyses
    Basic$99/mo100 prompts9,000/mo
    Pro$199/mo250 prompts22,500/mo
    Enterprisefrom $499/moCustomCustom

    All plans include a 30-day trial. The Basic plan covers ChatGPT, Perplexity, and AI Overviews tracking with four projects and four seats, which is enough for most mid-size marketing teams to get meaningful signal from day one.

    For teams not ready to commit to a platform, Topify also offers a free GEO Score Checker and an AI Search Volume Checker to get an initial read on your brand’s current AI search position.

    Other tools in the space offer partial coverage. Some focus exclusively on citation tracking without execution features. Others cover only one or two AI platforms. The right choice depends on whether you need monitoring only or a full optimization workflow.

    Conclusion

    AI search visibility isn’t a future concern. It’s a current one.

    Every day that ChatGPT, Perplexity, and Gemini answer your customers’ questions without mentioning your brand is a day your competitors fill that space instead. The gap compounds.

    The good news: this is still early enough that building structured tracking and a consistent optimization workflow creates a real moat. Most brands haven’t started yet.

    Start with a prompt audit. Measure your baseline. Then build from there.


    FAQ

    What is AI search visibility? AI search visibility refers to how frequently, prominently, and positively an AI system references your brand when responding to relevant user prompts across platforms like ChatGPT, Perplexity, and Gemini.

    How does AI search visibility work? AI systems use Retrieval-Augmented Generation (RAG) to pull from trusted web sources in real time, synthesize information, and generate answers. Brands that appear on high-authority sources the AI trusts get cited. Brands that don’t, don’t.

    How do I measure AI search visibility? The five core metrics are Visibility Score (citation frequency), Position (rank in AI responses), Sentiment Score (tone of how AI describes your brand), Citation Share (explicit source credits), and Share of Model (performance vs. competitors). Platforms like Topify track all five plus additional business-impact indicators.

    What are the most common mistakes in AI search visibility? The biggest ones are relying only on traditional SEO tactics, focusing exclusively on your own domain, optimizing for keywords instead of conversational prompts, and not monitoring how AI describes your brand over time.

    How much does AI search visibility tracking cost? Topify’s Basic plan starts at $99/month and covers 100 prompts with 9,000 AI answer analyses per month. Pro is $199/month for 250 prompts. Enterprise plans start at $499/month. A free GEO Score Checker is also available for an initial audit.


    Read More

  • How to Track ChatGPT Brand Mentions

    How to Track ChatGPT Brand Mentions

    Your domain authority is solid. Your Google rankings are holding. But none of that tells you whether ChatGPT is recommending your brand, dismissing it, or not mentioning it at all. With 37% of consumers now starting their product searches with AI tools rather than traditional engines, the gap between where your brand ranks on Google and where it stands in AI responses is becoming a real business problem.

    The issue isn’t awareness. Most marketing and SEO teams have heard about ChatGPT brand mentions by now. The issue is that nobody has a clean answer for how to actually track them.

    ChatGPT Brand Mentions Are Not the Same as Google Rankings

    This distinction matters more than most teams realize.

    A Google ranking is a fixed position on a list. You’re #3 for a keyword, or you’re not. ChatGPT brand mentions work differently: every time a user asks a question, the model generates a fresh response. There’s no list. There’s no stable position. Whether your brand gets mentioned depends on the prompt phrasing, the user’s context, and what the model has “learned” to associate with your category.

    Research into how AI platforms handle citations shows that ChatGPT, Gemini, and Perplexity each rely on different retrieval and training signals. A brand that gets strong citations on Perplexity might be nearly invisible on ChatGPT. The underlying mechanics are different enough that you can’t extrapolate from one platform to another.

    The strategic implication: ChatGPT brand mentions function more like reputation signals than rankings. They reflect how the model has synthesized information about your brand across its training data and retrieval pool. Getting mentioned is about trust, not just keyword relevance.

    Why Your Current Toolset Has a Blind Spot Here

    Ahrefs, Semrush, and similar platforms were built for a specific task: tracking what happens on pages that can be crawled, indexed, and ranked. That model doesn’t extend to AI-generated responses.

    Analysis of legacy SEO tool limitations points to three specific gaps. First, traditional tools measure keyword position on a static list. AI platforms generate dynamic answers that shift based on prompt variation. There’s no single “position” to track. Second, classic tools don’t capture semantic framing. When ChatGPT describes your product as “affordable but limited” versus “precise and efficient,” that distinction doesn’t show up in any rank tracker. Third, each major AI platform uses a different RAG (Retrieval-Augmented Generation) pipeline, meaning the citation logic for ChatGPT isn’t the same as for Gemini or Perplexity. Standard crawlers can’t monitor across these ecosystems.

    The result is a genuine monitoring blind spot. Your brand could be losing ground in AI-generated recommendations every week, and you’d have no way of knowing until a client or competitor points it out.

    What Makes ChatGPT Brand Mentions Hard to Measure

    There’s no API that returns “here’s who ChatGPT mentioned today.” Tracking requires what researchers call synthetic probing: systematically querying AI models at scale using variations of real user prompts, then analyzing the responses for brand mentions, position, sentiment, and citation sources.

    A single query gives you one data point. To get statistically meaningful data, you need to run hundreds or thousands of prompt variations across different phrasings, user scenarios, and question types. Then you need to normalize that data into a metric that shows change over time.

    This is why the evaluation criteria for AI visibility tools look different from what you’d apply to a traditional rank tracker:

    Evaluation MetricWhy It Matters
    Multi-platform coverageChatGPT and Perplexity use different citation logic; single-platform data is incomplete
    Statistical sampling depthHundreds of prompt variations required for a meaningful Visibility Score
    Source analysisIdentifying which domains AI cites reveals your content gaps
    Sentiment trackingCaptures how AI frames your brand, not just whether it appears
    Workflow integrationData needs to connect to content execution, not just dashboards

    Most tools check one or two of these boxes. The better ones cover all five.

    Best Tools to Monitor ChatGPT Brand Mentions

    The market for AI visibility monitoring has grown quickly in the past 18 months, but the tools vary considerably in what they actually measure.

    Topify is the most comprehensive option for teams that need full-spectrum ChatGPT brand monitoring. It tracks brand mentions across ChatGPT, Gemini, Perplexity, DeepSeek, and several other major AI platforms simultaneously, which matters because your audience isn’t using just one. The platform’s Visibility Tracking feature runs systematic prompt queries across your target category and aggregates results into a Visibility Score: the percentage of relevant AI responses where your brand appears. That score updates over a rolling window, so you can see whether you’re gaining or losing ground.

    What separates Topify from simpler mention trackers is the Source Analysis layer. It doesn’t just tell you whether ChatGPT mentioned your brand. It tells you which domains the AI cited when it did, and which domains it cited when it recommended a competitor instead. That data directly points to content gaps: articles you haven’t written, FAQs you haven’t answered, data you haven’t published. It turns a monitoring problem into an optimization roadmap.

    The platform also includes Sentiment Analysis (tracking how AI frames your brand, scored 0-100), Competitor Monitoring (automatically detecting which rivals are appearing in your target prompts), and Position Tracking (where your brand appears relative to competitors within the same AI response). For teams that want to act on the data, the One-Click Execution feature lets you define a content or optimization goal and deploy it without building a manual workflow.

    Topify’s Basic plan starts at $99/month and covers 100 prompts and 9,000 AI answer analyses across four projects. The Pro plan at $199/month expands to 250 prompts and 22,500 analyses.

    Other tools in this space include platforms that focus on single-platform tracking or offer lighter-weight mention alerts. They’re worth considering if your budget is limited and ChatGPT is the only platform you need to monitor. That said, evidence from AI search behavior studies suggests that user queries are increasingly distributed across ChatGPT, Perplexity, and AI Overviews simultaneously. Single-platform monitoring tends to give an incomplete picture.

    How to Set Up ChatGPT Brand Monitoring in Practice

    The setup process matters as much as the tool you choose. A few things to get right from the start.

    Define your prompt set carefully. The prompts you monitor should reflect how your actual target audience asks about your category, not how you’d phrase it internally. “Best [category] tools” and “which [category] platform should I use” will surface different brands. Include both.

    Add your top three competitors from the start. ChatGPT brand mentions are relative. A Visibility Score of 40% means something very different if your closest competitor is at 20% versus 80%. Competitor Monitoring in Topify tracks this automatically once you configure your competitive set.

    Look at Source Analysis before you touch your content calendar. Most teams jump straight to “we need more content.” Source Analysis tells you what kind of content is actually driving AI citations in your category. You might find that AI consistently cites comparison pages, or data-heavy resources, or community posts on specific platforms. That’s where your effort should go first.

    Set a 30-day baseline before optimizing. ChatGPT citation patterns shift gradually. You need at least 30 days of data to distinguish a real trend from normal variance. Use Topify’s app to set up tracking now, then review your baseline before making content decisions.

    Turning Brand Mention Data into Actual Strategy

    Data without a workflow is just a dashboard nobody looks at.

    The most useful output from ChatGPT brand mention monitoring isn’t the Visibility Score itself. It’s the pattern behind it. Which prompts produce mentions? Which produce silence? Which produce a mention of your competitor with a framing that positions them as the default choice?

    Those patterns map directly to GEO best practices: structure content for extractability (clear H2s, direct answer-first paragraphs, FAQ sections), address the specific sub-questions AI models break complex queries into, and use consistent entity naming with proper schema markup so the model can unambiguously associate your content with your brand.

    Research on AI citation behavior also shows that small brands can compete effectively on this dimension. AI models prioritize “answerability,” not domain size. A focused, data-rich response to a specific question often gets cited over generic content from a much larger site. That’s a real opportunity for brands that haven’t had it in traditional SEO.

    Track it. Optimize it. Repeat.

    Conclusion

    ChatGPT brand mentions are now a measurable, trackable signal, not a mystery you have to accept. The challenge isn’t philosophical. It’s practical: you need a tool that runs systematic prompt queries at scale, surfaces source-level citation data, and connects that data to what your content team does next.

    The gap between brands that monitor this and brands that don’t is growing. The ones tracking ChatGPT visibility today are building a compounding advantage in AI search, the same way early movers in Google SEO did in the early 2010s. Starting with a 30-day baseline is enough to know where you actually stand.


    FAQ

    Q: How often does ChatGPT update its brand recommendations?

    A: There’s no fixed update schedule. ChatGPT’s recommendations shift as the model’s retrieval pool changes and as your brand’s underlying authority signals (citations, mentions, expert coverage) evolve across the web. This is why tracking over a rolling 30-day window gives more reliable data than point-in-time checks.

    Q: What’s the difference between ChatGPT brand mentions and Google rankings?

    A: Google rankings are based on link equity and keyword relevance, measured against a static index. ChatGPT brand mentions reflect semantic understanding, factual verification, and trust signals synthesized from multiple sources. A high-authority domain doesn’t automatically translate to frequent AI mentions, and vice versa.

    Q: Can small brands get mentioned in ChatGPT?

    A: Yes. Because AI prioritizes “answerability,” a smaller brand that provides precise, data-rich answers to specific questions often gets cited ahead of larger, more generic competitors. The playing field in AI search is more level than in traditional SEO, particularly for niche or specialized categories.

    Q: How do I know if my ChatGPT visibility is improving?

    A: Move away from keyword rank as your primary metric. Monitor Citation Share (the proportion of relevant AI responses where your brand is cited) and Visibility Score (the percentage of category prompts where your brand appears) over a 30-day rolling window. Both are available in Topify’s tracking dashboard.


    Read More