Author: Elsa Ji

  • Why Big Sites Adopt llms.txt Less Than Mid-Size Ones

    Why Big Sites Adopt llms.txt Less Than Mid-Size Ones

    You’d expect the sites with the most content, the biggest engineering teams, and the most at stake in AI search to move first on llms.txt. A 300,000-domain study found the opposite. Sites pulling in 100,001 or more monthly visits adopt the file at a lower rate than sites getting a few thousand visits a month. That’s not a rounding error. It’s a pattern that says something about who actually believes llms.txt does anything.

    The Adoption Number Everyone Quotes Is Only Part of the Story

    Most coverage of llms.txt leads with one headline figure. SE Ranking’s analysis of roughly 300,000 domains found a 10.13% overall adoption rate. That’s the number that gets quoted in every “should you implement llms.txt” post.

    Break that number down by traffic tier and the story changes. Low-traffic sites, the ones getting 0 to 100 visits a month, sit at 9.88% adoption. Mid-traffic sites in the 1,001 to 5,000 visit range come in highest at 10.54%. High-traffic sites, the 100,001-plus tier, land at just 8.27%.
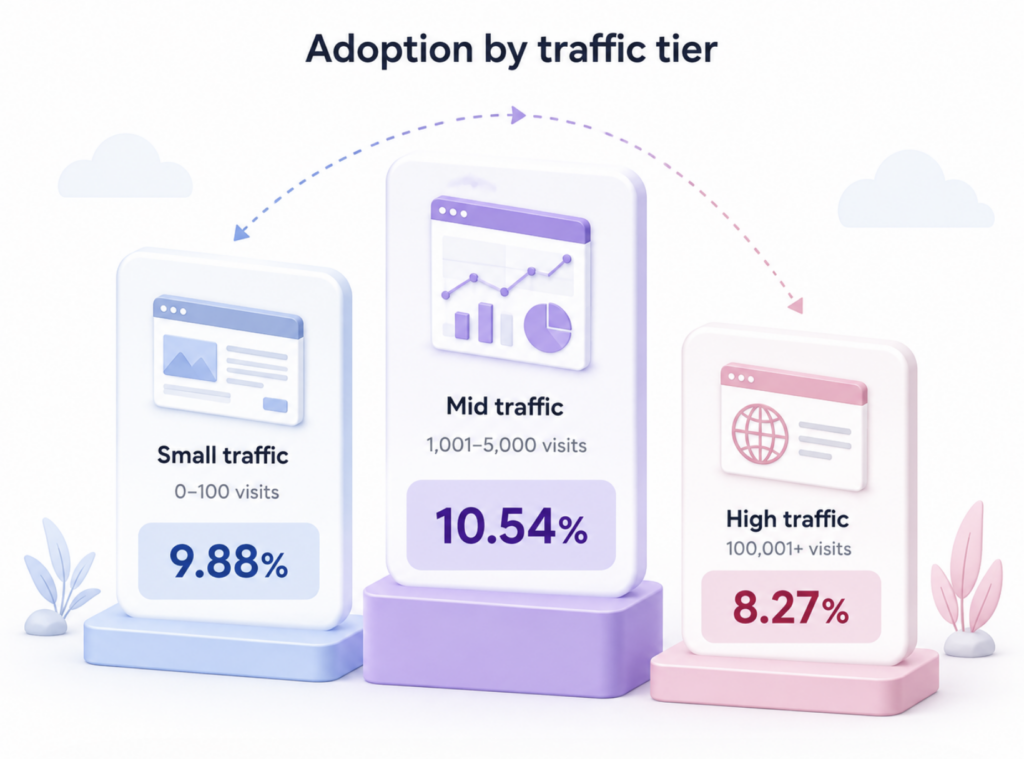
    The largest, most authoritative domains in the dataset are the least likely to have shipped the file. A separate look at the same data found adoption among the top 1,000 domains by traffic sits near zero percent. If llms.txt were becoming an SEO best practice the way XML sitemaps did, you’d expect the opposite curve. You’re not seeing that curve.

    Why Would the Biggest Sites Adopt llms.txt Less

    Look at who actually shipped llms.txt early and the pattern starts to make sense. The named adopters cited across multiple studies read like a developer tools roster: Anthropic, Stripe, Cloudflare, Vercel, Supabase, Pinecone, and LangChain. These are companies with small, technical teams who can ship a Markdown file in an afternoon without a sign-off chain.

    Enterprise sites don’t work that way. A Fortune 500 marketing team can’t add a new file to a production domain without legal review, security sign-off, and a business case. llms.txt has no governance body and no conformance test behind it, which makes that business case hard to write. Nobody wants to be the person who spent three sprint cycles shipping a file with no measurable return.

    Mid-size sites split the difference. They have enough technical staff to implement llms.txt without a committee, and enough curiosity about AI search to try a low-cost, low-risk tactic. That combination is exactly what shows up in the 10.54% figure. It’s not that mid-size sites believe more in llms.txt. It’s that they face less friction trying it.

    Site TypeAdoption RateWhy
    Low-traffic (0-100 visits)9.88%Small teams, easy to ship, nothing to lose
    Mid-traffic (1,001-5,000 visits)10.54%Technical enough to implement, curious enough to test
    High-traffic (100,001+ visits)8.27%Slower approval chains, higher bar for unproven tactics
    Top 1,000 domainsNear 0%Highest scrutiny, least tolerance for unproven SEO bets

    Does Having llms.txt Actually Change Anything

    Adoption rate is one question. Whether the file does anything once it’s live is a separate one, and the evidence there is thin.

    SE Ranking tested this directly. They built an XGBoost model to predict AI citation frequency using dozens of site-level features, including llms.txt presence. Removing the llms.txt variable from the model actually improved its accuracy. The file wasn’t a weak signal. It was noise.

    Google’s position matches that finding. Gary Illyes has confirmed Google doesn’t support llms.txt and has no plans to. John Mueller compared it directly to the long-discredited keywords meta tag. In June 2026, Google updated its AI optimization documentation to state plainly that llms.txt has no effect, positive or negative, on Search rankings or AI Overviews.

    Crawler behavior tells the same story from a different angle. Adoption has genuinely grown, up roughly 8.8x in twelve months to more than 36,000 sites according to Originality.ai. But 97% of those files never get requested by an AI crawler at all. A separate monitoring run across 500 million AI bot events found only a few hundred requests targeting llms.txt directly, out of that entire dataset. GPTBot, ClaudeBot, PerplexityBot, and Google-Extended are still overwhelmingly crawling regular HTML.

    What the Adoption Curve Actually Tells You About AI Visibility

    Here’s the trap in the adoption numbers. Total llms.txt adoption in the top-10k domains climbed from 1.04% to 5.61% in a single year, a 5.4x jump that looks like real momentum on a chart. Most of that growth is platform-driven rather than organic. Shopify alone accounts for over 78% of adopting sites in some samples, because the file gets auto-generated at the platform level, not chosen deliberately by each merchant.

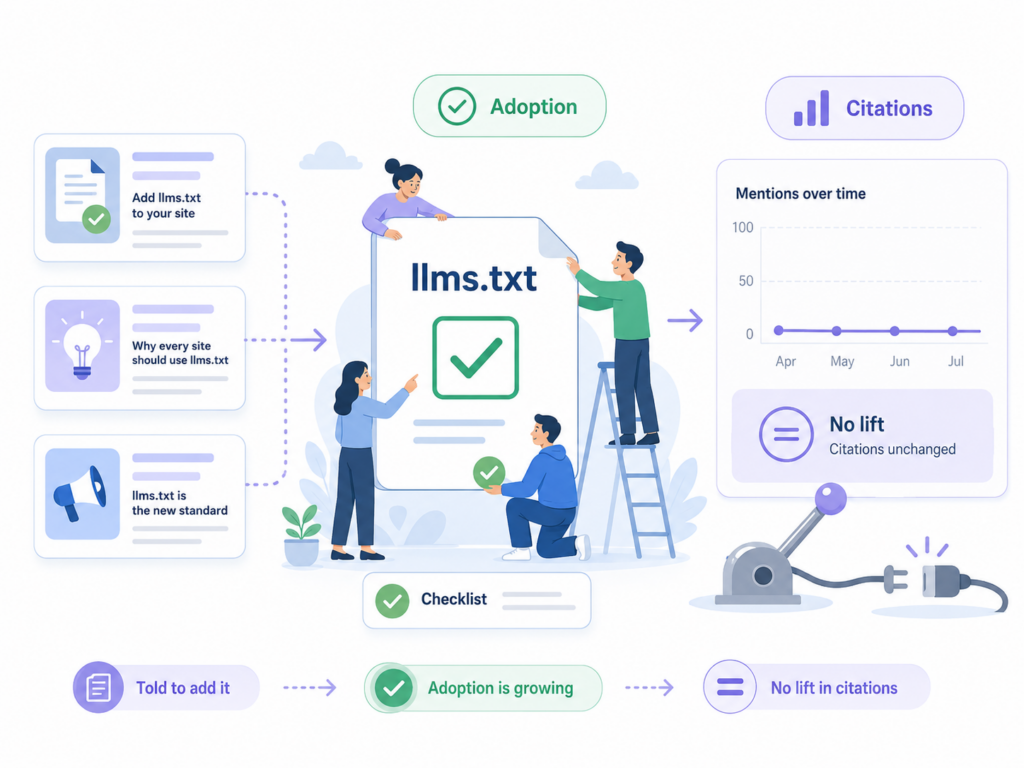
    Growing adoption plus flat-to-zero impact on citations is a specific combination worth sitting with. It means the file is spreading as a checkbox, not as a lever. Teams are adding it because a blog post told them to, not because they’ve measured a before-and-after difference in how often AI systems mention them.
    That gap between “we shipped something” and “we know if it worked” is exactly where most GEO efforts stall. Guessing whether a crawler read a file is a weak substitute for watching what AI systems actually cite. Topify’s Source Analysis tracks the specific domains and URLs that ChatGPT, Perplexity, and Google AI Overviews pull from when they answer prompts in your category, so you’re looking at confirmed citation behavior instead of an unverifiable file request log.

    Visibility Tracking closes the other half of the loop. Instead of asking “did the crawler read my llms.txt,” it asks “did my brand show up in the answer,” across the platforms your buyers actually use. That’s the metric that maps to pipeline, not the one that maps to a file sitting quietly at your domain root.

    If Not llms.txt, Where Should the Effort Go

    The same SE Ranking dataset that found llms.txt added noise also identified what actually moves citation frequency. According to a related analysis of over 150,000 citations, FAQPage schema lifted citation rate by 34% on Perplexity and 28% on ChatGPT. ClaimReview markup on stat-dense pages added a 41% lift on AI Mode specifically. Organization SameAs linkages, the structured data that ties your brand identity across LinkedIn, Crunchbase, and Wikipedia, added a 22% lift by helping models disambiguate who you are.

    TacticMeasured LiftWhere
    llms.txt presenceNo measurable effectAll platforms
    FAQPage schema+34% / +28%Perplexity / ChatGPT
    ClaimReview on stats+41%Google AI Mode
    Organization SameAs+22%Entity disambiguation
    Speakable cssSelector+18%Google AI Mode

    None of these tactics involve a root-level text file. They involve structured markup, entity consistency, and content that answers a question in a self-contained sentence an AI model can lift directly. If your team is deciding where to spend the next sprint, that table is a more defensible starting point than llms.txt.

    Conclusion

    The counterintuitive part of the llms.txt story isn’t that adoption is low. It’s that the sites with the most resources to test new tactics are the ones adopting it the least, while the tactics that actually move citation frequency have nothing to do with the file at all. If you’re deciding where to invest, treat llms.txt as a half-day, low-risk addition at best, and put the real effort into schema, entity consistency, and content structure you can actually measure against AI citation data.

    FAQ

    Q: Does llms.txt help with AI search rankings? 

    A: No measurable effect has been found. Google has confirmed it doesn’t factor into Search rankings or AI Overviews, and a 300,000-domain study found the same for citation frequency.

    Q: Why don’t large websites use llms.txt as often as expected? 

    A: Larger sites typically face longer approval chains and a higher bar for adopting unproven tactics. Early adopters skew toward small, technical teams like developer tools companies that can ship a file without a formal business case.

    Q: Is it still worth implementing llms.txt in 2026? 

    A: It’s low-cost and low-risk to add, but it shouldn’t replace higher-impact work like FAQPage schema, ClaimReview markup, or entity consistency, which have measurable citation lifts.

    Q: How do I know if AI models are actually reading my site? 

    A: File request logs for llms.txt tell you almost nothing, since most files get zero AI crawler requests. Tracking actual citations in AI answers, which tools like Source Analysis are built for, is a more reliable signal.
    Read More

  • The Trust Problem: Why AI Models May Ignore Your llms.txt File

    The Trust Problem: Why AI Models May Ignore Your llms.txt File

    Your team added an llms.txt file to the root of your domain three weeks ago. You expected ChatGPT and Perplexity to start citing your product pages more often. Nothing changed, and that gap between what the file promises and what models actually do with it is the whole problem.

    llms.txt Was Never a Rule Models Have to Follow

    The confusion starts with what llms.txt actually is. It’s a plain-text convention proposed in 2024, and it comes with no backing from any recognized standards body and no enforcement mechanism. AI providers can read it or skip it entirely, and there’s no penalty either way.

    That’s a different situation than robots.txt. Search engines built compliance into their crawlers over two decades, under pressure from a legal and reputational ecosystem that doesn’t exist yet for LLMs. llms.txt has no equivalent history, and no equivalent pressure.

    The data backs this up. A study of nearly 300,000 domains found that only 10.13% had an llms.txt file in place, a fraction of the adoption robots.txt or sitemaps reached. Adoption alone doesn’t prove impact, but it tells you the file hasn’t become infrastructure. It’s still an optional add-on that most sites skip.

    A separate audit went further and checked whether AI crawlers even request the file. Thirty days of CDN logs across 1,000 domains showed zero requests from GPTBot, ClaudeBot, or PerplexityBot. Google’s crawler accounted for 95% of hits, and it was mostly there for search indexing, not llms.txt specifically. If the bots that generate AI answers aren’t fetching the file, no amount of careful formatting inside it changes what the model does at inference time.

    Why Models Choose Sources That Never Declared Anything

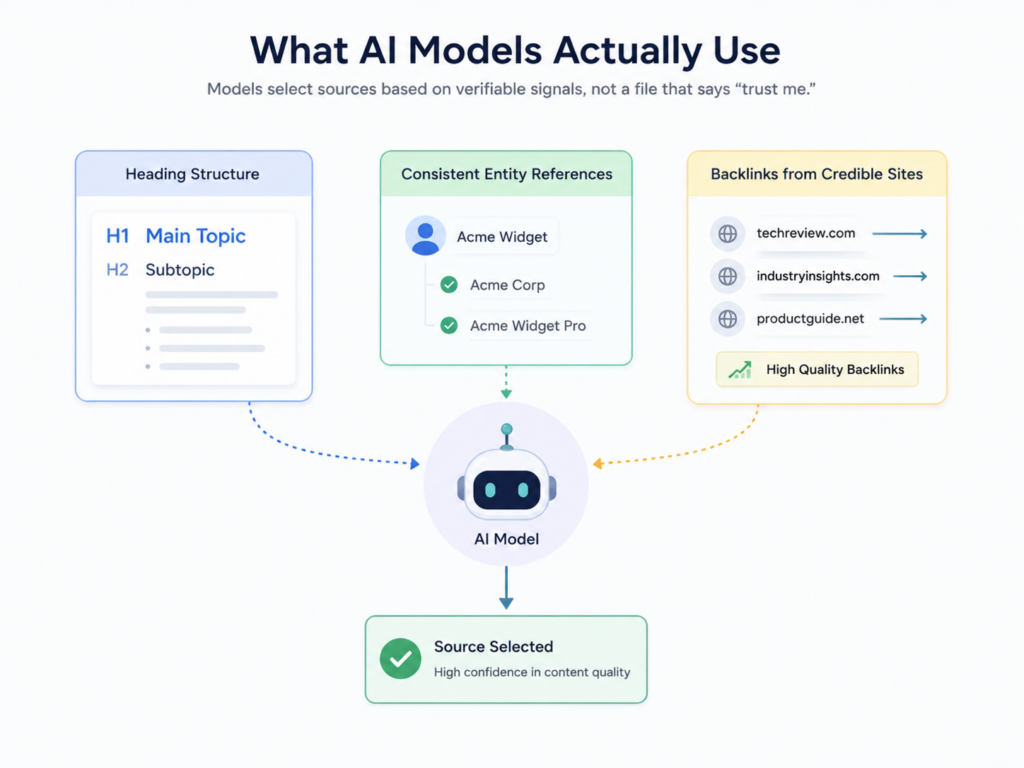
    If llms.txt isn’t the deciding factor, something else is. Models select sources based on signals they can verify independently: heading structure, consistent entity references, and how often other credible sites point back to the same content. None of that requires a file that says “trust me.”

    The same 300,000-domain study found no measurable correlation between having an llms.txt file and citation frequency. In fact, the model performed slightly better on sites without one, which suggests the file isn’t compensating for weak content. It’s just sitting next to it.

    The doesn’t file build trust. The content does.

    Research into what actually predicts citation backs this up with harder numbers. An analysis of pages cited by ChatGPT found 68.7% follow logical heading hierarchies, and pages using three or more schema types show a 13% higher citation likelihood. Those are structural signals a model can check against the page itself. A declaration in a separate file isn’t something it can check against anything.

    The Gap Between Claiming Trust and Earning It

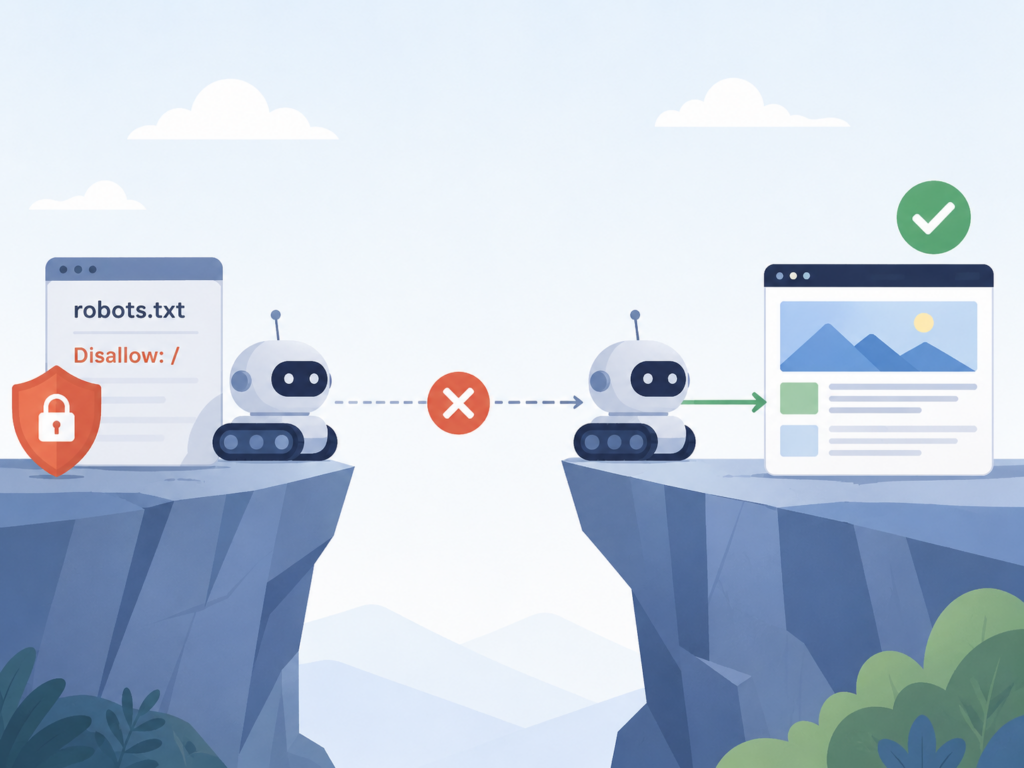
    This is where llms.txt and robots.txt diverge in a way worth naming directly. robots.txt tells a crawler what it’s allowed to do. llms.txt tries to tell a model what to believe about your site, and belief isn’t something a directive file can grant.

    Authority accumulates from external signals: consistent facts about your brand across multiple sources, clear entity identity, and content that other sites reference on their own. Organization schema plays a bigger role here than most teams expect, since it’s often the first thing AI systems use to evaluate whether a source is reliable, before the model ever gets to your product pages.

    Google has been the most direct of any major provider about where llms.txt fits on this. Its own guidance states the file has no effect on Search rankings or AI results, and staff have compared it to the long-abandoned keywords meta tag. As of the latest checks, none of OpenAI, Google, Anthropic, Meta, or Mistral has publicly committed to reading llms.txt in production answer systems. That’s not a rumor about one provider. It’s the absence of commitment across every major one.

    How to Know If Your llms.txt Is Actually Working

    Here’s the part most teams skip: verifying it. Deploying the file and waiting to see if citations change is a guess, not a measurement, because AI answers vary run to run and attribution is inconsistent even for well-established sources.

    A more direct approach is comparing what you declared in llms.txt against what AI platforms actually cite. This is exactly what Topify’s Source Analysis does: it tracks the domains and URLs that ChatGPT, Perplexity, Gemini, and other platforms pull from when answering prompts in your category, so you can see whether your claimed pages show up at all.

    If the pages you listed in llms.txt never appear in the citation data, that’s a clear signal the problem sits with content authority, not file syntax. If unrelated pages on your domain are getting cited instead, that tells you something too: the model already found a path to trust certain content, just not the path you tried to point it toward.

    What to Do When the Model Ignores What You Wrote

    The practical shift here is moving effort away from file maintenance and toward the signals that actually move citation. That means structured content with clear heading hierarchies, consistent entity data across pages, and schema markup that gives models something concrete to verify rather than take on faith.

    Visibility Tracking rounds this out by measuring whether that work is paying off over time, not just in a single snapshot. It’s often useful to pair with prompt-level monitoring, since a brand can be well-cited on one query type and invisible on a closely related one, and averaging the two hides the pattern.

    Once you can see where citations are landing and where they’re not, the next step is usually operational rather than analytical: adjusting which pages get restructured first, which entities need clearer markup, and which competitor is quietly winning the citations you expected to get. That’s less about writing a better file and more about running content decisions off real data instead of assumption.

    Conclusion

    llms.txt isn’t a switch that turns on AI trust, and treating it that way is where most of the frustration comes from. The file can still be worth deploying as a low-effort hedge for future standards, but it won’t compensate for content that lacks structure or authority today. The teams making progress aren’t the ones with the cleanest llms.txt file. They’re the ones tracking what AI platforms actually cite and adjusting based on that data instead of a declaration nobody’s required to read.

    FAQ

    Q: Does llms.txt actually work? 

    A: Current evidence says no, at least not as a direct driver of citations. A 300,000-domain study found no correlation between having the file and citation frequency, and no major AI provider has confirmed reading it in production.

    Q: What’s the difference between llms.txt and robots.txt? 

    A: robots.txt gives crawlers enforceable instructions about what they can access, backed by decades of compliance norms. llms.txt is a voluntary suggestion with no enforcement mechanism and no equivalent adoption history.

    Q: How do I know if AI is reading my llms.txt file? 

    A: Server log audits are one option, filtering for user agents like GPTBot or ClaudeBot, though most audits find little to no activity from these bots on llms.txt specifically. A more reliable approach is tracking whether the pages you listed actually show up in AI citations, which is what source-level monitoring tools are built for.

    Q: If llms.txt doesn’t help, what should I focus on instead? 

    A: Structural clarity and verifiable authority signals, things like consistent heading hierarchies, complete schema markup, and entity consistency across your site. These are the signals models can check directly, unlike a file that simply asserts what your important pages are.

    Read More

  • llms.txt Is Only One Layer. Here’s the Full AI Crawler Permission Stack.

    llms.txt Is Only One Layer. Here’s the Full AI Crawler Permission Stack.

    A content team ships an llms.txt file, checks the box, and moves on. Three months later, ChatGPT still can’t accurately summarize the product page, and server logs show zero requests to the file they spent an afternoon writing.

    That’s not a bug. It’s the current state of llms.txt in practice.

    What llms.txt Actually Controls, and What It Doesn’t

    llms.txt is a Markdown file at the root of a domain that gives AI systems a curated map of a site’s most useful content. It’s a navigation aid, not a gate.

    The data on how AI systems actually treat it is blunt. A study across 300,000 domains found adoption sitting around 10%, and among the fifty most AI-cited domains, only one had the file at all. Monitoring across a 90-day window turned up only a handful of hundred requests to /llms.txt out of over 500 million AI bot events, with GPTBot, ClaudeBot, PerplexityBot, OAI-SearchBot, and Google-Extended overwhelmingly crawling HTML pages directly instead.

    Google has been explicit about where it stands. Google’s Gary Illyes confirmed the company doesn’t support llms.txt and has no plans to, and John Mueller compared it to the discredited keywords meta tag. Separate testing found that eight out of nine sites saw no measurable traffic change after adding the file, and Mueller noted server logs show AI crawlers don’t even check for it.

    None of that means llms.txt is worthless. It costs almost nothing to publish and gives agentic tools a cleaner entry point if adoption grows. But it does mean llms.txt sits in a specific, narrow slot: a declaration of what a site would like AI systems to prioritize, with zero enforcement power behind it.

    The Five-Layer Permission Stack Behind Every AI Crawler Visit

    llms.txt is one layer in a stack that runs from soft declarations to hard technical enforcement. Understanding the full stack matters more than optimizing any single file.

    Layer 1: robots.txt. Standardized as RFC 9309, robots.txt tells crawlers what they’re asked not to fetch. It carries no legal force and doesn’t authenticate anything. Compliance depends entirely on whether a given bot chooses to honor it, and well-behaved crawlers generally do while others historically haven’t.

    Layer 2: llms.txt. As covered above, this is a content curation layer, not a permission layer. It suggests what to read first. It restricts nothing.

    Layer 3: CDN and WAF enforcement. This is where declarations turn into actual blocking. Cloudflare’s shift illustrates the pace of change here. In September 2026, Cloudflare will start blocking “mixed-use” crawlers, ones that blend search, agent, and training traffic, by default on any page carrying ads, unless the site owner overrides it. That follows a year of escalating economics: Cloudflare’s own data showed Anthropic’s crawler fetching roughly 38,000 pages for every referral visit it sent back, and OpenAI’s ratio landing around 1,091 crawls per referral. By June 2026, training-related crawlers made up 50.6% of all bot traffic on Cloudflare’s network, with search-related bots down to just 10.7%.

    Layer 4: Bot identity verification. Declaring rules is one thing. Knowing who’s actually knocking is another. Server logs and User-Agent verification catch crawlers that spoof legitimate identities or ignore declared rules entirely, and they’re the only way to confirm whether Layer 1 and Layer 2 are having any real effect.

    Layer 5: Licensing and legal terms. Terms of service, TDM opt-out clauses, and active litigation now form the outer boundary. Courts have kept public, logged-out scraping legal in cases like hiQ and Meta v. Bright Data, while training-specific disputes like Reddit v. Perplexity are actively testing where those lines sit. This is the layer where “allowed” gets defined in ways no text file can settle on its own.

    Declaring intent isn’t the same as enforcing it.

    Where Most Teams Get the Stack Wrong

    The most common mistake is treating Layer 2 as if it were Layer 3. A team writes a careful llms.txt, feels covered, and never checks whether their CDN is already blocking the same crawlers by default.

    That gap is widening fast. Analysis across Cloudflare’s network found GPTBot is now the most blocked AI crawler by robots.txt directive, and close to 90% of all AI crawler traffic serves training or mixed purposes rather than pure search. Separately, roughly 2.5 million sites now disallow AI training outright, and GPTBot alone is blocked by an estimated 19% of sites.

    Layer conflicts are common and mostly unresolved. If a CDN already blocks GPTBot at the network edge, an llms.txt file that welcomes it does nothing. The technical layer wins by default because it executes; the declaration layer only requests.

    There’s also a data-quality problem inside Layer 2 itself. One estimate put the share of llms.txt files that amount to little more than generic plugin stubs at nearly 40%, which suggests a lot of teams are checking a box rather than building something a machine-reading system could actually use.

    Getting the Permission Layer Right Doesn’t Guarantee AI Visibility

    Here’s the part that trips up even careful teams. Every layer in this stack governs access. None of them govern outcome.

    A site can configure robots.txt correctly, publish a genuinely useful llms.txt, keep its CDN rules aligned, and verify bot identities in its logs, and still never get mentioned when someone asks an AI assistant for a recommendation in its category. Permission is the entry ticket. It says nothing about whether the AI system finds the content worth citing once it’s inside.

    What actually drives citation is a separate set of factors: content structure, topical authority, and how often a brand’s name shows up across the sources an AI model actually pulls from when it forms an answer. That’s a visibility problem, not a permissions problem, and it needs its own monitoring layer.

    This is where Topify fits into the stack, not as a sixth permission layer, but as the measurement layer sitting on top of it. Once the technical access questions are settled, the open question becomes whether ChatGPT, Perplexity, or Google AI Overviews are actually citing the site, how often, and against which competitors. Topify’s Source Analysis tracks the exact domains and URLs AI platforms cite, which is the only reliable way to tell whether a permission configuration is translating into real mentions rather than just theoretical access.

    How to Audit Your Own Permission Stack in Practice

    A working audit runs through all five layers, in order, rather than stopping at whichever one is easiest to configure.

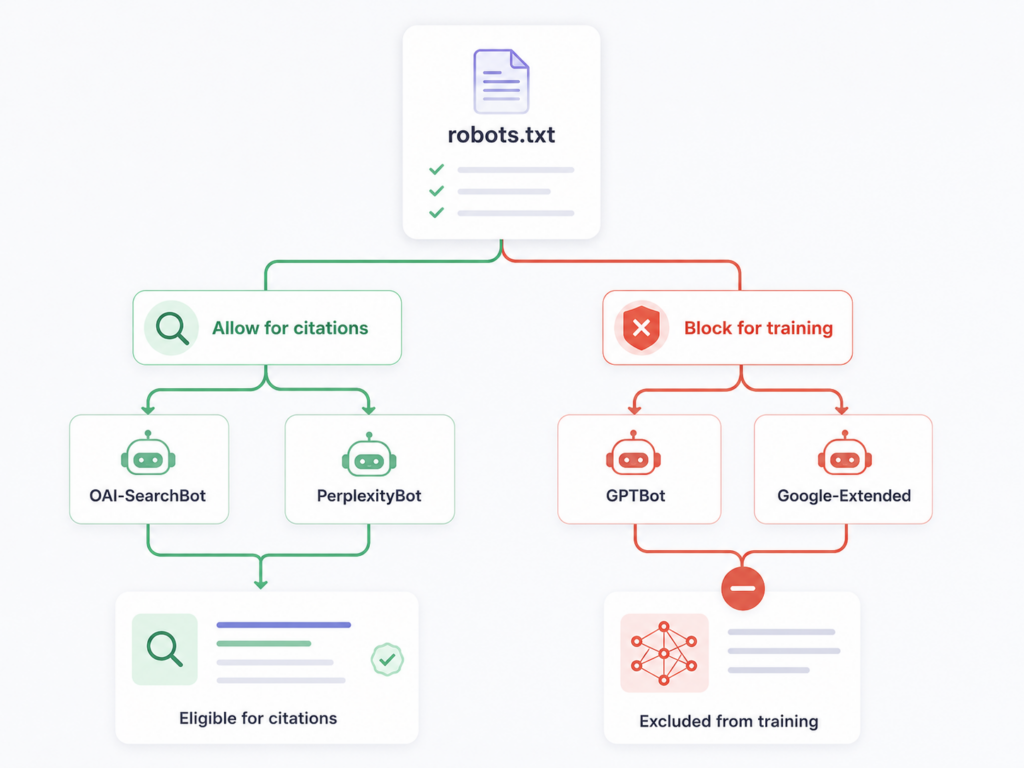
    Start with robots.txt. Confirm it explicitly addresses the AI user-agents that matter for the goal, whether that’s allowing search-oriented bots like OAI-SearchBot and PerplexityBot for citation eligibility, or blocking training-oriented bots like GPTBot and Google-Extended to keep content out of model training.

    Check llms.txt only after that, and only if there’s a genuine use case for agent-driven navigation. Skip generating a full Markdown mirror of every page. Indexable duplicate mirrors dilute crawl budget and can actively suppress the original pages in search results.

    Verify the CDN and WAF layer independently of what robots.txt claims. A rule declared in one place can be silently overridden or duplicated at the network edge, and the only way to know is to check both configurations side by side.

    Pull server logs and filter by known AI crawler user-agents to see what’s actually happening, not what the configuration implies should be happening. A honeypot link inside llms.txt that only an automated reader would follow is a simple way to confirm whether anything is reading the file at all.

    Finally, track outcomes, not just access. Set up ongoing monitoring for whether the brand shows up in AI answers, which sources get cited instead, and how that shifts as the permission layers change. This is the step most audits skip, and it’s the one that actually connects configuration work to business results.

    Conclusion

    llms.txt is real, cheap to publish, and worth having if a site already has its content fundamentals in order. What it isn’t is a permission system. It sits at the declaration end of a five-layer stack that runs through robots.txt, CDN and WAF enforcement, bot identity verification, and licensing terms, with real access control concentrated in the middle three layers, not the file getting most of the attention.

    Getting that stack configured correctly answers one question: can AI systems reach the content at all. It doesn’t answer the more important one: once they can, do they actually recommend the brand. That second question needs its own audit trail, separate from anything a text file at the root of a domain can provide.

    FAQ

    What is llms.txt used for? 

    It’s a Markdown file that gives AI systems a curated list of a site’s most relevant content, meant to help agentic tools navigate faster. It doesn’t restrict access or function as a security control.

    Is llms.txt the same as robots.txt? 

    No. robots.txt tells crawlers what they may not access and is broadly, though not universally, respected. llms.txt does the opposite: it suggests what to read first and carries no restrictive power at all.

    Does Google support llms.txt? 

    No. Google has stated on record that it doesn’t support the format and has no plans to, comparing it to the deprecated keywords meta tag.

    How do I check if AI crawlers are reading my llms.txt file? 

    Filter server access logs for requests to /llms.txt by known AI user-agents, or embed a unique link inside the file that only an automated reader would follow and monitor for traffic to that link.

    Read More

  • Should You Ship llms.txt? A Verdict by Site Type

    Should You Ship llms.txt? A Verdict by Site Type

    Two SaaS companies launched llms.txt the same month last year. One saw its AI Mode citations shift within days. The other checked its server logs three months later and found exactly zero requests for the file. Same standard, same effort, wildly different outcomes.

    That gap is the real story behind llms.txt, and it’s why the “should you ship it” debate keeps going in circles. The people saying yes and the people saying no are usually talking about different kinds of websites.

    What llms.txt Actually Promises to Do

    llms.txt is a plain-text Markdown file you place at your site’s root, something like example.com/llms.txt. It gives large language models a curated map of your content instead of forcing them to parse a full HTML page just to find your value proposition.

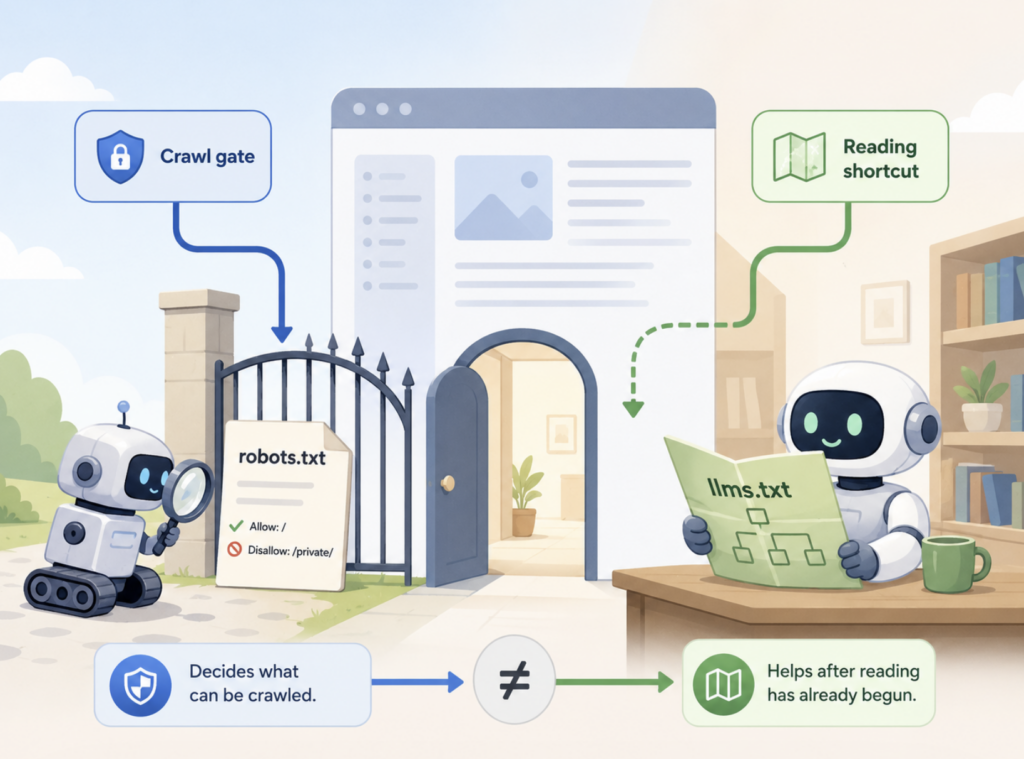
    It’s not a replacement for robots.txt. Robots.txt controls access. llms.txt is closer to a briefing document, one that tells an agent what your site is, who it’s for, and which pages matter most.

    That distinction matters because the two files serve completely different jobs, and confusing them is where a lot of the hype started. Search engines like Google use robots.txt to decide what to crawl at all. llms.txt only helps once something is already reading your site, which is a much narrower promise than most marketing posts about it suggest.

    The Real Question Isn’t “Should I?” It’s “Does My Site Even Need Guiding?”

    Most of the debate skips a more basic question: does an AI system actually struggle to understand your site without help?

    A ten-page marketing site with a clear homepage doesn’t need a curated map. An agent can read the whole thing in seconds. A 400-page documentation set with nested API references and versioned guides is a different story. That’s a genuine navigation problem, and it’s exactly the kind of problem llms.txt was built to solve.

    That’s the filter worth applying before anything else: content volume, structural complexity, and whether AI agents are already interacting with your site in a way that depends on navigation, not just crawling.

    Here’s the part most guides bury: llms.txt fixes a discovery problem, not a content quality problem. If your product pages are thin or your docs are outdated, a tidy index just helps an agent find the weak content faster.

    The Verdict, by Site Type

    Site TypeVerdictWhy
    Documentation & developer platformsShip itCoding agents like Cursor, GitHub Copilot, and Claude Code actively fetch llms.txt from docs sites during real sessions
    SaaS with heavy technical docsShip itSame agent-routing benefit as pure docs sites, plus it’s cheap to maintain alongside existing documentation workflows
    Small marketing sites and blogs (under 1,000 pages)Skip or deferThe homepage and nav already summarize the site well enough that a curated map adds little
    Large ecommerce (10,000+ pages)SkipMaintenance cost of keeping the file accurate outpaces the upside; product data and structured markup do more of the real work
    Small ecommerce (under 1,000 pages)Optional experimentCheap enough to test, but treat it as a minor bet, not a strategy
    News and publisher sitesSkip for nowNo major consumer AI search engine, including ChatGPT search, Perplexity, or Google AI Overviews, has confirmed it reads llms.txt for answering user queries

    Documentation sites are the one category where the evidence is unambiguous. Anthropic, Stripe, Vercel, Cloudflare, and Supabase all ship llms.txt on their developer docs, largely because Mintlify’s late-2024 rollout across hosted docs sites put thousands of platforms on the standard overnight. Coding agents fetch these files as a matter of routine, not as a hopeful bet on future adoption.

    Everyone else is placing a smaller, cheaper bet on a standard that hasn’t been confirmed by the platforms that matter most for organic visibility.

    Where Most Teams Get llms.txt Wrong

    The biggest mistake is treating llms.txt as an AI visibility strategy instead of a small technical convenience. It isn’t a ranking signal, and Google has said so directly.

    Google’s own search advocates have been unusually blunt about this. Gary Illyes confirmed Google doesn’t support llms.txt and has no plans to, and John Mueller went further, saying flat out that “for non-developer sites, I don’t think this makes much sense.” That’s the same Google whose Chrome Lighthouse tool has started auditing for llms.txt presence, which tells you the confusion isn’t just coming from marketers.

    The numbers back up the skepticism. A study of 300,000 domains found llms.txt adoption sitting at 10.13% after roughly eighteen months of industry conversation, and a separate June 2026 sample of the top 1,000 sites put confirmed adoption at 8.7%. Adoption isn’t accelerating the way early advocates predicted.

    Crawler behavior tells the sharper story. An analysis of 137,000 domains found that 97% of llms.txt files received zero crawler hits at all, and of the hits that did land, only 1% came from AI-related bots. A separate 90-day monitoring window across 500 million AI bot visits found roughly 408 requests actually targeting llms.txt files, close to 0.1% of total AI bot traffic.

    That’s a single-sentence gut check worth sitting with: the file most teams built for AI crawlers isn’t the thing AI crawlers are reading.

    A 90-day before-and-after study across ten sites in finance, B2B SaaS, ecommerce, insurance, and pet care found eight of the ten saw no measurable change in AI traffic after implementation, and one site actually declined by 19.7%. The two sites that did see gains had unrelated changes running in parallel, like PR campaigns and restructured comparison pages, so llms.txt wasn’t the cause.

    None of this means the file is worthless everywhere. It means the sites seeing zero return are usually the ones that never needed it in the first place.

    How to Know If It’s Actually Working

    Here’s the honest gap in almost every llms.txt guide: they tell you how to build the file, then stop. Nobody tells you how to check whether it changed anything.

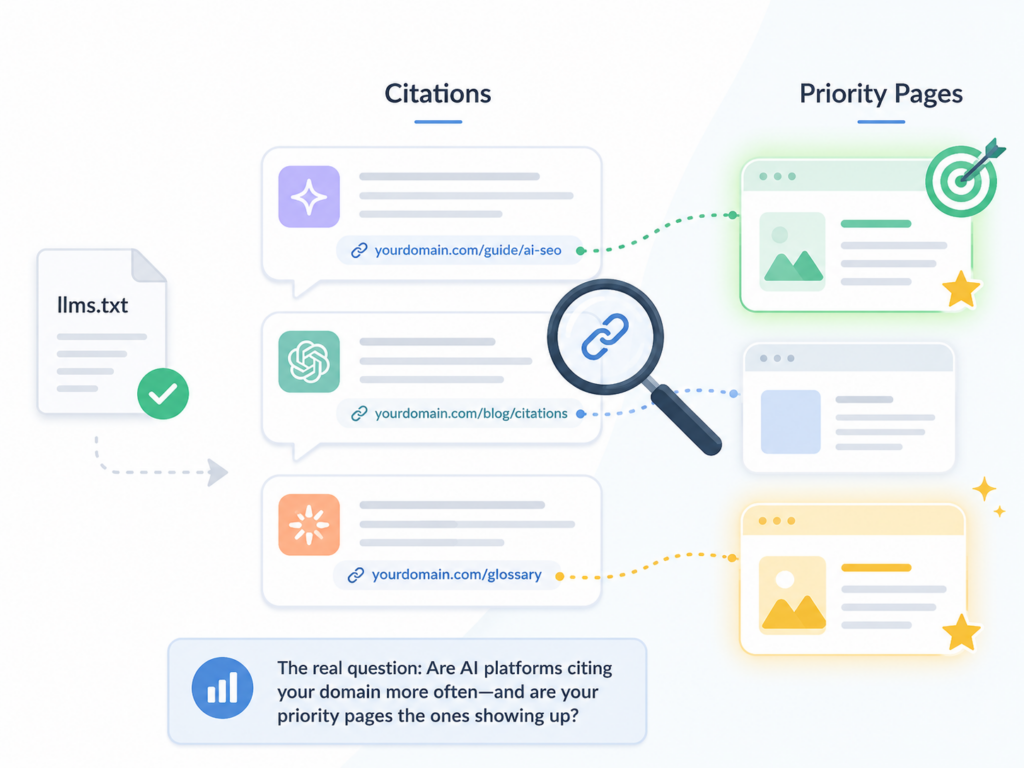
    The right question after shipping llms.txt isn’t “is it live.” It’s whether AI platforms are actually citing your domain more often, and whether the specific pages you flagged as priority are the ones showing up in AI answers. That’s a citation-tracking problem, not a file-formatting problem.

    This is exactly where Topify‘s Source Analysis comes in. It tracks the exact domains and URLs that AI platforms cite across ChatGPT, Perplexity, Gemini, and Google AI Overviews, which means you can see whether your llms.txt-linked pages are actually showing up as sources or whether the file is just sitting unread at your root. Pair that with AI Volume Analytics to check whether the topics your llms.txt prioritizes are even the ones generating meaningful AI search demand in the first place.

    For ecommerce brands weighing the maintenance cost, that visibility matters even more. Shopify reported AI-driven traffic to its stores grew 8x year over year, with AI-powered search orders up nearly 13x. That’s real upside, but it’s upside you can only capture if you’re measuring whether your AI visibility work, llms.txt included, is actually moving the needle instead of guessing.

    Conclusion

    There’s no universal answer to whether you should ship llms.txt, and anyone giving you one is skipping the part where site type changes everything. Documentation-heavy and developer-facing sites have a real, demonstrated case: coding agents use these files today, not hypothetically. Everyone else is looking at a low-cost, low-evidence bet that Google’s own search team has publicly called into question.

    Before you spend an afternoon on it, run through three checks: does your site have enough structural complexity that an agent would actually benefit from a map, is agent traffic a real part of your growth plan, and do you have the bandwidth to keep the file accurate as your site changes. If two of those three are no, your time is better spent on content structure and citation tracking than on a file most crawlers still aren’t reading.

    FAQ

    Q: What is an llms.txt file, exactly?
    A: It’s a plain-text Markdown file placed at a site’s root, typically at /llms.txt, that gives AI systems a curated index of the site’s most important pages instead of asking them to parse full HTML.

    Q: Is llms.txt the same as robots.txt?
    A: No. Robots.txt tells crawlers what they’re allowed to access at all. llms.txt only helps an AI agent navigate content it can already reach, which makes it a convenience layer, not an access control.

    Q: Does llms.txt actually work for AI search visibility?
    A: For consumer AI search like ChatGPT search, Perplexity, or Google AI Overviews, the evidence so far shows little to no measurable effect. For AI coding agents reading documentation sites, it demonstrably works, since tools like Cursor and Claude Code fetch these files during real coding sessions.

    Q: Do I need llms.txt for my blog or small marketing site?
    A: Usually not as a priority. If your homepage and navigation already summarize the site clearly, a curated map adds little. That time is typically better spent on content structure and technical SEO fixes.

    Read More

  • llms.txt: Google’s Split Personality on Skip It vs Audit It

    llms.txt: Google’s Split Personality on Skip It vs Audit It

    Your SEO lead pings you asking whether the site needs an llms.txt file. You check Google’s own AI optimization guide and it says skip it. Then you run a Lighthouse report that same afternoon and see an audit flagging the exact same file. Same company, two contradicting answers, eight days apart. The deadline to make a call on this is this sprint, not next quarter.

    Two Google Teams, Two Opposite Instructions on llms.txt

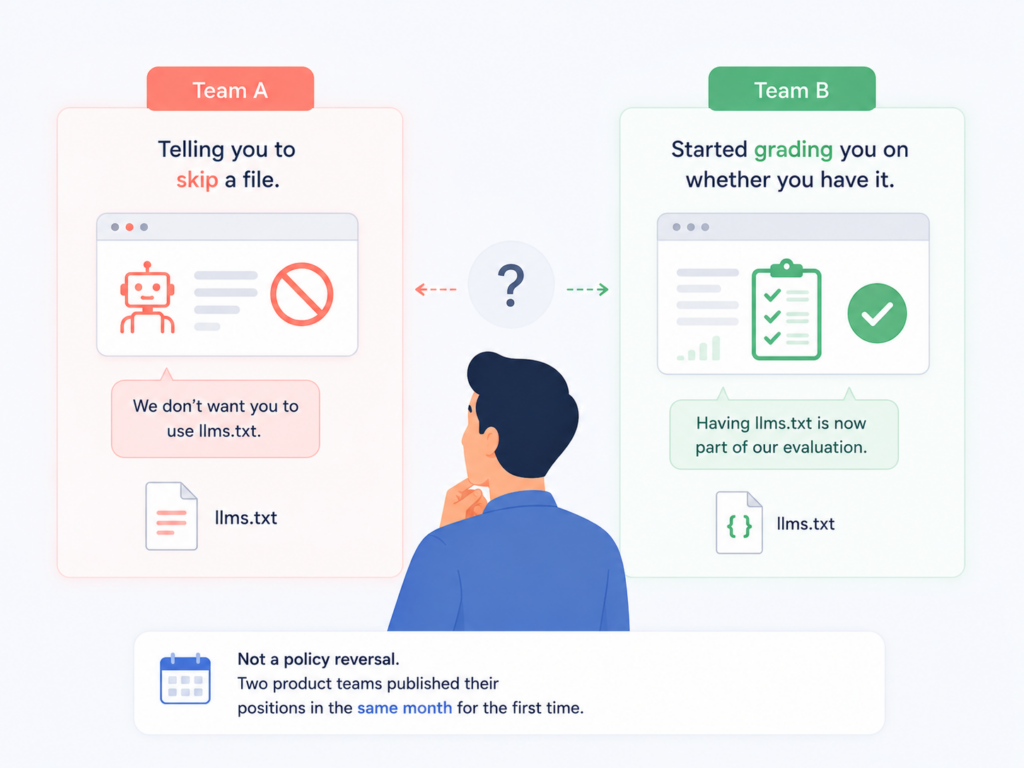
    Here’s the timeline that started the confusion. On May 7, 2026, Chrome’s Lighthouse 13.3 promoted a new Agentic Browsing category from experimental to default, and one of its checks looks for an llms.txt file at the root of the site.

    Eight days later, on May 15, Google Search Central published its first consolidated AI optimization guide. Buried in a mythbusting section, the guide states plainly that site owners don’t need new machine-readable files, AI text files, markup, or Markdown to appear in generative AI search.

    That’s not a policy reversal. It’s two product teams publishing their positions in the same month for the first time. One team is telling you to skip a file. The other team just started grading you on whether you have it.

    Why Search Says Skip It

    Google’s Search Central guide groups llms.txt with content chunking, AI-specific rewriting, and inflated structured data as tactics that don’t move the needle for AI Overviews or AI Mode. The reasoning is straightforward. Googlebot already renders and reads your actual HTML, so a separate summary file adds nothing it doesn’t already have.

    This isn’t a new stance dressed up as news. Search Advocate John Mueller has compared llms.txt to the keywords meta tag, a tag search engines stopped trusting over a decade ago because anyone can write anything into it with zero verification. Back in July 2025, he was already suggesting sites noindex the file so it doesn’t accidentally get indexed and confuse users. Gary Illyes went further at Search Central Live APAC, confirming Google doesn’t support llms.txt for ranking and has no plans to start.

    None of that changed on May 15. It just became official documentation instead of a forum reply.

    Why Chrome Audits It Anyway

    The Lighthouse Agentic Browsing category isn’t measuring what Search measures. It checks four things: WebMCP integration, agent accessibility, layout stability, and llms.txt. None of these produce a weighted 0-100 score the way Performance or SEO categories do, because Google says the standards for the agentic web are still forming.

    The llms.txt check specifically looks at whether an AI browsing agent, the kind that fills out forms or compares products on a user’s behalf, can find a quick summary of your site’s structure without having to crawl every page first. Chrome’s own documentation frames the absence of the file as a minor tax: agents “may spend more time crawling the site to understand its structure” without one.

    That’s a real but narrow use case. It has nothing to do with whether ChatGPT or Google’s AI Overviews decide to cite your brand.

    The Real Signal Google Is Betting On: WebMCP, Not llms.txt

    Most coverage of this split gets stuck arguing about a text file and misses the more telling detail sitting right next to it in the same audit category. WebMCP, the Web Model Context Protocol, is the second item Lighthouse checks, and it’s where Google appears to be putting its actual weight.

    WebMCP lets a site declare structured “tool contracts” directly in HTML attributes or JavaScript, so an agent can execute an action, book a slot, add to cart, submit a form, inside a live session instead of scraping the DOM or driving the UI through screenshots. It showed up in Chrome Canary in February 2026, got featured at Google I/O the same year, and is now running an origin trial in Chrome 149.

    A static file describing your site is a much smaller bet than a protocol that lets agents act on it. Chrome’s roadmap makes that priority obvious even if nobody’s saying it outright.

    Does llms.txt Actually Get Used? The Bot Traffic Says No

    Adoption numbers make the practical stakes clear. Roughly 10% of sites have already published an llms.txt file, but AI bots request it in only about 0.1% of cases. That gap between creation and actual use is close to the widest you’ll see for any SEO tactic in recent memory.

    A broader Ahrefs study of over 137,000 domains found that 28% had published a valid llms.txt, yet 97% of those files got zero bot requests in a full month of tracking. Of the small slice that did see traffic, 96% came from bots generally, and under a fifth came from named AI tools, mostly coding agents like GPTBot and Claude-Code pulling developer docs.

    A file nobody requests can’t be a citation signal. That’s the whole argument, reduced to one sentence.

    A Decision Framework: When llms.txt Is Actually Worth It

    Strip away the noise and the decision splits cleanly along one line: who’s actually consuming your site.

    For most consumer-facing brands, e-commerce stores, SaaS marketing pages, local business sites, the file does nothing measurable. Google Search doesn’t read it for ranking, AI Overviews, or AI Mode, and the traffic data confirms almost nobody is fetching it anyway. Your time is better spent on crawlable pages, non-commodity content, and the standard SEO fundamentals the Search Central guide reaffirms.

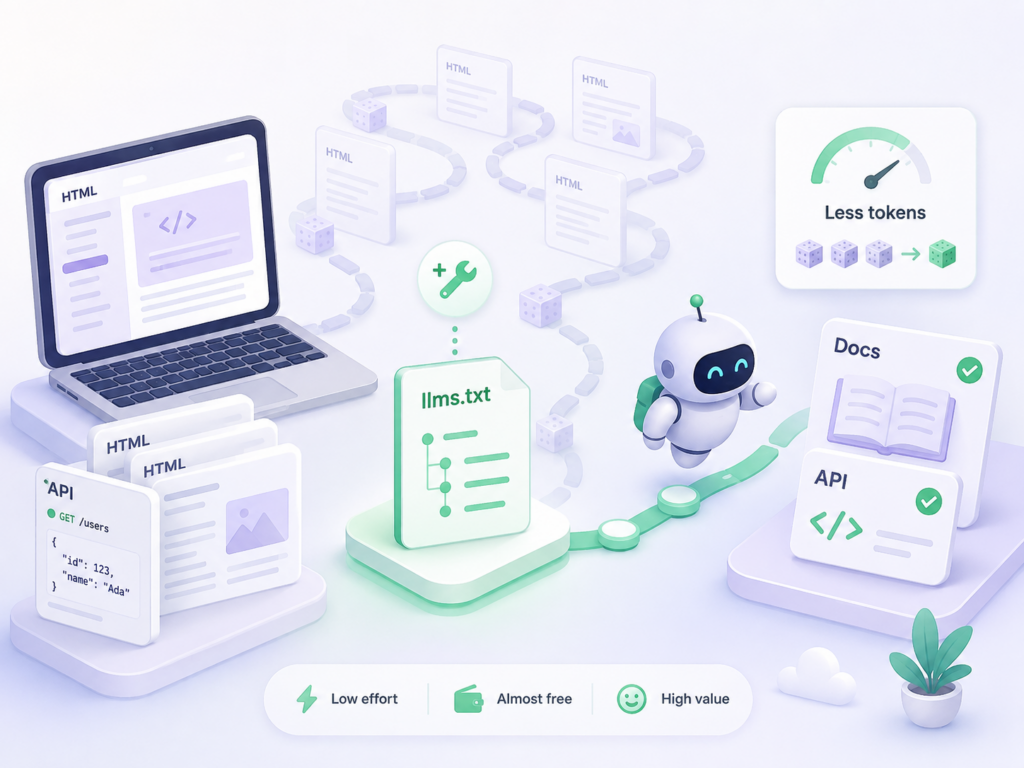
    For developer documentation, API references, or products where coding agents are a meaningful referral source, the calculus flips. Creating the file costs almost nothing, and Mueller himself acknowledged it can act as a token-saving shortcut for AI systems that already read your HTML fine but benefit from a simplified map.

    Here’s the part that matters more than the file format either way. Whether or not you publish llms.txt, you still need to know what AI models are actually saying about your brand and which sources they’re pulling that from. That’s a data problem, not a file problem, and it’s the layer most teams have zero visibility into.

    This is exactly the gap Topify is built to close. Its Source Analysis feature reverse-engineers the exact domains and URLs AI platforms cite when they answer questions in your category, so instead of guessing whether a machine-readable file helped, you see which pages actually earned the citation and which competitor’s content is filling the gap yours left open. Layered on top, Comprehensive GEO Analytics tracks visibility, sentiment, position, volume, mentions, intent, and CVR across ChatGPT, Gemini, and Perplexity in one view, which is the same foundational SEO signal set Google’s own guide points back to.

    Conclusion

    Google Search and Chrome aren’t contradicting each other so much as optimizing for different consumers of your site: one ranks crawlable HTML, the other checks readiness for browsing agents. For nearly every brand outside developer tooling, the answer is to skip the file and put that energy into content and crawlability that actually move AI citations. If you want to know whether that effort is working, get started with Topify and track the citations directly instead of betting on a file format nobody’s asking for yet.

    FAQ

    Q: Does llms.txt help with Google Search rankings or AI Overviews? 

    A: No. Google’s May 2026 AI optimization guide states directly that no special machine-readable files, AI text files, or Markdown are needed to appear in generative AI search features.

    Q: Should developer documentation sites still create an llms.txt file? 

    A: It’s a reasonable low-cost option there. Coding agents like GPTBot and Claude-Code make up most of the small amount of real llms.txt traffic that exists, and Mueller has acknowledged it can help AI systems parse developer references more efficiently.

    Q: Will Lighthouse’s llms.txt audit lower my SEO score if I don’t have the file? 

    A: No. The Agentic Browsing category doesn’t produce a weighted score like Performance or SEO categories do, and a missing file with a normal 404 response is marked Not Applicable rather than flagged as an error.

    Q: What’s the difference between llms.txt and robots.txt? 

    A: robots.txt tells crawlers what they’re allowed to access and is respected across search engines. llms.txt is a self-declared summary of a site’s content with no verification mechanism, and no major AI vendor has committed to treating it as a ranking or citation signal.

    Read More

  • The Data Debunk: Does llms.txt Actually Correlate With AI Citations?

    The Data Debunk: Does llms.txt Actually Correlate With AI Citations?

    Roughly 10% of measured domains have shipped an llms.txt file since the format launched in September 2024. That adoption curve looks like a standard is forming.

    But adoption and effect are two different questions. The one that actually matters for a GEO strategy is whether publishing llms.txt changes how often a brand gets cited in ChatGPT, Perplexity, or Google’s AI Overviews. Three independent studies, covering hundreds of thousands of domains, now have an answer.

    What llms.txt Actually Is, Beyond the Hype

    llms.txt is a Markdown file, hosted at a site’s root, that lists a brand’s most important pages in a clean, script-free format. Jeremy Howard and the team at Answer.AI proposed it on September 3, 2024, hosted at llmstxt.org. The pitch: a language model with a limited context window shouldn’t have to wade through navigation bars and ad scripts to find the content that matters.

    The format itself is intentionally simple. An H1 title, an optional summary paragraph, then grouped links to key pages. Some sites also publish an expanded llms-full.txt that inlines the full text of every linked page into a single fetch.

    That’s the whole spec. There’s no schema, no validator, no runtime API to register with. Anyone who can write a README can ship one in under an hour.

    Why Everyone Assumed llms.txt Would Boost AI Citations

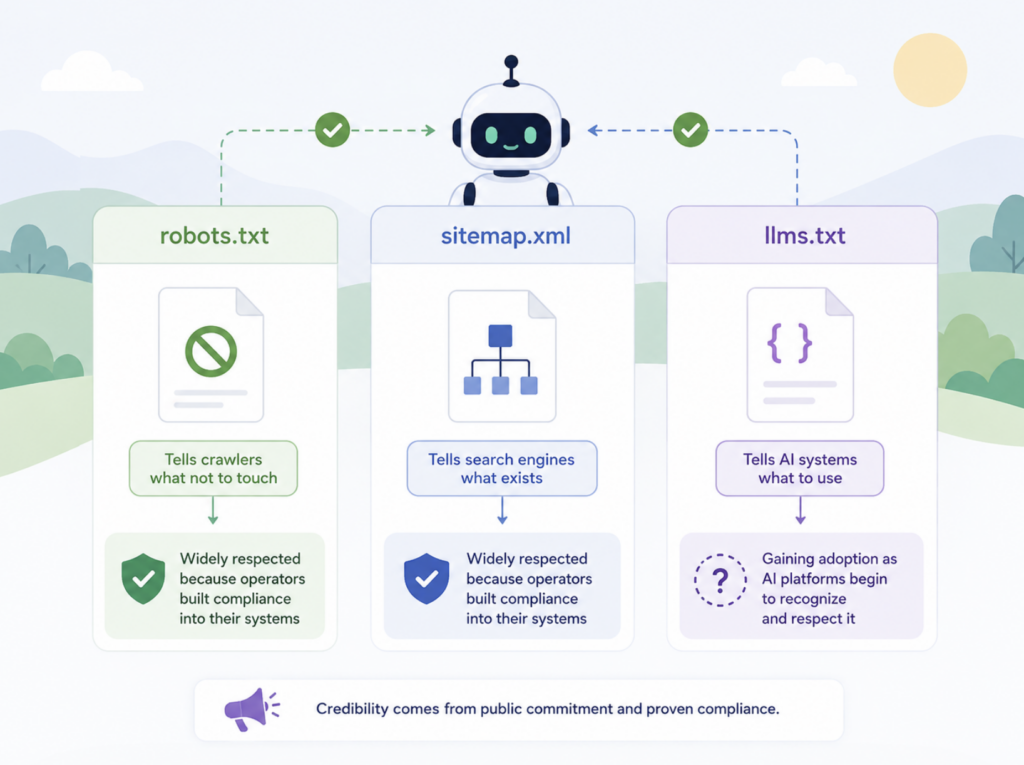
    The marketing pitch around llms.txt borrowed credibility from two older files. robots.txt tells crawlers what not to touch. sitemap.xml tells search engines what exists. Both are widely respected because the crawler operators built compliance into their systems and said so publicly.

    llms.txt skipped that step. No major AI platform has committed, on the record, to fetching it as part of how answers get generated.

    That gap didn’t stop the analogy from spreading. Once a file looks like robots.txt for AI, it’s easy to assume it behaves like one too.

    An assumption repeated enough times starts to look like a fact.

    What the Data Actually Shows About llms.txt and Citations

    This is the part the marketing pitch skips, and it’s where three separate research teams landed on the same conclusion.

    SE Ranking’s analysis is the largest public study to date: roughly 300,000 domains, checked for llms.txt at the root, then measured against how often each domain got cited across major AI-powered answer engines. They ran two tests: a straightforward correlation analysis, then an XGBoost model trained with and without llms.txt as a feature. The model got slightly more accurate once llms.txt was removed, which in plain terms means the file was adding noise, not signal.

    A second study from Trakkr scanned 37,894 AI-cited domains and cross-referenced 323,000-plus citations. The adoption rate came in at 12.7%, and the statistical test (Mann-Whitney U, chosen because citation counts are heavily skewed) returned a p-value of 0.81. That’s nowhere close to significant. Trakkr also found that among the top 50 most-cited domains, only 6% had adopted llms.txt at all, and adoption actually climbed further down the citation rankings. The sites hoping for a lift are shipping the file. The sites already winning citations mostly aren’t bothering.

    Here’s the pattern across both datasets, side by side:

    StudyDomains ScannedAdoption RateCitation Correlation
    SE Ranking~300,00010.13%None found; removing the feature improved the prediction model
    Trakkr37,89412.7%Not statistically significant (p=0.81)

    Two different research teams, two different samples, two different statistical methods. Same null result.

    Why LLMs May Be Ignoring llms.txt Entirely

    The absence of a correlation stops looking surprising once you look at how these systems actually pull information.

    ChatGPT’s web results run through Bing. Gemini runs through Google’s own index. Perplexity maintains its own crawl and index. None of the major consumer AI assistants have a separate, AI-specific discovery mechanism that visits a site’s root directory looking for a special file before generating an answer. They’re layered on top of search infrastructure that was built for a different purpose years earlier, then reads and synthesizes whatever that infrastructure surfaces.

    That’s the mechanical reason llms.txt was always a longer shot than robots.txt. robots.txt works because it plugs directly into the crawler behavior it’s meant to influence. llms.txt asks a model to take a detour to a file most retrieval pipelines were never built to check.

    Google’s own public position backs this up. At the Search Central Deep Dive event in Bangkok in July 2025, Gary Illyes stated plainly that Google does not use llms.txt and has no plans to. John Mueller drew a direct comparison to the keywords meta tag, a signal Google stopped trusting in the late 2000s because site owners control it and site owners can game it. In December 2025, an llms.txt briefly showed up on Google’s own developer documentation site and was pulled the same day. OpenAI, Anthropic, and Perplexity haven’t made an equivalent statement either way.

    The Counterpoint Nobody Should Skip

    Not every voice in this debate lands on the same side, and the strongest pushback is worth taking seriously rather than dismissing.

    Wix’s AI Search Lab argues that Google’s own index contained between 30,000 and 60,000 llms.txt files as of October 2025, which they read as proof that Google is crawling the file even while saying otherwise. They also point out the format’s token efficiency: a clean Markdown index costs a fraction of the tokens a rendered HTML page does, which matters more as agentic workflows lean on tighter context budgets.

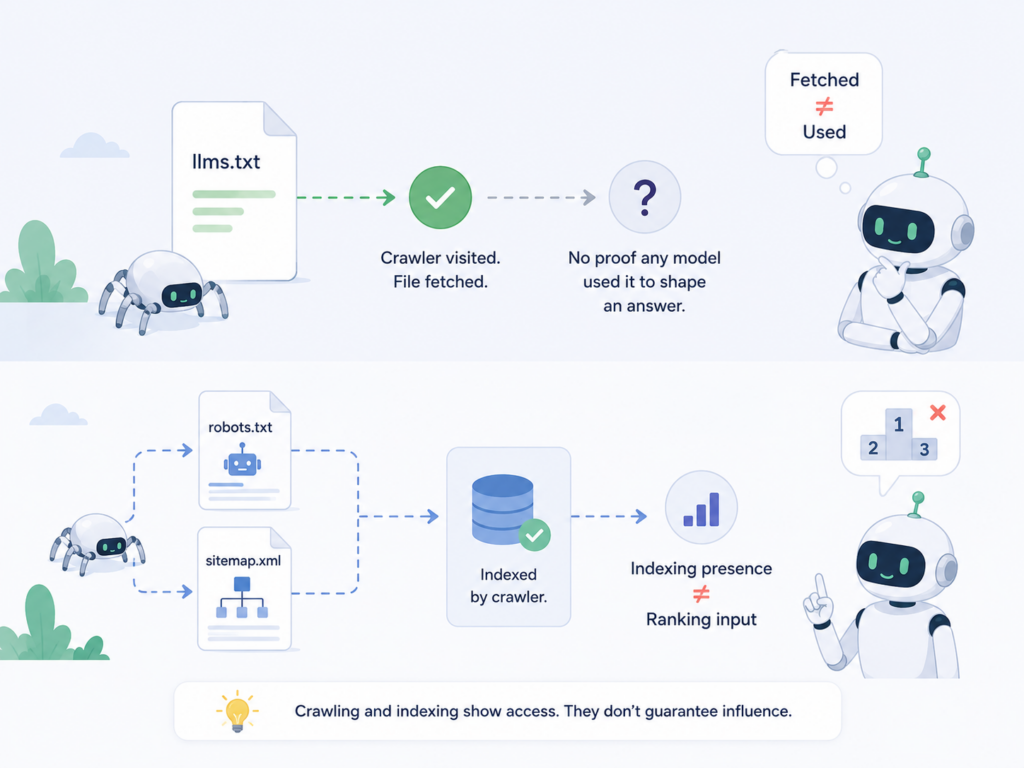
    Both points are fair, and both come with a catch. A crawler visiting a file tells you it got fetched. It doesn’t tell you any model used that fetch to shape an answer. The same crawler indexes robots.txt and sitemap variants too, and indexing presence has never been the same thing as a ranking input.

    Treat llms.txt as cheap insurance for a future where a major provider flips the switch, not as a lever that’s already paying off.

    What Actually Correlates With AI Citations

    If llms.txt isn’t the variable driving citations, the useful question becomes: what is?

    The research points back to the fundamentals GEO practitioners already know. Content that’s structured for extraction, backed by clear entity signals, and already earning citations from other authoritative sources tends to show up more often in AI answers. None of that requires a special file. It requires the same substantive, well-organized content that’s always mattered, now read by a different kind of reader.

    That’s less satisfying than a one-hour fix, but it’s what the data supports.

    The practical problem is that most brands don’t actually know which of their pages are getting cited, or why. Guessing at causes wastes the same budget llms.txt already wasted for a lot of teams. Topify’s Source Analysis feature exists to close that gap. It tracks the exact domains and URLs that AI platforms cite when answering questions related to your category, so you can see which of your own pages are pulling weight and which competitor content is winning the citation instead.

    How to Verify What’s Driving Your Own AI Visibility

    Before spending another hour on llms.txt, it’s worth spending that same hour checking what’s already influencing your citation rate.

    Start with a free GEO score check to get a baseline reading on how your site currently shows up across AI platforms. From there, Comprehensive GEO Analytics tracks visibility, sentiment, and position across ChatGPT, Gemini, and Perplexity over time, so a change in your content strategy shows up as a measurable shift rather than a guess. Pair that with Source Analysis to see which specific pages and domains AI systems are actually citing in your space right now.

    That combination replaces speculation about file formats with a direct read on what’s working.

    Conclusion

    llms.txt is not a proven citation lever. Three studies covering hundreds of thousands of domains agree on that, and Google’s own public statements back it up. That doesn’t make the file harmful. It’s cheap to ship, and if a major provider ever does start using it, having an accurate one already in place costs nothing.

    What it shouldn’t get is your GEO budget or your team’s attention as a primary strategy. The levers that correlate with AI citations today are the same ones that have mattered all along: structured, authoritative content that earns citations on its own merit. Spend the hour verifying what’s actually driving your visibility before spending it on a file the data says isn’t.

    FAQ

    Does llms.txt replace robots.txt or sitemap.xml? 

    No. robots.txt and sitemap.xml are established standards that crawler operators have publicly committed to honoring. llms.txt is a proposal with no equivalent commitment from any major AI platform, so it doesn’t function as a replacement for either.

    Do ChatGPT and Perplexity read llms.txt? 

    There’s no public confirmation from OpenAI, Anthropic, or Perplexity that their retrieval systems fetch or weight llms.txt at runtime. Google has stated it does not use the file. Scattered third-party observations of bot traffic to the file exist, but none rise to an official commitment.

    Is llms.txt worth setting up in 2026?

    If it takes about an hour and you can keep it accurate, there’s little downside. Just don’t treat it as an AI visibility strategy or a paid line item, since the data available in 2026 shows no measurable citation lift from having one.

    What actually influences whether AI platforms cite a brand? 

    Structured, extractable content, clear entity signals, and existing citations from authoritative sources correlate with AI citation frequency far more than any single root-level file.

    Read More

  • 5 Signals Your Brand Is Ready for Agentic Commerce

    5 Signals Your Brand Is Ready for Agentic Commerce

    Your marketing team just got asked a hard question in a planning meeting: are you ready for AI agents to shop on your customers’ behalf? Nobody had a clean answer.

    That’s not surprising. ChatGPT alone now handles roughly 50 million shopping queries a day, and AI-driven traffic to U.S. retail sites grew 393% year over year in the first quarter of 2026. Agentic commerce isn’t a future scenario anymore. It’s a channel your brand is already being evaluated in, whether you’ve set anything up for it or not.

    The problem is most readiness conversations stay abstract. “Get AI-ready” isn’t a checklist. It’s a slogan. This piece breaks agentic commerce readiness into five concrete signals you can check against your own brand today, no guesswork required.

    What Agentic Commerce Actually Changes for Brands

    Agentic commerce means an AI agent researches, compares, and increasingly completes a purchase on a shopper’s behalf, rather than just suggesting where to look. The shopper states an intent. The agent handles discovery, comparison, and checkout, sometimes without the shopper ever visiting your site.

    That shift matters because the rules of persuasion change. A polished product page written for a human browser doesn’t help much if the agent making the decision never renders that page the way a person would. It reads your data, not your design.

    The scale backs this up. McKinsey estimates agentic commerce could account for $3 trillion to $5 trillion in global retail spend by 2030, and Gartner projects AI agents will intermediate $15 trillion in B2B purchases by 2028. Consumer behavior is moving just as fast. 73% of consumers already use AI somewhere in their shopping journey, from getting product ideas to comparing prices.

    Here’s the gap. Demand is real, but most merchants aren’t set up to capture it. That gap is exactly what the five signals below are designed to surface.

    Signal 1: Your Product Data Is Structured for Machines, Not Just Humans

    Check this first: can an AI agent read your price, availability, and product attributes without guessing?

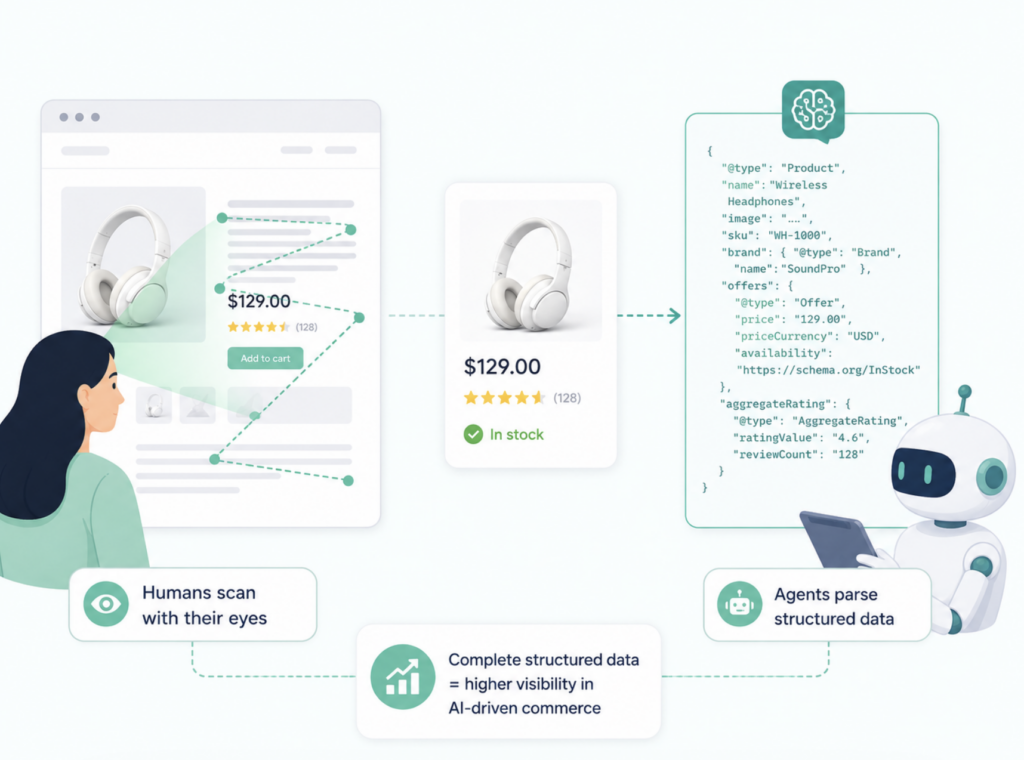
    Most brands still optimize product pages for people scanning with their eyes. Agents don’t scan. They parse structured data, and when it’s missing or incomplete, they either skip your product or misrepresent it. Pages with complete product schema, including pricing, availability, and ratings, see meaningfully higher visibility in AI-driven commerce queries.

    The evidence is consistent across independent tests. One study running comprehensive schema markup against a matched control group over 60 days found a 68% increase in AI citations for the pages with schema in place. Separately, pages combining Product schema with AggregateRating markup were found to be three times more likely to appear in AI recommendations than pages without it.

    The common mistake here isn’t ignorance. It’s assuming your existing SEO schema is “good enough” for agentic use cases. It rarely is. Agents need GTIN or MPN fields for product matching, synced availability status, and complete price and currency fields on every offer, not just a subset of your catalog.

    Signal 2: You Know Where AI Agents Currently Mention or Skip Your Brand

    Structured data gets you discoverable. Visibility tracking tells you whether it’s working.

    Here’s the uncomfortable truth: most brands have zero visibility into how often they show up when someone asks ChatGPT, Perplexity, or Gemini to recommend a product in their category. They’re flying blind on the exact channel that’s growing fastest.

    That’s a problem you can’t fix if you can’t see it. Topify tracks how often your brand gets mentioned in AI shopping and comparison prompts across major platforms, so you can see whether you’re showing up in the exact queries that lead to a purchase decision, not just generic brand searches.

    Without that visibility, you’re guessing at a scale problem. 54% of brands that rank well on Google are never cited by AI at all, which means your traditional SEO rank tells you almost nothing about your agentic commerce readiness. These are separate scoreboards.

    Signal 3: Your Pricing and Availability Data Stays in Sync in Real Time

    An agent that recommends a product with the wrong price or a sold-out size doesn’t just frustrate a shopper. It burns the trust the agent needs to keep recommending your brand at all.

    This is where a lot of otherwise well-prepared brands quietly fail. Their catalog feed updates nightly, or their inventory sync runs on a delay built for human browsing patterns, not machine-speed decision loops. Agents that hit stale data tend to route around it, choosing a competitor whose data they can trust in the moment.

    Real-time sync isn’t a nice-to-have anymore. Merchants are already seeing the payoff for getting this right: orders attributed to AI-powered search carried 14% higher average order values compared to organic search, and traffic from catalog-powered AI search converted twice as well as traffic from general AI search. The brands winning that upside are the ones whose data an agent can trust without double-checking.

    Signal 4: You Can Track Whether AI Recommendations Turn Into Actual Purchases

    Getting mentioned by an AI agent and getting bought by one are two different outcomes, and the gap between them is bigger than most teams assume.

    Consumer surveys show the disconnect clearly. 73% of consumers use AI somewhere in their shopping journey, but only 13% have completed a purchase after being referred by an AI assistant. Another study found a similar pattern: 58% research with AI, but only 17% complete a purchase through it. Visibility without conversion tracking leaves you celebrating a metric that doesn’t pay the bills.

    This is where most brands stop measuring, and it’s the exact gap Topify’s Conversion Visibility Rate is built to close. Rather than counting mentions alone, it estimates how likely an AI recommendation is to actually turn into an interaction with your brand, so you can tell the difference between an agent that name-drops you and one that’s actively steering shoppers your way.

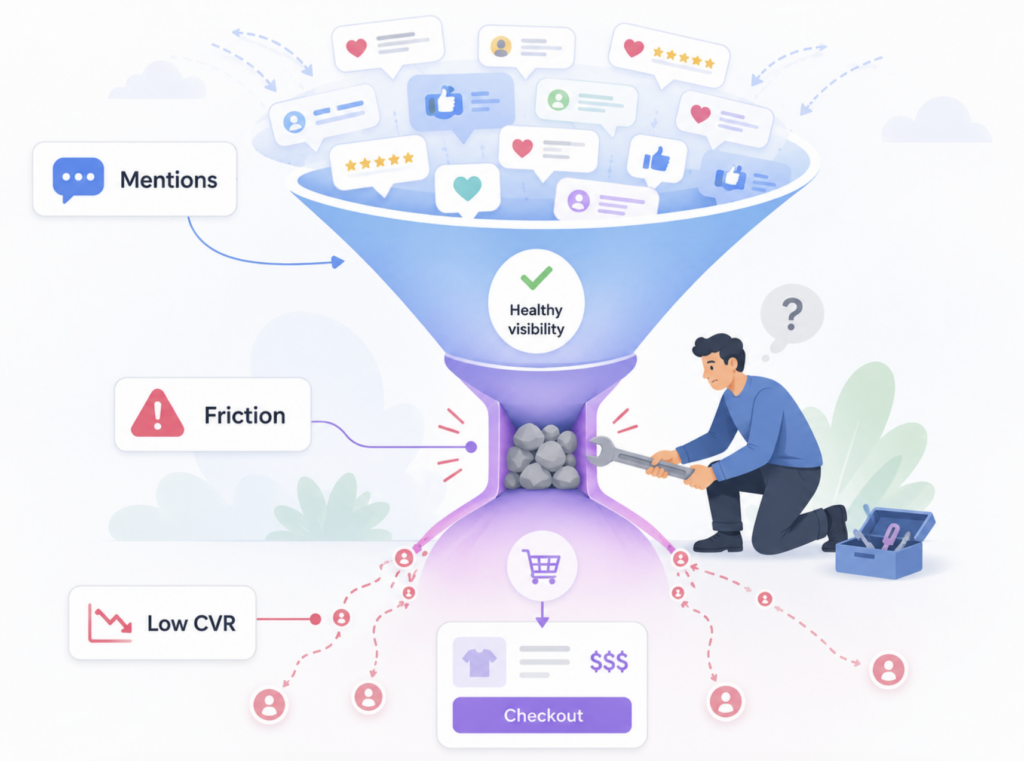
    In practice, that distinction changes what you optimize for. A brand with strong mention volume but weak CVR usually has a friction problem further down the funnel, not a visibility problem. Fixing the wrong end of that funnel wastes budget on a signal that was never the bottleneck.

    Signal 5: You’ve Mapped Which Competitors AI Agents Choose Instead of You

    The last signal is the one most teams skip entirely: do you know who wins when an agent picks a competitor over you for the same shopping intent?

    Agents don’t rank brands the way search engines rank pages. They evaluate options against the shopper’s stated goal, and the brand with clearer data, better reviews signal, or faster fulfillment details often wins, even if it’s less known. Structured, real-time delivery data is one of the deciding factors agents weigh when choosing between merchants, so a competitor with tighter logistics data can beat you on a query where your product is objectively a better fit.

    Without competitor benchmarking, you’re optimizing in the dark. Topify’s competitor benchmarking shows exactly which brands AI engines recommend instead of you for shared prompts, so you can see the pattern instead of guessing at it. Often the fix isn’t a better product description. It’s closing a specific data gap a competitor already closed.

    How to Start Closing the Gaps You Just Found

    If you checked most of these boxes, you’re ahead of most of the market. If you didn’t, the fix isn’t to tackle all five at once.

    Start with Signal 1. Structured data is the highest-leverage, lowest-cost fix, and every other signal depends on agents being able to read your catalog correctly in the first place. From there, move to visibility and conversion tracking, since you can’t prioritize what you can’t measure. Competitor benchmarking comes last, once you know your own baseline well enough to know what “winning” looks like.

    Get started with Topify if you want a single view across visibility, conversion tracking, and competitor benchmarking instead of stitching the picture together from five different tools.

    Conclusion

    Agentic commerce readiness isn’t a single feature you can buy off a shelf. It’s five separate capabilities, structured data, visibility tracking, real-time sync, conversion measurement, and competitor awareness, that together determine whether AI agents can find, trust, and choose your brand. The brands treating this as infrastructure work now will be the ones agents default to later. Start with the signal where your gap is widest, not the one that’s easiest to talk about in a meeting.

    FAQ

    Q: What is agentic commerce, in simple terms? 

    A: It’s when an AI agent handles the shopping process on a person’s behalf, from comparing products to completing checkout, based on the goals the person set rather than manual browsing.

    Q: How is agentic commerce readiness different from regular 

    SEO? 

    A: Traditional SEO rewards keyword relevance and backlinks. Agentic commerce readiness depends on machine-readable product data, real-time accuracy, and measurable outcomes an agent can act on directly.

    Q: How do I know if AI shopping agents are already mentioning my brand? 

    A: You need a visibility tracking tool that monitors AI platforms for the specific shopping and comparison prompts relevant to your category, since generic brand search tools won’t capture this.

    Q: What’s the fastest first step to improve AI agent shopping readiness? 

    A: Audit your product schema first. It’s the foundation every other signal depends on, and gaps here are usually the cheapest to fix relative to the visibility they unlock.

    Read More

  • How to Track Your Brand’s Visibility in Agentic Commerce

    How to Track Your Brand’s Visibility in Agentic Commerce

    Etsy’s stock jumped 16% the week ChatGPT turned on Instant Checkout. That’s not a stat about AI hype. It’s a stat about where purchase decisions are actually happening now, and it’s the reason brands that can’t answer “are we visible inside ChatGPT” are flying blind on a channel that’s already converting.

    Agentic commerce means an AI agent handles the full purchase, from product discovery to payment, without the shopper ever landing on your site. ChatGPT, Gemini, and Perplexity aren’t just answering shopping questions anymore. They’re completing the sale. If your product isn’t part of that conversation, no ad budget fixes it after the fact.

    This guide walks through what’s actually changed, the layers of visibility you need to track, and a step-by-step approach to building that tracking system instead of guessing.

    Your Site Isn’t the Point of Sale Anymore

    For most of ecommerce history, the store was the checkout. That’s no longer true. OpenAI’s Agentic Commerce Protocol and Google’s Universal Commerce Protocol now let AI agents search a product catalog, build a cart, and finish payment inside the chat interface itself.

    ChatGPT already has roughly 900 million weekly users, and AI-driven retail traffic grew 393% year over year in Q1 alone, according to Elogic’s 2026 commerce data. eMarketer projects AI platforms will drive $20.9 billion in retail spending in 2026, nearly four times 2025’s total.

    Your site is no longer the primary conversion surface. It’s the fulfillment layer.

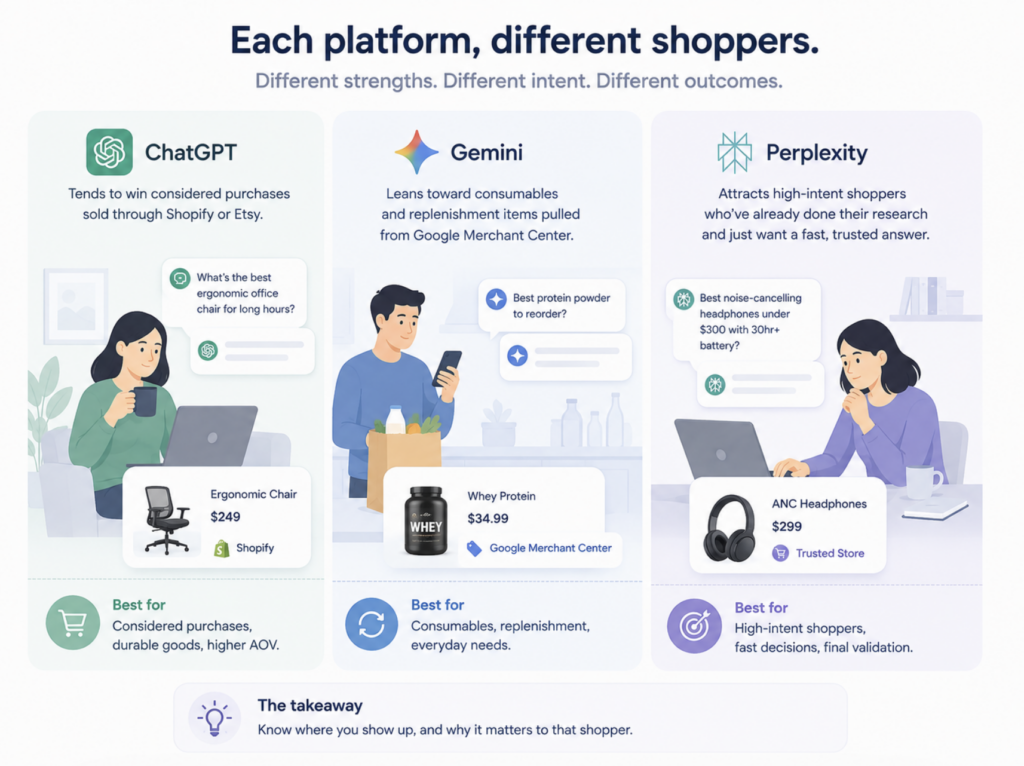
    That shift matters because each platform behaves differently. ChatGPT tends to win considered purchases sold through Shopify or Etsy. Gemini leans toward consumables and replenishment items pulled from Google Merchant Center. Perplexity attracts high-intent shoppers who’ve already done their research and just want a fast, trusted answer.

    Tracking one platform and assuming it represents the whole picture is how brands miss the agentic commerce keyword entirely in their own reporting.

    Why Asking ChatGPT Yourself Doesn’t Count as Tracking

    Most marketing teams start the same way. Someone opens ChatGPT, types a query their customer might ask, and screenshots whatever comes back. It feels like tracking. It isn’t.

    AI answers aren’t static. The same prompt asked twice in one week can surface different brands, different rankings, and different tones. A single good answer tells you nothing about your trend line.

    Manual checks also can’t scale across platforms. Conversion behavior alone proves the point: Claude converts shoppers at 16.8%, ChatGPT sits between 14.2% and 15.9%, Perplexity converts at 10.5%, and Gemini trails at 3.0%, per Elogic’s platform comparison. Each platform is a different audience with different intent, and a single spot check can’t tell you where you stand across all of them at once.

    That’s the gap most brands still can’t see.

    The Three Layers of Agentic Commerce Visibility

    Tracking your brand’s visibility in agentic commerce isn’t one metric. It’s three layers stacked on top of each other, and most tools only cover the first.

    Presence. Can the agent even find your product? This depends on whether your catalog is properly fed through Shopify’s Agentic Storefronts, Google Merchant Center, or direct ACP integration, and whether your product pages carry complete Schema.org markup.

    Recommendation. When a shopper asks a relevant question, does the agent mention you at all, or does it default to a competitor? This is where most brands first realize they’re invisible, not because their product is bad, but because the agent never surfaces it.

    Position and sentiment. Being mentioned third on a list of five isn’t the same as being the top pick, and a neutral mention isn’t the same as an enthusiastic one. Both affect whether a shopper actually clicks through.

    Products with complete Schema.org markup are 6.4 times more likely to be selected by AI agents for recommendations, according to LLMRecommend.com’s Q1 2026 data cited by Lexsis. That single technical fix moves you across all three layers at once.

    How to Actually Set Up Tracking

    Here’s the sequence that works, whether you’re doing this manually at first or moving straight to an automated system.

    Step 1: Build your prompt set from real shopper language. Skip generic keywords. Pull the actual phrasing your customers use, questions like “best running shoe for a wide toe box under $120,” not just your product category name.

    Step 2: Track those prompts across ChatGPT, Gemini, and Perplexity on a recurring basis. A one-time check tells you nothing. You need visibility over weeks, because agentic commerce answers shift as agents recrawl feeds and update reasoning.

    Step 3: Run the same prompts against your top two or three competitors. Visibility only means something in context. If a competitor shows up in nine out of ten answers where you show up in two, that’s the gap you need to close first.

    Step 4: Connect visibility to conversion likelihood, not just mention count. Getting named isn’t the goal. Getting named in a way that leads to a click or a completed purchase is.

    This is where a dedicated system starts to matter more than spreadsheets. Topify tracks brand mentions, position, and sentiment across ChatGPT, Gemini, Perplexity, and other major AI platforms automatically, and its CVR metric estimates how likely a given AI answer is to actually drive a customer to engage with your brand rather than just count how often you’re named. Dynamic Competitor Benchmarking runs the same comparison from Step 3 continuously, so a shift in a competitor’s position shows up as it happens instead of during a quarterly review.

    That combination matters specifically in agentic commerce, because a mention with no purchase intent behind it isn’t worth much when the whole point of the channel is that the agent can complete the sale on the spot.

    The Blind Spot Most Brands Miss: Amazon Doesn’t Play the Same Game

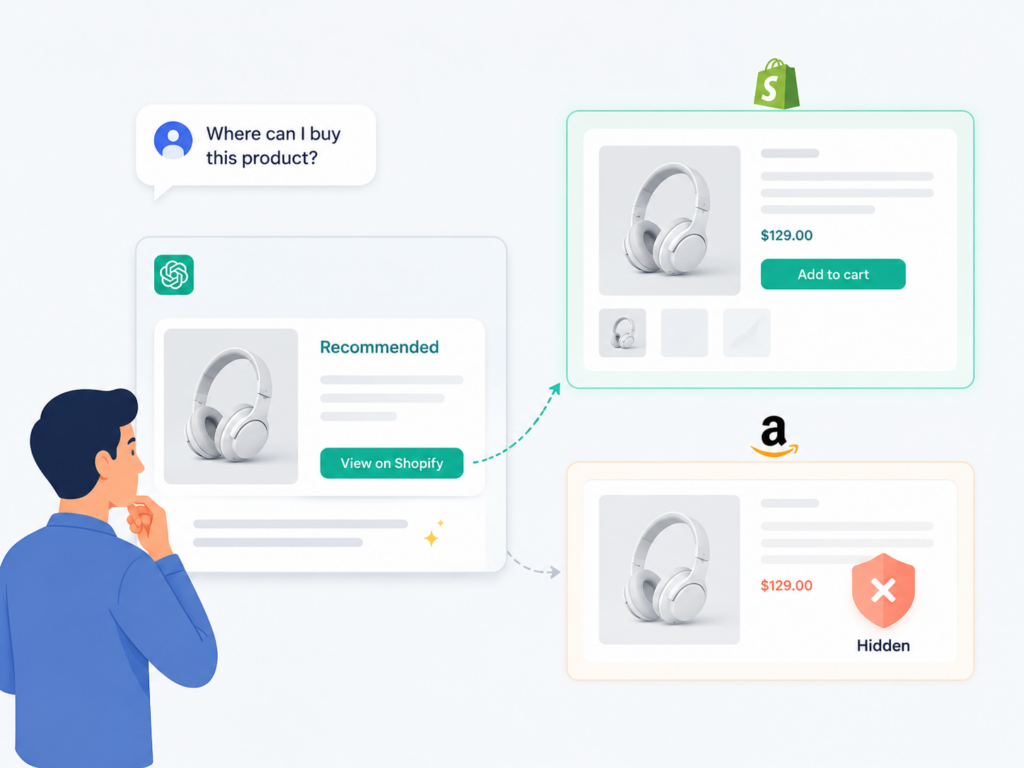
    If part of your catalog lives on Amazon, your tracking strategy needs a separate lane for it. Amazon has blocked the ChatGPT-User and OAI-SearchBot crawlers in its robots.txt file, which means Amazon listings can’t appear in ChatGPT’s shopping results in real time, per Elogic’s analysis.

    That’s a defensive move to protect Amazon’s own advertising business, but it creates an opening. A brand selling the same product on both Amazon and an independent Shopify store will see that Shopify listing surface in ChatGPT while the identical Amazon listing stays invisible.

    Amazon’s own agent, Rufus, works entirely differently. It recommends only from Amazon’s catalog and reviews, so optimizing for the open web agents does nothing for your Rufus visibility, and vice versa, according to Eevy’s 2026 comparison of AI shopping agents. If Amazon is a meaningful share of your revenue, track it as its own category, not a subset of your ChatGPT or Gemini numbers.

    Common Mistakes That Skew Your Visibility Data

    A few patterns show up again and again in brands new to this kind of tracking.

    Treating one good result as proof of visibility is the most common. One good answer from ChatGPT last week doesn’t mean you’re visible today.

    Others focus entirely on mention frequency and ignore sentiment and position, which means a brand can look “visible” on paper while consistently landing in a lukewarm, low-ranked mention that rarely converts. Review depth and third-party corroboration, things like editorial roundups and Reddit threads, are heavily weighted inputs across ChatGPT, Gemini, and Perplexity because they’re the closest thing to ground truth an agent can check your claims against, per Eevy’s research. A brand with thin review coverage will underperform in agent recommendations even with a technically clean product feed.

    The table below breaks down what each major platform actually weighs, so you know where to focus first.

    PlatformPrimary SignalBest Fit For
    ChatGPTProduct feed via ACP, review depthConsidered purchases, Shopify and Etsy sellers
    GeminiGoogle Merchant Center feed, Schema.org markupConsumables, replenishment items
    PerplexityThird-party trust, independent corroborationHigh-intent, research-heavy shoppers
    Amazon RufusAmazon catalog and review data onlyAmazon-first sellers

    Conclusion

    Agentic commerce didn’t arrive as a future trend. It’s already routing purchases through ChatGPT, Gemini, and Perplexity today, and the brands winning that channel are the ones treating visibility as something to measure, not assume. Start with your prompt set, track presence, recommendation, and position across platforms consistently, and connect what you find to actual conversion likelihood instead of raw mention counts. That’s the difference between knowing you’re in the conversation and just hoping you are.

    FAQ

    What is agentic commerce? 

    Agentic commerce is the shift where AI agents like ChatGPT, Gemini, and Perplexity handle the entire purchase process, from discovering a product to completing payment, without the shopper visiting a brand’s website directly.

    How is tracking AI shopping visibility different from tracking traditional SEO rankings? 

    Traditional SEO tracking measures a fixed position on a results page. AI shopping visibility is dynamic. The same prompt can return different brands, different rankings, and different sentiment depending on when it’s asked, which makes recurring, cross-platform tracking necessary instead of a one-time check.

    Which AI platform should ecommerce brands prioritize first? 

    It depends on your catalog. ChatGPT tends to favor considered purchases on Shopify and Etsy, Gemini favors consumables tied to Google Merchant Center, and Perplexity attracts shoppers who’ve already done deep research. Most brands need coverage across all three rather than picking one.

    Can I track AI shopping visibility manually? 

    You can start manually by running a consistent set of shopper prompts across platforms on a schedule, but manual checks struggle to catch trend shifts, competitor movement, and sentiment changes at scale, which is why most teams eventually move to automated tracking.

    Read More

  • Agentic Commerce and the Attribution Black Hole

    Agentic Commerce and the Attribution Black Hole

    Your Direct traffic jumped 30% last quarter and nobody on your team ran a new campaign. Sales are up, the CFO wants an explanation, and your GA4 dashboard has nothing useful to say. That gap isn’t a tracking bug you can patch with a UTM parameter. It’s what happens when agentic commerce starts routing purchases through a conversation your analytics stack was never built to see.

    When the Agent Buys, Your Dashboard Goes Blank

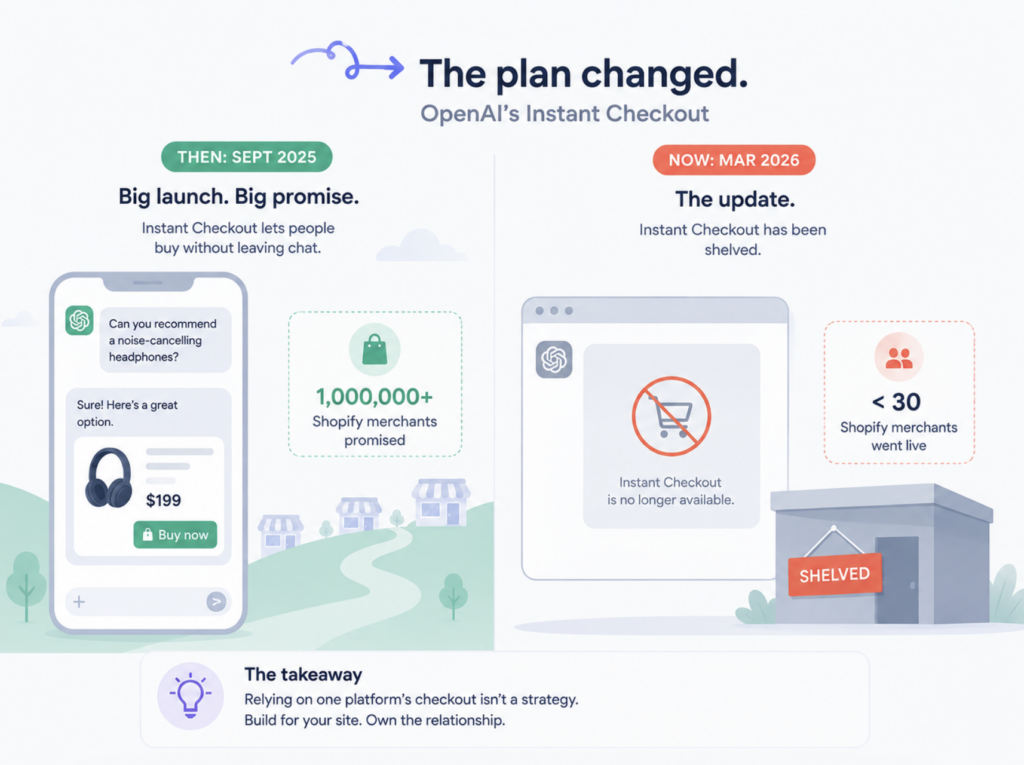
    Agentic commerce means an AI agent handles discovery, comparison, and increasingly the checkout itself, inside ChatGPT, Perplexity, or a Shopify Agentic Storefront, without the shopper ever landing on a page your pixels can fire on. OpenAI’s Instant Checkout and the newer Agentic Commerce Protocol let a customer buy without leaving the chat window, and Shopify reports AI-attributed orders on its platform grew 11x between January 2025 and January 2026.

    That’s not a niche edge case anymore. Salesforce projected agent-driven purchases would account for 22% of global orders during Cyber Week 2025 alone. Every one of those transactions starts with a recommendation your team never saw happen.

    The 70% That Vanishes Into Direct Traffic

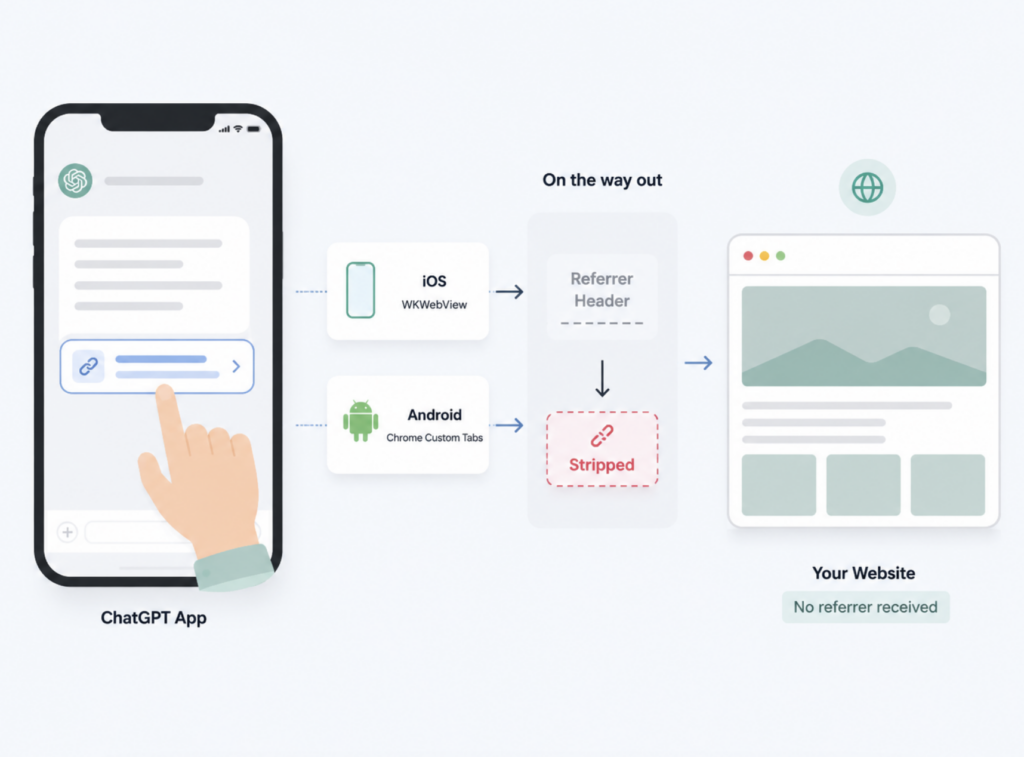
    Here’s the mechanical reason your reports look wrong. When someone taps a link inside the ChatGPT app, the referrer header often gets stripped before it ever reaches your site. iOS uses WKWebView, Android uses Chrome Custom Tabs, and both drop that header on the way out.

    The result is roughly 70.6% of AI-driven traffic arriving with no referrer at all, which means GA4 dumps it straight into Direct. One marketing researcher found 86% of her site’s new users were classified as Direct during a stretch when measurable referral traffic actually dropped 90%, even as new users grew 126% year over year.

    This isn’t a ChatGPT problem specifically. TikTok, Slack, Discord, and WhatsApp have stripped referrers for years. AI assistants just made the blind spot big enough that finance teams started asking questions.

    Why the Invisible Traffic Might Be Your Best Traffic

    Here’s the part that should actually worry you. The traffic your reports can’t see tends to convert better than the traffic they can.

    Dark AI traffic converts at 10.21% versus 2.46% for non-AI traffic, a 4.1x gap. Across the board, AI-referred sessions convert at roughly 4.4x the rate of traditional organic search. If your budget decisions run off GA4’s channel report, you’re likely underfunding the exact channel that’s outperforming everything else, simply because it shows up as “Direct” instead of “AI.”

    What You Can Still Track

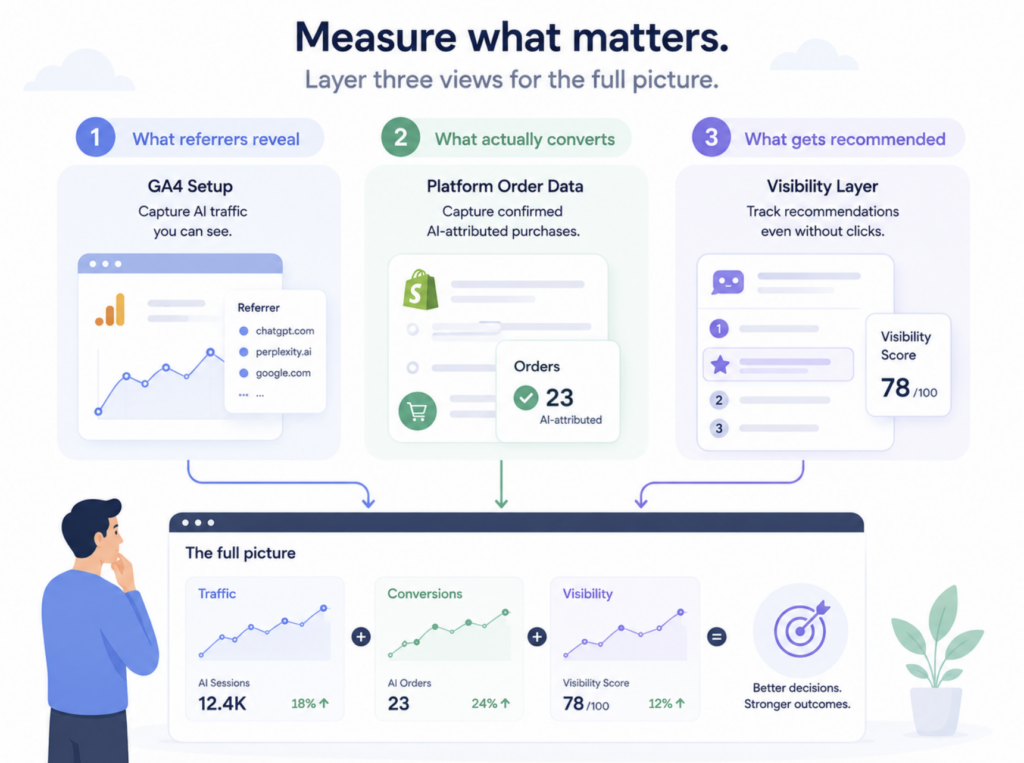
    Some of this is fixable. Google rolled out a default AI Assistant channel in GA4 in May 2026, which catches ChatGPT and Gemini automatically, but it still misses Perplexity and Claude. A custom regex channel group covering the major AI domains recovers most of what’s left, though it needs quarterly maintenance since referrer patterns keep shifting.

    Platform-native tools help too. Shopify’s Agentic Storefronts show you whether an order came from ChatGPT, Copilot, or Perplexity directly in the admin. That’s real progress. But even with all of it stitched together, 89% of brands still can’t properly attribute their AI referral traffic, because knowing an order came from an AI platform is a different problem from knowing why the AI chose you over a competitor in the first place.

    The Part That Stays Permanently Dark

    This is the actual black hole, and no amount of GA4 configuration closes it. Even a perfectly instrumented store can tell you a sale came from ChatGPT. It can’t tell you which prompt surfaced your brand, what the agent compared you against, or why it picked your product over three others with similar specs.

    That question doesn’t live in web analytics at all. It lives in the same layer that determines whether an AI agent can parse your product data in the first place: 42% of customers abandon purchases due to insufficient product information, and agents are far less forgiving of gaps than human shoppers, since they don’t guess in your favor when structured data is missing.

    This is where visibility tracking has to pick up where traffic attribution stops. Instead of chasing individual sessions, tools built for this measure the probability that an AI response leads to brand engagement at all. Topify’s Conversion Visibility Rate metric works this way, estimating how likely a given AI answer is to drive a customer toward your brand, even in cases where no clean referral trail exists to prove it after the fact. Paired with source analysis that shows exactly which domains and pages an AI platform is pulling from, it turns an unmeasurable event into a directional signal your team can actually act on.

    Building an Attribution Strategy for a Black Box

    The practical move isn’t chasing one unified number. It’s layering three views: a cleaned-up GA4 setup that catches what referrers reveal, platform-native order data from Shopify or your commerce backend that catches confirmed AI-attributed purchases, and a visibility layer that tracks whether you’re getting recommended in the first place, regardless of whether that recommendation ever produces a trackable click.

    Structured product data underpins all three. Without accurate Schema.org markup, agents can’t reliably evaluate your catalog, and no attribution fix downstream matters if the agent never considered you to begin with. Most estimates put full-confidence attribution frameworks 18 to 24 months out. Brands building the visibility and data infrastructure now will have evidence to show when that measurement matures. The ones waiting for a clean dashboard will still be guessing.

    Conclusion

    The attribution black hole in agentic commerce isn’t going away, and pretending your existing GA4 setup covers it just delays the budget conversation you’ll eventually have to have. Fix what’s fixable in traffic reporting, but don’t stop there. Pair it with a visibility layer that tracks whether AI systems are recommending you at all, because that’s the one question traffic data was never going to answer.

    FAQ

    Q: What is agentic commerce? 

    A: Agentic commerce refers to purchases where an AI agent, such as ChatGPT or a Shopify-connected assistant, handles product discovery, comparison, and sometimes checkout on a customer’s behalf, often without the customer visiting the brand’s website directly.

    Q: Why does ChatGPT traffic show up as Direct traffic in GA4? 

    A: Mobile apps typically strip the referrer header before a link opens, so GA4 has no source to attribute the visit to and defaults it to Direct. This affects a majority of AI-referred sessions, not just a small fraction.

    Q: Can brands fully track AI agent purchases? 

    A: Partially. Platform-native tools like Shopify’s Agentic Storefronts can confirm an order originated from an AI platform, but they can’t explain why the agent recommended that brand over a competitor, which remains outside standard analytics.

    Q: What’s the difference between ACP and UCP? 

    A: ACP, the Agentic Commerce Protocol, powers checkout inside ChatGPT and similar assistants. UCP, the Universal Commerce Protocol from Google and Shopify, covers the broader commerce journey including discovery, cart, and post-purchase steps. Most retailers end up needing both.

    Read More

  • Why Your Products Aren’t Showing Up When ChatGPT Shops for Customers

    Why Your Products Aren’t Showing Up When ChatGPT Shops for Customers

    ChatGPT now handles roughly 50 million shopping related queries every day. Searches for “AI shopping” alone have grown 1,767% over the last two years.

    If your products aren’t turning up in those conversations, you’re not losing a future channel. You’re losing a present one.

    The ChatGPT Shopping Moment Nobody Priced In

    Most brands still treat ChatGPT shopping as a side project. That’s a mistake.

    More than six in ten consumers have already used ChatGPT to shop, and one in four say it gives better recommendations than Google. Bain & Company found that 80% of consumers now rely on AI generated results for at least 40% of their searches.

    The dollars are catching up too. McKinsey projects agentic commerce could drive $3 to $5 trillion in global transactions by 2030. That’s not a niche. That’s a new front door for retail.

    Instant Checkout Died, but Agentic Commerce Didn’t

    Here’s a twist that changes the strategy for a lot of teams. OpenAI’s Instant Checkout, the buy-without-leaving-chat feature launched in September 2025, has been quietly shelved as of March 2026. Fewer than 30 Shopify merchants ever went live, against the over a million once promised.

    The reason wasn’t philosophical. It was conversion math.

    Walmart found that checkout inside ChatGPT converted roughly 3 times worse than a click through to walmart.com, even though ChatGPT drove about twice the new customer rate that Walmart sees from search. In practice, ChatGPT is turning out to be a discovery engine, not a checkout counter.

    The underlying Agentic Commerce Protocol, open sourced by OpenAI and Stripe, is still very much alive. It just plays a different role now: get discovered in the chat, close the sale on your own site. That’s the model worth building for.

    That’s the gap most brands still haven’t priced in.

    The Real Gatekeeper Is Google Shopping, Not ChatGPT

    Here’s the part that surprises most marketing teams. ChatGPT doesn’t build its own product index. It reads someone else’s.

    Peec AI analyzed over 43,000 ChatGPT carousel products and found that 83% were strong matches to Google Shopping’s organic top 40 results for the same query. A separate study found the number closer to 100%, with Bing Shopping explaining only about 11% of what showed up. ChatGPT also pulls roughly 75% of its raw product data straight from Google Shopping.

    Rank matters more than most teams assume. Peec AI’s data shows 60% of carousel matches come from Google Shopping’s top 10 results, climbing to 84% by the top 20. Products sitting at rank 21 to 40 account for only about 16% of matches.

    Google Shopping RankShare of ChatGPT Carousel Matches
    Top 10~60%
    Top 20~84%
    Rank 21 to 40~16%
    Outside top 40Effectively 0%

    If you’re not in Google Merchant Center with a clean feed, you’re not in ChatGPT’s candidate pool at all. No amount of great copywriting on your product page fixes that. Feed quality is the gate. Everything else decides what happens once you’re through it.

    Why Your Titles Fail a Model That Talks Like a Shopper

    Getting into the pool is step one. Getting picked is a different problem, and it’s where most feeds quietly fail.

    Shopping fan out queries inside ChatGPT average about seven words and read like something a person would actually say, not a keyword string. “Red Dress Cotton” doesn’t match how anyone talks to an AI. “Women’s A-Line Cotton Midi Dress in Cherry Red” does.

    Structured attributes carry the same weight. Google Shopping needs brand, product type, material, color, size, gender, condition, and a GTIN or manufacturer ID to place your product correctly. Skip a field and you either drop out of relevant queries or get miscategorized entirely.

    Freshness compounds this. ChatGPT’s own merchant feed spec supports updates every 15 minutes, compared to Google Shopping’s standard 24 hour cycle. Stale pricing or a phantom “in stock” tag is often the quiet reason a product that used to appear stops showing up.

    The Trust Signals That Decide Whether You Get Recommended

    Once ChatGPT has a shortlist, it starts reasoning about which product to actually suggest. That’s where trust signals take over from feed mechanics.

    Reviews matter more than most teams realize, because ChatGPT performs sentiment synthesis on the actual text of reviews to answer detailed shopper questions. If your review content isn’t wired into your feed, ChatGPT pulls social proof from Reddit or third party blogs instead, and you lose control of your own narrative.

    Brand mentions carry surprising weight too. Ahrefs found that branded mentions across the web correlate with AI visibility at 0.664, well above backlinks at 0.218 or domain rating at 0.326. A brand that only exists on its own storefront and its own feed is structurally harder for an AI agent to trust.

    Content depth adds another layer. Academic GEO research from Princeton and Georgia Tech found that content backed by statistics, citations, and structured evidence can lift AI visibility by up to 40%.

    None of these signals live in your product feed. They live in how your brand shows up everywhere else AI models look.

    How to Check If You’re Even in the Running

    Before fixing anything, you need to know where you actually stand.

    Run a handful of shopping style prompts through ChatGPT the way a real customer would phrase them. Not “best waterproof boots” but “what’s a good waterproof hiking boot for wide feet under $200.” Check whether your brand appears, where it lands in the carousel, and which competitors keep showing up instead.

    This works fine as a spot check. It falls apart at scale. Prompts drift, models get updated, and a brand that shows up today can quietly disappear next week without anyone noticing until sales already dipped.

    Turning Product Visibility Into Something You Can Track

    Manual prompt testing tells you what’s happening right now, once. What most teams actually need is a way to see the pattern over time, and to know which lever to pull when visibility drops.

    Topify‘s Visibility Tracking follows how often your products and brand actually surface across ChatGPT, Perplexity, and Google AI Overviews, so a drop shows up as a chart instead of a support ticket. Paired with Source Analysis, it shows exactly which domains and review sources AI models are citing when they explain a recommendation, which is often the fastest way to spot a content gap before a competitor fills it.

    Competitor Monitoring rounds it out by showing who’s winning the same carousel you’re trying to get into, and where their feed or content is simply stronger than yours right now. That turns “why aren’t we showing up” from a guess into a diagnosis.

    What to Fix This Week

    • Confirm your Google Merchant Center feed is complete: brand, GTIN, material, color, size, and condition, with no missing fields
    • Rewrite your top 20 product titles the way a customer would actually ask for them, not the way your internal catalog names them
    • Sync your product page schema markup with your feed data so the two never contradict each other
    • Wire your genuine review content into your feed instead of leaving AI models to source sentiment from third party sites
    • Start tracking your AI shopping visibility on a recurring basis instead of spot checking it once and moving on

    Conclusion

    Your products aren’t invisible to ChatGPT because AI shopping is some kind of black box. They’re invisible because Google Shopping’s organic index decides who even gets considered, and most feeds still aren’t clean enough to clear that bar. Fix the feed first. Build the trust signals second. Track what happens next, because a visibility gap you can’t see is one you can’t fix.

    FAQ

    Does ChatGPT rank paid ads in its shopping results? 

    No. Both Peec AI and OpenAI confirm that ChatGPT’s product carousel pulls from organic Google Shopping results only. There’s currently no way to pay for placement.

    Do I need to be on Shopify to appear in ChatGPT shopping? 

    No. Appearing depends on having a well optimized Google Merchant Center feed, not on which ecommerce platform you run. Etsy and independent merchants show up the same way Shopify stores do.

    Is Instant Checkout still worth building for? 

    Not as a priority. OpenAI shelved Instant Checkout for most merchants in March 2026 after adoption stalled. The Agentic Commerce Protocol behind it is still active, but the practical model right now is getting discovered inside ChatGPT and closing the sale on your own site.

    How is agentic commerce different from regular ecommerce SEO? 

    Regular SEO optimizes pages for crawlers and keywords. Agentic commerce optimizes structured data, primarily your Google Shopping feed, for an AI agent that reasons over attributes, reviews, and trust signals before recommending a product on a customer’s behalf.

    Read More