Author: Elsa Ji

  • AI Reputation Monitoring Dashboard: What to Track

    AI Reputation Monitoring Dashboard: What to Track

    You’ve spent two years positioning your product as enterprise-grade. Then you discover Perplexity describes it as “a budget alternative.” Gemini calls it “great for small teams.” Neither matches your messaging. The problem isn’t that AI got it wrong. It’s that nobody was tracking what AI was saying in the first place.

    That’s the gap a proper AI reputation monitoring dashboard is built to close.

    Your Google Alerts Don’t Work in AI Search. Here’s What Does.

    Traditional brand monitoring tools, including Google Alerts, Mention, and Brandwatch, were built on a simple premise: crawl indexed pages, flag mentions, send alerts. That logic worked when brand perception lived in articles, forums, and review sites.

    It doesn’t work anymore.

    When a user asks ChatGPT “Which CRM is best for my sales team?”, the model generates a unique, synthesized response. That response isn’t indexed anywhere. No crawler ever sees it. According to the research on AI monitoring inadequacy, standard monitoring tools miss up to 70% of brand mentions that occur inside AI-generated answers, because they simply can’t access the citation layer of AI.

    This is what researchers call the “black box” problem of RAG (Retrieval-Augmented Generation). A brand could be repeatedly recommended, or systematically misrepresented, by a major AI platform. The brand manager would never receive a single notification from their existing tool stack.

    An AI reputation monitoring dashboard solves this by querying AI engines directly, at scale, and capturing what the models actually say about your brand.

    The 7 Metrics a Real AI Reputation Monitoring Dashboard Should Show

    Not all dashboards are built the same. The difference between a useful AI reputation monitoring analytics system and a vanity metrics board comes down to which signals it actually captures.

    Here’s the framework that matters:

    MetricWhat It MeasuresWhy It Matters
    VisibilityHow often your brand appears in AI answersTop-of-funnel reach across AI channels
    SentimentThe emotional tone AI assigns your brandAI bias directly affects conversion intent
    PositionWhere your brand ranks in a list or recommendationPrime placement correlates with user trust
    VolumeNumber of unique queries surfacing your brandMeasures thematic authority across topics
    MentionsHow your brand is defined in AI summariesTracks whether AI’s “knowledge” aligns with positioning
    IntentAlignment with high-value transactional queriesFilters signal from noise, focuses on revenue-relevant prompts
    CVREstimated conversion rate from AI-driven recommendationsConnects reputation data directly to revenue

    Most platforms cover one or two of these. A complete AI reputation monitoring system tracks all seven together, so you’re not running blind on any single dimension.

    Sentiment Score: Not Just Positive or Negative

    Sentiment analysis in AI monitoring is more nuanced than social media listening. It’s not just about whether the AI “likes” your brand. It’s about what language the AI uses when it describes you, and whether that language aligns with your positioning.

    Topify scores sentiment on a 0-100 scale, tracking shifts across ChatGPT, Gemini, Perplexity, and other platforms. A drop from 74 to 61 over two weeks often signals a source-level change worth investigating.

    Position Tracking: Where You Rank in AI Answers

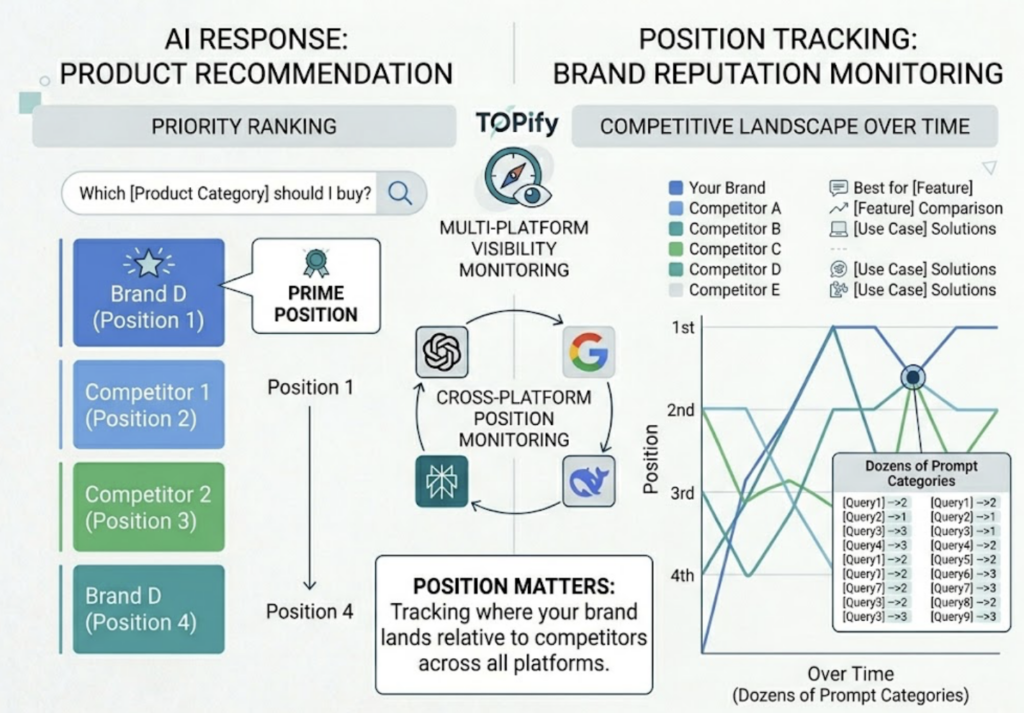
    There are no page one rankings in AI search. But there is a “prime position” problem. When an AI engine lists four products in response to a recommendation query, being listed first versus third matters. Position tracking in an AI reputation monitoring tool monitors exactly that: where your brand lands relative to competitors, across dozens of prompt categories, over time.
    What Makes an AI Reputation Monitoring Tool Actually Useful

    The data is only half the job. The other half is knowing what to do with it.

    Here’s where most AI reputation monitoring software falls short. They deliver weekly reports packed with visibility scores and sentiment trends, but stop before telling you what actually changed, or why. You’re left doing the diagnostic work yourself.

    Four criteria separate actionable platforms from data-heavy reports:

    Multi-platform coverage. Your audience doesn’t use only one AI engine. An AI reputation monitoring solution that only covers ChatGPT misses Gemini, Perplexity, DeepSeek, Doubao, and a growing list of specialized models. Each platform has different citation patterns and source preferences.

    Prompt granularity. The ability to test specific user personas and query phrasing matters. Generic keyword tracking won’t show you that your brand is visible when users ask “best enterprise CRM” but completely absent when they ask “CRM with the best onboarding.” That gap is a content strategy issue, and you can’t fix what you can’t see.

    Competitive benchmarking. Knowing your own visibility score is less useful than knowing how it compares to competitors on the same prompt cluster. Real-time competitor monitoring shows you not just where you’re losing ground, but which specific topics are driving the gap.

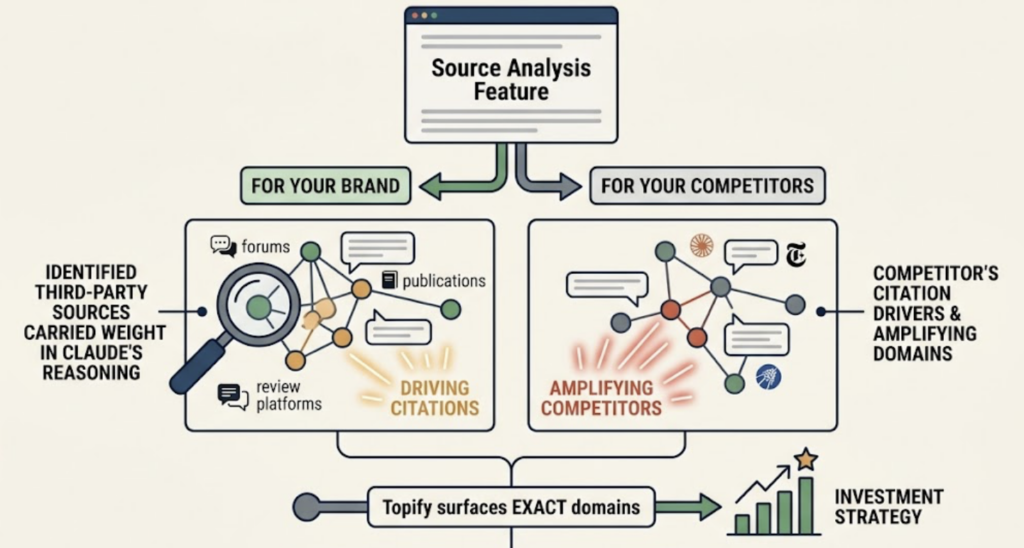
    Source tracking. This is the one most platforms miss. AI engines don’t generate opinions from nothing. They pull from a set of cited domains and content assets. An AI reputation monitoring platform with source tracking shows you exactly which URLs and domains are shaping the AI’s view of your brand, so you can prioritize those in your content strategy.

    Voice Search and AI Answer Engines: A New Reputation Blind Spot

    Voice is where the “winner-take-all” problem gets most pronounced.

    When a user types a query into Google, they get ten links to evaluate. When they ask Siri a brand question powered by ChatGPT, they get one synthesized response. According to research on voice-integrated AI models, user reliance on AI-synthesized answers for product discovery has grown 3x compared to standard search. That ratio is not evenly distributed. Brands with strong AI visibility get the single recommended slot. Everyone else gets brand erasure.

    Voice search AI answer engine visibility tools are still an emerging category, but the monitoring logic is the same: simulate the queries voice users are likely to ask, track what AI engines respond, and identify where your brand is included or excluded from those truncated, high-stakes answers.

    This isn’t a future concern. It’s already happening in every product category where voice-first users are common. Healthcare, travel, SaaS productivity tools, and consumer electronics are all early-impact verticals.

    How Topify’s AI Reputation Monitoring Platform Works in Practice

    Here’s what a weekly monitoring workflow looks like when it’s set up correctly.

    A brand manager starts by defining a prompt library: 80 to 100 queries that represent how the target audience actually searches for products in their category. In Topify’s Basic plan at $99/month, you can run up to 100 prompts across ChatGPT, Perplexity, and AI Overviews simultaneously, generating 9,000 AI answer analyses per month.

    Each week, the AI reputation monitoring platform surfaces three things automatically: which prompts showed sentiment shifts, which competitor gained or lost position on specific clusters, and which source domains are newly influencing AI citations for your category.

    That third signal is often the most actionable. If a competitor’s documentation page or PR placement suddenly starts appearing in AI citations, that’s a content gap you can close in two to four weeks. On the Pro plan at $199/month, you get 250 prompts and full source analysis, which is where competitive intelligence becomes operational rather than just observational.
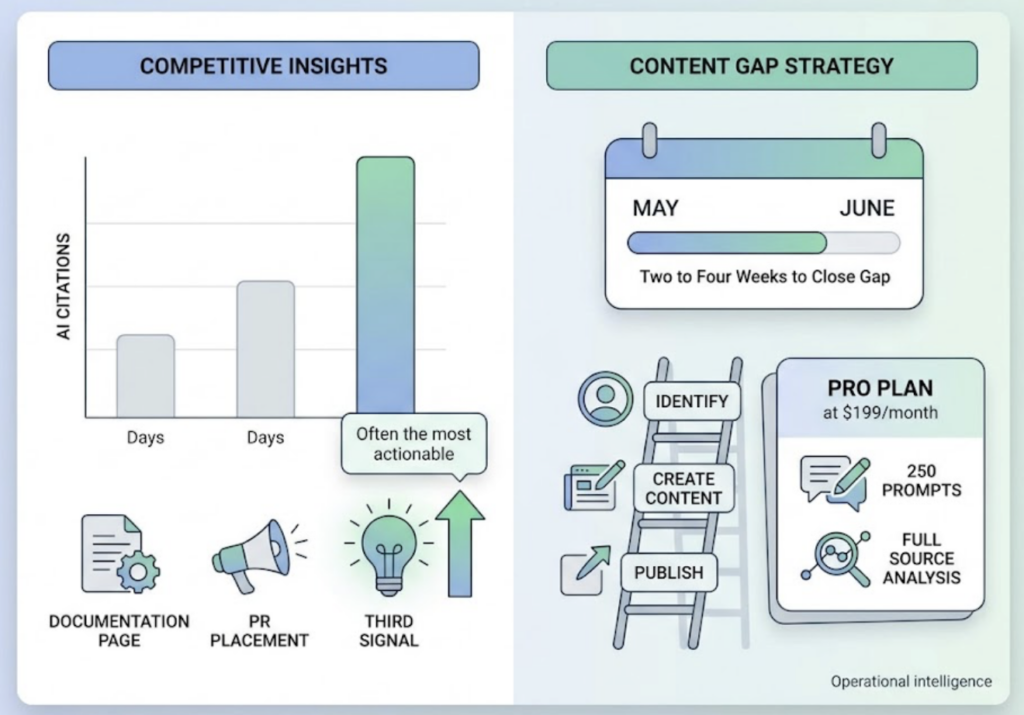
    The workflow structure follows a clear loop:

    1. Define high-intent prompts that map to purchase decisions in your category
    2. Monitor daily sentiment and position shifts across AI platforms
    3. Trace visibility changes back to specific source domains
    4. Update content strategy to reinforce definitional anchoring: ensuring AI associates your brand with the right attributes, in the right context

    Most teams run this cycle monthly. The brands gaining ground in AI search are running it weekly.

    Conclusion

    Brand reputation used to be managed through earned media, review platforms, and search rankings. Those channels still matter. But AI engines now synthesize that information into a single confident recommendation, and most brands have no visibility into what that recommendation says or why.

    An AI reputation monitoring dashboard doesn’t replace your existing PR and SEO stack. It shows you what your existing stack can’t: how AI engines define your brand, where competitors are outranking you in AI-generated answers, and which content investments will actually move the needle in model-driven discovery.

    Get started with Topify to see where your brand stands in AI search before your next quarterly review.


    FAQ

    Q: What is an AI reputation monitoring dashboard?

    A: An AI reputation monitoring dashboard is a centralized interface that tracks how your brand appears in AI-generated search answers across platforms like ChatGPT, Perplexity, and Gemini. Unlike traditional brand monitoring tools that crawl indexed pages, it queries AI engines directly to capture sentiment, position, visibility, and citation sources in real time.

    Q: How is AI reputation monitoring different from traditional brand monitoring?

    A: Traditional tools flag mentions in indexed content. AI reputation monitoring captures synthesized responses that are never indexed. When an AI engine recommends your competitor in response to a transactional query, no standard tool will alert you. AI-specific monitoring fills that gap by simulating user queries and analyzing model outputs directly.

    Q: What AI platforms should I monitor for brand reputation?

    A: At minimum, ChatGPT, Perplexity, and Google AI Overviews cover the majority of AI search volume for most markets. Depending on your target audience, DeepSeek, Doubao, and Gemini are also worth including. Enterprise brands with global operations typically monitor eight or more platforms to capture regional variation in AI citation behavior.

    Q: Can I track voice search AI answer engine visibility with these tools?

    A: Yes, though the coverage varies by platform. Voice search AI answer engine visibility tools work by simulating the short, conversational queries that voice interfaces typically process. Since voice responses are often pulled from the same underlying LLMs powering text search, tracking AI answer quality on text queries gives you a strong proxy for voice performance as well.
    Read More

  • AI Visibility Score Service: What It Tracks and Who Needs It

    AI Visibility Score Service: What It Tracks and Who Needs It

    Your brand has a Domain Authority. You probably track keyword rankings weekly. But if someone asks ChatGPT to recommend a tool in your category right now, do you know what it says?

    Most brands don’t. That’s not a content problem. It’s a measurement problem.

    An AI visibility score service exists to close that gap. It turns what was previously a black box into a structured set of metrics you can track, benchmark, and act on.

    Your Brand Has a Google Rank. It Probably Has No AI Score.

    Traditional search and generative search are built on completely different mechanics. In Google, visibility is deterministic: your page ranks or it doesn’t, and the position is relatively stable.

    AI search is probabilistic. A large language model synthesizes a response from its training data and retrieval context, and your brand is either included or omitted. As research on brand visibility in AI-mediated markets describes it, this creates a “binary inclusion-exclusion dynamic” where there’s no page two. Either you’re cited or you’re not.

    That changes what “visibility” means. It’s no longer about link equity or crawl frequency. It’s about how effectively your brand’s identity clusters with relevant search attributes inside an LLM’s latent space.

    Standard SEO metrics don’t capture any of this. A DA score tells you nothing about whether Perplexity mentions you when a user asks for a product recommendation in your category.

    What an AI Visibility Score Actually Measures

    Because AI outputs vary by prompt, session, and model version, a single number isn’t enough. The more useful frameworks evaluate brand presence across multiple dimensions simultaneously.

    Here’s what a well-structured AI visibility scoring system typically covers:

    DimensionWhat It MeasuresWhy It Matters
    Visibility (Impression)How often your brand appears in synthesized responsesTop-of-funnel brand awareness in AI channels
    SentimentEmotive tone associated with your brand (positive/neutral/negative)Brand reputation and AI-generated framing
    PositionWhere you appear in the citation list or response flowHigher position correlates with higher trust
    Volume (Mention Rate)Number of distinct queries triggering a brand mentionBreadth of topical authority
    Intent AlignmentSemantic relevance to the user’s specific queryEnsures you’re cited for high-value queries
    CVR (Agent Execution)Rate at which an AI agent acts on or selects your brandDirect correlation with transactional outcomes
    StabilityConsistency across repeated promptsIdentifies whether visibility is reliable or random

    One caveat worth noting: research by Aggarwal et al. (2024) found that relying on mention rate alone can be misleading because of the stochastic nature of token generation. A brand can show up in 70% of responses on Monday and 40% on Friday, with no change in content strategy. That’s not a campaign problem. That’s normal AI variance, and it’s exactly why single-metric snapshots fail.

    Service vs. Tool vs. Dashboard: What You’re Actually Buying

    The terminology in this space is loose, and vendors use it interchangeably. Here’s a working distinction:

    TypeWhat It DoesWhat It Lacks
    ToolSingle-point function (e.g., mention tracking)No cross-platform synthesis
    Software / DashboardVisualizes raw dataMay lack strategic interpretation
    PlatformMulti-dimensional data, integrated viewVaries in actionability
    ServiceData plus strategic execution adviceHigher cost, higher output

    The critical variable is not which label a vendor uses. It’s whether the AI visibility score tool supports continuous monitoring or only generates point-in-time reports.

    A one-off score is useful once. A tracked score over time is what drives decisions.

    Why Continuous Monitoring Is the Part Most Teams Underestimate

    AI search outputs don’t sit still. They shift with model fine-tuning, training data updates, and prompt variations that no brand controls.

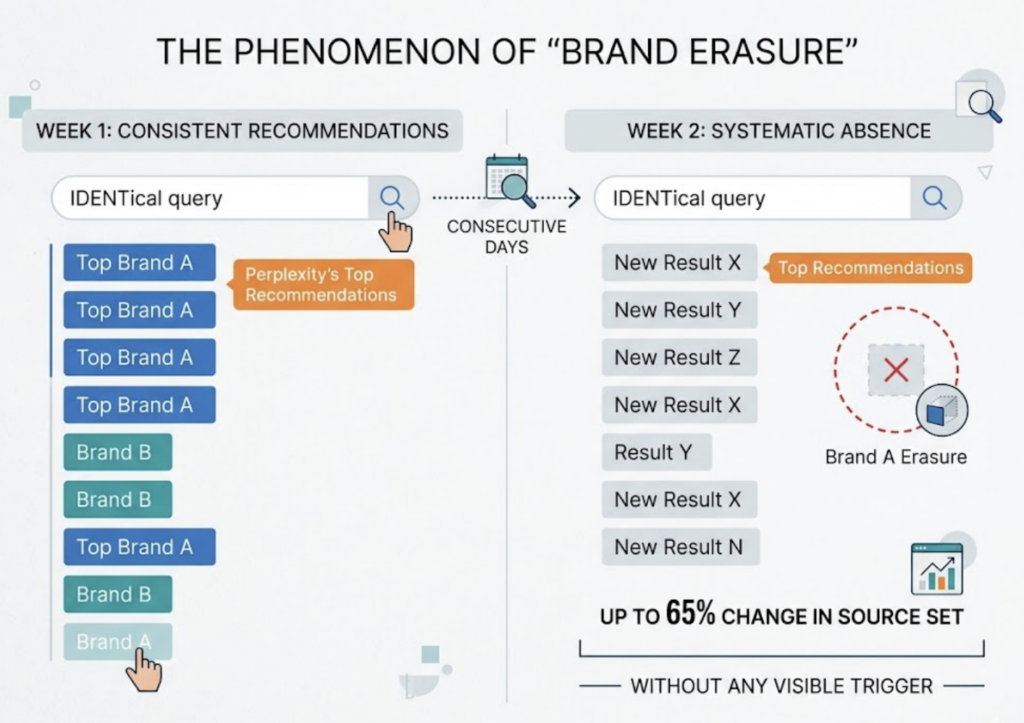
    Academic research using the Jaccard similarity coefficient has found that source sets for identical queries can change by up to 65% in consecutive days. A brand that appeared consistently in Perplexity’s top recommendations this week may be systematically absent next week. This phenomenon, which researchers call “brand erasure,” can happen without any visible trigger on your end.

    That’s the core argument for tools for continuous monitoring of AI search visibility. It’s not about obsessive data collection. It’s about detecting drift early enough to respond.

    In practice, continuous monitoring catches two things that snapshots miss: the gradual erosion of visibility as AI model weights shift, and sudden drops triggered by changes in which sources an AI platform chooses to cite. Both require time-series data to diagnose.

    A static report tells you where you stood. A monitoring system tells you where you’re heading.

    Five Things to Look for in an AI Visibility Score Service

    The market for AI visibility score software and platforms has expanded quickly, and the capability differences between vendors are significant. Here’s a practical evaluation framework:

    1. Platform breadth. A service that only tracks ChatGPT misses how your brand performs on Perplexity, Gemini, DeepSeek, and regional AI platforms. Coverage should span the major models where your audience actually searches.

    2. Update frequency. Given that source sets can shift by up to 65% day-over-day, weekly or monthly snapshots create blind spots. Look for platforms that run tracking at a frequency that matches how fast AI outputs change.

    3. Dimensional depth. A single visibility percentage isn’t enough. You need sentiment, position, intent alignment, and source data in the same view. A score without context is noise.

    4. Competitive benchmarking. Your AI visibility score only matters relative to your category. An AI visibility score dashboard that shows your metrics without showing where competitors sit gives you an incomplete picture.

    5. Actionable output. The best AI visibility score solutions don’t stop at data. They surface which content gaps are costing you citations and which source domains you need to be featured on to improve your position.

    How Topify Structures AI Visibility Scoring

    Topify is built around the premise that AI visibility has to be measurable before it can be managed. The platform tracks brand performance across seven core metrics: visibility, sentiment, position, volume, mentions, intent, and CVR.

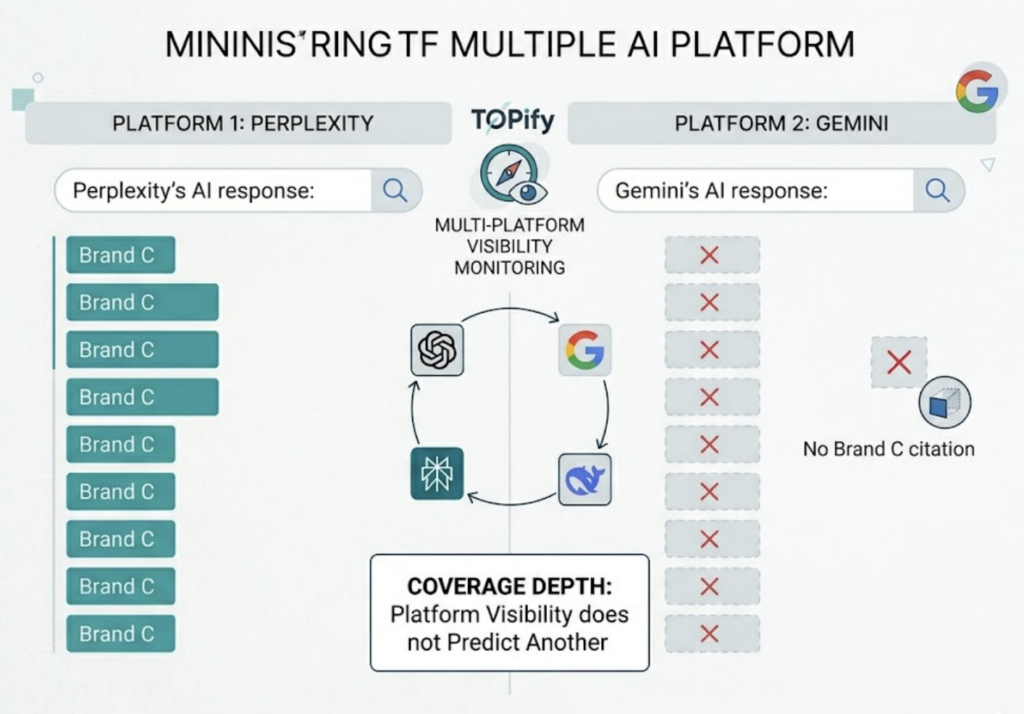
    What makes this more than a dashboard is coverage depth. Topify monitors brand presence across ChatGPT, Gemini, Perplexity, DeepSeek, Doubao, Qwen, and other major AI platforms. That matters because visibility on one platform doesn’t predict visibility on another. A brand can be consistently cited by Perplexity while being largely absent from Gemini’s responses for the same query category.

    The AI visibility score platform also surfaces competitive data automatically. You can see which competitors appear in the same AI responses as your brand, track their position relative to yours, and identify when new rivals are emerging in AI recommendations before they show up in traditional marketing reports.

    For source analysis specifically, Topify traces which domains AI platforms cite when recommending brands in your category. This makes it possible to identify content placement priorities at the domain level, rather than guessing which publications influence AI training and retrieval.

    Pricing starts at $99/month on the Basic plan, which covers 100 prompts across ChatGPT, Perplexity, and AI Overviews. The Pro plan at $199/month expands to 250 prompts and 10 seats. Get started with Topify with a 30-day trial.

    Conclusion

    An AI visibility score is the equivalent of a Domain Authority for generative search, except it moves faster, changes more often, and reflects a completely different set of signals. Brands that rely on traditional SEO metrics to gauge their AI search presence are measuring the wrong channel with the wrong ruler.

    The right AI visibility score service does three things: tracks multiple dimensions rather than a single score, monitors continuously rather than generating static reports, and connects data to action by identifying which changes will move the needle. If a service you’re evaluating can’t do all three, it’s a dashboard, not a strategy system.


    FAQ

    Q: What’s the difference between an AI visibility score and a GEO score?

    A: They’re often used interchangeably, but there’s a useful distinction. A GEO score typically refers to your brand’s overall optimization posture for generative search. An AI visibility score is more specific: it measures how often and how favorably your brand actually appears in AI-generated responses, based on live tracking data. One is about readiness; the other is about outcomes.

    Q: How often should an AI visibility score be updated?

    A: Research indicates that AI source sets can change by up to 65% day-over-day for identical queries, which means weekly or monthly snapshots create significant blind spots. For brands in competitive categories, continuous monitoring with at least daily tracking frequency is worth the investment.

    Q: Can a small brand benefit from an AI visibility score service?

    A: Yes, and often more than larger brands. Smaller brands typically have more room to move on AI visibility metrics, especially in niche categories where LLMs have fewer established references to draw on. Knowing you’re absent from AI recommendations early, before category leaders solidify their position, gives smaller brands a strategic window to act.

    Q: What AI platforms should a visibility score service cover?

    A: At minimum, ChatGPT, Perplexity, and Google AI Overviews. These represent the highest-traffic AI search touchpoints for most B2B and B2C audiences. Depending on your target markets, DeepSeek, Doubao, and Gemini coverage matters too, particularly for brands with international or enterprise audiences.


    Read More

  • AI Visibility Score Monitoring: What It Measures and Why It Matters

    AI Visibility Score Monitoring: What It Measures and Why It Matters

    Your domain authority is solid. Your keyword rankings are holding. But none of that tells you whether Perplexity is recommending your competitor instead of you. Traditional SEO tools were built for a crawl-index-rank world. AI search engines don’t work that way, and the brands that figure out how to measure AI visibility score monitoring first are quietly taking market share from those that haven’t.

    Your Google Rank Doesn’t Tell You What ChatGPT Says About You

    Over 60% of Google searches now resolve without a click. On AI-native platforms like ChatGPT or Perplexity, that number approaches 100%. Users ask a question and get a synthesized recommendation. They don’t scroll through ten blue links.

    The problem is that traditional SEO tools track your position in a ranked list. AI search engines use Retrieval-Augmented Generation (RAG) to select and recommend brands based on a completely different set of signals. Whether you get cited depends on your authoritative footprint across the web, not your backlink profile.

    That’s the gap. You can rank #1 on Google and still be invisible in every AI answer your customers are reading.

    What AI Visibility Score Monitoring Actually Measures

    AI visibility score monitoring is the practice of systematically tracking how, where, and how favorably a brand appears in AI-generated answers across multiple platforms.

    It’s not a single number. It’s a composite framework built from seven dimensions:

    1. Visibility (Mention Rate): How often does your brand appear in AI answers for your target prompts?
    2. Position: Are you mentioned at the top of the shortlist, or buried in a footnote? Top-of-answer placement converts significantly better.
    3. Sentiment Score: Does the AI describe your brand as “enterprise-grade” or “a budget alternative”? Qualitative tone matters as much as presence.
    4. AI Volume: How much demand exists for the prompts that trigger AI-led discovery in your category?
    5. Mentions: Quantitative tracking of brand appearances across specific buyer contexts.
    6. Intent Alignment: Is the AI surfacing your brand at the right buyer stage, consideration versus active procurement?
    7. CVR (Conversion Visibility Rate): What’s the correlation between your AI visibility and downstream pipeline growth?

    Topify structures these seven dimensions into a unified GEO Analytics framework, letting teams treat AI visibility as a measurable growth variable rather than a guessing game.

    How AI Visibility Score Monitoring Works

    The mechanics are more systematic than most brands expect.

    A monitoring platform starts with prompt discovery: identifying the specific questions your target buyers are actually asking AI engines. Not broad keywords, but high-intent buyer questions like “What’s the best CRM for a mid-size healthcare company?” These become your tracking prompts.

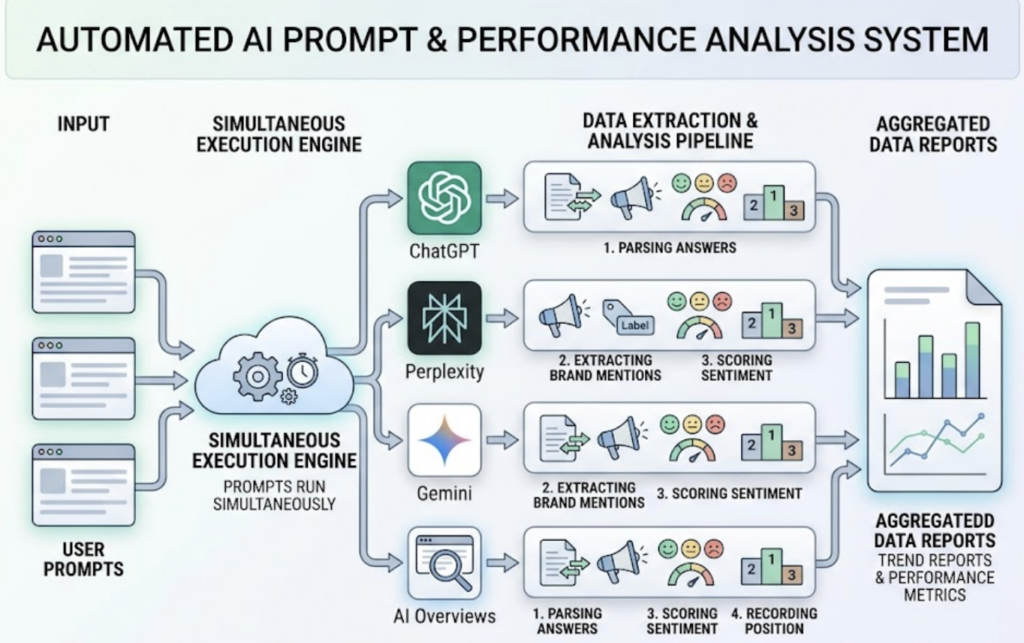
    From there, the system runs those prompts simultaneously across ChatGPT, Perplexity, Gemini, AI Overviews, and other relevant platforms. It parses the AI-generated answers, extracts brand mentions, scores sentiment, records position, and aggregates the data into trend reports.

    The cadence matters. AI models update their citation patterns constantly as new training iterations roll out. A one-time audit tells you where you stood last Tuesday. Continuous monitoring tells you when something changed and what likely caused it.

    Topify’s Basic plan, at $99/month, covers up to 100 high-intent prompts and 9,000+ AI answer analyses per month, which provides enough statistical depth to identify real trends rather than noise.

    5 Metrics That a Proper AI Visibility Score Should Include

    Not all monitoring platforms track the same things. When evaluating AI SEO rank tracking platforms, the coverage of these five metrics is the right place to start:

    Mention Rate tells you baseline presence. You can’t optimize what you’re not tracking. Start here.

    Sentiment Score tells you whether presence is actually good. A brand mentioned as “often criticized for poor support” has worse visibility than a brand that isn’t mentioned at all.

    Position Rank separates shortlist placements from footnotes. AI answers frequently recommend 3-5 products in a list. Being #1 versus #5 on that list has meaningful conversion implications.

    Source Coverage shows which domains and URLs the AI is currently citing in your category. This is actionable: if you’re not present on those sources, that’s your content gap.

    CVR closes the loop between visibility data and business outcomes. Without it, you can’t build a business case for GEO investment.

    The mistake most teams make is treating mention rate as the whole score. It’s one variable. A brand with 70% mention rate and consistently negative sentiment is in worse shape than a brand with 40% mention rate and strong positive framing.

    Common Mistakes That Skew Your AI Visibility Score

    Flawed monitoring leads to flawed optimization. Here are the patterns that show up most often:

    Platform siloing is the most common error. Teams optimize for ChatGPT and ignore Perplexity, DeepSeek, or Gemini. In practice, different AI platforms have different discovery patterns and different citation preferences. A brand that dominates on one may be invisible on another.

    Over-broad prompting produces data that looks comprehensive but isn’t actionable. Monitoring “best marketing software” tells you almost nothing. Monitoring “best email automation tool for B2B SaaS under 50 seats” tells you exactly where you stand with a specific buyer.

    No competitor baseline. Measuring your visibility in isolation is like reviewing your traffic without knowing your category’s total search volume. What matters is Share of Voice: how your visibility compares to the brands your customers are actually choosing between.

    Insufficient sampling frequency. A monthly spot-check doesn’t capture the volatility of AI citation patterns. Model updates can shift recommendations in days. Weekly or daily monitoring is the standard that makes optimization decisions statistically meaningful.

    How to Improve Your AI Visibility Score: A Practical Checklist

    Improving your score starts with understanding why AI engines cite certain sources and not others. The short answer is authority and parsability.

    • Structure content for RAG extraction. Use clear H1-H3 headings, concise definitions, and FAQ sections. AI systems need to parse and extract coherent answers quickly. Dense paragraphs without clear structure get skipped.
    • Build third-party authority. AI models prioritize sources that reputable third parties already cite: industry roundups, high-authority directories, analyst reports. Digital PR strategy is now GEO strategy.
    • Audit your source footprint. Use Topify’s Source Analysis to identify which domains your AI search competitors are currently being cited from, then close the gap by getting featured on those platforms.
    • Maintain entity consistency. Name, description, and value proposition should be identical across every web touchpoint. Inconsistency signals unreliability to AI models that are trying to verify brand information across sources.
    • Monitor and address negative sentiment. Forum discussions on Reddit, G2, and Trustpilot get ingested by AI grounding systems. A pattern of negative mentions in those communities can suppress your visibility score even if your owned content is excellent.
    • Respond to model updates. When citation patterns shift after a model update, you need monitoring data to know it happened. Without that signal, you’re optimizing blind.
    • Expand prompt coverage over time. Start with 20-30 high-intent prompts, validate which ones drive meaningful visibility data, and build from there. More prompts = more signal.

    Choosing an AI Visibility Score Monitoring Platform: What to Look For

    The AI SEO rank tracking platforms market has grown quickly, and not all of them measure the same things. Here’s how to evaluate options against what actually matters in 2026:

    Evaluation DimensionWhat to Require
    Platform BreadthFull coverage: ChatGPT, Perplexity, Gemini, AI Overviews, and ideally international LLMs
    Data FrequencyDaily or near-daily updates for prompt-level visibility (weekly is becoming the floor)
    Sentiment AnalysisQualitative tone tracking, not just presence/absence
    Position TrackingShortlist placement vs. footnote differentiation
    Competitor BenchmarkingShare of Voice relative to named competitors
    Source AnalysisWhich domains and URLs the AI cites in your category
    Business Conversion MappingAbility to connect visibility data to pipeline or conversion metrics
    Pricing ModelTiered by prompt volume, not inflated enterprise bundles

    Topify covers all eight dimensions. The Basic plan at $99/month gives teams 100 prompts and 9,000 AI answer analyses monthly, which is enterprise-relevant scale for most marketing teams getting started. The Pro plan at $199/month expands to 250 prompts and 22,500 analyses. Enterprise plans start at $499/month and include custom configurations and a dedicated account manager.

    For teams that want optimization execution alongside monitoring, Topify’s managed GEO service runs $3,999-$5,999/month and includes content production, Reddit visibility, and prompt-level strategy. That’s a different category than software-only monitoring, but worth knowing if your team needs more than a dashboard.

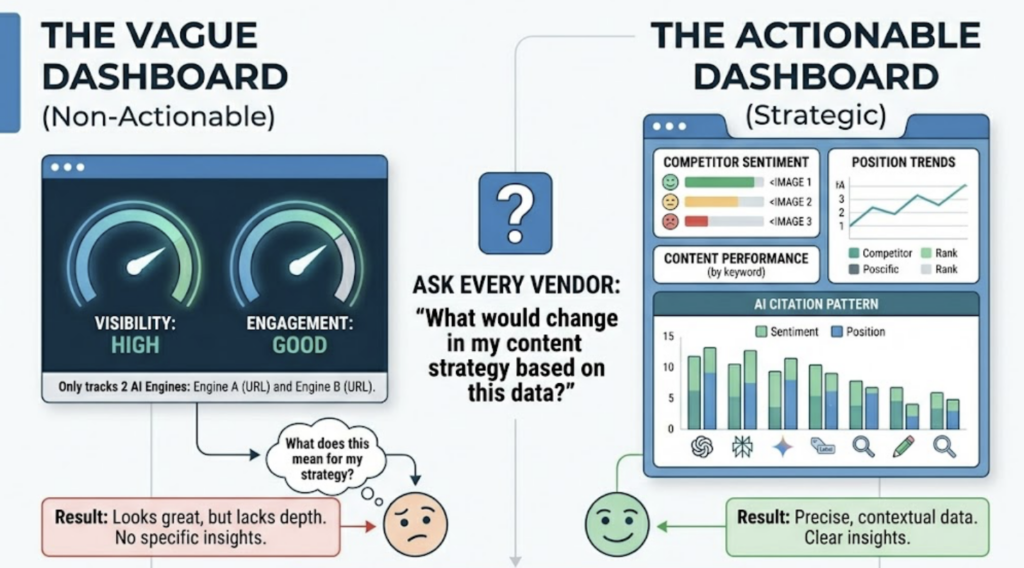
    The platforms that only track one or two AI engines, or that report visibility without sentiment or position context, tend to produce dashboards that look impressive but don’t generate actionable decisions. The question to ask any vendor is: “What would change in my content strategy based on this data?” If the answer is vague, the tool probably is too.

    Get started with Topify if you want to run your first prompt set and see where your brand actually stands across AI search platforms.

    Conclusion

    AI visibility score monitoring isn’t a replacement for SEO. It’s the layer that SEO tools don’t cover, and increasingly the layer that matters most to your buyers. The brands that know their visibility score, track its components, and optimize systematically will have a structural advantage over brands still waiting for their ranking tools to explain why organic traffic is declining.

    The data infrastructure exists. The monitoring frameworks are established. What’s missing for most teams is simply starting: picking a prompt set, choosing a platform that covers the metrics that matter, and building the feedback loop that makes GEO optimization as routine as any other channel.


    FAQ

    Q: What is AI visibility score monitoring?

    A: AI visibility score monitoring is the systematic practice of tracking how often, how favorably, and in what position a brand appears in AI-generated search answers across platforms like ChatGPT, Perplexity, and Gemini. It measures a composite score built from dimensions including mention rate, sentiment, position, source coverage, and conversion visibility.

    Q: How do I measure my AI visibility score?

    A: You measure it by defining a set of high-intent buyer prompts relevant to your category, running those prompts across multiple AI platforms on a regular cadence, and analyzing the resulting AI answers for brand mentions, sentiment, and position. Platforms like Topify automate this workflow across 100+ prompts and thousands of AI answer analyses per month.

    Q: How does AI visibility score monitoring work technically?

    A: Monitoring platforms use automated querying to run defined prompts against AI engines, then parse the generated answers to extract brand mentions, qualitative sentiment, and placement position. Results are aggregated into trend dashboards that show how visibility changes over time and across platforms. Continuous monitoring is necessary because AI citation patterns shift with every model update.

    Q: What are common mistakes in AI visibility score monitoring?

    A: The four most common mistakes are: tracking only one AI platform (each platform has distinct citation behaviors), using prompts that are too generic to be actionable, measuring visibility without a competitor baseline to contextualize the data, and running ad-hoc audits instead of consistent daily or weekly monitoring that provides statistically reliable trend data.


    Read More

  • AI Search Monitoring Software: What to Look for in 2026

    AI Search Monitoring Software: What to Look for in 2026

    Search “best GEO tool” and you’ll find a dozen platforms, each claiming to track AI search visibility. Half of them only cover ChatGPT. The other half show you dashboards full of numbers but no explanation of what changed or why. Meanwhile, AI search engines are shifting their citation patterns every few weeks, and last month’s data is already stale.

    The real problem isn’t finding an AI search monitoring tool. It’s figuring out which one actually measures what matters, across the platforms your audience is using right now.

    Why Your Current SEO Stack Can’t Monitor AI Search

    Traditional rank trackers were built on a simple loop: crawl, index, rank. That model doesn’t apply to generative search, and the gap is widening faster than most marketing teams realize.

    Here’s the core issue. AI search engines like ChatGPT, Perplexity, and Google AI Overviews synthesize answers from multiple sources and deliver them as natural language summaries. A significant portion of search volume now ends without a click. Users read the AI’s answer, take the recommendation, and move on. Your domain authority and keyword rankings played no role in whether you were mentioned.

    Traditional SEO tools track position in a static list. AI search monitoring tracks something different: citation frequency and share of model, metrics that measure whether your brand appears in the AI’s synthesized answer at all.

    There’s a third gap that’s easy to miss. Traditional tools can’t tell you how your brand is being described. An AI might mention your product in every response but consistently frame it as “a budget option” or “suited for small teams,” even if your positioning is enterprise-grade. That kind of brand narrative drift is invisible without dedicated AI search monitoring analytics.

    5 Capabilities That Separate Real AI Search Monitoring from Noise

    The market for AI search monitoring software is crowded with tools that look similar on a demo call but diverge significantly in what they actually measure. These five capabilities are the clearest differentiators.

    Multi-Platform Coverage

    Any AI search monitoring platform that only tracks one or two AI engines is giving you an incomplete picture. As the research from Nightwatch confirms, ChatGPT, Perplexity, Gemini, Claude, and Google AI Overviews each have different training corpora and citation logic. A brand that ranks prominently in Perplexity answers may be nearly invisible in Gemini, and vice versa. Coverage has to span the full ecosystem.

    Prompt-Level Tracking

    AI search engines respond to conversational queries, not keyword fragments. An effective AI search monitoring system tracks performance against sets of “buyer-intent prompts,” such as “What’s the best CRM for enterprise sales teams?” or “Which project management tools integrate with Slack?” These are the actual questions your prospects are asking. Monitoring generic brand keywords won’t tell you how visible you are at the moments that drive purchase decisions.

    Sentiment and Position Analysis

    Being mentioned is not the same as being recommended. According to Graph Digital’s visibility framework, high-quality AI search monitoring analytics must capture two distinct signals: sentiment (whether the AI’s description of your brand is positive, neutral, or negative) and position (whether your brand appears at the top of the AI’s shortlist or is buried in a closing disclaimer). Both signals are actionable. Neither shows up in a traditional SEO dashboard.

    Competitor Benchmarking in AI Answers

    Your AI search visibility only matters relative to your competitors’. A good AI search monitoring solution shows you Share of Voice within the same AI-generated responses where your brand appears. If a competitor is being cited in 70% of high-intent prompts and you’re cited in 20%, that gap is more important than any individual keyword ranking. The actionable question is: what sources is the AI using to build its answer for them, and not for you?

    Source and Citation Tracking

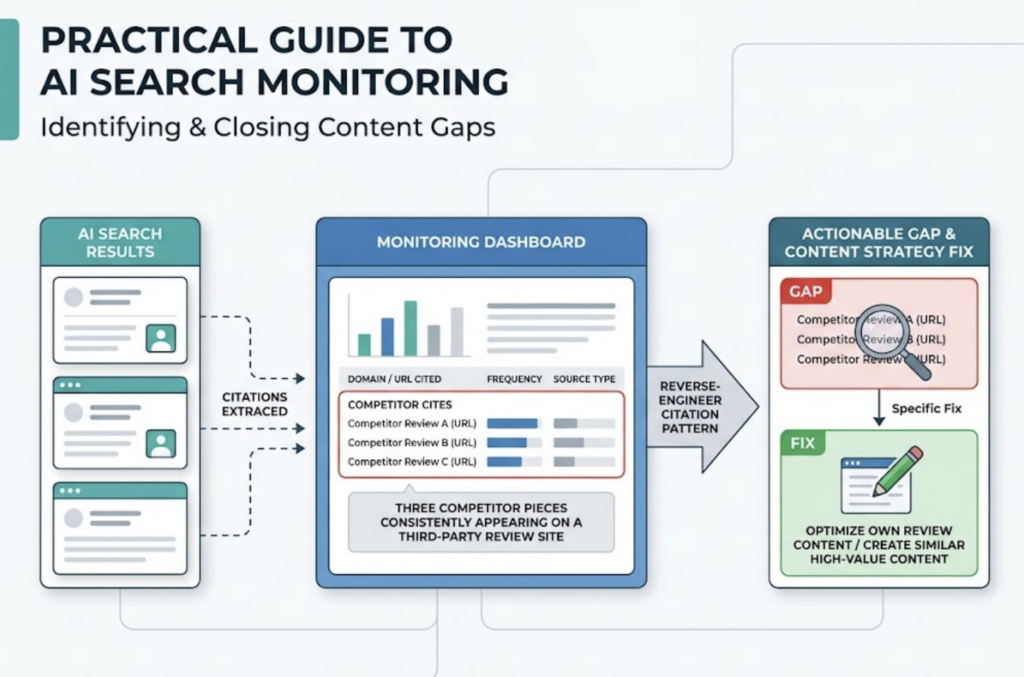
    This is where AI search monitoring becomes directly useful to a content team. As Omnia’s practical guide to AI search monitoring documents, identifying which URLs and domains AI models are citing to construct their answers lets content teams reverse-engineer the citation pattern. If three of your competitor’s pieces on a third-party review site are consistently appearing in AI citations, that’s a specific gap with a specific fix.

    What a Real AI Search Monitoring Dashboard Shows You

    A mature AI search monitoring dashboard doesn’t just confirm that your brand was mentioned. It quantifies the full picture across seven dimensions.

    According to the measurement framework now adopted by leading organizations, the seven KPIs that define AI visibility are:

    • Visibility Rate: the percentage of target queries where your brand appears in AI answers
    • Share of Model: your prominence relative to competitors within the same AI response
    • Sentiment Score: a qualitative rating of how AI engines describe your brand
    • Citation Source: the specific URLs and domains AI platforms are pulling from
    • AI Search Volume: demand for specific prompts and topic clusters
    • Intent Alignment: whether AI surfaces your brand at the right stage of the buyer journey
    • CVR (Conversion Visibility Rate): the correlation between AI-led discovery and downstream traffic or conversions

    In practice, a dashboard that shows all seven metrics lets you move from “we’re being mentioned” to “we understand exactly why our AI visibility dropped last month and what content to create to recover it.”

    Topify: An AI Search Monitoring Platform Built Around These Seven Metrics

    Topify is one of the few AI search monitoring platforms that tracks all seven dimensions out of the box. Built by founding researchers from OpenAI and champion Google SEO practitioners, it covers ChatGPT, Gemini, Perplexity, DeepSeek, Doubao, Qwen, and other major AI platforms, including both Western and Asian markets.

    The core product is built around a few things that most monitoring tools don’t offer together.

    Prompt Discovery continuously surfaces high-value AI search queries relevant to your brand and category, so you’re not manually guessing which prompts to track. It finds the questions your target customers are actually asking AI engines before they visit any website.

    Competitor Benchmarking runs automatically. Topify detects which competitors appear in the same AI responses as your brand, then tracks their position, sentiment, and citation sources over time. You don’t need to manually add rivals to a watchlist.

    Source Analysis shows the exact URLs and domains that AI platforms are citing when they mention your brand or your competitors. This is the most direct path from monitoring to action: see the citation gap, identify the content type, close it.

    One-Click Agent Execution ties the analytics layer to a strategy layer. Once the data identifies an opportunity, such as a citation gap on a high-intent prompt cluster, Topify’s AI agent can propose and deploy a GEO strategy with a single click.

    Pricing starts at $99/month on the Basic plan, which includes 100 prompts and 9,000 AI answer analyses per month across 4 projects. The Pro plan ($199/month) scales to 250 prompts and 22,500 AI answer analyses. Enterprise plans start at $499/month with a dedicated account manager and custom configurations.

    How to Evaluate AI Search Monitoring Services in 2026

    Beyond SaaS platforms, some organizations opt for service-oriented AI search monitoring, where an agency or consulting team runs audits and executes strategy on their behalf. As the buyer’s evaluation framework from Rankability outlines, the right choice depends on what your team actually needs.

    DimensionSaaS Platform (e.g., Topify)Service-Oriented (Agency)
    Best forDaily/weekly monitoring, trend analysisStrategy, content production, citation PR
    Data frequencyDaily or real-timePeriodic audits or campaign-based
    ActionabilityData provided; team executesAgency executes on your behalf
    Pricing modelSubscription-basedRetainer-based
    Team fitIn-house marketing or SEO teamTeams without GEO execution capacity

    Topify also offers a managed service tier, where their team handles prompt strategy, content production, Reddit visibility campaigns, and monthly reporting alongside platform access. The managed plans start at $3,999/month and are designed for brands that want full execution rather than just data.

    For most in-house marketing teams and agencies managing multiple clients, the SaaS platform is the faster path to visibility data. Managed services make more sense for brands that don’t have the internal bandwidth to act on the data themselves.

    3 Signs You Need an AI Search Monitoring System Now

    Most brands delay investing in AI search monitoring until a specific event forces the question. These three patterns are the clearest early signals.

    Competitors are showing up in AI answers and you don’t know why. If you can see that a rival is being recommended on high-intent queries but your team can’t identify which sources are driving those citations, you’re operating blind. That’s not an SEO problem. It’s a monitoring gap that traditional tools won’t close.

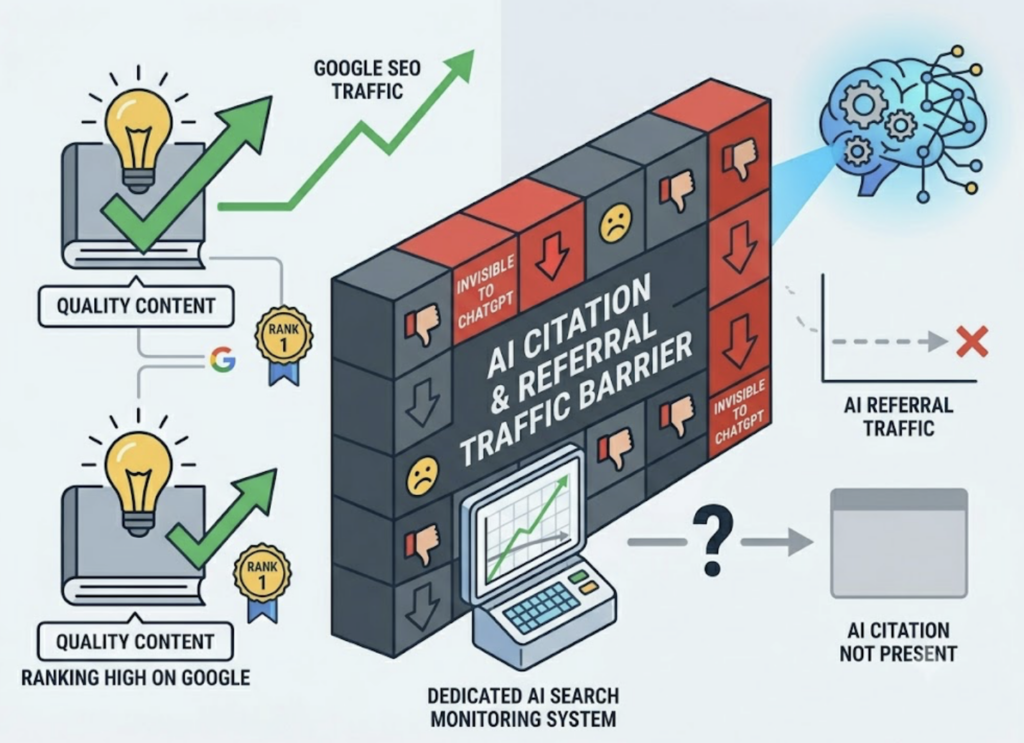
    Your content is ranking on Google but AI referral traffic is flat. SEO/AI divergence is one of the most reliable indicators that your content is optimized for keyword crawlers but not for AI citation. Ranking high on Google and being invisible to ChatGPT are not mutually exclusive. Without a dedicated AI search monitoring system, you won’t know which is happening.

    You’re not sure what AI is saying about your brand. This one surprises most teams. You can be mentioned frequently in AI answers and still have a brand narrative problem, where the AI consistently frames you in ways that don’t match your positioning. Without sentiment tracking, that drift is silent.

    Conclusion

    The monitoring question used to be simple: where do we rank? In 2026, that question has split into two. Where do we rank on Google, and what is AI saying about us? The tools that answer the first question don’t answer the second.

    An AI search monitoring system that covers multi-platform visibility, prompt-level tracking, sentiment analysis, competitor benchmarking, and source citation gives your team the data to act on both. Get started with Topify to see where your brand currently stands across ChatGPT, Perplexity, Gemini, and the other platforms your audience uses before they ever reach your website.

    FAQ

    Q: What is the best AI search tracking software in 2026?

    A: The best AI search tracking software in 2026 depends on your team’s specific needs, but a strong platform should cover multiple AI engines (not just ChatGPT), track performance at the prompt level, and provide sentiment and competitor benchmarking. Topify is one of the most comprehensive options, offering seven-dimensional GEO analytics across ChatGPT, Gemini, Perplexity, DeepSeek, and other major AI platforms, with plans starting at $99/month.

    Q: How is AI search monitoring different from SEO monitoring?

    A: SEO monitoring tracks where a page ranks in a static list of search results. AI search monitoring tracks whether and how your brand appears in AI-generated answers, what sentiment those mentions carry, how your brand is positioned relative to competitors within the same AI response, and which external sources the AI is citing. These are fundamentally different data sets, and traditional SEO tools aren’t built to capture the AI layer.

    Q: What does an AI search monitoring analytics dashboard typically include?

    A: A mature AI search monitoring dashboard covers visibility rate (how often your brand appears in AI answers for target queries), share of model (your prominence relative to competitors), sentiment score, citation source analysis, AI search volume for specific prompts, intent alignment, and CVR. Tools that only show mention frequency without sentiment or citation data are giving you an incomplete picture.

    Q: What should I look for in an AI search monitoring solution for a small team?

    A: For smaller teams, the key is a platform that surfaces actionable insights without requiring a dedicated analyst to interpret the data. Look for automated competitor detection, prompt discovery that identifies high-value queries without manual input, and clear citation tracking that tells you exactly which content gaps to address. Topify’s Basic plan at $99/month is designed with this use case in mind.

    Read More

  • AI Search Optimization: Strategy, Tools & Metrics

    AI Search Optimization: Strategy, Tools & Metrics

    Your brand might rank on page one of Google. But if ChatGPT doesn’t mention you, a growing share of your potential customers will never find you.

    That’s not a hypothetical. AI-powered search engines like Perplexity, ChatGPT Search, and Google AI Overviews are changing how people get answers. Instead of clicking through a list of blue links, users get synthesized responses drawn from sources the AI has already decided to trust. If your brand isn’t in that shortlist, you’re invisible at the moment of decision.

    AI search optimization is the discipline that closes this gap.

    What AI Search Optimization Actually Means

    AI search optimization is the systematic process of improving how AI engines understand, reference, and recommend your brand. The goal isn’t a higher ranking. It’s citation-worthiness: the likelihood that an AI selects your content as a trusted source within a generated response.

    That’s a fundamentally different target than traditional SEO.

    DimensionTraditional SEOAI Search Optimization
    Primary goalHigher SERP rankingCited as a trusted AI source
    Success metricCTR, organic trafficCitation frequency, sentiment, share of model
    Key driverBacklinks and keyword volumeContextual authority, semantic clarity
    Output typeURL listSynthesized natural-language answers
    Engine behaviorCrawling and indexingRetrieval-Augmented Generation (RAG)

    The shift matters because the two systems reward different things. You can have a strong backlink profile and still never appear in a ChatGPT response. AI visibility requires its own strategy.

    How AI Search Engines Decide What to Recommend

    When a user submits a query to an AI engine, the system doesn’t browse the web in real time. It runs a process called Retrieval-Augmented Generation (RAG): retrieve relevant documents from its corpus, evaluate their credibility, and synthesize an answer using an LLM.

    The citation decision follows a clear hierarchy.

    First, semantic completeness: the content must answer the query directly and comprehensively. AI models favor front-loaded answers where core information appears in the first 30% of the content. Second, entity authority: a brand is considered authoritative if it’s consistently mentioned across high-trust platforms like industry news sites, G2, or Trustpilot. Third, source verifiability: AI systems prefer content backed by original data or proprietary statistics, since these reduce the risk of hallucination.

    Why Traditional SEO Isn’t Enough

    A strong domain authority doesn’t translate automatically into AI citations. Keyword density doesn’t influence how an LLM weighs your content. The signals that move you up Google’s SERP and the signals that get you cited in a ChatGPT response are largely independent.

    That’s the gap most brands still haven’t addressed.

    5 Strategies That Actually Move the Needle

    1. Build Content That Provides Information Gain

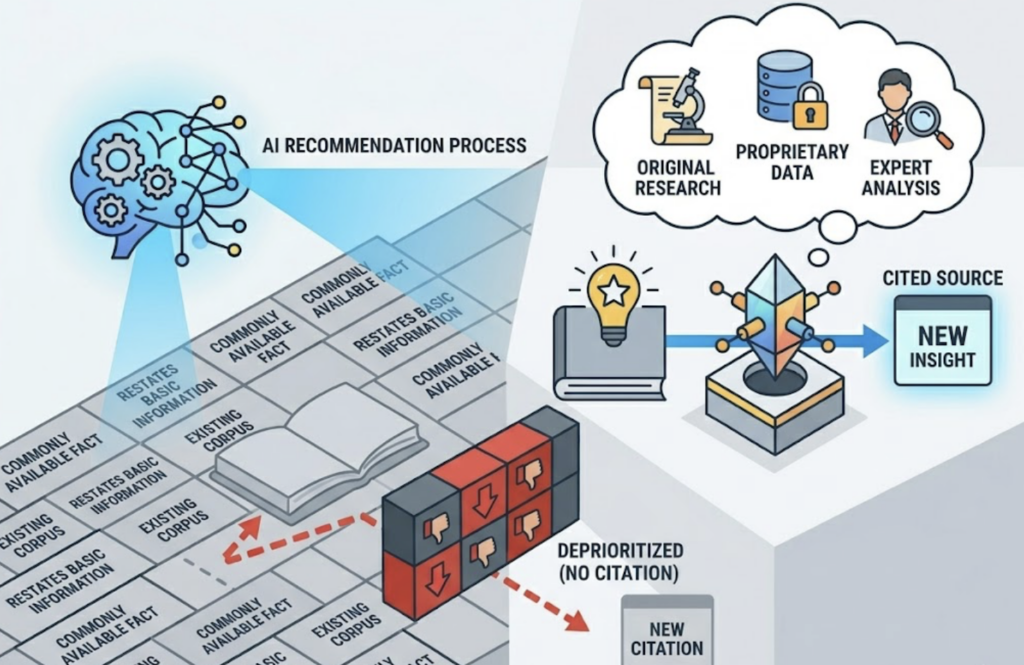
    AI systems are specifically trained to deprioritize content that restates commonly available facts. To get cited, you need original insights, proprietary data, or a perspective that adds something new to the existing corpus. Think primary research, case studies, or expert analysis.

    Generic content doesn’t earn citations. Authoritative content does.

    2. Structure Content for Machine Extraction

    Clean heading hierarchies (H1 through H3), clear HTML, and structured data markup make your content machine-readable. AI parsers extract information from well-structured documents far more reliably than from dense, unformatted prose.

    FAQ sections, definition blocks, and comparison tables are all formats AI engines handle well. Adding an llms.txt file to your site provides a machine-readable summary of your most important content.

    3. Expand Your Entity Footprint Across the Web

    AI doesn’t only read your website. It aggregates signals from across the web. If your brand is consistently mentioned in industry forums, third-party review platforms, and news outlets, the model builds a richer, more authoritative entity profile for you.

    Targeting only your own domain is a siloed strategy. Cross-web presence is how you build AI trust.

    4. Monitor Prompt Coverage and Fill the Gaps

    Your brand might be visible for some queries and completely absent for others. Identifying which prompts your audience actually uses, and tracking whether you appear in those specific AI answers, is the core operational loop of AI search optimization.

    Topify‘s Competitor Monitoring and Source Analysis features surface exactly this: which prompts your competitors own, which domains AI engines are citing in your category, and where your brand has coverage gaps. You can track up to 250 prompts on the Pro plan and benchmark your citation share against direct competitors in real time.

    5. Benchmark Against Competitors, Not Just Yourself

    Your absolute visibility rate matters less than your relative position. If your main competitor is cited in 60% of relevant AI responses and you’re at 20%, that’s the gap you need to close, regardless of your raw score.

    Competitor benchmarking gives you a map. Without it, you’re optimizing blind.

    How to Measure AI Search Optimization Performance

    Ranking positions aren’t the right proxy here. AI search optimization requires a different measurement framework.

    Topify tracks seven metrics across major AI platforms including ChatGPT, Perplexity, Gemini, and Google AI Overviews:

    MetricWhat It Measures
    VisibilityPercentage of target prompts where your brand is cited
    SentimentWhether AI mentions of your brand are positive, neutral, or negative (0-100 score)
    PositionYour brand’s ranking order relative to competitors in AI responses
    VolumeEstimated search volume for tracked AI prompts
    MentionsRaw frequency of brand citations across platforms
    IntentThe user intent category behind prompts where you appear
    CVR (Conversion Visibility Rate)Likelihood that an AI answer guides a user toward your brand

    A Practical Measurement Checklist

    TaskFrequency
    Track brand visibility across target promptsWeekly
    Review sentiment score and flag negative mentionsWeekly
    Audit competitor position for top 20 promptsMonthly
    Identify new high-volume prompts in your categoryMonthly
    Review which domains AI is citing in your categoryMonthly
    Correlate AI visibility changes with direct trafficQuarterly
    Update content strategy based on citation gapsQuarterly

    Start with a baseline. Without one, you can’t tell whether your optimization efforts are working.

    Common Mistakes That Kill Your AI Visibility

    Treating AI visibility like a rank-tracking project. Page-one Google rankings don’t guarantee a single ChatGPT citation. The two systems are independent. Brands that assume SEO success transfers to AI visibility consistently underperform.

    Weak entity positioning. If your website doesn’t clearly define what your brand does and what problem it solves, AI models develop “entity ambiguity” about you. That ambiguity translates to fewer citations, or worse, inaccurate ones.

    Mass-producing generic content. High-volume, undifferentiated content actively works against AI visibility. LLMs are trained to identify and deprioritize content that adds no new information. One authoritative piece outperforms twenty generic ones.

    Ignoring external signals. Optimizing only your own website while ignoring third-party platforms misses most of how AI builds trust. Cross-web presence drives entity authority.

    No baseline, no benchmark. Many teams optimize content without knowing their starting visibility rate. Without a baseline, you can’t measure ROI, justify budget, or identify what’s actually working.

    Best Tools for AI Search Optimization

    The AI search optimization tooling market is still relatively early, but a few platforms have emerged with purpose-built infrastructure for tracking and improving brand visibility in AI responses.

    Topify covers the full workflow: prompt discovery, cross-platform visibility tracking across ChatGPT, Perplexity, Gemini, and DeepSeek, competitor benchmarking, source analysis, sentiment scoring, and one-click GEO strategy execution. It’s built specifically for this use case, which is why teams use it instead of adapting traditional SEO tools to a problem they weren’t designed to solve.

    PlanPriceKey Limits
    Basic$99/mo100 prompts, 9,000 AI answer analyses, 4 projects
    Pro$199/mo250 prompts, 22,500 AI answer analyses, 10 seats
    EnterpriseFrom $499/moCustom prompts, dedicated account manager

    A 30-day trial is available on the Basic plan. For teams that want managed execution rather than a self-serve platform, Topify also offers a full-service GEO package starting at $3,999/mo, which includes content production, Reddit visibility, and SEO alongside AI monitoring.

    FAQ

    What is AI search optimization? 

    AI search optimization is the process of improving how AI-powered search engines understand, reference, and recommend your brand. The goal is to increase citation frequency, sentiment quality, and position within AI-generated responses across platforms like ChatGPT, Perplexity, and Google AI Overviews.

    How does AI search optimization work? 

    AI engines use a process called Retrieval-Augmented Generation (RAG): they retrieve relevant documents, evaluate credibility, and synthesize an answer. Optimization means making your content more authoritative, better structured, and more widely referenced so that the AI selects it as a trusted source.

    What are examples of AI search optimization? 

    Common tactics include publishing original research to establish topical authority, adding structured data markup so AI can parse your content, expanding brand presence on third-party platforms to build entity authority, and monitoring which prompts your competitors own so you can target the gaps.

    What’s the difference between AI SEO and traditional SEO? 

    Traditional SEO targets search engine rankings using backlinks and keyword optimization. AI search optimization targets citation inclusion in AI-generated answers, which is driven by semantic authority, structured content, and cross-web entity presence. The signals, tools, and success metrics are largely distinct.

    How much does AI search optimization cost? 

    Self-serve platforms like Topify start at $99/month. Managed GEO services typically run $3,999-$5,999/month and include content production and active optimization alongside monitoring.

    How do I measure AI search optimization performance? 

    The core metrics are visibility rate (what percentage of target prompts your brand appears in), sentiment, position relative to competitors, and CVR (the likelihood an AI answer leads to a brand interaction). Tools like Topify track all seven of these metrics across major AI platforms.

    Read More

  • AI Search Optimization: What It Is and How to Do It

    AI Search Optimization: What It Is and How to Do It

    Your brand might rank on page one of Google. But when someone asks ChatGPT to recommend a tool in your category, you’re not there. That’s not a content problem. It’s a visibility problem in a system most teams haven’t started measuring yet.

    AI search optimization is the practice of making your brand visible, citable, and trustworthy to AI systems. It operates by a different set of rules than traditional SEO, and the gap between teams who understand that and teams who don’t is widening fast.

    AI Search and Traditional SEO Are Not the Same Game

    Traditional SEO is about ranking. You optimize for crawlability, keyword density, and backlinks. The output is a position on a results page.

    AI search doesn’t work that way. When a user asks ChatGPT or Perplexity a question, the model doesn’t return a ranked list. It synthesizes an answer and, in doing so, decides which sources to cite and which brands to mention. That decision isn’t about ranking. It’s about perceived authority, semantic clarity, and cross-platform trust signals.

    The practical implication: two brands with identical Google rankings can have completely different AI visibility outcomes. The one that shows up in AI answers isn’t necessarily the one with more backlinks. It’s the one the model “trusts” as a source.

    That’s a different optimization problem.

    So, What Is AI Search Optimization?

    AI search optimization (also referred to as Generative Engine Optimization, or GEO, and Answer Engine Optimization, or AEO) is the process of making a brand visible and citable across AI-driven search platforms including ChatGPT, Gemini, Perplexity, and Google AI Overviews.

    Unlike traditional SEO, which targets keyword rankings, AI search optimization targets the model’s citation decision. The goal is to be the brand that gets mentioned when a user asks an AI system a question relevant to your category.

    Here’s a useful way to frame the shift:

    Traditional SEOAI Search Optimization
    Core goalHigh SERP rankingInclusion as a cited source in AI answers
    InterfaceLists of linksSynthesized natural-language answers
    What models analyzeKeyword density, backlinksSemantic clarity, entity authority, factual accuracy
    Key metricsCTR, organic trafficBrand mention rate, citation rate, sentiment score

    The underlying mechanism matters here. AI systems use retrieval-augmented generation (RAG) to find relevant sources before generating an answer. They don’t rank pages. They assess which sources best answer the query with accuracy, clarity, and authority. That’s the process you’re optimizing for.

    The 5 Signals That Actually Drive AI Citations

    Most teams assume that good SEO automatically translates to AI visibility. It often doesn’t. The signals LLMs use to select sources are related to, but distinct from, traditional ranking factors.

    Answerability. Models favor content that front-loads answers. If the most important information sits in the first 30% of your content, it’s significantly more likely to be retrieved. Structured Q&A sections, direct definitions, and clean paragraph openings all improve answerability.

    Entity authority. AI systems cross-validate brands by checking whether they appear consistently across high-authority domains, such as industry publications, news sites, forums like Reddit, and review platforms like G2 or Trustpilot. A brand mentioned once on Forbes carries less weight than a brand mentioned consistently across 20 relevant sources.

    Semantic structure. Clean HTML, heading hierarchies, and schema markup help models parse and extract facts accurately. Structural clarity isn’t just a UX consideration; it’s a retrieval consideration.

    Freshness. LLMs exhibit a recency bias. Content that’s regularly updated, or that reflects real-time developments, is more likely to be retrieved than static pages that haven’t changed in two years.

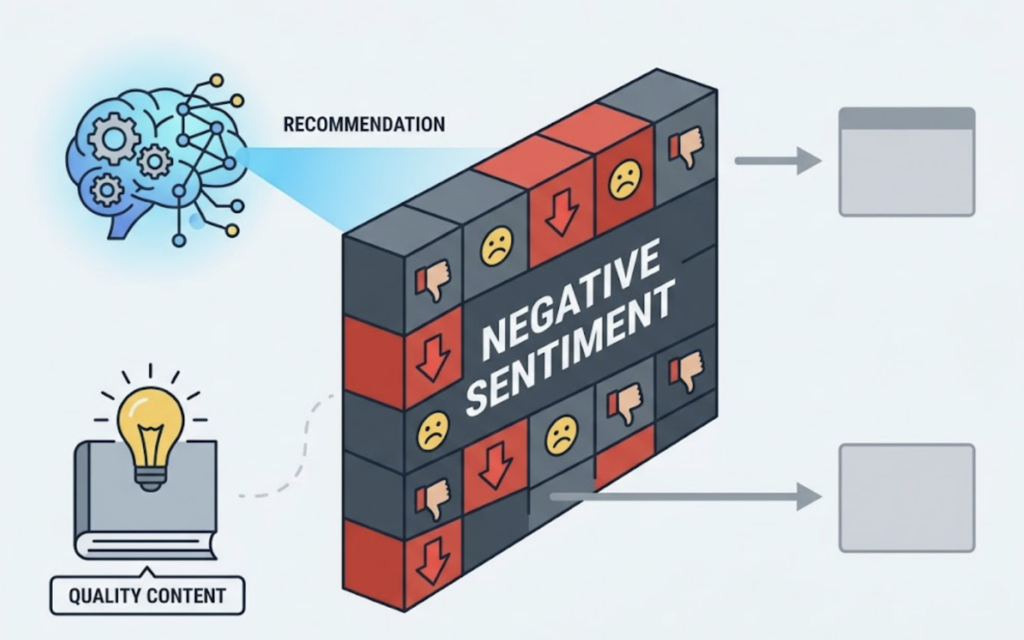
    Sentiment. Negative sentiment in reviews or forum discussions can suppress AI recommendations regardless of content quality. If the prevailing signal around your brand is negative, the model may simply avoid citing you even when your content is technically authoritative.

    How to Measure AI Search Optimization

    This is where most teams have a blind spot. They’re running AI search optimization without any measurement infrastructure. When visibility shifts, they don’t know if it’s because of an algorithm update, a competitor’s content push, or something they did themselves.

    Effective AI search intelligence requires a distinct set of KPIs:

    AI visibility rate: The percentage of relevant prompts where your brand is explicitly mentioned or cited by the AI. This is your baseline metric.

    Citation rate: How often the AI provides a direct link to your domain as a source. Higher citation rate generally correlates with higher answerability and entity authority.

    Share of voice (SOV): Your brand’s presence relative to competitors within the same AI response. SOV tells you not just whether you’re visible, but how visible you are compared to the alternatives.

    Sentiment score: An automated analysis of how the AI describes your brand. Positive sentiment isn’t just good PR; it’s a functional prerequisite for being recommended.

    Position tracking: Where your brand appears in a multi-source AI response. First mention carries more weight than a footnote.

    Conversion visibility rate (CVR): The estimated likelihood that an AI mention drives a user toward a brand interaction. This connects AI visibility to revenue potential.

    Platforms like Topify are built specifically for this measurement layer. Topify tracks all seven of these metrics across ChatGPT, Gemini, Perplexity, and other major AI platforms, giving teams a structured dashboard instead of manual spot-checking. The Basic plan starts at $99/month and includes tracking for 100 prompts, 9,000 AI answer analyses, and four projects.

    Without this kind of AI search analytics infrastructure, you’re running optimization in the dark.

    A Practical 6-Step Strategy for AI Search Optimization

    Building an AI search optimization strategy doesn’t require starting from scratch. Most of the infrastructure is already there. The work is in adapting it.

    Step 1: Identify your target AI prompts. The prompts your audience types into ChatGPT are often different from the keywords they search on Google. Start by mapping the questions your potential customers are asking AI systems about your category. Focus on “best [category] for [use case]” and “what is [problem] and how do I solve it” patterns. These are the high-intent prompts where AI citations directly influence purchase decisions.

    Step 2: Audit your baseline AI visibility. Before optimizing anything, run a baseline audit. Test your brand’s current appearance across ChatGPT, Gemini, and Perplexity using your target prompts. Document which prompts trigger a mention, what sentiment the mentions carry, and where you appear relative to competitors. This baseline is the foundation of everything that comes after.

    Topify’s Visibility Tracking automates this across platforms, running 9,000+ AI answer analyses per month on the Basic plan so you’re not doing it manually.

    Step 3: Optimize source authority. Digital PR is one of the highest-leverage activities in AI search optimization. Being mentioned on “kingmaker” domains, such as industry publications, high-DR news sites, and category-specific forums, is a primary driver of LLM discovery. A single placement on a well-regarded industry site does more for your AI visibility than a dozen low-authority backlinks.

    Step 4: Restructure content for answerability. Audit your existing content and refactor it. Add direct Q&A sections, clean up paragraph openings so the main point comes first, use FAQ schema, and eliminate filler. Every paragraph should either answer a question or establish a fact. Content that wanders doesn’t get cited.

    Step 5: Manage entity consistency. Your brand information, including your name, product descriptions, mission statement, and key differentiators, should read consistently across your website, social profiles, and third-party directories. AI systems cross-reference multiple sources. Inconsistency between sources reduces the confidence the model has in your brand as a reliable entity.

    Step 6: Monitor, iterate, and track changes. AI model updates shift citation patterns. Competitor content activity affects your share of voice. A prompt that surfaces your brand today may not surface it three months from now if your content hasn’t been refreshed or a competitor has outpaced your authority.

    Treat AI search intelligence as a live dashboard, not a quarterly report. Topify’s competitor monitoring tracks competitor positioning in real time, so you know when a rival’s AI visibility is climbing before it shows up in your own metrics.

    Common Mistakes That Suppress AI Visibility

    Most teams who are “doing AI search optimization” are making at least one of these mistakes.

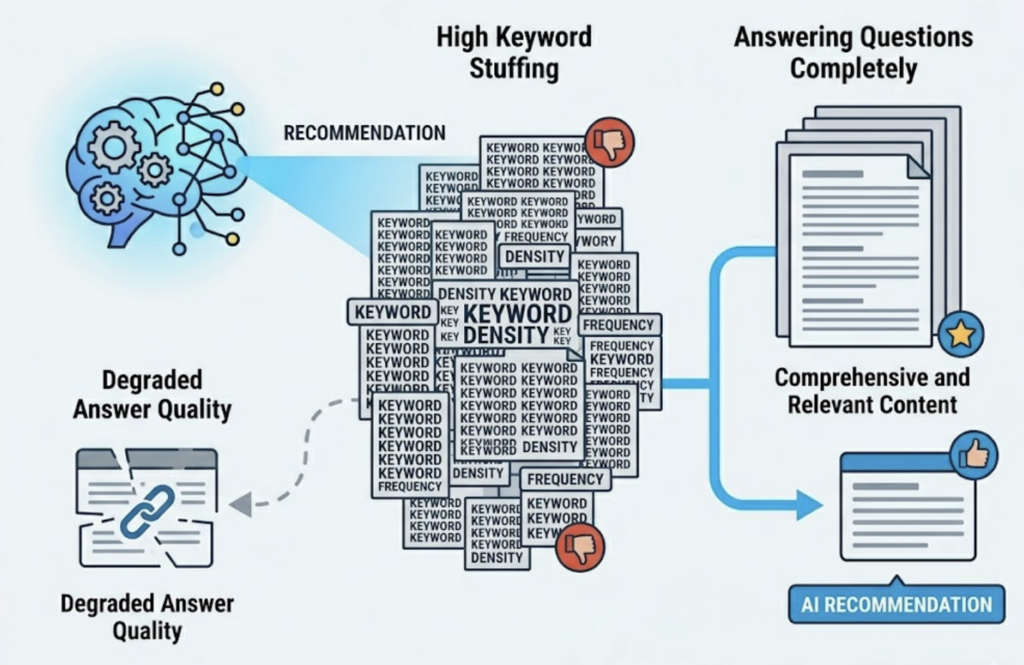
    Optimizing for keywords instead of intent. AI models prioritize semantic relevance, not keyword frequency. Keyword stuffing doesn’t improve AI citations. In some cases, it actively degrades answer quality and makes a source less likely to be retrieved. Focus on answering questions completely, not on hitting keyword density targets.

    Treating AI search as a zero-click problem. Some teams deprioritize AI visibility because it doesn’t generate direct referral traffic. That framing misses the point. AI search is a brand-building channel. A user who hears your brand name three times in AI responses before they ever visit your site is not a cold lead.

    Applying legacy tactics to a new system. Mass-produced, low-quality content, thin pages, and templated structures are precisely what LLMs are trained to filter out. The tactics that gamed Google in 2012 don’t translate.

    Running optimization without measurement. This is the most common mistake. Without an AEO-specific tracking system, you can’t distinguish the impact of a content update from the impact of a model update. You’re optimizing blind.

    AI Search Optimization Checklist

    Use this checklist before, during, and after any AI search optimization effort:

    Foundation

    • [ ] Target AI prompts identified and documented
    • [ ] Baseline visibility audit completed across ChatGPT, Gemini, and Perplexity
    • [ ] Competitor AI visibility benchmarked

    Content

    • [ ] Key content pages refactored with front-loaded answers
    • [ ] FAQ sections and Q&A schema added to relevant pages
    • [ ] Paragraph openings lead with the main point
    • [ ] Content updated within the last 90 days

    Authority

    • [ ] Brand mentioned consistently on at least 3 high-authority external domains
    • [ ] Entity information consistent across website, social, and directories
    • [ ] Sentiment on public review platforms monitored and addressed

    Measurement

    • [ ] AI visibility rate tracked per prompt
    • [ ] Citation rate and sentiment score monitored
    • [ ] Competitor share of voice tracked
    • [ ] CVR (Conversion Visibility Rate) established as a target metric

    Iteration

    • [ ] Visibility changes logged with timestamps
    • [ ] Content refreshes scheduled quarterly at minimum
    • [ ] AI platform model updates monitored for citation pattern shifts

    Conclusion

    AI search optimization isn’t a future consideration. It’s a present gap. Brands that are ranking well on Google but invisible in AI answers are already losing discovery to competitors who’ve started treating AI visibility as a structured, measurable growth channel.

    The core shift is this: from ranking for keywords to being cited as a trusted source. The strategy, the metrics, and the tools are all different. But the underlying logic is familiar. Authority, relevance, and consistency still win. They just play out on a different surface.

    Topify gives teams the infrastructure to track, measure, and optimize AI brand visibility across every major platform. If you’re starting from zero, the baseline audit is the first step. Everything else follows from knowing what you’re actually working with.

    FAQ

    What is AI search optimization? 

    AI search optimization (also called GEO or AEO) is the process of making your brand visible and citable in AI-generated answers across platforms like ChatGPT, Gemini, and Perplexity. It focuses on being included as a trusted source in AI responses rather than ranking in traditional search results.

    How does AI search optimization work? 

    AI systems use retrieval-augmented generation (RAG) to find relevant sources before generating an answer. They assess source authority, content structure, semantic clarity, and cross-platform consistency. Optimizing for these signals increases the likelihood that your brand is cited in relevant AI answers.

    How do I measure AI search optimization? 

    Key metrics include AI visibility rate (how often your brand appears in relevant AI answers), citation rate, sentiment score, share of voice relative to competitors, and conversion visibility rate. Platforms like Topify provide dashboards for tracking all of these across multiple AI engines.

    What are the best tools for AI search optimization? 

    Topify is an AI search optimization platform that tracks brand visibility across ChatGPT, Gemini, Perplexity, and other major AI engines. It covers seven core metrics including visibility, sentiment, position, and CVR. Plans start at $99/month for 100 prompts and 9,000 AI answer analyses. For a broader list of free GEO tools, see the GEO free tools reference.

    What are examples of AI search optimization in practice? 

    A SaaS company auditing which prompts surface their brand in ChatGPT. A marketing team running digital PR to get mentioned on high-authority industry sites. An in-house SEO team restructuring blog posts to front-load answers. A brand tracking competitor share of voice across Perplexity after a product launch. These are all AI search optimization in practice.

    What is the difference between AI SEO and traditional SEO?

    Traditional SEO targets keyword rankings on search engine results pages. AI SEO (or GEO/AEO) targets inclusion as a cited source in AI-generated answers. The signals, metrics, and content strategies differ significantly, though they share some foundational principles around authority and relevance.

    How much does AI search optimization cost? 

    Costs vary. DIY approaches using free tools can get you started at no cost. Dedicated platforms like Topify start at $99/month for self-serve tracking. Full-service GEO optimization programs that include content production and strategy execution start at $3,999/month.

    Read More

  • Is Your Brand in Claude Opus 4.8’s Answers? Check Now

    Is Your Brand in Claude Opus 4.8’s Answers? Check Now

    You did everything right. Your domain authority is solid, your content ranks, and your SEO team has the keyword coverage locked down. Then someone on your executive team opens Claude Opus 4.8, types “What are the top tools for [your category]?” and your brand isn’t in the answer.

    That’s not a fluke. And it can’t be fixed with another backlink.

    Why Claude Opus 4.8 Brand Visibility Works Differently

    Claude Opus 4.8, launched on May 28, 2026, isn’t another chatbot upgrade. It’s Anthropic’s most capable model yet, with enhanced agentic reasoning, improved citation precision, and what Anthropic describes as “effort-control” capabilities. More enterprises and professional buyers are using it daily for vendor research, category discovery, and product comparison.

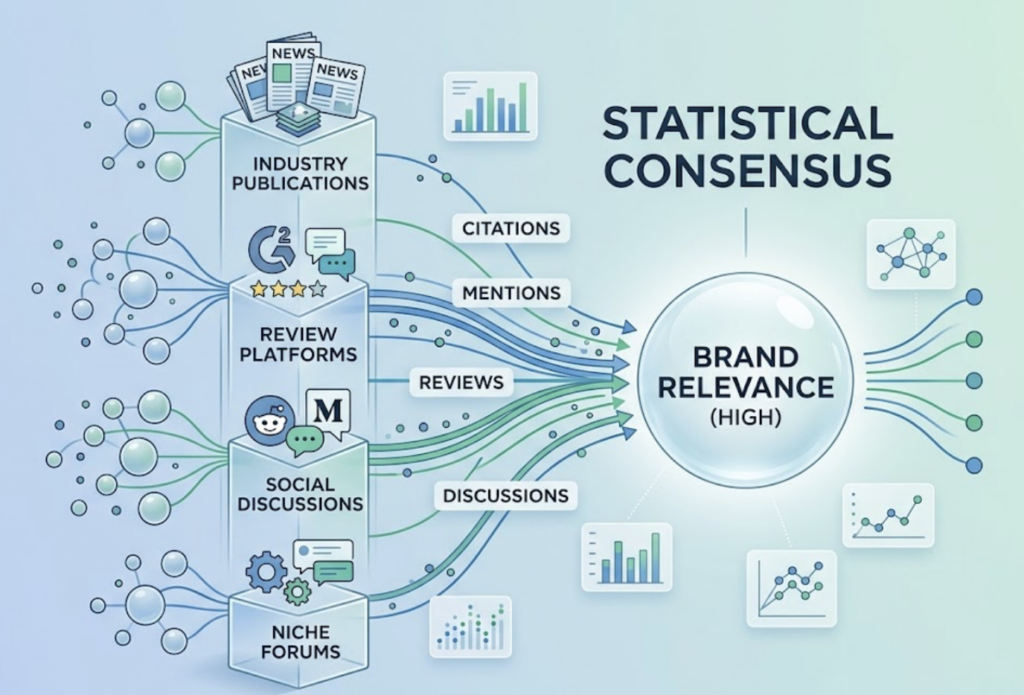
    The visibility problem here is structural. Claude doesn’t index websites in real time the way Google does. According to research on GEO vs. SEO dynamics, traditional search engines measure clicks and rankings, while AI models operate on something closer to “probabilistic knowledge graphs.” Your brand is “visible” only if the model has built a strong statistical association between your name and the user’s intent during training and retrieval.

    That’s a fundamentally different game.

    Opus 4.8’s superior reasoning capability makes this even more pronounced. It’s more selective about citations than previous models, less likely to surface brands backed by shallow or ambiguous content. If your brand presence across the web is thin, inconsistent, or hard to parse, Opus 4.8 is more likely to skip you than earlier Claude versions would have.

    The Manual Check: How to Query Claude Opus 4.8 for Your Brand

    The fastest starting point is direct. Open Claude Opus 4.8 and test a few prompts yourself. But the query structure matters more than most teams realize.

    Generic queries like “tell me about [Brand X]” bypass the actual decision context where brand citations happen. Instead, test these three prompt categories:

    Comparative queries — “Compare the top platforms for [your category]. What are the tradeoffs?”

    Intent-based queries — “What’s the best tool for [specific use case] for a mid-size marketing team?”

    Expert-opinion queries — “If I were advising a B2B SaaS company on [your problem space], what would you recommend?”

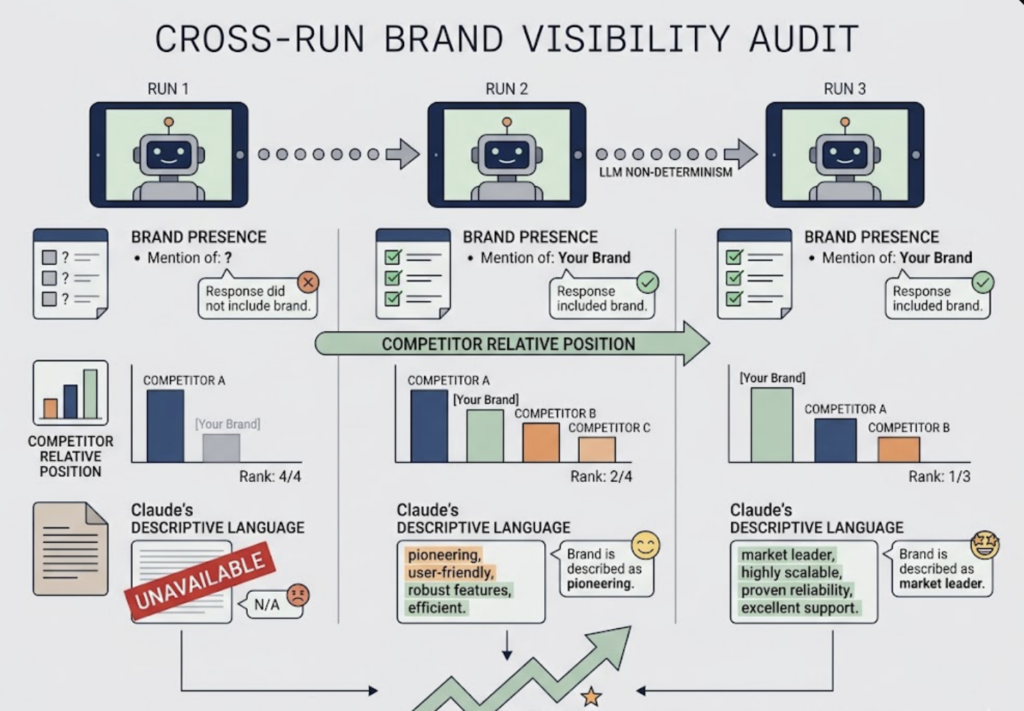
    Run each prompt two to three times. LLM responses are non-deterministic, so a single result tells you almost nothing. What you’re looking for across multiple runs: Does your brand appear at all? Where does it appear relative to competitors? What language does Claude use to describe you?

    That last point matters more than the mention itself.

    What Claude’s Answer Actually Tells You About Your Brand

    Getting mentioned isn’t the same as getting recommended.

    Claude Opus 4.8’s enhanced reasoning means it often contextualizes citations with nuance. Watch for three distinct patterns:

    Top-level mentions — Your brand appears in the lead recommendations without qualifiers. This is where you want to be.

    Qualified mentions — Claude includes your brand but attaches limitations: “good for smaller teams,” “better for budget-conscious buyers,” “newer to the market.” If this doesn’t match your positioning, you have a narrative problem.

    Competitive context only — Your brand appears solely as a comparison point for a competitor. “Unlike Brand X, Brand Y offers…” This is the lowest-value visibility position.

    Research on LLM citation decay describes how brands can drop from AI answers entirely despite stable Google rankings. One common cause is what researchers call “semantic ambiguity.” If your messaging is inconsistent across platforms, Claude may fail to map your brand to a specific category confidently, and choose a more clearly-defined competitor instead.

    The sentiment and position data you gather from manual testing forms a baseline. The problem is keeping it current at any useful scale.

    Why Manual Testing Breaks Down Fast

    Here’s what manual testing can’t tell you.

    Claude’s responses aren’t stable. The same prompt tested today versus next week may produce different results as Anthropic updates the model or adjusts retrieval mechanisms. A single round of manual testing gives you a snapshot, not a trend.

    Coverage is the bigger issue. Your brand isn’t discovered through one or two query types. Real users ask questions in hundreds of different ways. “Best tool for X” generates different results than “X for enterprise” or “alternatives to [competitor].” Testing even 10 prompt variants manually takes significant time. Testing 100 is practically impossible.

    And Claude Opus 4.8 is one platform. Your buyers are also using Perplexity, ChatGPT, Gemini, and increasingly AI-powered agents that pull from multiple sources. A brand that shows up well in Claude but is invisible in Perplexity has a coverage problem you’d never detect from Claude testing alone.

    This is why professional GEO strategy requires a systematic prompt matrix approach, not periodic spot-checks.

    How to Track Claude Opus 4.8 Brand Visibility at Scale

    Systematic Claude Opus 4.8 brand monitoring starts with building a prompt matrix that mirrors how real users discover brands in your category.

    Topify is built specifically for this. The platform monitors brand visibility across Claude, ChatGPT, Perplexity, Gemini, and other major AI engines simultaneously, tracking seven metrics across each: Visibility Score, Sentiment Score, Position Rank, mention frequency, source citations, intent alignment, and CVR (Conversion Visibility Rate).

    The Prompt Discovery feature is particularly useful for Claude Opus 4.8 monitoring. It continuously surfaces high-volume AI prompts relevant to your category, including query variations you wouldn’t have thought to test manually. This means your monitoring coverage expands over time rather than staying locked to the 10 or 20 prompts you set up at launch.

    For brand managers tracking Claude Opus 4.8 specifically, Topify’s Competitor Monitoring module shows where your brand lands relative to competitors across each query type. You’re not just seeing “did we appear,” but “did we appear before or after Brand X, and in what context.”

    The Source Analysis feature closes the loop. When Claude cites your brand, it’s drawing on specific third-party sources — forums, publications, review platforms — that carry weight in its reasoning. Topify surfaces exactly which domains are driving those citations, and which domains are currently amplifying your competitors. That’s where your PR and content strategy investments should go next.

    Interpreting Your Claude Opus 4.8 Visibility Data

    Once you have consistent monitoring in place, the data starts to tell a clearer story.

    A high Visibility Score — the percentage of AI responses where your brand appears — with a low Position Rank means Claude knows you exist but isn’t leading with you. That’s typically a content authority problem. The model has weak statistical association between your brand and high-confidence recommendation, often because you’re underrepresented in the third-party sources it trusts most.

    A Visibility Score drop after a model update (Opus 4.7 to 4.8, for example) is a signal worth investigating immediately. As the Anthropic documentation on Opus 4.8 notes, the model has improved citation precision. Brands that were coasting on shallow presence in earlier versions often see a visibility decline when the model upgrades its standards.

    Negative sentiment in Claude’s responses — even while your brand is still mentioned — is the most underreported issue. Topify’s Sentiment Score (0-100 scale) quantifies this. A brand scoring 40 on sentiment while a competitor scores 75 is losing buyer consideration in a way that traditional analytics will never surface.

    Three Moves If Your Brand Isn’t Showing Up

    If your Claude Opus 4.8 visibility is low, the fix isn’t more blog posts.

    Build authority anchors in sources Claude trusts. According to guidance from Jasper’s GEO research, AI models prioritize information validated by reliable third-party sources. For most B2B categories, this means Reddit, G2, industry journals, and recognized analyst publications. A brand consistently cited across diverse, high-authority domains builds the “consensus presence” Claude uses to confidently recommend.

    Restructure your content for AI parsing. Claude Opus 4.8 prefers what researchers describe as “extraction-friendly” content. Structured formats — organized FAQs, clear comparison tables, intent-based headings — make it easier for the model to synthesize your brand’s value proposition into a direct answer. Unstructured long-form content often gets passed over in favor of competitors who’ve made their positioning explicit and parseable.

    Treat each major model release as a monitoring trigger. GEO isn’t a set-it-and-forget-it discipline. Opus 4.8’s reasoning changes how it evaluates sources relative to Opus 4.7. The brands that maintain Claude Opus 4.8 visibility are the ones continuously monitoring their position after each update, not the ones who checked six months ago and assumed nothing changed.

    Conclusion

    Claude Opus 4.8 is where an increasing share of professional buying decisions start. If your brand isn’t in its answers, or is appearing with the wrong context, you’re losing consideration before a competitor even gets mentioned.

    Manual testing gets you a starting point. It won’t keep you there. Building a systematic approach to Claude Opus 4.8 brand visibility — tracking the right prompts, measuring sentiment and position, and connecting citations back to specific sources — is what separates teams that react to AI search from teams that shape it. Get started with Topify to set up your baseline and see where your brand stands across every major AI engine today.

    FAQ

    Q: Does Claude Opus 4.8 use real-time data to decide which brands to mention?

    A: Not entirely. Claude Opus 4.8 combines patterns from its training data with Retrieval-Augmented Generation (RAG) in certain configurations. This means your brand’s presence in high-authority third-party sources — both historical and recent — influences whether it gets cited. Real-time indexing isn’t how the model works, which is why consistent presence across trusted domains matters more than any single piece of recent content.

    Q: Can you directly optimize for Claude Opus 4.8 specifically?

    A: There’s no Claude-specific SEO playbook the way there’s a Google-specific one. What you can do is optimize for the behaviors Claude’s reasoning rewards: authoritative third-party coverage, structured and parseable content, and consistent brand messaging across diverse platforms. These signals tend to improve visibility across multiple AI engines, not just Claude.

    Q: How often should I check my brand’s Claude Opus 4.8 visibility?

    A: Spot-checking once a month won’t catch the drift. AI model behavior shifts with updates, and prompt volumes in your category fluctuate. A systematic approach — automated monitoring across a defined prompt matrix with weekly or bi-weekly reporting — gives you the trend data needed to act before a visibility drop becomes entrenched.

    Q: What’s the most common reason brands disappear from Claude’s answers?

    A: Researchers call it LLM citation decay. A brand can hold steady Google rankings while gradually losing AI citations because its coverage across diverse, high-authority domains hasn’t grown. Claude Opus 4.8’s improved reasoning makes it more selective, so brands that relied on thin presence in earlier models often see sharper drops. Source Analysis tools help pinpoint exactly which citation gaps to close first.

    Read More

  • Claude Opus 4.8 Just Changed AI Search. Are You Ready?

    Claude Opus 4.8 Just Changed AI Search. Are You Ready?

    Your SEO team ran its weekly audit. Rankings look fine. Traffic is stable. But somewhere in the last 72 hours, Claude stopped recommending your brand.

    You won’t see that in Google Search Console. You won’t find it in your rank tracker. And by the time a competitor notices the gap and fills it, you’re already behind.

    That’s the core problem with model updates. They’re invisible to traditional monitoring. And Claude Opus 4.8, released on May 28, 2026, is one of the most consequential updates for brand visibility that AI search has seen.

    Claude Opus 4.8: What Actually Changed This Time

    Not every model update matters for brand visibility. Most are incremental. Opus 4.8 is different.

    The model introduced two structural changes that directly affect how brands get recommended. First, Opus 4.8 significantly increased its “honesty filter”: when the model isn’t confident a brand claim is supported by independent, authoritative sources, it’s now more likely to omit the brand entirely rather than risk citing something unverified. Second, it introduced tunable “effort settings,” where high-effort responses pull from a wider, more authoritative cross-section of training data.

    That second point matters more than it sounds.

    Why Effort Settings Shift the Recommendation Landscape

    When a user runs a high-effort query, Opus 4.8 doesn’t just answer faster. It synthesizes deeper. It draws on a broader range of sources to determine which brands have genuine, cross-referenced credibility versus which ones are simply present online.

    Brands that have invested heavily in their own website content but neglected third-party coverage are now disproportionately at risk. Visibility in Opus 4.8 isn’t about how often you appear. It’s about how consistently you appear across independent sources the model treats as authoritative.

    The Three Signals Claude Opus 4.8 Uses to Rank Brands

    The research is clear on what Opus 4.8 actually weights when deciding which brands to recommend.

    Mention momentum and diversity. Statistical association is the underlying mechanism: the more frequently a brand appears alongside a specific problem category across independent third-party domains (industry blogs, review platforms, analyst reports), the stronger the weight the model assigns to that entity. A brand mentioned 200 times on its own site doesn’t compete with a brand mentioned 50 times across TechCrunch, G2, Capterra, and a handful of respected analyst reports.

    Structural clarity of content. Opus 4.8 prioritizes “extraction-friendly” information: schema markup, FAQ sections with clearly defined answers, benefit lists, technical documentation. Long-form narrative content without structural hierarchy is harder for the model to ingest as definitive knowledge. If your content answers the right questions but in the wrong format, the model may simply pass over it.

    Source authority. A single mention in a top-tier industry report can outweigh dozens of mentions in low-quality directories. The model weights citations from recognized aggregators and professional publications as “validation anchors.” These signals tell Opus 4.8 that your brand has been independently evaluated, not just self-described.

    Why Traditional SEO Tools Won’t Catch This

    Here’s the disconnect most marketing teams are missing: AI models like Claude Opus 4.8 don’t crawl the web to rank websites. They retrieve “reputation patterns” embedded during training and refined through Retrieval-Augmented Generation (RAG). Your domain authority means nothing to the model’s recommendation logic.

    This creates a measurement gap that traditional SEO tools simply can’t bridge.

    DimensionTraditional SEOGEO (AI Visibility)
    ObjectiveDriving clicksEarning citations
    Visibility unitOrganic positionEntity association strength
    Ranking logicBacklinks, keywordsStatistical “ground truth” probability
    PlatformGoogleClaude, ChatGPT, Perplexity

    The practical consequence: a brand can rank #1 in Google for its target keyword and be completely absent from Claude Opus 4.8 recommendations for the same category. These are separate ecosystems with separate rules.

    That gap is only going to widen as users increasingly rely on AI to answer product and vendor questions rather than conducting traditional searches.

    What a Brand “Disappearing” From Claude Looks Like in Practice

    Most brand teams don’t notice AI visibility loss immediately. There’s no alert, no ranking drop notification, no red flag in the dashboard. The decay is gradual and only becomes visible in downstream metrics: lower referral intent from AI sources, fewer inbound inquiries referencing AI-recommended discovery, competitors suddenly showing up in sales conversations as “what the AI suggested.”

    By the time a brand realizes it’s been de-emphasized in Claude Opus 4.8 recommendations, weeks of competitive positioning may already have been lost.

    The core issue is that brand visibility in AI is probabilistic, not binary. The model doesn’t “remove” you. It just assigns your entity a lower probability weight for a given category. That shift can happen quietly after a model update, and without dedicated monitoring, you won’t know until the downstream effects surface.

    This is not an SEO problem. It’s an AI visibility problem, and the tools to solve it are different.

    How to Track Your Brand’s Position in Claude Opus 4.8

    There are two approaches to monitoring AI visibility after a model update: active prompt testing and passive cross-platform monitoring.

    Active prompt testing means running a structured set of category queries across AI platforms (e.g., “What’s the best tool for [your category]?”, “Which brands do you recommend for [use case]?”) and logging whether your brand appears, in what position, and with what sentiment framing. This gives you a point-in-time snapshot.

    Passive monitoring means having a system that continuously runs these queries, tracks position shifts over time, and alerts you when your brand’s mention rate or recommendation rank changes significantly.

    Topify is built specifically for the second approach. Its AI visibility monitoring tracks brands across ChatGPT, Perplexity, Gemini, and other major platforms, measuring seven core metrics: Visibility Score, Sentiment Score, Position Rank, AI Volume, Mention Count, Intent alignment, and CVR (Conversion Visibility Rate). When Opus 4.8 rolled out, teams running Topify could see in real time whether their brand’s position shifted relative to competitors, without waiting for downstream sales signals.

    Build a Visibility Baseline Before the Next Model Update

    The single most important thing a brand can do right now is establish a baseline: how often does the brand currently appear for its top category queries across major AI platforms, in what position, and with what sentiment framing?

    Without that baseline, you can’t measure the impact of the next model update. And there will be a next one. Opus 4.9 and eventual Opus 5.0 are coming, and each iteration will recalibrate the recommendation weights that determine which brands get cited.

    The brands that invested in baseline tracking before Opus 4.8 dropped could quantify the impact and respond within days. The ones without monitoring are still figuring out what changed.

    What High-Visibility Brands Do Differently After a Model Upgrade

    The brands that maintain strong AI visibility across model updates share a common pattern. They don’t optimize for any single model. They optimize for the underlying signals that every model version tends to reward.

    Entity consistency. Brand name, product features, and core use cases are described consistently across all digital touchpoints: website, social profiles, third-party listings, review platforms. Semantic inconsistency (describing the same feature in five different ways across five platforms) is a primary driver of “brand blur” in models with stronger reasoning like Opus 4.8.

    Citation-worthy content. The content that earns model citations is structurally different from content that earns Google rankings. Think original benchmark data, case studies with quantifiable outcomes, and technical documentation that other industry players naturally reference. That kind of content builds the cross-domain mention momentum that Opus 4.8 uses as an authority signal.

    Source diversification. Brands that appear only on their own properties and in a narrow band of low-tier directories are disproportionately vulnerable to model updates. Teams that systematically earn mentions in recognized publications, analyst reports, and high-authority review platforms build the kind of distributed credibility that holds across model iterations.

    Topify’s Source Analysis feature lets teams see exactly which domains and URLs Claude and other AI platforms are citing when recommending brands in their category. That tells you where the authority signals are actually coming from, and where your content distribution strategy has gaps.

    Conclusion

    Claude Opus 4.8 didn’t just make AI smarter. It made AI more selective. Models that flag uncertainty, weight authority, and synthesize across a wider cross-section of sources are fundamentally raising the floor for brand inclusion in AI-generated answers.

    The brands that treat AI visibility as a structured, measurable discipline, not an afterthought to traditional SEO, will widen their lead over the next several model updates. The ones that don’t will keep finding out about changes after the fact, when the competitive ground has already shifted.

    A dedicated GEO monitoring platform that tracks brand performance across AI engines at the prompt level isn’t a future investment. After Opus 4.8, it’s a baseline requirement.


    FAQ

    Does Claude Opus 4.8 change how brands appear in ChatGPT or Perplexity?

    Not directly. Claude Opus 4.8 is Anthropic’s model and affects visibility specifically within Claude-powered surfaces. That said, the underlying recommendation logic shifts (weighting source authority, entity consistency, structural clarity) reflect trends across major AI models. A GEO strategy that improves your brand’s authority signals will generally benefit visibility across Claude, ChatGPT, and Perplexity simultaneously.

    How often should I audit my brand’s AI visibility?

    Weekly monitoring is a practical minimum for most brands. After a major model update like Opus 4.8, a dedicated audit within the first 48-72 hours gives you the clearest view of what changed. Platforms like Topify run these queries continuously, so you’re not dependent on manual audit cycles.

    What’s the difference between SEO rank and AI visibility rank?

    SEO rank measures your page’s position in a search engine results page for a given keyword. AI visibility rank measures how often your brand appears in AI-generated answers for category queries, in what position relative to competitors, and with what sentiment framing. A brand can rank #1 in Google and have near-zero AI visibility, and vice versa. The signals that drive each are largely separate.

    How does Opus 4.8’s honesty filter affect brand recommendations?

    The model is now more likely to omit brands entirely rather than cite them with low confidence. If your brand’s digital presence is inconsistent or lacks cross-referenced authority backing, the filter treats that ambiguity as a reason for exclusion. Structural clarity and third-party credibility signals are the most direct countermeasures.


    Read More

  • Why Your Brand Is Missing from Claude Opus 4.8

    Why Your Brand Is Missing from Claude Opus 4.8

    Your content team has been publishing consistently. Your SEO authority is solid. Then a potential buyer opens Claude, types “best tool for [your category],” and gets a confident, well-structured answer — featuring three of your competitors and zero mention of you.

    That’s not a fluke. It’s a structural problem, and it predates your last content sprint by months.

    Claude Opus 4.8 Isn’t Just a Better Chatbot

    Most coverage of Claude Opus 4.8 focuses on benchmark scores and reasoning improvements. Those upgrades matter, but not in the way most marketers think.

    What changed isn’t just capability. It’s selectivity. Opus 4.8 introduced enhanced multi-step reasoning, scoring significantly higher on GPQA Diamond and agentic benchmarks than its predecessors. That sounds like a good thing until you realize it means the model is now a stricter filter on what it considers worth including in an answer.

    On “High Effort” settings — which more sophisticated users are increasingly applying — Opus 4.8 spends additional compute to synthesize a definitive, authoritative response. That environment heavily favors brands with deep, structured, verifiable documentation over those with polished marketing copy.

    If your brand’s digital presence is mostly promotional, Opus 4.8 is less likely to trust it.

    The Gap Between SEO Visibility and Claude Opus 4.8 Visibility

    Here’s the core problem: Google and Claude don’t read the web the same way.

    Google rewards pages that match keyword intent, earn backlinks, and load fast. Claude builds answers by synthesizing statistical associations from its training data and grounding those answers against live sources it considers authoritative. Your Google rank doesn’t transfer.

    AI search visibility differs from traditional SEO in a specific, measurable way: what matters isn’t whether a page ranks, but whether the content on that page is the kind that AI systems cite and encode. A brand can dominate page one and remain completely invisible in Claude’s outputs.

    This isn’t a gap most teams are set up to see. Their analytics track clicks, rankings, and traffic. None of those metrics capture what Claude is saying about them.

    Why Claude Opus 4.8 Skips Your Brand Specifically

    Three structural factors typically explain brand invisibility in AI answers.

    Low citation authority on AI-trusted domains. Claude’s underlying corpus weights specific types of sources more heavily than generic web content: analyst reports, practitioner forums, G2-style review platforms, trade publications, and technical documentation. If your brand lacks a presence on these nodes, it fails an implicit authority check, regardless of your domain rating.

    Semantic ambiguity in how your brand is defined. Claude identifies brands as entities. If your homepage describes you as a “CRM platform,” your press releases call you an “automation tool,” and your blog categories suggest you’re an “analytics solution,” the model can’t cleanly map your brand to a specific problem or outcome. Inconsistent self-description gets resolved as exclusion. The model prefers to omit rather than hallucinate.

    Lack of AI-readable structure. According to research on how LLMs choose which brands to recommend, models process information best when it’s structured in extraction-friendly formats: tables, clearly bounded FAQ sections, schema-marked entity definitions. Narrative-heavy content that works well for human readers is harder for the model to parse and trust under reasoning pressure.

    These three factors compound. A brand with inconsistent positioning, no third-party citations on authoritative domains, and unstructured content is effectively invisible to Claude Opus 4.8, even if it publishes excellent material daily.

    What Claude Actually Uses to Build Its Answers

    Understanding the mechanism matters more than chasing workarounds.

    Claude Opus 4.8 draws on two knowledge sources simultaneously. The first is internalized training data: massive historical snapshots of the public web that have been compressed into statistical associations within the model’s weights. If your brand was consistently mentioned alongside a specific problem or outcome across diverse, credible sources, that association is now encoded in the model. If it wasn’t, the baseline is zero.

    The second source is Retrieval-Augmented Generation (RAG): live grounding that retrieves current content at query time. When a user asks Claude about a category, the model may pull fresh content from domains it treats as high-authority. Whether your domain makes that shortlist depends on the same citation-authority logic above.

    The practical implication: AI citation tracking isn’t just about knowing if your brand appears. It’s about understanding which sources Claude is citing instead of you, and why those sources rank higher in the model’s internal trust hierarchy.

    That’s information most brands don’t have.

    You Can’t Fix What You Can’t See

    Brand managers often discover the Claude Opus 4.8 problem the wrong way: a sales rep gets asked about an AI recommendation that didn’t include them, or a prospect mentions they heard about a competitor “from AI research.” By that point, the visibility gap has been open for months.

    The reason it goes undetected is simple. Standard analytics don’t capture AI answer data. Traffic reports, keyword rankings, and backlink audits measure what happened on your website. They don’t measure what Claude says when your product category comes up.

    This is where Topify directly addresses the measurement gap. It tracks brand visibility across ChatGPT, Perplexity, Google AI Overviews, and other major AI platforms at the prompt level — returning seven key metrics: Visibility Score, Sentiment, Position Rank, Volume, Mentions, Intent, and CVR (Conversion Visibility Rate).

    What makes this actionable is the Source Analysis layer. Topify’s platform identifies exactly which domains AI systems are citing when they answer prompts in your category. If Claude is consistently pulling from three competitor-adjacent publications and ignoring your domain, you can see that pattern in the dashboard and respond with a targeted content or PR strategy.

    For brands currently invisible in Claude Opus 4.8, the starting point is always the same: run a prompt audit across your target category queries to establish a baseline. You need to know your current Position Rank relative to competitors before you can measure whether any change you make is working.

    Three Moves That Actually Get Brands Into Claude Opus 4.8’s Answers

    These aren’t shortcuts. They’re structural changes that alter how Claude encodes your brand.

    Audit which prompts trigger your category. High-intent prompts in your vertical are generating answers right now, and you need to know where you stand in each of them. Tools like Topify’s prompt discovery feature surface high-volume AI prompts critical to your brand, including queries you might not be monitoring. This is the foundation for everything else.

    Build content that AI platforms cite. The research on GEO tactics for Claude visibility points to a consistent pattern: original data, practitioner-authored content, and structured documentation earn third-party citations more reliably than SEO-optimized blog posts. A single original study cited by four industry publications is worth more to your AI visibility than forty keyword-targeted articles. Also consider your llms.txt file configuration, an emerging standard that helps Claude identify which sections of your site are most authoritative and AI-relevant.

    Implement entity grounding across your site. Use structured data markup (Organization, Product, and Person schema) to give the model an unambiguous digital identifier for your brand. This directly addresses the semantic ambiguity problem. When Claude encounters consistent, schema-marked entity definitions, it can map your brand to a specific category with confidence, rather than excluding you to avoid a hallucination risk.

    Claude Opus 4.8 Will Keep Updating. So Will the Rankings.

    The competitive calculus here is different from traditional SEO because AI models aren’t static.

    As Anthropic releases updates and Opus 4.8 continues to evolve, the model will re-process its internal associations and recalibrate which brands it trusts. What gets your brand into Claude’s answers this quarter is not a permanent solution. Brands that treat AI visibility as a one-time optimization project will lose ground every time the model updates.

    What actually works long-term is what the research on AI visibility continuity describes: systematic presence across diverse, high-trust digital channels, maintained continuously. Not single-platform dominance. Not a quarterly content sprint. A structured process for monitoring where you stand, identifying which sources Claude is prioritizing, and updating your strategy accordingly.

    The brands that will consistently appear in Claude Opus 4.8’s answers are the ones tracking it as a live channel, not treating it as a fixed result.

    Conclusion

    The core issue isn’t that Claude Opus 4.8 is unfair to your brand. It’s that the model is working exactly as designed — synthesizing answers from the most coherent, credible, citation-supported signals available. If your brand isn’t generating those signals, the model’s silence is accurate feedback, not an error.

    The fix starts with visibility into where you actually stand. Audit your AI answer presence, identify which sources Claude is citing in your category, and build a content strategy that earns authority on those specific nodes. Get started with Topifyto run a prompt audit across your target queries and get a baseline before the next model update shifts the rankings again.

    FAQ

    Q: Does Claude Opus 4.8 use real-time web search to generate answers?

    A: It depends on the user’s setup. Claude Opus 4.8 can operate in two modes: relying on internalized training data, or performing live RAG grounding against current web sources. Enterprise users and API deployments often enable real-time retrieval. In both cases, the authority of the sources being cited matters more than recency alone.

    Q: How is AI visibility different from SEO rankings?

    A: SEO rankings measure where a page appears in a results list. AI visibility measures whether a model includes your brand in a synthesized answer. A page can rank highly in Google and be completely absent from Claude’s outputs — because the two systems prioritize different signals. SEO rewards keyword relevance and backlink authority. Claude rewards citation authority on AI-trusted domain types, entity clarity, and structured content.

    Q: How do I check if my brand appears in Claude Opus 4.8’s answers?

    A: The manual approach is to run a series of prompts in your product category directly in Claude and record the results. The systematic approach is to use an AI visibility monitoring platform like Topify, which tracks brand mentions, Position Rank, and Source data across multiple AI platforms automatically, so you’re not relying on manual spot checks.

    Q: Can I optimize for Claude specifically, or do I need a general AI strategy?

    A: The underlying factors that drive visibility in Claude — citation authority, entity coherence, structured documentation — are largely the same factors that drive visibility across ChatGPT, Perplexity, and Gemini. A platform-specific tactic (like llms.txt configuration) can help with Claude directly, but most high-impact GEO work improves your standing across AI platforms simultaneously. Start with a cross-platform audit to identify where your gaps are largest before prioritizing.

    Read More

  • Why Claude Opus 4.8 Picks Some Brands Over Others

    Why Claude Opus 4.8 Picks Some Brands Over Others

    Your domain authority is solid. Your keyword rankings are where they should be. But none of that tells you whether Claude Opus 4.8 is recommending your competitor when a user asks, “What’s the best tool for [your category]?”

    That’s the gap most brands haven’t measured. And with Claude Opus 4.8 now handling a growing share of AI-assisted decisions, the cost of being invisible to it is no longer hypothetical.

    Claude Opus 4.8 Isn’t a Search Engine. It’s a Referee.

    Most marketers assume Google rankings translate directly to AI search visibility. They don’t.

    Search engines index, rank, and surface links. Claude Opus 4.8 does something fundamentally different: it synthesizes patterns from its training data and reconstructs what it “knows” about your brand from memory. There’s no real-time crawl, no live index, no backlink graph to climb.

    According to Anthropic’s Claude Opus 4.8 technical system card, the model was built with a strong emphasis on honesty and agentic reasoning. That means it’s designed to be more selective—and more skeptical—about which sources and brands it cites. If your brand doesn’t have a strong enough footprint in the data it was trained on, it’s not downranked. It’s simply absent.

    That’s a meaningful distinction. An absent brand gets no second chance from a better meta description.

    The 4 Signals Claude Opus 4.8 Uses to Decide on a Brand

    Research into how Claude AI chooses brands points to four core signals that shape which names the model surfaces and how confidently it cites them.

    Source Authority: The Anchor Signal

    Claude Opus 4.8 shows a strong preference for brands that appear in authoritative, editorial sources—industry journals, established tech publications, credible documentation sites.

    These aren’t just “high-DA” domains in the SEO sense. They’re sources that humans have historically trusted to provide accurate information, which means the model treats them as grounding anchors when forming its understanding of a category.

    A brand mentioned once in a roundup post on a niche blog carries far less weight than a brand cited in a Gartner analysis, a Product Hunt discussion thread with hundreds of upvotes, or a well-referenced Wikipedia entry.

    Mention Density: Statistical Weight Across the Web

    Frequency acts as a proxy for relevance. If your brand appears across hundreds of independent, contextually relevant sources—Reddit threads, G2 reviews, Medium posts, industry newsletters, niche community forums—the model registers a statistical consensus.

    Research on training data frequency and brand citation patterns confirms that mention density across diverse platforms is one of the most consistent predictors of LLM recall. It’s not about one high-profile placement. It’s about breadth.

    Sentiment Consistency: Narrative Stability

    Claude Opus 4.8 is specifically tuned for what Anthropic calls “honesty calibration.” According to analysis of Opus 4.8’s agentic capabilities, the model reports a 4x reduction in unsupported claims compared to prior versions.

    In practice, that means the model is more likely to avoid citing brands that have contradictory descriptions across different sources. If your product is described as “enterprise-grade” on your site but “a budget alternative” in third-party reviews, the model may hedge—or skip your brand entirely to avoid making an unsupported claim.

    Consistent messaging across all digital touchpoints isn’t just a brand strategy concern. It’s now an AI visibility concern.

    Category Dominance: Semantic Association

    The model must be able to map your brand clearly to a category and a problem. Not vaguely—specifically.

    Think: “Brand X is a leading CRM for mid-sized teams” or “Brand Y is the go-to platform for AI search visibility tracking.” That kind of explicit category-to-brand association, repeated across multiple credible sources, is how Claude builds the semantic connection needed to recommend you by name when a user asks a category-level question.

    Generic positioning kills this. If your brand is described differently depending on the channel, the model can’t establish a clean association.

    Why Your Brand Might Be Invisible to Claude Right Now

    Three patterns account for most of the brand invisibility cases in Claude Opus 4.8.

    First: missing high-authority citations. If your brand is primarily mentioned in self-published content or low-signal platforms, the model doesn’t have enough grounding material to cite you with confidence.

    Second: brand name ambiguity. If your product name is also a common word or shares a name with another product, the model may consistently resolve the ambiguity toward the more established entity.

    Third: fragmented content presence. A brand that publishes strong content but only on its own domain hasn’t built the cross-source footprint that LLMs use to establish credibility.

    Claude doesn’t rank you. It remembers you.

    And if it can’t remember you clearly, it won’t cite you at all.

    What Changed in Claude Opus 4.8 That Brands Need to Know

    The upgrade from earlier Claude versions to Opus 4.8 isn’t just a capability improvement. It changes how the model evaluates the quality of information it synthesizes.

    Anthropic’s release notes for Opus 4.8 introduced effort-control settings that let users configure how deeply the model reasons through a query. On default “High Effort” settings, the model is designed to think more carefully rather than pattern-match to shallow content.

    The practical effect: keyword-stuffed content and generic marketing copy are increasingly filtered out by the model’s reasoning process. Content that provides specific, verifiable, actionable information gets prioritized. Content that makes unsupported claims gets deprioritized or ignored.

    That’s a meaningful shift. What worked as SEO content in 2023 may now actively hurt your chances of being cited by Claude Opus 4.8—not because the content is penalized, but because it doesn’t meet the model’s threshold for credibility.

    Brands that have invested in technical documentation, documented case studies, and third-party validation are better positioned in this environment than brands relying on volume-based content strategies.

    The Brands Claude Opus 4.8 Tends to Recommend

    The brands that appear most consistently in Claude Opus 4.8’s recommendations aren’t always the largest or most heavily funded. They share a different profile.

    According to research on the psychology of brand mentions and training data signals, the common thread is what researchers call “Semantic Certainty”: the model has encountered the brand often enough, across credible enough sources, with consistent enough messaging, that it can cite the brand without risking an unsupported claim.

    In practical terms, that means:

    • Cited in at least a handful of authoritative sources (not just self-published)
    • Mentioned across multiple independent platforms with similar descriptions
    • Clearly associated with a specific problem or category in the model’s training data
    • Described in a way that holds up under the model’s honesty calibration

    The bar isn’t impossible. But it requires a systematic approach, not a one-off PR push.

    How to Track Whether Claude Opus 4.8 Is Recommending Your Brand

    Here’s the problem: Claude doesn’t provide a rank tracker. There’s no search console equivalent for LLM visibility. You can’t log into a dashboard and see “Your brand appeared in 34% of relevant Claude queries this month.”

    That gap is exactly where Topify operates. Topify’s AI search visibility platform tracks how brands appear across major AI engines—ChatGPT, Gemini, Perplexity, Claude, and others—at the prompt level.

    The key metrics Topify surfaces for teams trying to understand their Claude visibility:

    Visibility Score: How often your brand appears in response to category-level prompts, across tracked AI platforms. A drop in this score often signals a change in how training data or citation patterns are shifting.

    Share of Model: Your brand’s relative presence compared to competitors across the same set of prompts. This is the AI equivalent of share of voice—and it’s the metric that tells you whether Claude is recommending you or your competitor.

    Source Analysis: Which domains Claude and other AI engines are pulling from when they cite brands in your category. If a specific forum or third-party review site consistently appears as a citation source for your competitors, that’s your next content target.

    Position Rank: Where your brand appears in AI-generated recommendation lists. Being mentioned is different from being mentioned first.

    Because each AI model is trained on a different corpus, cross-platform monitoring matters. A brand can have strong visibility in ChatGPT and near-zero presence in Claude Opus 4.8 if the training sets diverge. Topify’s AI search visibility tracking covers this cross-platform gap in a single view.

    Three Things You Can Change This Week

    Most brands can’t rewrite their entire content strategy overnight. But there are three moves that have an outsized effect on LLM brand visibility, and none of them require a full GEO overhaul.

    Audit your citation sources. Use Topify’s Source Analysis to identify which domains AI engines are pulling from in your category. Then cross-reference your brand’s presence on those exact platforms. If you’re not there, that’s your gap. Getting a mention on a site the model treats as authoritative is worth far more than ten mentions on low-signal platforms.

    Standardize your brand description. Pull your brand’s descriptions from your own site, G2, Capterra, Reddit, and any major review or community platform. Look for contradictions in how your product is positioned. Resolve them. Consistency across sources is a direct input into the model’s confidence when citing you.

    Build a presence on independent platforms. Owned content matters, but the model’s sense of your brand comes from sources it treats as independent. Reddit threads where users recommend your product, thoughtful answers on Quora, community mentions in niche Slack groups or newsletters—these build the “mention density” signal in a way that your own blog cannot.

    Get started with Topify to run a baseline visibility check across AI platforms before you make changes. You can’t optimize what you haven’t measured.

    Conclusion

    Claude Opus 4.8’s brand recommendation logic isn’t opaque—it follows a consistent pattern of source authority, mention density, sentiment consistency, and category association. What’s changed with the Opus 4.8 release is that the model’s honesty calibration now makes it more demanding. Generic content and thin citation footprints get filtered out. Brands with documented credibility across independent sources get surfaced.

    The monitoring infrastructure to track this didn’t exist a few years ago. It does now. The teams that build a baseline understanding of their Claude visibility in 2026 will have a significant head start on the ones still measuring success purely through Google Search Console in 2027.


    FAQ

    Q: Does Claude Opus 4.8 update its brand knowledge in real time?

    A: No. Claude Opus 4.8 generates responses based on patterns from its training data, which has a fixed cutoff date. It doesn’t crawl the web or update citations in real time. This means brand visibility in Claude is a function of what was present in training data—and why monitoring your current presence across AI platforms requires dedicated tooling, not a one-time check.

    Q: Can I “optimize” my brand for Claude the way I optimize for Google?

    A: Not in the same way. There’s no equivalent of on-page SEO for LLMs. What you can influence is the footprint your brand has across sources the model weights as credible: authoritative publications, independent review platforms, community discussions, and technical documentation. That’s the GEO equivalent of link building—it takes time, but it compounds.

    Q: How is Claude Opus 4.8 different from ChatGPT in recommending brands?

    A: The core mechanism is similar—both models synthesize brand knowledge from training data—but they’re trained on different corpora and have different calibration priorities. Claude Opus 4.8’s emphasis on honesty and reduced unsupported claims means it’s generally more conservative in its brand citations than GPT-based models. A brand that appears frequently in ChatGPT responses may have lower visibility in Claude if the underlying sources differ.

    Q: What’s the fastest signal I can improve to get picked by Claude?

    A: Sentiment consistency tends to have the highest leverage for most brands in the short term. Auditing and aligning how your brand is described across third-party platforms—especially high-authority review and community sites—removes a key reason Claude might avoid citing you. It doesn’t require new content creation, just cleanup and coordination across existing touchpoints.


    Read More