Author: Elsa Ji

  • AI Recommendation Tracking: Tools, Metrics, and What to Look for

    AI Recommendation Tracking: Tools, Metrics, and What to Look for

    Search “best project management software” on Perplexity right now. You’ll get a list of recommendations, a short explanation of each, and a confident tone that suggests the question is settled. Your brand may or may not appear. Either way, your GA4 dashboard won’t register a thing.

    That’s the core problem with AI recommendation tracking in 2026. The discovery is happening, the brand decisions are being made, but traditional analytics can’t see any of it. The tools that help you fix that are what this article covers.

    Why Your Analytics Stack Has a Blind Spot for AI Recommendations

    Traditional web analytics were built for a specific model: user searches, sees a link, clicks it, lands on your site. Every step leaves a data trail.

    AI search breaks that model at step two. When ChatGPT or Perplexity answers a query, users often don’t click anywhere. They read the answer and move on. The industry has started calling this “Zero-Click Visibility” because brand discovery happens inside the AI’s output, not on a results page.

    The consequence is a systematic blind spot. Your brand might be recommended 200 times a day across AI platforms, or it might not be mentioned at all, and your current analytics setup will report the same number either way: zero.

    There’s also a subtler risk. Researchers have identified a phenomenon called Prompt Drift, where model updates or shifts in training data quietly change how an AI describes or ranks your brand. A competitor gets a new round of press coverage, their domain authority climbs, and six weeks later ChatGPT starts listing them first in your category. Without an AI recommendation tracker, you won’t notice until the pipeline starts thinning.

    The Metrics That Actually Matter in AI Recommendation Tracking

    Before evaluating any AI recommendation tracking software, it helps to know what you’re measuring. The industry has started to converge on five core KPIs, though platforms differ significantly in how they define and calculate each one.

    Mention Rate is the percentage of relevant prompts where your brand is explicitly named. If you’re tracking 100 prompts about project management tools and your brand appears in 34 of the responses, your mention rate is 34%. Simple, but foundational.

    Citation Rate goes deeper: how often does the AI link to a specific URL on your domain as a source? Citation rate matters because it’s a signal that AI systems treat your content as authoritative, not just your brand name as a data point.

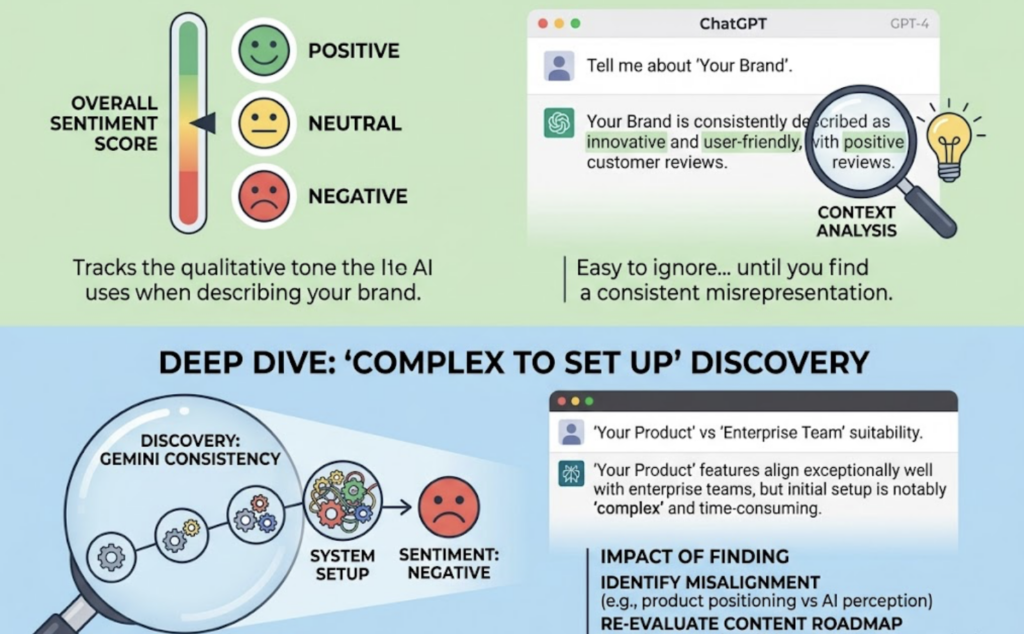
    Sentiment Score tracks the qualitative tone the AI uses when describing your brand. Positive, neutral, or negative. This one is easy to ignore until you discover that Gemini consistently describes your product as “complex to set up” or “better suited for enterprise teams.”
    Position tells you where your brand ranks within the AI’s recommendations. Being mentioned fifth out of five is very different from being mentioned first.

    CVR (Conversion Visibility Rate) is the newest metric on this list, and arguably the most commercially relevant. It estimates how likely an AI recommendation is to translate into actual user behavior, factoring in position, sentiment, and prompt intent. It’s the bridge between AI visibility data and revenue attribution.

    5 Things That Separate a Real AI Recommendation Tracker from a Basic Monitor

    Not all AI recommendation tracking tools are built the same. Here’s what to look for before committing to a platform.

    1. Cross-platform coverage that actually includes the platforms your audience uses. Some tools only track ChatGPT. Others add Perplexity. But if your audience skews toward Gemini, or toward regional models like DeepSeek, a tool with narrow coverage gives you an incomplete picture. Look for platforms that measure visibility across ChatGPT, Perplexity, Gemini, and ideally others.

    2. Prompt-level tracking, not brand-level tracking. Searching your brand name directly in ChatGPT tells you almost nothing. Real tracking means defining a prompt taxonomy, a structured set of user intent queries like “best CRM for remote sales teams” or “alternatives to Salesforce for startups,” and then monitoring how your brand performs across all of them. This approach captures how buyers actually search, not how your marketing team thinks they search.

    3. Competitor benchmarking built in. Knowing your own mention rate is useful. Knowing your mention rate is 28% while your closest competitor runs 61% is actionable. A solid AI recommendation tracking platform should automatically surface competitor data alongside your own, not require you to set up separate projects for each.

    4. Historical trends and delta alerts. Point-in-time snapshots are useful for baselines. What you really need is the ability to spot changes over time and get flagged when something shifts significantly. A drop in Citation Rate after a model update, or a sudden jump in a competitor’s Position, are the signals that drive strategy.

    5. Optimization guidance, not just data. The gap between a monitoring tool and a tracking platform is what happens after you see the numbers. Does the AI recommendation tracking system tell you which source domains the AI is currently citing in your category? Does it show you where your content coverage is thin compared to competitors? Data without a path to action is just a prettier dashboard.

    AI Recommendation Tracking Tools Compared

    Here’s how the main platforms stack up across the dimensions that matter most for practical use:

    ToolPlatform CoverageMetric DepthCompetitor MonitoringOptimization ExecutionStarting Price
    TopifyChatGPT, Perplexity, Gemini, DeepSeek, and more7 metrics incl. CVRYes, automatedYes, one-click agent$99/mo
    Keyword.comPerplexity-focusedBrand mentionsLimitedNoVaries
    ProfoundChatGPT, Perplexity, othersPrompt volumes, SOC2YesNoEnterprise
    RankscaleChatGPT, Perplexity, AI OverviewsHigh-accuracy pollingPartialNoVaries
    Ahrefs / SemrushAI-adjacent (mostly traditional)SEO + basic AI trendsTraditional onlyTraditional SEOFrom $99/mo

    A few things worth noting about this table. Keyword.com’s strength is depth on Perplexity specifically, which makes it a decent fit for brands whose audience skews heavily toward that platform. Profound targets enterprise security and compliance requirements, including SOC2 reporting, which matters for regulated industries. Rankscale handles high-volume prompt polling well for large-scale operations.

    Topify covers the widest range of AI platforms and is the only option on this list that combines tracking with one-click optimization execution. Rather than just showing you that your Citation Rate dropped, it surfaces which source domains are being cited in your category and lets you deploy a content strategy against those gaps directly from the dashboard. For teams that need to go from insight to action without adding headcount, that distinction matters.

    How to Start Tracking AI Recommendations in 3 Steps

    You don’t need a six-month setup to start getting useful data. Here’s a practical starting point.

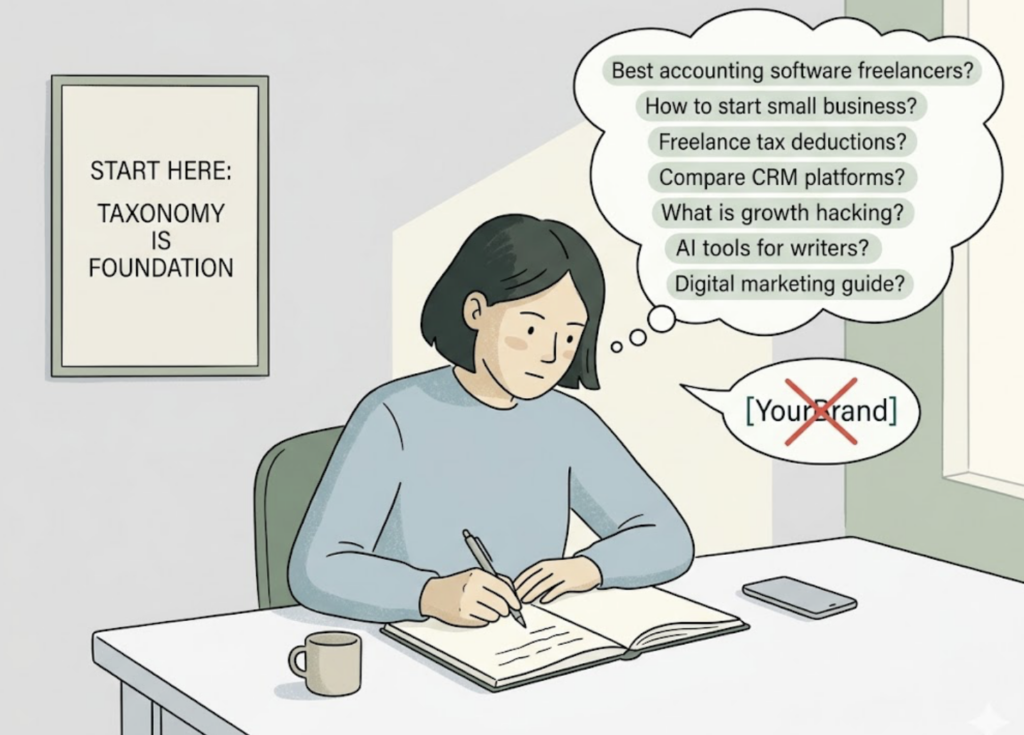
    Step 1: Define your prompt taxonomy before you touch any tool. Don’t start by tracking your brand name. Start by listing 20 to 30 user intent queries in your category, the kinds of questions your ideal customers are actually asking AI systems. “What’s the best accounting software for freelancers?” is a prompt. “[YourBrand]” is not. The taxonomy is the foundation everything else runs on.
    Step 2: Establish your baseline. Run your prompt set across ChatGPT, Perplexity, and Gemini and capture your current Mention Rate, Sentiment Score, and Position for each. This snapshot becomes the reference point for every future measurement. Without it, you can’t tell whether your optimization efforts are working.

    Step 3: Connect the data to your reporting workflow. AI recommendation tracking dashboards work best when the data flows into existing team processes, whether that’s a monthly marketing report, a quarterly C-Suite deck, or a weekly SEO standup. Visibility data that sits in a separate tool no one checks isn’t visibility data, it’s noise.

    For teams using Topify’s AI recommendation tracking solution, these three steps happen inside a single platform. The prompt taxonomy feeds the tracking engine, the baseline is captured automatically on day one, and the Source Analysisfeature shows which domains are being cited so you know exactly where to publish next.

    Conclusion

    The brands that win in AI search aren’t the ones with the highest domain authority. They’re the ones that know what AI is saying about them, why, and what to do about it.

    AI recommendation tracking closes the feedback loop that traditional analytics can’t. Start with a clear prompt taxonomy, establish a baseline across the platforms your audience actually uses, and pick an AI recommendation tracking tool that goes beyond monitoring to tell you what to fix. The data is there. The question is whether you’re set up to read it.

    Get started with Topify to see where your brand stands in AI recommendations today.

    FAQ

    Q: Is AI recommendation tracking the same as social listening?

    A: No. Social listening monitors what people say about your brand on platforms like X, Reddit, and LinkedIn. AI recommendation tracking monitors what AI systems say about your brand when users ask for product recommendations or category guidance. The two are complementary but measure completely different channels.

    Q: How often should I pull AI recommendation tracking reports?

    A: Weekly tracking is practical for most teams. That said, any major content push, PR announcement, or competitor product launch is worth a manual check, since AI citation patterns can shift within days of a significant publication event.

    Q: Can I track competitors’ AI recommendations too?

    A: Yes, and you should. Knowing your own Mention Rate in isolation is only half the picture. Competitor benchmarking shows you whether your category is dominated by one or two brands in AI responses, which tells you both where the opportunity is and how much ground you need to cover. Most AI recommendation tracking platforms support competitor monitoring as a core feature.

    Q: What’s the difference between AI recommendation tracking and traditional rank tracking?

    A: Traditional rank tracking shows your position on a Google SERP for a given keyword, a fixed list format with numbered positions. AI recommendation tracking measures presence, sentiment, source citation, and position within conversational AI outputs, across multiple platforms simultaneously. The underlying data structure and the actions you take based on it are fundamentally different.
    Read More

  • AI Recommendation Tracking Dashboard: Tools & Guide

    AI Recommendation Tracking Dashboard: Tools & Guide

    Your domain authority is solid. Your content calendar is full. Your SEO rankings haven’t moved in months, which usually means everything’s working.

    Then a prospect tells you they asked ChatGPT for a recommendation in your category and went with a competitor they’d never heard of before. You check. Your brand wasn’t mentioned once. And there’s nothing in GA4, Search Console, or your rank tracker that explains why.

    That’s the gap an AI recommendation tracking dashboard is built to close.

    What Your Analytics Stack Can’t See

    Google Analytics 4 tracks sessions. Search Console tracks clicks. Neither has visibility into what ChatGPT, Perplexity, or Gemini says when someone asks a buying question in your category.

    The core problem is structural. Traditional BI and SEO tools operate on a batch model, analyzing past structured data to explain what happened. AI recommendation tracking requires real-time, conversational analysis of unstructured, non-deterministic output.

    Three gaps stand out:

    Zero-click invisibility. AI search satisfies user intent directly in the chat interface. The traffic never hits your website, so your analytics never see it.

    Non-deterministic results. LLMs don’t return static SERPs. The same query can yield different brand mentions depending on model version, context, or recent training data. Weekly manual checks miss most of that variance.

    Source blindness. You can’t tell which of your content assets are building LLM trust or citation authority, so you can’t prioritize what to optimize.

    Tracking AI recommendations requires a purpose-built layer. That’s what an AI recommendation tracking dashboard delivers.

    What an AI Recommendation Tracking Dashboard Actually Tracks

    The term “dashboard” gets used loosely. A real AI recommendation tracking dashboard doesn’t just count brand mentions. It maps your brand’s position in the AI answer ecosystem across six dimensions:

    MetricWhat It Measures
    Visibility ScoreHow frequently your brand appears across a core set of buyer-intent prompts
    AI Share of Voice (SOV)Your mentions relative to competitor mentions across the same prompt set
    Sentiment ScoreWhether AI describes your brand positively, neutrally, or negatively
    Citation SourcesWhich URLs and domains LLMs use to validate their recommendations about your brand
    Mention PositionWhere your brand ranks within AI-generated lists (top 3 vs. buried in paragraph text)
    CVR (Conversion Visibility Rate)Estimated likelihood that AI-cited pages lead to downstream business outcomes

    Visibility Score tells you whether you exist in AI search. Share of Voice tells you whether you’re winning. Sentiment tells you whether being visible is actually helping your brand. Citation Sources tell you what to optimize.

    Without all six, you’re managing partial information.

    5 Signals Your Team Needs This Now

    You don’t always need a dashboard until something makes the absence obvious. These are the situations that tend to force the decision:

    A competitor appears in ChatGPT recommendations with no clear reason. They’re newer, smaller, and rank below you on Google. But AI keeps recommending them. Without citation source data, you can’t reverse-engineer why.

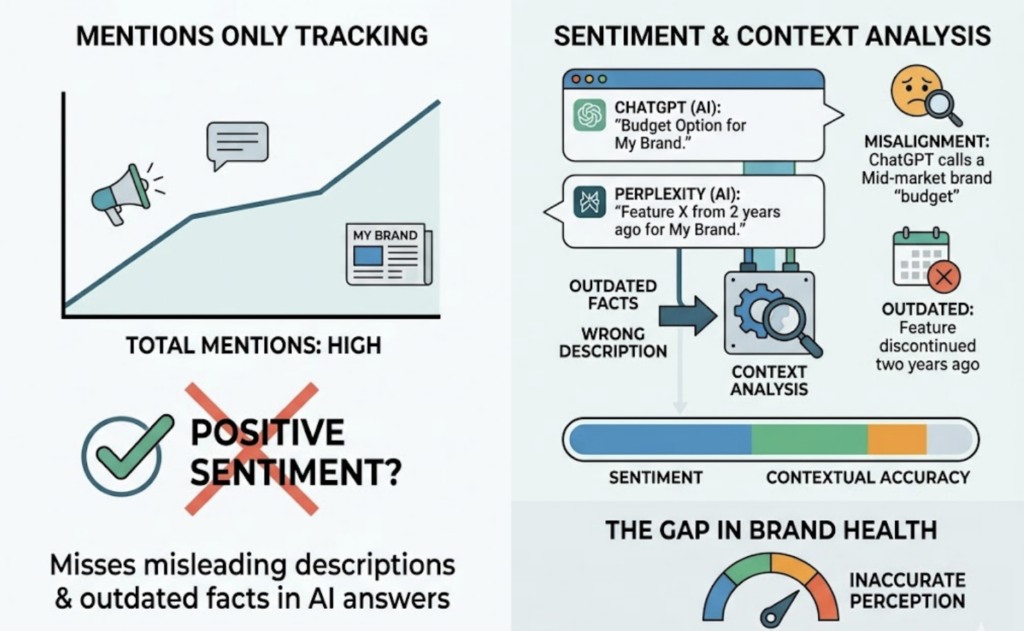
    Your brand shows up in AI answers, but the description is wrong. ChatGPT calls you a “budget option” when your positioning is mid-market. Perplexity describes a product feature you discontinued two years ago. Tracking only mentions without context doesn’t catch this. Sentiment analysis does.

    Traffic from AI platforms is unattributed in GA4. You’re seeing a new referral source you can’t identify, or direct traffic is climbing without an obvious cause. AI-referred traffic often lands as dark traffic.

    Your content team doesn’t know which assets build LLM authority. They’re producing articles without knowing whether any of them are cited by ChatGPT or Perplexity. Source analysis closes that gap.

    You’re reporting on AI search to leadership with no data. “We checked ChatGPT and our brand showed up” is not a reportable metric. A structured dashboard is.

    That last one is accelerating adoption. According to Semrush’s 2026 AI search visibility guide, marketing teams are under increasing pressure to report AI search performance alongside traditional SEO metrics.

    How to Measure What Actually Matters in AI Recommendations

    Not every metric in an AI recommendation tracking dashboard deserves equal weight. Some are useful for optimization. Others are useful for reporting. A few are mostly vanity.

    High-signal metrics (change your strategy):

    • Citation Sources: directly tells you what content to build or update
    • Sentiment Score: tells you whether your messaging is landing in AI training data
    • Mention Position: affects click intent; being mentioned fifth in a list is meaningfully different from being mentioned first

    Reporting metrics (useful for stakeholders):

    • Visibility Score and Share of Voice: trackable over time, comparable to competitors

    Context-dependent metrics:

    • CVR is valuable for BOFU teams but less relevant if your goal is top-of-funnel awareness

    One common mistake is tracking mentions without geo-context. A brand that appears in U.S. ChatGPT responses may be invisible in the UK or Australia. Localized citation patterns vary significantly, and global averages mask that variance.

    The practical benchmark: if a metric doesn’t tell you what to do next week, it’s probably not worth your weekly review time.

    Best Tools for AI Recommendation Tracking in 2025

    The market has split into two generations of tools. The first generation layered AI tracking onto existing SEO platforms. The second generation was built specifically for AI recommendation monitoring from the ground up.

    Here’s how the main options compare:

    ToolAI Platform CoverageCore StrengthBest For
    TopifyChatGPT, Gemini, Perplexity, DeepSeek, Doubao, Qwen + othersFull-spectrum GEO: visibility, sentiment, position, citation, CVR, competitor monitoring, one-click executionMarketing teams and agencies needing end-to-end AI visibility management
    OmniaChatGPT, Perplexity, AI OverviewsStrong action layer: converts citation data into content briefsContent teams focused on AI Overviews
    SE RankingPrimarily Google AI OverviewsIntegrates AI tracking into existing SEO workflowsSEO teams that want to add AI coverage without switching tools
    Semrush / AhrefsLimited AI-specific trackingStrong on traditional SEO, backlinks, on-pageTeams where traditional SEO is still the primary channel

    The difference between first- and second-generation tools becomes clear at the execution layer. Semrush and Ahrefs are excellent for on-page SEO and traditional backlinks but generally lack the generative AI-specific tracking required to measure LLM citations or prompt-level share.

    Topify sits closest to what the research calls an “action-layer” platform. It monitors brand performance across seven metrics simultaneously (visibility, sentiment, position, volume, mentions, intent, and CVR), covers more AI platforms than most alternatives, and connects monitoring to execution through its One-Click GEO Agent. For teams that need to do something with the data, not just look at it, that last part matters.

    Pricing starts at $99/month (Basic: 100 prompts, 9,000 AI answer analyses, 4 projects) and scales to $199/month (Pro: 250 prompts, 22,500 analyses) and enterprise plans from $499/month. There’s also a free GEO Score Checker available without signup.

    Build Your AI Tracking Workflow in 5 Steps

    A dashboard with no workflow attached is just a reporting tool. Here’s how to turn one into an active optimization system:

    Step 1: Build your prompt library. Aggregate high-intent buyer questions from sales call logs, support tickets, and your existing keyword research. Convert them into natural language prompts that mirror how your customers actually talk to AI. This is your monitoring foundation.

    Step 2: Set up competitor benchmarking. Catalog your brand alongside 3-5 direct competitors, including product variations and common aliases. You need this baseline before you can measure share of voice or position changes.

    Step 3: Deploy cross-platform monitoring. Run your prompt library across multiple LLMs simultaneously. Tracking only ChatGPT and ignoring Perplexity or Gemini misses the broader market reality. AI rankings fluctuate daily, so automated, consistent monitoring matters more than manual spot-checks.

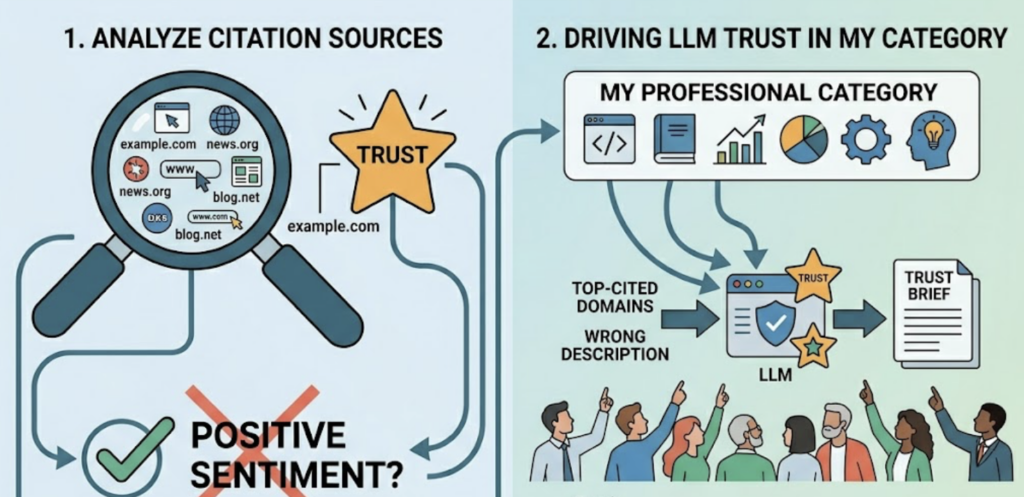
    Step 4: Analyze citation sources first. Before you look at visibility scores, check which domains and URLs are driving LLM trust in your category. This is your content optimization roadmap. Reverse-engineer what top-cited competitors are publishing, then build your own authority briefs.

    Step 5: Run a monthly prompt refresh. Buyer language evolves. Model training data updates. Your prompt library should reflect both. A static set of prompts gives you data, but not necessarily current data.

    That last step is what separates teams that get value from their dashboard from teams that have a dashboard they stopped checking.

    What Does an AI Visibility Dashboard Cost?

    Pricing in this market varies more than you’d expect, largely because the tools serve different scope requirements.

    Free tier: Several platforms offer limited free access. Topify’s GEO Score Checker requires no signup and gives you a starting benchmark. Useful for a first read, not for ongoing monitoring.

    Entry-level paid ($49-$99/month): Covers basic AI platform monitoring, limited prompt volume, and single-project tracking. Suitable for solo founders or small teams running one brand. Topify’s Basic plan at $99/month includes 100 prompts and 9,000 AI answer analyses across ChatGPT, Perplexity, and AI Overviews.

    Professional ($199-$499/month): Expanded prompt volume, multi-project support, competitor monitoring, and sentiment tracking. Topify’s Pro plan at $199/month handles 250 prompts and 22,500 analyses across 8 projects. See full pricing here.

    Enterprise ($499+/month): Custom prompt volumes, dedicated account management, and full-suite analytics. For larger agencies managing multiple client brands, Topify’s enterprise tier starts at $499/month.

    The pricing logic is straightforward. Cost scales with prompt volume and platform coverage, not with feature gates. You pay for how much monitoring you need, not for access to the metrics that matter.

    Conclusion

    The shift from “Google rankings” to “LLM authority” isn’t a future trend. It’s already shaping where high-intent buyers go after a ChatGPT conversation. Brands without an AI recommendation tracking dashboard are making decisions based on data that doesn’t include their most important discovery channel.

    The good news: the tooling has matured. You can build a functional tracking workflow in a week, with a structured prompt library, cross-platform monitoring, and citation source analysis. Start with a free GEO score check, map your current prompt coverage against competitors, and add systematic tracking from there. The brands building this infrastructure now will be the ones Get started with Topify showing up first when the next buyer asks.


    FAQ

    Q: What is an AI recommendation tracking dashboard? 

    A: It’s a monitoring tool that tracks how often, how positively, and in what position your brand appears in AI-generated responses across platforms like ChatGPT, Perplexity, and Gemini. Unlike traditional analytics tools, it captures brand presence in AI answers rather than website traffic.

    Q: How does an AI recommendation tracking dashboard work? 

    A: The system runs a library of buyer-intent prompts across multiple LLMs on a recurring basis, then analyzes the responses for brand mentions, sentiment, position, and citation sources. Over time, it builds a dataset that shows how your AI visibility changes relative to competitors.

    Q: What are examples of metrics tracked in an AI visibility dashboard? 

    A: Common metrics include Visibility Score (how often your brand appears), Share of Voice (your mentions vs. competitors’), Sentiment Score (positive/neutral/negative), Citation Sources (which domains AI trusts to validate your brand), Mention Position (rank within AI-generated lists), and CVR (Conversion Visibility Rate).

    Q: How much does an AI recommendation tracking dashboard cost? 

    A: Entry-level plans typically start around $49-$99/month for basic monitoring. Professional-tier tools with competitor tracking and multi-platform coverage run $199-$499/month. Enterprise pricing is custom. Some platforms, including Topify, offer a free GEO score check without requiring a subscription.


    Read More

  • AI Recommendation Tracking System: A Practical Guide

    AI Recommendation Tracking System: A Practical Guide

    Your brand ranks on Google. You’ve got dashboards, keyword reports, a healthy backlog of optimized content.

    But when someone asks ChatGPT “what’s the best [your category] tool,” you have no idea what it says. You’re not tracking it. You’re not even sure where to start.

    That’s the gap an AI recommendation tracking system is designed to close.

    What an AI Recommendation Tracking System Actually Does

    An AI recommendation tracking system (ARTS) is a framework for measuring how often, how positively, and in what context your brand appears inside LLM-generated answers across platforms like ChatGPT, Perplexity, Gemini, and others.

    It’s not keyword rank tracking. It’s entity-based attribution at the prompt level.

    The distinction matters. Traditional SEO tools track where your page appears in a list. An ARTS tracks whether your brand is named, recommended, or cited inside a generated answer, and what role it plays in that answer.

    The 5 Data Points Worth Tracking

    Most teams start by counting mentions. That’s not enough. A complete tracking system captures five signals:

    Direct Citation: How often your brand name appears in a generative response across your target prompt set.

    Sentiment Polarity: Whether AI positions you as a recommended solution, a neutral comparison, or a negative example. Being mentioned isn’t the same as being recommended.

    Source Attribution: Which of your URLs the model is citing as “evidence” when it mentions you. This tells you which content is actually driving your AI presence.

    Recommendation Category: Is the AI calling you “best for X,” an “alternative to Y,” or just including you in a generic list? The classification determines real commercial value.

    Prompt Coverage Consistency: Whether your brand appears across a range of semantically related queries, or only shows up on one narrow phrasing. Consistency is what converts visibility into a reliable channel.

    Why Your Current Analytics Can’t See Any of This

    Traditional tools like Google Analytics or Search Console are built on one assumption: users click through to your site.

    AI search breaks that assumption entirely. A user asks Perplexity a question, gets a fully formed answer, and never visits anyone’s website. There’s no click to track. No session to attribute. No conversion path to follow.

    The problem runs deeper than zero-click behavior, though.

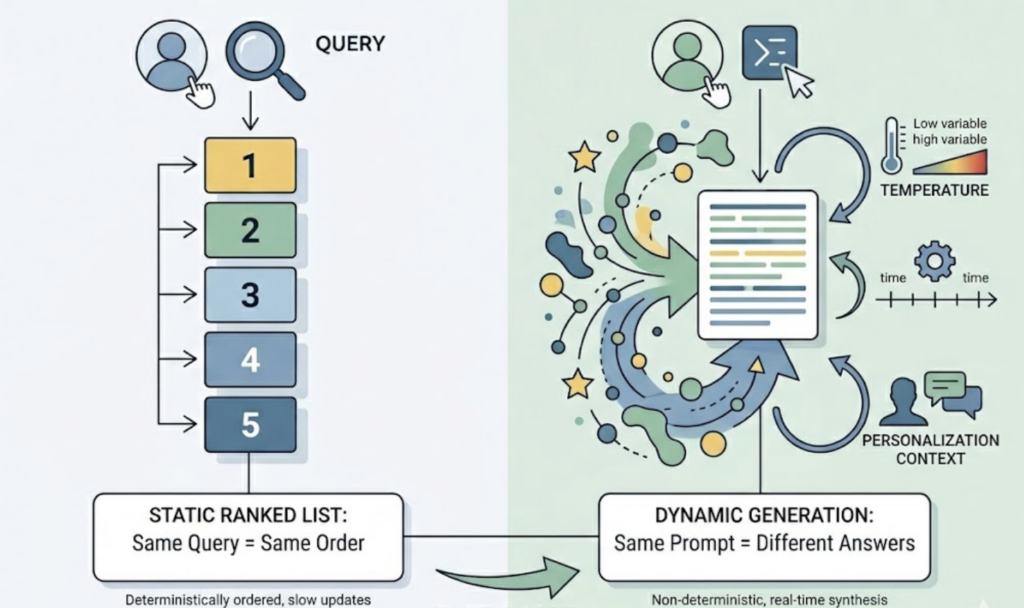
    Traditional SEO assumes static results. Type a query, get a ranked list. LLMs don’t work that way. The same prompt run twice can return different answers depending on model temperature, recent fine-tuning, or personalization context. Standard rank-tracking logic doesn’t apply to non-deterministic outputs.

    There’s also what researchers call the “black box” problem. Traditional tools can’t identify whether an LLM recommendation is driven by a direct citation in a RAG pipeline or by patterns baked into the model’s weights during training. Without that distinction, you can’t act on what you’re seeing.

    How the Tracking System Works, Step by Step

    A well-structured ARTS follows a three-stage cycle that runs continuously, not just once a quarter.

    Stage 1: Prompt Coverage

    The system executes a pre-defined set of high-intent queries against multiple LLMs simultaneously. Not just one model. A brand that only monitors ChatGPT is missing Perplexity users, Gemini users, and every AI assistant embedded in a browser or productivity tool.

    The query set should include head terms (“best CRM for small business”), long-tail variants (“what CRM do most startups use in 2026”), and comparison prompts (“alternatives to [competitor]”). Semantic coverage determines how accurate your visibility picture is.

    Stage 2: Answer Capture

    Raw responses are logged systematically: full answer text, any URLs cited, follow-up questions the model suggests, and the framing used around brand mentions. The goal is structured data, not screenshots.

    Stage 3: Brand Signal Extraction

    NLP or LLM-based classifiers parse each captured response to extract brand presence, sentiment score, citation source, and recommendation type. This is where raw tracking data becomes actionable insight.

    The full cycle runs continuously. AI rankings can shift daily based on model updates and changes in which content sources the model prioritizes.

    The Metrics That Actually Move Decisions

    Not all metrics are equally useful. Here’s how to prioritize:

    MetricWhat It MeasuresPriority
    AI Share of VoiceYour brand mentions vs. total competitor mentions in the tracked prompt setPrimary
    Citation DepthNumber of unique owned URLs the AI is citingPrimary
    Sentiment BiasPositivity/negativity of the context around your brandSecondary
    Query ReachHow many prompt variations result in a brand mentionSecondary

    One metric to deprioritize: click-through rate. It’s a reflex from traditional SEO thinking. In AI search, recommendation share is the signal that matters. Whether your brand is named and positioned favorably, not whether a click happened.

    Topify consolidates these metrics into a single visibility dashboard, tracking brand performance across ChatGPT, Gemini, Perplexity, and several other major AI platforms via seven core signals: visibility, sentiment, position, volume, mentions, intent, and CVR (Conversion Visibility Rate).

    5 Mistakes That Distort Your AI Tracking Data

    Most teams starting with AI recommendation tracking hit the same problems.

    Tracking only one model. ChatGPT is large, but it’s not the whole market. Different user segments use different AI tools. A brand that only monitors one platform is measuring a fragment of its actual AI footprint.

    Counting mentions without context. A brand mentioned as a “cautionary example” still counts as a mention. Without sentiment filtering, high mention volume can mask a fundamentally negative AI positioning.

    Ignoring source injection. If the AI is citing a competitor’s blog post as the “authoritative source” on your product category, that’s a content gap you need to fill. Tracking which URLs the model cites is as important as tracking brand names.

    Running static tests. A monthly manual check isn’t tracking. It’s a snapshot. AI models are fine-tuned continuously, and a content update from a competitor can shift your recommendation share within days.

    Prioritizing volume over quality. A mention buried in a low-intent, off-topic response is worth far less than a direct recommendation in a high-intent research prompt. Reach means nothing if the context doesn’t drive decisions.

    How to Choose the Right AI Recommendation Tracking Platform

    If you’re evaluating tools, these are the capabilities that separate functional platforms from ones that look good in a demo:

    Multi-model coverage. The platform should audit your brand across at least three to four major LLMs. Single-model tools give you partial data at full price.

    Automated prompt generation. Manually writing query sets at scale isn’t sustainable. Look for platforms that generate semantic permutations of your core terms automatically.

    Citation mapping. You need to see which specific URLs the AI is pulling from when it recommends or cites your brand. This is how you connect your content strategy to your AI visibility.

    Temporal tracking. Visibility trends over time, especially in response to content updates, are what let you prove ROI and iterate intelligently.

    Sentiment and position data. Knowing you’re mentioned isn’t enough. You need to know whether you’re being positioned as the first recommendation or the afterthought.

    Topify’s Source Analysis feature maps exactly which domains and URLs AI platforms cite when your brand or competitors come up. Its Competitor Monitoring module tracks position in real time across the full competitive set, so you know not just where you stand, but why.

    Pricing starts at $99/month for the Basic plan, covering 100 prompts and 9,000 AI answer analyses across ChatGPT, Perplexity, and AI Overviews. Enterprise plans start at $499/month with dedicated account management and custom configurations.

    For teams not ready to commit, Topify’s free GEO Score Checker provides an immediate read on your current AI visibility baseline without requiring signup.

    FAQ

    What is an AI recommendation tracking system? 

    It’s a framework for measuring how often and how favorably a brand appears in AI-generated answers across platforms like ChatGPT, Perplexity, and Gemini. It captures mentions, sentiment, source citations, and recommendation category across a defined set of prompts.

    How does an AI recommendation tracking system work? 

    It runs a defined set of queries against multiple LLMs continuously, captures full responses, and uses NLP classifiers to extract brand signals: presence, sentiment, position, and citation source.

    How do you measure an AI recommendation tracking system’s effectiveness? 

    The primary metrics are AI Share of Voice (your mentions vs. competitors) and Citation Depth (how many of your own URLs the AI is citing). Recommendation Share is a more actionable signal than click-through rate in this context.

    What’s the difference between an AI recommendation tracking tool and traditional SEO software? 

    Traditional SEO tools track page rankings in static search results. AI tracking tools monitor dynamic, generated answers where your brand may be recommended, compared, or excluded, with no traditional ranking signal to follow.

    How often should you run an AI recommendation tracking system? 

    Continuously. AI model fine-tuning happens frequently, and recommendation patterns can shift week to week. Monthly snapshots miss the movement between updates.

    What are the best tools for AI recommendation tracking? Platforms with multi-model coverage, automated prompt generation, citation mapping, and temporal tracking are the most reliable. Topify covers all four, with dedicated analytics for each major AI platform.

    How much does an AI recommendation tracking system cost? 

    It varies widely. Topify’s Basic plan starts at $99/month. Enterprise configurations with custom prompt sets and dedicated account managers start at $499/month.

    What are common mistakes in AI recommendation tracking? 

    Monitoring only one AI model, counting mentions without sentiment context, running static monthly tests, and focusing on mention volume over recommendation quality in high-intent prompts.

    Read More

  • AI Search Visibility Platforms: Why Security Matters

    AI Search Visibility Platforms: Why Security Matters

    You’ve narrowed your shortlist to three AI search visibility platforms, and on paper they look nearly identical. Each one promises to track how ChatGPT, Perplexity, and Gemini talk about your brand. What none of the sales decks mention is what you hand over to use them: your prompt strategy, your target keywords, your competitive intelligence, all fed into an external system that probes public AI models on your behalf. That data is your search strategy in raw form. Most buyers study the dashboard and never ask where it goes.

    That gap is why two platforms with the same feature list can carry very different risk.

    What AI Search Visibility Actually Means

    AI search visibility measures how often your brand gets mentioned, cited, or recommended inside answers generated by AI engines like ChatGPT, Perplexity, Gemini, and Google AI Overviews.

    It’s a different target than a search ranking. Traditional search returns a list of links and lets the user pick. AI search synthesizes one answer from many sources, then presents it as the answer. The thing you’re competing for shifts from a position on a page to what the research calls synthesized authority: being treated as a credible enough source to fold into the reply.

    Here’s the shift that trips up most teams. Success used to be a blue-link click. Now it’s citation authority, being the source a model selects when it builds its response.

    How an AI Visibility Platform Turns Raw Answers Into AI Search Analytics

    An AI visibility platform sits between raw model output and something a marketing team can act on. The work happens in four stages.

    First, structured probing: the platform runs a curated set of high-value prompts across multiple AI engines. Second, synthesis parsing, where it ingests each unstructured response and normalizes it into structured data. Third, an analytics layer that tracks citation frequency, position in a recommendation list, and sentiment polarity. Fourth, an intelligence layer that compares that data over time.

    That last layer is where AI search analytics becomes AI search intelligence. Analytics tells you a competitor got cited four times this week. Intelligence tells you why: cleaner schema, deeper content, a data point the model found quote-worthy.

    The distinction matters at selection time. A platform that only counts mentions leaves you guessing. One that explains the gap gives you something to fix.

    AI SEO vs AI Search Optimization: What Changes When Answers Replace Links

    These two terms get used interchangeably, and they shouldn’t be. They describe different layers of the same problem.

    TermWhat it coversWhere it operates
    AI SEOTechnical and content adjustments like schema, entity recognition, and content structure that make your information machine-readableThe page and markup level
    AI search optimization, or GEOInfluencing how the model makes its decision: conversational intent, entity authority, and quote-worthy data pointsThe model’s synthesis process

    The practical takeaway is the part that surprises SEO teams. Signals like backlink counts and keyword density are drifting away from AI performance. A page with zero backlinks can still hold high entity authority for a narrow topic, which makes it a preferred AI source.

    That’s why your domain authority score can look healthy while your AI brand visibility quietly drops. We’ve broken that disconnect down further in a comparison of AI search visibility versus Google rankings.

    AI Search Visibility Platforms Security Features: The Question Most Buyers Skip

    Here’s the part procurement usually catches too late. To track your visibility, a platform has to ingest the questions you care about, the competitors you watch, and the keywords you’re chasing. That’s not telemetry. That’s your strategy.

    Treating AI search visibility platforms security features as an IT checkbox is the mistake. It belongs in the core evaluation, right next to coverage and accuracy.

    Run the same framework across every vendor on your list.

    Security dimensionWhy it matters for AI visibility
    Data isolationKeeps your prompt strategy from being shared or used to train models serving other tenants
    SOC 2 Type IIConfirms security controls held up over a period, not just on audit day
    RBAC and SSOStops unauthorized access to competitive intelligence dashboards
    Audit logsRecords who queried what, and which AI interactions ran
    Encryption in transit and at restProtects proprietary search data from interception

    A Practical Security Checklist for Platform Selection

    On a vendor call, five questions separate a serious platform from a risky one:

    1. Data retention: are prompt-level queries deleted after a set period, or kept indefinitely?
    2. Prompt isolation: can the vendor show that your prompt sets are segregated from other clients?
    3. Independent testing: does the platform run annual penetration testing or third-party security audits?
    4. Model governance: how does it connect to AI engines, is that traffic encrypted, and does it respect each provider’s terms?
    5. Data residency: under GDPR or similar rules, can the vendor tell you where your visibility data lives?

    A platform that answers these cleanly has thought about more than its dashboard. Data security and compliance aren’t features you bolt on after signing.

    What Strong AI Brand Visibility Tracking Looks Like in Practice

    Good tracking does more than report a number. It closes a loop: see where you stand, understand why, then act.

    This is where Topify fits for teams measuring AI brand visibility across several engines at once. Three of its functions map directly to the questions buyers actually have.

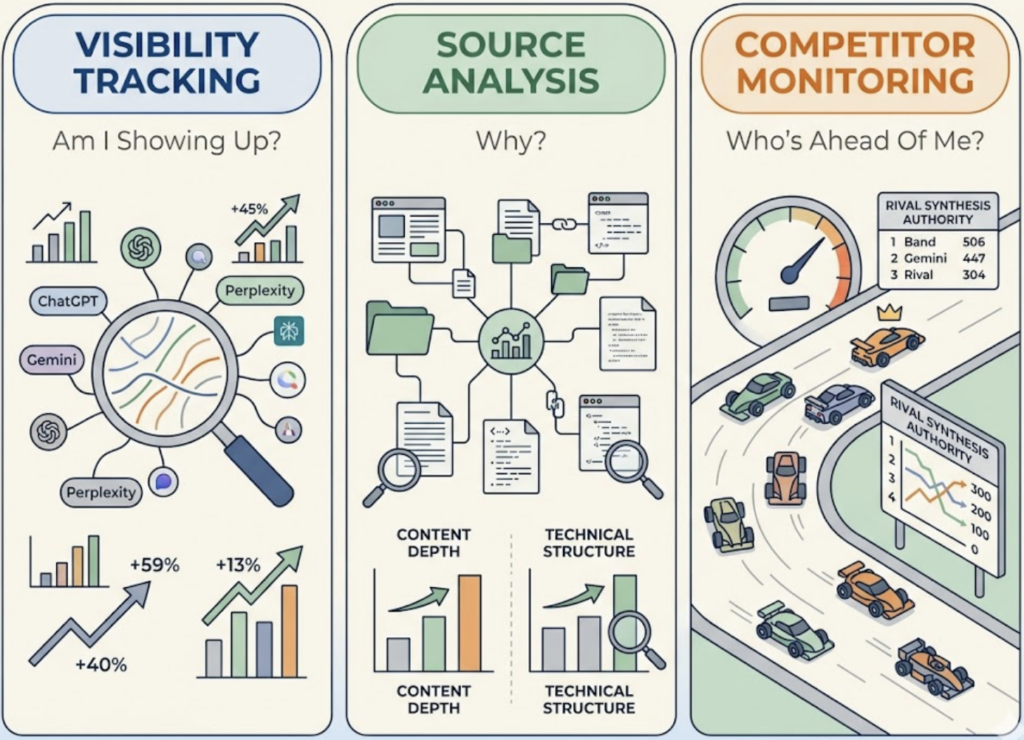
    Visibility Tracking answers “am I showing up,” monitoring how often your brand appears across ChatGPT, Gemini, Perplexity, and others. Source Analysis answers “why,” surfacing the exact domains and URLs AI engines cite so you can tell whether content depth or technical structure is winning the reference. Competitor Monitoring answers “who’s ahead of me,” tracking how rival synthesis authority moves in real time.

    On the governance side, the same data isolation and access controls from the checklist above are what let a marketing team hand this to legal without a fight.

    A reasonable starting path looks like this:

    1. Define a repository of 20 to 50 high-intent customer prompts.
    2. Baseline your current visibility rate by running probes across engines.
    3. Audit any competitor that keeps getting cited, checking their entity authority for cleaner schema or more comprehensive data.
    4. Iterate on your content structure, using FAQs, tables, and concise data summaries that match how models pull answers.

    How to Start Measuring AI Search Visibility

    You don’t need a six-month rollout to get a signal. Pick your ten highest-intent prompts, run them across the engines your buyers use, and write down who gets cited. That baseline alone usually surfaces a gap nobody on the team knew about.

    From there, the platform earns its place by telling you what to change. To set up a live baseline, you can get started with Topify and probe your prompt set across engines in a few minutes.

    Conclusion

    The platforms on your shortlist will keep looking alike on the feature grid. The difference shows up in two places: whether the tool explains why you weren’t cited, and whether it can be trusted with the strategy data you feed it. Score both. A platform that nails coverage but can’t answer the five security questions isn’t a bargain, it’s a liability sitting next to your competitive intelligence. Define your prompts, set a baseline, and treat security as a selection criterion rather than a formality you handle after the contract is signed.

    FAQ

    Q: What should I look for in an AI search visibility platform? 

    A: Prioritize intelligence over raw analytics. The platforms worth shortlisting explain why you weren’t cited, cover multiple AI engines, and back it with verifiable security like SOC 2 and role-based access.

    Q: How is AI search analytics different from traditional SEO analytics? 

    A: Traditional SEO measures your rank on a static page. AI search analytics measures synthesis authority, the probability that your brand gets selected and cited as a credible source inside a non-deterministic AI answer.

    Q: Why do AI search visibility platforms security features matter so much? 

    A: These platforms ingest your core marketing and competitive strategy to do their job. Weak data isolation or open-ended retention can expose your search intent, which is exactly what you’d least want a competitor to see. Data security and compliance belong in the evaluation, not after it.

    Q: Can I track AI brand visibility across multiple engines at once? 

    A: Yes. Look for structured probing that accounts for the different query fan-out logic each model uses, so your numbers stay comparable across ChatGPT, Perplexity, Gemini, and others.

    Read More

  • What Is AI Recommendation Tracking and Why It Matters

    What Is AI Recommendation Tracking and Why It Matters

    Your team spent a year building content, earning links, and climbing Google rankings. Then a buyer in your category opened ChatGPT and asked for the best option. The model named five brands. Yours wasn’t one of them. Nothing in your SEO dashboard explained why, because those metrics were never built to measure what an AI decides to say out loud. That blind spot has a name, and closing it starts with knowing what’s being said in the first place.

    What AI Recommendation Tracking Actually Means

    AI recommendation tracking is the systematic process of monitoring how AI-powered search engines represent your brand when someone asks for a product or service suggestion. It’s less about where a page ranks, and more about whether the model names you at all.

    Traditional SEO tracks the position of a specific URL on a results page. Recommendation tracking watches the synthesized answer an LLM generates, and asks one question: did your brand make the shortlist?

    That distinction matters more than it sounds. A top-three Google ranking doesn’t guarantee a single mention inside a ChatGPT answer. The two systems retrieve and prioritize information in different ways.

    This work sits under Generative Engine Optimization, or GEO. AI models pull live web data through a Retrieval-Augmented Generation (RAG) pipeline, then condense it into a short, ranked set of recommendations. If your brand isn’t in the retrieved set, it can’t be recommended. There’s no second page to scroll to.

    That’s the gap most brands still can’t see.

    How Does AI Recommendation Tracking Work

    AI systems are non-deterministic. Ask the same question twice and the wording, order, and even the names can shift. So tracking can’t be a one-time check. It has to be a repeatable measurement discipline.

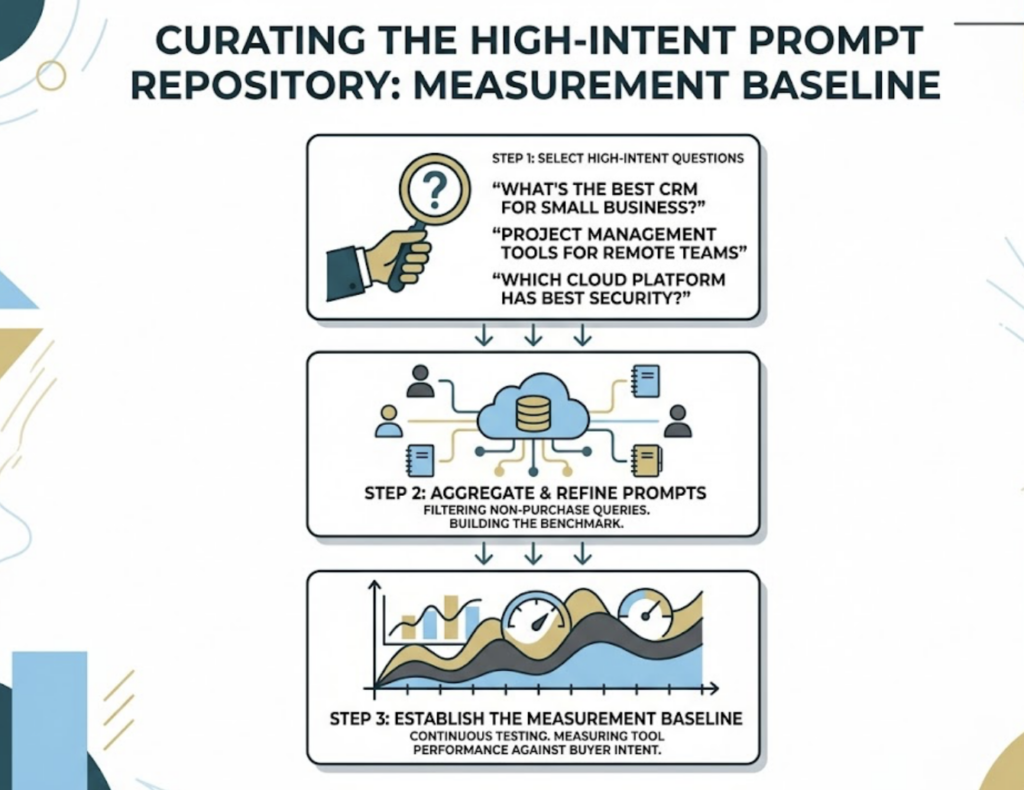
    In practice, a working setup runs through four steps.

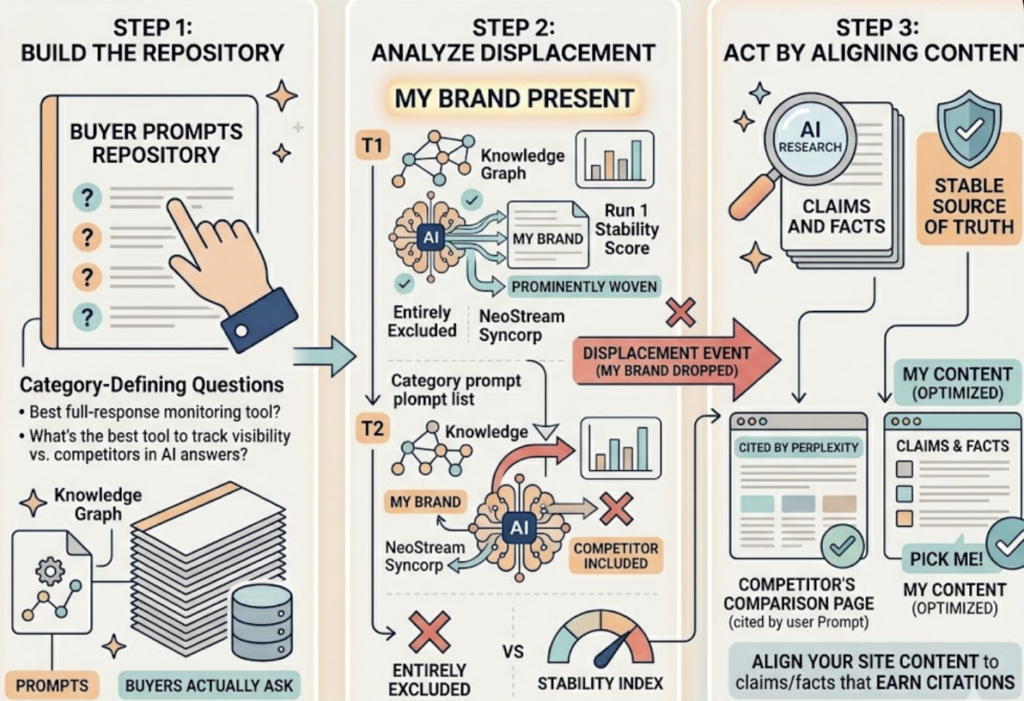
    First, a prompt repository. You curate a set of high-intent, category-defining questions a real buyer would ask, like “What’s the best CRM for a small business?” or “Which project management tool works for remote teams?” These prompts become your measurement baseline.

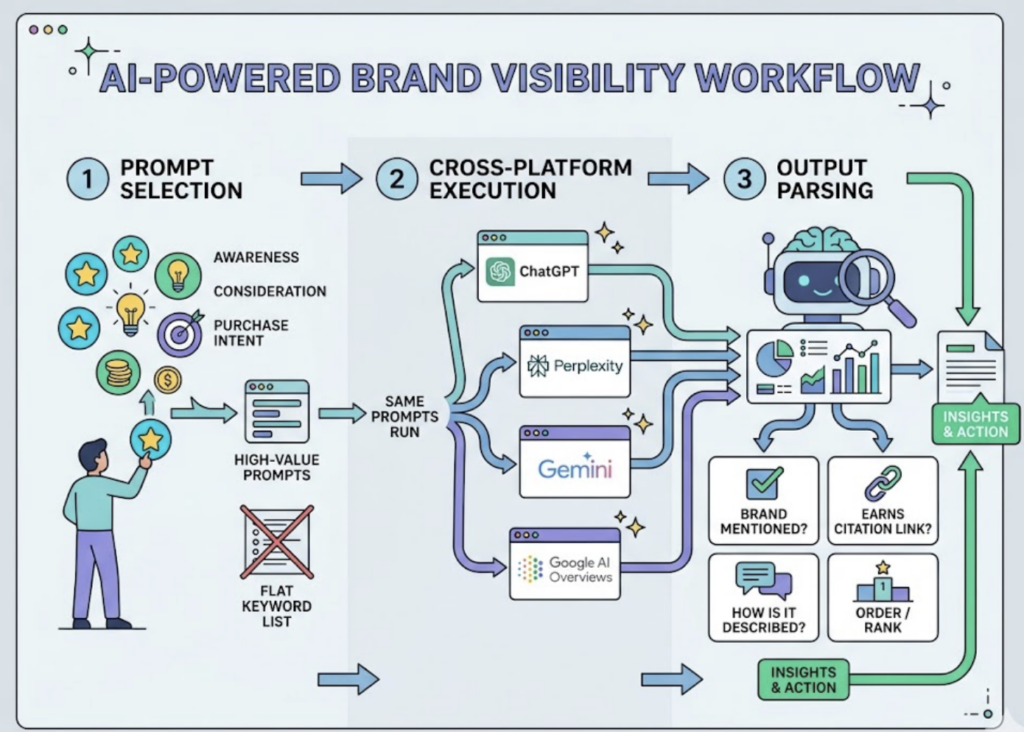
    Second, cross-platform probing. The same prompts run across ChatGPT, Perplexity, Gemini, and Google AI Overviews. Each engine retrieves and ranks sources differently, so a brand that dominates one can be absent on another.

    Third, cyclical sampling. Because responses drift with model updates and changing retrieval results, a single snapshot is close to useless. Running the prompt set weekly builds a stable visibility baseline instead of a lucky guess.

    Fourth, semantic parsing. Automated systems read each answer and pull out the structured signals: whether your brand was mentioned, where it sat in the list, how it was described, and which source the model cited.

    Here’s a concrete version. A team tracks 200 prompts across four AI platforms, sampled weekly for 30 days. By the end, they don’t have an opinion about their AI presence. They have a measured rate, a position trend, and a list of the exact pages the models keep citing instead of theirs.

    How to Measure AI Recommendation Tracking

    Knowing you’re “sometimes mentioned” isn’t a metric. To report on AI presence with any credibility, you need a defined framework. Most mature programs track five signals.

    MetricWhat It Tells You
    Visibility (mention) rateShare of prompts where your brand appears at all. Your top-of-funnel presence.
    Position / share of voiceWhere you land in the recommendation list, relative to competitors.
    Citation shareHow often the model links directly to your domain. A proxy for source authority.
    Sentiment accuracyThe tone and framing used when your brand is named.
    Conversion rate (CVR)How AI-referred traffic converts compared to traditional search traffic.

    Each metric answers a different question, and skipping any one leaves a blind spot. Visibility without position tells you that you exist, not whether you’re the first name a buyer sees. Citation share without sentiment tells you the model links to you, not whether it’s describing you the way you want.

    This is also where ai-powered brand visibility tracking tools earn their place. Pulling these five signals by hand, across four platforms, every week, isn’t realistic. Automation is what turns scattered observations into a baseline you can actually trend over time.

    How to Improve AI Recommendation Tracking and Avoid Common Mistakes

    Measurement tells you where you stand. Improving the result is a separate discipline, and it tends to come down to making your brand easy for a model to retrieve, trust, and quote.

    A few practices do most of the work.

    Entity optimization. AI engines favor brands that are legible to a machine. Consistent factual claims across the web, clean product data, and structured Schema markup help a model anchor a recommendation to you rather than guess.

    Expertise-first content. Models reward signals of experience, authority, and trust. Original research, clear methodology, and named expert bios make a page more likely to be cited than generic marketing copy.

    Answer-first formatting. Direct Q&A blocks, FAQs, and short summaries are easier for a model to extract. Content it can lift cleanly is content it’s more likely to surface.

    Now the mistakes. Most teams lose visibility not from doing nothing, but from measuring the wrong way.

    • Single-platform bias. Assuming a strong ChatGPT showing means you’re visible everywhere. Each engine runs a different RAG mechanism.
    • Snapshot reliance. Testing once a month and treating it as truth, despite how much responses fluctuate week to week.
    • Ignoring sentiment. Being mentioned, but framed as the “legacy” or “budget” option. Presence isn’t the same as a good recommendation.
    • Neglecting source authority. Chasing mentions while giving the model nothing citable to point at.

    If you want a quick self-check, run this list before your next review: Are you tracking more than one AI platform? Are you sampling on a schedule, not once? Are you watching position, not just mentions? Are you reading sentiment, not assuming it’s neutral? Do you know which pages get cited in your category? Five yeses is a healthy program. Anything less is a gap worth closing.

    AI-Powered Brand Visibility Tracking Tools: What to Look For

    The market for AI visibility tools is filling up fast, and most of them measure a slice of the picture. The best tools for AI recommendation tracking share a few non-negotiable traits.

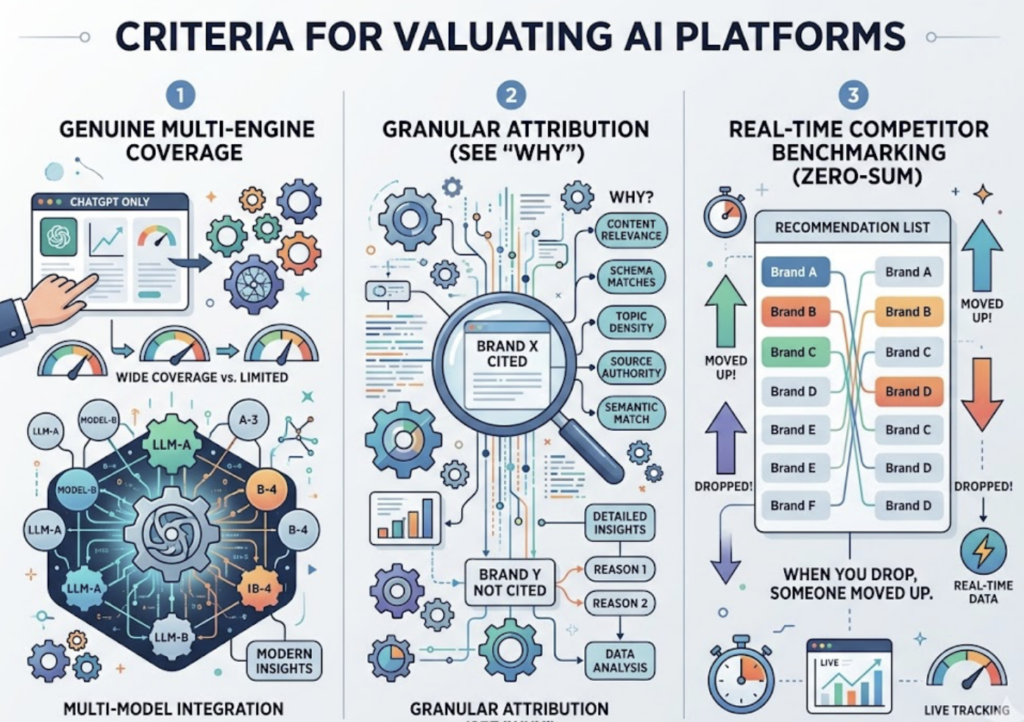
    Look for genuine multi-engine coverage, not a ChatGPT-only dashboard wearing a broader label. Look for granular attribution, so you can see why a brand was or wasn’t cited, down to content relevance and schema matches. And look for real-time competitor benchmarking, because a recommendation list is zero-sum: when you drop, someone else moved up.

    For teams that want these signals in one view, Topify tends to stand out by consolidating Visibility, Position, Sentiment, and Citation Share rather than reporting them in separate silos. In practice, that means you can catch a drop in your ChatGPT mention rate, trace it to a competitor that replaced you in the answer, and see which source the model cited instead, all in the same place.

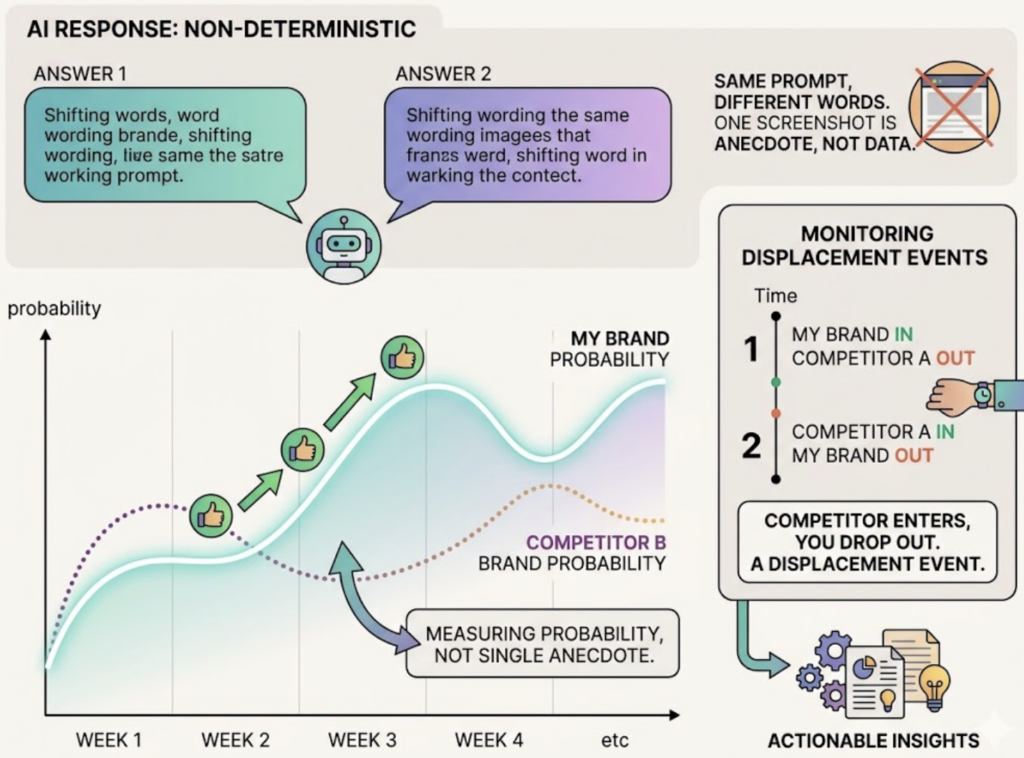
    Topify’s team frames that last pattern as a “Displacement Event,” the moment a rival takes your slot in an AI response. Competitor Monitoring surfaces it in real time, Source Analysis shows the citation that anchored the swap, and Position Tracking confirms how far you slid. That’s the difference between knowing your number went down and knowing what to do about it.

    Pricing follows usage rather than inflated enterprise bundles, which makes it realistic to start small and expand as the data proves out. If you want to set a baseline this week, you can get started with Topify and run your first prompt set across multiple engines before your next reporting cycle.

    Conclusion

    AI recommendation tracking has moved from a nice-to-have SEO add-on to a basic requirement for staying visible in a generative-first web. The buyers asking ChatGPT and Perplexity for a recommendation aren’t waiting for your rankings to catch up. The practical first step is small: build a prompt repository for your category, pick a tool that covers more than one platform and more than one metric, and measure a baseline. Once you can see what AI is saying, you can finally do something about it.

    FAQ

    Q: What is AI recommendation tracking in simple terms? 

    A: It’s monitoring whether and how AI search engines name your brand when a user asks for a recommendation. Instead of tracking a page’s rank, you track whether the model includes you in its synthesized shortlist, where you land in that list, and how it describes you.

    Q: How does AI recommendation tracking work across different platforms? 

    A: You run a fixed set of high-intent prompts across engines like ChatGPT, Perplexity, Gemini, and Google AI Overviews, then sample them on a schedule because responses shift over time. Automated parsing extracts your mentions, position, sentiment, and citations from each answer so you can compare platforms side by side.

    Q: What does AI recommendation tracking pricing typically look like? 

    A: It usually scales with how many prompts and platforms you monitor. Topify’s plans start around $99 per month for tracking across ChatGPT, Perplexity, and AI Overviews, with a Pro tier near $199 and Enterprise from roughly $499, so smaller teams can start lean and expand as value becomes clear. You can review the current tiers on the Topify pricing page.

    Q: What are some examples of AI recommendation tracking in practice? 

    A: A common example is tracking a prompt like “best [your category] tool” across four AI platforms, weekly, for 30 days. The output shows your mention rate, your average position versus competitors, and which sources the models cite, which together reveal exactly where to focus content and citation efforts.

    Read More

  • What an AI Prompt Tracking Service Actually Sees

    What an AI Prompt Tracking Service Actually Sees

    Your AI visibility dashboard shows a score of 62. Last month it was 58. That looks like progress, until you realize the number can’t tell you which customer questions actually surface your brand and which ones hand the answer to a competitor. A single score averages away the one thing that moves pipeline: presence at the prompt level. Most teams end up watching a metric rise and fall without ever knowing why, or what to fix.

    That’s the gap an AI prompt tracking service is built to close.

    What an AI Prompt Tracking Service Is

    An AI prompt tracking service is a platform that monitors how AI engines like ChatGPT, Perplexity, and Gemini represent your brand when real users type natural-language questions. Traditional SEO watches keyword positions on a results page. Prompt tracking watches the synthesized answer the model actually generates.

    The difference is granularity. A “total visibility score” rolls everything into one figure. Prompt-level tracking shows you exactly which questions trigger a mention and which ones leave you out.

    That distinction matters more than it sounds. You can rank high on Google yet still be absent from AI-generated answerswhere competitors appear. With 37% of people now starting searches with AI and Gartner projecting a 25% drop in traditional search volume by 2026, the prompt layer is no longer optional to measure.

    This is why the category is sometimes called an AI prompt tracking tool, software, or solution. The labels vary. The job is the same: tell you where your brand stands inside AI answers, prompt by prompt.

    How an AI Prompt Tracking Service Works

    A prompt tracking system treats each AI model as a black box that has to be probed on purpose. The workflow comes down to three moves.

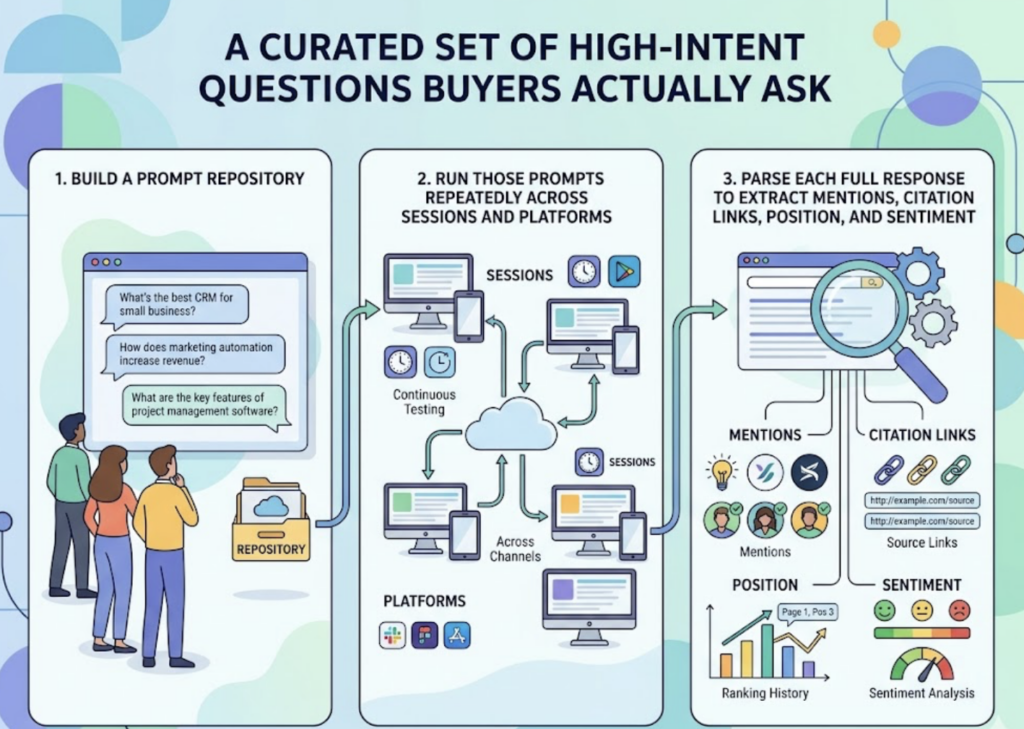
    First, build a prompt repository: a curated set of high-intent questions your buyers actually ask, like “what’s the best CRM for small business?” Second, run those prompts repeatedly across sessions and platforms. Third, parse each full response to extract mentions, citation links, position, and sentiment.

    The repeated part isn’t optional. AI systems give probabilistic responses that change even when users enter the same prompt, so a single check tells you almost nothing.

    One snapshot is noise. A distribution is signal.

    Only aggregate data over time can confirm whether you’ve reached authority status in a prompt category or just got lucky on one run. A platform that samples once a month is reporting a coin flip. A real tracking solution samples often enough to build a stable picture per prompt, per platform.

    Why Prompt-Level Tracking Beats a Single Visibility Score

    Here’s the thing about aggregate scores: they hide the cases you most need to act on. Your score can hold steady at 62 while you quietly lose every comparison prompt in your category to one competitor.

    Semrush frames the prompt set as a portfolio organized by business impact, not vanity visibility, covering revenue, reputation, competitor, and gap prompts. Each type maps to a different growth signal. Lump them into one number and you lose the ability to tell a reputation problem from a revenue one.

    The strongest case for prompt-level data is the displacement event: a question where a rival shows up in the answer and you don’t. That single insight is worth more than a month of trend lines, because it points to a specific content gap you can fix.

    A dashboard that only shows movement can’t show you that. A prompt-level view can.

    How to Measure an AI Prompt Tracking Service

    Useful measurement moves past raw mention counts. The working set of dimensions most teams settle on looks like this.

    MetricWhat It Tells You
    Visibility RateThe share of tracked prompts where your brand is named. Your baseline for existence.
    Citation ShareThe share of AI answers that link to your site. Your “source of truth” authority.
    Average PositionWhere you land in recommendation lists. Users rarely read past the first three.
    SentimentThe context of the mention. Top choice, or legacy alternative?
    Share of VoiceYour frequency versus direct competitors in the same prompt cluster.

    Two of these deserve a closer look. AI Share of Voice is the AI-era version of market presence, showing how often you appear relative to rivals across prompts and platforms. Prompt coverage, the percentage of your tracked set where you show up at all, exposes structural gaps that a high score on one narrow cluster will mask.

    A good AI prompt tracking dashboard puts these side by side so a drop in one is traceable to a cause, not just a lower number.

    What to Look for in an AI Prompt Tracking Tool

    Once you understand the metrics, choosing a platform gets simpler. Three capabilities separate a real tracking solution from a glorified spreadsheet.

    The first is high-value prompt discovery. You shouldn’t have to guess your prompt set. The platform should surface the questions buyers are actually asking in your category, since that’s where visibility converts to revenue.

    The second is source and position analysis. Knowing you lost a prompt is half the answer. Knowing why, usually because a competitor’s content is more machine-readable, is what lets you respond.

    The third is cross-platform coverage. ChatGPT presence doesn’t predict Perplexity or Gemini presence. Each engine surfaces different brands for identical questions, so single-platform tracking gives you a false read.

    This is where a platform like Topify fits the brief. It runs a seven-dimension analysis (visibility, position, sentiment, citation share, volume, mentions, and intent) and pairs it with High-Value Prompt Discovery, so you’re not just monitoring a fixed list but continuously finding new prompts as AI recommendations shift.

    In practice, that means you can catch a displacement event the week it happens: a competitor enters the answer for a high-intent prompt, Topify flags it, and its Competitor Monitoring and Source Analysis show you which domains the model now cites instead of yours. Coverage spans ChatGPT, Gemini, Perplexity, DeepSeek, and other major engines, so the read holds across the platforms your audience actually uses.

    Common Mistakes and a Strategy That Works

    Most teams don’t fail at prompt tracking because the tooling is hard. They fail because of a few repeatable mistakes.

    The dashboard trap comes first. Obsessing over a single visibility score while ignoring the prompt data underneath. Entrepreneur put it bluntly: many teams track GEO performance with dashboard numbers that don’t connect to anything real.

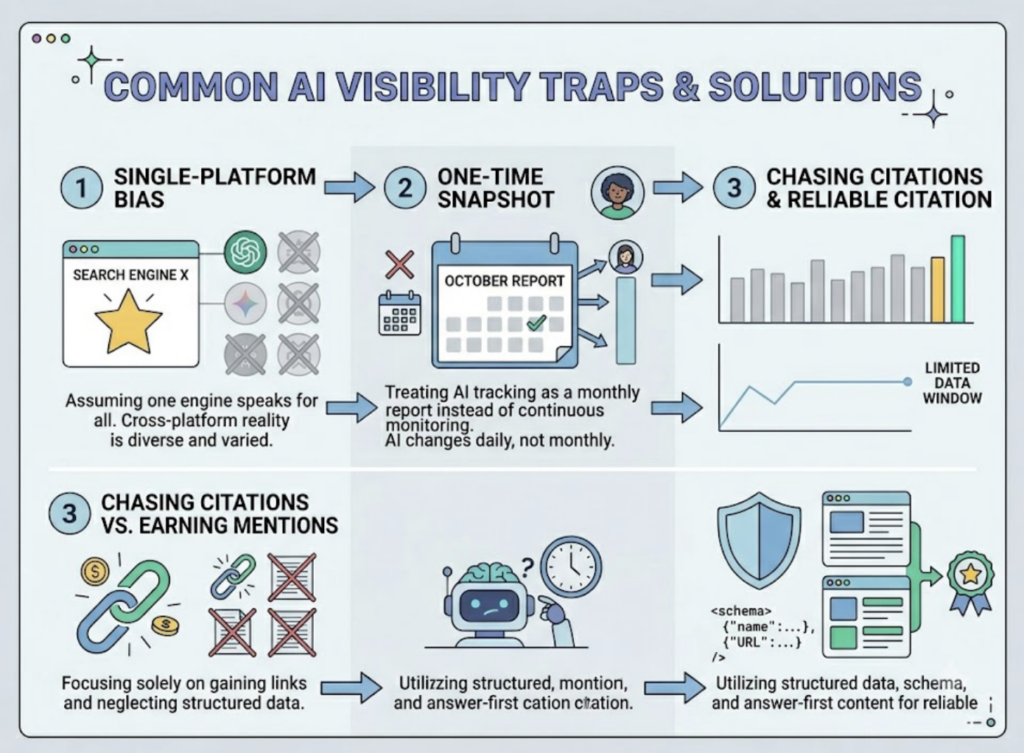
    The next three are just as common. Single-platform bias, assuming one engine speaks for all. The one-time snapshot, treating tracking as a monthly report instead of continuous monitoring. And chasing citations instead of earning mentions, while neglecting the structured data, schema, and answer-first content that lets AI cite you reliably.

    Going quiet after launch is the quietest killer of all.

    A workable strategy reverses each mistake. Build a repository of at least 20 to 50 high-value questions. Run baseline probes across all your primary platforms to establish your visibility rate. Use the data to spot source gaps, then treat the prompts you’re missing as content targets and audit your page structure to answer them directly. Then re-measure. The cycle is the point: track, find the gap, fix the source, re-test.

    What an AI Prompt Tracking Service Costs

    Pricing for most prompt tracking software scales on two things: how many prompts you track and how many platforms you cover. Sampling frequency and depth of source analysis push it up from there.

    Typical starting tiers run from around $99 a month for entry plans to $499 and up for enterprise coverage. Topify follows that shape, with a Basic plan at $99/month, Pro at $199, and Enterprise from $499, scaling on tracked prompts, AI answer analyses, projects, and seats rather than locked into inflated bundles.

    The math worth running isn’t the subscription. It’s the cost of a competitor owning every comparison prompt in your category while you can’t see it happening. You can start tracking your own prompt set and get a baseline visibility rate before committing to a paid tier.

    Conclusion

    An AI prompt tracking service exists to answer one question a visibility score can’t: which buyer prompts surface your brand, and which ones hand the answer to someone else. The teams getting value from it aren’t the ones with the highest score. They’re the ones who built a focused prompt set, measured across every platform that matters, and turned the gaps into content targets.

    Start small. Pick 20 high-intent prompts, run a baseline across ChatGPT, Perplexity, and Gemini, and see where you actually stand. The number on the dashboard will make a lot more sense once you can see the prompts behind it.

    FAQ

    Q: What is an AI prompt tracking service, in one sentence? 

    A: It’s a platform that monitors how AI engines mention, cite, and rank your brand when users ask natural-language questions, measured at the level of individual prompts rather than a single aggregate score.

    Q: How do I improve my AI prompt tracking results? 

    A: Find the high-intent prompts where competitors appear but you don’t, then make your content the most machine-readable answer to those exact questions using clear structure, schema, and answer-first formatting. Re-measure after each change to confirm the prompt now surfaces your brand.

    Q: What’s a quick checklist for evaluating an AI prompt tracking tool? 

    A: Look for four things: automatic high-value prompt discovery, repeated sampling across sessions, coverage of multiple AI platforms, and source or citation analysis that explains why a competitor was chosen. A tool missing any one of these gives you an incomplete read.

    Q: Is a prompt tracking system different from a visibility dashboard? 

    A: They overlap, but a dashboard often shows only an aggregate score, while a prompt tracking system preserves the underlying per-prompt data. The dashboard tells you the number changed. The prompt-level system tells you which question caused it.

    Read More

  • AI Prompt Tracking: What It Is and How to Measure It in 2026

    AI Prompt Tracking: What It Is and How to Measure It in 2026

    Your team can pull domain authority, keyword positions, and organic traffic in about thirty seconds. Then someone in the room asks whether your brand showed up when a buyer typed your category into ChatGPT, and the report goes quiet. Traditional SEO tools were built to measure a ranked list of links, not whether you’re part of a synthesized answer. That gap is where AI prompt tracking lives, and most teams don’t realize how wide it’s gotten until a competitor’s name is the one the model keeps recommending.

    What AI Prompt Tracking Actually Means, and Why Rankings Don’t Apply

    AI prompt tracking is the systematic monitoring of how your brand shows up inside the natural-language responses that generative engines produce. The question shifts from “where do we rank” to “are we part of the answer” that ChatGPT, Perplexity, or Google’s AI Overviews hand the user.

    That shift matters because the two systems behave differently. Classic search is deterministic: the same query returns roughly the same ranked list. AI search is probabilistic. The model runs a query fan-out, breaking one prompt into sub-questions, pulling from multiple sources, and synthesizing a fresh response each time.

    So your brand can headline the answer in one run and disappear in the next. None of that surfaces in a rankings report.

    The stakes are concrete. Organic click-through rate falls 61% on queries where an AI Overview appears, while brands cited inside that overview see click-through about 35% higher than the page’s normal rate. Presence in the answer isn’t a vanity metric. It’s the difference between earning the click and watching it evaporate.

    How AI Prompt Tracking Works Under the Hood

    Page crawlers don’t work here. There’s no fixed results page to scrape, so AI prompt tracking relies on structured probing: feeding defined prompts into each engine and parsing the response the way a real user would receive it.

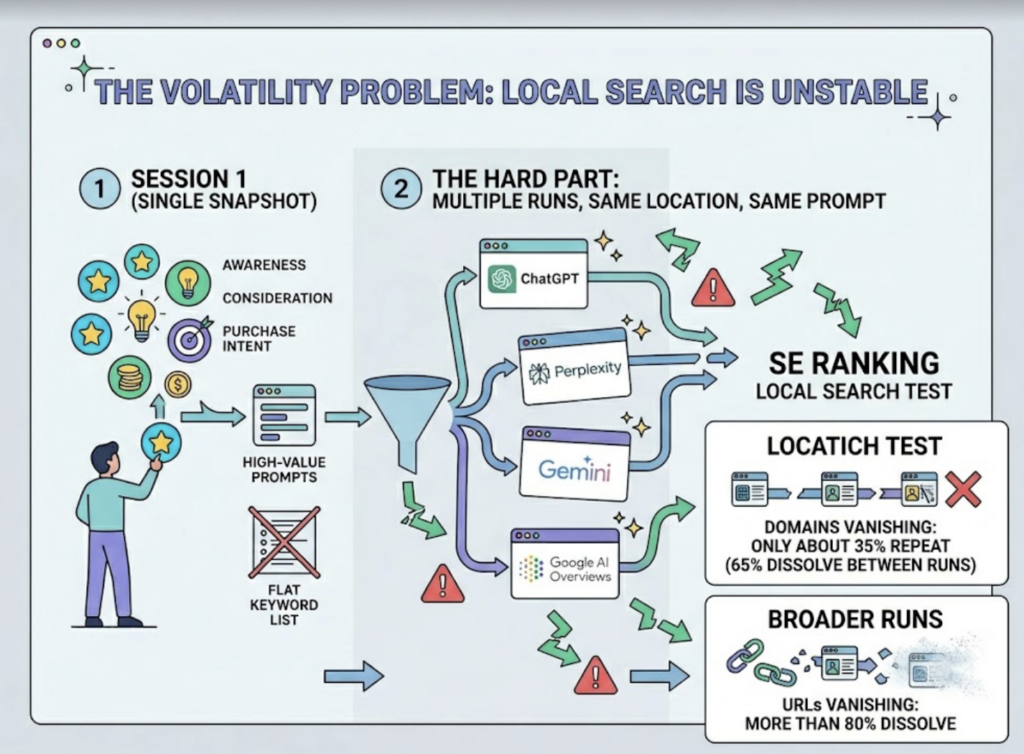
    The hard part is volatility. In SE Ranking’s local search test, only about 35% of domains repeated when the same prompt ran multiple times from the same location. Broader runs show more than 60% of domains and 80% of URLs vanishingbetween sessions. A single snapshot tells you almost nothing.

    That’s why credible systems use repeated sampling. They run each prompt many times across accounts and locations, then average the results into a visibility score that’s statistically stable instead of a lucky screenshot.

    The fan-out adds another layer. When the engine decomposes a master prompt into sub-queries, a good tracker watches which sub-topics the model associates with your brand, not just whether your name appears once.

    How to Measure AI Prompt Tracking: The Metrics That Matter

    Counting raw mentions is the trap most teams fall into. A useful measurement framework tracks five metrics together, because each one answers a different question.

    MetricWhat it tells you
    Mention RateThe share of your tracked prompts where the brand gets named at all
    Citation ShareHow often the engine links to your site, which drives referral traffic
    Average PositionWhere you land in the AI’s ordered list of recommendations
    SentimentWhether the model frames you as positive, neutral, or negative
    Share of VoiceYour mentions relative to a defined competitor set across the same prompt cluster

    The signal hiding in this table is the gap between mention rate and citation share. If AI names you often but rarely cites your page, that usually points to a structural problem on your site: missing schema, thin information architecture, or content the model can’t confidently treat as a source of truth.

    This is also where ai search trackers earn their keep. Pulling five metrics by hand across three engines, repeated often enough to beat the volatility, isn’t realistic. The tooling exists to automate the sampling and turn it into something you can report on weekly.

    How to Improve AI Prompt Tracking, and the Mistakes That Quietly Sink It

    Improving your numbers starts with not sabotaging them. A few mistakes show up again and again.

    The dashboard trap is the most common. Tracking “total monthly mentions” with no denominator and no competitor context produces a number that climbs as the AI ecosystem grows, not as your performance improves. It feels like progress and measures nothing.

    Siloing GEO from SEO is the second. AI engines lean on the same E-E-A-T signals (expertise, experience, authoritativeness, trustworthiness) that Google’s classic systems reward, so treating AI visibility as a separate discipline wastes the authority you’ve already built.

    The third is ignoring source accuracy. Models often describe brands using stale or wrong data from their retrieval index, which is why entity audits, checking that the AI understands your products, founders, and positioning, belong in the workflow.

    On the improvement side, structure does heavy lifting. 44.2% of LLM citations come from the first 30% of a page’s text, and structured formats like clear headings, lists, and FAQ blocks tend to get pulled more often than dense prose. Put your answer up top, mark it up cleanly, and you make it easy for the model to quote you.

    A Quick AI Prompt Tracking Checklist

    If you’re building a process from scratch, this is the short version:

    • Curate a high-value prompt repository by intent (procedural, comparative, problem-solving) instead of tracking every keyword.
    • Standardize the query environment, including location when it’s relevant, to cut baseline noise.
    • Run each prompt multiple times and average, rather than trusting one response.
    • Track mentions and citations together, and earn the name-drop before chasing the link.
    • Benchmark against a fixed competitor set so your share of voice means something.
    • When a rival gets cited and you don’t, run a diff on their page structure, schema, and content depth.

    Best AI Search Trackers 2026: What to Look for in a Prompt Tracking Tool

    When you start comparing the best AI search trackers 2026 has to offer, the useful filter is simple: look for a visibility system, not a reporting dashboard. A dashboard shows you numbers. A system tells you why the engine chose one source over another and what to do about it.

    Three capabilities separate the two. Cross-engine coverage, so you’re watching ChatGPT, Perplexity, and AI Overviews at once rather than one platform in isolation. Competitor benchmarking, so every metric reads as relative performance inside a peer group. And actionable attribution, so the tool can point at the page structure, schema, or content depth that earned a citation.

    This is where Topify fits the brief. It runs prompt-level tracking across the major engines and folds visibility, position, sentiment, and source analysis into a single view, so a drop in ChatGPT mentions can be traced back to the specific source that stopped citing you.

    Its High-Value Prompt Discovery is the part most reporting tools skip. Instead of waiting for you to guess which prompts matter, it surfaces the high-volume questions in your category and watches how the answers shift, which moves a team from passive monitoring toward proactive content work. Competitor Monitoring then shows who the engines recommend ahead of you, and where the gap sits.

    On cost, plans start at $99 a month and scale by prompt volume and seats, with usage-based tiers rather than inflated enterprise bundles. Other platforms cover slices of this well, but the payoff of a single connected view is that you stop stitching three tools together to answer one question. You can get started without committing to a year up front.

    Conclusion

    The quiet moment in that meeting, when the rankings report can’t say whether you showed up in the AI answer, isn’t going away on its own. It widens every quarter as more buyers start their research inside a chatbot instead of a search bar.

    The fix isn’t complicated to start. Define a small set of high-intent prompts, run them across ChatGPT, Perplexity, and AI Overviews a few times each, and see where you actually stand. Once you can measure it, you can improve it, and that’s the whole point of AI prompt tracking.

    FAQ

    Q: What is AI prompt tracking? A: It’s the practice of monitoring whether and how your brand appears inside generative AI responses, prompt by prompt, across engines like ChatGPT, Perplexity, and Google AI Overviews. Instead of measuring keyword rank, it measures presence in the synthesized answer the user actually reads.

    Q: What are some examples of AI prompt tracking in practice? A: Running “best tools for [your category]” across three engines fifty times and recording how often your brand is named, tracking whether Perplexity cites your pricing page versus a competitor’s, or watching your average position drop after a model update. Each is a prompt tracked, sampled, and scored over time.

    Q: What do AI search trackers typically cost? A: Pricing varies by prompt volume, engine coverage, and seats. Entry tiers tend to start around $99 a month for a capped set of prompts and projects, with higher plans scaling sampling and competitor coverage. Usage-based pricing generally beats fixed enterprise bundles for teams still sizing their prompt set.

    Q: What are the most common mistakes in AI prompt tracking? A: Reporting total mentions with no denominator or competitor context, treating GEO as separate from SEO when both reward the same E-E-A-T signals, and trusting a single snapshot despite the volatility that makes most results shift between runs.

    Read More

  • AI Prompt Tracking Analytics: What It Is and How It Works

    AI Prompt Tracking Analytics: What It Is and How It Works

    Your team spent the last quarter publishing content, earning links, and climbing Google rankings. Then a buyer in your category opened ChatGPT and asked which tool to use. The answer named five options. Yours wasn’t one of them, and nothing in your analytics flagged it.

    That’s the blind spot. Google reports organize the world by keywords and pages. AI assistants organize it by prompts: the actual questions people type. When the two don’t line up, you can rank well and still go unmentioned where buying decisions now start. Closing that gap is the job of AI prompt tracking analytics.

    What Is AI Prompt Tracking Analytics?

    AI prompt tracking analytics is the practice of monitoring how a brand gets mentioned, cited, or recommended in AI-generated answers when people ask category-relevant questions.

    The shift in logic matters more than the definition. Traditional SEO tracks keywords, which are static search strings tied to a page. Prompt tracking follows prompts, which are full natural-language questions that span the buyer’s journey, from “what is X” to “which X should I buy.”

    There’s a structural reason the old model breaks. AI engines don’t return a fixed ranked list. They run a query fan-out, splitting one prompt into several retrieval tasks and synthesizing an answer from many sources at once. So the question stops being “where do I rank” and becomes “how often does the model include me, and in what light.”

    That’s a probability, not a position. And probability is exactly what analytics is good at measuring.

    How AI Prompt Tracking Analytics Works

    Prompt tracking doesn’t work like a crawler checking a ranking. It works through structured probing: a repeatable, automated routine that treats each AI answer as a data point.

    Three steps run on a loop.

    First, prompt selection. You curate a set of high-value prompts mapped to awareness, consideration, and purchase intent, instead of a flat keyword list. Second, cross-platform execution. The same prompts run across ChatGPT, Perplexity, Gemini, and Google AI Overviews, because each model has its own bias about who to name. Third, output parsing. An AI layer reads each response and pulls out whether your brand is mentioned, whether it earns a citation link, how it’s described, and where it sits in the order.

    Here’s the part most teams underestimate: consistency.

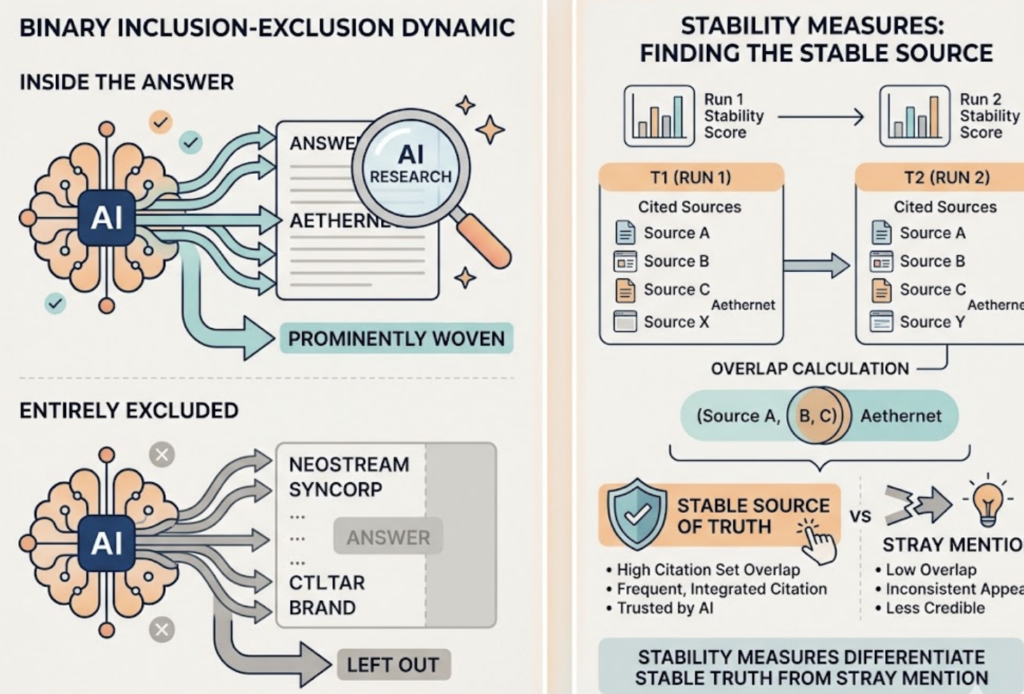
    AI answers are probabilistic, so the same prompt can return a different lineup on the next run. In one analysis of repeated queries, only 35% of domains showed up again across runs, meaning two-thirds dropped out between identical searches. The drift goes deeper than sources. A separate study found that AI recommendation lists repeat less than 1% of the timewhen you ask twice.

    So a single check tells you almost nothing. A reliable AI prompt tracking system measures presence across dozens of runs over 30+ days, and treats stable presence, not a lucky snapshot, as the real signal of authority.

    How to Measure AI Prompt Tracking Analytics: The Metrics That Matter

    Standard analytics suites have no built-in metric for AI visibility. Teams that report to executives tend to settle on a small, consistent framework instead.

    MetricThe business question it answers
    Share of AnswersDo we have a baseline visibility problem in our category?
    Third-Party Mention RateAre we recommended by name in AI-generated lists?
    Citation ShareAre we earning “source of truth” status that drives traffic?
    Sentiment PolarityDoes AI position us as a leader or a legacy option?
    Recommendation RankingDo we land in the top three of the response?

    The trade-off with any single metric is that it answers half the question. Share of Answers tells you if you show up. It says nothing about whether the model frames you as the category leader or a budget afterthought.

    This is where a unified view earns its keep. Topify tracks brand performance across major AI platforms through seven dimensions at once: visibility, sentiment, position, volume, mentions, intent, and CVR. Pulling sentiment and position into the same frame as raw mentions is what separates “we got named” from “we got named, ranked second, and described as premium.” The CVR layer goes one step further, estimating how likely an AI answer is to push a user toward real brand interaction, which connects visibility to revenue rather than vanity counts.

    Where Teams Use It: Examples of AI Prompt Tracking Analytics in Practice

    The clearest examples of AI prompt tracking analytics show up in three recurring jobs.

    The first is executive reporting. When a leadership team asks “are we showing up in ChatGPT,” a prompt-level dashboard turns a vague worry into a number trended over time. The second is competitor monitoring. Topify’s competitor benchmarking shows which rivals the models recommend, tracks your position against them, and flags new entrants the moment they start getting named. The third is content diagnosis.

    That last one is where prompt data gets genuinely actionable.

    Reverse-engineering AI citations means looking at the exact domains and URLs a model pulls from, then asking why a competitor’s page got cited and yours didn’t. Topify’s source analysis maps those references at scale, so a drop in Perplexity mentions can be traced back to a specific source that stopped citing you, all inside one view.

    Choosing an AI Prompt Tracking Tool, Platform, or Dashboard

    Search “AI prompt tracking tool” and you’ll find software that all promises AI visibility. The differences hide in three places, and they’re worth a short framework before you commit.

    Platform coverage comes first. A tool that only watches ChatGPT misses Perplexity, Gemini, and AI Overviews, where your buyers may be getting a completely different answer. Attribution depth comes second: does the platform explain why a citation moved, or just chart that it did. Execution comes third. Some solutions stop at reporting; others let you act on the finding without exporting to a separate workflow.

    On all three, Topify tends to stand out by covering global AI engines and pairing the data with one-click execution. You state a goal in plain English, review the proposed strategy, and deploy it from the same place you spotted the problem. For teams drowning in dashboards that report and never resolve, that closes the loop. You can get started with Topify on a single project before scaling across a brand portfolio.

    Plenty of category tools handle one slice of this well. The question isn’t which one is loudest, but which one matches how your team actually works.

    What Separates a Dashboard from a Real AI Prompt Tracking System

    A reporting dashboard shows you where you stand. A visibility system tells you why and what to do next. That distinction decides whether an AI prompt tracking dashboard is useful or just decorative.

    Dashboards hand you a number: “mentioned five times this week.” Systems and solutions hand you attribution: a competitor got cited because their landing-page schema matched the prompt’s intent, and here’s the gap to close. One describes the weather. The other tells you to bring an umbrella.

    How to Improve Your AI Prompt Tracking Analytics

    Improving prompt tracking is less about more data and more about avoiding the mistakes that quietly distort it.

    Four show up constantly. The volume trap is treating prompts like keywords and chasing mention frequency while ignoring citation authority. Single-model bias is assuming strong ChatGPT presence guarantees Perplexity or AI Overviews coverage; it doesn’t. Snapshot reliance is running a prompt once and trusting it, despite the volatility covered earlier. Siloed execution is the quiet one: treating generative engine optimization as separate from SEO, when AI models lean on the same trust signals, E-E-A-T, clean structure, technical health, that good SEO already builds.

    A workable strategy for AI prompt tracking analytics fits on a short checklist.

    1. Map your prompts. Take your top 20 to 40 high-intent keywords and rewrite them as natural-language questions a buyer would actually ask.
    2. Establish a baseline. Track those prompts across at least three models for 30 days before drawing any conclusion.
    3. Audit source gaps. When a competitor gets cited, study their page structure, schema, and how directly they answer the question.
    4. Iterate content. Structure yours answer-first, with clear headers and factual summaries a model can lift cleanly.

    Run that loop, and the analytics stop being a report card and start being a roadmap.

    Conclusion

    The gap between what your Google reports show and what AI assistants tell buyers isn’t closing on its own. As generative AI adoption climbs past 20% inside enterprises, the brands that win won’t be the ones ranking for the most keywords. They’ll be the ones AI engines treat as the preferred source of truth.

    Start small. Pick a focused set of high-intent prompts, baseline them across the major models for a month, and watch where you appear and where you vanish. That single habit turns AI visibility from a thing you worry about into a channel you can measure and move.

    FAQ

    Q: What is AI prompt tracking analytics? 

    A: It’s the systematic monitoring of how a brand is mentioned, cited, or recommended in AI-generated answers across platforms like ChatGPT, Perplexity, and Google AI Overviews. Unlike keyword tracking, it follows the full natural-language prompts people actually ask and measures the probability of brand inclusion rather than a fixed ranking.

    Q: How much does AI prompt tracking analytics cost? 

    A: Pricing varies by coverage and prompt volume. Topify’s platform starts at $99 per month for the Basic plan with 100 tracked prompts, moves to $199 per month for Pro at 250 prompts, and offers Enterprise plans from $499 per month for teams that need dedicated support and higher limits.

    Q: What are the most common mistakes in AI prompt tracking analytics? 

    A: The frequent ones are chasing mention volume over citation authority, assuming one platform represents all of them, relying on a single snapshot despite AI answer volatility, and treating GEO as separate from SEO instead of building on the same trust signals.

    Q: How do I build a strategy for AI prompt tracking analytics? 

    A: Convert your highest-intent keywords into natural-language prompts, baseline them across at least three AI models for 30 days, audit why competitors get cited when you don’t, and restructure your content to be answer-first so models can extract it easily.

    Read More

  • AI Prompt Tracking: What It Is and How It Works

    AI Prompt Tracking: What It Is and How It Works

    Your team ranks on page one for the keywords that matter. Backlinks are solid, content is fresh, and Search Console looks healthy. Then a buyer skips Google entirely, opens ChatGPT, and asks for the best tool in your category. The model names five options. Yours isn’t one of them. Nothing in your SEO dashboard explains why, because those metrics were built to track links and rankings, not what an AI decides to say about you. That blind spot has a name: AI prompt tracking. Closing it starts with knowing exactly what these engines say about your brand when it comes up.

    What AI Prompt Tracking Actually Means

    AI prompt tracking is the practice of monitoring how your brand appears in AI-generated answers at the level of individual prompts, rather than at the level of keywords. A prompt is the actual question a person types into ChatGPT, Perplexity, or Google AI Overviews. Instead of asking “where do I rank for this keyword,” you ask “how does the model represent my brand when someone poses this question.”

    The shift matters because generative engines have decoupled visibility from blue links. Traditional search returned a ranked list, and tools like Google Search Console gave you data on impressions and clicks. Large language models work differently. They synthesize an answer, and they don’t hand you a dashboard showing how often your brand made it into that answer.

    That’s the observability gap most brands still can’t see.

    The scale of the change is hard to ignore. By August 2025, more than half of the US working-age population was using generative AI. As people lean on these engines for product research and recommendations, brands that never surface in AI responses face a silent loss of traffic, the kind traditional SEO metrics were never designed to detect.

    How Does AI Prompt Tracking Work

    At its core, prompt tracking replaces one-time snapshots with a repeatable measurement loop. The workflow has four moving parts.

    First, selection. You define a set of high-value prompts that reflect how real buyers describe their needs, things like “best e-commerce analytics tool” or “compare Brand X vs Brand Y.” These are your prompt clusters, the questions that decide whether you get discovered.

    Second, execution. Because AI responses are stochastic, meaning the same question can return different answers on different runs, you automate recurring queries across ChatGPT, Gemini, Perplexity, and AI Overviews. One run tells you almost nothing. Thirty runs across four platforms start to reveal a pattern.

    Third, parsing. For each response, you extract whether the brand was mentioned at all, where it landed in any ranked list, whether the AI gave a clickable citation to your domain, and how it described you.

    Fourth, aggregation. You roll those signals up over time to separate a lucky one-off from a consistent presence.

    Here’s a concrete example. Say you track the prompt “best e-commerce analytics tool” across four engines, twice a day for 30 days. That’s 240 data points for a single prompt. If your brand appears in 180 of them but earns a citation link in only 40, you’ve learned something specific: you have awareness, but not the source authority that drives referral traffic.

    Research on AI search points to a binary inclusion-exclusion dynamic, where a brand tends to be either prominently woven into the answer or left out entirely. Stability measures, such as the overlap between citation sets across runs, help you tell a stable source of truth apart from a stray mention.

    How to Measure AI Prompt Tracking

    Counting total mentions feels productive, but it’s a vanity metric. Useful measurement focuses on indicators that map to trust and traffic.

    MetricWhat it tracksWhy it matters
    Mention RateThe share of prompts where your brand appearsEstablishes whether you have any top-of-funnel presence
    Citation ShareHow often the AI links to your domain as a sourceValidates authority and drives referral traffic
    PositioningThe order your brand appears in AI-generated listsPredicts how likely a user is to trust and pick you
    Sentiment PolarityThe tone the AI uses, from “reliable” to “expensive”Measures brand alignment before anyone clicks

    The pattern to watch is the gap between mention rate and citation share. A high mention rate with low citation share means the AI knows you exist but doesn’t treat your site as the source worth linking. That’s usually a content and authority problem, not an awareness problem.

    Common Mistakes in AI Prompt Tracking

    Most tracking failures come from a handful of repeatable errors.

    Single-platform bias is the most common. Plenty of brands monitor only Google AI Overviews and assume the picture holds everywhere. It doesn’t. Models don’t share citation logic, so you can lead on Perplexity and stay invisible on Gemini.

    Then there’s the volume trap, where teams celebrate mention frequency while ignoring whether those mentions came with a citation link. A mention without a citation is brand awareness. It rarely moves traffic.

    Static monitoring is another. Running a prompt once a month treats a probabilistic system as if it were deterministic. You need aggregate data over time to know your true standing.

    The subtle one is attribution drift. AI engines often cite a source while misstating what that source actually says. So you track not just whether you’re cited, but what the model claims about you when it does.

    Choosing Software for Visibility That Tracks Prompts, Not Keywords

    You can run prompt tracking by hand in a spreadsheet, but it breaks down fast once you’re covering multiple platforms and dozens of prompts on a schedule. That’s where software for visibility earns its place, provided it treats AI visibility as a system to design rather than an audit to repeat.

    A few capabilities separate genuine prompt-tracking software from a dashboard that just counts mentions.

    CapabilityWhat to look for
    Multi-engine coverageIngests data across ChatGPT, Gemini, Perplexity, and AI Overviews, not one platform
    Prompt-level discoverySurfaces new, relevant prompts people are actually asking in your category
    Citation source analysisReports why the AI chose a given source, your page versus a competitor’s
    Executable insightsMoves you from “we got mentioned” to “we got mentioned because this page matched this intent”
    Competitor benchmarkingFlags displacement events, where a rival appears in your place

    This is the layer where Topify fits for teams managing AI visibility at scale. Its Visibility Tracking monitors how often your brand surfaces across major engines, while High-Value Prompt Discovery keeps finding new prompts worth tracking as the category shifts. In practice, that means you can spot a drop in ChatGPT mentions and trace it to a specific source that stopped citing you, inside one view rather than four browser tabs.

    On pricing, prompt-tracking platforms vary with how many prompts and AI answers you monitor. Topify’s plans start at $99 a month for around 100 tracked prompts and scale up from there for teams that need more prompts, projects, and seats. The practical question isn’t the sticker price. It’s how much unmeasured AI visibility is costing you in lost recommendations.

    How to Improve and Build a Strategy for AI Prompt Tracking

    Tracking is only useful if it changes what you do next. The strongest strategy for AI prompt tracking runs as a loop, not a report.

    Start by building a repository of category-defining prompts, the questions your buyers actually ask. Then analyze for displacement events, the prompts where a competitor shows up instead of you. Those are your clearest opportunities. Finally, act by aligning your site content with the claims and facts that lead AI engines to pick a source. If Perplexity keeps citing a competitor’s comparison page, that tells you what kind of content earns the citation.

    To improve results over time, treat citation share as your north star, not raw mentions. Re-test after every content change so you can attribute movement to a specific action. And widen your prompt set as the category evolves, because the questions buyers ask in six months won’t match today’s.

    When you’re ready to operationalize this, you can get started with Topify and let its agent handle the recurring queries and parsing.

    Track it. Analyze it. Act on it.

    Conclusion

    The buyer who asked ChatGPT for the best tool in your category isn’t coming back to check your Google ranking. AI prompt tracking exists to answer the one question your SEO dashboard can’t: when an engine speaks for your brand, what does it say, and how often does it say it. Pick a focused set of high-value prompts, measure citation share alongside mentions, run it across every engine that matters, and feed what you learn back into your content. The brands that close the observability gap first are the ones AI keeps recommending.

    FAQ

    Q: What is AI prompt tracking in simple terms? 

    A: It’s monitoring how your brand shows up in AI answers based on the actual questions people ask, instead of tracking keyword rankings. You watch whether the AI mentions you, links to you, and how it describes you across engines like ChatGPT and Perplexity.

    Q: How do you measure AI prompt tracking? 

    A: Focus on four metrics: mention rate (how often you appear), citation share (how often the AI links to your domain), positioning (where you land in AI-generated lists), and sentiment (the tone the AI uses). Citation share tends to matter most because it drives referral traffic.

    Q: Is there a checklist for getting started with AI prompt tracking? 

    A: A simple checklist works: define your high-value prompts, pick the engines your buyers use, run each prompt repeatedly rather than once, track mention rate and citation share over time, watch for competitor displacement, and re-test after content changes.

    Q: How much does AI prompt tracking software cost? 

    A: Pricing usually scales with the number of prompts and AI answers you monitor. Entry plans tend to start around $99 a month for a limited prompt set, with higher tiers for teams tracking more prompts across more projects and platforms.

    Read More

  • AI Response Monitoring Service: What It Tracks and Why

    AI Response Monitoring Service: What It Tracks and Why

    Your team spent six months building content, earning backlinks, and climbing Google rankings. Then a prospect opened ChatGPT, asked for the best option in your category, and got a tidy list of five names. Yours wasn’t one of them. Nothing in your analytics flagged it, because traditional metrics were never built to measure what AI chooses to say about you. That gap, between the search world you can see and the AI answers you can’t, is what an AI response monitoring service exists to close.

    What an AI Response Monitoring Service Actually Tracks

    An AI response monitoring service systematically analyzes how large language models and answer engines represent your brand across real user prompts. It’s not web ranking, and it’s not social listening. AI engines synthesize answers rather than return a list of links, so the unit of measurement shifts from “where does my page rank” to “what does the model say when someone asks.”

    That distinction matters more than it first appears.

    Counting how many times your name shows up is a vanity metric. It tells you nothing about whether you were recommended as a top choice or buried as a footnote, whether the model called you a market leader or a legacy option, or whether it linked to your content as a source. The useful signal lives in three layers: positioning, sentiment, and citation. A name that appears without a citation means the model knows you exist but doesn’t trust you enough to point to you.

    So a real monitoring service tracks the full picture: whether your brand appears, how it’s described, which competitors share the answer, and which sources the model cites to justify the response. The most reliable way to capture this is prompt testing across platforms like ChatGPT, Google AI Overviews, Perplexity, and Claude, since no single method gives you complete visibility on its own.

    How an AI Response Monitoring Service Works, Step by Step

    The mechanics are more structured than “ask the AI and screenshot it.” A working AI response monitoring service runs on prompt clusters, not keywords.

    First, you build a set of prompts that mirror how customers actually phrase intent: “best [product] for [use case],” “compare [brand A] and [brand B],” “alternatives to [competitor].” Then those prompts run across the major engines on a recurring schedule, often weekly. The system captures each response, extracts your brand’s position in the list, records the sentiment around it, and logs the exact sources cited.

    The last step is the one most teams skip: tracking change over time.

    AI answers are non-deterministic. Ask the same question twice and the wording shifts. A single screenshot is anecdote, not data. What you’re really measuring is the probability that your brand appears for a given prompt, and how that probability moves week to week. A monitoring service watches for displacement events, the moments a competitor enters an answer while you drop out, and ties those shifts back to something you can act on.

    The 7 Metrics That Show Whether You’re Visible to AI

    Knowing how to measure an AI response monitoring service is what separates a dashboard you check once from a system that drives decisions. Surface-level tools report mentions and stop. A measurement framework worth its cost spans seven dimensions.

    MetricWhat it answers
    VisibilityHow often you appear across tracked prompts and platforms
    MentionsWhere and in what context your name surfaces
    PositionAre you recommended first, or listed fifth
    SentimentDoes the model describe you favorably, neutrally, or as a fallback
    Share of VoiceYour presence in AI answers versus direct competitors
    Citation AuthorityHow often the model links to your site as the source
    CVRThe likelihood an answer pushes a user toward you

    These map onto what most research now treats as the three pillars of AI visibility: share of voice, citation authority, and sentiment positioning. The single most telling indicator is the gap between mentions and citations. If you’re named often but cited rarely, you haven’t earned enough authority to be the source of truth, and that gap is exactly where competitors quietly absorb the traffic.

    This is where a purpose-built platform earns its place. Topify tracks all seven metrics across ChatGPT, Gemini, Perplexity, and other major engines in one view, and its Source Analysis reverse-engineers the precise domains and URLs the models cite. In practice, that means you can spot a drop in ChatGPT mentions and trace it to a specific source that stopped referencing you, inside the same dashboard.

    5 Mistakes That Make AI Response Monitoring Useless

    Most teams don’t fail at monitoring because they pick the wrong tool. They fail because they measure the wrong things, or measure and never act.

    The volume trap. Prioritizing raw mention counts over citation authority. A high count with no citations means the model talks about you without trusting you.

    Static snapshots. A one-time check ignores the probabilistic nature of AI answers. You need recurring runs to see the trend, not a lucky screenshot.

    Chasing citations, ignoring mentions. In most commercial contexts, getting recommended by name moves the needle more than a linked footnote. Both matter, but teams that obsess over citations alone miss the recommendation that actually drives the deal.

    Treating GEO and SEO as silos. AI engines weigh the same trust signals as traditional search: editorial mentions, reviews, technical authority. A monitoring program disconnected from your SEO work duplicates effort and misses leverage.

    Ignoring localized context. AI responses vary by region. A brand that dominates US answers can be invisible in another market, and global-only reporting hides it.

    The common thread: data without action is theater. Monitoring is the input, not the outcome.

    From Tracking to Improvement: Turning Data Into Action

    A monitoring service only pays off when it closes a loop. The strategy is simple to describe and harder to sustain: detect the gap, fix the underlying signal, recheck.

    Detection comes from the metrics above. When a displacement event shows a rival winning a prompt you used to own, the next move is to look at what they’re citing and where your content falls short. Often the fix is structural: clearer answer-first formatting, stronger original data, better topical authority on the exact question being asked.

    Here’s the part most teams underestimate. You can verify AI-driven impact with first-party data. OpenAI already provides UTM referral tracking, so you can see real traffic arriving from AI tools in your own analytics. Pair that with recurring manual prompt checks and you have a measurement framework built on outcomes you can confirm, not scores a dashboard invented.

    This is where execution speed separates platforms. Topify’s One-Click Execution lets you state a goal in plain language, review the proposed GEO strategy, and deploy it without rebuilding a manual workflow each time. The point isn’t automation for its own sake. It’s shortening the distance between seeing a problem in the data and doing something about it.

    Tools vs. Best GEO Agencies: How to Choose and What It Costs

    Once you’ve decided to monitor AI responses seriously, the real question is who runs the program. Broadly, two paths exist: a self-serve platform your team operates, or one of the best GEO agencies handling it as a managed service.

    Neither is universally right. The trade-off comes down to control, speed, and budget.

    ApproachCoverage and depthExecutionTypical starting cost
    Self-serve platformYou control prompts, platforms, and reporting cadenceYour team acts on insights directlyOften $99 to $200 per month
    GEO agencyStrategy and reporting handled for youAgency executes, slower feedback loopFrequently several thousand per month

    A self-serve platform tends to suit in-house teams that want to own the data and move fast. An agency tends to suit brands that lack internal GEO capacity and prefer to outsource strategy, though it usually costs more and adds a layer between you and the dashboard. Several specialized monitoring platforms exist in this space, and a few agencies now offer GEO as a retainer service.

    Topify covers both models. Its self-serve plans start at $99 per month for Basic and $199 for Pro, with Enterprise from $499. For teams that want execution done for them, Topify also runs a managed service from $3,999 per month that bundles prompt monitoring with content production. The practical takeaway: you can start small, validate the data against your own analytics, and scale into managed execution only once the value is clear.

    Conclusion

    The brand left off that ChatGPT list rarely knows it happened. That’s the real cost of flying blind in AI search, and it’s the problem an AI response monitoring service was built to solve. Monitoring isn’t the finish line, though. The teams that win treat it as the first step in a loop that ends with action.

    Start with a baseline. Run a fixed set of customer-intent prompts across the major engines, measure where you stand on visibility, sentiment, and citations, then fix the weakest signal first. Get started with Topify to see your AI visibility baseline before your competitors widen the gap.

    FAQ

    Q: What is an AI response monitoring service in simple terms? 

    A: It’s a system that watches how AI engines like ChatGPT, Perplexity, and Google AI Overviews talk about your brand when people ask relevant questions. Instead of tracking page rankings, it tracks whether you’re mentioned, how you’re described, where you rank in the answer, and which sources the AI cites.

    Q: How do you measure it, and what’s a basic checklist? 

    A: A solid checklist covers seven things: visibility, mentions, position, sentiment, share of voice, citation authority, and conversion likelihood. Run a fixed prompt set across multiple platforms on a weekly cadence, watch the mention-citation gap, and connect shifts to first-party referral data so you’re measuring outcomes, not isolated screenshots.

    Q: What are some examples of AI response monitoring in practice? 

    A: Examples include tracking whether ChatGPT recommends you for “best tool for [use case],” checking how Perplexity describes your product’s positioning against a named competitor, and identifying which domains an answer engine cites when it leaves you out. Each example points to a specific content or authority fix.

    Q: What does AI response monitoring service pricing usually look like? 

    A: Self-serve monitoring platforms typically run from around $99 to a few hundred dollars per month depending on prompt volume and seats. Managed services and GEO agencies generally cost several thousand per month, since they bundle strategy, content, and execution alongside the tracking.

    Read More