Blog

  • Claude 4.7 vs 4.5: What Changed for Marketers

    Claude 4.7 vs 4.5: What Changed for Marketers

    Most model updates don’t require marketers to change anything. Claude 4.7 is different.

    Released on April 16, 2026, Claude Opus 4.7 introduced a “Hybrid Reasoning” architecture that doesn’t just generate smarter outputs. It changes how AI systems evaluate, cross-reference, and ultimately recommend brands to users. If your content strategy was built around Claude 4.5 or 4.6 behaviors, some of those assumptions no longer hold.

    Here’s what actually shifted, and what it means for your team.

    The Core Upgrade: From Generative to Hybrid Reasoning

    Claude 4.5 and 4.6 were generative models. They produced text by predicting what should come next. Claude 4.7 introduces what Anthropic calls “Adaptive Thinking,” a unified architecture where reasoning runs inside the model rather than as a separate post-processing step.
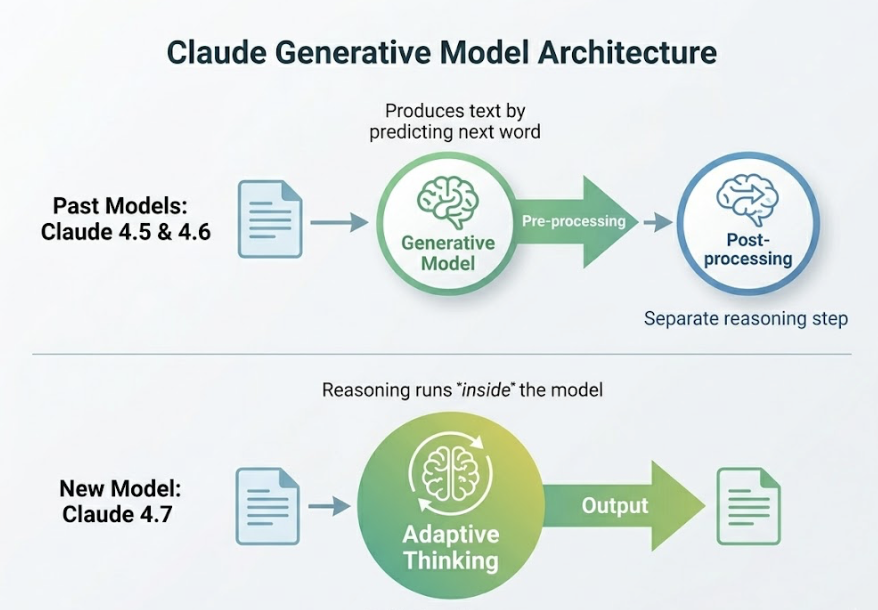
    In practice, this means Claude 4.7 can toggle between fast responses for simple queries and deep, multi-step reasoning for complex ones. The model doesn’t just write an answer. It checks its own logic before delivering it.

    For marketers, the downstream effect is significant: AI outputs are now more consistent, better at following complex briefs, and less prone to generating “confident but wrong” content.

    FeatureClaude 4.5/4.6Claude 4.7
    Context Window200,000 tokens (4.5) / 1M (4.6)1,000,000 tokens
    Reasoning ArchitectureGenerativeHybrid (Adaptive Thinking)
    Instruction FollowingInterprets “spirit” of promptLiteral, precise
    Self-VerificationManual (prompt-required)Built-in at “xhigh” effort level
    Visual Resolution~1.15 megapixels~3.75 megapixels

    The context window alone is worth noting. Claude 4.7 carries 1 million tokens into every session. That’s enough to load an entire brand content archive and maintain stylistic consistency across a full campaign, without resetting or chunking.

    Instruction Following Got More Literal. That’s a Double-Edged Change.

    This is the update most marketing teams will feel first.

    Claude 4.5 would often interpret the “spirit” of an ambiguous prompt. Ask for “a casual product description” and it would reasonably infer your tone preferences from context. Claude 4.7 doesn’t do that. It follows what you wrote, not what you meant.

    That’s not a flaw. It’s a design choice that removes a layer of unpredictability from high-volume automation.

    But it does require prompt audits. Prompts written for 4.5 often rely on the model’s ability to fill in unstated assumptions. Those prompts may return “flatter” results in 4.7: technically correct, creatively inert.

    The fix is straightforward. Use XML tags to separate instructions from content. Provide a positive example and a negative example. Specify formatting explicitly. Claude 4.7 rewards precision and returns proportionally better outputs when it gets it.

    This is a one-time adjustment. Teams that update their prompt libraries now will build a more stable, repeatable content production system in the process.

    Visual Reasoning Jumped 3x. Here’s Where That Matters.

    Claude 4.5 processed images at roughly 1.15 megapixels. Claude 4.7 handles up to 3.75 megapixels, a 3x increase in resolution support.

    The XBOW visual acuity benchmark reflects this directly: Claude 4.7 scored 98.5% versus 54.5% for Claude 4.6, a 44-point gap.

    For marketing workflows, this unlocks three practical capabilities:

    Creative asset auditing: You can now submit full Figma frames or high-resolution web screenshots for layout review. Claude 4.7 can catch small text legibility issues, spacing inconsistencies, and hierarchy problems that earlier models would miss.

    Dense document extraction: Complex charts, multi-series graphs, and financial tables can be accurately read and summarized. This is particularly useful for competitive intelligence reports or media performance reviews.

    Visual brand consistency checks: The model can compare a draft asset against a brand style guide with enough precision to flag icon placement and logo sizing that fall outside spec.

    None of this replaces a human designer. But it meaningfully reduces the manual review loop for teams producing high volumes of creative assets.

    The Cost Reality: Same Price, Potentially Higher Bill

    Anthropic kept the sticker price unchanged at $5/$25 per million input/output tokens for Opus 4.7. The catch is a redesigned tokenizer.

    The new tokenizer was built to improve multilingual handling for non-Latin scripts. As a side effect, the same volume of English text and code now tokenizes at roughly 1.1x to 1.35x the rate of the 4.5 era tokenizer. That’s an effective cost increase of 10% to 35% per task, without any change to the listed rate.

    For teams running high-volume content automation, that gap adds up.

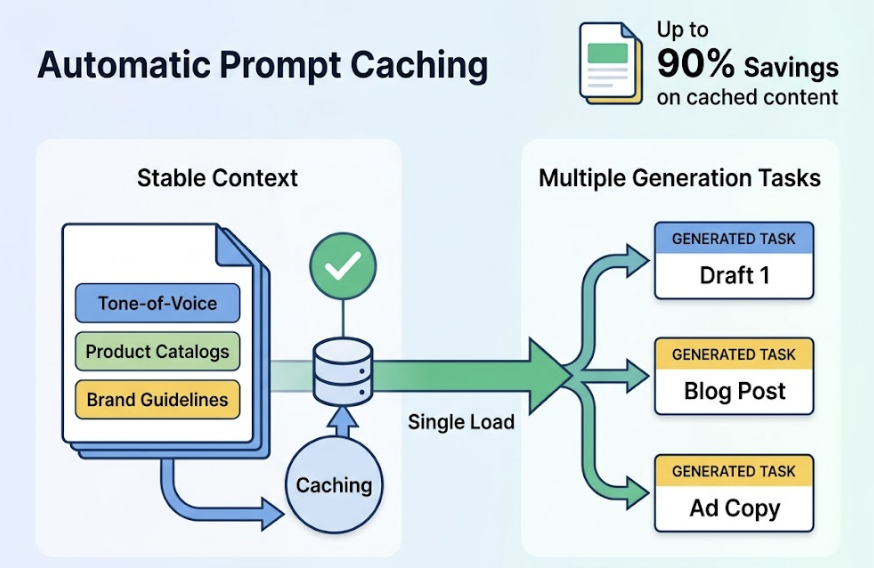
    The mitigating factor is Automatic Prompt Caching, introduced in early 2026. You can now cache large context blocks automatically as the conversation grows: tone-of-voice documents, product catalogs, brand guidelines. Anthropic reports up to 90% savings on cached content. Teams that structure their workflows to load stable brand context once, then run multiple generation tasks against it, can offset much of the tokenizer cost increase.
    How Claude 4.7 Changes Brand Recommendations in AI Search

    This is where the model upgrade stops being a tool question and becomes a visibility question.

    Claude 4.7 carries a higher “honesty” profile than its predecessors. It’s less prone to sycophancy: agreeing with users or making confident brand recommendations without strong third-party evidence. The model requires meaningful citation coverage before it will consistently recommend a brand in a professional context.

    In concrete terms, this means brands that were “riding” on weak AI visibility are now more exposed. Claude 4.7 cross-references third-party sources more rigorously. If your brand lacks coverage on authoritative forums, review platforms, or industry publications, it becomes harder for the model to include you confidently in a recommendation.

    That’s not a bug. It’s what “less hallucination” actually looks like from the brand side.

    Research suggests that 82% to 85% of AI citations come from third-party media, review sites, and community platforms, not from a brand’s own website. Claude 4.7’s improved reasoning means it relies on that third-party signal pool even more heavily than earlier versions.

    3 Things Marketers Should Adjust After Claude 4.7

    1. Audit your high-value prompt library.

    Prompts written for Claude 4.5 or 4.6 often depended on the model’s ability to “read between the lines.” Run your top 10 most-used automation prompts through 4.7 and compare outputs. Look specifically for where creative flair has been replaced by mechanical compliance. Add explicit tone guidance, use XML tags, and include formatting examples.

    2. Check which sources Claude 4.7 cites for your category.

    Use a GEO platform like Topify to reverse-engineer the sources Claude and other AI platforms are pulling when they discuss your brand’s product category. If competitors are being cited from sources you’re absent from (specific Reddit threads, niche review sites, industry blogs), that’s your earned media gap. Topify’s Source Analysis feature maps the exact URLs driving AI perception of your brand, so you can prioritize where to publish next.

    3. Set up visibility monitoring before the next model update.

    Claude 4.7 won’t be the last significant release this year. Each major update can shift “Model Drift,” where AI preference for a brand changes overnight due to updated internal weights. Topify’s Visibility Tracking monitors your brand’s mention rate across ChatGPT, Claude, Gemini, and Perplexity simultaneously, and flags unusual shifts in Sentiment Velocity before they affect conversion. Weekly monitoring is the minimum for a brand category with active competitors.

    Is It Worth Upgrading? The Honest Take

    Not every use case benefits equally from Claude 4.7.

    Use CaseRecommended ModelRationale
    High-volume content draftsSonnet 4.6Better speed-to-cost ratio
    Complex campaign briefsOpus 4.7Agentic persistence, consistent instruction following
    Brand sentiment monitoringOpus 4.7Superior reasoning for nuanced analysis
    Deep document QA (100k+ tokens)Opus 4.6Better recall accuracy above 100k tokens
    Competitive SEO researchOpus 4.7Loop resistance and tool-calling reliability

    For most marketing teams, a hybrid approach works best. Use Opus 4.7 for strategic tasks: research briefs, campaign architecture, and brand voice analysis. Use Sonnet 4.6 for execution-heavy volume work like social copy and email sequences.

    That’s not a compromise. It’s actually how Anthropic intends the model family to be used.

    Conclusion

    Claude 4.7 is not a minor iteration. The shift to Hybrid Reasoning, the 3x visual acuity improvement, and the stricter instruction fidelity represent a meaningful change in how AI processes and evaluates marketing inputs.

    The more important implication is at the brand recommendation level. A model that hallucinates less and cross-references more aggressively raises the bar for what it takes to appear in an AI-generated recommendation. That’s a GEO challenge as much as it is a content challenge.

    Brands that track their AI visibility systematically, and adjust their earned media strategy based on what the model is actually citing, are the ones that will hold their position as the reasoning quality of these models continues to improve. Tools like Topify exist precisely to make that monitoring systematic rather than reactive.

    The window to build that foundation before the next major release is now.


    FAQ

    Is Claude 4.7 significantly better than 4.5 for content marketing?

    Claude Opus 4.7 provides a meaningful upgrade in consistency and adherence to complex briefs. Its increased literalness may require more detailed prompting to achieve the creative range that was easier to access in 4.5. For marketers managing long-form content or complex multi-session campaigns, 4.7’s agentic persistence and 1M token context window make it the stronger choice for maintaining coherence across extended workflows.

    Does Claude 4.7 change how AI platforms recommend brands?

    Yes. Claude 4.7 has a higher “honesty” profile and better cross-referencing capability, which means it requires stronger third-party validation before confidently recommending a brand. Brands that were benefiting from weaker AI citation logic in earlier models may see their visibility shift.

    Should I update my prompts after switching to Claude 4.7?

    Yes. Prompts written for 4.5 or 4.6 often assumed the model would interpret unstated intent. Claude 4.7 follows instructions literally. Audit your prompt library and add explicit formatting requirements, XML tags, and positive/negative examples where you relied on implied context before.

    How do I measure if Claude 4.7 affects my brand’s AI visibility?

    Standard SEO tools are not built to track AI outputs. Use a GEO-specific platform like Topify to monitor your Share of Sentiment and brand mention rate across multiple AI platforms. Tracking Sentiment Velocity during the weeks following a major model release like Claude 4.7 is particularly important for catching early drift before it compounds.
    Read More

  • Agentic AI Has a Web. Your Brand Isn’t on It.

    Agentic AI Has a Web. Your Brand Isn’t on It.

    AI agents don’t search the way users do. They don’t browse your homepage, read your about page, or scan your pricing table. They pull from a trusted layer of citations, training data, and real-time references, and in seconds, they decide whether your brand exists.

    For most brands, the answer is: it doesn’t.

    This isn’t a traffic problem. It’s a structural one. And understanding why requires a clear look at what agentic AI actually does, and what it means when your brand isn’t part of the answer.

    Agents Don’t Browse. They Decide.

    The difference between a traditional AI search and an agentic AI isn’t just speed. It’s intent.

    Generative AI responds to questions. Agentic AI completes tasks. When a user asks ChatGPT “what’s a good project management tool for remote teams?”, they’re researching. When an AI agent is delegated that same decision with authority to book, compare, and recommend, it’s executing.

    That shift matters for brands because task-oriented agents don’t produce a list of results for the user to scroll through. They make a call. According to research on agentic behavior, the primary touchpoint for brand discovery is no longer a search results page. It’s the agent’s internal reasoning process, drawing on an AI trust layer built from training data, real-time citations, and memory.

    If your brand doesn’t appear in that reasoning, it doesn’t appear at all.

    There’s a New Layer Between Your Brand and Your Buyers

    Think of it as the neural intermediation layer: a system sitting between your marketing assets and your potential customers, built from three sources that most brand teams have never optimized for.

    The first is parametric memory, the foundational knowledge baked into a model during training. If your brand didn’t appear in authoritative content before the model’s training cutoff, you start at a deficit.

    The second is retrieval-augmented generation (RAG), the “live” citation layer where agents pull real-time data to ground their answers. This is where most discovery happens in 2026. The third is agent memory, the persistent understanding of a specific user’s preferences and prior brand interactions.

    Traditional SEO doesn’t touch any of these layers. Ranking for a keyword doesn’t guarantee that an AI cites you. Having a fast site doesn’t mean an agent can process what you offer. This is why brands with strong Google presence are often completely invisible to agentic systems.

    The goal is no longer to rank. It’s to be characterized accurately and cited consistently.

    Why 95% of B2B Brands Are Invisible to Agentic AI

    The number isn’t exaggerated. The 2026 2X AI Visibility Index found that 95.7% of B2B companies are invisible during the earliest stages of AI-driven buyer discovery. These brands only appear when a buyer already knows their name. They’re absent from the AI-generated shortlists that define entire categories.

    There are three structural reasons this happens:

    Content built for humans, not machines. Most brand content is narrative and keyword-heavy. AI systems prioritize content that’s “retrieval-ready”: chunked, front-loaded with direct answers, and high in fact density. A wall of text that ranks on Google may never be cited by a language model.

    No third-party consensus. AI models behave like risk-averse analysts. They cite sources where multiple independent sites agree on a brand’s core attributes. Brands with strong owned content but thin review ecosystems and limited independent mentions get ignored.

    Technical friction. Site performance directly affects citation rates. Research shows that pages with a Largest Contentful Paint over 4 seconds face a citation penalty of up to 72%. Pages with high Cumulative Layout Shift face similar suppression.

    The deeper issue: most brands don’t even know which of these problems applies to them, because traditional analytics tools can’t see what’s happening inside AI responses.

    What “Having a Page” on the Agentic Web Actually Means

    In the era of AI agents, brand presence isn’t about URLs. It’s about existing accurately and prominently in the AI’s answer share.

    That presence has three dimensions.

    Visibility measures how often your brand appears in AI-generated responses across a target set of prompts. It’s not just about being mentioned. Position matters. Being named first in a three-option list carries significantly more weight than being third, a phenomenon driven by the primacy effect that Topify’s Position-Adjusted Word Count (PAWC) model is built to track.

    Sentiment tracks how the AI describes you. A brand that gets mentioned but is consistently framed as “expensive” or “limited” can have high visibility and low conversion. Sentiment scoring on a 0-100 scale catches AI hallucinations and outdated characterizations before they erode pipeline.

    Source analysis reveals which URLs and domains the AI is actually citing to support its recommendation. Often, the AI isn’t citing your own site. It’s pulling from a competitor’s blog, a three-year-old forum thread, or a niche review platform you’ve never prioritized. Understanding these citation gaps is the first step to closing them.

    Topify tracks all three dimensions across ChatGPT, Gemini, Perplexity, and other major AI platforms, giving brand and marketing teams a structured view of exactly how they exist in the AI trust layer.

    The Brands That Agents Already Trust

    The brands that have successfully built presence on the agentic web share a common characteristic: they are structurally unambiguous.

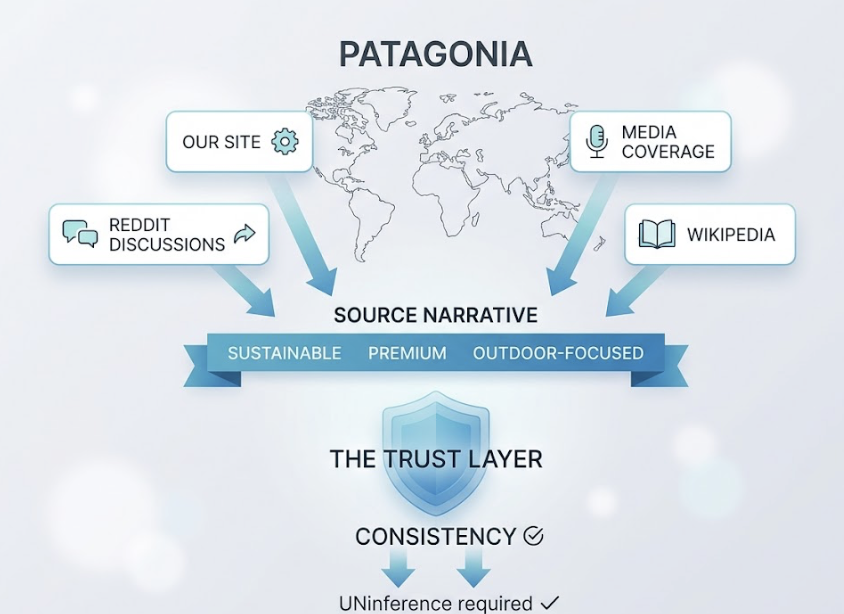
    Consider how Patagonia is characterized across AI responses. Every source, its own site, media coverage, Reddit discussions, Wikipedia, consistently reinforces the same narrative: sustainable, premium, outdoor-focused. That consistency allows language models to confidently recommend Patagonia when a user’s agent is looking for “sustainable outdoor gear.” There’s no inference required. The answer is already in the trust layer.

    The same principle applies in B2B. Research across 1.2 million ChatGPT answers shows that brands with active community discussions on platforms like Reddit are cited more than three times as often as brands without community presence. Real-time engines like Perplexity weight community validation heavily because it signals that a brand’s reputation isn’t just marketing copy.

    The common thread isn’t budget or brand size. It’s consistency of characterization across independent sources, combined with content that machines can actually extract and use.

    How to Start Building Your Presence on the Agentic Web

    There’s a three-step framework that holds up across verticals: Diagnostic, Positioning, Execution.

    Step 1: Run a diagnostic audit. Before optimizing anything, you need to know your current answer share. That means mapping out not a keyword list, but a prompt universe of 150-300 questions that real users ask AI when researching your category. Topify’s AI Volume Analytics surfaces high-volume AI prompts that don’t even register in traditional SEO tools, because they’re being asked in chat interfaces, not search bars. The gap between what users type in Google and what they ask ChatGPT is larger than most teams expect.

    Step 2: Restructure content for machine reasoning. GEO-optimized content isn’t just a style preference. Research from Princeton and other institutions shows that content using structured strategies like “answer-first format,” added statistics, and explicit citations can boost AI citation frequency by 30% to 115%. The practical changes: break long-form content into self-contained 200-400 word sections, front-load each page with a direct 40-60 word answer capsule, and increase fact density with specific numbers, dates, and expert quotes.

    Step 3: Fix the technical layer. Two steps have outsized ROI. First, implement an /llms.txt file in your site’s root directory. This Markdown-formatted file strips away HTML noise and acts as a direct cheat sheet for AI crawlers, reducing the computational cost of processing your content. Second, adopt robust Schema.org markup for Organization, Brand, and Product. This “entity disambiguation” links your brand name to specific qualitative traits in the vector space agents reason through.

    If your audience uses ChatGPT or Microsoft Copilot, adopting OpenAI’s Agentic Commerce Protocol (ACP) gives agents the ability to interact with your services directly. Google’s Universal Commerce Protocol (UCP) covers the broader transaction lifecycle across any AI surface.

    None of these steps require a full content overhaul. Most brands can close the most critical gaps in 60-90 days with focused execution.

    Conclusion

    The agentic web isn’t a future scenario. It’s the current operating environment for an increasing share of buyer discovery, and the brands that treat it as a waiting problem are already falling behind.

    The logic is simple: if an AI agent is making a recommendation and your brand isn’t in its trust layer, the user never hears your name. Not because you lost the comparison, but because you weren’t part of the reasoning at all.

    Visibility, sentiment, and source analysis are the new metrics that matter. The /llms.txt file and Schema markup are the new technical fundamentals. And prompt universe mapping is the new keyword research.

    The infrastructure of how AI agents discover, evaluate, and recommend brands is being built right now. Getting your brand onto that infrastructure is still early-mover territory.

    FAQ

    What’s the difference between agentic AI and regular AI search?

    Regular AI search synthesizes an answer to a question. Agentic AI executes multi-step tasks using external tools. An AI search might list three project management tools. An agentic AI might evaluate them against your team’s requirements, check pricing, and initiate a trial. The brand selection happens before the user sees anything.

    How does a brand know if it’s being recommended by AI agents?

    Standard analytics tools like GA4 can’t track what happens inside AI models. The internal “hidden” responses that drive agent recommendations are invisible to traditional dashboards. Brands need purpose-built diagnostic tools to simulate user prompts and track Answer Share and Position Rank across platforms like ChatGPT, Gemini, and Perplexity. Topify’s Visibility Tracking does this across major AI platforms with seven core metrics.

    Does GEO content optimization actually move the needle for agentic systems?

    Yes, with caveats. The optimization strategies that work for generative AI search (answer-first structure, fact density, source citations) also improve agentic citation rates because agents draw from the same underlying models. The difference is that agentic systems place more weight on technical accessibility and third-party verification than on content volume alone.

    Should brands block AI crawlers to protect their content?

    Generally, no. Blocking training bots like GPTBot prevents a brand from entering the model’s parametric memory. That means the AI won’t know the brand exists at a foundational level. The better approach is to guide agents using /llms.txt and structured protocols toward the most accurate, high-value information rather than blocking access altogether.

    What’s the single most impactful step a brand can take this week?

    Run a prompt audit. Identify 20-30 high-intent prompts in your category and run them through ChatGPT, Gemini, and Perplexity. Track whether you’re named, where you appear, and how you’re described. That baseline alone will reveal more about your agentic web presence than a year of traditional SEO reporting.

    Read More

  • How Agentic AI Changes Brand Visibility Tracking

    How Agentic AI Changes Brand Visibility Tracking

    You asked ChatGPT to recommend a project management tool for remote teams. It returned three names. Yours wasn’t one of them.

    That’s not a content gap. That’s not a keyword problem. That’s the result of how agentic AI decides which brands are worth recommending — and most marketing teams still don’t have a system to measure it.

    Agentic AI Doesn’t Just Search. It Decides.

    Traditional search engines work like librarians. They index content, match keywords, and hand you a list. You do the evaluation.

    Agentic AI works differently. It enters a multi-step reasoning loop: it breaks down your query into sub-tasks, pulls data from multiple sources, evaluates the evidence for confidence, and synthesizes a single answer. There’s no list of links for the user to sort through. There’s just a recommendation.

    That shift matters enormously for brands. When a user asks, “Which CRM is best for a mid-market manufacturing firm?” an agentic system doesn’t return 10 results — it returns one or two names it’s judged to be most credible. If your brand isn’t part of that judgment, you don’t get a fallback position. You’re simply not in the answer.

    The gap between traditional search and agentic AI isn’t about design preferences. It’s architectural.

    DimensionTraditional SearchAgentic AI
    RoleInformation indexerResearch analyst
    LogicKeyword matchingSemantic reasoning
    OutputList of linksSynthesized answer
    RetrievalSingle-pass indexingIterative sense-decide-act loop
    User actionClicks to decideAgent has already decided

    The 3 Signals Agentic AI Uses When Evaluating Your Brand

    Agentic AI doesn’t have preferences. It follows patterns. And those patterns are shaped by three measurable signals.

    Mention Frequency. LLMs are trained on statistical density. If your brand appears frequently in high-quality, relevant discussions — Reddit threads, industry journals, news coverage — the model builds a strong semantic link between your name and your category. Crucially, unlinked mentions carry nearly as much weight as linked ones. Unlike Google’s PageRank logic, LLMs analyze patterns across the whole web, not just backlink graphs.

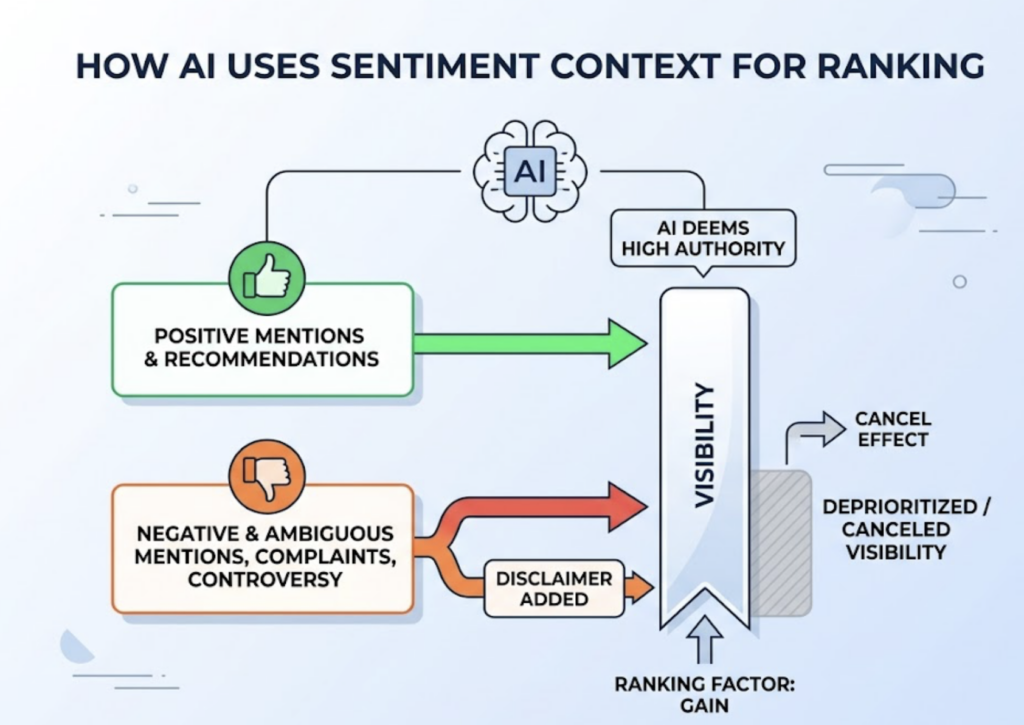
    Sentiment Context. Being mentioned isn’t enough. The AI classifies the tone surrounding each mention. A positive recommendation scores high; a negative or ambiguous mention can effectively cancel visibility gains. If your brand’s historical footprint includes unresolved customer complaints or controversy on forums, the model will either deprioritize you or add disclaimers. Your reputation isn’t just a brand metric — it’s a ranking factor.

    Source Authority. Agentic systems minimize hallucination by grounding responses in trusted sources. Research shows brands are 6.5 times more likely to be cited through third-party platforms like G2, Wikipedia, or reputable industry publications than through their own websites. If your narrative only lives on your own domain, the AI assigns it a low confidence score.

    These three signals compound. High frequency + positive sentiment + authoritative third-party coverage = a brand the AI recommends confidently. Miss one, and you’re in the “sometimes mentioned” category. Miss two, and you’re invisible.

    Why Strong Google Rankings Don’t Guarantee AI Visibility

    This is the assumption that catches most teams off guard.

    An Ahrefs analysis of 1.9 million AI citations found that only 12% of those citations matched Google’s Top 10 results for the same query. More striking: 80% of AI citations don’t rank anywhere on Google for the original search term.

    The systems prioritize different things. Google weights backlinks, page speed, and keyword placement. Agentic AI weights what researchers have formalized as “Semantic Completeness” and “Extractability” — basically, can the AI parse your content quickly and confidently?

    Here’s a real pattern that illustrates this: a law firm ranked #1 on Google for “personal injury lawyer Miami” — a position built on a DA 80 domain and decades of link-building. In ChatGPT, it received zero mentions. Smaller boutique firms with Reddit discussions and “Best of” mentions on niche legal blogs got recommended instead. Their content was structured for AI extraction; the high-DA firm’s content was structured for crawlers.

    SignalGoogleAgentic AI
    Primary currencyBacklinks & domain authorityMentions & digital consensus
    Content structureLong-form narrativeExtractable chunks, answer-first
    LogicLexical stringsSemantic entities
    OutcomeClick-through trafficCitation & recommendation

    Agentic AI is computationally “lazy” in a specific way: it favors sources that deliver a clean 40-60 word definition or fact over sources that require it to synthesize across paragraphs. If your content makes the model work harder to extract an answer, it’ll pull from a source that doesn’t.

    A Step-by-Step Look at How Brand Visibility Tracking Actually Works

    Because AI responses are probabilistic — they vary by session, user context, and model version — static audits don’t work. You need continuous probability mapping. Here’s the methodology that holds up.

    Step 1: Define the prompts AI users actually ask.

    Don’t track your brand name. That’s a bottom-funnel vanity metric. Real discoverability happens when you appear in unbranded, category-level queries. Build a prompt library across three types:

    • Category prompts: “What are the best [category] tools for remote teams?”
    • Comparison prompts: “Tool A vs. Tool B for mid-market security”
    • Problem-solution prompts: “How to reduce infrastructure costs for a SaaS startup”

    Step 2: Run those prompts across multiple AI platforms.

    ChatGPT, Gemini, and Perplexity don’t agree. There’s only an 11% overlap between sources cited by ChatGPT and Perplexity for the same query. Each platform has its own retrieval bias: ChatGPT favors authoritative encyclopedic sources; Perplexity rewards freshness and community validation; Gemini leans on Google’s Knowledge Graph. A brand invisible on one may be prominent on another.

    Step 3: Measure visibility rate, position, and sentiment per platform.

    A single check is a data point. Running the same prompt 100 times gives you a confidence interval. Your brand might appear in 34% of ChatGPT responses but 61% of Perplexity responses. That’s a strategic insight, not a coincidence.

    Three numbers matter here: Visibility Rate (raw probability of being mentioned), Position in Response (brands in the first three positions carry 4-5x more recall weight than later mentions), and Sentiment Score (is the AI recommending you or just listing you?).

    Step 4: Identify the sources the AI is citing.

    Reverse-engineer the footnotes. Find the exact URLs the AI’s retrieval layer treats as authoritative for your category. If a competitor is winning citations because of a specific Reddit thread or a pricing guide on a third-party review site, that’s your next content target.

    Step 5: Close the gap with targeted actions.

    If your Visibility Rate is low but your Google ranking is strong, the problem is extractability. Restructure your content with clear headings, answer-first architecture, and structured data tables. If visibility is low because of missing third-party coverage, build it: guest contributions, G2 profiles, community presence on the platforms the AI trusts.

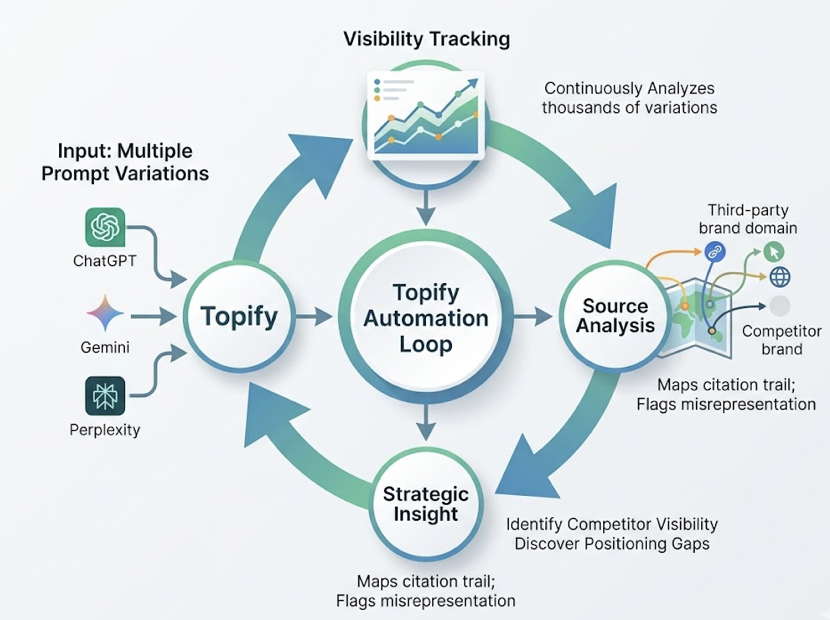
    Topify automates this entire loop. Its Visibility Tracking continuously analyzes thousands of prompt variations across ChatGPT, Gemini, and Perplexity simultaneously — without manual testing. The Source Analysis feature maps the citation trail automatically, identifying which third-party domains are carrying competitor visibility and flagging positioning gaps where your brand is being misrepresented or underrepresented.

    The Metrics That Actually Matter in an Agentic AI World

    Most marketing dashboards weren’t built for this environment. Clicks, impressions, and bounce rates don’t capture whether an AI recommended you or ignored you.

    MetricWhat It MeasuresPriority
    AI Visibility Rate% of relevant prompts where your brand appears⭐⭐⭐ High
    Position in Response1st mention vs. 4th — predicts decision influence⭐⭐⭐ High
    Source Citation RateHow often AI cites your domain vs. third-party sources⭐⭐⭐ High
    Sentiment ScorePositive / neutral / negative mention context⭐⭐ Medium
    Branded Search LiftIncrease in branded searches after AI-driven discovery⭐⭐ Medium
    ❌ Keyword RankingTraditional Google positionLow

    Keyword ranking isn’t worthless. It still supports bottom-funnel conversions when someone’s looking for your checkout page. But it’s a poor predictor of whether you’ll make it into the AI’s initial recommendation set.

    That’s the metric shift the “Answer Economy” requires.

    What Optimization Looks Like When You Have the Data

    The data tells you which problem you actually have. Two scenarios illustrate this clearly.

    High Sentiment, Low Visibility. Your Sentiment Score is strong — the AI describes your brand as “innovative” and “reliable” — but your Visibility Rate sits at 8%. The diagnosis: the AI likes you, but can’t find enough evidence across its retrieval sources to mention you consistently. It’s an exposure gap, not a reputation gap. The fix is building third-party consensus: guest mentions on industry blogs, updated G2 reviews, presence in the Reddit communities the AI’s retrieval layer trusts.

    High Visibility, Low Position. Your brand appears in 70% of relevant AI answers but consistently lands 3rd or 4th in the list. The AI knows you exist but treats you as a secondary option. To move up, you need what practitioners call “Information Gain” — proprietary research, case studies with quantified outcomes, or named frameworks that give the AI a definitive data point it can quote as ground truth.

    The operational challenge is what happens after the diagnosis. Most teams stall here because executing content changes across multiple platforms and formats takes time. Topify’s One-Click Agent Execution addresses this directly: once a visibility gap is detected, the platform’s AI agent analyzes content gaps against competitor citations, drafts GEO-optimized content including schema markup and data tables, and deploys directly to your CMS. Brands using this execution model report a 920% lift in AI-driven traffic compared to teams relying on manual optimization cycles.

    The sense-decide-act loop isn’t a metaphor. It’s how optimization actually runs in 2026.

    Conclusion

    Agentic AI doesn’t recommend brands because they have good products. It recommends them because they’re the most “legible” and “verified” solutions within its reasoning space.

    That means visibility is measurable. It’s not luck, and it’s not a black box. Mention frequency, sentiment context, and source authority follow patterns you can track, benchmark, and close gaps against.

    The brands that figure this out first aren’t just winning AI recommendations. They’re setting the consensus that everyone else gets measured against.


    Frequently Asked Questions

    What is agentic AI in the context of brand visibility? Agentic AI refers to AI systems that autonomously plan, retrieve information, and synthesize answers — rather than returning a list of links. For brands, this means the AI is actively deciding whether to recommend you based on your presence in its training data and retrieval sources.

    How is AI brand visibility different from traditional SEO rankings? Traditional SEO optimizes for crawler-readable content and backlink authority. AI visibility depends on mention frequency, sentiment context, and third-party source coverage. Research shows only 12% of AI citations match Google’s Top 10 results for the same query — the two systems are largely measuring different things.

    Which AI platforms should I track my brand on? At minimum: ChatGPT, Perplexity, and Gemini. Each uses different retrieval logic and cites different sources. There’s only 11% source overlap between ChatGPT and Perplexity responses — tracking just one gives you an incomplete picture.

    How often should I run brand visibility tracking? AI responses are probabilistic and shift with model updates, so continuous monitoring beats periodic audits. Running the same prompts 100 times across platforms gives you a statistically reliable confidence interval rather than a single data point.


    Read More

  • Agentic AI Tools for Marketers: What They Miss

    Agentic AI Tools for Marketers: What They Miss

    Your agentic AI dashboard looks great. Mentions are up. Prompt coverage is green. And yet, somewhere in your funnel, qualified buyers who asked ChatGPT for a recommendation never made it to your site.

    That’s the gap most marketing teams don’t see until it’s too late.

    Agentic AI tools have fundamentally changed what’s possible in brand monitoring. But the tools that excel at tracking activity often leave out the metrics that drive revenue. Understanding the difference between the two is the most important diagnostic question a marketer can ask in 2026.

    What Agentic AI Actually Does for Marketing Teams

    An agentic AI tool doesn’t wait for instructions. It monitors, decides, and acts.

    Where traditional marketing automation runs on “if-then” decision trees, agentic systems use probabilistic reasoning to navigate uncertain environments. A traditional tool sends a welcome email when a trigger fires. An agentic tool tracks competitor pricing shifts, detects sentiment drifts in third-party reviews, spots a content gap across AI platforms, and initiates a content response, all without a human setting each step.

    In a marketing context, this plays out in real use cases: a listener agent monitors AI-generated answers for brand mentions, a creator agent drafts tailored assets based on what buyers are asking, and a deployment agent pushes updates to the content pipeline. The cycle is continuous, not batch-processed.

    That shift matters because consumer discovery has moved. Search volume is rising, but clicks to websites are declining as AI-generated summaries resolve queries without ever sending a user to a brand page. Marketers who rely solely on traditional tools are missing the layer where AI shapes preferences before a website visit happens.

    The 4 Things Agentic AI Tracking Does Well

    These tools have genuine strengths. It’s worth being clear about where they actually deliver.

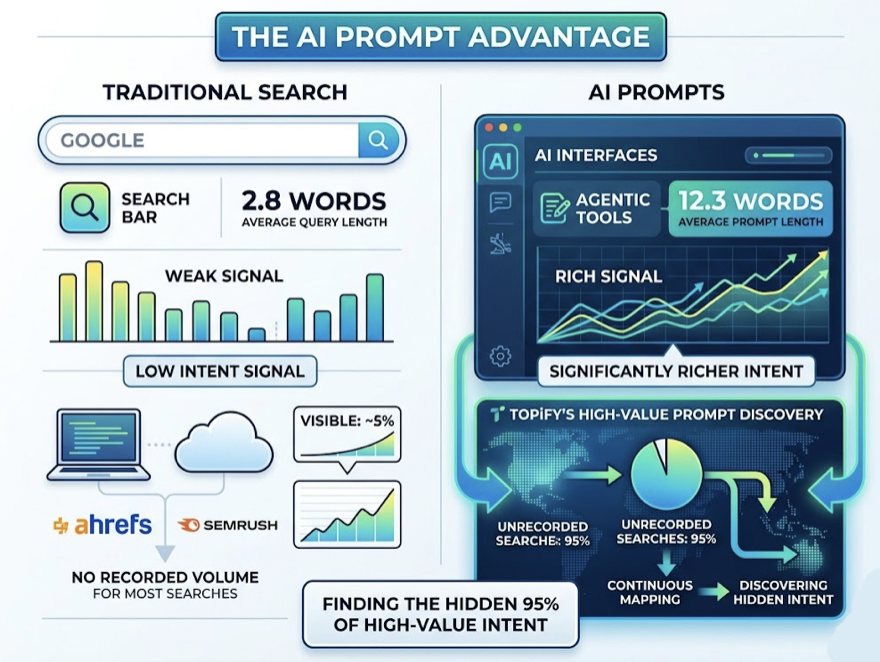
    Prompt frequency and volume. Agentic tools surface how buyers are asking questions in AI interfaces, not search bars. The average AI prompt runs 12.3 words versus Google’s 2.8, which means the intent signal is significantly richer. Topify’s High-Value Prompt Discovery continuously maps these prompts, including the 95% that have no recorded search volume in traditional SEO tools like SEMrush or Ahrefs.

    AI Visibility Rate. This measures what percentage of AI-generated responses for a target prompt set include your brand. Average brand visibility sits at 0.3%, while leaders in competitive SaaS categories reach 59.4%. Tracking this number is the baseline for any serious GEO strategy.

    Competitor benchmarking in AI answers. Unlike traditional search, where competitors appear in a vertical list, AI engines cluster brands by semantic relevance. Agentic monitoring shows which rivals are consistently recommended alongside or instead of you, including niche aggregators that don’t rank on the first page of Google.

    Citation source tracking. Because 85% of brand mentions in AI-generated answers come from third-party domains, knowing which URLs are driving a competitor’s visibility is as valuable as knowing your own citation rate. Agentic tools track which platforms (Reddit, G2, Trustpilot) are feeding the model’s recommendations.

    These four capabilities are genuinely useful. They’re also incomplete.

    The 3 Gaps That Undermine Your Agentic AI Stack

    Most tools track whether you’re showing up. Few track how you’re showing up, or what happens next.

    Gap 1: Sentiment Polarity

    Tracking mentions without tracking sentiment is like counting impressions and ignoring click-through rate.

    AI models don’t just list brands. They characterize them. A brand with a high visibility score might be described as “an outdated solution” or “prone to support issues,” which actively works against conversion. Google AI Overviews are 44% more likely to surface negative brand sentiment than ChatGPT. If the language framing is neutral or negative, that brand is structurally ineligible to win “best-of” queries regardless of how often it appears.

    Topify’s Sentiment Analysis scores brand sentiment on a 0-100 scale across platforms, so teams can see not just that they were mentioned, but whether the AI is positioning them as a recommended option or a cautionary example.

    Gap 2: Position Within the Answer

    Being mentioned fifth in a recommendation is not the same as being mentioned first.

    In a conversational interface, position signals the model’s confidence and determines where the user’s attention lands. Research shows 44.2% of AI citations are drawn from the first third of a page’s content, and brands appearing in the initial summary capture the majority of the trust transfer from AI to buyer. The challenge is that AI responses are probabilistic: a brand might be first in 40% of responses and fifth in the other 60%. Without position tracking, you can’t see the distribution.

    Topify’s Position Tracking monitors where your brand lands relative to competitors across each target prompt, giving teams the data to understand whether they’re consistently leading the answer or drifting toward the footnotes.

    Gap 3: The Conversion Signal

    This is the gap that makes the other two feel manageable by comparison.

    Traditional analytics tools are structurally blind to AI interactions. The engagement happens on the AI platform’s servers, not your website. But the traffic that does arrive from AI referrals converts at 14.2%, compared to 2.8% for Google organic. That’s a 5x advantage. AI search traffic also generates $47 revenue per visit against $9 for Google search.

    Without tracking what happens after an AI recommendation, marketers can’t close the loop between visibility and pipeline. Topify’s Conversion Visibility Rate (CVR) connects AI discovery to downstream funnel signals, giving teams a way to prove that GEO investment is translating into high-value leads.

    Why These Gaps Get Worse Over Time

    Missing sentiment and position data isn’t a static oversight. It compounds.

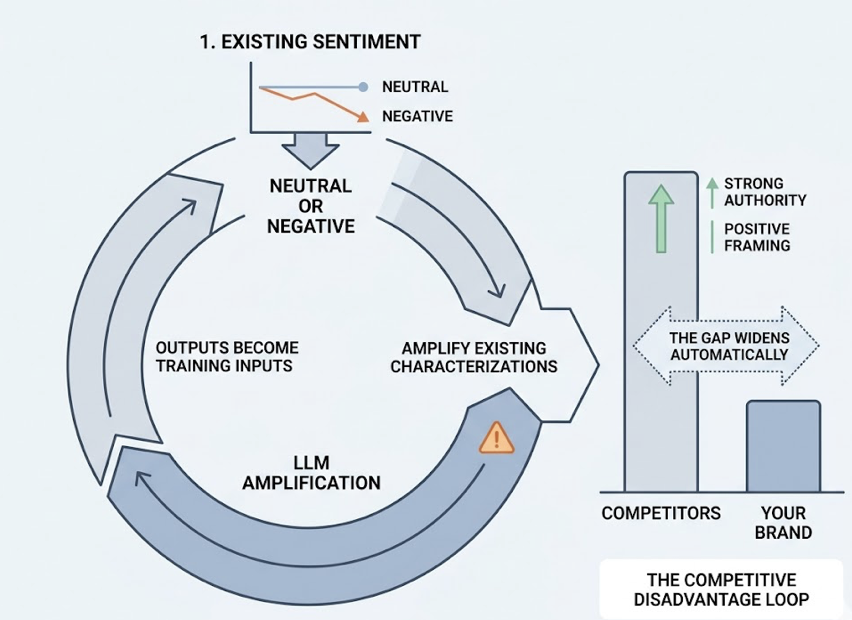
    Large language models operate through reinforcement feedback loops. Outputs are fed back as training inputs, which means existing characterizations get amplified with each model update. If a brand’s sentiment is consistently neutral or negative, the model’s internal probability weights progressively favor competitors with stronger authority signals and positive framing. The gap widens automatically.

    This effect is especially acute in B2B, where AI search queries average 12.3 words and the model typically returns only 2-3 curated solutions rather than a page of ten links. Being left off that shortlist isn’t a ranking problem. It’s binary exclusion.

    The math on CTR reinforces this. Even a brand that ranks #1 in traditional SEO can see its click-through rate drop by 47% if an AI summary resolves the user’s query without sending them anywhere. AI visibility within the answer is the only defensible KPI for top-of-funnel protection.

    That’s not a future risk. It’s the current condition.

    A 3-Layer Tracking Framework That Covers the Full Picture

    Moving from passive monitoring to strategic execution requires a structure that connects technical visibility to brand quality and revenue. Topify’s seven core metrics (visibility, sentiment, position, volume, mentions, intent, and CVR) map directly onto three tracking layers.

    Layer 1: Visibility. Are you showing up at all? This layer tracks prompt coverage and AI Visibility Rate across ChatGPT, Gemini, and Perplexity. If a brand is absent from 90% of relevant prompts, it signals a structural content problem or a failure in how the retrieval-augmented generation process is pulling brand information.

    Layer 2: Quality. How are you showing up? This layer audits sentiment polarity and position within the answer. It identifies whether the AI is framing your brand as a market leader or a niche fallback, and which third-party domains are influencing that framing. Topify’s Source Analysis reverse-engineers the exact citation sources shaping the model’s characterization.

    Layer 3: Impact. What happens after? This connects AI discovery to CVR and pipeline signals. Buyers who find a brand through AI move 73% faster to a purchase decision than those coming from Google. Tracking this layer is how GEO investment gets defended in a budget conversation.

    Each layer is necessary. Running only Layer 1 is like tracking email deliverability without tracking opens or clicks.

    How to Audit Your Agentic AI Setup Now

    This doesn’t require a full platform overhaul. A structured audit cycle surfaces the gaps quickly.

    Step 1: Map your high-value prompts. List the natural-language questions your buyers are likely asking AI interfaces during discovery. Traditional keyword tools don’t capture this; you need an intelligence layer that sees actual prompt frequency inside AI platforms. Topify’s High-Value Prompt Discovery automates this and surfaces emerging prompts as they shift.

    Step 2: Run cross-engine benchmarking. Test each prompt across ChatGPT, Gemini, and Perplexity separately. Platform-specific biases are real: Perplexity tends to favor niche expertise and citation depth, while Gemini has grown 388% year-over-year and integrates tightly with Google’s search ecosystem. What surfaces on one platform won’t always match another.

    Step 3: Audit narrative framing. For each prompt where your brand appears, check the characterization. Is the AI citing your documentation? A G2 review? A Reddit thread from 2022? The source shapes the framing. Topify’s Source Analysis identifies exactly which domains are feeding the model’s description of your brand.

    Step 4: Map gaps to execution. Identify where your brand is missing, characterize the cause (content gap, citation gap, or sentiment signal), and deploy targeted fixes. Topify’s AI Agent can identify a citation gap, propose a content restructure, and deploy to the CMS with one click, closing the loop from insight to action without a manual handoff.

    Conclusion

    Agentic AI tools are only as good as what they’re measuring. If your stack tracks activity but not outcomes, you’re flying with half the instruments.

    The financial stakes are documented: cited brands receive 35% more organic clicks and 91% more paid clicks. AI traffic converts at 5x the rate of Google organic. Missing from the AI’s recommended shortlist isn’t a visibility problem. It’s a revenue problem.

    The shift from “are we mentioned?” to “how are we characterized, where do we rank in the answer, and what do buyers do next?” is the difference between a monitoring stack and a growth strategy. Building toward Topify and a full 3-layer framework is how marketing teams close that gap before the compounding effect works against them.


    FAQ

    What’s the difference between agentic AI and regular AI tools?

    Regular AI tools are task-specific and reactive. They wait for a human to set a trigger, then execute a narrow instruction. Agentic AI is goal-oriented and autonomous: it can plan multi-step workflows, reason across platforms, and initiate actions independently to pursue a broader objective like managing brand visibility across multiple AI engines.

    Which AI platforms should marketers track in 2026?

    At minimum: ChatGPT for volume, Gemini for its 388% year-over-year growth and Google ecosystem integration, and Perplexity for B2B and research-heavy segments where citation accuracy drives trust. Claude traffic converts at 16.8%, making it essential for high-intent niches despite lower overall volume.

    How do I know if my brand’s AI sentiment is hurting conversions?

    Monitor your Sentiment Polarity score across high-intent queries. If AI engines consistently describe your brand with negative qualifiers or place a competitor first despite your brand appearing in the same answer, sentiment is likely causing buyers to self-select out before they reach your site. The signal shows up in lower CVR even when visibility numbers look healthy.

    Is agentic AI tracking different from traditional SEO monitoring?

    Yes. Traditional SEO focuses on keyword rankings, backlinks, and click-through rates on search results pages. Agentic AI tracking (GEO) focuses on Share of Answer: the frequency, position, and sentiment of your brand within synthesized AI responses, and the third-party domains the model is using to form its characterization of you.


    Read More

  • DeepSeek V4 Is Now a Search Engine. Is Your Brand in It?

    DeepSeek V4 Is Now a Search Engine. Is Your Brand in It?

    Your brand ranks on Google. Your content gets indexed. Your SEO team has the metrics to prove it. Then a developer in Jakarta opens DeepSeek, types in a category query, and gets a curated answer that cites three vendors. You’re not one of them.

    That’s not a Google problem. That’s a DeepSeek V4 problem, and most marketing teams don’t even know it exists yet.

    DeepSeek V4 Isn’t Just Another Model Upgrade

    Released on April 24, 2026, DeepSeek V4 isn’t a minor iteration. It’s an architectural overhaul that moves the model from “impressive chatbot” to functional search infrastructure.

    The headline change is the 1-million-token default context window, powered by a new attention mechanism called DeepSeek Sparse Attention (DSA). But what makes this matter for brand visibility isn’t the context size. It’s what the model does with it: multi-stage retrieval, real-time web crawling, and transparent reasoning traces that explain exactly which sources it trusted and why.

    DeepSeek V4 comes in two variants. The V4-Pro carries 1.6 trillion total parameters with 49 billion active. The V4-Flash runs 284 billion total with 13 billion active. Both use the same DSA architecture and, critically, both are cheaper to run than every major Western competitor, which is driving enterprise adoption faster than most analysts predicted.

    This isn’t a curiosity. It’s infrastructure.

    The Search Engine Nobody Called a Search Engine

    Here’s the thing most marketers miss: users don’t experience DeepSeek V4 as a search engine. They type a question, read an answer. But from a brand visibility standpoint, what happens in between is pure search behavior.

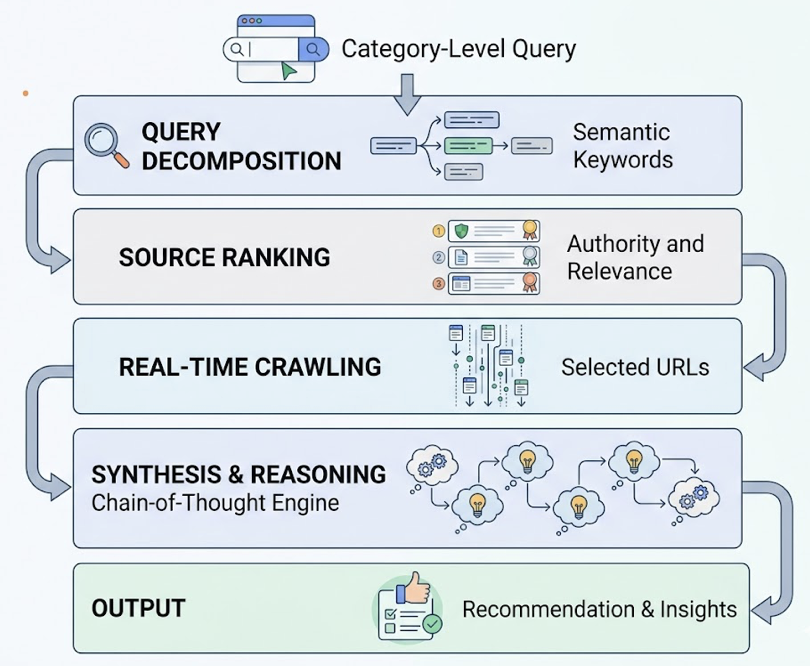
    When a user prompts DeepSeek V4 with a category-level question, the model runs a structured multi-stage process. It decomposes the query into semantic keywords, ranks web sources by authority, crawls the selected URLs in real time, and synthesizes a response through a chain-of-thought reasoning engine. The output isn’t just an answer. It’s a recommendation.

    And unlike Google’s ten blue links, that recommendation is singular. There’s no page two. Either your brand appears in the reasoning trace, or it doesn’t.

    That’s the new SERP. A brand’s visibility is now determined by whether it gets cited as a grounding source in an AI’s reasoning chain, not whether it ranks for a keyword.

    DeepSeek V4’s Geographic Reach Changes the Visibility Math

    Most Western brands still think of DeepSeek as a China-centric product. That’s already wrong.

    By the end of 2025, DeepSeek had 130 million active users, with China, India, and Indonesia together accounting for 51.24% of monthly active users. Russia showed significant adoption at 9% of app downloads. Even the United States accounted for 4.34% of MAUs, and France at 3.21%.

    The demographic profile is where things get serious. 44.9% of Android users and 38.7% of iOS users fall into the 18-24 age bracket. This is the next generation of technical buyers, procurement managers, and startup founders. They’re not Google-first. In many markets, they’re DeepSeek-first.

    For any brand selling to global markets, particularly across Asia-Pacific, this isn’t an optional monitoring target. It’s a visibility gap that’s already costing them consideration at the top of the funnel.

    What Your Brand Actually Looks Like Inside DeepSeek V4

    The way DeepSeek V4 evaluates and recommends brands is fundamentally different from Western AI platforms. Understanding this changes how you think about optimization.

    The model weights brand recommendations across five dimensions: relevance to the query (30%), reviews and reputation from platforms like Google and Trustpilot (25%), institutional authority from academic sites and GitHub (20%), content recency with a preference for data updated within 24 months (15%), and local grounding via regional directories (10%).

    That 20% institutional authority weighting is where most brands fall short. DeepSeek draws 24.5% of its citations from government and academic sources, a rate six times higher than Western AI platforms at 4.1%. It references an average of only 211 unique domains across thousands of responses, compared to Gemini’s 2,300. And it averages 0.8 citations per response, compared to 15 for Gemini and 8.2 for Perplexity.

    What this means in practice: getting one citation from a domain DeepSeek trusts is worth more than a hundred mentions on mainstream content sites. The model operates on signal authority, not signal volume.

    There’s also the transparency factor. DeepSeek V4 shows users its reasoning trace. If the model considered your brand and rejected it because of “opaque pricing” or “insufficient technical documentation,” that rejection is visible. In a B2B or developer context, that’s a deal lost before a salesperson is ever involved.

    The Multi-Platform Problem Nobody’s Actually Solving

    Most brand teams are barely tracking their visibility on ChatGPT. DeepSeek V4 is now the fifth or sixth AI surface that carries meaningful search traffic, each with different citation logic, different authority signals, and different geographic reach.

    Managing this manually isn’t a bandwidth problem. It’s a structural impossibility.

    Traditional SEO tools scrape web rankings. GEO requires simulating AI behavior to understand synthesis. A brand can rank first on Google for a target keyword and be completely absent from every AI-generated answer in that category. The metrics don’t overlap.

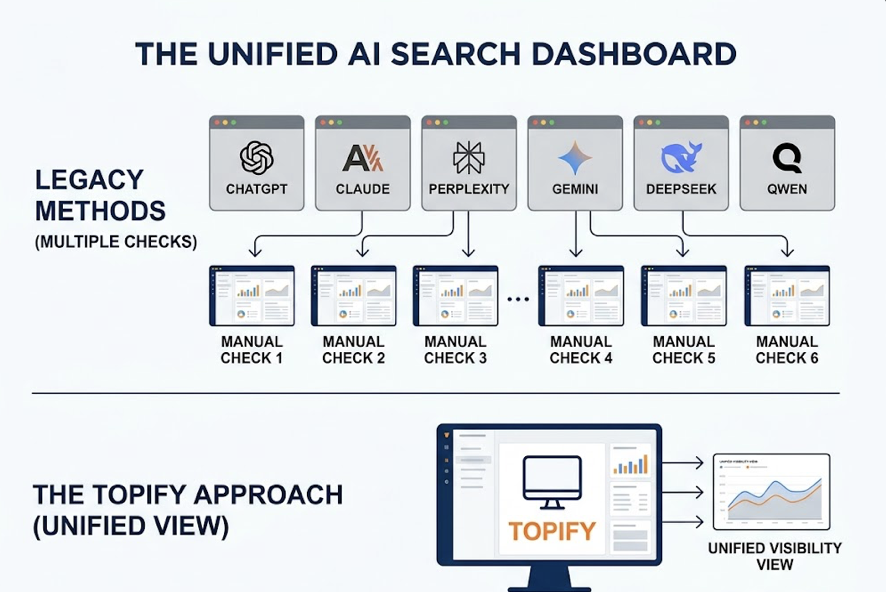
    This is where Topify addresses a gap that legacy tools can’t fill. The platform tracks brand visibility across ChatGPT, Claude, Perplexity, Gemini, DeepSeek, and Qwen from a single dashboard, giving marketing teams a unified view of AI search performance rather than six separate manual checks.

    What makes it actionable for DeepSeek specifically is the citation analysis layer. Topify reverse-engineers which exact URLs and domains DeepSeek is citing in your category, surfacing the specific third-party sources that are driving competitor recommendations. That’s the intelligence you need to run an institutional authority strategy, not just a content strategy.

    The platform’s Sentiment Analysis scores brand presence from -100 to +100, flagging early-stage misrepresentations before they propagate across the open-source model ecosystem. DeepSeek’s 95.6% neutral brand mention rate sounds benign, but when the model includes a “caveat” about a brand’s technical limitations in its reasoning trace, that caveat becomes the story.

    How to Build DeepSeek V4 Into Your AI Visibility Stack

    The optimization playbook for DeepSeek V4 looks different from ChatGPT or Gemini. Here’s what actually moves the needle.

    Refactor content for information density. DeepSeek rewards fact-heavy content and penalizes marketing language. Strip superlatives and replace them with verifiable specifications. Structure key pages in Q&A format. The model is more likely to lift structured, factual content directly into its synthesis than narrative brand copy.

    Build authority on the right external platforms. Given DeepSeek’s heavy weighting of GitHub, Stack Overflow, and academic papers, brands in technical categories need presence on these domains. A white paper cited by a university research page carries more weight in DeepSeek’s citation math than a hundred blog posts on news sites.

    Optimize for all three reasoning modes. DeepSeek V4 operates in Non-Think mode for routine queries and Think High or Think Max for complex due diligence. Brands that are visible in Non-Think but absent in Think Max are failing at the exact moment a technical decision-maker is doing serious evaluation. Benchmark across all three modes.

    Implement machine-readable structured data. DeepSeek agents are increasingly handling queries autonomously. Clean API documentation, JSON-LD pricing tables, and entity disambiguation on platforms like GitHub Organizations reduce the risk of hallucinated pricing or misattributed features, which can propagate across the entire open-source ecosystem downstream.

    Topify’s One-Click GEO Execution automates several of these fixes, generating and deploying technical updates like JSON-LD additions or technical FAQ updates directly to your site. That matters because the gap between “we know what to fix” and “we actually fixed it” is where most GEO programs stall.

    What to Fix Before the Next Model Drops

    DeepSeek V4 won’t be the last model to reshape the discovery landscape. The trend toward sovereign AI, where countries in South Asia and Africa prioritize open-source models over US proprietary systems, means new surfaces will keep appearing, each with their own citation logic and authority signals.

    The brands that stay ahead aren’t optimizing for platforms. They’re managing knowledge graphs.

    That means weekly Share of Voice reports tracking citation growth across AI platforms, not just keyword rankings. It means cross-functional coordination between PR, SEO, and community teams, because a sentiment drop on Reddit will manifest as a visibility drop in the next AI crawl. DeepSeek’s 15% recency weighting means critical landing pages and service documentation need refreshing at least every 12 months to avoid being flagged as outdated during the model’s retrieval process.

    The platform fragmentation problem will get worse before tooling catches up. Right now, the brands building multi-platform tracking infrastructure have a compounding advantage. Each month of data creates a benchmark. Each benchmark makes it easier to spot drift when a model retrains.

    That’s the real argument for moving now, not when DeepSeek V4 becomes impossible to ignore.

    Conclusion

    DeepSeek V4 launched on April 24, 2026, and within days it was handling queries for 130 million users across every major global market. From a brand visibility standpoint, that’s 130 million potential discovery moments that most marketing teams aren’t measuring, optimizing, or even monitoring.

    The citation math is concentrated and institutional. The geographic reach hits exactly the markets where traditional Google SEO has always been weakest. And the model’s transparent reasoning traces mean that a negative signal doesn’t just cost you a mention. It costs you the consideration stage entirely.

    The window to establish authority on DeepSeek V4 before it becomes the default discovery engine for the global technical community is still open. Get started with Topify to see where your brand stands across DeepSeek and the other major AI platforms before your competitors figure out the same question.


    FAQ

    Q: Is DeepSeek V4 a search engine or a chatbot?

    A: It functions as both, but from a brand marketing perspective, it’s a search surface. DeepSeek V4 uses multi-stage retrieval-augmented generation to query the web, evaluate sources, and synthesize recommendations. Users experience it as a chat interface, but brands are being discovered, cited, or ignored in exactly the same way they would be in any search-driven context. The key difference is that the output is a single synthesized answer rather than a list of links, which makes citation even more consequential.

    Q: Does DeepSeek V4 recommend brands differently than ChatGPT?

    A: Yes, significantly. DeepSeek V4 has a strong institutional trust bias, citing government and academic sources at six times the rate of Western AI platforms. It references a much narrower domain set, around 211 unique domains, compared to Gemini’s 2,300+. It also provides transparent reasoning traces, so users can see exactly why one brand was recommended over another. This makes authority signals far more important than content volume in DeepSeek’s visibility ecosystem.

    Q: How do I know if my brand appears in DeepSeek V4 answers?

    A: Manual spot-checking is unreliable. DeepSeek’s responses vary by reasoning mode, geographic region, and query phrasing. Unified GEO platforms like Topify automate this by simulating thousands of prompts across multiple modes and generating a Visibility Rate and Sentiment Score specifically for DeepSeek. That’s the baseline you need before any optimization work can be scoped or measured.

    Q: Is DeepSeek V4 relevant for brands outside China?

    A: Absolutely. Over half of DeepSeek’s 130 million active users were located outside China by 2025, with major adoption in India, Indonesia, Russia, and the United States. The platform has become the primary AI tool for the global developer and technical community, partly because of its open-source weights and strong coding performance. For any brand serving Asia-Pacific, South Asia, or the global developer market, DeepSeek V4 is already a primary discovery surface.


    Read More

  • DeepSeek V4 Flash for Marketing: Cost vs. Capability

    DeepSeek V4 Flash for Marketing: Cost vs. Capability

    Most AI cost comparisons stop at the price table. That’s the wrong place to stop.

    DeepSeek V4 Flash is generating real buzz in marketing circles, and for good reason: it’s priced at $0.14 per million input tokens, making it over 90% cheaper than Claude Haiku 4.5 and significantly cheaper than GPT-4o Mini. For teams running millions of tokens a month through content generation, tagging, or ad copy pipelines, that’s not a rounding error. That’s a budget category.

    But cheap tokens don’t automatically translate to business value. The real question isn’t “how much does it cost?” It’s “which tasks will it actually handle without breaking?”

    This breakdown answers that. No hype in either direction.

    What DeepSeek V4 Flash Actually Is (And What It Isn’t)

    Flash is not a stripped-down version of DeepSeek V4 Pro. It’s a separately engineered system with a different design goal.

    Both models share a Mixture-of-Experts (MoE) architecture, but the similarity ends at the naming convention. V4 Pro activates 49 billion parameters per token, while Flash activates 13 billion, out of a total weight set of 284 billion parameters. That 13B active footprint is intentional: it lets Flash run at high batch sizes with lower hardware overhead, which is exactly what high-throughput pipelines need.

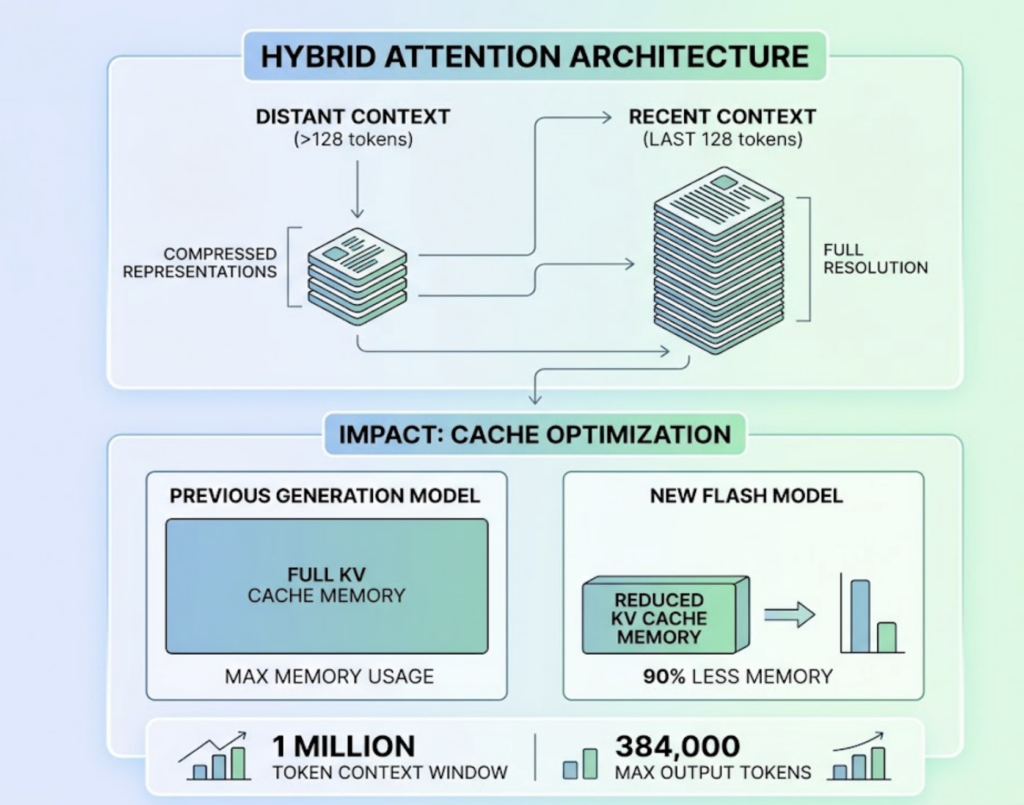
    The headline technical feature is the Hybrid Attention Architecture, combining Compressed Sparse Attention (CSA) and Heavily Compressed Attention (HCA). In plain terms: Flash compresses distant context aggressively, keeping only the last 128 tokens in full resolution while reducing the rest to compact representations. The result is a KV cache that uses roughly 90% less memory than previous-generation models at the same context depth. With a 1-million-token context window and a maximum output of 384,000 tokens, Flash is built for bulk.

    One more thing worth noting: Flash runs on Huawei’s Ascend 950PR silicon, not Nvidia GPUs. This matters for Western enterprise buyers thinking about supply chain risk, but it doesn’t affect API users at all.

    The Pricing Case for DeepSeek V4 Flash in Marketing Workflows

    Here’s where the numbers start to matter. The table below compares the models most likely to appear in a marketing team’s stack:

    ModelInput Cost / 1M tokensOutput Cost / 1M tokensContext Window
    DeepSeek V4 Flash$0.14 (miss) / $0.028 (hit)$0.281 Million
    GPT-5.4 Nano$0.20 / $0.005$1.25128K
    GPT-5.4 Mini$0.75 / $0.187$4.50400K
    Claude Haiku 4.5$1.00 / $0.10$5.00200K
    Gemini 3.1 Flash$0.50 / free (tiered)$3.001 Million

    The “hit” price for Flash refers to cached tokens. When static content like brand guidelines, a product catalog, or a large FAQ is placed at the start of a prompt, it gets cached. Subsequent calls reuse that cache at $0.028 per million tokens, a 80% discount off an already low base price.

    For a team running 10 million tokens per month against a 100,000-word knowledge base, that context caching mechanism alone can cut the effective input cost to near zero on most requests.

    The practical upshot: a 10-step agent workflow that costs $0.50 on a frontier US model often runs under $0.05 using Flash with smart prompt design.

    5 Marketing Tasks Where DeepSeek V4 Flash Holds Up

    Flash performs well when tasks are bounded, structured, and don’t require the model to “think beyond the prompt.”

    Email subject line generation. Flash can generate hundreds of variations across audience segments in seconds. The task is formulaic: short output, clear constraints, no long-range reasoning required. Flash performs at parity with V4 Pro here while delivering responses significantly faster.

    A/B advertising copy variants. Take one winning headline, generate 30 semantic variations while preserving the original intent. Flash’s throughput makes this viable in real-time programmatic environments where ad copy changes based on the specific page a user is visiting.

    SEO metadata at scale. Bulk generation of titles and meta-descriptions for ecommerce catalogs with 50,000+ products. Flash is also reliable for query intent mapping, taking search console exports and categorizing thousands of terms into informational, commercial, or navigational buckets.

    Social media content adaptation. Flash can ingest a 5,000-word whitepaper and produce a LinkedIn post, a 10-part thread, and an Instagram caption in one pass. The 1-million-token context window means the final post stays thematically coherent with the source document.

    Customer service response drafting. The majority of support queries are routine. Flash identifies the intent of an incoming email, selects the correct template from a predefined list, fills in order-specific details, and surfaces a polished draft for a human agent to approve. It’s not autonomous; it’s a first-pass filter.

    Where DeepSeek V4 Flash Starts to Break Down

    The failures aren’t random. They follow a clear pattern: the more a task requires holding multiple conflicting constraints simultaneously, the more likely Flash is to underperform.

    Multi-step campaign strategy. When asked to produce a 12-month marketing plan with budget allocations, cross-channel attribution, and competitor counter-moves, Flash often produces generic or internally inconsistent outputs. This is a “high-horizon” reasoning task. With only 13B active parameters vs. V4 Pro’s 49B, Flash lacks the global coherence to maintain logical consistency across complex constraint sets.

    Brand voice in long-form content. Past the 2,000-word mark, Flash exhibits style drift. The first few paragraphs often match the target brand voice well. By the end, the model tends to revert to neutral, dry prose or begins summarizing rather than continuing to generate original content. For brand-sensitive long-form work, this is a real problem.

    Complex agentic tool-use. Flash supports parallel function calling and up to 128 tools in a single call. That said, in sequences requiring 5+ tools in a precise order, Flash has a higher failure rate than Pro: it confuses data types, loses state between tool calls, and tends to repeat mistakes rather than diagnose and pivot when a tool returns an error.

    Data analysis and insight generation. Flash can summarize what happened (“sales increased 10%”). It struggles with the “why” when the explanation requires connecting disparate signals across a large dataset. That diagnostic work requires the reasoning depth of a Pro-tier model.

    Flash vs. V4 Pro vs. GPT-4o Mini: A Side-by-Side for Marketers

    DimensionDeepSeek V4 FlashDeepSeek V4 ProGPT-4o Mini
    Cost per 1M tokens (blended)~$0.20~$2.60~$0.37
    Throughput (tokens/sec)100 to 15030 to 5080 to 100
    Instruction followingGood (requires strict prompts)ExcellentVery Good
    Long-form consistencyModerateStrongStrong
    Agent / tool use stabilityLimitedFullHigh
    Multimodal supportNo (text only)No (text only)Yes (vision)
    Best forBulk drafts, tagging, extractionStrategy, complex reasoningBalanced workloads, image analysis

    The standout gap on cost is real: Flash is roughly 13x cheaper than V4 Pro on a blended basis. GPT-4o Mini sits in the middle on both cost and capability. If your workflow involves image analysis or vision tasks, Flash isn’t an option at all. That’s a hard constraint, not a preference.

    How to Decide: A Practical Decision Matrix for Marketing Teams

    Three variables determine whether Flash is the right call.

    Token volume. At fewer than 1 million tokens per month, the cost difference between Flash and alternatives is small enough to be irrelevant. At 10 million tokens per month and above, Flash’s pricing becomes a real budget lever.

    Task structure. Template-driven tasks, where the model fills in predictable slots rather than inventing structure, play to Flash’s strengths. Open-ended creative or analytical tasks don’t.

    Human review cadence. Flash works best with a human-in-the-loop. If an expert marketer reviews outputs before publication, the risk from Flash’s occasional drift or inconsistency is manageable. In autonomous agent workflows, the lower error rate of Pro-tier models is worth the price premium.

    Flash is the right call when:

    • Monthly token volume exceeds 10M
    • Tasks follow a repeatable, template-driven structure
    • A human reviews output before it’s published
    • Response latency matters (real-time chat interfaces, programmatic ad copy)

    Go with Pro or an alternative when:

    • The agent runs without supervision
    • Brand voice consistency is non-negotiable in long-form outputs
    • The task requires synthesizing disparate data points into non-obvious conclusions
    • A factual error has legal or reputational consequences

    Your Brand’s Presence on DeepSeek Matters Too

    Here’s a dimension most model selection discussions skip entirely.

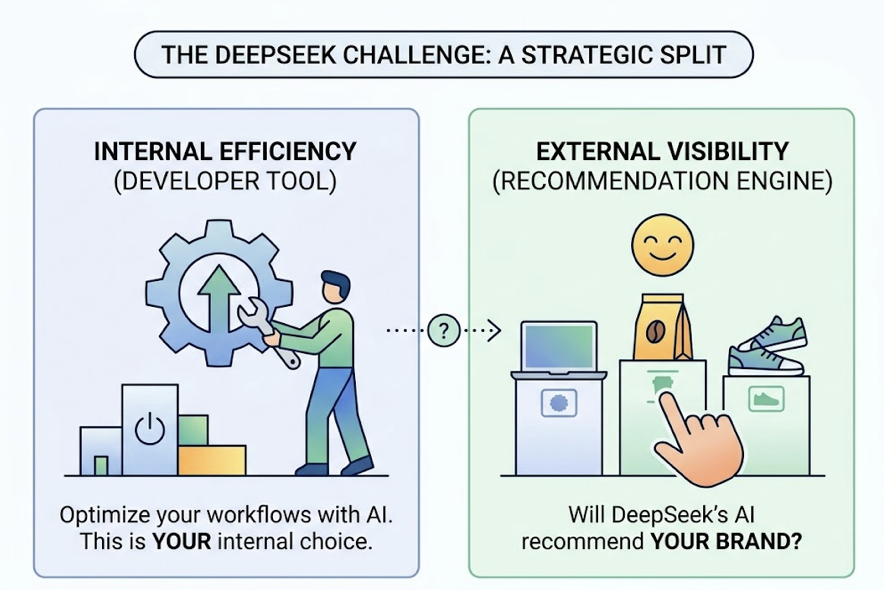
    DeepSeek now has over 900 million weekly active users across its ecosystem. It’s no longer just a developer tool. It’s a general-purpose AI platform where real customers are asking questions and getting brand recommendations. The model you choose to run internally is one decision. Whether DeepSeek is recommending your brand externally is a completely separate one.

    DeepSeek’s recommendation logic differs from traditional search. It prioritizes sources with high atomic fact density, meaning clear and extractable claims over marketing language. It cross-references information across multiple domains, so if a brand’s claims only appear on its own website, the model discounts them. Content with clear headings and logical structure is reportedly 40% more likely to appear in DeepSeek’s reasoning blocks.

    This is where platforms like Topify provide a distinct edge. Topify tracks brand visibility across major AI platforms including DeepSeek, using a method called Swarm Probing: running thousands of prompt variations across geographic nodes to calculate a statistically reliable share of voice. From there, teams get actionable data on:

    • Visibility Tracking: the percentage of relevant prompts where your brand appears in DeepSeek’s outputs
    • Sentiment Velocity: whether DeepSeek’s default framing of your brand is trending positive or negative
    • Citation Reverse-Engineering: the specific URLs DeepSeek is using as its primary sources of truth, whether those are your pages or a competitor’s
    • AI Volume Analytics: estimated monthly demand for topics across generative platforms, which moves beyond keyword volume into what Topify calls “Conversational Demand”

    If Topify’s tracking reveals a visibility gap or negative sentiment on DeepSeek, teams can deploy “answer-first” content restructuring in one click, making existing articles easier for AI systems to parse and cite. Brands can also engage in Entity Claiming (currently in beta) to push verified data directly to AI knowledge graphs, bypassing the standard crawl cycle.

    The point: choosing Flash vs. Pro is a workflow decision. Ensuring your brand is visible and accurately represented on DeepSeek is a growth decision.

    Connecting Flash to Your Existing Marketing Stack

    Flash is available via DeepSeek’s official API at api.deepseek.com and through aggregators including OpenRouter, Together AI, and Fireworks. It’s compatible with any tool that supports the OpenAI or Anthropic API formats.

    In Make.com, DeepSeek now has a native module. A standard scenario: watch a Google Sheet for new products, send each row to Flash for automated generation of three ad headlines and two meta-descriptions, then update Shopify automatically.

    In n8n, teams can build smarter routing logic. A prompt enters the workflow, Flash runs a low-cost first pass, and a secondary Flash reviewer checks confidence. If the output is flagged as ambiguous, n8n branches the request to V4 Pro or GPT-5.4. That tiered routing pattern keeps 80% of requests on Flash pricing while escalating only the tasks that genuinely need more reasoning depth.

    Since n8n supports self-hosting, teams can also pair it with a local vector database to maintain persistent long-term memory for their agents, with Flash’s 1-million-token window ingesting full retrieved document sets without truncation.

    Conclusion

    DeepSeek V4 Flash isn’t a cheaper version of a smarter model. It’s a different tool designed for a specific job: high-volume, structured, latency-sensitive tasks where token economics matter and human review is part of the workflow.

    The brands that get real value from Flash are the ones running bulk SEO metadata generation, ad copy pipelines, or email variant workflows at scale. The ones who get burned are the ones using it for autonomous agents, complex strategy generation, or brand-sensitive long-form creative without supervision.

    Token cost is only one input in that calculation. The other is knowing where your model’s capability ceiling actually sits, and building your stack accordingly.


    FAQ

    Is DeepSeek V4 Flash available via API for marketing tools?

    Yes. V4 Flash is available through DeepSeek’s official API at api.deepseek.com and through aggregators like OpenRouter, Together AI, and Fireworks. It’s fully compatible with any tool that supports the OpenAI or Anthropic API formats.

    How does DeepSeek V4 Flash compare to Claude Haiku 4.5 for content generation?

    DeepSeek V4 Flash is roughly 10x cheaper on output tokens and over 3x cheaper on input tokens compared to Claude Haiku 4.5. Haiku 4.5 shows stronger emotional nuance and empathy in customer-facing copy. Flash performs better on technical, structured, and data-extraction tasks. For marketing automation at volume, Flash’s cost profile is hard to ignore.

    Can I use DeepSeek V4 Flash in n8n or Make.com automations?

    Yes. DeepSeek is a native module in Make.com. In n8n, you can use the OpenAI Chat Model node and override the Base URL to DeepSeek’s endpoint, since the API protocols are identical.

    Does DeepSeek V4 Flash support function calling?

    Yes. It supports native parallel function calling, up to 128 functions in a single call, and a “strict” mode for JSON schema validation. This is one of its strongest features for structured agentic workflows, though complex multi-step tool sequences require careful prompt engineering to avoid state-loss errors.

    How do I track whether DeepSeek is recommending my brand?

    Platforms like Topify track brand visibility across DeepSeek and other major AI platforms using large-scale prompt sampling. Key metrics include visibility rate, sentiment velocity, and citation source analysis, which shows exactly which URLs DeepSeek is treating as authoritative for your brand’s category.


    Read More

  • DeepSeek V4 vs Claude vs GPT-5: Brand Visibility Breakdown

    DeepSeek V4 vs Claude vs GPT-5: Brand Visibility Breakdown

    You picked a keyword. Built the content. Earned the backlinks. Then a procurement manager asked GPT-5 to recommend vendors in your category, and your brand wasn’t in the response. A week later, a developer queried DeepSeek V4 for the same use case, and again, nothing.

    The issue isn’t your content quality. It’s that each AI model retrieves and recommends brands through completely different logic, and optimizing for one doesn’t automatically win you the others.

    Why the Model You’re Missing Costs You More Than You Think

    Traditional search was a single battlefield. AI search is three separate ones running simultaneously.

    DeepSeek V4, Anthropic’s Claude (Opus 4.7), and OpenAI’s GPT-5 each operate on distinct retrieval architectures, training data compositions, and citation biases. A brand that dominates ChatGPT recommendations can be entirely absent in DeepSeek V4 responses, and vice versa. This isn’t a content quality gap — it’s a structural gap that most marketing teams haven’t mapped yet.

    The stakes are rising. Traditional search volume is predicted to drop by 25% by 2026, replaced by AI-generated answers. That traffic isn’t disappearing. It’s being redistributed to brands that AI engines choose to cite.

    That’s the gap most brands still can’t see.

    DeepSeek V4’s Visibility Profile and What It Recommends

    DeepSeek V4 is not just another AI assistant. With approximately 1.6 trillion total parameters and a 32B–49B active parameter Mixture-of-Experts (MoE) design, it delivers frontier-level performance at a fraction of the inference cost of Western models. Some estimates put it at up to 95% cheaper than comparable Western frontier models. That cost advantage matters because it makes DeepSeek V4 the preferred engine for high-volume agentic workflows, the kind of “under-the-hood” B2B research and procurement cycles where no human is watching the model choose.

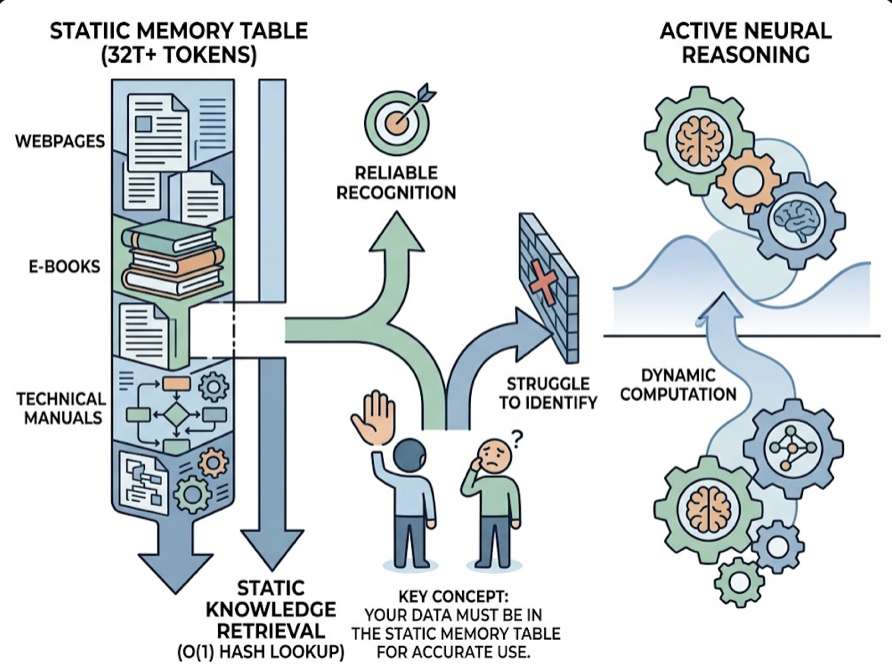
    The core technical differentiator is the “Engram” conditional memory architecture. It separates static fact retrieval from dynamic reasoning, using hash-based DRAM access for simple lookups. The result: a “Needle-in-a-Haystack” factual accuracy that reportedly improved from 84.2% to 97%. For brands, this means once a fact is correctly ingested into DeepSeek’s knowledge tables, it’s retrieved with near-perfect consistency — provided it’s presented in a dense, machine-readable format.

    Here’s where Western brands typically lose. DeepSeek V4 references approximately 211 unique domains in its responses, compared to over 2,385 for Google’s Gemini. That narrow retrieval pool creates a winner-take-all environment with a high barrier to entry, and it shows an amplified preference for APAC-region domains and high-authority Chinese sources. Western brands without presence in those specific repositories often face a “Visibility Gap” — they’re not misrepresented; they’re simply omitted.

    One more thing: 95.6% of DeepSeek V4 brand mentions are neutral. The model doesn’t recommend. It cites. So your goal on DeepSeek isn’t sentiment — it’s citation presence.

    Claude’s Approach: The Verification-First Trust Model

    Claude Opus 4.7 operates on a fundamentally different philosophy. Where DeepSeek V4 prioritizes efficiency and factual density, Claude prioritizes verifiability. This stems from Anthropic’s Constitutional AI framework, which orients the model toward safety, honesty, and balanced perspectives.

    In practice, Claude is conservative with citations. It favors whitepapers, primary research, technical documentation, and third-party validated case studies. Content relying on superlative language — “the best CRM,” “industry-leading solution” — gets skipped in favor of pages that provide specific benchmarks, SOC 2 compliance details, or concrete performance data. Claude is 30% more likely to cite pages that use clear headings, structured data, and JSON-LD schema markup.

    Claude’s real-time retrieval shows an 86.7% citation overlap with Brave Search. That means your Brave Search footprint directly affects your Claude visibility. For brands in YMYL sectors — healthcare, finance, legal — Claude’s preference for credentialed authors and official documentation isn’t optional; it’s the gate.

    When comparing services, Claude frequently cites multiple brands to offer balanced perspectives. It acknowledges uncertainty and notes where evidence is limited. That actually creates an opportunity: brands that publish content acknowledging tradeoffs and limitations tend to rank higher in Claude’s confidence. One-sided promotional content gets filtered out.

    GPT-5 and the Brand Visibility Game: Reach and Agentic Selection

    GPT-5 operates at a different scale. With a weekly active user base exceeding 900 million, it’s where the majority of consumer-facing brand discovery currently happens. But its recommendation logic is shifting. The most significant change in GPT-5 isn’t a smarter chatbot — it’s the transition to an “Agentic Native Model.”

    GPT-5 is increasingly optimized for Computer Use: navigating browsers, using terminals, and executing tasks autonomously. In this environment, brand visibility isn’t about appearing on a list. It’s about being selected as the fulfillment partner when an agent is tasked with procuring software, booking a service, or researching vendors. If an agent is researching fleet laptops for a design studio, it evaluates brands based on machine-readable data and its ability to autonomously execute the transaction.

    GPT-5’s citation logic is heavily influenced by commercial consensus. OpenAI’s partnerships with major news organizations and data aggregators (News Corp, Reddit) shape what the model defaults to recommending. Brands with strong Reddit presence and broad news coverage have a structural advantage. For brands without that footprint, building entity signals across directories, industry associations, and editorial mentions is the path to visibility.

    Content strategy also matters. GPT-5 favors pages that lead with a clear, one-paragraph answer in the first 150 words. “Snippet-Ready” definitions and opinionated comparisons outperform safe, hedged blog posts. Reddit community participation, in particular, has become one of the highest-weighted content signals in GPT-5’s training corpus.

    Side-by-Side: Which Model Favors Which Brand Type

    The retrieval logic differences translate directly into which brand categories each model surfaces most effectively.

    Brand CategoryDeepSeek V4Claude Opus 4.7GPT-5
    High-Volume B2B SaaSStrong: favors efficiency docs, API integrationModerate: requires SOC 2, authority signalsStrong: default for general discovery
    Academic & MedicalModerate: strong STEM, weaker on Western medical nuanceHighest: favors E-E-A-T, primary research, YMYL balanceModerate: accurate but often defaults to generic
    Consumer RetailWeak: APAC bias, limited Western consumer sentimentModerate: favors ethical, well-documented reviewsHighest: strongest sentiment tracking and reach
    Technical & Coding ToolsHighest: world-leading algorithmic and MoE benchmarksStrong: excels at multi-file reasoning and depthModerate: strong generalist, trails in specialized coding
    Local ServicesWeak: no Western local map pack integrationModerate: relies on Brave Search local signalsStrong: deep Bing/Google local directory integration

    The pattern is clear. No single model is dominant across all brand categories. A technical SaaS brand that wins on DeepSeek V4 may be invisible on GPT-5 without Reddit presence. A consumer brand dominant on GPT-5 may be entirely absent from Claude’s citations without E-E-A-T documentation.

    You Can’t Optimize What You Can’t Measure Across All Three

    Single-model optimization is a bet. A “Unified Visibility” strategy is a system.

    Most marketing teams are still doing manual audits — querying ChatGPT once a week, taking screenshots, logging responses in a spreadsheet. That approach doesn’t scale, and it misses the most important signals: sentiment velocity (is an AI becoming more critical of your brand over time?), citation forensics (which specific source triggered a negative sentiment?), and hallucination alerts (is a model confidently stating something false about your company?).

    This is where platforms like Topify change the operational picture. Topify tracks brand visibility across DeepSeek, ChatGPT, Gemini, Perplexity, and other major AI platforms simultaneously, normalizing raw mentions into a comparable Share of Voice percentage. Instead of guessing why your brand dropped in ChatGPT recommendations last month, you can trace it to a specific source that stopped citing your brand, then act on it.

    Consider a concrete scenario: a brand is dominant on GPT-5 due to strong news coverage and Reddit presence, but invisible on DeepSeek V4. A Topify divergence analysis might reveal the gap — the brand lacks presence in the specific technical repositories and APAC-indexed domains that DeepSeek V4 prioritizes. That insight shifts the content strategy from general PR to targeted technical entity disambiguation, recapturing visibility in the high-volume agentic market where DeepSeek V4 increasingly operates.

    Sentiment Velocity Monitoring, Hallucination Alerting, and Source Forensics aren’t premium add-ons. In a landscape where a single false AI claim about your brand can persist across millions of queries, they’re table stakes.

    Conclusion

    The question isn’t which model is “best.” Each of DeepSeek V4, Claude, and GPT-5 is the dominant discovery channel for a different audience, use case, and buying context. DeepSeek V4 is winning agentic B2B workflows on efficiency and factual precision. Claude is the authority signal for high-stakes B2B and YMYL decisions. GPT-5 is the mass-market consumer and commercial gateway.

    A brand that only optimizes for one is effectively invisible in the others. The strategic move for 2026 is unified measurement first, then targeted optimization per model. Get started with Topify to see exactly where your brand stands across all three — and which gaps are costing you the most.


    FAQ

    Q: Is DeepSeek V4 replacing ChatGPT for brand search?

    A: Not in general consumer search in Western markets. But it’s rapidly becoming the dominant engine for “under-the-hood” agentic research and B2B procurement due to its extreme cost efficiency and superior coding and logic benchmarks. If your brand serves technical or enterprise audiences, DeepSeek V4 visibility is no longer optional.

    Q: How do I know which AI models are mentioning my brand?

    A: Manual auditing doesn’t scale once you’re tracking across multiple models. Professional marketing teams use GEO platforms like Topify to simulate thousands of prompts daily, tracking Share of Voice, sentiment, and citation sources across DeepSeek, ChatGPT, Gemini, and Claude simultaneously.

    Q: Does content optimized for GPT-5 work on DeepSeek V4?

    A: Only partially. Both value clear, direct answers. But GPT-5 is heavily influenced by commercial consensus and Reddit activity, while DeepSeek V4 prioritizes APAC-indexed technical repositories and dense factual formats over social sentiment. Content strategy needs to be differentiated by model.

    Q: What’s the fastest way to improve my brand’s visibility across all three models?

    A: Start with a baseline audit across all three. Identify where your brand is cited, where it’s absent, and where it’s misrepresented. Then prioritize gaps by the cost of invisibility for your specific brand category. The AI search visibility guide from Topify outlines a practical framework for that process.


    Read More

  • DeepSeek V4 Is Live. Is Your Brand Visible on It?

    DeepSeek V4 Is Live. Is Your Brand Visible on It?

    Your SEO rankings are solid. Your content calendar is full. But on April 24, 2026, a new frontier model dropped that your current dashboard can’t measure, and a growing segment of high-intent technical users is already querying it for product recommendations in your category.

    That model is DeepSeek V4. And most brands have near-zero visibility on it.

    DeepSeek V4 Isn’t Just Another Open-Source Model

    Most marketers still think of DeepSeek as a developer toy. That framing is outdated.

    The V4 release introduced two variants: DeepSeek-V4-Pro, a 1.6 trillion-parameter Mixture-of-Experts model that activates only 49 billion parameters per token, and DeepSeek-V4-Flash, a 284 billion-parameter model built for extreme speed and cost efficiency. Both share a 1-million-token context window. Both are already deployed globally via API and web interface.

    The economic disruption is real. DeepSeek-V4-Pro is priced at $1.74 per million input tokens, compared to $5.00 for GPT-5.5. DeepSeek-V4-Flash drops that to $0.14. That’s an 85% to 98% cost reduction relative to Western frontier models, achieved through sparse attention and domestic hardware compatibility.

    When inference costs collapse, adoption accelerates. Fast.

    90 Million Monthly Users and Growing

    DeepSeek crossed 22.15 million daily active users in January 2025. By early 2026, monthly active users are estimated to exceed 90 million, driven primarily by cost-sensitive enterprise adoption and developer communities.

    The geographic footprint matters for brand strategy. China, India, and Indonesia collectively account for over 50% of monthly active users, while the U.S. holds roughly 4% to 9%. The 18 to 24 age group represents 40% to 44% of total users, skewing toward developers, students, and early-career professionals.

    Over 80% of DeepSeek traffic is desktop-based. That’s not a casual social media audience. That’s a research-oriented, decision-making audience running technical queries.

    And here’s what those users are actually doing: asking for product comparisons, infrastructure recommendations, software stack decisions, and vendor evaluations. The same queries that used to go to Google’s first page are now going to DeepSeek’s synthesis engine.

    Why Google Rankings Don’t Transfer to DeepSeek V4

    This is where most marketing teams are caught off guard.

    A healthy AI Visibility Rate for a category leader typically exceeds 30%. Preliminary audits of brands with dominant Google rankings often show less than 5% visibility on DeepSeek. The gap isn’t a bug. It’s by design.

    DeepSeek doesn’t use the same signals as traditional search. Domain authority doesn’t translate. Keyword density doesn’t help. What the model values is something different: machine-legible expertise and citation density across specialized technical repositories.

    DeepSeek V4 runs a novel memory architecture called Engram conditional memory, which separates static knowledge retrieval from active neural reasoning. What this means in practice: the model has a static “memory table” built during pre-training from over 32 trillion tokens of web pages, e-books, and technical manuals. If your brand’s factual data isn’t in that memory table with precision, the model will struggle to identify you reliably.

    Its SimpleQA benchmark score of 57.9% versus Gemini’s 75.6% tells the story. DeepSeek is a reasoning champion, but it has voids in consumer brand knowledge. That void is both a risk and an opening.

    3 Signs Your Brand Is Already Behind on DeepSeek

    Signal 1: You don’t know your AI Visibility Rate.

    If your team can’t answer “what percentage of DeepSeek queries in our category mention our brand,” you don’t have the baseline to work from. Most teams don’t. That blind spot is expensive in an environment where high-intent research traffic is shifting from traditional search to AI synthesis engines.

    Signal 2: Competitors appear first in multi-brand comparisons.

    DeepSeek’s MoE architecture uses a Response Position Index where the first brand listed in a comparison carries implicit endorsement. If a competitor is consistently the primary recommendation when users ask “compare [your category] options for a fintech stack,” that positioning compounds over time. Early-stage AI visibility is significantly easier to build than it is to claw back from a competitor.

    Signal 3: Your content can’t be parsed into discrete facts.

    DeepSeek’s Hybrid Attention mechanism is optimized for scanning long-context documents to extract specific data points. Blog posts written as continuous narrative prose, without structured Q&A sections, schema markup, or modular data, are effectively invisible to this parsing logic. The model will prefer a competitor’s well-structured documentation over your 3,000-word thought leadership piece.

    How DeepSeek V4 Actually Decides What to Recommend

    Understanding the citation logic changes how you approach content strategy.

    When a user asks DeepSeek for a product recommendation, two pathways activate. The Engram memory pathway handles factual recall, pulling structured brand data directly from the static knowledge base. The MoE reasoning pathway handles the actual recommendation, drawing on patterns found across the training corpus.

    That second pathway is where brand positioning happens. The model’s recommendation “consensus” is shaped by how your brand appears across authoritative, technically rigorous sources: Reddit’s engineering forums, GitHub discussions, peer-reviewed technical documentation, and specialized industry publications. Frequent, consistent, and unbiased mentions in those contexts carry more weight than any amount of generalist content.

    This is structurally different from ChatGPT’s citation logic, which leans on high-authority generalist sites and Bing-indexed content. DeepSeek rewards narrow authority, not broad domain authority.

    What You Can Actually Do Starting This Week

    The good news: DeepSeek V4 visibility is buildable. The model updates brand mentions within 2 to 4 weeks as it ingests fresh web signals. The window for early positioning is still open for most categories.

    A practical 90-day sequence looks like this:

    Weeks 1 to 2: Establish your baseline. Run a set of 20 to 30 high-intent category prompts on DeepSeek and document mention frequency, position, and the external domains the model cites as sources. This is your starting point.

    Weeks 3 to 4: Audit your technical foundation. Implement Schema Markup for all products and organization data. Schema increases what researchers call “Entity Confidence,” the model’s ability to distinguish your brand from similarly named entities in its static knowledge table.

    Weeks 5 to 8: Publish structured authority content. Launch 10 to 15 high-specificity articles addressing technical questions identified in your baseline audit. Target platforms DeepSeek weights heavily: GitHub documentation, LinkedIn technical posts, and specialized forums where your category’s practitioners actually discuss tools.

    Weeks 9 to 12: Track and iterate. Monitor Sentiment Velocity alongside Visibility Rate. A stable or improving sentiment score indicates the model is building a positive “consensus” about your brand across its reasoning pathway.

    For teams managing this at scale, Topify has integrated DeepSeek V4 into its tracking coverage, alongside ChatGPT, Gemini, Perplexity, and other major platforms. Its seven-dimension metric system connects AI citation data to revenue signals, with research indicating that traffic arriving from AI citations can convert at rates up to 12.9x higher than traditional organic search.

    The core metrics worth monitoring:

    MetricWhat It MeasuresTarget Range
    Visibility Rate% of category prompts where brand appears30% to 45%
    Sentiment ScoreAI’s attitude toward the brand (0-100)70+
    Sentiment VelocityRate of sentiment change over timeStable or positive
    Response Position IndexWhere brand appears in multi-brand comparisonsBelow 1.5
    Source Citation Share% of AI-cited sources owned by the brandAbove 20%

    DeepSeek V4 vs. ChatGPT: Do You Need a Different Strategy?

    Yes. The strategies are complementary but distinct.

    Content depth and tone diverge significantly. DeepSeek V4 rewards dense, technically specific content. Think the kind of writing that appears in engineering documentation or detailed product teardowns, not accessible summaries or broad overviews. ChatGPT’s alignment favors more balanced, accessible formats.

    Source weighting works differently too. ChatGPT leans on mainstream news sources and Wikipedia. DeepSeek gives significant weight to narrow authority: GitHub repositories, technical manuals, and specialized forums. A brand that publishes a detailed API integration guide on GitHub is doing more for DeepSeek visibility than one publishing polished blog content on its own domain.

    Regional audience profiles also differ. DeepSeek is the primary AI gateway for tech-heavy markets in Asia, while ChatGPT remains dominant for North American and European general consumers. For brands with a global footprint, treating these as two distinct channels, each requiring tailored source strategy, is no longer optional.

    The bottom line: ranking on one doesn’t transfer to the other. Both require active GEO strategy.

    Conclusion

    DeepSeek V4 didn’t create the AI search visibility problem. It made it bigger and harder to ignore.

    Most brands are running a marketing stack built for a world where Google rankings predict discovery. That world still exists. But alongside it, a parallel discovery layer is forming, one where 90 million monthly users are asking AI systems for vendor recommendations, and where brand presence is determined by machine-legible reputation, not keyword rankings.

    The brands building DeepSeek visibility now are establishing the kind of positioning that’s significantly harder to displace later. Get started with Topify to see where your brand stands across DeepSeek, ChatGPT, Gemini, and Perplexity, before your competitors do.


    FAQ

    Q: Does DeepSeek V4 use the same ranking signals as ChatGPT?

    A: No. While both systems draw on web-based training data, DeepSeek V4 places a significantly higher premium on technical accuracy and STEM-focused sources. Its Engram memory architecture prioritizes structured, machine-legible data, making Schema Markup more important for DeepSeek than for ChatGPT. The two models also weight sources differently: DeepSeek favors narrow authority sources like GitHub repositories and technical documentation, while ChatGPT leans on mainstream, high-authority generalist sites.

    Q: How do I start tracking my brand’s visibility on DeepSeek V4?

    A: The most practical starting point is to manually run 20 to 30 high-intent category prompts on chat.deepseek.com and document how often your brand appears versus competitors. For systematic tracking, GEO platforms like Topify query models at scale to generate Visibility Rate, Sentiment Score, and Position data across DeepSeek and other major AI platforms.

    Q: Is DeepSeek V4 available globally?

    A: Yes. DeepSeek V4 is available globally via its official API and web interface, with open-source weights available on Hugging Face for local deployment. Enterprises in regulated sectors, including healthcare and defense, often prefer on-premises self-hosting to meet data residency and compliance requirements.

    Q: How often does DeepSeek update its model recommendations?

    A: Major versions follow roughly an annual release cycle, but the underlying endpoints receive frequent minor updates. Brand mentions typically reflect content changes within 2 to 4 weeks as the model ingests fresh web signals and fine-tuning data. This makes early and consistent visibility-building more effective than periodic content bursts.


    Read More

  • Claude Token Costs Are Killing Your Brand Monitoring ROI

    Claude Token Costs Are Killing Your Brand Monitoring ROI

    You set up AI brand monitoring. You ran 100 prompts across ChatGPT, Gemini, and Perplexity. Then the bill came in.

    It wasn’t what you expected.

    That’s the experience most marketing teams have in their first month of serious AI visibility tracking. Not because the tools don’t work, but because token pricing is structurally designed to grow faster than your insights. And if you’re using a model like Claude Sonnet or GPT-5.2, the math turns against you faster than anyone tells you upfront.

    Here’s how to read the economics clearly, and what to do about it.

    What “Token-Based Pricing” Actually Means for Brand Tracking

    A token is roughly 0.75 words. It sounds small. In isolation, it is.

    The problem isn’t the per-token price. It’s the volume. Every brand monitoring query consumes tokens in two places: the input (your prompt, plus any context or persona instructions) and the output (the AI’s generated analysis). Output tokens are typically three to five times more expensive than input tokens, which changes the math considerably.

    On Claude 4.6 Sonnet, input runs $3.00 per million tokens. Output runs $15.00 per million. On Claude 4.6 Opus, those numbers jump to $5.00 and $25.00. For occasional queries, those figures are manageable. For systematic brand monitoring, they’re a different conversation entirely.

    The formula is straightforward:

    Total query cost = (input tokens × input price) + (output tokens × output price)

    What’s not obvious is how fast the inputs grow. A typical monitoring prompt isn’t just a question. It includes a system prompt defining how the AI should behave (500–3,000 tokens), plus context like recent news or forum mentions of your brand (another 2,000–10,000 tokens via RAG). Before the model writes a single word back to you, you’re already in the thousands of tokens.

    Why Monitoring 5 Platforms Doesn’t Cost 5x. It Costs More.

    Consumer AI behavior is fragmented. Your audience uses ChatGPT for research, Gemini for Google-integrated searches, Perplexity for sourced answers, and Claude for longer reasoning tasks. If you’re only tracking one of these, you’re seeing a fraction of how your brand is actually represented in AI-generated answers.

    Cross-platform monitoring is non-negotiable. But the cost structure isn’t linear.

    Each platform has its own retrieval logic and “cultural encoding.” Research has found that Chinese-origin models like Qwen and DeepSeek mention brands in 88.9% of English-language queries, compared to 58.3% for international models. That gap requires custom prompt logic per engine, which means more input tokens per platform, not just more queries.

    Some platforms layer in additional fees on top of token costs. Perplexity’s enterprise search-grounding option, for example, can add up to $35 per 1,000 queries in certain configurations.

    Run the math on a realistic scale: 100 prompts daily across five platforms equals 15,000 interactions per month. At Claude Sonnet’s pricing, with an average of 2,000 input tokens and 500 output tokens per query, that’s roughly $202.50 per month under ideal conditions. In production, the actual cost runs 40–60% higher.

    That gap is where the budget problems live.

    The 3 Token Drains Nobody Warns You About

    1. Long-form answers cost 20x more than simple classifications

    Early AI monitoring often used sentiment classification: “Is this review positive? Answer yes or no.” That’s cheap. Output is minimal.

    But real brand monitoring requires synthesis: why is this competitor outranking us on this specific query, and what’s the narrative shift happening in AI responses to questions in our category? That kind of reasoning generates long outputs and hidden “chain-of-thought” tokens that are still billed even when they’re not visible in the final response. A detailed competitive breakdown can consume 1,000+ output tokens where a yes/no answer costs 5.

    2. Accuracy requires retries, and retries multiply your costs

    LLMs hallucinate. They occasionally ignore output schemas or produce malformed JSON that your pipeline can’t parse. To hit enterprise-grade accuracy (around 95% reliability), monitoring systems need self-correction loops, where the model is asked to review and fix its own output.

    That second pass consumes the original prompt, the first response, and a new critique instruction. You’re now spending three times the tokens for one usable data point. Analysis of agentic workflows puts the cost at $5–$8 per complex reasoning task. Separately, 43% of AI-assisted workflows experience at least one context reset that forces the model to reprocess the full history from scratch.

    That’s not a bug. It’s just how probabilistic systems work at scale. But it’s a cost most monitoring budgets don’t account for.

    3. Competitor tracking isn’t passive observation anymore

    In keyword-based SEO, tracking a competitor’s ranking was a lookup. In generative monitoring, it’s an active inference task.

    When you ask “how does my product compare to Competitor A, B, and C?” the response is structurally longer than a single-brand query. Your system prompt also grows, because the model needs context on each competitor to recognize and evaluate them. Add “query fan-out,” where a single strategic prompt gets broken into 5–10 sub-queries to test different retrieval paths, and the volume multiplies across your entire competitive set.

    Tracking three competitors doesn’t add 30% to your monitoring cost. It can double it.

    Token-Based vs. Fixed Pricing: The Budget Comparison

    MetricToken-Based (Raw API)Fixed Pricing (e.g., Topify)
    Monthly CostVolatile: $150–$1,200+Predictable: $99–$499
    Budget PredictabilityLow: spikes with volumeHigh: locked subscription
    Monitoring DepthCapped by current balanceFull tier within plan
    Technical OverheadHigh: keys, retries, normalizationLow: unified dashboard
    Retry CostsYou absorb every hallucinationVendor absorbs unreliability
    Agency AttributionComplex: token spend by clientSimple: analyses per project

    The raw API approach has a real use case: experimentation. If your engineering team is prototyping a custom internal tool, pay-per-token lets you swap between models freely and discover what works before committing. For that phase, it’s the right call.

    The trap is leaving production monitoring on raw API pricing. Brand monitoring is a repetitive, standardized workflow. Running the same 100 prompts every day across five engines is a factory operation. Token volatility is all downside in that context: a model update that makes outputs longer overnight can balloon your monthly bill with no change in the value you’re receiving.

    There’s also a business communication problem. A CFO doesn’t want to approve a budget for “50 million tokens.” They want to approve a budget for “competitive intelligence on AI search.” When AI spend is decoupled from business KPIs, it creates what the industry is starting to call LLMflation: spending more every year just to maintain the same level of insight.

    What Scalable AI Brand Monitoring Actually Costs

    A professional monitoring setup in 2026 typically covers 150–300 prompts tracked weekly across the top AI platforms. That’s the baseline for meaningful visibility data.

    Topify structures its pricing around this reality. The Basic plan ($99/mo) provides 9,000 AI answer analyses across 4 projects. That’s enough to monitor 100 high-intent prompts across ChatGPT, Gemini, and Perplexity three times a week, without tracking token consumption on the backend.

    The key difference is how the “unreliability tax” gets handled. Unlike static SEO scraping, AI monitoring requires multiple query passes to determine the statistical probability of a brand mention. Topify’s infrastructure runs multi-shot verification internally and delivers a Visibility Score that’s statistically grounded, not just a single data point. The cost of those verification loops doesn’t appear on your bill.

    The agency math, made simple

    Consider a mid-market agency managing 8 client brands. On raw API pricing, billing becomes a shared-credit nightmare: one client’s PR crisis triples their monitoring volume and burns through the agency’s token budget. A client requesting deep sentiment analysis subsidizes one that only needs basic tracking. Attributing actual costs per client is nearly impossible.

    On Topify Pro ($199/mo, 22,500 analyses), the numbers work cleanly:

    • 22,500 ÷ 8 clients = 2,812 analyses per client per month
    • $199 ÷ 8 clients = $24.88 per client per month

    Even if Client A’s situation turns negative and the AI generates longer responses, the agency’s cost stays at $24.88. The token drain is absorbed by the platform. The agency can focus on strategy and client value instead of margin erosion.

    6 Questions to Ask Before Signing Any AI Monitoring Contract

    Before committing to a monitoring vendor, run through this checklist:

    1. Does pricing scale by tokens, prompts, or analyses? Prompt- or analysis-based pricing is predictable. Token-based pricing isn’t.

    2. Which models are actually running? The difference between Claude 4.6 Sonnet and Claude 4.6 Opus isn’t just quality. It’s $22 per million output tokens. Make sure you know which tier you’re getting.

    3. Does the base plan include multi-platform coverage? Monitoring ChatGPT only tells you part of the story. Confirm whether Gemini, Perplexity, and others are included or add-on costs.

    4. Is there built-in hallucination detection? Without a verification loop, your data quality is unreliable. Ask whether the vendor handles retry logic internally or passes that cost (and complexity) to you.

    5. Can you attribute usage by client or project? For agencies especially, this is non-negotiable. Cost visibility per client is what makes the model billable.

    6. Are real-time search grounding fees included? Some platforms charge separately for grounded search queries. That $35 per 1,000 queries adds up faster than the token cost itself.

    Conclusion

    Token pricing isn’t inherently bad. It’s the right model for exploration, for custom tooling, for one-off deep analysis that needs a flagship model’s reasoning. That use case is real and it matters.

    But brand monitoring isn’t exploration. It’s a factory. The same prompts, the same platforms, the same competitive set, run on a weekly or daily cadence. In that context, token volatility is pure operational risk with no corresponding upside.

    The organizations getting this right in 2026 are treating token-based access as a prototyping layer and production monitoring as a fixed-cost intelligence subscription. That split isn’t about cutting corners. It’s about building a measurement system that actually scales without the economics working against you.

    When your CFO asks what you spent on AI visibility last quarter, “it depends on how many tokens the model used” is not a defensible answer.


    Frequently Asked Questions

    How many tokens does it take to monitor a brand on ChatGPT?

    A single monitoring query typically uses 2,000–13,000 input tokens (prompt plus context) and 500–1,500 output tokens depending on the complexity of the analysis. For a basic mention check the lower end applies; for competitive sentiment breakdowns, expect the higher end. At Claude Sonnet 4.6 pricing, that’s roughly $0.01–$0.06 per query before any retry costs.

    Is there an AI brand monitoring tool that doesn’t charge by token?

    Yes. Platforms like Topify use a prompt/analysis-based pricing model, where you pay for a monthly volume of analyses rather than the underlying token consumption. This means the vendor absorbs retry costs and verification overhead, and your monthly spend stays predictable regardless of output length or model behavior.

    How does Claude’s token pricing compare to other AI models for brand monitoring?

    Claude 4.6 Sonnet sits at $3.00/1M input and $15.00/1M output, making it a mid-tier option suited for general visibility tracking. Claude 4.6 Opus ($5.00/$25.00) is better for high-stakes reputation or legal risk analysis where reasoning depth matters. For high-volume, lower-complexity tasks, budget models like GPT-5.2 Nano ($0.05/$0.40) can significantly cut costs, but at the expense of analytical depth.


    Read More

  • How to Slash Token Usage While Tracking AI Brand Visibility

    How to Slash Token Usage While Tracking AI Brand Visibility

    Track how ChatGPT and Perplexity mention your brand — without letting API costs spiral out of control.

    You set up an AI monitoring script. It runs. Two weeks later, the API invoice arrives and the number is three times what you budgeted.

    That’s not a freak accident. It’s the default outcome of applying traditional SEO monitoring logic to a system that charges by the token. The math is punishing in ways that aren’t obvious until you’re already in the hole.

    Here’s how to track brand visibility across ChatGPT and Perplexity without burning your token budget — and what that actually looks like in practice.

    Your Token Bill Spikes Faster Than You Think

    Most teams underestimate AI monitoring costs because they calculate against a single query. The real cost multiplies quickly once you account for how LLM-based monitoring actually works.

    Large language models are probabilistic. The same prompt doesn’t return the same answer twice. To get statistically reliable visibility data, you need multiple samples per prompt — typically three to five runs to establish a baseline. That sampling requirement alone doubles or triples your raw token count before you’ve even optimized anything.

    Then there’s the system prompt problem. Every API call carries your system instructions. A system prompt that starts at 500 tokens tends to grow — added context, extra constraints, few-shot examples — and quickly balloons to 1,800 tokens or more. For a monitoring system running 5,000 calls a day, that bloat costs tens of thousands of dollars a year in pure overhead. The queries haven’t changed. The instructions are just getting heavier.

    Add cross-platform tracking and the pressure compounds. ChatGPT and Perplexity index differently: Perplexity pulls from real-time web searches, Reddit threads, and review sites like G2. ChatGPT leans on its training corpus and high-authority licensed content. Because their ecosystems diverge, most DIY systems run full-volume scans on both platforms independently — which effectively doubles your spend without doubling your insight.

    Most Teams Are Querying AI the Expensive Way

    The “spray and pray” approach works in deterministic search. In token-billed LLMs, it destroys budgets.

    Here’s how it typically plays out: a team wants to track a cloud services brand, so they build queries for every long-tail variation they can think of — “best cloud storage for small businesses,” “affordable cloud servers,” “cloud services with auto backup” — and run each one as a separate API call. These queries overlap heavily in semantic space. The model surfaces similar brand recommendations across all of them. You’re paying for redundant signal.

    Uncompressed tool definitions and verbose JSON schemas compound the waste. Research on production LLM systems shows that poorly structured outputs — where you’re requesting a full narrative response instead of a compact structured extract — can inflate output token spend by 70% or more compared to format-constrained alternatives.

    The cross-platform mirroring problem is just as costly. If a brand has 30% mention rate on Perplexity but near-zero on ChatGPT, running identical query volumes on both platforms makes no economic sense. Most DIY scripts don’t account for this asymmetry. They mirror queries across platforms regardless of where signal actually exists.

    That’s the gap between a scraping script and a monitoring architecture.

    5 Ways to Slash Token Usage Without Losing Coverage

    1. Prioritize High-Signal Prompts Over Full-Keyword Sweeps

    You don’t need to track 500 prompts to understand your brand’s AI visibility. You need to track the right 50.

    The goal is identifying which queries actually sit on your customers’ decision path — the moments where AI recommendations influence purchase or evaluation behavior. Research on AI monitoring systems indicates that tracking the top 20% of high-intent queries covers roughly 80% of the brand visibility conversion points in the AI ecosystem.

    Start by mapping your customer’s decision journey, then identify the prompts that correspond to each stage: awareness, comparison, and selection. That’s your core prompt library. Everything else is optional depth.

    2. Use Response Sampling Instead of Full-Text Capture

    You don’t need a 600-word AI response to know whether your brand was mentioned.

    Forcing structured, minimal output — brand name, ranking position, sentiment score — through constrained prompt formatting can cut output token consumption by more than 70% compared to open-ended responses. For routine daily baseline checks, this lightweight approach gives you enough signal to detect trends without paying to generate paragraphs of context you won’t read.

    Reserve full-text capture for high-signal events: a competitor spike, a sentiment shift, a new prompt category performing unexpectedly.

    3. Use Batch Processing for Non-Urgent Monitoring Tasks

    For weekly audits, competitor share analysis, or historical trend tracking, real-time API calls are the wrong tool.

    OpenAI’s Batch API and equivalent batch processing options from other providers typically offer 50% price reductions in exchange for delayed responses, usually within 24 hours. The trade-off is almost always worth it for anything that isn’t crisis monitoring.

    Processing ModeCostBest For
    Real-time API100% (standard price)Crisis PR, breaking sentiment shifts
    Batch API50% (discounted)Weekly visibility reports, audits
    Utility model routing (Nano/Mini)10–20%Basic mention detection, initial filtering

    Mapping your query types to the right processing tier — before you build the system, not after — is one of the highest-leverage architectural decisions you can make.

    4. Set Visibility Thresholds to Trigger Queries On Demand

    Not all monitoring needs to run on a fixed schedule. A smarter approach uses a tiered trigger system.

    Run lightweight, low-cost scans continuously using utility models (GPT-5.4-nano or equivalent). Reserve expensive high-fidelity analysis for threshold events — for example, when a competitor’s mention rate on Perplexity spikes more than 15% in a single day, or when brand sentiment drops below a defined floor. That triggers a deeper query cycle using a more capable model.

    This alarm-system approach keeps your baseline spend low while ensuring you don’t miss the moments that actually matter. Most brands don’t need hourly deep analysis. They need reliable detection of anomalies and the capacity to respond fast when they appear.

    5. Standardize Prompt Structure and Implement Caching

    Prompt caching allows you to store stable system instructions and background context so they aren’t re-billed on every API call. Providers including Anthropic and OpenAI offer caching discounts of up to 90% on repeated prompt segments.

    Pairing caching with a compact output format — structured text fields instead of verbose JSON schemas — reduces structural token waste by 30% to 60%. The savings compound over time. A monitoring system that runs thousands of queries per month accumulates meaningful cost reductions from these two optimizations alone, without any change to what you’re actually measuring.

    What Efficient Tracking Looks Like in Practice

    Numbers are clearer than principles, so here’s a concrete example.

    Take a mid-sized cloud services company running 10,000 cross-platform queries per month with a DIY script. At standard API rates using a frontier model with no optimization, monthly API spend lands around $1,200. The system catches brand mentions but struggles with accuracy — hallucinations aren’t filtered, competitor tracking is limited to three names, and the prompt architecture is bloated.

    After restructuring with a three-layer approach — nano model for daily full-sweep detection, batch API for deep analysis on flagged prompts, and prompt caching for system instructions — the same brand coverage costs $480 per month. That’s a 60% reduction. Competitor tracking expands from three to ten names. Brand coverage accuracy improves from 85% to 98% because multi-step verification filters out hallucinated mentions.

    Less spend, broader coverage, higher accuracy.

    That’s not a theoretical outcome. It’s the direct result of matching query type to processing mode and eliminating structural redundancy.

    When DIY Stops Making Financial Sense

    Token spend is only part of the cost. Once you factor in everything required to build and maintain a production-grade monitoring system, the economics shift.

    Building a monitoring pipeline that handles API connection management, cost observability, output validation, and prompt versioning typically consumes 80% of an engineering team’s time on infrastructure — time not spent on anything that generates revenue. AI engineers command 30% to 50% salary premiums over traditional DevOps. Meeting GDPR and SOC2 compliance standards for data storage and processing adds $50,000 to $100,000 in annual overhead for most organizations.

    Then there’s the fragility problem. OpenAI and Anthropic release model and pricing changes nearly every quarter. Custom scripts built against one API version regularly break on the next, generating constant maintenance cycles that accumulate into significant annual engineering cost.

    None of these costs appear in a token bill. All of them appear in a P&L.

    A purpose-built platform doesn’t just reduce API overhead. It eliminates the infrastructure maintenance burden, the compliance exposure, and the engineering distraction — and it handles edge cases that a script simply can’t, like cross-model context reuse and normalized sentiment scoring across different LLM output formats.

    How Topify Tracks AI Brand Visibility Without the Token Overhead

    Topify was designed around coverage efficiency rather than query volume. The architecture eliminates redundant token spending at the structural level, before a single API call goes out.

    The platform’s High-Value Prompt Discovery engine uses semantic clustering of real user search behavior to generate a compact, full-funnel prompt set for each brand. Instead of asking you to input hundreds of keywords, it identifies the queries that actually drive brand recommendations — from initial awareness through competitive evaluation — and builds a prompt library optimized to minimize input token redundancy.

    Topify’s cross-platform tracking uses a single query cycle to capture visibility data across ChatGPT, Perplexity, Gemini, and other major AI platforms. Where DIY systems run separate full-volume scans per platform, Topify’s architecture reuses context across platforms and applies intelligent routing — directing queries to Perplexity when real-time web search signal is needed, to ChatGPT when reasoning-based recommendations are the target. That cross-model efficiency translates directly to lower per-insight cost.

    A few other structural advantages worth noting:

    Unified sentiment scoring normalizes output from different models onto a single scale (–100 to +100), eliminating the token overhead of running separate sentiment analysis pipelines per platform.

    Source fingerprinting means that when multiple AI platforms cite the same web page, Topify parses it once rather than billing for redundant retrieval and preprocessing.

    Dynamic sampling frequency adjusts automatically based on brand activity — running lightweight checks during quiet periods and ramping up precision during PR events or competitive spikes.

    For teams on the Basic plan at $99 per month, that architecture covers 100 prompts and 9,000 AI answer analyses across ChatGPT, Perplexity, and AI Overviews — without requiring you to build or maintain any of the underlying infrastructure.

    Conclusion

    Token costs in AI brand monitoring aren’t a billing quirk. They’re the direct result of applying high-volume, undifferentiated query logic to a system that charges per word generated.

    The fix isn’t spending less on monitoring. It’s spending more precisely. High-signal prompt selection, response format constraints, batch processing, threshold-triggered analysis, and prompt caching each reduce waste without reducing coverage. Together, they typically cut token spend by 50% to 60% while improving data quality.

    For teams tracking more than a handful of prompts across multiple platforms, rebuilding that efficiency layer from scratch is rarely the highest-value use of engineering time. A platform with the optimization logic already built in changes the economics entirely.

    Brand visibility in AI search is becoming a core growth channel. The question isn’t whether to track it. It’s whether you’re doing it in a way that compounds over time — or one that quietly drains your budget while you’re looking somewhere else.

    FAQ

    Why is my brand visible on Perplexity but invisible on ChatGPT?

    The two platforms index differently. Perplexity relies on real-time web search and pulls from recent blog posts, Reddit discussions, and press releases. ChatGPT’s responses reflect its training corpus and tend to favor long-established domain authority. A brand that’s been publishing actively for six months might show up prominently in Perplexity while remaining largely absent from ChatGPT. Closing that gap typically requires building the kind of long-form, citation-worthy content that earns references from high-authority sources.

    What’s the fastest way to cut token costs without changing what I track?

    Enable batch processing for any monitoring that doesn’t need to happen in real time. Switch output format from open-ended text to structured minimal fields — brand name, position, sentiment flag. Those two changes typically reduce monthly spend by 50% to 70% with no change to what you’re measuring.

    Does traditional SEO (backlinks, domain authority) still influence AI brand visibility?

    Less than it used to. AI models weight entity association and information gain more heavily than raw link equity. Pages with original statistics, expert citations, and clear topical authority are cited roughly 30% to 40% more often than pages that rely primarily on inbound links. The optimization target has shifted from link acquisition to content credibility.

    At what scale does a purpose-built platform outperform a DIY script?

    The crossover typically happens around 50 to 100 prompts tracked per month across two or more platforms. Below that, a well-optimized script can be cost-effective. Above it, the infrastructure overhead — maintenance, compliance, versioning — starts to exceed the cost of a platform subscription.

    Read More