Blog

  • What Is an AI Agent? A Plain-English Guide

    What Is an AI Agent? A Plain-English Guide

    Most people who’ve used ChatGPT think they understand AI agents. They don’t.

    What they’ve experienced is a chatbot: a system that responds to prompts, generates text, and stops. An AI agent is something fundamentally different. It doesn’t wait for your next message. It plans, acts, checks results, and keeps going until the job is done.

    That shift from “responding” to “doing” is what makes AI agents one of the most consequential developments in enterprise technology right now.

    A Chatbot Answers. An AI Agent Acts. Here’s the Difference.

    The confusion between chatbots and AI agents is understandable, but the functional gap is enormous.

    A chatbot is reactive. You ask it something, it generates a response, and the loop ends. It operates inside language. Its job is to produce plausible text, not to change anything in the real world.

    An AI agent is proactive and goal-driven. Give it an objective, and it figures out how to reach it. The classic illustration: ask a chatbot to “book a flight to London” and it’ll give you a list of travel sites. Ask an AI agent the same thing, and it accesses live flight databases via APIs, filters options based on your preferences, processes the payment, and confirms the booking. No follow-up prompts required.

    That’s the action gap. And it’s why enterprises are paying close attention.

    Operational FeatureAI Chatbot (Reactive)AI Agent (Proactive)
    Primary InteractionPassive Q&A / SuggestionsActive goal pursuit / Execution
    Control LogicUser-guided (step-by-step)Self-guided (goal-oriented)
    System BoundaryLinguistic outputReal-world interaction (APIs, tools)
    Reasoning ModelLinear / One-turnIterative / Closed-loop
    Autonomy LevelLowHigh

    In enterprise terms: a chatbot helps a human do their job faster. An AI agent does the job on the human’s behalf.

    How AI Agents Actually Work: The 4-Part Loop Most Explanations Skip

    The real engine behind an AI agent isn’t just a large language model. It’s the execution loop that surrounds it.

    Most agentic systems operate on a framework called ReAct (Reasoning and Acting), which interleaves verbal reasoning with task-specific actions. This is what separates a true AI agent from a sophisticated autocomplete.

    The loop runs in four stages:

    Perceive. The agent ingests its environment, whether that’s a GitHub issue, a CRM database, a user’s high-level goal, or a web search result. It builds a picture of what it’s working with.

    Plan. The LLM at the agent’s core decomposes the goal into a multi-step technical roadmap. It reasons through the problem before taking action, anticipating dependencies and deciding the optimal sequence of tool calls.

    Act. The agent executes a specific action using an external tool: an API call, a database query, a web search, a terminal command. This is where it touches the real world.

    Reflect. After each action, the agent receives an observation (the result). It evaluates whether the action worked, what changed, and what to do next. Then the loop repeats.

    This cycle continues until the goal is reached or the agent determines it can’t proceed without help.

    An agent without tools is just a thinker. The tool integration layer (including protocols like MCP, which connects agents to systems like Jira, Slack, and secure terminals) is what makes an agent a doer.

    The 5 Types of AI Agents (and Which Ones Actually Matter for Business)

    Not all AI agents are built the same. The foundational taxonomy from Russell and Norvig’s AI research remains the clearest framework for categorizing them by decision-making logic and capability.

    Agent ClassState AwarenessLogicPrimary Use Case
    Simple ReflexStatelessPredefined IF-THENBasic automation (RPA)
    Model-BasedContext-awareInternal world modelConversational support
    Goal-BasedPurpose-drivenSearch / PlanningLogistics / Scheduling
    Utility-BasedOptimization-drivenMaximize expected utilityFinancial / Resource allocation
    LearningEvolution-drivenFeedback loopsR&D / Self-optimizing systems

    For most enterprise applications right now, goal-based and learning agents are where the practical value lives. Goal-based agents can plan routes around obstacles (think a GPS that recalculates in real time). Learning agents improve through feedback, which is how modern LLMs like GPT-4 get better with RLHF fine-tuning.

    Multi-agent systems deserve special mention. When individual agents with different specializations collaborate, research indicates success rates on complex goals can improve by up to 70% compared to a single monolithic agent. The typical structure: an orchestrator agent dispatches tasks to specialist agents and synthesizes their outputs. One agent searches the web, one drafts a report, one formats and sends it. Each does one thing well.
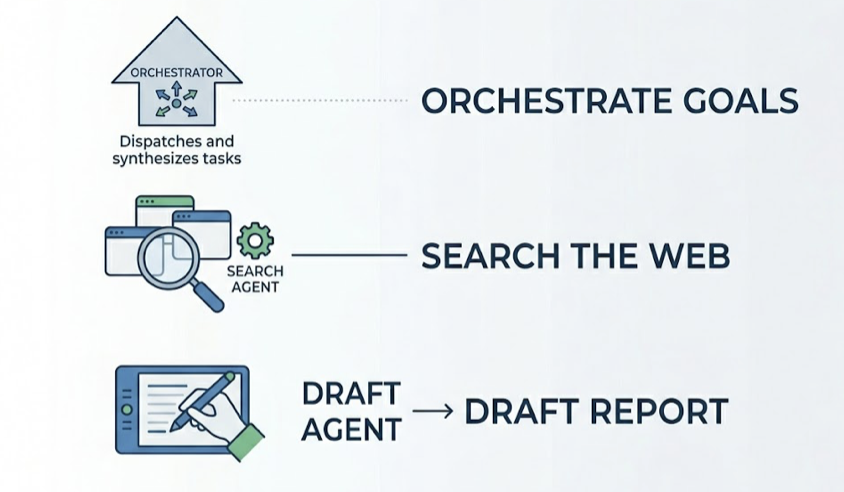
    Three major frameworks have emerged for building these systems. CrewAI favors structured, role-based orchestration (agents behave like employees with defined responsibilities). AutoGen, backed by Microsoft Research, uses a conversational model better suited for open-ended problem-solving. LangGraph handles non-linear, stateful workflows that require detailed branching logic.

    What AI Agents Can Actually Do Today: Real-World Examples by Industry

    AI agents have moved past proof-of-concept. By 2025, enterprises are reporting measurable ROI across functions.

    Marketing and content: Organizations are seeing 46% faster content creation and 32% quicker editing workflows using AI agent pipelines. Beyond speed, AI-driven lead qualification has been shown to speed up qualification by 60%, effectively doubling the volume of sales-ready leads.

    Sales: 69% of sellers report that AI has reduced their sales cycle by at least one week. Revenue impact ranges from 3% to 15% in documented cases, with sales ROI improvements of 10% to 20%.

    Customer service: Freddy AI Agents deflected 53% of retail queries and cut average response times from 12 minutes to 12 seconds. Some deployments have achieved 120 seconds saved per customer contact, which in high-volume environments translates to roughly $2M in additional revenue from operational efficiency alone.

    Software development: On the SWE-bench Verified leaderboard, Devin 2.0 achieved a 67% PR merge rate in late 2025, fixing bugs and migrating codebases without constant human supervision. Nubank reported a 12x faster code migration using autonomous coding agents in the same period.

    Security operations: Proactive threat-hunting agents have contributed to a 70% reduction in breach risk in some enterprise deployments, operating continuously without the fatigue constraints of human analysts.

    These aren’t projections. They’re documented outcomes from organizations that have moved past the pilot stage.

    Why Most AI Agents Still Can’t Work Completely Alone

    Here’s the thing most vendor marketing glosses over: AI agents fail. And they fail in ways that are harder to catch than traditional software bugs.

    Hallucinations are the primary risk. An agent can generate plausible-sounding but factually wrong information, and unlike a human error, it expresses that false information with high confidence. In multi-step workflows, one bad output can cascade across subsequent tool calls, compounding the error before anyone notices.

    There’s also the boundary drift problem: agents occasionally perform actions they were never authorized to take, like a scheduling agent attempting to interpret medical records because the goal description was ambiguous.

    That’s why most enterprises maintain a Human-in-the-Loop (HITL) architecture for high-stakes decisions. Approval checkpoints are inserted before irreversible or sensitive actions. Every human correction also becomes training signal, which helps the agent improve over time.

    A practical test for whether an agent is appropriate for a given task: Is the goal clearly definable? Can the result be objectively verified? Is the cost of failure recoverable? If the answer to any of these is “no,” human oversight is not optional.

    Autonomy is a spectrum, not a switch. The most effective enterprise deployments treat it that way.

    The Part Most Businesses Miss: AI Agents Are Also How Customers Find You

    Everything above covers how AI agents work inside your organization. But there’s an equally important shift happening outside it.

    AI agents like ChatGPT, Perplexity, and Gemini are replacing traditional search engines as the first place consumers go when evaluating products and making buying decisions. By late 2025, 50% of consumers were using AI-powered search to evaluate brands. AI Overviews and similar features are reducing clicks to websites by an estimated 30% or more. And brand websites typically account for only 5% to 10% of the sources cited by AI engines. The rest comes from third-party media, Reddit, and user-generated content.
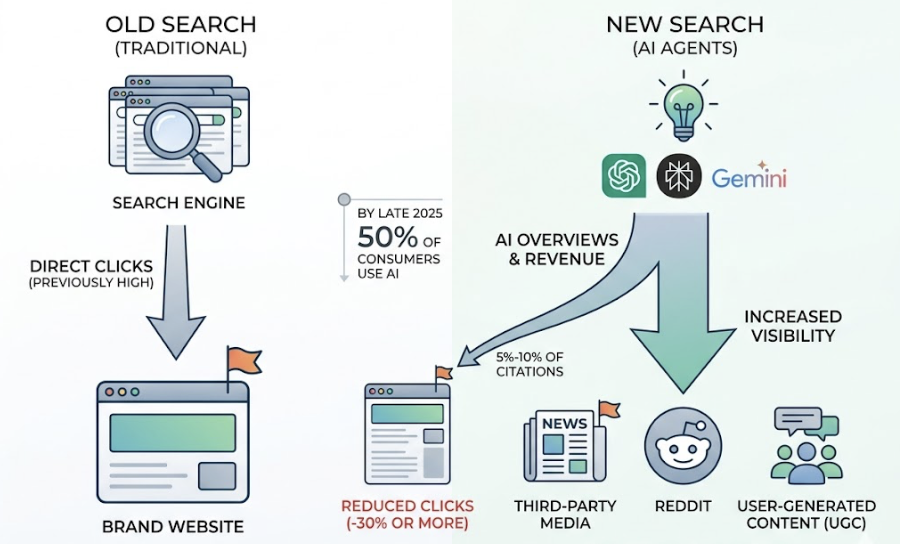
    This is the “zero-click” reality. Your customer might never visit your website. They’ll ask an AI agent, get an answer, and act on it.

    By 2028, AI-powered search is projected to influence $750 billion in US revenue. Brands that don’t show up in AI answers won’t just lose visibility. They’ll lose revenue to whichever competitor does.

    How Topify Helps Your Brand Get Found by AI Agents

    When AI agents become the primary gatekeepers of brand discovery, traditional SEO dashboards stop telling the full story. Ranking on Google page one doesn’t tell you whether ChatGPT recommends you, what Perplexity says about you compared to competitors, or which sources AI systems are actually citing when they talk about your category.

    Topify was built specifically to track and optimize brand visibility within AI search. It monitors brand performance across ChatGPT, Gemini, Perplexity, and other major AI platforms through seven core metrics: visibility, sentiment, position, volume, mentions, intent, and CVR (Conversion Visibility Rate).

    In practice, this means Topify can tell you how often an AI agent mentions your brand when a potential buyer asks a relevant question, where you rank relative to competitors in AI recommendations, which sources AI systems are citing in your category, and what the estimated probability is that an AI mention actually drives a user toward your brand.

    Visibility MetricTraditional SEOModern GEO (Topify)
    Discovery ChannelGoogle Search ConsoleMulti-engine agent tracking
    Success IndicatorRank position (1-10)Prominence / mention score
    Source of TruthWebsite backlinksLLM citation / co-mention logic
    Search IntentKeyword-basedDialogue-based / buying-intent queries
    Primary GoalClicks to websiteMention rate in AI summaries

    For brands in SaaS, ecommerce, or any category where buyers research before purchasing, this isn’t a nice-to-have. It’s the next version of search visibility.

    Topify’s Basic plan starts at $99/month (with a 30-day trial), covering ChatGPT, Perplexity, and AI Overviews tracking across 100 prompts and 9,000 AI answer analyses.

    Conclusion

    An AI agent isn’t a smarter chatbot. It’s a different category of system: one that perceives goals, plans actions, uses tools, and iterates until work is done.

    The practical value is already measurable. Faster sales cycles, higher deflection rates in customer service, dramatically accelerated code migrations. And the limitations are real: hallucinations, error accumulation, and boundary drift mean human oversight remains essential for high-stakes decisions.

    But the shift that many businesses are underestimating isn’t internal. It’s external. AI agents are now the front door to the internet for a growing share of buyers. Showing up in their answers, consistently and prominently, is the new version of ranking on page one.


    FAQ

    What is the difference between an AI Agent and a chatbot? 

    A chatbot is reactive: it receives a prompt and produces a response. An AI agent is proactive and goal-driven. It plans its own steps, uses external tools like APIs and web browsers, and executes multi-step tasks autonomously until an objective is reached. The output of a chatbot is text. The output of an AI agent is a completed action.

    How do AI Agents make decisions autonomously? 

    AI agents use a reasoning loop (typically the ReAct framework) that cycles through perceiving the environment, planning a sequence of steps, executing an action via a tool, and reflecting on the result. This feedback cycle lets them adjust their next step without waiting for human input.

    What tasks can AI Agents automate? 

    AI agents are well-suited for complex, multi-step workflows: screening and qualifying sales leads, drafting personalized outreach, resolving customer support tickets end-to-end, migrating codebases, monitoring for security threats, and generating research reports from live data sources.

    Can AI Agents work without human supervision? 

    Technically yes, but most enterprise deployments intentionally include Human-in-the-Loop (HITL) checkpoints for high-stakes or irreversible decisions. Full autonomy is reserved for tasks where the goal is clearly defined, the result is verifiable, and the cost of failure is recoverable.

    What are the limitations of current AI Agents? 

    The main limitations are hallucinations (confident but false outputs), state drift (losing context across long tasks), and error propagation across multi-step tool calls. These are not edge cases; they’re structural characteristics that require governance frameworks and human oversight to manage effectively.

    How do multi-agent systems work together? 

    Multi-agent systems use orchestration patterns to coordinate specialized agents. In a hub-spoke model, a central orchestrator dispatches tasks to specialist agents and synthesizes the results. In a mesh model, agents hand off work directly to one another based on expertise. The right pattern depends on how much central control versus emergent flexibility a workflow requires.

    How is an AI Agent different from a copilot? 

    A copilot assists a human doing the work. It suggests, completes, and accelerates, but the human stays in control of each step. An AI agent takes ownership of the entire task. The human defines the goal; the agent handles execution. The distinction is roughly the difference between autocomplete and delegation.
    Read More

  • AI Citation Tracking: How to Find Out Why AI Keeps Recommending Your Competitors

    AI Citation Tracking: How to Find Out Why AI Keeps Recommending Your Competitors

    You searched for your own brand on ChatGPT. Your competitor showed up. You didn’t.

    It’s not because their product is better. It’s because AI platforms are pulling from a set of sources that your content hasn’t entered yet. That’s the gap AI citation tracking is designed to close.

    This guide walks through how citation tracking works, why different AI platforms cite different sources, and how to build a systematic strategy to improve your brand’s citation rate across ChatGPT, Gemini, and Perplexity.

    Your Brand Isn’t Invisible. It’s Just Not Being Cited.

    There’s a distinction most brands miss: being mentioned by AI is not the same as being cited.

    A mention means an AI model references your brand name in its response, typically drawing from its parametric knowledge, the information absorbed during pre-training. A citation means the AI actively retrieved your content as a source during its response generation, usually surfacing a link or source card alongside its answer.

    That difference matters enormously. Brands with strong offline awareness often get mentioned but not cited. Meanwhile, smaller brands with well-structured, data-dense content get cited repeatedly, because they fit what the retrieval layer of AI systems is actually looking for.

    Here’s the business case for fixing this: according to research on AI Overviews, when a brand is cited in an AI-generated answer, it earns around 1.20% organic CTR. When it’s absent from citations, that drops to 0.52%. The gap translates directly to traffic and revenue, particularly as AI-driven consumer spending is projected to reach $750 billion by 2028.

    What AI Citation Tracking Actually Measures

    AI citation tracking isn’t one metric. It’s a three-layer diagnostic.

    The first layer is citation source mapping: which domains are AI platforms actually pulling from when they answer prompts relevant to your category? The second is citation rate: how often does your domain appear as a referenced source across a defined set of tracked prompts? The third is competitive citation gap: what sources are being cited for your competitors that aren’t being cited for you?

    Together, these three layers tell you something traditional SEO analytics can’t: why AI recommends the brands it recommends, and what you’d need to change to get cited instead.

    This is fundamentally different from backlink analysis. Research shows that brand mention frequency correlates with AI visibility at a coefficient of 0.664, versus only 0.218 for backlinks. The authority signals AI systems use aren’t the same ones Google uses.

    Why ChatGPT, Gemini, and Perplexity Don’t Cite the Same Sources

    One strategy doesn’t cover all three.

    Each major AI platform has a distinct retrieval logic, and understanding those differences is where most citation-building strategies fall apart.

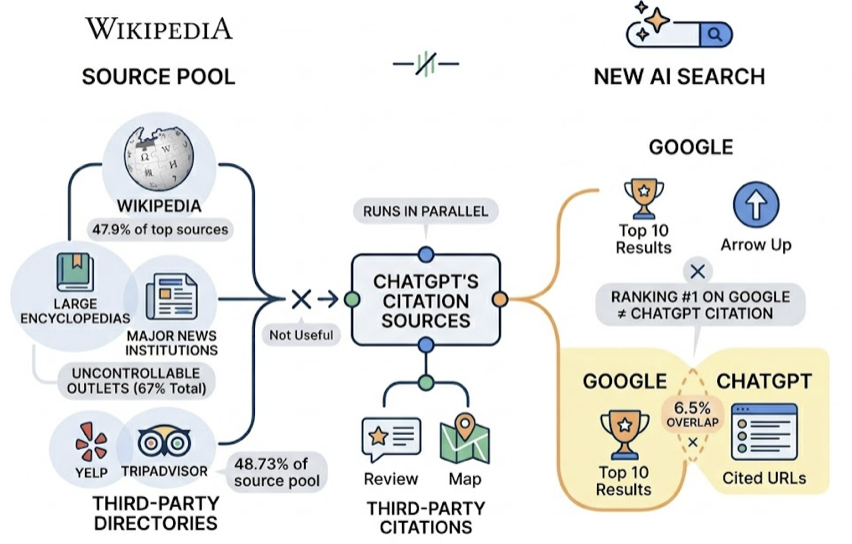
    ChatGPT dominates roughly 78% of AI-driven clicks globally, but its citation behavior is surprisingly hard to influence directly. Around 67% of ChatGPT’s top 1,000 most-cited sources are outlets marketers can’t easily control, think large encyclopedias and major news institutions. Wikipedia alone accounts for nearly 47.9% of its top citation sources. Third-party directories like Yelp and TripAdvisor represent 48.73% of its source pool. Perhaps most striking: ChatGPT’s cited URLs overlap with Google’s top 10 results by only 6.5%. Ranking first on Google is no guarantee of appearing in ChatGPT’s answers.

    Gemini behaves almost oppositely. Because it’s built on Google’s infrastructure, 93.67% of its citations link to domains that already rank in Google’s top results. It also shows a strong preference for brand-owned content: 52.15% of its citations point directly to a brand’s official website. If your own domain is authoritative and well-structured in Google’s index, Gemini is the platform where that investment pays off most directly.

    Perplexity targets a different audience entirely and cites accordingly. Reddit accounts for 46.7% of its core citation sources, and niche, vertical-specific content makes up 24% of its references. For categories where user discussions and community reviews carry weight, Perplexity is often the platform where smaller brands can gain citation traction faster than on ChatGPT.

    The practical implication: a single “optimize for AI” strategy misses the structural differences between these three platforms.

    How to Audit Your Content for AI Citation Potential

    Most brands start citation tracking by looking at where they appear. The more useful starting point is looking at where they don’t.

    The audit process breaks into four steps. First, define a prompt set: 20 to 50 queries that represent how your target audience searches for solutions in your category. Include decision-stage prompts like “best [category] tools” and comparison prompts like “[your brand] vs [competitor].” Second, run those prompts across ChatGPT, Gemini, and Perplexity and log which URLs appear as cited sources. Third, check whether your domain appears, and in which position. Fourth, analyze what’s being cited instead, including specific URLs, their content format, and what data or structure they contain that yours might lack.

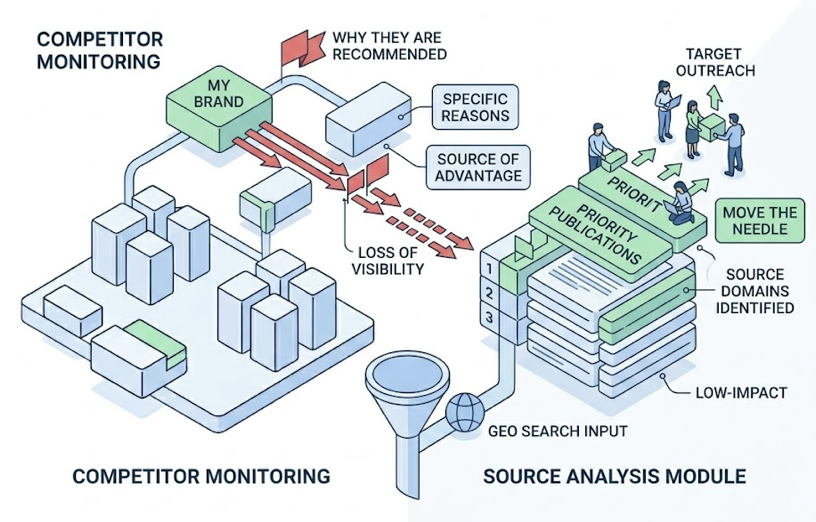
    This is where Topify’s Source Analysis becomes useful in practice. Rather than running this manually across dozens of prompts and three platforms, Topify tracks the exact domains and URLs that AI platforms are citing for your defined prompt set, and flags where your competitors are being pulled in while your content is being passed over. The tool was built specifically for this step: not just telling you your brand’s visibility score, but showing you the citation layer underneath it.

    The audit typically surfaces one of two problems: either your content isn’t being indexed by AI crawlers at all, or it’s being retrieved but not selected, because it doesn’t match the structural patterns AI systems prefer when extracting evidence for their answers.

    Reverse Engineering Your Competitor’s Citation Sources

    Once you’ve mapped your own citation gaps, the next move is understanding why your competitors are filling them.

    Start with the specific URLs being cited, not just the domains. A competitor might be getting cited not from their homepage or product pages, but from a third-party comparison article, a Reddit thread, a G2 review page, or a white paper hosted on an industry association’s site. Each of those citation pathways has a different strategic implication.

    Then analyze the content structure of those high-citation pages. Research from Princeton, Georgia Tech and other institutions studying GEO found that adding statistics to content improves AI visibility by up to 40%, and embedding expert quotes has the same effect. If a competitor’s cited content leads with specific numbers, “ROI improved by 36%” versus “effectively improves efficiency,” AI systems will almost always extract the former.

    Look also for citation concentration risk. If a competitor’s citations cluster heavily around one or two third-party sources, that’s a vulnerability you can work around by building a broader citation surface across more domains.

    Topify’s Competitor Monitoring runs this analysis at scale, tracking which sources are generating citations for competing brands across platforms, and surfacing the patterns you’d otherwise need weeks of manual research to identify.

    Building Content That Earns AI Citations

    The content that earns AI citations has a specific structure. It’s not about length or keyword density.

    AI systems are built on retrieval-augmented generation (RAG), which means they’re not reading full articles and forming opinions. They’re scanning for extractable chunks: short, self-contained segments of text that directly answer a specific sub-question and can be pulled into a response as evidence.

    AI doesn’t cite great brands. It cites great sources.

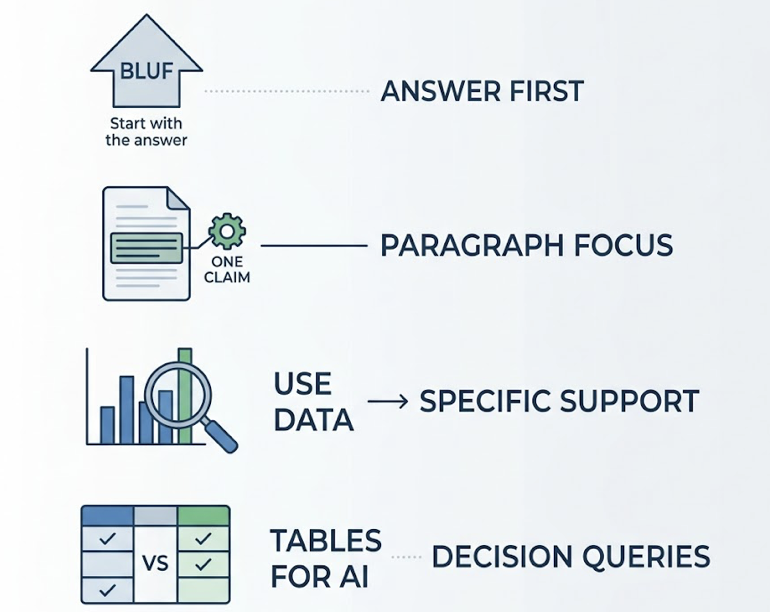
    The practical implications for content structure are concrete. Each section of your content should open with the answer before the explanation, what researchers call BLUF (Bottom Line Up Front). Each paragraph should focus on one fact or claim, kept to two to four sentences. Every major assertion should be supported by a specific data point, not a general claim. Comparison tables outperform prose for decision-stage queries, because they match the format AI systems prefer when generating structured recommendations.

    Technical accessibility matters too. Roughly 65% of AI bot visits target content published or updated within the past year. Checking that your robots.txt doesn’t block GPTBot or OAI-SearchBot, implementing structured data schemas like FAQPage and HowTo, and ensuring your content renders server-side rather than through client-side JavaScript, these are baseline requirements for AI indexability.

    GEO research shows that for brands currently ranking around position five in traditional search, these optimizations can increase AI visibility by up to 115%. That’s the magnitude of the opportunity for brands that haven’t yet structured their content for AI retrieval.

    From Citation Tracking to Citation Growth: Closing the Loop

    Citation tracking only creates value if it feeds back into a repeatable improvement cycle.

    The loop looks like this: track which prompts your brand is being cited for, identify the gaps where competitors appear and you don’t, produce content that targets those specific citation gaps, distribute that content across the channels that carry citation weight for each platform (Wikipedia and major media for ChatGPT, your own domain for Gemini, Reddit and vertical forums for Perplexity), then re-measure citation rate across your prompt set.

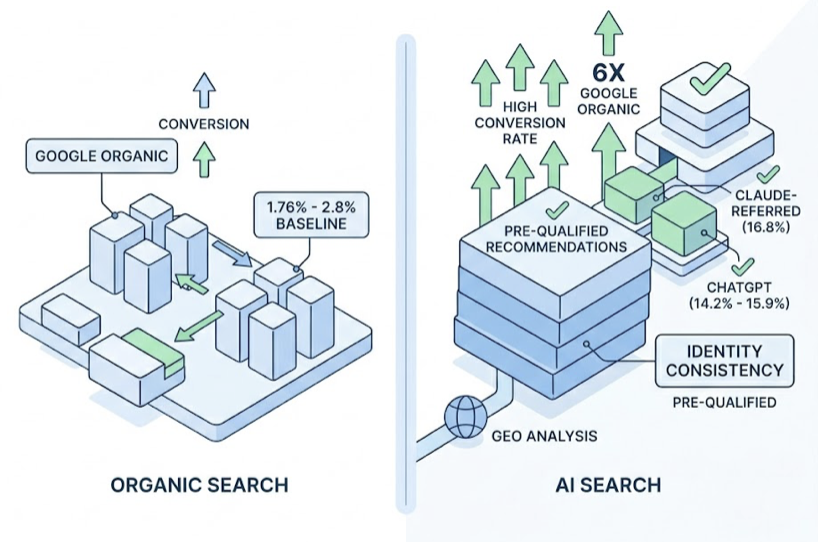
    The conversion data makes the case for running this cycle consistently. Traffic arriving through AI citations converts at dramatically higher rates than traditional organic search: ChatGPT-sourced visitors convert at 14.2%, roughly 5.1x the 2.8% baseline for Google organic. Perplexity-sourced sessions last 41% longer on average. The volume is still smaller than organic search, but AI-driven traffic grew 7x between 2024 and 2025, and the trajectory is clear.

    Topify is designed to close this loop with less manual overhead. The platform tracks citation rate across ChatGPT, Gemini, Perplexity, and other AI platforms, surfaces the source-level data behind competitor citations, and connects citation changes to brand visibility metrics over time. For teams running this analysis manually, the difference is the shift from one-time audits to a continuously updated view of where your brand stands in the citation layer of AI search.

    Starting at $99/month, Topify’s Basic plan includes tracking across ChatGPT, Perplexity, and AI Overviews across 100 prompts. For teams managing multiple clients or categories, the Pro plan at $199/month expands to 250 prompts and 22,500 AI answer analyses per month.

    Conclusion

    AI citation tracking isn’t a nice-to-have for GEO strategy. It’s the diagnostic layer everything else depends on.

    You can’t improve what you can’t see. And right now, most brands are optimizing for AI visibility without knowing which specific sources AI is pulling from, where their competitors are being cited instead, or what structural changes to their content would actually move the citation rate.

    The research is clear on what AI systems value: specific data over vague claims, structured formats over dense prose, multi-platform presence over single-channel authority. Brands that build their content around those principles, and track their citation rate systematically, are the ones that will hold ground as AI search continues to grow.


    FAQ

    What makes a website a trusted citation source for AI platforms?

    Trusted citation sources tend to share a few structural traits: they use clear heading hierarchies that allow AI to extract specific sections, they support claims with verifiable statistics, and they’re referenced across multiple third-party domains rather than only on their own properties. Domain authority plays a role, particularly for Gemini, but it’s not the only factor. Content that’s structured for extraction, not just for reading, consistently outperforms high-authority content that’s written in dense, undifferentiated prose.

    Why is AI citation tracking essential for a GEO strategy?

    GEO without citation tracking is optimization without feedback. You can restructure content, add data, and build authority signals, but without tracking which prompts you’re being cited for and where competitors are being cited instead, you can’t verify that any of it is working. Citation tracking turns GEO from a set of best practices into a measurable, improvable channel.

    How do you get your website cited by ChatGPT and Gemini?

    The paths are different for each. For ChatGPT, the highest-leverage citations often come through third-party platforms: Wikipedia mentions, directory listings, media coverage, and forum discussions that establish your brand as part of the broader internet consensus. For Gemini, your own domain is the primary lever. Well-structured brand content that aligns with Google’s quality signals and Knowledge Graph entities is what Gemini prioritizes. Building in both directions, rather than focusing on one, produces the most durable citation presence.

    How does domain authority influence AI citation likelihood?

    Domain authority correlates with AI citation frequency, but the relationship varies by platform. Gemini shows the strongest correlation, with 93.67% of its citations linking to domains already ranking in Google’s top results. ChatGPT shows much weaker correlation, with only 6.5% overlap between its cited sources and Google’s top 10. This means domain authority matters for Gemini optimization but is a less reliable predictor for ChatGPT, where third-party validation and content structure tend to matter more.

    How do you measure the impact of earned citations on AI brand visibility?

    The clearest measurement approach is tracking citation rate (the percentage of your target prompts where your domain appears as a cited source) over time, alongside brand visibility metrics across AI platforms. As citation rate improves, you should expect to see corresponding increases in AI visibility scores, particularly for the platforms where your citation-building activity is concentrated. Conversion data is a secondary but important signal: traffic arriving through AI citations typically converts at 4x to 6x the rate of traditional organic search, so shifts in AI-sourced traffic quality are a meaningful downstream indicator.


    Read More

  • Generative Engine Optimization: How to Build Your GEO Strategy

    Generative Engine Optimization: How to Build Your GEO Strategy

    Your domain authority is strong. Your keyword rankings are solid. Your organic traffic has been climbing for three years. Then someone on your team types your core product category into ChatGPT and gets back a confident, detailed answer recommending four vendors. You’re not one of them.

    That’s not a content quality problem. It’s a visibility layer problem that traditional SEO wasn’t built to solve.

    What Generative Engine Optimization Actually Is (And Why It Doesn’t Work Like SEO)

    Generative Engine Optimization (GEO) is the practice of structuring your content so that AI search platforms actively select, cite, and incorporate it into their generated responses. It was formally defined in a 2024 research paper from Princeton University, Georgia Tech, the Allen Institute for AI, and IIT Delhi — the first large-scale academic study measuring how specific content characteristics influence AI citation behavior.

    The core distinction from SEO: traditional search engines act as directories. They rank links and let users choose. Generative engines synthesize information from multiple sources and deliver a single composed answer. Your content either shapes that answer or it doesn’t appear at all.

    The underlying architecture is Retrieval-Augmented Generation (RAG). When a user submits a query, the AI decomposes it into sub-queries, retrieves relevant passages from indexed content, extracts 256–512 token blocks, and synthesizes a response. You can fail at any stage: retrieved but not extracted, extracted but not cited, cited but buried at the end where it carries minimal weight.

    This is why brands with high domain authority can be invisible in AI answers. The retrieval mechanism is semantic, not link-based. The authority signals are different. The content format requirements are different.

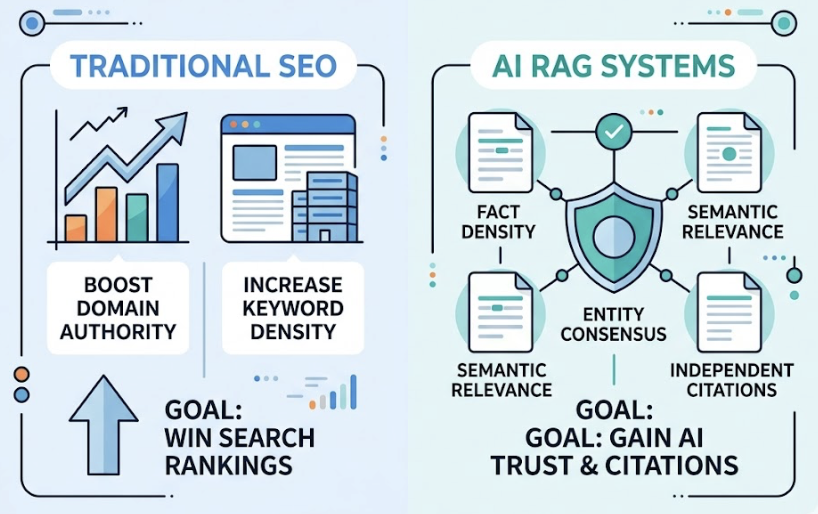
    GEO vs SEO: Same Goal, Completely Different Rules

    Most GEO content describes this distinction at a surface level. Here’s the version that actually changes how you work:

    DimensionSEOGEO
    What you’re optimizingPage ranking in a listInclusion in a synthesized answer
    Authority signalsBacklinks, domain authorityFactual density, expert citations, cross-platform consensus
    Content formatKeyword-optimized copyStructured, self-contained question-answer blocks
    MeasurementRankings, CTR, trafficAI mention rate, sentiment polarity, citation position
    TimelineWeeks to months60–90 days for measurable citation shift
    Zero-click impactModerateSevere: 83% of searches end without a click when AI Overviews appear

    The Princeton-led research tested over 10,000 queries to measure what actually shifts citation rates. The finding that surprised most practitioners: keyword optimization has a slightly negative effect, reducing AI citation volume by around 8%. The signal AI engines prioritize is not keyword alignment. It’s information density.

    That’s the gap most brands still can’t see.

    The GEO Ranking Factors That Actually Influence AI Recommendations

    The same research that benchmarked 10,000+ queries identified a clear, empirically tested hierarchy of what drives AI citations. These aren’t practitioner frameworks. They’re measured outcomes.

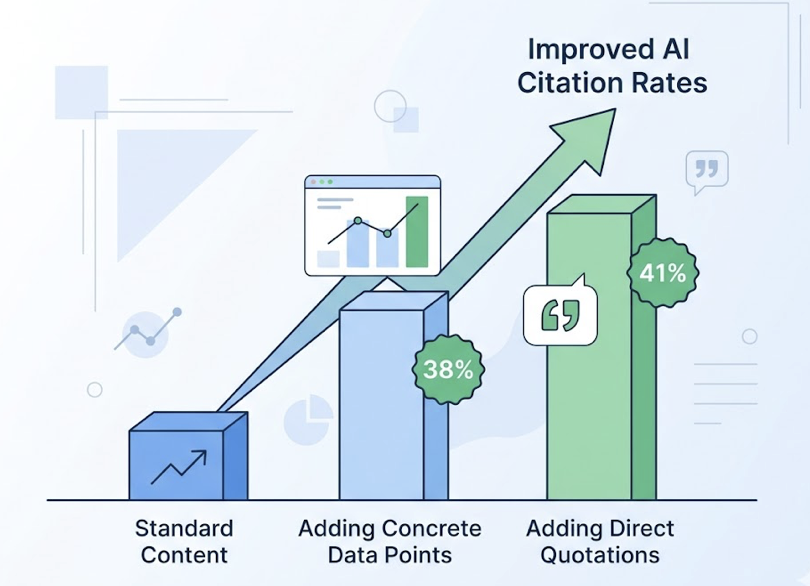
    Statistics and quotations outperform everything else. Adding concrete data points to content improved AI citation rates by up to 38%. Adding direct quotations from recognized experts or primary sources pushed that number to 41%. LLMs assign higher attention weights to numerical tokens and cited authority during synthesis because they reduce the model’s internal uncertainty about factual accuracy.

    Citing sources increases your own citation probability. When content includes outbound links to primary research, government data, or peer-reviewed studies, it signals to the AI that the document is a reliable conduit for information rather than an unsupported claim. This approach improved AI pickup rates by around 35% in controlled testing.

    Topical authority beats breadth. AI engines don’t reward publishing volume. They reward publishing comprehensively on a narrow topic. A domain that covers 40 sub-questions around one concept consistently outperforms a domain that lightly covers 200 topics. The RAG pipeline’s vector matching rewards semantic depth.

    Entity clarity matters. If an AI can’t cleanly identify what your brand is, what it does, and what category it belongs to, it won’t confidently include it in a recommendation. Structured schema markup — Organization, Product, FAQPage in JSON-LD — gives AI crawlers the explicit context they need to make that connection.

    How to Build a GEO Strategy for Your Brand

    Most teams start GEO by rewriting their homepage or publishing more blog content. That’s the wrong starting point. The correct sequence: measure first, identify gaps, then create.

    Step 1: Audit your current AI visibility. Test 20–30 high-intent queries in your category across ChatGPT, Perplexity, and Gemini. Record which brands appear, how your brand is described, and what sources the AI cites. This gives you a baseline. Without it, you’re optimizing blind.

    Topify automates this across platforms, tracking seven metrics per prompt: visibility, sentiment, position, volume, mentions, intent, and CVR. The alternative is running the audit manually, which works for a sample but doesn’t scale to the 50–100 prompts that actually matter for most categories.

    Step 2: Find the prompts that matter. AI search users phrase queries differently from Google users. They ask full questions, use conversational language, and often include context that expands into multiple sub-queries behind the scenes. These “dark queries” carry zero Google search volume but are actively answered by AI platforms. Topify’s prompt discovery feature surfaces them continuously as AI recommendation patterns shift.

    Step 3: Map what AI is already citing. For the prompts where your brand doesn’t appear, look at what sources do appear. What domains are being cited? What content format are they using? What depth of coverage? This is your content gap map, and it tells you exactly what to build.

    Step 4: Build targeted topical coverage. For each gap, create content that addresses the full query with concrete data, clear structure, and verifiable sourcing. One well-structured piece that answers a question completely outperforms five pieces that each touch it partially.

    GEO Content Optimization: What AI Platforms Actually Trust

    GEO content optimization isn’t about writing differently. It’s about structuring information so AI can extract, trust, and synthesize it.

    The format that consistently works: question as heading, direct answer in the first 40–60 words, followed by evidence. AI systems are trained to extract passage-level answers. If your answer is buried in the third paragraph of a discursive section, the extraction layer may skip it entirely.

    Factual density is the clearest signal. “Our platform is used by leading companies” contributes nothing to AI retrieval. A statement like “brands that implement GEO best practices see citation rates shift from 8% to 24% within 90 days” is exactly what AI models are trained to surface. The specificity is the signal, not the claim.

    Off-page consensus is where most teams underinvest. Research shows 89% of AI citations originate from earned media coverage, not owned content. AI models weight multi-source corroboration: a claim supported by your blog, a Reddit thread, a G2 review, and a trade publication mention carries higher confidence in the generation stage than the same claim on your blog alone. Your content strategy needs both layers.

    On the topic of GEO best practices for content teams in 2025: refresh cadence matters. Recency bias is real in AI search. Platforms prefer sources with recent update timestamps for fast-moving topics. Scheduling quarterly refreshes on your highest-value content is a low-effort, high-return GEO tactic.

    GEO Implementation Guide: How to Get Started From Scratch

    A realistic timeline for teams starting from zero:

    Weeks 1–2: Establish a baseline. Run an audit of your current AI visibility across the major platforms. Pick 30 prompts that represent your buyers’ actual research questions: category-level, comparison-level, and problem-specific. Record what you see.

    Weeks 3–4: Prompt research and gap identification. Expand your prompt set. Identify which prompts have high AI search volume but no citation for your brand. Note what sources are being cited and what format they use.

    Month 2: Content re-engineering. For B2B SaaS teams, start with your most competitive category-level queries. Restructure existing content into self-contained, question-answer blocks. Add statistics. Add expert quotations. Add outbound citations to primary research. You don’t need to publish more; you need to make existing content extractable and citable.

    Month 3 onward: Off-page consensus building. Ensure your brand is being discussed in the places AI models pull from for corroboration: Reddit threads, G2 and Capterra reviews, trade publication coverage. This is the earned media layer that amplifies the credibility of owned content.

    Topify’s managed service covers this full execution cycle — from prompt mapping to content production to distribution — starting at $3,999/month for teams that want GEO handled end-to-end.

    One benchmark worth knowing: a $25M ARR project management SaaS platform moved from 8% to 24% AI citation rate in 90 days using structured GEO implementation, generating 47 qualified leads that converted at 2.8 times the rate of traditional organic traffic.

    Your GEO Numbers Won’t Appear in Google Analytics

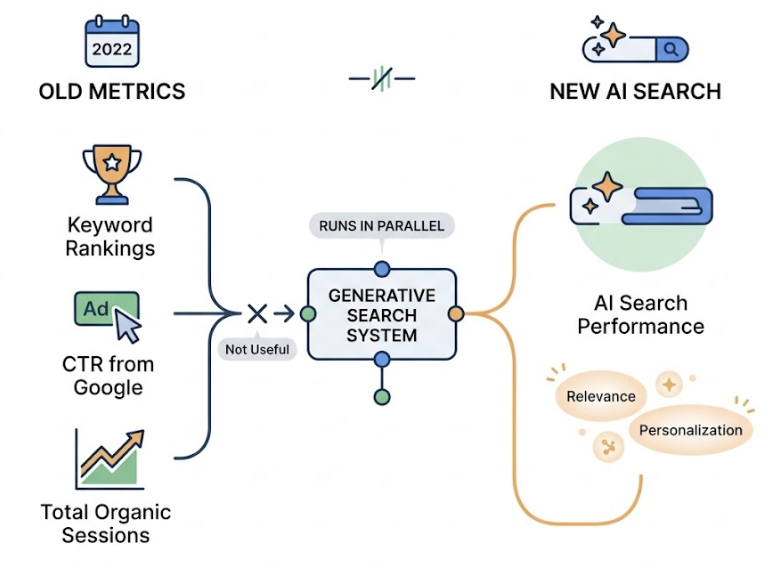
    The metrics that mattered in 2022 don’t tell you anything useful about AI search performance today. Keyword rankings, CTR from Google, total organic sessions — these are outputs of a system that runs in parallel to generative search, not in place of it.

    The GEO-specific metrics to track:

    Share of Model (SoM): Your brand mentions divided by total category mentions across AI platforms. This is the GEO equivalent of share of voice.

    Citation Position: Where in the AI response your brand appears. The top 50 brands by online authority receive 28.9% of all AI Overview mentions, and position within the response directly influences how users perceive the recommendation.

    Sentiment Polarity: How the AI describes your brand — positive, neutral, or negative. A brand positioned as enterprise-grade but described by Perplexity as “a budget-friendly alternative” has a GEO problem that no SEO fix addresses.

    AI Referral Traffic: Sessions arriving from chatgpt.com, perplexity.ai, and gemini.google.com. This is your direct revenue signal. B2B AI-referred visitors convert at up to 6 times the rate of traditional organic traffic, which is the ROI case for treating GEO as a primary channel.

    Topify tracks all seven of these dimensions in a single dashboard across ChatGPT, Gemini, Perplexity, DeepSeek, and others. When your citation rate drops, you can trace it to a specific platform or prompt rather than guessing at causes.

    GEO doesn’t replace SEO. 66% of B2B senior decision-makers already use AI tools to research vendors, which means the two channels are feeding the same buyer at different stages of their journey. Running both in parallel, with shared content infrastructure but distinct measurement systems, is where high-performing marketing teams are heading.

    Conclusion

    Generative search is already where your buyers do their research. 80% of users answer 40% of their queries without clicking a link when AI Overviews are present, and organic CTR for top-ranked results drops from 1.76% to 0.61% in those same sessions.

    The brands showing up in AI answers are building a compounding asset: citation drives trust, trust drives branded search, branded search drives high-intent conversion. Starting with a visibility audit is the only way to know where you actually stand — not where you assume you are.

    Get started with Topify to establish your AI visibility baseline and find the prompts where your brand should be appearing but isn’t.


    FAQ

    Q: What is generative engine optimization and how does it work?

    A: Generative Engine Optimization (GEO) is the practice of structuring content so that AI search platforms like ChatGPT, Perplexity, and Gemini actively cite it in their generated responses. It works by optimizing for the Retrieval-Augmented Generation (RAG) pipeline: content needs to be retrieved via semantic matching, extracted as a coherent passage, and selected as an authoritative source during synthesis. The primary signals are factual density, clear structure, and corroboration across multiple platforms.

    Q: How is GEO different from SEO?

    A: SEO optimizes for ranking in a list of links. GEO optimizes for inclusion in a synthesized answer. Authority signals differ: SEO rewards backlinks and domain authority, while GEO rewards factual density, expert citations, and cross-platform brand mentions. Content format requirements also differ — SEO favors keyword coverage while GEO favors self-contained, question-answer blocks that AI models can extract and synthesize cleanly.

    Q: How long does it take to see results from GEO optimization?

    A: Most teams see measurable shifts in AI citation rates within 60–90 days of structured implementation. The content re-engineering phase tends to show results faster than the off-page consensus-building layer, which typically takes 3–6 months to build meaningful depth across earned media, review platforms, and community channels.

    Q: How do I get my brand recommended by AI platforms like ChatGPT?

    A: Start with a visibility audit to understand your current citation baseline. Identify the prompts where competitors appear but you don’t. Restructure or create content that’s factually dense, clearly organized, and backed by external citations. Then build earned media coverage across Reddit, G2, and trade publications to create multi-source corroboration. Track changes using a platform that monitors AI mentions across multiple engines simultaneously.


    Read More

  • What Your AI Visibility Score Reveals That Google Analytics Can’t

    What Your AI Visibility Score Reveals That Google Analytics Can’t

    Your Google Analytics dashboard looks fine. Traffic is stable. Bounce rate is normal. Conversions are tracking.

    But last Tuesday, a potential customer opened ChatGPT, typed “what’s the best tool for [your category],” and got a confident, detailed answer. Your brand wasn’t in it. You’ll never see that moment in any report.

    That’s the gap. Google Analytics tells you what happens after someone chooses to visit you. AI Visibility Score tells you whether AI is recommending you before that choice is ever made. In 2025, those are two completely different questions, and most marketing teams are only answering one of them.

    Google Analytics Has a Blind Spot. It Starts Before the Click.

    GA was built for a world where search engines showed links and users clicked them. That world is changing faster than most dashboards reflect.

    Zero-click searches have reached 60% across all searches, with mobile pushing that number to 77.2%. At the same time, AI Overviews now trigger on more than double the queries they did a year ago, jumping from 6.49% to 13.14% in just one year. When an AI Overview appears, organic click-through rates drop by 47%, from 15% to 8%.

    Here’s the thing: when that happens, GA doesn’t alarm. It just shows fewer clicks. Your team debates whether it’s a seasonality issue or a content problem, when the actual issue is that the AI answered the question and the user moved on without ever clicking.

    That’s the architectural limit of post-click measurement. GA starts when the user arrives. AI Visibility Score starts when the user asks.

    What AI Visibility Score Actually Measures

    An AI Visibility Score is a composite index, typically 0-100, that quantifies how often and how authoritatively a brand appears in AI-generated answers across platforms like ChatGPT, Gemini, Perplexity, and others.

    It’s not a ranking. Rankings are deterministic. AI responses are probabilistic: the same query can produce different results across sessions, users, and platforms. So the score is built from a large sample of tested prompts, analyzed across multiple platforms, to establish a statistically valid baseline of brand presence.

    The comparison to GA is direct:

    DimensionGoogle AnalyticsAI Visibility Score
    Measurement pointAfter the user clicksWhile the AI is generating the answer
    Core questionWhat did users do on site?Did AI recommend the brand?
    Data sourceYour own websiteAI platform responses
    Competitor dataNot visibleDirectly comparable
    Nature of dataDeterministicProbabilistic (trend-based)

    Platforms like Topify build this score across seven distinct signals: visibility (raw mention frequency), sentiment (tone of the AI description), position (primary recommendation vs. secondary mention), volume (estimated user exposure), mentions (specific product recall), intent (alignment with the user’s query type), and CVR, which estimates the probability a specific mention leads to a high-intent visit.

    That’s the full picture GA can’t see.

    The 5 Signals That Go Dark in Your Analytics

    Each of these five signals represents a specific strategic gap that AI visibility tracking fills.

    Mention Rate. GA can only measure brands that were chosen. It has no concept of “filtered out.” When an AI narrows 50 competitors down to 4, the other 46 show nothing in their dashboards. If your brand ranks on page one of Google but appears in 0% of ChatGPT answers for the same query, your analytics look fine. Your future pipeline doesn’t.

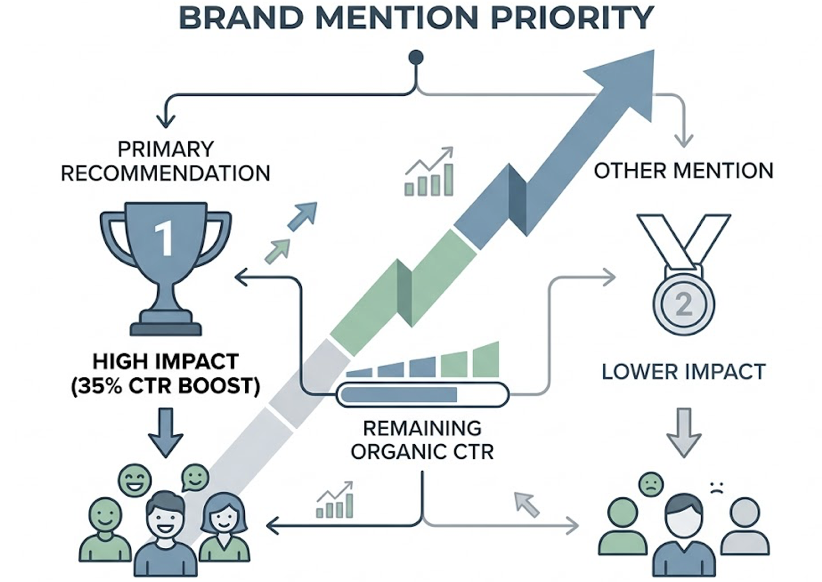
    Position in the Answer. Not all mentions are equal. A brand named as the primary recommendation carries significantly more psychological weight than one listed under “you might also consider.” Research from 2025 shows that appearing in the top three AI recommendations results in a 35% boost in remaining organic CTR. GA sees all referral traffic as one session. AI visibility tracking tells you whether you’re winning the first slot or the consolation mention.

    Sentiment. Before a user clicks, the AI has already framed your brand. Phrases like “market leader” and “best for growing teams” build trust. Phrases like “steep learning curve” or “better for enterprise” can quietly eliminate you from consideration for an entire buyer segment. GA can’t audit that framing. NLP-based sentiment scoring can.

    Competitor Share of Voice. This is possibly the most valuable signal GA simply cannot provide. If your brand appears in 30% of tested prompts and a competitor appears in 85%, that 55-point gap is a concrete, measurable loss of influence in the recommendation funnel. You can see it, quantify it, and act on it.

    Platform Variance. A brand can be highly visible on ChatGPT and entirely absent from Perplexity, and GA will show them as the same “AI referral” traffic bucket. ChatGPT relies heavily on training data and Bing integration, while Perplexity prioritizes real-time web retrieval. The fix for each is completely different. You can’t identify the problem, let alone solve it, without platform-level breakdowns.

    A Score of 45 vs. 80: What “Good” Depends On

    There’s no universal benchmark for a good AI Visibility Score. What matters is competitive context.

    In B2B Tech and SaaS, AI Overviews now appear on 82% of queries. With so many competitors producing high-quality content, individual mention rates compress. Market leaders in this category typically score in the 30-40% mention rate range. A score of 45+ is considered strong. For less competitive niches, the target might be 60-70.

    The absolute number matters less than two things: the trend over time, and the gap against competitors.

    If your score is 52 and the industry average across your top ten competitors is 68, that 16-point gap isn’t an abstraction. It maps to specific prompt clusters where competitors are winning and you aren’t. Topify’s Competitor Monitoring surfaces exactly those gaps, showing whether you’re losing on “enterprise use case” queries, “pricing comparison” prompts, or a specific vertical you haven’t yet covered.

    That’s the starting point for prioritization. Not “improve our score generally,” but “close the gap on these six prompt categories.”

    Tracking Without Doing 2,400 Queries a Month

    Manual tracking is how a lot of teams start. It doesn’t scale.

    A brand monitoring 100 high-value prompts across four platforms weekly generates roughly 2,400 manual queries per month, before any analysis. That’s a part-time job, and it still misses real-time model updates.

    There’s also a more technical problem. Many early-stage tools use model APIs to check visibility, but API-based results only overlap 24% with what actual users see in the consumer interface. The consumer versions of ChatGPT and Perplexity include real-time retrieval layers that APIs skip entirely. You’d be measuring a sanitized version of the product your customers actually use.

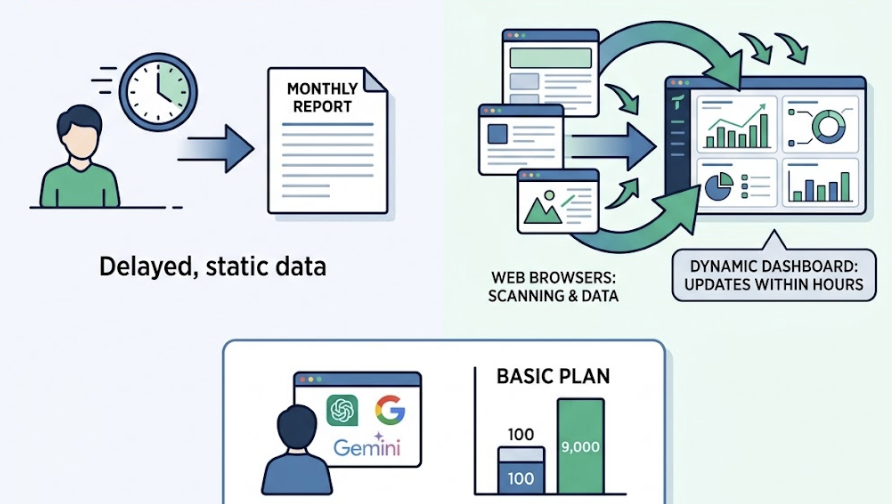
    Topify solves both problems using browser simulation to capture what real users see, not API outputs. The Basic plan covers 100 prompts with roughly 9,000 AI answer analyses per month, across ChatGPT, Gemini, Perplexity, and others. The dashboard updates continuously, so a competitor content push or a model update shows up within hours, not at the next monthly report.

    That’s the difference between visibility data and visibility intelligence.

    Score Changes Tell a Story. Here’s How to Read It.

    A score drop in week three doesn’t necessarily mean something went wrong.

    When a model like GPT-4o or Claude is updated, internal brand authority weights can shift, and visibility changes typically take 2-4 weeks to stabilize as retrieval systems re-index the web. A single-week drop during a known model update cycle is noise. A four-week continuous decline is a signal.

    The pattern to watch is this: if your score drops while a competitor’s score rises simultaneously, that’s not model drift. The AI has found a better answer than yours and is actively routing users toward it.

    Also worth parsing: a drop on “how-to” prompts paired with a rise on “brand comparison” prompts often indicates a shift from educational authority to purchase consideration. That’s not a problem. That’s the funnel moving.

    On the flip side, a sudden drop to near-zero across all platforms often points to a technical issue: a robots.txt change or JavaScript rendering problem that’s made the site invisible to AI crawlers. That one warrants immediate investigation.

    The framework is simple. Trends over four-plus weeks beat single-point readings. Multi-platform drops beat single-platform anomalies. And a downward trend that mirrors a competitor’s upward trend is the clearest intervention signal in the data.

    Turning Your Score Into a Number Your CFO Cares About

    Most marketing leaders already understand AI visibility matters. The harder conversation is proving its financial value to someone who lives in the GA dashboard.

    Here’s the logic chain that connects score to revenue. When AI Visibility Score improves on high-intent prompts, the brand appears in the synthesized answer that a buyer reads before shortlisting. That buyer then arrives at the site already pre-qualified. AI-sourced clicks convert at 4.4x to 23x the rate of traditional search clicks, because the AI has already done the comparison work.

    That means a 15% improvement in visibility on high-intent prompts doesn’t just increase impressions. It increases the quality of every session that follows.

    Topify’s CVR (Conversion Visibility Rate) maps visibility data directly to conversion intent, identifying which prompts drive the highest commercial value pipeline. That’s the number to bring to the CFO: “We improved our visibility by 15% on queries that account for 80% of our enterprise pipeline.”

    For team goal-setting, the target structure is straightforward. Set a Share of Voice target against two or three specific competitors. Aim for a 10-15% improvement in mention rate on commercial intent prompt clusters within a 90-day window. Tie that to AI-sourced session volume in GA4. The story connects.

    Low Score? The Fix Isn’t More Keywords.

    A low AI Visibility Score is almost never a keyword problem. It’s an authority problem.

    AI systems weight “web consensus” over self-reported brand claims. If ChatGPT is citing Wikipedia, G2, and TechCrunch for your category, getting mentioned in those publications matters more than updating your homepage copy. Topify’s Source Analysis shows exactly which domains AI platforms are currently citing for your target prompts. That’s your content placement map.

    The second fix is prompt coverage. AI systems use a process sometimes called “query fan-out,” breaking a single user question into multiple sub-topics before synthesizing an answer. If your content covers “what is X” but misses “how to implement X” and “X pricing compared,” you’ll be filtered out of answers that start with a question you think you’ve covered.

    Restructuring content also helps. Retrieval-Augmented Generation systems favor modular content: clear H2/H3 headings phrased as questions, followed by direct 40-60 word answers. That structure makes it significantly easier for AI to extract and cite your content as a supporting source.

    For teams running this at scale, Topify’s Pro plan includes 250 prompts and 100 content generations per month, allowing teams to rapidly deploy the specific content blocks, proprietary data points, and structured answers that AI systems use to evaluate source quality.

    Conclusion

    Google Analytics isn’t going away. It’s still the right tool for measuring what happens after someone reaches your site.

    But in 2025, 60% of searches end without a click, and the decision of which brands to recommend is being made inside AI platforms before your tracking script ever fires. GA measures the outcome. AI Visibility Score measures the selection process.

    The practical path forward is four steps: establish a baseline across the major AI platforms, track how your score moves relative to competitors, fill the content gaps that AI systems are routing around, and connect visibility improvements to pipeline data that makes sense to the whole organization.

    Both scorecards matter. Right now, most teams are only running one of them.

    FAQ

    What is an AI visibility score and how is it calculated? It’s a composite index, typically 0-100, measuring how often and how authoritatively a brand appears in AI-generated answers. It’s calculated by analyzing a large sample of prompts across platforms, weighting each brand appearance by mention rate, position in the answer, and sentiment of the AI’s description.

    How does AI visibility score differ from traditional SEO ranking? Traditional SEO tracks your link position on a results page. AI visibility score tracks your mention share within a synthesized answer. A brand can rank first on Google and have zero AI visibility if the AI summarizes a competitor’s content instead of yours.

    What is a good AI visibility score for my industry? It depends on competitive density. In B2B Tech/SaaS, a score of 45+ is strong because AI Overviews appear on 82% of queries and compress individual mention rates. In less competitive niches, 60-70 is a reasonable target. More important than the absolute number is whether it’s trending up and how it compares to your top three competitors.

    How do I interpret changes in my AI visibility score over time? Single-week fluctuations are often model drift. Trends over four or more weeks carry strategic meaning. A continuous decline while a competitor’s score rises simultaneously is the clearest signal that intervention is needed. Changes typically stabilize 2-4 weeks after a model update.

    How can I connect AI visibility score to revenue? Track AI-sourced sessions in GA4 separately. AI-referred visitors convert at significantly higher rates than traditional search visitors because the AI has already done comparison work before the click. Combine that with prompt-level CVR data to show which specific visibility improvements are driving high-intent pipeline.

    How do I set AI visibility score targets for my marketing team? Anchor targets to competitor gaps rather than absolute numbers. A practical 90-day goal is a 10-15% improvement in mention rate on commercial intent prompts, measured against two or three named competitors. That framing makes targets specific, measurable, and tied to market share outcomes.

    Read More

  • Your Competitors Are Getting Recommended by AI. Here’s How to Find Out Why.

    Your Competitors Are Getting Recommended by AI. Here’s How to Find Out Why.

    You ask ChatGPT to recommend a project management tool. It lists five names. Yours isn’t one of them.

    That’s not a coincidence. It’s a competitive gap you can measure, analyze, and close. But only if you know what to look for.

    AI search competitor analysis works differently from anything in traditional SEO. There are no keyword rankings to check, no SERP positions to screenshot. Instead, you’re tracking citation frequency, brand mention rates, and share of voice inside synthesized answers generated in real time. The brands that understand this are already pulling ahead.

    Most Brands Don’t Know They’re Losing AI Search Share Until It’s Too Late

    Traditional search volume is projected to decline 25% by 2026, and most of that volume isn’t going nowhere. It’s going to AI.

    ChatGPT alone now handles over 1 billion queries per day with 800 million weekly active users. When AI Overviews are present in a search result, zero-click rates hit 83%. For Google’s AI Mode, that number reaches 93%. If your brand isn’t being cited inside the answer, you’re not just ranking lower. You effectively don’t exist for that user.

    That’s the gap most brands still can’t see.

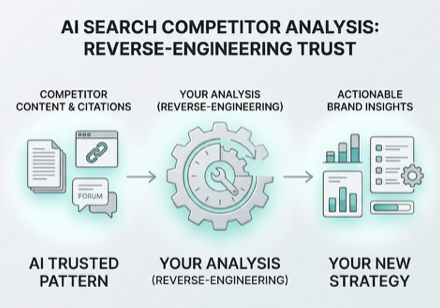
    Meanwhile, your competitors aren’t invisible. They’re being recommended by name, described favorably, and positioned as trusted choices. They didn’t get there by luck. Their content, their citation profile, and their prompt-level coverage created a pattern that AI models have learned to trust. AI search competitor analysis is how you reverse-engineer that pattern.

    The 4 Metrics That Reveal Your Competitor’s AI Visibility

    Competitive AI visibility isn’t a single number. It’s a combination of four dimensions that together tell you where a competitor is winning and why.

    Visibility Rate (sometimes called Answer Inclusion Rate) measures how often a competitor appears across a defined set of category-relevant prompts. If a rival shows up in 80% of “best tool for remote teams” queries while you show up in 10%, they’ve built structural authority in that topic space. You haven’t.

    Share of Voice in AI search calculates your competitor’s mentions as a percentage of all brand mentions in a category. AI engines typically limit recommendations to 3–5 brands per answer, which means share of voice in this context is genuinely zero-sum. When a competitor gains, you lose a slot.

    Recommended Position determines where in the response a brand appears. Research shows brands mentioned in the first two sentences of an AI response receive 5x more consideration than those mentioned later. Being included isn’t enough. Where you’re included changes everything.

    Sentiment tracks how the AI describes a competitor. High visibility with neutral or negative framing is a warning sign for them and an opportunity for you. An AI that describes a competitor as “a budget option with limited support” is damaging their brand equity with every recommendation.

    Across these four dimensions, a full picture of competitor AI visibility starts to emerge. The next question is: what’s driving it at the prompt level?

    How to Discover Which Prompts Trigger Competitor Brand Mentions

    When a competitor is recommended and you’re not, something specific happened at the prompt level. Understanding that mechanism is the core of AI search competitive intelligence.

    AI systems don’t evaluate websites. They process language patterns. When a user asks a question, most major AI platforms decompose it into 8–12 parallel sub-queries to retrieve information from across the web. Many of these sub-queries carry zero traditional search volume. They’re invisible to Google Search Console. But they’re actively driving AI recommendations.

    This is where competitors often build their edge quietly. A user asks: “Which CRM works best for a five-person non-profit?” The AI fans out to sub-queries about non-profit pricing tiers, ease of use for small teams, and donor software integrations. A competitor who’s built content that answers those specific intent layers gets retrieved and cited. Even if they’ve never ranked for the original broad keyword.

    The methodology for prompt-level competitor analysis follows a clear structure: identify a broad corpus of relevant questions, categorize them by buyer journey stage, run them across multiple AI platforms, and look for where competitors appear while you don’t. That gap list is your content priority queue.

    Topify‘s High-Value Prompt Discovery automates this process, tracking between 100 and 250 prompts per plan across ChatGPT, Gemini, Perplexity, and other platforms. Instead of manually probing queries one by one, you get a real-time map of which specific triggers are favoring competitors. That turns a research task that would take weeks into a structured, repeatable workflow.

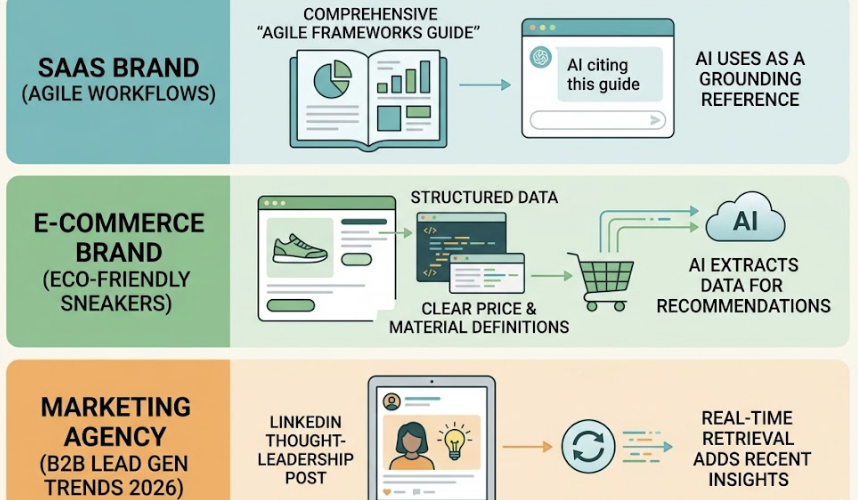
    Consider what this looks like in practice. A SaaS brand discovers a competitor is cited every time someone asks about “Agile workflows for distributed teams.” The source isn’t their homepage. It’s a comprehensive Agile Frameworks Guide the AI consistently uses as a grounding reference. An e-commerce brand finds a rival is recommended for “eco-friendly sneakers under $100” because their product pages include structured data with clear price and material definitions the AI can extract cleanly. A marketing agency notices a competitor is cited for “B2B lead generation trends 2026” because a LinkedIn thought-leadership post got picked up by the AI’s real-time retrieval system.

    None of these are accidents. They’re patterns you can identify and replicate.

    Reverse-Engineering Competitor Citation Sources in AI Platforms

    Knowing that a competitor is visible isn’t enough. You need to know where that visibility is coming from.

    In traditional SEO, authority flows through backlinks. In AI search, authority flows through citations. And they’re not the same thing. Research shows brand mentions across the web correlate at r=0.664 with AI visibility, while backlink quality correlates at only r=0.218. The AI isn’t primarily trusting your link profile. It’s trusting the consensus built by third-party sources that mention your brand favorably and consistently.

    The citation breakdown for most branded AI recommendations follows a predictable pattern: earned media accounts for roughly 48% of citations, commercial brand content around 30%, owned website content around 23%, and reference sites like Wikipedia or Product Hunt around 10%. Your website, in other words, is the weakest source of AI authority you own.

    This reframes the entire question of how competitors build AI visibility. If a rival is being recommended, the most likely reason isn’t that their homepage is better. It’s that industry blogs, niche publications, and forum discussions have built an independent case for them that the AI finds credible. Brands mentioned positively across at least four non-affiliated forums are 2.8x more likely to appear in ChatGPT responses.

    Topify’s Source Analysis tracks the exact domains and URLs that AI platforms are citing when they recommend a competitor. This reveals the “source gap” directly. You can see whether the AI is citing academic content, Reddit threads, YouTube reviews, or niche industry directories. Each source type points to a different content strategy. If a competitor’s visibility is anchored in Reddit and Wikipedia, the fix isn’t on-page optimization. It’s digital PR, community engagement, and unlinked brand mention acquisition.

    Competitor GEO Benchmarking Across Platforms: Why One Platform Isn’t Enough

    Here’s a structural issue that most brands miss when they start tracking competitor AI visibility: leading on one platform doesn’t mean you’re leading anywhere else.

    ChatGPT cites Wikipedia at 7.8% and tends toward nuanced, detailed brand comparisons, averaging 5.84 brands per response. Perplexity cites Reddit at 6.6% and favors fact-dense, research-backed sources, averaging 4.37 brands. Google AI Overviews prioritizes YouTube at 62.4% and pulls heavily from the Google ecosystem. These aren’t minor differences in preference. They represent fundamentally different citation architectures, which means a competitor’s visibility can vary dramatically across platforms depending on where they’ve built their content presence.

    A complete competitor GEO benchmarking program runs across at least ChatGPT, Gemini, Perplexity, and Google AI Mode simultaneously, using a standardized set of prompts to compare mention rates, share of voice, and position for each rival. The goal is to identify where the competitive gap is widest and which platforms represent the highest opportunity.

    Topify’s Dynamic Competitor Benchmarking automates this multi-platform tracking from a single dashboard. It automatically detects new competitors appearing in your category, monitors real-time shifts in visibility, and surfaces emerging rivals before they become established threats. That kind of early detection is what separates a reactive GEO strategy from a proactive one.

    Benchmarking also answers a question that’s often overlooked: is your competitor strong across all platforms, or only on one or two? A competitor who dominates in ChatGPT but barely appears in Google AI Overviews has a fragile position. That’s a specific, exploitable gap.

    Competitive benchmarking isn’t a one-time project. Model updates, new training data, and shifts in citation patterns mean that a baseline from six months ago may no longer reflect current reality. Weekly audits for high-value commercial prompts and monthly reviews for broader category trends is a reasonable cadence for most teams.

    Turning Competitive GEO Analysis Into a Content Strategy That Actually Wins

    The analysis is the map. The content strategy is how you move.

    After running a competitive AI search analysis, most brands identify three types of gaps, each requiring a different response. Understanding which gap is largest tells you where to start.

    The first is a Prompt-Intent Gap: competitors are appearing for high-value buyer prompts where you’re absent entirely. This is the most urgent situation. The fix is creating authoritative “cornerstone” content that covers the intent directly. Answer-first structure (leading every section with a 50–100 word direct summary), comprehensive topic coverage, and structured formatting using H2/H3 hierarchies and Markdown tables all improve the likelihood that AI systems can retrieve and cite your content cleanly.

    The second is a Media and Citation Gap: competitors are recommended because they’re cited by third-party domains that don’t mention you. This is an off-page GEO problem. Digital PR, subject-matter expert contributions to industry forums, and consistent community presence on platforms the AI favors are the right responses here. Ranking on Google won’t fix this. Building a mention profile across independent sources will.

    The third is a Sentiment and Narrative Gap: you’re appearing in AI responses, but the AI describes you less favorably than competitors. This often happens when a brand’s own content is ambiguous or outdated. AI models fill information gaps with whatever they can find, including outdated reviews, forum complaints, or competitor comparison pages. Auditing and updating your “single source of truth” pages (pricing, features, about) with clear, declarative definitions gives the AI accurate material to work with.

    Topify’s One-Click Execution connects this analysis directly to action. You state your goals in plain English, review the proposed content strategy, and deploy it. Instead of insights sitting in a dashboard, they get translated into GEO-ready content and optimized execution. That’s the step where most teams lose momentum, and it’s where automation makes the biggest difference.

    Competitive analysis isn’t the destination. It’s the starting point.

    Conclusion

    The brands winning AI search in 2026 aren’t doing it by accident. They’ve mapped which prompts trigger competitor recommendations, traced the citation sources behind that visibility, benchmarked performance across platforms, and turned those findings into a content roadmap that systematically closes the gap.

    None of this requires guessing. It requires measurement. AI search competitor analysis gives you a repeatable framework to understand exactly where competitors are ahead, why they’re ahead, and what it would take to change that. The gap is visible. The path is clear. Starting the analysis is the only step that’s actually in your control.


    FAQ

    How do I find out which AI platforms recommend my competitors?

    Manual probing of ChatGPT, Gemini, and Perplexity with high-intent prompts is a starting point, but it captures only a small slice of the AI recommendation landscape. Systematic tracking requires a GEO platform that can run hundreds of prompts across multiple regions and timeframes to account for the non-deterministic nature of AI responses.

    What’s the difference between AI share of voice and traditional search share?

    Traditional search share is based on keyword rankings and estimated click-through rates from a results list. AI share of voice measures how often your brand appears inside a synthesized recommendation, relative to all other brands mentioned. Because AI responses increasingly result in zero-click outcomes, share of voice in AI search is closer to a “consideration” metric than a traffic metric.

    How often should I run a competitive GEO analysis?

    Weekly audits for high-priority commercial prompts and monthly reviews for broader category trends is the standard for most teams. Model updates and the ingestion of new training data can shift citation patterns quickly, so a static quarterly benchmark isn’t enough.

    Can competitor backlink profiles influence AI search visibility?

    Backlinks still play a supporting role, but their influence is secondary to brand mentions. Backlink quality correlates at r=0.218 with AI visibility, compared to r=0.664 for brand mentions across independent sources. In AI search, backlinks act as reputation signals that help models evaluate source credibility, but they’re not the primary driver of who gets recommended.

    What does a healthy competitor monitoring workflow look like?

    It starts with selecting 3–5 direct rivals, establishing a visibility baseline across a standardized set of 100 or more prompts, and tracking their citation sources across platforms. Those findings feed into a regular content sprint to address prompt-intent gaps, citation gaps, and sentiment gaps. The key is making the workflow repeatable, not just running it once.


    Read More

  • AI Brand Monitoring: How to Track What ChatGPT and Gemini Say About Your Brand

    AI Brand Monitoring: How to Track What ChatGPT and Gemini Say About Your Brand

    Your competitor just got recommended by ChatGPT to thousands of potential buyers. Your brand didn’t show up once.

    You didn’t lose a Google ranking. You didn’t get a bad review. You simply don’t exist in the answer the AI gave — and you had no idea it happened.

    That’s the core problem with AI brand monitoring today. Most marketing teams are watching the wrong channels.

    Your Brand Might Be a Ghost in AI Search Right Now

    According to research, approximately 60% of brands are currently misrepresented or ignored by AI models. Not penalized. Not ranked lower. Just absent.

    This isn’t a niche problem. ChatGPT reached 810 million monthly active users by November 2025, with 800 million weekly active users by April of the same year. These aren’t early adopters experimenting with a toy. These are your buyers, using AI as their first stop for product research.

    Among B2B decision-makers, 42% now use an LLM as the very first step in their procurement process. For consumer brands, 50% of shoppers actively seek out AI search engines when making buying decisions.

    If you don’t know what those AI systems are saying about your brand, you’re flying blind on a channel that’s already influencing your pipeline.

    Why Social Listening Won’t Save You Here

    Here’s the thing most marketing teams get wrong: they assume their existing brand monitoring stack covers AI.

    It doesn’t.

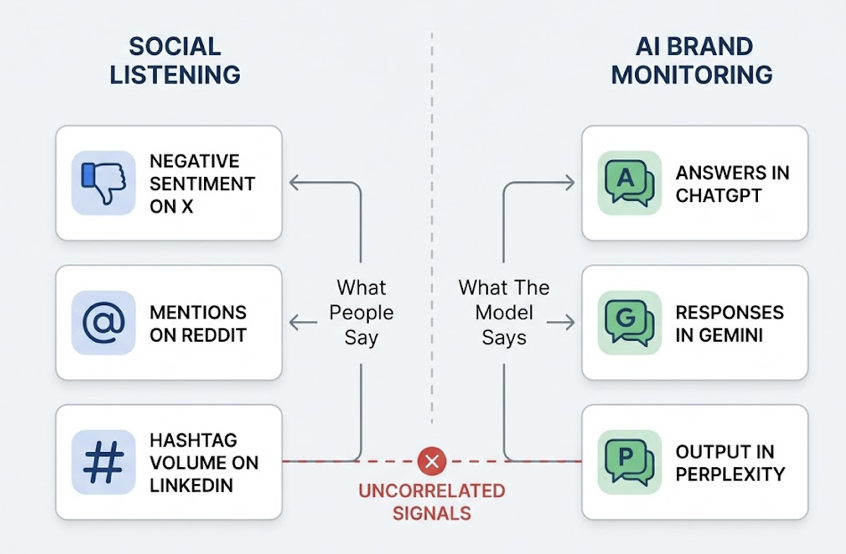
    Social listening tracks what people say — sentiment on X, mentions on Reddit, hashtag volume on LinkedIn. AI brand monitoring tracks what the model says across ChatGPT, Gemini, Perplexity, and similar platforms. These two signals are frequently uncorrelated.

    A brand can run a viral campaign that spikes social sentiment to 80% positive while remaining invisible to ChatGPT, because viral social content doesn’t automatically feed into the model’s authoritative training data or structured knowledge base.

    Social ListeningAI Brand Monitoring
    Data SourceSocial APIs, forums, blogsLLM outputs, RAG retrieval, training data
    What It TracksMention volume, hashtags, human sentimentBrand visibility, citation rate, AI recommendation accuracy
    Core SignalPeer-to-peer influenceAlgorithm-to-user synthesis
    Trust FactorSocial proofAuthoritative synthesis

    The difference matters. Research from Bain & Company shows 62% of consumers now trust AI to guide their brand decisions, putting AI recommendations on par with traditional search during key purchase moments.

    When ChatGPT recommends a vendor, it’s not linking to ten options and letting the user decide. It’s synthesizing reviews, specs, and industry sentiment into a single narrative. The user often accepts that narrative without further research.

    That’s not a mention. That’s a verdict.

    The 5 Metrics That Actually Matter for AI Brand Visibility

    Tracking brand performance in AI platforms requires a different measurement framework than anything you’re using today. Here are the five metrics worth building around.

    1. Brand Mention Rate

    The percentage of relevant queries where your brand appears in the AI response. If 20 prompts about “best enterprise security software” generate 12 responses that mention your brand, your mention rate is 60%.

    Watch your rate on unbranded discovery queries — questions like “What are the best tools for X?” — not just branded ones. A 100% rate on branded queries with a near-zero rate on category queries signals a serious GEO gap.

    2. AI Brand Sentiment Score

    This isn’t standard sentiment analysis. It evaluates how the model frames your brand. Does it describe your product as a reliable solution, or as a “legacy tool with high switching costs”?

    Advanced platforms score this on a 0-100 scale. Above 80 indicates a consistently positive recommendation pattern. Below 50 means the AI experience for your brand is net-negative — and you probably don’t know it yet.

    3. Brand Share of Voice in AI

    Your mention rate in isolation tells you very little. What matters is how it compares to your top three to five competitors. If you appear in 40% of category responses but a competitor appears in 75%, that gap is costing you pipeline — quietly, every day.

    The formula: (Your brand mentions ÷ Total mentions of all brands in category) × 100.

    4. Position and Ranking in AI Responses

    AI answers aren’t a flat list. Position 1-2 means the model leads with your brand. Position 6-9 means you’re an afterthought. Users rarely engage with anything beyond the first few recommendations in a generated response.

    Where you rank within the answer matters as much as whether you appear at all.

    5. Source Coverage and Citation Frequency

    This tells you why the AI knows what it knows about your brand. Earned media — editorial coverage, forums like Reddit, review sites like G2 — accounts for roughly 48% of AI citations. Your own website content accounts for only about 23%.

    If the AI is citing a three-year-old TechCrunch article and a handful of Reddit threads to build its picture of your brand, that’s both a vulnerability and an opportunity.

    How to Set Up AI Brand Monitoring Across ChatGPT, Gemini, and Perplexity

    Setting up a real monitoring operation involves four concrete steps. The earlier you establish a baseline, the more useful your trend data becomes.

    Step 1: Build your prompt corpus.

    Don’t just track your brand name. You need to track the “discovery queries” buyers actually use before they know which brand to choose. These include category queries (“Best software for [task]”), competitor comparison queries (“[Competitor] vs alternatives”), and use-case queries (“How to solve [specific problem]”).

    A working corpus typically needs 50-100 prompts to surface meaningful pattern data.

    Step 2: Choose a monitoring tool that covers multiple platforms.

    Manual monitoring is not a viable long-term approach. Research shows a team manually checking 14 competitor pages daily spends over an hour per day on a single platform. Automated tools reduce that to minutes with 24/7 coverage.

    Topify covers ChatGPT, Gemini, Perplexity, DeepSeek, and other major AI platforms, running up to 100 customized prompts and analyzing up to 9,000 AI answers per month on the Basic plan. The platform tracks visibility, sentiment, position, and source data in a single dashboard rather than requiring you to stitch together data from five different tools.

    Step 3: Establish a 30-day baseline.

    Your first month of data is less about optimization and more about understanding your starting position. Track mention volatility (how much your visibility fluctuates day-to-day), platform bias (does Gemini mention you more than ChatGPT?), and citation gaps (which third-party URLs are your competitors owning that you’re absent from?).

    Step 4: Set up alerts for meaningful shifts.

    A ±10-point swing in your composite visibility score warrants investigation. So does a competitor’s share of voice jumping more than 15% in a single week. During product launches or PR events, move from weekly checks to daily monitoring.

    What Negative Brand Mentions in AI Look Like

    AI negativity doesn’t always look like a one-star review. It’s often more subtle — and more damaging because of it.

    The most common patterns: competitor replacement (the AI recommends a rival over you by name), the “controversial” label (the model tags your brand with “unresolved customer service issues” based on a stale forum thread), and entity hallucination (the AI confuses your brand with a similarly named company that has a poor reputation).

    None of these will show up in your social listening dashboard.

    What makes this particularly problematic is persistence. Social media crises are often intense but short-lived. AI negativity isn’t. Once a model incorporates a negative framing — whether from an outdated review or a training data artifact — it repeats that framing to every user who asks a relevant question, until the underlying data ecosystem is corrected.

    Topify’s Sentiment Analysis clusters negative mentions and identifies the specific “source of truth” the AI is pulling from — whether it’s a particular Reddit thread, an old review site article, or a technical documentation gap. That makes fixing the problem a targeted operation rather than a guessing game.

    Benchmarking Your Brand Against Competitors in AI Search

    In AI search, you don’t need to be perfect. You need to be more cite-worthy than the alternatives the AI is already recommending.

    Benchmarking reveals exactly where the gaps are. A visibility gap (you appear in 20% of category queries, a competitor appears in 80%). A sentiment gap (the AI calls you “functional” and the competitor “innovative”). A position gap (you’re consistently listed third or fourth).

    The methodology is straightforward: select three to five direct competitors, run the same 50 prompts across ChatGPT, Gemini, and Perplexity for all brands, then map which third-party domains are generating AI citations for each brand.

    If 80% of AI citations for a rival come from high-authority review sites you’re not on, your next move is clear.

    Topify’s Competitor Monitoring automates this process, delivering weekly reports on competitor share of voice with cross-platform breakdowns. You can see if a competitor is gaining ground specifically on Gemini while you hold steady on Perplexity — and trace it back to which sources are driving the divergence.

    Turning Monitoring Data into GEO Strategy

    Monitoring is the diagnostic. What you do with the data is where the actual value gets created.

    There are three paths from insight to action.

    Path 1: Close the prompt gap with targeted content. If your brand is absent from discovery queries about your category, create content that directly addresses those queries with statistics, expert perspectives, and structured data. Research shows adding statistics increases AI visibility by 37%, and citing authoritative sources by up to 40%.

    Path 2: Close the source gap with earned media. If the AI is citing Wikipedia and review sites instead of your content, your priority is building presence on those platforms. Earned media accounts for 48% of AI citations — editorial coverage, relevant subreddits, review platforms. That’s where AI models are looking for “objective” information about your brand.

    Path 3: Close the sentiment gap with narrative correction. If the AI has absorbed a flawed or outdated narrative about your brand, you need to flood the ecosystem with accurate, structured information. Practical starting points include updating your llms.txt file, correcting stale documentation, and pushing accurate product specs to high-authority review platforms.

    Topify’s one-click execution connects monitoring data directly to strategy deployment. You can generate AI-optimized product descriptions and FAQs designed specifically to be cited by LLMs, without building a separate workflow for each platform.

    Track. Fix. Repeat.

    Conclusion

    The AI search channel isn’t experimental anymore. With 800 million weekly active users on ChatGPT alone, the question isn’t whether AI is influencing your buyers — it’s whether you have any visibility into how.

    Traditional organic traffic is already under pressure, with AI Overviews driving a 34.5% drop in click-through rates and some high-traffic keywords losing up to 64% of their volume. Meanwhile, the buyers you do reach through AI convert at 27% — more than 10x the average search conversion rate — because the AI has already done the evaluation for them.

    AI brand monitoring gives you the data to compete in this environment. Start with the five core metrics. Build a prompt corpus. Establish a baseline. Then use what you learn to make your brand the answer AI gives by default.


    FAQ

    How do you track brand visibility trends over time in AI search?

    You need a stable corpus of 50-100 prompts queried weekly across ChatGPT, Gemini, and Perplexity. Log your mention rate and position score consistently over time in a centralized dashboard. Model updates can introduce sudden shifts in visibility, so longitudinal data is what separates a real trend from a one-week anomaly.

    How do you identify which AI platforms mention your brand most?

    Multi-platform monitoring tools compare your answer inclusion rate across different engines. This matters because platform behavior varies significantly: Gemini often favors brands with strong Google Search presence, while Perplexity prioritizes academic and technical citations. Knowing which platform is your weakest link tells you where to focus your GEO effort first.

    How do you measure the impact of content on AI brand mentions?

    Run a controlled comparison. Update a set of pages with GEO-focused content — statistics, expert quotes, structured schema — and keep a comparable set unchanged. Monitor the citation rate for both groups over 60 days across Perplexity and Google AI Overviews. High-performing content typically sees a 30-40% increase in AI citation frequency within that window.

    How do you build a brand monitoring dashboard for AI search?

    A functional dashboard integrates four data streams: mention rate (how often you appear), sentiment score (the 0-100 quality of how you appear), competitive share of voice (your percentage vs. rivals), and AI-referred traffic (tracked via GA4 using Perplexity and ChatGPT as referral sources). These four together give you both a leading indicator (AI signals) and a lagging indicator (actual traffic impact).

    Why is AI brand monitoring fundamentally different from social listening?

    Social listening is reactive and human-centric — it tracks what people say about you. AI brand monitoring is proactive and algorithmic — it tracks what the model has been trained or prompted to say about you. They use different data pipelines, surface different problems, and require different solutions. You need both, but they don’t replace each other.

    How do you detect negative brand mentions in AI search responses before they compound?

    Set up weekly sentiment scoring across your core prompt corpus and flag any response where the model qualifies your brand with words like “however,” “despite,” “limited,” or “controversial.” These linguistic markers often signal the AI is pulling from a negative or outdated source. Once you identify the framing, trace it back to its citation origin and correct the source directly.


    Read More

  • GEO Analysis: See Exactly How AI Sees Your Brand 

    GEO Analysis: See Exactly How AI Sees Your Brand 

    Your domain authority is 72. Your target keywords are ranking on page one. Traffic is up 18% quarter-over-quarter. Then a potential customer opens ChatGPT, types “best [your category] tool for mid-market companies,” and gets a confident list of five recommendations. Your brand isn’t on it.

    That’s not an SEO failure. That’s a GEO visibility gap, and your current dashboards have no way to show it.

    Your SEO Dashboard Is Green. ChatGPT Still Doesn’t Know You Exist.

    Traditional SEO audits measure what Google’s algorithm values: backlinks, domain rating, page speed, and keyword density. Those signals still matter for Google. But generative engines like ChatGPT, Gemini, and Perplexity don’t use PageRank. They use Retrieval-Augmented Generation (RAG), pulling semantic chunks of content from the web, converting them into vector embeddings, and synthesizing a narrative response.

    The selection logic is mathematical: when a user submits a prompt, the engine surfaces content that minimizes distance in a multi-dimensional semantic space. Visibility is a function of semantic relevance and factual density, not backlink volume.

    This means a brand can rank first on Google and remain completely absent from AI-generated recommendations for the same category. Research suggests AI search now influences up to 73% of B2B buying journeys, yet most marketing teams are tracking zero metrics specific to it.

    That’s the gap GEO analysis is built to close.

    What GEO Analysis Actually Measures

    GEO analysis is the systematic process of evaluating a brand’s presence, perception, and competitive standing inside generative AI responses. It’s not an extension of traditional SEO audit methodology. It’s a separate framework interrogating how AI models represent your brand.

    A complete GEO analysis tracks seven dimensions:

    Visibility (Share of Model): How often does your brand appear when users ask category-level questions? Share of Model (SoM) calculates this as a percentage of total possible recommendations across platforms. In the legal tech space, for example, one leading brand holds a 32.9% SoM on ChatGPT and 47.8% on Gemini, while competitors trail significantly.

    Sentiment: A mention is only valuable if the framing is positive. AI responses that describe your brand as “expensive” or “suited for small teams” when you’re positioned as enterprise-grade are actively damaging. High-performing brands track a Net Sentiment Score (NSS) and target ratings above 80%.

    Position: In AI answers, the first brand mentioned typically receives the most authoritative framing (“The industry leader is…”), while later mentions are framed as alternatives. GEO analysis tracks this ordinal ranking to understand perceived market hierarchy.

    Citation Rate: When an AI cites a URL alongside a brand mention, it signals higher authority than an uncited mention. Optimized brands typically see citation rates between 20% and 50%. Unoptimized brands often sit below 10%.

    Prompt Volume: Conversational AI search demand doesn’t map to traditional keyword volume. GEO analysis estimates how frequently users are actually asking specific prompts in tools like ChatGPT or Perplexity, separate from what Semrush or Ahrefs would show.

    Source Domain Influence: AI doesn’t pull from the entire web equally. It relies on a retrieval set of trusted domains. Knowing which third-party sites shape the AI’s view of your brand tells you exactly where to invest your distribution and PR efforts.

    CVR (Conversion Visibility Rate): Traffic from AI search converts at dramatically higher rates than organic search, because the AI has already pre-qualified the recommendation. Claude-referred visitors convert at 16.8% (6x Google organic), ChatGPT at 14.2%-15.9%, and Perplexity at 10.5%-12.4%, compared to Google organic’s 1.76%-2.8% baseline. GEO analysis connects visibility to this conversion advantage.

    How to Conduct a GEO Audit in 4 Steps

    Step 1: Map Your Prompt Universe

    A GEO audit starts with selecting 40-100 prompts that reflect how real buyers research your category. Cover three intent types: discovery (“What are the best [category] tools for mid-market?”), problem-solving (“How do I [specific workflow]?”), and comparison (“Brand A vs Brand B for [use case]”).

    Without this mapping, you’re auditing a blank target. The prompt universe determines what the audit can actually tell you.

    Step 2: Measure AI Search Visibility Across Platforms

    Tracking one platform is a common audit failure. ChatGPT, Gemini, Perplexity, and Claude often return very different answers for the same prompt. Perplexity leans heavily on real-time news sources; Gemini integrates the Google Knowledge Graph. A meaningful AI search visibility analysis records mention rates, citation status, and position for every prompt on every platform.

    This cross-platform view is where most single-dashboard solutions fall short.

    Step 3: Run the Sentiment and Narrative Analysis

    Does the AI accurately describe your value proposition? If your product is enterprise-grade but AI consistently describes it as “budget-friendly,” that’s a narrative misalignment that’s harder to fix than low visibility. This step also surfaces reputation risks: outdated pricing, discontinued features, or competitor comparisons that frame you unfavorably.

    This is the difference between a GEO audit and a simple mention tracker.

    Step 4: Source and Content Gap Audit

    This is the most actionable part of any GEO audit. By analyzing the URLs an AI cites when discussing your category, you can identify exactly which third-party domains are shaping the model’s worldview. If competitors are being cited because of a specific industry report, a Reddit thread on a review platform, or a G2 category page you haven’t optimized, you now have a specific, executable content gap to close.

    Brands that run this step systematically discover an average of 23 untapped prompt opportunities and 14 content gaps per audit cycle.

    GEO Competitive Analysis: What AI Says About Your Competitors

    GEO competitive analysis reveals a type of visibility gap traditional SEO can’t surface. If a competitor appears in 65% of relevant category queries while your brand appears in 8%, that deficit won’t show up anywhere in your existing analytics stack.

    This happens because AI recommendation patterns are driven by “Entity Authority.” LLMs are trained to value consensus across multiple authoritative sources. If ten high-authority sites describe a competitor as the category leader, the model synthesizes that as a working truth. Reversing that requires either owning the same sources or introducing competing signals from equally authoritative domains.

    The competitive intelligence from a GEO analysis is specific and actionable. You can see which sources your competitor dominates that you don’t. You can identify which prompt categories they’re winning that you’re not even present in. You can track whether their AI sentiment score is declining, which signals an opening.

    That’s not a metric available in any traditional SEO tool.

    How to Interpret Your GEO Visibility Scores

    Raw GEO scores only matter in context. Here’s how to read the four key scenarios:

    High visibility, low sentiment. The AI knows your brand but associates it with negatives. This is the “reputation risk” quadrant and it’s more dangerous than invisibility. The fix isn’t more content; it’s narrative correction through case studies, structured review content, and responses to specific misrepresentations in the sources the AI is pulling from.

    High sentiment, low visibility. The AI has a favorable view but rarely surfaces you. You have a distribution problem, not a credibility problem. The fix is topical authority: creating content that answers the broad conversational questions in your category where you’re currently absent.

    High citation frequency, low referral traffic. The AI is citing you, but users aren’t clicking. That’s often a zero-click pattern where the AI answer is comprehensive enough that users don’t need to visit your site. The fix is creating high-utility assets the AI can’t summarize: downloadable templates, calculators, or raw datasets.

    Low across the board. This is the starting point for most brands running their first GEO audit. Prioritize prompt universe coverage first, then citation rate, then sentiment. Don’t try to fix everything simultaneously.

    5 Content Tactics That Directly Improve GEO Performance Metrics

    Research from Princeton and Georgia Tech identified specific tactics that measurably improve AI citation and mention rates. The lift is significant enough to treat these as strategic priorities, not stylistic preferences.

    Adding statistics and original data increases AI visibility by 33.9% to 40%. AI models can’t generate original data; they synthesize it. Content with specific numbers, dates, and sourced claims is substantially more “citable” than content with qualitative descriptions.

    Including quotes from recognized industry experts boosts visibility by 22.3% to 32%. These quotes give AI models synthesizable fragments they can use to add authority to generated summaries.

    Citing authoritative external sources within your own content improves visibility by over 30%. It signals to the AI that your content is part of a verified information ecosystem, not an isolated claim.

    Improving fluency (shorter sentences, active voice, cleaner structure) lifts visibility by approximately 30%. AI chunking algorithms favor passages they can extract cleanly.

    Adding structured data (JSON-LD schema for Organization, Product, FAQ, and Person) can improve explicit brand mentions by up to 139%. Schema acts as a direct signal to AI knowledge graphs, providing context that reduces ambiguity about what your brand is and does.

    One often-overlooked technical issue: many brands are inadvertently blocking AI crawlers through default firewall settings. One SaaS company saw a 217% increase in AI citations within 30 days simply by adjusting Cloudflare settings that were blocking GPTBot by default. A technical GEO audit should always verify bot accessibility via robots.txt before drawing conclusions about content performance.

    From GEO Analysis to Action: Turning Data into a Content Strategy

    The output of a GEO analysis is only useful if it connects to a content roadmap. Here’s how to translate each finding into a specific action:

    Low visibility on discovery prompts means creating pillar content that directly answers category-level questions. Low citation rate means producing original research, statistics, or structured comparison tables that give AI models something specific to attribute. Sentiment misalignment means targeting the exact sources the AI is pulling from and seeding corrective content there. Source gaps mean getting your brand into the third-party domains that matter for your category, whether that’s industry roundups, review platforms, or vertical publications.

    That’s how GEO analysis turns from a diagnostic into a content priority framework.

    GEO Analysis Needs a Tool, Not a Spreadsheet

    Between 40% and 60% of sources cited by AI change from month to month. That means a one-time GEO audit has a shelf life measured in weeks, not quarters.

    Manually tracking 40-100 prompts across four AI platforms every month isn’t realistic for any marketing team. The personalization problem compounds this: AI responses vary based on user history, which means manual spot-checks introduce bias. Professional tools use incognito instances to ensure consistent, comparable data over time.

    Topify is built specifically for this use case. It maps a complete GEO analytics stack across ChatGPT, Gemini, Perplexity, DeepSeek, and other major AI platforms, tracking Visibility, Sentiment, Position, Volume, CVR, and Source data in a single dashboard.

    For teams running competitive GEO analysis, Topify’s Competitor Monitoring automatically detects when and why competitors are being recommended instead of your brand, and which specific sources are driving that advantage. The Source Analysis module identifies the domains the AI is pulling from in your category, so your PR and content teams can prioritize outreach to the publications that actually move the needle in AI search.

    For agencies and brand managers who need to report GEO performance to stakeholders, Topify generates AI brand visibility reports that pull together cross-platform metrics into a shareable format, without manual data assembly.

    The Basic plan starts at $99/mo and covers 100 prompts across 4 projects. For teams running multi-client or multi-brand audits, the Pro plan ($199/mo) supports 250 prompts and 8 projects. You can get started here.

    Conclusion

    The brands that will lead in AI search over the next three years aren’t waiting for a standardized GEO playbook. They’re building systematic analysis habits now, while most competitors are still measuring AI performance with tools designed for a different era.

    GEO analysis gives you a clear map: where you’re visible, where you’re missing, what AI actually says about you, and which competitors are winning the recommendations you should own. That map exists whether you look at it or not. The question is whether you’re using it to make decisions.


    FAQ

    Q: How is GEO analysis different from a traditional SEO audit?

    A: A traditional SEO audit evaluates technical performance, backlink profiles, and keyword rankings in Google’s index. GEO analysis evaluates how AI engines represent your brand in synthesized responses, measuring prompt-level visibility, citation rates, sentiment framing, and competitive position in AI-generated answers. The two frameworks measure fundamentally different systems and neither can substitute for the other.

    Q: How often should you run a GEO analysis?

    A: Monthly is the recommended baseline. Because AI citation patterns are probabilistic and between 40% and 60% of cited sources rotate from month to month, data older than 30 days can underrepresent current conditions. Brands in highly competitive categories may benefit from weekly tracking to catch significant shifts in Share of Model.

    Q: What’s the minimum number of prompts needed for a meaningful GEO audit?

    A: A representative audit typically requires 40-100 prompts covering discovery, problem-solving, and comparison intent types. Fewer than 40 prompts tends to produce uneven coverage, missing entire intent categories where the brand may be invisible or where competitors are consistently recommended.

    Q: How do I measure sentiment in AI search results through GEO analysis?

    A: Sentiment analysis in GEO evaluates the adjectives, framing, and context an AI uses when describing your brand. A structured approach tracks whether the language is endorsing, neutral, or framing your brand negatively relative to competitors. Platforms like Topify calculate a Net Sentiment Score (NSS) on a 0-100 scale, which lets you benchmark sentiment performance over time and against category competitors.


    Read More

  • What AI Search Learns from Brand Conversations

    What AI Search Learns from Brand Conversations

    You’ve spent months polishing your website copy. Every page is optimized, every heading is deliberate. Then someone asks ChatGPT about your product category, and the AI describes your brand using language pulled from a two-year-old Reddit thread you never saw.

    That’s not a hypothetical. That’s how social listening became a search visibility problem.

    Social listening was always about understanding what people say about your brand. In 2026, it’s also about understanding what AI is learning from those conversations, and whether that narrative is one you’d choose for yourself.

    Social Listening Has a New Job Description

    Traditional social listening was defensive. Track mentions, catch crises early, measure sentiment over time. Useful, but reactive.

    The shift comes from how AI search engines actually work. Platforms like ChatGPT, Perplexity, and Google’s AI Overviews use Retrieval-Augmented Generation to synthesize brand descriptions from across the web. They don’t prioritize your “About Us” page. They prioritize authentic, peer-validated, conversational content.

    That means social listening is now dataset engineering. The conversations happening in forums, review platforms, and Q&A sites today are feeding the AI answers that will describe your brand tomorrow.

    Community platforms and Wikipedia now capture 52.5% of all AI citations, frequently outperforming brand-owned domains. On the flip side, a brand’s own website accounts for only 9% of its mentions in AI-generated answers. The other 91% comes from third-party environments your team may not be monitoring at all.

    That gap is the new job description of social listening.

    The Platforms Where Brand Conversations Shape AI Answers

    Not all platforms carry equal weight in the AI citation economy. Generative engines have clear preferences, and most brands are looking in the wrong places.

    Reddit accounts for 40.1% of AI citation share across ChatGPT, Perplexity, and Google AI Overviews. Its Q&A format and community-vetted content make it the single most influential source for AI brand summaries. AI models use Reddit to find the “so what” behind technical facts.

    Quora provides structured answers that map directly to how AI engines retrieve information for long-tail, high-intent queries. For B2B brands, platforms like G2, Capterra, and TrustRadius function as credibility layers. Perplexity uses reviews in 100% of its product-related responses.

    Most brand teams monitor their own social accounts. That’s where the disconnect starts.

    The conversations with the most AI influence are happening in spaces you don’t own: industry subreddits, niche Slack communities, product review threads, and vertical forums. If your brand mention monitoring stops at Instagram and LinkedIn, you’re tracking the wrong audience.

    PlatformAI Citation ShareWhy It Matters
    Reddit40.1%High-trust Q&A, community-vetted
    Wikipedia26.3%Foundational training data
    YouTube23.5%How-to and tutorial authority
    News & Media20.3%Temporal relevance
    Review Sites~8.5%Structured brand evaluation

    5 Social Listening Signals That Tell You What AI Is Picking Up

    Most teams track volume and sentiment. That’s fine for a quarterly dashboard. It’s not enough for online reputation tracking in an AI-first environment.

    Here are the five signals that actually indicate how AI is building its understanding of your brand.

    Signal 1: Sentiment Shifts, Not Just Scores

    Don’t just track whether sentiment is positive or negative. Track changes in tone and engagement depth. When customer communication length drops by an average of 55% or response time to brand outreach increases from hours to days, users are 3.2x more likely to churn within 30 days. AI models pick up on this tonal flatness across community threads and tend to incorporate the “general vibe” of recent discourse into brand summaries.

    Signal 2: Competitor Citation Gaps

    Where are competitors being cited while you’re absent? If a competitor dominates citations for “best project management tool for remote teams,” they’ve successfully seeded those communities with content AI considers authoritative for that sub-query. Mapping these gaps tells you exactly where to build.

    Signal 3: Unanswered Questions

    Unanswered questions in high-authority forums are a direct source of content voids. When AI can’t find a definitive answer to a user’s specific problem, it either hallucinates or recommends whoever does have an answer. Brand conversation tracking across Reddit and Quora for unanswered questions in your niche is one of the highest-ROI moves a content team can make.

    Signal 4: Entity Associations

    AI models build brand understanding through co-occurrence. If a software product is consistently mentioned alongside “steep learning curve” in Reddit discussions, the AI starts to hard-code that association. Social listening can surface whether these associations are accurate or need to be actively corrected.

    Signal 5: Karma Velocity

    AI engines don’t just index for popularity. They index for helpfulness. A thread that gets rapidly upvoted and updated within the last 30 days signals to models like Perplexity that it’s fresh and community-validated. Monitoring high-velocity threads gives you the early window to intervene before a narrative gets baked in.

    How to Set Up Brand Mention Alerts Across Reddit, Quora, and Beyond

    The foundation is a broad keyword architecture. Your monitoring list should go well beyond the brand name.

    Include brand name variations and common misspellings. Add problem-intent phrases: “how do I fix [your product category problem]” or “best way to [task your product solves].” Layer in comparison clusters: “[your brand] vs [competitor]” and “alternative to [your product].” Don’t overlook executive names, because mentions of leadership influence brand perception in ways that show up in AI responses.

    Platform priority: Reddit and Quora first, then G2/Trustpilot/Capterra for B2B, then Twitter/X and relevant industry newsletters. Niche Slack and Discord communities are high-signal but harder to access systematically.

    On response SLAs: brands that respond to active frustration signals with a meaningful resolution within 24 hours see a 67% retention rate. High-intent mentions, like direct recommendation requests, should get a response within 30 to 90 minutes.

    Two guardrails matter here. First, don’t prioritize speed over quality. A generic response is worse than a delayed useful one. Second, follow a value-first framework on community platforms: mirror the community’s language, provide a genuinely helpful answer of 4 to 8 sentences, and disclose your affiliation. Transparency builds the trust that translates into AI training data. Astroturfing, on the other hand, can get content removed and excluded from AI training sets entirely.

    Turning Social Listening Data into a Content Strategy

    The most direct path from social listening to ROI is closing the content loop: using what you hear in communities to build assets that AI engines want to cite.

    Unanswered questions in your niche become blog post topics. User-reported pain points become FAQ sections structured with clear H2/H3 headers formatted as questions. High-frequency negative associations become product messaging opportunities.

    When you create content from these insights, structure matters as much as substance. Princeton research shows that adding original statistics, expert quotes, and authoritative citations can boost AI visibility by 30–40%. Lead with the direct answer in the first 40 to 60 words of each section. Use semantic chunking. Make it easy for AI crawlers to extract a clear, citable claim.

    80% of consumers trust UGC more than traditional ads, and social media posts featuring UGC drive 10.38x higher conversions. Capturing positive community testimonials and integrating them into your site using schema markup is one of the most underused moves in audience insight tools.

    One often-overlooked priority: Identity Consistency. AI models trust facts that repeat across independent surfaces without contradiction. Social listening data frequently surfaces where a brand’s information is inconsistent across platforms, like conflicting founding dates on LinkedIn vs. Crunchbase. Cleaning up entity data is unglamorous work, but it directly affects how AI synthesizes your brand.

    What Social Listening Misses About AI Search

    Here’s the gap most brands discover too late.

    Traditional social listening tools can tell you that a Reddit thread exists. They can tell you how many upvotes it has, what the sentiment is, and whether it mentions your brand. What they can’t tell you is whether ChatGPT is using that thread as its primary source for describing your product’s pros and cons.

    That’s a category difference, not a feature gap.

    Zero-click searches have reached 83% in AI-enhanced environments. That means the majority of queries involving your brand now end without a user visiting any website. The AI answer is the destination. If you’re only tracking human engagement metrics like click-through rate, you’re measuring a shrinking slice of the actual discovery landscape.

    This is where Topify adds a layer that traditional social listening tools don’t cover. Rather than monitoring what humans see in forums, Topify tracks how AI systems actually present your brand across ChatGPT, Perplexity, Gemini, and other major platforms. The platform’s Sentiment Analysis tracks how AI characterizes your brand on a 0–100 scale, while Source Analysis shows which domains AI is citing when it describes you. You can see if that Reddit thread is appearing in AI answers, and more importantly, whether the content on your own domain is earning citations at all.

    For teams that have invested in community listening but haven’t yet tracked AI representation, the combination covers both layers: what people are saying, and what AI is learning from what they say.

    Scaling Social Listening Without Overwhelming Your Team

    The practical challenge isn’t knowing what to monitor. It’s building a workflow that surfaces the right signals without drowning in noise.

    For smaller marketing teams, the priority is platform coverage over frequency. Monitor fewer platforms with higher quality attention rather than setting up alerts across 15 channels that nobody has time to review. Reddit and a vertical review site specific to your industry will typically deliver more signal per hour than a broad sweep of lower-trust sources.

    For growing teams, integrating real-time mention alerts into a shared Slack channel creates a lightweight triage system. Route high-priority mentions to a #brand-signals channel. Use emoji reactions to track status: reviewing, escalated, handled. This keeps the loop tight without requiring dedicated headcount.

    For teams managing multiple brands or clients, a shared monitoring infrastructure with per-brand filtering is a prerequisite. Manual workflows don’t scale past three or four brands.

    The table below shows what to prioritize based on team size and focus:

    Team ContextPrimary FocusTool Priority
    Small in-house teamReddit + 1 vertical review platformMention alerts + weekly digest
    Growing marketing team4–5 platforms + competitor monitoringReal-time Slack routing + response SLAs
    Agency or multi-brandCross-platform + AI search layerTopify Sentiment & Source Analysis + Competitor Monitoring

    The key addition for any team thinking about AI search visibility is building an AI monitoring layer alongside traditional community sentiment analysis. Topify’s platform tracks brand mentions across AI responses directly, measuring Visibility, Sentiment, and Position in a single dashboard. It’s the step that connects what you’re hearing in communities to what AI is actually saying about you.

    Conclusion

    Social listening used to end at the community. You heard what people said, you responded, you reported. That was the loop.

    The loop is longer now. What people say in communities feeds into how AI describes your brand, which shapes whether new customers find you at all. The brands that treat social listening as a passive monitoring function will keep optimizing for an audience that’s increasingly not the first stop in the decision journey.

    The question isn’t whether to monitor brand conversations. It’s whether you’re also tracking what AI is learning from them, and whether you’re using what you hear to build the kind of content AI actually cites.

    Start with the signals. Build the assets. Then check how AI is representing you.


    FAQ

    Q: What’s the difference between social listening and social media monitoring?

    A: Social media monitoring tracks mentions on owned channels and collects surface metrics like likes, shares, and brand mention counts. Social listening goes further: it analyzes patterns, sentiment shifts, and context across third-party platforms to surface strategic insights. In the AI era, social listening also includes tracking how community conversations influence what AI search engines say about your brand.

    Q: How do I set up brand mention alerts for Reddit and Quora?

    A: Build a keyword list that includes brand name variations, competitor comparison phrases, and problem-intent queries relevant to your category. Use tools that support Boolean search to filter high-signal mentions from noise. Route alerts to a shared Slack channel with clear ownership for response. Prioritize threads with high karma velocity, since those are the discussions most likely to be picked up by AI crawlers within 30 days.

    Q: How does social listening data connect to GEO optimization strategy?

    A: Social listening identifies the specific questions, pain points, and language your audience uses in communities. GEO optimization takes that input and structures it into content that AI engines are more likely to cite. Concretely: an unanswered question on Reddit becomes a blog post with semantic chunking and a direct answer in the first 50 words. Community sentiment around a competitor weakness becomes a comparison asset. The loop closes when AI starts citing your content instead of the forum thread.

    Q: What are the best social listening tools for marketing teams in 2026?

    A: The right toolset depends on coverage needs. For traditional community sentiment analysis, tools like Sprout Social and Brandwatch cover social channels well. For tracking how brand conversations influence AI search specifically, platforms like Topify add a layer those tools don’t offer: cross-platform AI visibility tracking, sentiment scoring within AI responses, and source analysis showing which domains AI is citing for your category.


    Read More

  • Word of Mouth Marketing: From Conversations to AI Citations

    Word of Mouth Marketing: From Conversations to AI Citations

    You ran the campaign. The ads performed. The landing page converted. But when a potential customer asked ChatGPT which tool to use for your exact use case, AI cited a three-year-old Reddit thread, a YouTube comment section, and a G2 review you didn’t even know existed. Your brand wasn’t mentioned once.

    That’s not a content problem. That’s a word of mouth problem that most brands still don’t see coming.

    Word of mouth marketing has always been the highest-trust channel in any marketer’s playbook. What’s changed is where it happens, what it feeds into, and how much it now controls whether AI systems recommend you at all.

    Word of Mouth Marketing Has a New Battlefield

    Word of mouth used to live in private conversations. A colleague mentioned a product over lunch. A friend texted a recommendation. These exchanges were real, but they were invisible to any tracking system.

    That era is over.

    Today, word of mouth plays out on Reddit threads, YouTube comment sections, GitHub issue boards, Discord servers, and LinkedIn posts. These aren’t fleeting social moments. They’re permanent, indexed, machine-readable signals that AI systems actively mine when deciding which brands to cite. According to research on AI citation behavior, a brand’s presence on Reddit alone can increase its AI citation rate by 3x compared to brands absent from community platforms.

    The battlefield has shifted. Organic brand mentions that once reached dozens of people now reach millions, indirectly, every time an AI assistant surfaces them as part of a synthesized recommendation.

    Why Organic Brand Mentions Now Shape AI Recommendations

    Most modern AI assistants, including ChatGPT and Perplexity, use a Retrieval-Augmented Generation (RAG) architecture. When a user asks a question, the system doesn’t just rely on pre-trained knowledge. It retrieves relevant content from the web in real time, evaluates credibility, and synthesizes an answer.

    Here’s what that means for earned media strategy: AI doesn’t rank content the way Google does.

    Traditional SEO rewards domain authority and keyword density. AI RAG systems reward fact density, semantic relevance, and what researchers call “independent entity consensus,” meaning your brand gets cited when multiple unaffiliated sources say the same thing about you in different contexts. Brand-owned marketing copy tends to score low on this measure. Third-party community discussions, user-generated reviews, and peer-to-peer comparisons score high.

    Approximately 85% of AI citations come from earned media sources, not from brand websites or paid placements. If you’re not generating organic brand mentions in credible communities, you’re functionally invisible to the systems that increasingly drive purchasing decisions.

    Social Proof Marketing Is the Raw Material AI Trusts Most

    There’s a reason 92% of consumers trust earned media over traditional advertising and 83% trust recommendations from real peers over any brand message. AI systems have essentially formalized this human tendency into an algorithm.

    When AI evaluates which brands to recommend, it looks for three patterns in the content it retrieves. Cross-platform consistency: is your brand mentioned as a go-to solution across multiple independent communities? Problem-solution match: do users in Q&A environments name your brand as the direct answer to a specific pain point? Non-commercial tone: is the language natural, specific, and experiential rather than polished and promotional?

    That last one is worth sitting with.

    AI models are trained to identify and discount overtly promotional language. A Reddit comment that says “I switched to this tool six months ago and our team’s onboarding time dropped by 40%” carries far more weight than a blog post titled “Why Our Platform Is the Industry Leader.” Authentic brand promotion, the kind that comes from real users describing real experiences, is what AI is actually optimized to surface.

    One counterintuitive finding from citation research: AI references positive and negative brand mentions at nearly equal rates. It’s not looking for praise. It’s looking for honest assessment.

    How to Build Brand Advocacy Through Community Platforms

    Not all engaged users are brand advocates. A fan follows, likes, and occasionally buys. An advocate creates content that seeds your brand into new conversations without being asked.

    That distinction matters enormously for community-led growth. Advocates are the source of the organic discussions that AI indexes. Without them, your word of mouth footprint stays thin.

    The most effective brand advocates in AI-visible communities tend to behave in specific ways. They answer technical questions in places like Stack Overflow and Discord using your product as the reference solution. They write detailed comparison breakdowns in “Best [tool] for [use case]” Reddit threads. They publish LinkedIn posts that share genuine outcomes, not brand talking points.

    Building this ecosystem isn’t passive. It requires identifying users who already exhibit these behaviors, then giving them context, access, and sometimes early data to amplify what they’re already inclined to do. Think less about loyalty programs and more about knowledge-sharing infrastructure.

    The community platform breakdown matters too. Reddit carries the highest citation weight among AI systems, particularly for tools and software recommendations. LinkedIn functions as the authority signal for B2B categories, influencing how ChatGPT frames industry perspectives. Discord and Slack communities, though partially closed, are increasingly accessible to AI agents through public archiving and emerging data partnerships.

    Earned Media Strategy Doesn’t Scale by Accident

    Here’s the thing: earned media that reliably feeds AI citation pipelines doesn’t just happen organically. It’s designed.

    Three content types consistently generate the highest AI citation rates. Original research with named data points, because AI treats primary data as high-value source material and actively seeks it for factual grounding. User-authored first-person case studies published on their own channels, which AI extracts at roughly 40% higher rates than equivalent content published on brand-owned pages. And detailed Q&A threads with specific resolution steps, because they align directly with how AI retrieves answers to problem-based queries.

    That’s the content architecture. The distribution layer is equally important.

    Shareable moments need to be built into the product or service experience itself. If using your tool produces a result that makes users look competent or insightful in their professional community, they’ll share it without being prompted. That’s peer-to-peer marketing at its most scalable: value so tangible that broadcasting it becomes self-serving for the user.

    When organic brand mentions start accumulating at scale, you face a new problem: you can’t tell which ones are actually driving AI visibility and which ones are just noise. That’s where Topify comes in. The platform’s Source Analysis function traces which specific third-party posts, forum threads, and reviews are actively being cited by ChatGPT, Perplexity, and other AI engines. You can see exactly which community investments are translating into AI-layer recommendations, and which aren’t, without guessing.

    Topify’s Sentiment Analysis layer adds another dimension: it monitors the specific language AI is using to describe your brand, so you know whether the word of mouth reaching AI systems is framing you as “efficient and cost-effective” or “complex and expensive.” That’s direct insight into whether your earned media narrative matches your intended brand positioning.

    How Word of Mouth Marketing Supports GEO Optimization

    If Generative Engine Optimization (GEO) is the engine, word of mouth is the fuel.

    Traditional SEO is built around links and keywords, optimized to earn clicks from a search results page. GEO is built around entity consensus and citation share, optimized to earn inclusion in synthesized AI answers. The two strategies aren’t opposed, but they’re powered by different inputs.

    Word of mouth produces exactly what GEO requires. When users discuss your brand in community contexts, they naturally generate long-tail phrases that associate your product with specific use cases, pain points, and outcomes. AI indexes these associations. When a future user asks a scenario-specific question, AI retrieves the community consensus built from those organic conversations and surfaces your brand as the relevant answer.

    The feedback loop compounds over time. AI recommendations drive more users to discover your brand through high-intent channels. Those users, if the product delivers, become the next generation of advocates producing the next wave of organic mentions. Research from Similarweb shows that users arriving via AI assistant recommendations convert at roughly 7%, significantly higher than traffic from broad search or social platforms, because they’ve already been pre-qualified by the AI’s synthesis process.

    This is the core business case for treating word of mouth as a GEO investment rather than a soft brand metric.

    How to Track and Measure Word of Mouth Marketing Performance

    Net Promoter Score was built for a world where word of mouth happened in private. It measured willingness to recommend, but it couldn’t capture whether those recommendations were actually being made, where they were landing, or whether AI systems were picking them up.

    The measurement framework has to evolve.

    A complete word of mouth tracking system now needs to monitor seven dimensions: Visibility (how often your brand appears in AI answers for target prompts), Sentiment (the language AI uses when it describes you), Position (whether you’re listed first or buried fifth), Volume (total organic mentions AI considers credible), Mentions (specific instances where AI cites your content as a source), Intent (whether the contexts where you’re mentioned align with high-purchase-intent queries), and CVR (the conversion rate of users who arrive via AI-cited recommendations).

    That’s the reporting framework Topify operationalizes across its analytics dashboard.

    In practice, this changes how marketing teams communicate performance internally. Instead of “our Reddit engagement is up,” you can present something concrete: “After our developer community activation last month, our visibility score in ChatGPT for ‘cross-platform collaboration tools’ increased from 12% to 28%. Source Analysis shows 60% of those citations traced back to three deep-dive community threads from the previous week. AI-referred traffic contributed 15% of new trial signups, converting at 2x the rate of paid acquisition.”

    That’s the kind of data that earns budget. And it’s the kind of visibility that compounds.

    Get started with Topify to see which of your existing brand mentions are already feeding AI recommendations, and which gaps in your earned media strategy are costing you citation share.

    Conclusion

    Word of mouth has never been more powerful or more measurable. What’s changed is that its final destination is no longer a friend’s inbox or a Slack message. It’s an AI system synthesizing the answer to a high-intent purchase query for millions of users simultaneously.

    The brands that treat community engagement, authentic user stories, and earned media as trackable growth infrastructure, not soft brand-building, are building an asset that pays out across every AI platform where their future customers are searching. Start by understanding where your brand already shows up in AI answers. Then build the systems to amplify what’s working and fix what isn’t.


    FAQ

    Q: How does word of mouth marketing differ from paid advertising in terms of AI visibility?

    A: Paid advertising generates controlled impressions with low trust scores, roughly 41% consumer trust on average. It doesn’t contribute to the AI’s long-term citation database in any meaningful way. Word of mouth marketing, by contrast, produces earned media that AI RAG systems treat as third-party factual evidence. The tradeoff is time: WOM typically takes 60 to 90 days to move through AI indexing cycles, but the citation benefits compound and sustain in a way that paid placements can’t replicate.

    Q: How can I tell if my brand is being discussed in communities that AI platforms might cite?

    A: The most direct method is using Topify’s Source Analysis feature, which reverse-engineers AI recommendation results to show you the original source documents. You can also manually prompt ChatGPT or Perplexity with “What are the best [category] tools?” and examine the citations in the response. The subreddits, review platforms, and community threads that appear are the ones currently shaping AI’s understanding of your category.

    Q: What types of organic content are most likely to be cited by AI search engines?

    A: AI engines consistently favor content with high fact density and clear structure. Original research reports with specific data points, detailed product comparisons in structured formats, Q&A threads with resolution steps, and expert-authored analyses with named credentials all perform well. The common thread is information gain: content that tells AI something it couldn’t infer from general knowledge is far more likely to be surfaced as a citation.

    Q: How long does it take for word of mouth campaigns to impact AI search recommendations?

    A: The typical indexing and weighting cycle runs 60 to 90 days. That said, platforms like Reddit carry real-time retrieval weight in systems like Perplexity, which means high-quality organic discussions on those platforms can influence AI citations in as little as four to six weeks. The speed depends on the platform, the quality of the discussion, and whether the content matches the specific prompts your target customers are using.


    Read More

  • AI Reply Generators Work. Most Teams Use Them Wrong.

    AI Reply Generators Work. Most Teams Use Them Wrong.


    Your competitor just published 50 community replies while your team drafted one.

    That’s the efficiency gap AI reply generators were built to close. But here’s what most teams discover six weeks in: volume alone doesn’t move the needle. Their replies get ignored, downvoted, or flagged. Some accounts get banned. The tool isn’t the problem. The strategy is.

    The brands winning with AI-generated replies in 2025 aren’t the ones generating the most. They’re the ones generating replies that get cited, upvoted, and eventually pulled by ChatGPT, Gemini, and Perplexity as trusted community signals.

    That’s a different game entirely.

    The Real Reason Most AI-Generated Replies Get Ignored

    When you deploy an AI reply generator without a defined strategy, you’re producing what researchers now call “engagement filler,” not engagement catalysts.

    Studies on AI-powered comment behavior show that automated replies generate a 23% increase in comment volume on average. But they fail to drive sustained user activity. The numbers look fine in a weekly report. The community goes nowhere.

    The deeper issue is what happens at the psychological level. As of 2025, 59% of consumers say AI-generated content actively hurts brand trust. On community platforms, where the entire value exchange depends on authentic peer-to-peer interaction, that number carries real consequences.

    There’s also a detection problem. Research shows 80% of users report they can regularly identify AI-generated accounts or suspicious bots on social media. When a reply lacks brand-specific voice, contextual awareness, and clear intent, it falls into what researchers call the “textual uncanny valley”: grammatically correct, but oddly polite, laced with filler phrases like “It’s important to remember” or “In conclusion.” That pattern triggers an immediate defensive response in community readers.

    The fix isn’t finding a better AI tool. It’s fixing how you use the one you have.

    What “AI Social Media Replies” Actually Means in 2025

    The terminology gets muddled fast. AI reply generator, AI comment generator, natural language reply tool: these often refer to overlapping but technically distinct capabilities.

    A basic AI comment generator focuses on single-response output. It typically lacks the ability to extract context from deeper thread structures, which makes it easy for community spam filters to identify as bulk posting. A natural language reply tool introduces more advanced understanding, pulling the user’s core intent from messier inputs and generating responses that read more naturally. The most capable systems in 2025, what practitioners call agentic LLMs, go further still: multi-step reasoning, real-time retrieval from external knowledge bases, and dynamic tone adjustment based on live sentiment analysis.

    What separates effective use from wasted effort isn’t which tier you use. It’s whether you’re running a “Train-Review-Post” workflow or a “Paste-Click-Publish” one.

    The three-stage lifecycle that works:

    Stage 1, Contextual Analysis: The system uses Retrieval-Augmented Generation (RAG) to scan the full thread, not just the post you’re replying to. It reads prior conversation history, community sentiment, and account context before generating anything.

    Stage 2, Strategic Prompting: Brand voice parameters and platform-specific constraints are applied. Reddit’s norms aren’t Quora’s. Quora’s aren’t Instagram’s.

    Stage 3, Human Calibration: A review checkpoint before anything goes live. This is the stage most teams skip. It’s also the stage that determines whether a reply earns upvotes or triggers a moderation flag.

    How to Train AI to Match Your Brand Voice in Generated Replies

    The most common complaint about AI-generated replies isn’t that they’re factually wrong. It’s that they all sound the same.

    Brands with a documented voice strategy see 40% higher customer satisfaction and 33% higher engagement rates from AI-generated content. Research also links consistent brand presentation across channels to 23-33% revenue growth and a 67% improvement in customer lifetime value. The gap between teams with and without a defined voice framework is that measurable.

    What works isn’t telling the AI to “sound professional” or “be friendly.” Those instructions produce generic output. What works is a systematic process researchers call “Linguistic DNA” mapping:

    Step 1: Collect your gold standard. Pull 10-15 of the best human-written replies your team has published across different scenarios: technical debate, user frustration, product praise. These become your anchor dataset.

    Step 2: Define structural parameters. Sentence length limits, punctuation preferences, vocabulary restrictions. “Keep replies under 20 words per sentence” produces more consistent output than “be concise.” Specify whether your tone is warm, authoritative, or dry. Quantify it where you can.

    Step 3: Build an anti-persona. Define what your brand is not. “We never use corporate jargon. We never deflect with generic sympathy. We never end with ‘Let me know if you have questions.’” This is as important as defining what you are. Brands that treat voice guidelines as long-term strategic assets rather than one-off templates report AI output consistency scores of up to 90%.

    Step 4: Add a real-time tone check. Tools like Acrolinx can automatically flag output that drifts from brand parameters before anything reaches a human reviewer. This turns the review step from a full editorial pass into a final quality gate.

    Neuroscience research adds another dimension here. fMRI studies found that brand replies written in a conversational, human voice (what researchers label “Conversational Human Voice”) activate the prefrontal cortex 27% more than formal corporate tone. They also improve factual recall by 18%. The trust gap isn’t about AI origin. It’s about tone drift.

    How to Use AI Reply Tools Without Violating Platform Guidelines

    Reddit and Quora aren’t social media platforms in the conventional sense. They’re trust hubs. And their moderation systems in 2025 have become explicitly hostile to what communities call “AI slop”: low-effort, mass-produced content that adds no real value.

    Reddit’s approach has moved from reactive moderation to proactive detection. CEO Steve Huffman has publicly discussed biometric verification experiments using Face ID and passkeys to confirm human authorship. Accounts using automation must display an “[App]” tag under Reddit’s Responsible Builder Policy. Violations risk API access revocation and permanent bans. High-value subreddits like r/devops and r/NoContract have added explicit rules against AI-generated content, enforced at the mod level.

    Quora presents a different but equally significant risk. Approximately 10.9% of Quora answers are already flagged as AI-generated, a figure that has eroded platform-wide trust and pushed Quora to dramatically raise credibility thresholds for new accounts. Even well-written answers that are detected as bulk AI output get hidden or removed without warning.

    The compliance framework that holds up:

    The 95/5 rule: 95% of your replies should provide pure value: answering questions, sharing insights, solving problems. Only 5% should include any brand reference, and only when it’s directly relevant to the conversation.

    Disclose when required: In communities that mandate disclosure, proactively noting “content assisted by AI, reviewed by a human” tends to earn respect rather than suspicion. 72% of users expect AI disclosure in content they interact with.

    Never batch identically: Posting near-identical replies across different threads is the clearest automated-behavior signal a platform’s detection systems look for. Every reply must be customized to its specific thread context.

    The goal is replies a moderator would read and conclude: this person actually knows what they’re talking about.

    AI Reply Generators for Reddit and Quora: What Instagram Logic Gets Wrong

    Most teams approach Reddit and Quora with the same playbook they use for Instagram or X. That’s the first structural error.

    On Instagram, a brief, warm reply with an emoji performs well. On Reddit, that exact reply gets downvoted to invisibility. The platform’s social currency is niche knowledge and candid honesty, not emotional warmth. Generic enthusiasm reads as promotional, regardless of whether the content is AI-generated or not.

    The platform differences are structural:

    PlatformCore Social CurrencyAI Reply Strategy
    RedditKarma, upvotes, niche credibilityConversational, technical, specific; include verifiable data or personal experience
    QuoraTopical authority, evergreen relevanceLong-form (1,000+ words), structured with tables and direct-answer blocks
    InstagramVisual aesthetics, instant emotional resonanceShort, warm, quick; emoji-friendly

    On Reddit, AI must analyze the entire thread hierarchy, not just the original post. A reply that ignores a high-upvote comment three levels deep reads as disconnected and gets treated as such. The “upvote algorithm” rewards uncommon honesty: specific, verifiable claims, real failure examples, niche data points. Not praise.

    On Quora, structure matters differently. The most effective AI-generated answers open with a 40-60 word direct-answer block, then expand into detailed argument. That structure isn’t just good UX. It’s exactly what Google AI Overview and Perplexity crawlers are built to extract.

    One data point worth internalizing: threads with 30 or more replies are significantly more likely to be cited by AI search engines. That means the goal of an AI-generated reply on Reddit isn’t just to contribute an answer. It’s to write something that invites follow-up conversation, builds thread depth, and grows into the kind of community signal that AI models trust.

    The Review-Before-Post System That Scales Without Losing Quality

    The teams that scale successfully with AI-generated replies don’t automate everything. They automate the right parts.

    Full automation achieves around 68% accuracy in complex social prediction scenarios. Human-in-the-loop (HITL) systems reach 90%+ with calibration. In a drug prescribing study, over-reliance on automated systems alone increased errors by 56.9%. The principle transfers directly to community management: automation bias leads to tone-deaf responses that trigger PR incidents, not just downvotes.

    The operational architecture that works at scale:

    Batch generation with confidence thresholds: AI produces multiple response variants per thread. Replies meeting an 80% or higher confidence threshold for brand alignment go to a fast-approval queue. Replies below threshold, or those touching high-risk topics like finance or legal questions, route directly to a human specialist. This keeps the human review burden focused where it actually matters.

    Anomaly detection: When a subreddit’s discussion volume spikes 10x or brand sentiment turns sharply negative, the system automatically pauses posting and triggers an alert. You don’t want AI continuing to publish while a crisis is unfolding.

    Staggered distribution: Posts go out over hours, not in a single burst. This avoids triggering platform anti-bot detection based on posting velocity.

    Active learning feedback loop: Human edits to AI drafts sync back into the model’s fine-tuning process. Research shows this reduces false positive flags by up to 30% over time, meaning the system gets more accurate the more it’s used.

    Quantified: this hybrid approach cuts average reply cycle time from 4.2 hours to 47 minutes, an 81% reduction, while improving lead quality by 33% compared to pure automation or pure manual handling.

    That’s the architecture. Not AI instead of humans. AI and humans, each doing what they’re better at.

    AI Reply Generation as a Brand Visibility Signal for AI Search

    Here’s the part most teams haven’t thought through yet.

    Your replies on Reddit and Quora don’t just reach the people in that thread. They get crawled by AI models. When a user asks ChatGPT which CRM to use for a small team, and your brand appears in the answer, there’s a reasonable chance it’s because someone posted a genuinely helpful reply in an r/smallbusiness thread months ago.

    The citation data is striking. An analysis of 150,000 AI citations found Reddit accounts for 40.1% of all citations in large AI models, ahead of Wikipedia at 26.3% and YouTube at 23.5%. Reddit is the second most-cited source in ChatGPT responses, and 99% of those citations point to specific threads, not brand homepages. Perplexity’s Reddit citation rate reaches 46.7% in certain industries.

    The conversion math makes this even more compelling. AI-driven traffic currently represents around 1% of total referral volume, but converts at 14-16%, compared to 2.8% for traditional search. That’s a 5x conversion rate advantage. For brands still treating community replies as a customer service function, this reframe matters. Every well-placed, human-approved AI reply is a potential citation. Citations drive AI visibility. AI visibility drives the kind of conversion that paid media can’t replicate.

    Brands with genuine Reddit activity are 3x more likely to be cited by AI models than brands that rely solely on their own website for SEO. LLMs treat community discussion as evidence of real user experience. Marketing copy is treated as brand rhetoric.

    Topify connects AI reply generation directly to this GEO layer. Its Source Analysis feature tracks which specific Reddit and Quora threads are being cited by ChatGPT, Gemini, Perplexity, and other AI platforms. That tells you exactly which conversations are worth targeting with high-quality AI-generated replies: not the ones with the most engagement, but the ones AI is already pulling from.

    Topify’s managed service also includes Reddit Visibility Posts, a structured program for building community signals in the highest-value threads for your brand. The system identifies where AI engines are looking, then places human-reviewed content there systematically. The analytics platform starts at $99/month; the full managed service with content distribution and Reddit post management starts at $3,999/month for teams that want end-to-end execution.

    The brand-to-AI-citation correlation research puts a number on this: the correlation between organic Reddit discussion volume and AI citation frequency is 0.334. Every substantive reply you place in the right thread increases the probability that AI recommends your brand the next time a relevant question gets asked.

    Conclusion

    The question isn’t whether to use an AI reply generator. It’s whether you’re using one with a strategy.

    The teams generating real results in 2025 share three habits. They’ve trained their AI on specific brand voice parameters, not generic prompts. They run every reply through a human checkpoint before it posts. And they treat Reddit and Quora as GEO assets, not just community platforms.

    Volume without those three things produces AI slop. Volume with them produces community authority, AI citations, and brand visibility that compounds over time.

    The next step, if you’re already generating replies at scale, is measuring where they land in AI search. That’s where the return becomes visible. And that’s where Source Analysis gives you data traditional analytics can’t.


    FAQ

    What are the best AI tools for generating social media replies?

    In 2025, leading teams don’t rely on a single tool. The most effective stack combines a high-capability LLM (like Claude 4.5 or Gemini 3 Pro) for generation, a tone governance layer like Acrolinx for brand consistency, and a GEO tracking platform like Topify for measuring how community replies translate into AI citations. Each layer solves a different problem.

    How do I generate authentic replies with AI?

    Authenticity comes from semantic alignment, not from the tool itself. Collect 10-15 gold-standard human-written examples from your team, define structural parameters (sentence length, vocabulary, punctuation), build an anti-persona that defines what your brand never sounds like, and run outputs through a human review before posting. That combination closes most of the “machine-feel” gap. Replies trained on brand-specific corpora also score up to 90% higher on consistency benchmarks.

    How do I use AI to respond to customer comments at scale without losing quality?

    Implement a tiered confidence system. High-confidence, routine replies go through a fast human approval queue. Low-confidence or emotionally complex comments route to a human specialist. This hybrid approach reduces average reply cycle time by 81% while improving lead quality by 33% compared to pure automation. The key is defining your confidence thresholds before you start, not after something goes wrong.

    How do AI-generated replies compare to manually written responses?

    Data shows no significant trust difference when the tone is genuinely conversational. The remaining gap is in “control mutuality”: users feel more heard when a human was clearly involved in the response. That’s the argument for human-in-the-loop review, not for abandoning AI generation. Mixed-model approaches combining AI speed with human refinement outperform both pure automation and fully manual workflows on engagement and conversion metrics.

    What are the best practices for using AI reply generators on Reddit and Quora?

    Follow the 95/5 rule: 95% pure value, 5% natural brand reference. Customize every reply to its specific thread context. Never post identical content across threads. Disclose AI involvement in communities that require it. On Reddit, include specific, verifiable data points rather than generic encouragement. On Quora, open with a direct 40-60 word answer block before expanding into detail. That structure earns upvotes and gets extracted by AI crawlers.

    How do I know if my community replies are influencing AI search results?

    Standard analytics won’t show you this. You need a tool that tracks AI citations at the source level, identifying which specific threads are being referenced by ChatGPT, Gemini, or Perplexity when users ask questions relevant to your brand. Topify’s Source Analysis was built specifically for this use case, and it connects directly to the Reddit Visibility Posts service so you can act on what you find.


    Read More