Your brand appears in a category prompt until the buyer adds one condition. Ask for a general recommendation and the model includes you. Add “for a regulated team,” “under $100,” or “with Salesforce integration,” and a competitor takes your place. A conventional content-gap report may show no obvious problem because both sites target the same keywords.
AI prompt gap analysis starts from the answer that changed. It compares prompts, recommendations, and cited evidence to determine whether the missing piece is product fit, content, authority, or simple measurement noise. That distinction prevents a visibility problem from turning into another generic article no buyer needs.
An AI Prompt Gap Is an Answer-Level Difference
An AI prompt gap exists when a brand, product, claim, or source is consistently present in relevant AI answers for competitors but missing or misrepresented for your brand. The unit of analysis is not the keyword. It is the prompt and the evidence path behind the generated response.
There are at least four different gaps that can look identical in a visibility dashboard:
- Recommendation gap: a competitor is selected and your brand is omitted.
- Citation gap: your brand is mentioned, but the answer relies on competitor or third-party sources.
- Attribute gap: the system cannot confirm a feature, price, policy, integration, or qualification.
- Narrative gap: the brand appears, but with a weaker or outdated description.
Each gap requires a different response. Publishing more category content may help a citation gap, but it will not make an unsupported integration exist or fix an outdated return policy in a product feed.
Prompt Gaps and Keyword Gaps Answer Different Questions
Traditional keyword gap analysis asks which queries competitors rank for and you do not. AI prompt gap analysis asks which decisions cause an AI system to prefer, cite, or describe competitors differently.
| Analysis type | Primary unit | Main evidence | Best question answered | Common blind spot |
|---|---|---|---|---|
| Keyword gap | Search query and ranking URL | Rankings, clicks, impressions | Where do competitors rank that we do not? | Cannot see synthesized recommendations |
| Content gap | Topic and page inventory | Coverage, format, depth | Which useful topic or format is missing? | May assume coverage creates visibility |
| Citation gap | Source URL or domain | Links used in AI answers | Which sources support competitor inclusion? | Citation may follow rather than cause selection |
| AI prompt gap | Prompt, constraints, answer, and sources | Repeated model outputs | Under which buyer conditions do we disappear? | Requires controlled, repeatable sampling |
Google’s guidance says generative features can use query fan-out to issue related searches and build a response. A single prompt can therefore expose multiple evidence gaps at once. A request for payroll software for a multinational team may require country coverage, compliance details, integrations, and pricing clarity before any brand is considered suitable.
The practical value is diagnosis. You are not merely learning that a competitor won. You are identifying which decision condition and source pattern accompanies the win.
Build a Controlled Prompt Set Before Comparing Brands
A reliable gap analysis needs prompt pairs or small prompt families that change one meaningful variable at a time. Begin with one decision, such as selecting a provider or comparing products, then create controlled variants around the constraints most likely to matter.
For example:
- Recommend project management software for a small agency.
- Recommend project management software for a small agency with client portals.
- Recommend project management software for a small agency under $20 per user.
- Recommend project management software for a small agency with SSO and audit logs.
Keep platform, language, region, and timing consistent. Run more than one observation because generated answers can change. Store the complete response, ordered recommendations, explanation, citations, and any follow-up questions.
Do not expand the set with dozens of cosmetic paraphrases before you understand the important constraints. More rows do not automatically produce better evidence.
Diagnose the Gap Across Four Evidence Layers
Once a prompt reliably produces a difference, trace it through four layers. This prevents teams from jumping from “we were absent” to “write a blog post.”
Layer one: product truth
Confirm whether the brand actually satisfies the condition. Check the current product, plan, geography, integration, security, and policy facts. If the competitor has a capability you do not, the result may be accurate rather than an optimization failure.
Layer two: owned evidence
Check whether the fact is available on a crawlable, current page. Product details hidden behind login, rendered only in an interactive widget, or mentioned vaguely in sales copy may be difficult to verify.
Layer three: independent corroboration
Review the external sources the answer uses. Independent reviews, directories, documentation, research, and community discussions may confirm or contradict owned claims. Do not manufacture endorsements or attempt to manipulate community content.
Layer four: answer behavior
Determine whether the pattern persists across repeated observations and platforms. One missing mention is a clue, not a conclusion. A stable omission tied to one constraint is much more actionable.
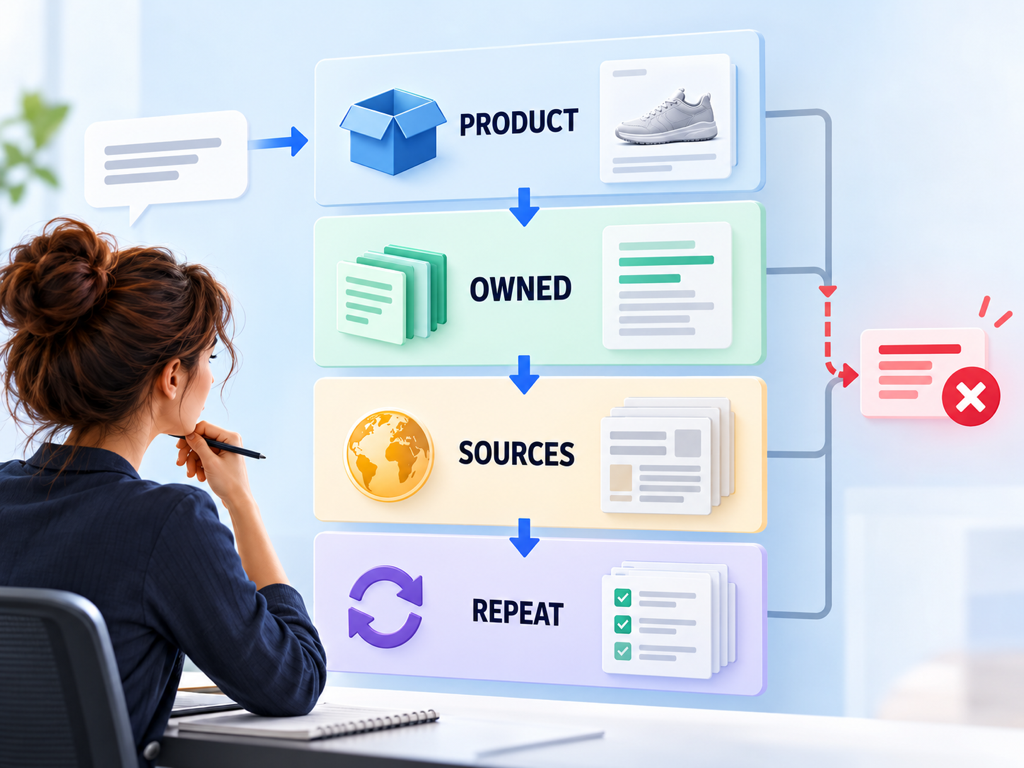
The layer where the evidence breaks determines the next action.
Classify the Root Cause Before Assigning Work
Most prompt gaps fall into a small set of root causes. Naming the cause makes the response more precise.
True fit gap: the product does not meet the requirement. Clarify positioning or route the prompt to a better-fit use case. Do not optimize around a false claim.
Evidence availability gap: the product fits, but the supporting information is missing, vague, inaccessible, or outdated. Improve the authoritative page or documentation.
Source authority gap: owned evidence exists, but independent sources consistently support the competitor. The response may involve analyst relations, digital PR, review programs, or stronger original research.
Entity ambiguity gap: the brand, product, or feature name is confused with another entity. Consistent naming, organization data, and clear product relationships may be required.
Measurement gap: the difference disappears when prompts are rerun or controlled. Increase the sample before changing strategy.
This taxonomy also sets a boundary. A content team should not promise to solve product fit, policy, or reputation problems with copy alone.
Turn the Diagnosis Into a Prioritized Action Queue
For every stable gap, record the prompt cluster, missing brand or claim, winning competitors, cited sources, root-cause hypothesis, confidence, owner, and next test. Then prioritize by business value and evidence strength.
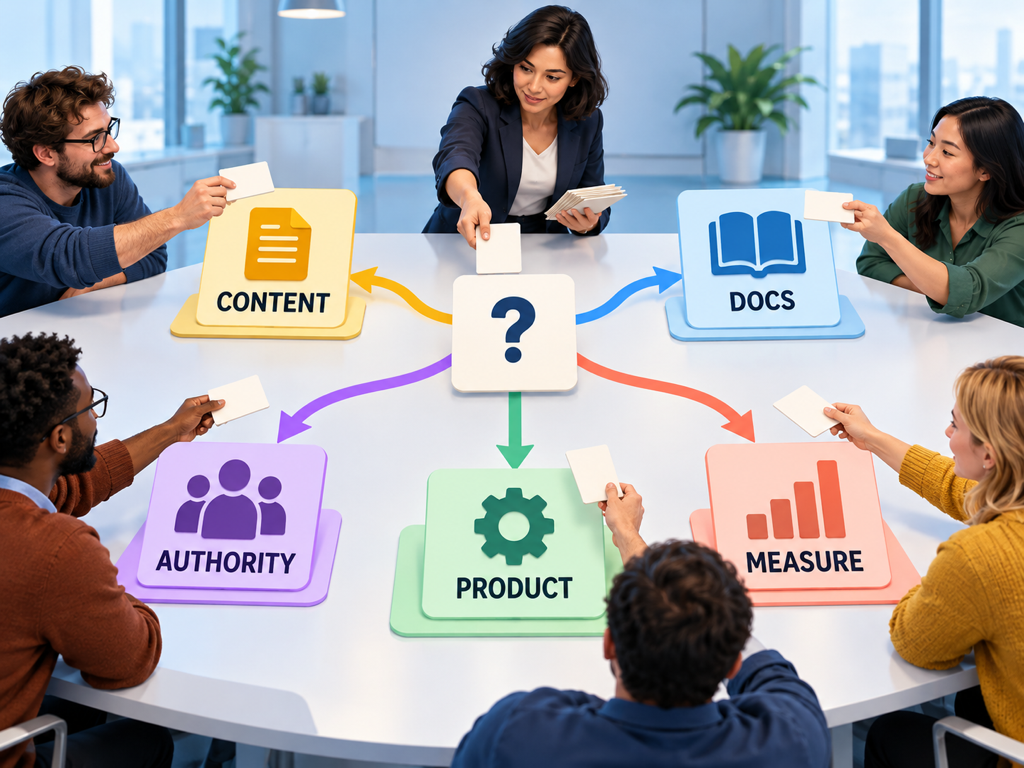
Use a simple decision rule:
- Create a new content asset only when the buyer decision is distinct, recurring, supportable, and not already served.
- Improve documentation when a verifiable product fact is hard to find or explain.
- Pursue external authority when trusted third parties repeatedly shape the answer.
- Escalate to product or operations when the gap reflects actual fit, availability, or policy.
- Gather more observations when the result is volatile or the sample is too small.
The queue should include rejection reasons. “No action” is valid when the prompt has weak relevance, the answer is factually correct, or the proposed asset would duplicate an existing page.
Measure Whether the Gap Actually Closes
Define the baseline before changing anything. At minimum, record brand inclusion, explicit recommendation, position when ordered, cited owned pages, cited third-party domains, competitor overlap, and sentiment or framing.
After an intervention, rerun the same prompt versions under the same conditions. Compare the stable cluster rather than adding new prompts mid-test. Allow enough time for crawling, indexing, feed refreshes, or source changes before declaring success.
Success is not limited to “brand mentioned.” A stronger result may be a correct attribute, an owned citation, a higher recommendation position, or the removal of an outdated caveat. The metric should match the diagnosed gap.
Google advises site owners to focus on helpful, reliable, people-first content rather than pages designed only to attract search systems. That principle applies here. The asset should resolve the buyer’s evidence need even if no AI answer changes immediately.
Use Topify to Connect Prompt Gaps With Sources and Competitors
Topify can make the monitoring part of this workflow repeatable. Its current Prompt Discovery page describes visibility-gap detection, competition analysis, and prompt opportunity scoring. Use those signals to identify prompt clusters where competitors appear and your brand does not.
Then inspect the answer and citation layer rather than treating an opportunity score as a content order. Compare controlled prompt variants, review which competitors persist, and map the sources supporting their inclusion. Tag each gap with the root-cause taxonomy before assigning work.
Keep paid or high-volume prompt activation separate from planning. Approve the exact prompt set, platforms, regions, and cadence before it becomes a recurring monitor. A smaller stable baseline is usually more informative than a large, changing collection.
The outcome should be a defensible action queue: which evidence is missing, why that matters to the buyer, who owns the fix, and how the same prompt set will verify the result.
Conclusion
AI prompt gap analysis is most useful when it explains why a recommendation changes, not merely where your brand is absent. A controlled prompt set lets you connect buyer constraints to product truth, owned evidence, independent sources, and repeated answer behavior.
Start with one decision and vary one condition at a time. Classify stable gaps as fit, evidence, authority, ambiguity, or measurement problems. Then assign the fix to the right owner and retest the unchanged baseline. That process turns an opaque AI omission into a bounded business question without filling the blog with duplicate content.
FAQ
What is AI prompt gap analysis?
AI prompt gap analysis compares repeated AI answers to find prompts where competitors are recommended, cited, or described more favorably, then traces the difference to its evidence source.
How is prompt gap analysis different from keyword gap analysis?
Keyword gaps compare search rankings. Prompt gaps compare generated answers, buyer constraints, recommendations, citations, and supporting evidence across AI experiences.
Does every AI prompt gap require new content?
No. The cause may be product fit, missing documentation, weak independent corroboration, entity confusion, or sampling noise. New content is only one possible response.
How many times should an AI prompt be tested?
There is no universal minimum. Use repeated observations sufficient to distinguish a persistent pattern from normal variation, and keep platform, region, language, and prompt version consistent.
Leave a Reply