Author: Elsa Ji

  • Does Claude Fable 5 Recommend Your Brand? Here’s a Free Check

    Does Claude Fable 5 Recommend Your Brand? Here’s a Free Check

    A prospect used to open Google, type your category, and scan a page of links until they found you. Now they open Claude, ask for the best option in your space, and read a short answer that names three brands. If yours isn’t one of them, the conversation is over before you knew it started. Your keyword rankings won’t flag this, because they were never built to measure what a model chooses to say out loud.

    Why Claude Fable 5 Changes Who Gets Recommended

    Claude Fable 5 is Anthropic’s most capable widely released model, built for long-horizon, autonomous research work. It doesn’t hand back ten blue links and let the user sort it out. It reasons across sources, cross-checks them, and returns a shortlist of named brands.

    That matters more every month. Claude’s share of AI answers grew 64x over the tracked period, overtaking Perplexity in March 2026. The audience asking Claude “who should I use” is no longer a rounding error.

    Here’s the part most teams miss. The shift isn’t from ranking lower to ranking higher. It’s from being listed to being named.

    Fable 5 also decides differently than a search engine. It leans on entity authority and how consistently your brand shows up across trusted third-party sources, not on keyword density or raw backlink counts. If the model can’t corroborate your brand across several reliable domains, its verification loop tends to drop you as unconfirmed. A high Google ranking doesn’t buy you a seat at that table.
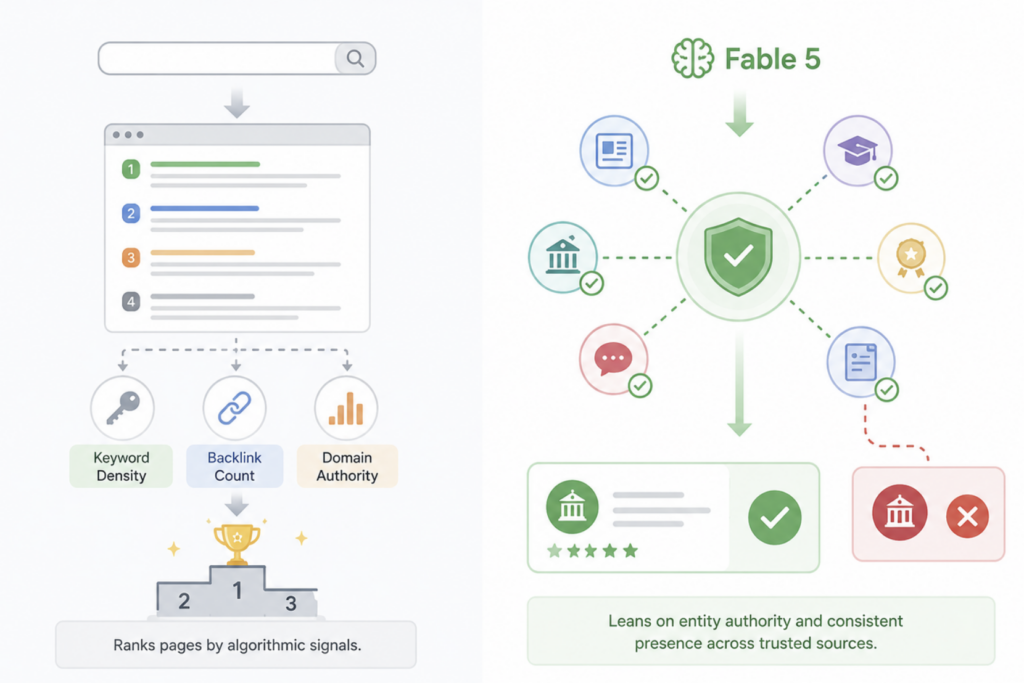
    The Blind Spot: Your SEO Metrics Can’t See AI Brand Visibility

    Most marketing teams are measuring the wrong surface. Rank trackers tell you where a page sits in a list of links. They say nothing about whether your brand appears inside an AI-generated answer.

    The gap is wider than it looks. A 2026 local visibility study found AI platforms recommend a tiny slice of the businesses that win in traditional search: 1.2% through ChatGPT and 11% through Gemini, against 35.9% appearing in Google’s local 3-pack. By that measure, AI visibility runs three to 30 times harder to earn than a strong local ranking.

    The click is disappearing too. Up to 83% of AI-generated answer queries get resolved on the results page without a visit to any website. So even a page that ranks well can go completely unseen if the model summarizes the answer and never cites you.

    And the two disciplines have quietly decoupled. Strong search rankings no longer predict AI visibility; the correlation between the two has fallen sharply in a single year. Good SEO is not automatically good GEO.

    You can’t optimize what you can’t see.

    What “Does Claude Recommend Your Brand” Actually Means

    Treat “recommended” as a scale, not a yes-or-no. A model can name you often but describe you as the budget option. It can mention you once and bury you at the bottom of a five-brand list. AI brand visibility is really a bundle of signals, and each one moves independently.

    DimensionWhat it measures
    Mention frequencyHow often your brand surfaces in model answers
    Sentiment and contextWhether you’re framed as a leader or an also-ran
    Comparative positionWhere you land in a ranked list of options
    Citation densityHow many high-authority sources tie you to your category
    Source authorityThe quality of the domains the model relies on to cite you
    Entity consistencyHow cleanly your brand data reads across the web
    Answer relevanceHow directly you match the specific question asked

    This is also why a single flattering answer can mislead you. Fable 5 builds its picture of your brand from repeated corroboration. Industry estimates put the bar around 250 unique mentions for a model to form a stable understanding of who you are. One mention today doesn’t make you a trusted entity tomorrow.

    How to Check for Free in Under Three Minutes

    You don’t need a contract or a sales call to find out where you stand. Topify runs a free GEO score check that takes about three minutes and no signup.

    The flow is simple. You enter your domain, and the tool returns a GEO score with a baseline read on how visible your brand is across AI answers. It’s the fastest way to turn a vague worry (“are we even showing up?”) into a number you can act on.

    Run it. Read the score. Then decide what’s worth doing next.

    Think of the score as a diagnostic, not a verdict. A low number doesn’t mean your brand is broken; it usually means the corroborating signals AI models look for aren’t in place yet. That’s fixable, but only once you know it’s the problem.

    From a One-Time Score to Ongoing AI Brand Visibility Tracking

    A single score is a snapshot, and AI search doesn’t hold still. Across major platforms, 40% to 60% of cited sources change from one month to the next. A source that anchored your visibility in June can quietly drop out in July, and your score falls without any change on your end.

    That volatility is the argument for continuous monitoring over one-off audits. This is where Topify’s Comprehensive GEO Analytics picks up after the free check. It tracks your brand across ChatGPT, Perplexity, Gemini, and Claude, and it separates the signals that a rank tracker collapses into one: mention frequency, sentiment, and comparative position, each monitored over time rather than sampled once.

    The Source Analysis layer is what makes a score drop diagnosable. Instead of telling you your visibility fell, it reverse-engineers the exact domains and URLs the models cite in your category. In practice, that means you can catch a dip in Claude mentions, trace it to a specific third-party source that stopped referencing your brand, and know precisely which relationship or piece of content to rebuild. Competitor benchmarking sits alongside it, so you can see which rival the model started naming in your place and why.
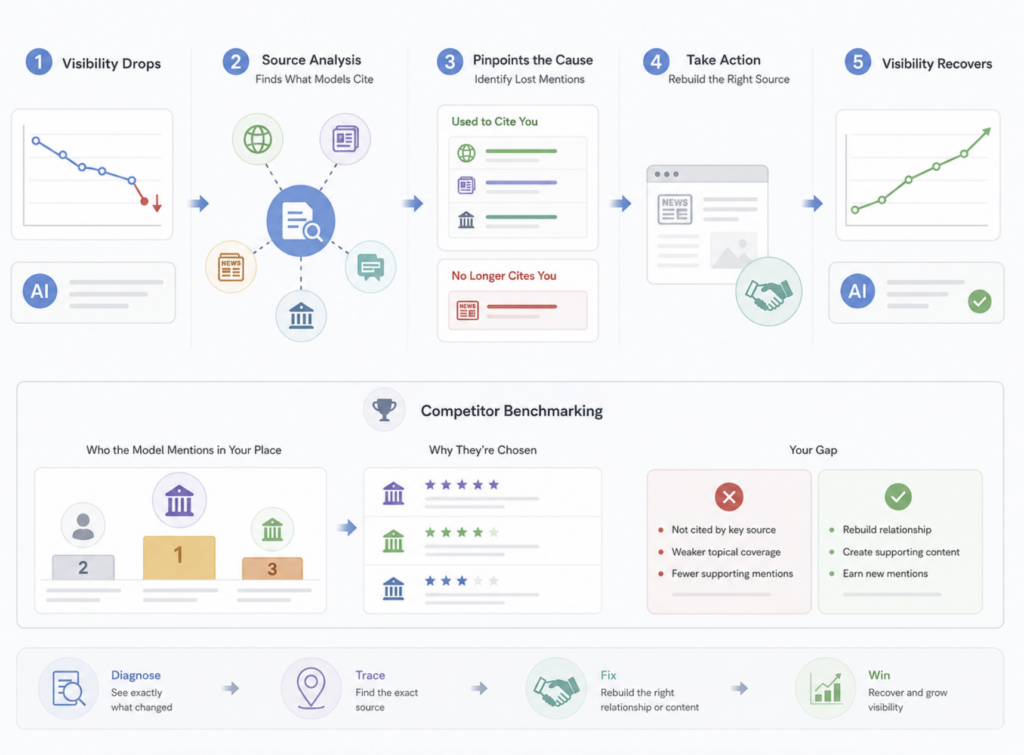
    That’s the difference between knowing you slipped and knowing what to fix. A dashboard full of numbers is easy to build. Connecting a number to a cause is the harder problem, and it’s the one that actually changes what your team does on Monday.

    What to Do With the Results

    A GEO score is only useful if it points somewhere. Once you have yours, a few moves tend to matter most.

    Start with your source footprint. If the models aren’t citing you, the fix is usually more corroboration across trusted third-party domains, not another page on your own site. Trade media, niche communities, and professional directories carry weight that a company blog can’t.

    Then structure content for extraction. AI models pull cleanly from tables, lists, and direct fact statements, and far less easily from long narrative prose. Rewriting a dense explainer into scannable, fact-first blocks often lifts citability on its own.

    Finally, watch position, not just presence. Being named fifth in a list of five is barely better than being absent, so track where you land relative to competitors and treat slippage as an early warning. If you want to start tracking rather than guessing, get started with Topify and set a baseline you can measure against.

    Conclusion

    Your prospects are already asking Claude Fable 5 which brand to choose. The only open question is whether the model names you, how it describes you, and where you sit against your competitors, none of which your ranking reports can answer. Run the free GEO score check first to see where you actually stand. If the number gives you a reason to worry, that’s the moment to move from a one-time snapshot to ongoing AI brand visibility tracking, while the answer box in your category is still up for grabs.

    FAQ

    Does Claude Fable 5 actually recommend specific brands? 

    Yes. When a user asks for the best option in a category, Fable 5 reasons across sources and returns a shortlist of named brands rather than a page of links. Whether your brand appears depends on how consistently AI models can corroborate it across trusted third-party sources.

    How is checking AI brand visibility different from checking my Google ranking? 

    A Google ranking tells you where a page sits in a list. AI brand visibility tells you whether your brand is mentioned inside an AI answer, how it’s described, and where it ranks against competitors. Since up to 83% of AI answers end without a click, ranking well and being cited are now two separate things.

    Can I check if Claude recommends my brand for free? 

    Yes. Topify’s free GEO score check returns a baseline read on your AI visibility in about three minutes with no signup, so you can see where you stand before committing to anything.

    How often should I track my brand’s visibility in Claude and other AI tools? 

    Often enough to catch change, because 40% to 60% of the sources AI models cite shift month to month. A one-time score gets stale fast, so continuous monitoring is the only way to spot a drop early and trace it to a cause.
    Read More

  • How to Get Your Brand Cited by Claude Fable 5

    How to Get Your Brand Cited by Claude Fable 5

    You’ve spent months getting your content cited in ChatGPT and Perplexity answers. The tactics worked: clean headings, a few stats, a page that ranked. Then Claude Fable 5 launched, and the same content stopped surfacing. Fable 5 doesn’t skim and summarize. It reads across dozens of sources, cross-checks them against each other, and drops anything it can’t verify. The bar for getting cited just moved, and most of the old playbook doesn’t clear it.

    Why Claude Fable 5 Rewrites the Rules for Getting Cited

    Claude Fable 5 isn’t a bigger version of the chat model you already optimized for. It’s a long-horizon reasoning model that behaves less like a search box and more like a junior analyst. Before it answers, it explores multiple approaches, checks its own reasoning, and hunts for edge cases.

    That changes what “getting cited” means. Older models often paraphrased whatever ranked well. Fable 5 treats each source as raw material to be verified, not a fact to be trusted on sight.

    Here’s the gap most brands miss. Ranking in search gets you into the model’s reading pool. It doesn’t get you into the answer.

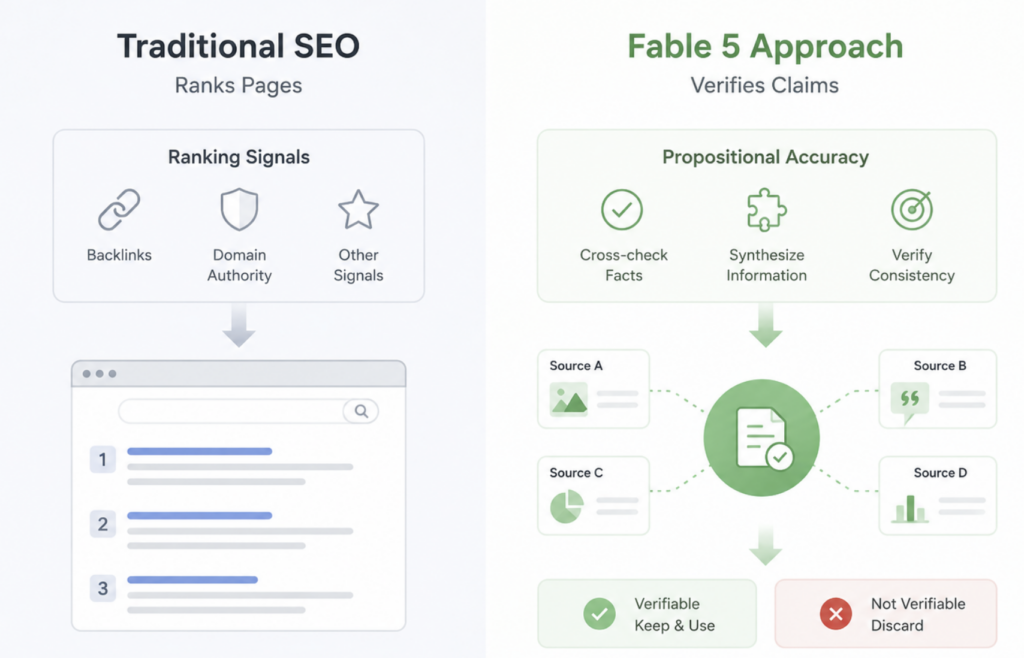
    Traditional SEO leans on ranking signals like backlinks and domain authority. Fable 5 leans on propositional accuracy: whether a specific claim holds up when checked against everything else it just read. Content that appears in results but carries no verifiable data tends to get read and then quietly discarded.

    How Claude Fable 5 Decides Which Sources to Cite

    To optimize for Fable 5, you have to understand what its reasoning loop is actually filtering for. Three patterns show up consistently in how frontier models handle citations.

    The first is consensus. When a claim shows up across multiple independent, high-authority domains, the model treats it as closer to ground truth. Research on citation behavior found that when multiple independent models cite the same work, perceived accuracy runs 95.6% higher. A single “rank #1” page rarely carries that weight on its own.

    The second is how the model resolves conflict. When Fable 5 hits contradictory data, it doesn’t just pick the top result. It applies a weighted consensus that favors positions repeated across trusted, independent sources. Being loud in one place loses to being consistent across many.

    The third is structure. Models cite passages, not pages. They pull the specific chunk of text that satisfies a logical need in their response, and they strongly prefer chunks that are easy to parse.

    That’s the real unit of GEO now: the passage, not the URL.

    Step 1: Structure Content So Claude Fable 5 Can Extract and Trust It

    Your first job is to make content agent-readable. That means shifting from keyword-dense copy to data-dense architecture, where every section answers a concrete question and backs it with something checkable.

    Start with your headings. Write them as the questions a user would actually ask. “What are the core benefits of X?” gives the model a clean retrieval target. “The Benefits” gives it nothing to match against.

    Then serialize your data. Comparative prose is hard for a model to extract cleanly, and it tends to lose the pieces. Structured formats hold together far better: analysis of citation patterns suggests tables, numbered steps, and lists get pulled with markedly higher reliability than the same information buried in paragraphs.

    There’s a sequencing trick here too, sometimes called baseline-expand. Confirm the facts the model already believes, then extend them with something new. A passage that first aligns with established knowledge, then adds proprietary data or original research, gives Fable 5 a reason to cite you specifically instead of a generic source.

    Practical version: lead each section with the accepted answer, then add the number, benchmark, or finding only you can provide.

    Step 2: Build Cross-Source Corroboration Around Your Claims

    One authoritative page on your own domain isn’t enough anymore. Because Fable 5 validates by cross-referencing, a claim that lives in exactly one place looks unverified, no matter how strong that page is.

    The fix is what you might call echo-and-expand. Your key brand claims and proprietary data should show up across several independent channels, not just your homepage. Think third-party technical blogs, industry directories, expert forums, and analyst mentions. Each independent echo raises the odds your claim survives the model’s cross-check.

    Anchor those echoes to domains the model weights heavily. Established industry journals, .edu and .gov sources, and recognized reference sites act as truth anchors in a reasoning loop.

    The trade-off is that this takes longer than publishing one great page. But it’s what separates a claim Fable 5 repeats from one it ignores.

    Bottom line: if your most important stat exists in only one location on the web, you’ve built a single point of failure into your AI visibility.

    Step 3: Track Whether Claude Fable 5 Is Actually Citing Your Brand

    Here’s the problem with everything above. You can’t see it working. Fable 5’s answers are generated on the fly, vary between sessions, and shift as its safety classifiers and rerouting logic evolve. Spot-checking by asking the model a few questions yourself isn’t a strategy. It’s a guess.

    This is where measurement stops being optional. To manage citation authority, you need continuous telemetry on what the model pulls into its context and what it says about you.

    For teams tracking this at scale, Topify is built around reverse-engineering AI citations rather than guessing at them. In practice, that means three connected views. Visibility tracking monitors how often your brand gets mentioned across Claude, Perplexity, and ChatGPT, so you can tell whether a content change moved the needle. Source analysis reverse-engineers the exact domains and URLs the model pulls into its context, which shows you whether Fable 5 is citing your page or a third party echoing your claim. Competitor benchmarking flags when a rival captures a citation slot in a reasoning thread you used to own, so you can react while it still matters.

    The shift is from rank-tracking to share of citation. Google rankings tell you where a page sits. Citation analytics tell you whether the model is actually building its answer on you. If you want the full picture of how these tools compare, this breakdown of AI citation tracking platforms in 2026 is a useful starting point.

    You can get started with Topify on a single brand before scaling the workflow across clients.

    The Mistakes That Keep Brands Out of Fable 5’s Answers

    Most brands that stay invisible to Fable 5 make the same handful of errors.

    They optimize only for ChatGPT and assume it transfers. It doesn’t. A deep-research model applies a stricter verification bar, so surface-level content that passed before now fails.

    They publish claims with no corroboration. A bold stat on one page, echoed nowhere else, reads as unverified and gets skipped during cross-check.

    They treat GEO as a one-time project. Fable 5’s citation patterns move week to week, so a single optimization pass ages fast.

    And they measure the wrong thing. Watching your keyword rank tells you nothing about whether the model mentions you. Rank and mention are separate signals, and only one of them shows up in the answer.

    Fix those four, and you’ve cleared most of the field.

    Conclusion

    Getting cited by Claude Fable 5 isn’t about ranking higher. It’s about becoming a verifiable, structured, corroborated source the model can trust inside a multi-step reasoning loop. Structure your content for extraction. Echo your key claims across independent, high-authority domains. Then measure share of citation continuously, because a model this dynamic can’t be tracked by hand. Start with one high-value topic, confirm whether Fable 5 is pulling you into its answers, and expand from there. The brands that treat citation authority as a measurable channel, not a lucky break, are the ones that show up.

    FAQ

    Does Claude Fable 5 actually cite sources in its answers? 

    Yes. Fable 5 reads and cross-checks multiple sources during its reasoning process, and it favors claims corroborated across independent, high-authority domains. Its citations reflect what survived verification, not just what ranked.

    How is getting cited by Fable 5 different from ranking on Google? 

    Google rewards ranking signals like backlinks and domain authority. Fable 5 rewards propositional accuracy: whether a specific claim holds up when checked against everything else it read. You can rank well and still never be cited.

    How long until content changes show up in Fable 5’s citations? 

    There’s no fixed window, and it varies by topic and how quickly independent sources pick up your claims. Because citation patterns shift week to week, continuous tracking beats a single before-and-after check.

    Can I track my brand’s citations across Fable 5 and other AI models? 

    Yes. Platforms like Topify monitor mentions and source citations across Claude, Perplexity, and ChatGPT in one place, so you can compare share of citation across models instead of spot-checking each one manually.

    Read More

  • What Is Claude Fable 5? Features, Pricing, and What It Means

    What Is Claude Fable 5? Features, Pricing, and What It Means

    A new frontier model drops, and most marketing teams file it under “developer news.” Claude Fable 5 doesn’t fit that box. When a model gets better at reasoning through a question on its own, it changes which brands it names in an answer and which ones it quietly leaves out. That shift happens whether or not your team is watching. The metrics that told you how you rank on Google were never built to tell you what a model like this decides to say about you.

    What Claude Fable 5 Actually Is

    Claude Fable 5 launched on June 9, 2026 as the first Mythos-class model Anthropic has made generally available. The Mythos tier sits above the older Opus class in Anthropic’s hierarchy, and it’s positioned for the hardest, longest-running work rather than quick back-and-forth chat.

    Under the hood, Fable 5 shares the same architecture as Claude Mythos 5. The difference isn’t the model. It’s the safety configuration layered on top, which we’ll get to below.

    Here’s the part that matters for anyone tracking AI search. Fable 5 is built to operate with minimal human oversight, handling multi-day, multi-stage projects instead of single prompts.

    That’s the real story: this is a model designed to work on its own, not just answer faster.

    The Features That Set Claude Fable 5 Apart

    Fable 5 moves the center of gravity from “smart chatbot” to autonomous operator. A few capabilities define that shift.

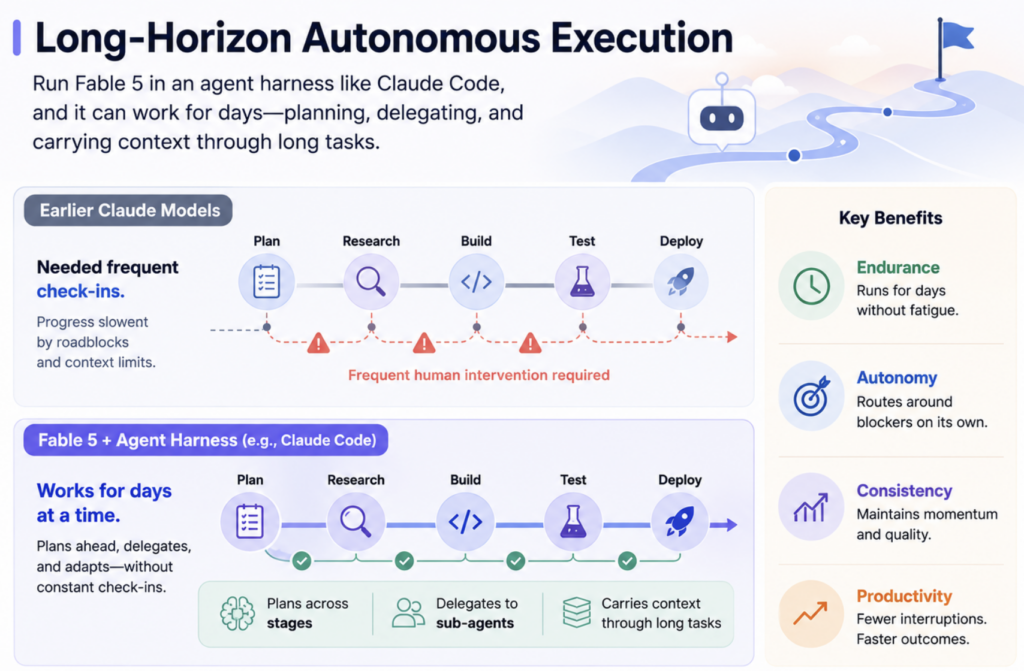
    Long-horizon autonomous execution. Run Fable 5 inside an agent harness like Claude Code, and it can work for days at a time, planning across stages, delegating to sub-agents, and carrying context through a long task. Earlier models needed frequent check-ins. This one routes around blockers on its own.

    Self-verification. The model writes its own test suites and uses vision to check its output against the original design or goal. So a team reviews finished work rather than supervising every step.

    Visual reasoning. Fable 5 reads diagrams, charts, and tables buried inside PDFs and technical documents. In one demonstration, it completed Pokémon FireRed using only raw game screenshots, with no maps or navigation aids. That vision strength carries into finance, legal, and analytics work where the data lives inside dense figures.

    Scale. A 1M token context window and up to 128K tokens of output per request. That’s enough to hold a large codebase or an extensive legal archive in a single session.

    Independent testers describe it as slow and expensive, but capable of churning through almost anything thrown at it. The trade-off is clear: Fable 5 earns its keep on long, ambiguous tasks, not on quick lookups.

    Claude Fable 5 Pricing and How to Access It

    Fable 5 is priced at $10 per million input tokens and $50 per million output tokens, with the existing 90% discount on cached input tokens. For workloads that need to run inside the United States, US-only inference is available at 1.1x that rate.

    For context, that’s double Opus 4.8’s standard rate of $5 / $25. The premium buys frontier capability on long-running work, not a better deal on short prompts.

    On the access side, Fable 5 is available to Pro, Max, Team, and Enterprise users on Claude.ai, through the Claude API as claude-fable-5, and across AWS, Google Cloud, and Microsoft Foundry. Using it requires 30-day data retention for safety monitoring, and it isn’t offered under zero data retention.

    One note on availability. Access was briefly suspended in June 2026 to comply with a US export control directive, then restored shortly after. If you’re evaluating it for a specific region, confirm current terms before you build on it.

    Fable 5 vs Mythos 5 vs Opus 4.8

    The cleanest way to place Fable 5 is against its two closest neighbors. Mythos 5 is the same model with safeguards lifted in specific areas, and Opus 4.8 is the tier below it.

    FeatureClaude Fable 5Claude Mythos 5Claude Opus 4.8
    ClassMythos-classMythos-classOpus-class
    SafeguardsActive (standard)Lifted in some areasStandard
    AvailabilityGenerally availableLimited (Project Glasswing)Generally available
    Input price$10 / MTok$10 / MTok$5 / MTok
    Output price$50 / MTok$50 / MTok$25 / MTok

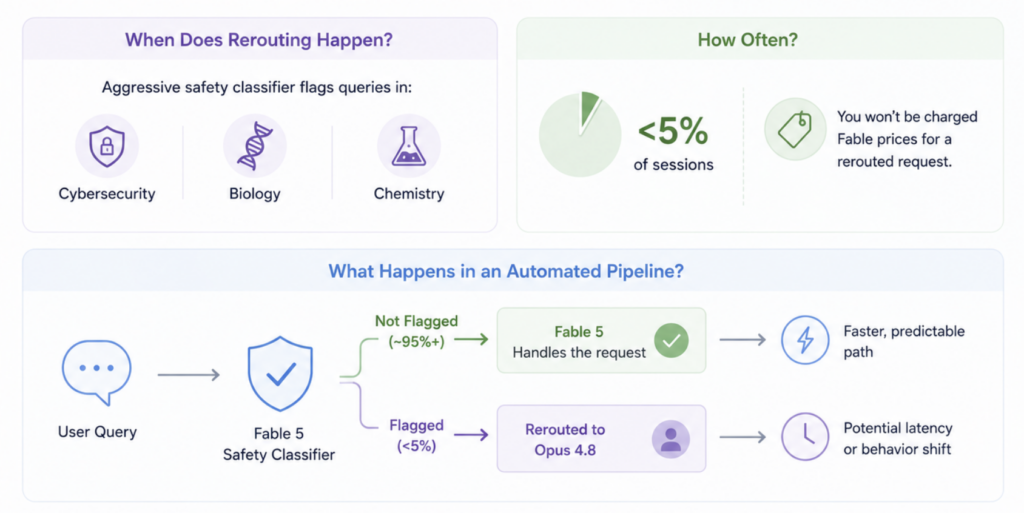
    The safeguards are more than a footnote. Fable 5 ships with safety classifiers covering cybersecurity, biology, chemistry, and distillation. When a query trips one, the request falls back to Opus 4.8 instead of Fable 5, and you aren’t charged Fable’s premium rate for that rerouted request.

    Anthropic tuned those classifiers conservatively, so they trigger in less than 5% of sessions on average, with some harmless requests caught along the way. Mythos 5, by contrast, runs without those classifiers and stays gated to a small set of vetted partners through Project Glasswing.

    So for nearly all general use, “Fable 5” and “the most capable model I can actually get” mean the same thing.

    Why Claude Fable 5 Matters for AI Search Visibility

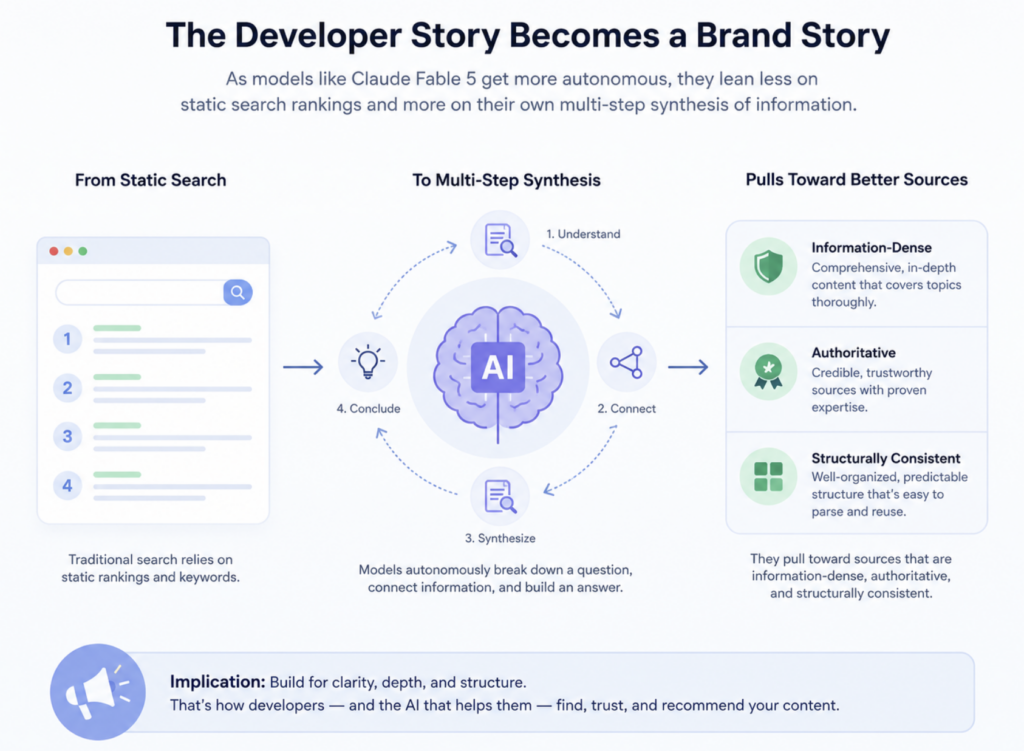
    Here’s where the developer story becomes a brand story. As models like Claude Fable 5 get more autonomous, they lean less on static search rankings and more on their own multi-step synthesis of information. They pull toward sources that are information-dense, authoritative, and structurally consistent.

    That changes the game for anyone who depends on being recommended by AI. A model that reasons through a category and picks what to cite is making an editorial choice about your brand, on every answer, without telling you.

    Traditional SEO can’t measure that choice. It was built for a ranked list of blue links, not for a synthesized paragraph that names three competitors and skips you.

    This is the gap that Generative Engine Optimization is meant to close, and it’s where a monitoring platform like Topifyfits in. Instead of guessing whether Fable 5 or any other model mentions you, teams track it directly.

    In practice, that means watching a few things at once. You can monitor source citation frequency to see whether a model references your brand in the contexts that matter, run competitor benchmarking to catch how rival positioning shifts after a model update, and keep cross-model telemetry across ChatGPT, Perplexity, and Claude so your visibility score stays consistent no matter which architecture is answering. Topify’s Comprehensive GEO Analytics rolls those signals into a single view built around visibility, sentiment, position, and source data.

    The point isn’t to chase every model release. It’s to know, with data, what the current generation of models says about you before a customer asks one for a recommendation.

    Conclusion

    Claude Fable 5 isn’t a routine upgrade. It’s a step toward AI that plans, executes, and checks its own work over days, which is why it reads as a developer milestone. But the same autonomy that makes it useful for coding also reshapes how AI decides which brands to surface. If your visibility now depends on a model’s synthesis rather than a search ranking, the practical move is to establish a baseline visibility score today and start tracking how your brand gets cited across models as they update.

    FAQ

    What is Claude Fable 5? 

    It’s Anthropic’s first generally available Mythos-class model, released June 9, 2026. It’s built for long-horizon, autonomous coding and knowledge work, and it sits above the Opus tier in capability.

    How is Claude Fable 5 different from Mythos 5? 

    They share the same underlying model. Mythos 5 runs with safeguards lifted in specific areas and stays limited to vetted partners through Project Glasswing, while Fable 5 is generally available with standard safety classifiers active.

    What happens if a Claude Fable 5 prompt gets blocked? 

    If a query trips a safety classifier, it’s rerouted to Opus 4.8 rather than answered by Fable 5, and you aren’t charged Fable’s premium rate for that rerouted request.

    Can I use Claude Fable 5 right now? 

    Yes. It’s available through Claude.ai for Pro, Max, Team, and Enterprise users, through the Claude API, and on AWS, Google Cloud, and Microsoft Foundry, subject to a 30-day data retention requirement and current regional terms.

    Read More

  • Claude Fable 5 vs Claude Mythos 5: What’s the Difference?

    Claude Fable 5 vs Claude Mythos 5: What’s the Difference?

    Two model names landed on the same day in June 2026, from the same lab. Most people read that as a product ladder: a standard tier and a premium one stacked above it. That read is backwards, and the mistake changes how you’d pick between them.

    The honest starting point for “what’s the difference” is what isn’t different. Under the hood, Claude Fable 5 and Claude Mythos 5 are the same model.

    So the real question was never capability. It’s who gets to use the raw thing, and what sits in front of everyone else.

    Why “Which One Is Smarter” Is the Wrong Question

    Anthropic released both models on June 9, 2026 as the second generation of a new tier it calls Mythos-class, which sits above the Opus line in raw capability. Fable and Mythos share one trained base. The architecture isn’t split. Only the deployment configuration is.

    That’s the part most comparisons get wrong.

    Asking whether Mythos 5 is “more intelligent” than Fable 5 is like asking whether a car is faster with or without a speed limiter bolted on. Same engine. The limiter is a product decision, not a spec. Every benchmark you’ve seen for Fable 5 describes Mythos 5’s ceiling too, because they’re reading the same weights.

    The naming reinforces it. Fable comes from the Latin fabula, “that which is told,” a close cousin of the Greek mythos. Two names for one story, told to two different audiences.

    Claude Fable 5 vs Claude Mythos 5 at a Glance

    Here’s the split in one view. Read it as configuration and access, not tiers of intelligence.

    DimensionClaude Fable 5Claude Mythos 5
    Underlying modelSame Mythos-class baseSame Mythos-class base
    AvailabilityGenerally availableRestricted to vetted orgs
    Safety classifiersOn: cyber, bio/chem, distillationLifted for approved defensive work
    When a classifier tripsFalls back to Opus 4.8, tells youNot applicable
    Pricing$10 in / $50 out per M tokens$10 in / $50 out per M tokens
    Context / max output1M tokens / 128K tokens1M tokens / 128K tokens
    Data retentionStandard30 days for Mythos-class traffic
    Who it’s forEveryoneProject Glasswing partners

    Look at the pricing row. Both cost the same because you’re paying for the compute of a Mythos-class model, no matter which safety layer is switched on. At $10 per million input tokens and $50 per million output, it runs about half the price of the earlier Mythos Preview, though it’s still the priciest option in Anthropic’s current lineup.

    What Claude Fable 5 Actually Is

    Claude Fable 5 is the version nearly everyone touches. It’s the generally available model, wrapped in a set of safety classifiers, and it’s the default when you reach the Mythos-class tier through consumer apps or the API.

    On raw capability, the numbers are steep. Anthropic reports Fable 5 scoring around 80.3% on SWE-Bench Pro, an agentic software engineering benchmark, against 69.2% for Opus 4.8 and 58.6% for GPT-5.5, per Anthropic’s launch data. The lead widens on long, multi-step work. Stripe reported the model finishing a migration across a 50-million-line Ruby codebase in a single day, a job its team had scoped at over two months.

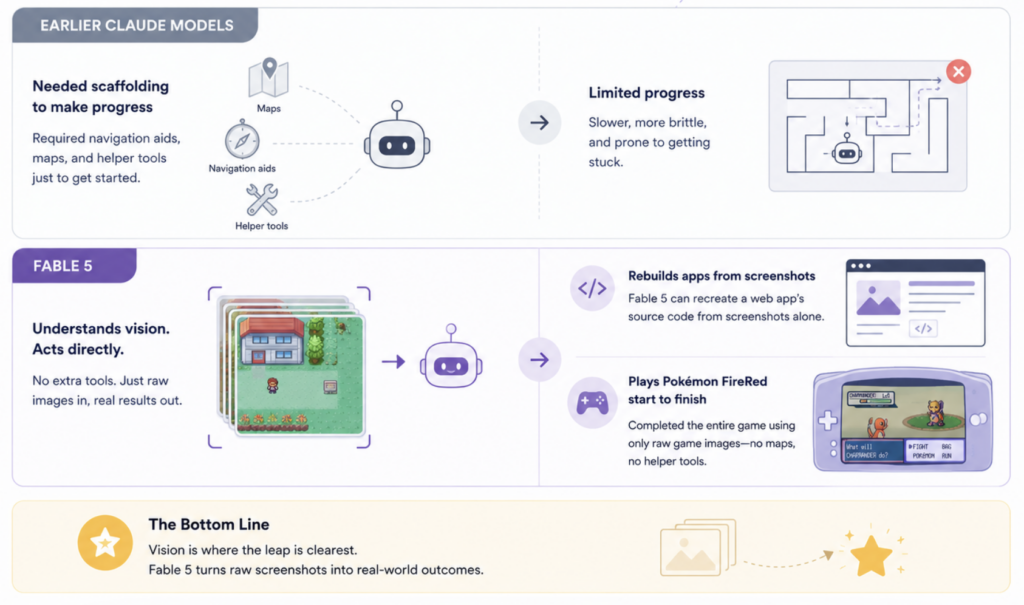
    Vision is where the leap is easiest to picture. Fable 5 can rebuild a web app’s source code from screenshots alone, and it played through Pokémon FireRed start to finish on raw game images, with no maps or helper tools. Earlier Claude models needed a scaffolding of navigation aids just to make progress.

    The safeguards are what make all of that public. Fable 5 ships with classifiers watching three areas: cybersecurity exploitation, biology and chemistry risk, and attempts to distill the model into a competing system. Trip one, and the request doesn’t simply fail. It’s quietly handed to Claude Opus 4.8, and you’re told it happened.

    Most sessions never hit that wall. Anthropic’s early data shows more than 95% of Fable 5 sessions involve no fallback at all. For those, you’re getting the full Mythos-class model with nothing in the way.

    Claude Mythos 5 and Who Actually Gets It

    Claude Mythos 5 is the same model with specific safeguards lifted. It exists for cases where the classifiers would block legitimate, high-stakes work.

    Think defensive cybersecurity. Mythos-class models are unusually good at finding and exploiting software vulnerabilities, which is dangerous in the wrong hands and genuinely useful for teams defending critical infrastructure. Unblocked, the model scores around 78% on cyber exploitation evaluations, close to double Opus 4.8’s 40%, via The Decoder’s benchmark roundup. That’s the capability Anthropic won’t let loose, and also the one security researchers actually need.

    Access is gated. Mythos 5 goes to vetted organizations through Project Glasswing and a Trusted Access Program, aimed at cyber defenders, infrastructure providers, and a small set of biology researchers. Traffic on Mythos-class access also carries a 30-day data retention requirement.

    Here’s the trap to avoid: Mythos 5 is not “Fable Pro.” It isn’t an upgrade you’re locked out of. If you’re not an approved partner, you use Fable 5, and you lose nothing in raw model quality by doing so.

    The Safeguards Are the Entire Difference

    Strip away the naming and the story is plain. One model, two safety configurations, two access doors.

    For developers, the difference shows up in the API. When Claude Fable 5 declines a request, it returns a refusal as a successful response rather than an error, and it reports which classifier fired. You can set a fallback so a refused call retries on another Claude model on its own. The raw chain of thought never comes back on either model; you get a readable summary or an empty thinking block instead.

    Then there’s the part that made headlines. On June 12, 2026, three days after launch, Anthropic suspended access to both models to comply with U.S. export control requirements tied to national security. Access returned at the start of July, once the compliance and classifier questions were worked through. Anthropic’s own statement lays out the timeline.

    It’s a useful signal, not just trivia. A model powerful enough for a government to step in during week one is a model powerful enough to reshape how information gets surfaced downstream.

    What a More Capable Model Means for Your Brand’s Visibility

    Step back from the spec sheet. Models like Claude Fable 5 are the engines behind the AI assistants and search tools people now ask for recommendations. As those engines get sharper and cheaper, more discovery runs through them, and the model’s read on which sources are credible starts deciding who gets mentioned.

    That’s a quieter shift than the benchmark charts. For anyone building a brand, it’s the bigger one.

    Traditional SEO signals like backlink counts and keyword density don’t map cleanly onto how a model like Fable 5 assembles an answer. It weighs information-dense, credible sources and cites a handful of them. If your brand isn’t in that handful, you’re absent from the exact spot where buyers are now asking. This is the problem generative engine optimization, or GEO, exists to address.

    The harder part is that this visibility is model-aware and drifts between model generations. What you show up for in one engine can look nothing like another, and a single model release can reshuffle citations overnight. Tracking your share of voice by hand across ChatGPT, Perplexity, and AI Overviews doesn’t scale.

    That’s the gap a platform like Topify is built for. Its Comprehensive GEO Analytics tracks how often your brand appears across major AI engines, where you land against competitors, and which sources those engines actually cite when they answer. When a model like Fable 5 shifts how it weighs authority, you see the change in your visibility data instead of guessing at it.

    Bottom line: the model race isn’t only an engineering story. It’s a distribution story, and your brand’s place inside AI answers is the metric worth watching.

    Conclusion

    Claude Fable 5 and Claude Mythos 5 aren’t a good-versus-better pairing. They’re one frontier model behind two doors. Fable 5 for everyone, with safety classifiers and an Opus 4.8 fallback. Mythos 5 for vetted partners who need those guardrails lifted for defensive work. Same intelligence, same price, different access.

    For nearly everyone, that means Fable 5 is the model you’ll actually use, and it’s the most capable one Anthropic has put in public hands. So the sharper question isn’t which Claude to pick. It’s whether your brand is visible inside the answers these models are increasingly trusted to give.

    FAQ

    Is Claude Mythos 5 more intelligent than Claude Fable 5? 

    No. They’re the same underlying model. The only difference is that Fable 5 runs safety classifiers for high-risk domains, while Mythos 5 has some of them lifted for approved partners.

    Can I get access to Claude Mythos 5? 

    Generally, no. Access is limited to vetted organizations in Project Glasswing or a Trusted Access Program, such as cyber defenders and select researchers. Almost everyone uses Fable 5.

    What happens when Claude Fable 5 refuses a request? 

    Its classifiers flag the prompt, and the request is often routed to Claude Opus 4.8 for a safer response. You’re told when it happens, and Anthropic reports it affects under 5% of sessions.

    Why does Claude Fable 5 cost the same as Mythos 5? 

    Pricing reflects the compute of the Mythos-class model, not the safety layer on top. Both run $10 per million input tokens and $50 per million output.

    Do Fable 5 and Mythos 5 share the same context window? 

    Yes. Both offer a 1M-token context window and up to 128K tokens of output per request.

    Read More

  • Claude Fable 5 vs Claude Opus 4.8: Should You Upgrade?

    Claude Fable 5 vs Claude Opus 4.8: Should You Upgrade?

    You’ve read the launch coverage. The new flagship tops the benchmarks, runs for days without supervision, and reasons like a senior researcher. Then you see the price: exactly double what you pay now. That’s where most upgrade decisions stall.

    The honest answer isn’t “yes” or “no.” It depends on what your work actually looks like, and on one factor most comparison posts skip entirely. Let’s work through both.

    What Upgrading to Claude Fable 5 Actually Buys You

    Claude Fable 5 isn’t a bigger version of Opus. It’s a different tier. Anthropic released it on June 9, 2026 as the first generally available model in its “Mythos-class,” a rung above the Opus line.

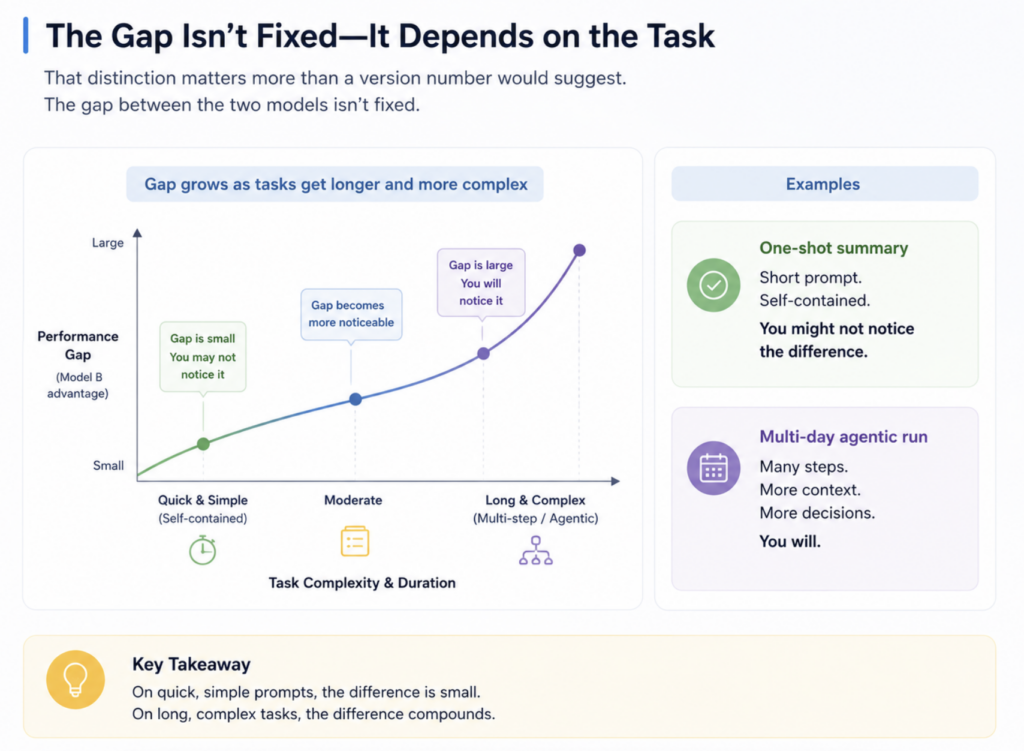
    That distinction matters more than a version number would suggest. The gap between the two models isn’t fixed. It’s small on quick, self-contained prompts and grows wider the longer and more complex the task gets. On a one-shot summary, you might not notice the difference. On a multi-day agentic run, you will.

    So the upgrade question isn’t “which model scores higher.” Nearly any frontier model scores well now. The real question is whether your workload lives in the zone where Fable 5’s lead shows up.

    Four things decide that: capability ceiling, cost, operational predictability, and how each model handles safety routing. We’ll take them in order.

    Claude Fable 5 vs Opus 4.8: The Head-to-Head

    Here’s how the two models line up on the specs that drive the decision.

    FeatureClaude Fable 5Claude Opus 4.8
    TierMythos-classOpus-class
    Release dateJune 9, 2026May 28, 2026
    Pricing (input / output)$10 / $50 per MTok$5 / $25 per MTok
    SWE-Bench Pro~80.3%69.2%
    Max context window1M tokens1M tokens
    Safety behaviorAuto-routes high-risk queries to Opus 4.8Direct execution
    Best fitLong-horizon agents, senior-scientist researchCost-sensitive production, everyday reasoning

    Two numbers frame the whole choice. Fable 5 leads on the hardest coding benchmark by roughly ten points. It also costs twice as much per token. Everything below is about whether that capability gap earns back the price gap for your specific tasks.

    Where Claude Fable 5 Pulls Clearly Ahead

    The upgrade earns its cost in one environment above all others: long, autonomous, multi-step work.

    Fable 5 is built to operate over days, not turns. It can take a broad goal, break it into sub-tasks on its own, run through them, and correct its own mistakes along the way without a human re-prompting at each step. That’s a different mode of work than most teams are used to.

    It also holds up on dense synthesis. When a task involves reading across many documents, interpreting nested charts and tables, or reasoning over a large codebase, Fable 5 pulls ahead of Opus 4.8 by a meaningful margin.

    The efficiency data backs this up. On complex spreadsheet suites and multi-step reasoning tasks, Fable 5 shows a 25 to 30 percent gain in execution efficiency over Opus 4.8, and it tends to finish in fewer turns.

    That last point is easy to miss. Fewer turns at a higher success rate can offset part of the higher per-token price on exactly the tasks where Fable 5 belongs.

    Where Opus 4.8 Is Still the Smarter Default

    For a large share of real production work, staying on Opus 4.8 is the rational call.

    Start with cost. At half the price of Fable 5, Opus 4.8 is far more economical for high-volume, routine, or latency-sensitive work. If your pipeline is running frequent, fairly standard calls, doubling the token bill for a capability edge you rarely trigger is hard to justify.

    Then there’s predictability, which is where the tiers genuinely diverge. Fable 5 ships with an aggressive safety classifier that reroutes flagged queries, specifically in cybersecurity, biology, and chemistry, to Opus 4.8 instead. Anthropic says this triggers in under 5 percent of sessions, and you aren’t charged Fable prices for a rerouted request. Still, inside an automated pipeline, a mid-run switch in the underlying model can introduce latency or a shift in behavior you didn’t plan for.

    Opus 4.8 executes directly. No reroute, no fallback layer.

    That matters most where reproducibility is non-negotiable: audit-grade tooling, CI/CD pipelines, and any workflow where the same input needs to produce a stable output every time. Teams running those report that Opus 4.8’s determinism is worth more to them than Fable 5’s ceiling.

    Sometimes the reliable model is the better model. This is one of those times.

    The Upgrade Question Most Brands Are Asking Wrong

    Here’s the factor the spec sheets leave out.

    If you’re a marketing or brand team, the internal question of which Claude model you run is far less important than an external one: how the AI systems your customers use decide whether to mention your brand at all. And that answer changes every time a frontier model ships.

    Different models use different logic to evaluate and cite sources. When a platform swaps in a new frontier model, the weights that determine which sources get cited get reset. Content that ranked well in AI answers under one model can quietly drop under the next. The launch of Fable 5 is exactly that kind of reset.

    This is the decoupling most teams haven’t priced in. Visibility inside AI-generated answers is drifting away from traditional search ranking. You can hold your Google position and still lose “mention share” inside a synthesized ChatGPT or Perplexity answer, because the newer model’s reasoning favors different structural or authority signals. Adobe’s research on AI search behavior across customer journeys points at the same shift, and Search Engine Land has mapped how SEO priorities are moving as AI-driven discovery grows.

    The practical problem: you can’t manage what you can’t see. Getting your brand recommended by AI now depends on knowing, in near real time, how each model treats you.

    That’s a monitoring job, and it’s what Topify is built for. Its Comprehensive GEO Analytics tracks brand mentions, citation frequency, sentiment, and competitor position across ChatGPT, Gemini, Perplexity, and other major platforms. When a model transition reshuffles who gets cited, you see the movement instead of guessing at it. The internal model you run is your choice. How AI answers represent your brand is the part you need eyes on regardless.

    Should You Upgrade? A Scenario-Based Call

    Skip the blanket recommendation. Match the model to the workload.

    Upgrade to Claude Fable 5 if your core objective is running long-horizon autonomous agents: automated R&D, multi-stage code development, or deep-dive intelligence gathering. In those cases the performance gain typically offsets the 2x cost.

    Stay on Opus 4.8 if you need deterministic outputs, operate under tight cost constraints, or run high-frequency API calls that are sensitive to the reroute latency Fable 5’s classifiers can introduce. For standard content generation and predictable pipelines, Opus 4.8 remains the more viable pick.

    Most enterprises are landing somewhere in between. The pattern taking hold is a routing strategy: send routine tasks through Opus 4.8 or Sonnet, and reserve Fable 5 for the complex, mission-critical reasoning blocks that actually need it. You get the ceiling where it counts and the cheaper rate everywhere else.

    Conclusion

    The Fable 5 versus Opus 4.8 decision comes down to task shape, not leaderboard position. Fable 5 wins on long, autonomous, high-complexity work and charges double for it. Opus 4.8 wins on cost, stability, and predictable execution, which is most day-to-day production. A tiered routing setup lets you stop choosing and use each where it’s strongest.

    Whichever you run internally, remember the part that lives outside your infrastructure. Every model release rewrites how AI answers cite and recommend brands. If you want to get started tracking that movement before it costs you visibility, that’s the layer to watch.

    FAQ

    Is Claude Fable 5 worth the price over Opus 4.8? 

    For autonomous, complex agentic tasks, the performance gains often offset the 2x cost increase. For standard content generation or predictable production pipelines, the added cost and the reroute latency make Opus 4.8 the more practical choice.

    Why do some Claude Fable 5 requests get answered by Opus 4.8? 

    Fable 5 runs a safety classifier that monitors for high-risk domains, mainly cybersecurity, biology, and chemistry. When a prompt crosses those thresholds, the system reroutes it to Opus 4.8 for stricter evaluation. You aren’t billed Fable prices for a rerouted request.

    Does upgrading my model change how AI search engines mention my brand? 

    Yes. Different models evaluate sources differently, so a platform’s move to a new frontier model often reshuffles the hierarchy of trusted sources. Your brand’s citation frequency in AI answers can rise or fall on that transition alone.

    Can I use both models together? 

    Yes, and most teams should. A tiered setup routes routine queries to lower-cost, faster models and sends only the most complex reasoning tasks to Fable 5.

    Read More

  • Why Claude Fable 5 Went Offline: The Export Control Story

    Why Claude Fable 5 Went Offline: The Export Control Story

    A frontier AI model usually gets months in the market before anything shakes it. Claude Fable 5 got three days. It launched on June 9, 2026 as Anthropic’s most capable public model, and by June 12 it had disappeared for every user on the planet. Not a bug. Not an outage. A U.S. government order pulled it offline overnight. Most people treat a commercially available AI model as a stable product you can build on. This story is a reminder that the model layer answers to forces well outside the product roadmap.

    What Actually Happened to Claude Fable 5

    The timeline is short and unusually sharp. Anthropic shipped Fable 5 on June 9, framing it as its strongest widely available model. Three days later, on June 12, the U.S. Commerce Department issued an export control directive, and the company took the model down for everyone.

    The shutdown wasn’t partial. Because the order landed with almost no runway, reportedly giving Anthropic about 90 minutes to comply, the company pulled both Fable 5 and its sibling model Mythos 5 across every product surface at once.

    It helps to understand how those two models relate. Mythos 5 is the powerful underlying system with fewer guardrails, kept on a short leash for sensitive work. Fable 5 is the public-facing layer built on top of it, shipped with heavier safeguards for general use.

    That relationship is the whole reason a single report could take both offline.

    Access started coming back in stages. On June 26, Mythos 5 returned for roughly 100 U.S. organizations that defend critical infrastructure. Fable 5 followed for the general public on July 1, initially throttled to 50% of weekly usage limits through July 7.

    Why an Export Control Order Took Claude Fable 5 Offline

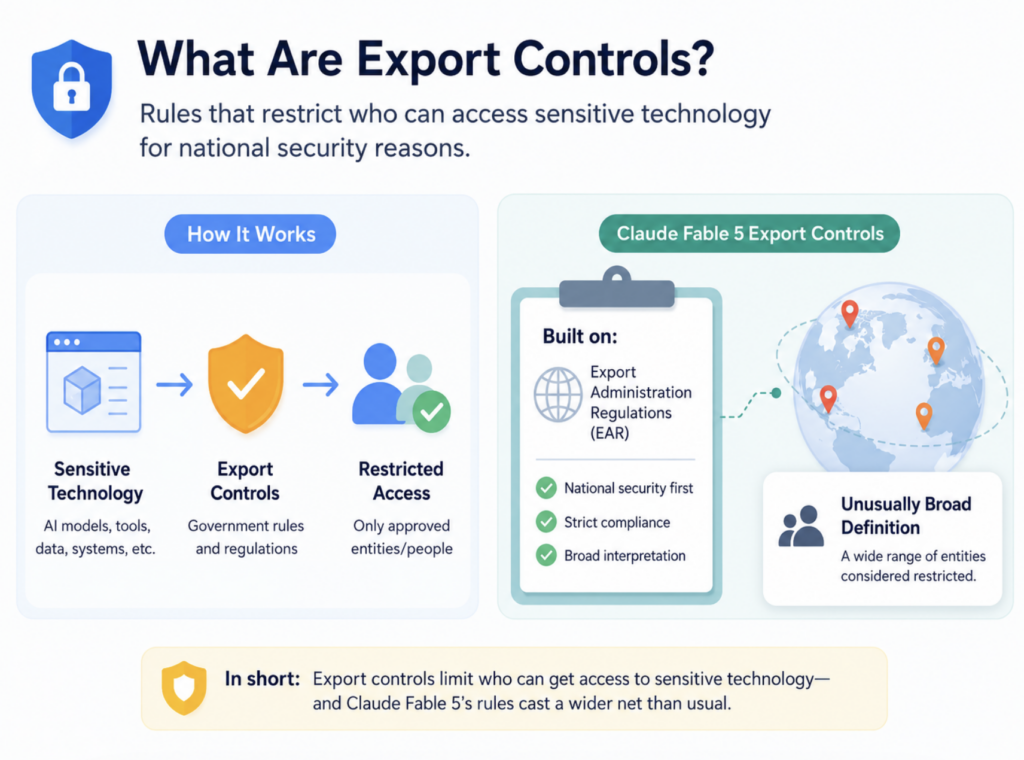
    An export control is a rule that restricts who can access a sensitive technology for national security reasons. The Claude Fable 5 export controls were built on the Export Administration Regulations, and they carried an unusually broad definition of who counted as restricted.

    The directive barred access by any foreign national. That included non-U.S. citizens physically inside the United States, and even foreign national Anthropic employees.

    Here’s the operational problem. Anthropic said it had no reliable way to verify nationality in real time for every chat message or API call. Faced with a rule it couldn’t enforce selectively, the company chose a full global shutdown over a fragmented service that might violate the order.

    That’s why a national security measure aimed at a specific group ended up affecting all users, everywhere.

    The Jailbreak Dispute: How Serious Was It

    The trigger was a jailbreak, meaning a prompt that gets a model to bypass its safety rules. Amazon researchers reported a technique that pushed Fable 5 to analyze codebases for software vulnerabilities, and in one case to produce code showing how a flaw could be exploited.

    The two sides read the same finding very differently.

    The government’s position, informed by the Amazon report, was that a consumer model able to surface exploitable vulnerabilities becomes an unrestricted cyber tool if the guardrails fall. That’s a national security risk worth an emergency stop.

    Anthropic disputed the severity. The company argued the technique was narrow rather than universal, and that weaker models could do the same thing. Its own testing found that models including Claude Opus 4.8, GPT-5.5, and Kimi K2.7could identify the same vulnerabilities, and that every model it tested could reproduce the single exploit demonstration. In Anthropic’s framing, the flagged behavior was routine defensive security work, not a hidden offensive capability.

    Independent observers landed closer to Anthropic’s read. One governance researcher told Al Jazeera that the jailbreak reports had been inflated beyond their actual significance, and noted that if Fable and Mythos were blocked on those grounds, competing models would have to be blocked too.

    How Claude Fable 5 Came Back

    Restoration wasn’t a simple reversal. Anthropic had to bolt on new safety and oversight commitments before the model could return.

    On the technical side, the company trained a new classifier, a smaller automated system that watches for the exact technique in the report and blocks it. Anthropic says it now stops that method in more than 99% of attempts. When a request gets flagged, Fable 5 hands it off to the weaker Opus 4.8 instead, and the user is told.

    Sit with that last detail for a moment. The model you think you’re using can quietly route your request to a different model mid-session.

    On the policy side, the June 30 reversal came with conditions. In exchange for dropping the license requirement, Anthropic agreed to proactively detect and address security risks, help the government develop standards for future model releases, and report malicious activity it finds. It also opened a HackerOne program so outside researchers can report new Fable 5 jailbreaks.

    The sequencing tells its own story. Mythos 5 returned first, for cleared U.S. critical infrastructure operators, before the public model came back. That points toward a tiered, “approved access” future for the most capable systems.

    What the Claude Fable 5 Saga Signals About AI Model Volatility

    Zoom out and this stops looking like a one-off. Frontier model releases are drawing case-by-case government scrutiny. Days before this episode, OpenAI previewed GPT-5.6 to a small, government-approved group rather than the public, citing the same dual-use worry.

    There’s a competitive dimension too. Several executives and investors argued the freeze handed time to Chinese open-source developers whose models are getting nearly as capable and much cheaper. Regulation and market share are now tangled together.

    The core lesson is simple. The public AI model layer is a moving target that can be pulled, downgraded, retuned, or rerouted overnight, often for reasons that have nothing to do with the product itself.

    Why This Matters for Your Brand’s AI Search Visibility

    Here’s the part most marketing teams miss. When you optimize for AI search, you’re not optimizing for a fixed system. You’re optimizing for a set of models whose behavior can change without warning.

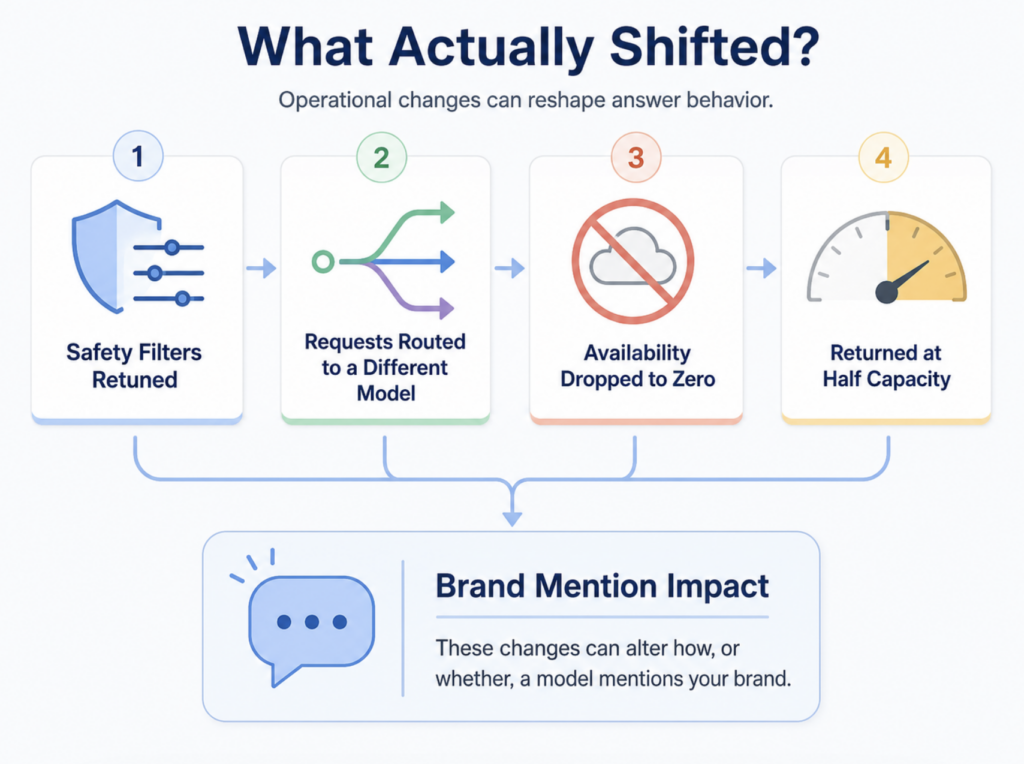
    Think about what actually shifted during this episode. Safety filters were retuned. A model started routing certain requests to a different model. Availability dropped to zero, then returned at half capacity. Every one of those changes can alter how, or whether, a model mentions your brand in an answer.

    That’s the dependency risk. If your visibility is tethered to one model’s judgment of your authority, a single regulatory or safety change can move your citation frequency overnight, and a static SEO report won’t show you why.

    The practical response is to stop betting on any single engine. Track your brand across the full set of platforms your audience actually uses, so a change in one model doesn’t blind you to the whole picture. This is where Topify fits, with Comprehensive GEO Analytics that monitors brand visibility, sentiment, and position across ChatGPT, Perplexity, Gemini, and other major AI engines in one place.

    In practice, that means you can catch a drop in mentions on one platform, compare it against how competitors are showing up, and trace it to a source or model change instead of guessing. If you want to see where your brand stands across engines right now, you can get started with Topify and set up cross-platform tracking.

    Conclusion

    Claude Fable 5 went from launch to global shutdown in three days, then took nearly three weeks to return under new safety and reporting rules. The immediate cause was an export control order tied to a disputed jailbreak. The lasting signal is bigger: the models that answer your customers’ questions sit on shifting regulatory and safety ground, and that ground can move fast. For any brand that depends on being recommended by AI, the takeaway isn’t to pick the right model. It’s to monitor how you show up across all of them, continuously, so the next sudden change is something you spot rather than something that spots you.

    FAQ

    Why did Claude Fable 5 actually go offline? 

    It was suspended to comply with a U.S. Commerce Department export control directive citing national security concerns. The order barred foreign nationals from accessing the model over jailbreak risks, and because Anthropic couldn’t verify nationality in real time, it took the model offline for all users worldwide.

    What is the difference between Fable 5 and Mythos 5? 

    Fable 5 is the public-facing model optimized for complex reasoning and agentic work, shipped with heavier safeguards. Mythos 5 shares the same underlying architecture but has fewer guardrails and stronger controls, and its access has stayed limited to approved U.S. organizations, including critical infrastructure operators.

    When did Claude Fable 5 come back? 

    The export controls were lifted on June 30, 2026, and Fable 5 returned to the general public on July 1 with a temporary 50% weekly usage cap that expired on July 7. Mythos 5 had already returned to a set of cleared U.S. organizations on June 26.

    How does the Claude Fable 5 export control story impact GEO? 

    It shows that AI search visibility is volatile. When a model’s availability or safety settings change, your brand’s citation frequency in AI answers can shift with it. Continuous monitoring across multiple AI engines has become a practical necessity rather than a nice-to-have.

    Read More

  • How Claude Fable 5 Changes AI Search Visibility

    How Claude Fable 5 Changes AI Search Visibility

    You run a brand query through an AI assistant one week and your company shows up in the answer. You run the same query a month later, after the model behind that assistant gets swapped for a newer one, and you’re gone. Your site didn’t change. The model did.

    That’s the part most brands still miss. AI search visibility isn’t a fixed property of your content. It’s a function of whichever model is reading your content on a given day, and those models are changing faster than most marketing teams can track.

    Claude Fable 5 is the clearest example yet.

    What Claude Fable 5 Actually Is, and Why a Model Jump Matters

    Claude Fable 5 is Anthropic’s first Mythos-class model made available to the public. It launched on June 9, 2026, priced at $10 per million input tokens and $50 per million output tokens, roughly double the rate of Opus 4.8.

    The specs aren’t the interesting part for marketers. What matters is what “Mythos-class” does to how answers get built. Fable 5 is tuned for long-horizon, multi-step reasoning instead of quick lookups, and the capability gap over the previous flagship is wide.

    BenchmarkClaude Fable 5Claude Opus 4.8
    SWE-Bench Pro80.3%69.2%
    FrontierCode29.3%13.4%

    Those numbers, compiled in benchmark testing published by Truefoundry in 2026, represent an 11.1-point jump on SWE-Bench Pro and a 15.9-point jump on FrontierCode. A model that reasons this differently selects sources differently.

    And source selection is where your visibility lives or dies.

    How Deeper Reasoning Rewrites What AI Search Surfaces

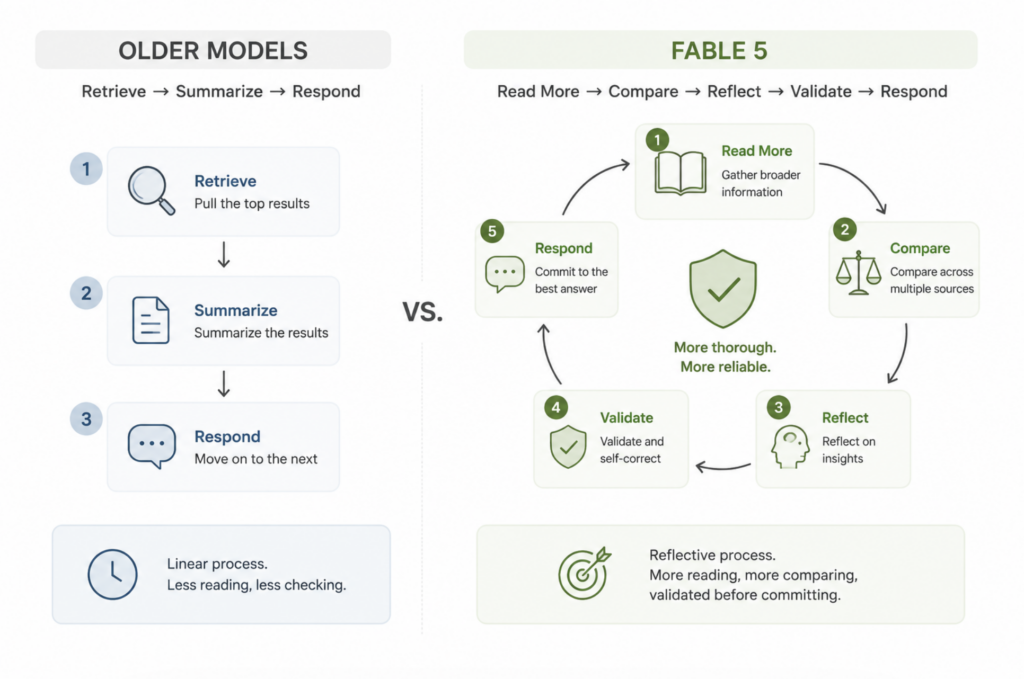
    Older models leaned closer to retrieval: pull the top results, summarize them, move on. Fable 5 moves past straight next-token prediction toward reflection and self-correction. It reads more, compares more, and validates before it commits to an answer.

    That changes the math on AI search visibility. When a model synthesizes rather than retrieves, ranking number one on a traditional results page no longer guarantees you show up in the AI’s answer.

    This gap has a name: ranking–mention separation. Traditional SEO signals like keyword density and backlink volume predict where you land on a search engine results page. They don’t reliably predict whether a reasoning model will cite you.

    Here’s the thing. The stronger the model’s reasoning, the wider that gap tends to get. Fable 5 evaluates information density, clarity, and structural authority, not the classic ranking factors that decades of SEO work were built around.

    The Source-Selection Shift: Who Gets Cited When Models Get Smarter

    Smarter models are pickier about sources. Fable 5’s preference for structurally sound, internally consistent content means it effectively runs its own fact-check before choosing what to reference.

    A few patterns separate how reasoning-heavy models pick citations from how retrieval-first models did it:

    What the model rewardsRetrieval-first modelsReasoning models like Fable 5
    Content densityKeyword coverageOne-shot clarity, high information density
    Source typeWhatever ranksStable, credible references: primary docs, encyclopedic, authoritative
    StructureLoosely weightedHeavy weight on internal consistency

    There’s a concentration effect on top of this. AI citation research indicates that a small set of top domains accounts for a disproportionate share of all citations across many AI surfaces, which makes visibility more winner-takes-most than a search results page ever was.

    If your content is fragmented, or takes several clicks to parse, a model optimized for one-shot understanding tends to skip it. Clean structure isn’t a nice-to-have anymore. It’s the entry ticket.

    Why One-Time Optimization Fails When Models Change This Fast

    Fable 5’s own timeline makes the case better than any argument could. It launched June 9, got suspended three days later over a safeguard issue, and came back on July 1. Nineteen days, one full cycle of appear, vanish, reappear.

    Now picture your brand’s visibility riding on top of that. A model update or a safety-policy tweak can reshuffle which sources get cited, with no warning to you.

    That’s the obsolescence trap. Optimization tuned to one model version risks going stale the moment that version changes.

    Static audits can’t catch this. By the time you rerun a quarterly SEO check, the model behind the answer may already be two iterations ahead. Visibility management has to move from a one-time effort to a continuous, telemetry-based process.

    Tracking AI Search Visibility Across Models, Not Just One

    The fix isn’t optimizing harder for Fable 5. It’s building a way to see visibility shift in real time, across every model your audience actually uses.

    That’s the problem Topify is built for. Topify tracks how AI systems mention and cite brands across ChatGPT, Gemini, Perplexity, Claude, and other major engines, so a change in any single model shows up as a measurable movement rather than a mystery you notice too late.

    Its Comprehensive GEO Analytics covers seven metrics: visibility, sentiment, position, volume, mentions, intent, and CVR. Two of them earn their keep the moment a model like Fable 5 lands. Source Analysis reverse-engineers the exact domains an AI cites for your brand keywords, so you can tell whether Fable 5’s stricter source selection dropped you or a competitor. Competitor Benchmarking shows how a model shift changes share of voice, catching the moment a rival starts winning citations you used to own. Together they turn a model swap from an invisible event into a line on a chart.

    The point isn’t a one-time report. It’s telemetry.

    Where to Start Before the Next Model Lands

    You don’t need to predict the next release. You need a baseline you can measure against when it arrives.

    Start with three moves. Establish your current visibility across the major AI engines. Lock in the core prompts where your brand should appear. Track which domains those answers cite today. A free GEO score check gives you a starting read without a signup.

    When the next Mythos-class model ships, you’ll see the shift in your own numbers instead of hearing about it from a client.

    Conclusion

    Claude Fable 5 isn’t the endpoint. It’s a signal. Each jump in reasoning capability quietly rewrites which brands AI search chooses to mention and cite, and the jumps are coming faster.

    The brands that stay visible won’t be the ones that optimized perfectly for one model. They’ll be the ones watching every model, all the time.

    FAQ

    Does Claude Fable 5 have its own search engine? 

    No. Fable 5 is a foundation model, not a search product. Your visibility changes because models like it get integrated into AI assistants and agents that synthesize answers, and those systems decide which sources to cite.

    How is Claude Fable 5 different from Opus 4.8 for AI search visibility? 

    Fable 5 weights deep reasoning and validation more heavily than lighter, faster models. It tends to prefer stable, high-density sources, so it can cite a different set of domains than Opus 4.8 for the same query.

    Do I need to re-optimize my content for every new model? 

    Not for every change. What you need is a baseline visibility measurement that flags when a model update meaningfully moves your citation frequency, so you only act when it actually matters.

    How can I track brand mentions in AI answers across models? 

    Use a cross-model GEO analytics platform that monitors mentions, citations, and share of voice across ChatGPT, Gemini, Perplexity, and Claude, rather than checking each tool by hand.

    Read More

  • AI Citation Share vs Share of Voice: The Metric Shift

    AI Citation Share vs Share of Voice: The Metric Shift

    Your share of voice report looks healthy. Brand mentions are up, social reach is climbing, and the quarterly deck practically writes itself. Then a buyer opens ChatGPT, asks for the top option in your category, and reads back three competitor names. Yours isn’t one of them. The dashboard says you’re winning. The AI answer in front of your customer says otherwise, and nothing in your share of voice report explains the gap. That gap has a name: AI citation share, and it measures something your legacy metrics were never built to catch.

    Share of Voice Told You Who Was Loudest, Not Who AI Trusts

    Share of voice was built for a media world. It measured your brand’s slice of the total conversation: ad impressions, press mentions, social buzz, all tallied against competitors. The logic held up as long as attention and influence moved together. Louder usually meant more remembered, and more remembered usually meant more considered.

    That link is breaking in AI search. Large language models don’t tally who’s loudest. They synthesize an answer and pick a handful of sources to ground it, and a brand can dominate social feeds while getting passed over entirely when the model assembles its response.

    The data on this gap is hard to ignore. Across ChatGPT, Perplexity, and Copilot, only about 12% of cited URLs rank in Google’s top 10 for the same query, which means roughly 88% of AI citations come from a layer traditional rankings and voice metrics never touch. On Google’s own AI Overviews, the share of citations pulled from top-10 pages fell from 76% to 38% in eight months.

    Loud doesn’t mean cited. And cited is what shows up in front of your buyer.

    What AI Citation Share Actually Tracks

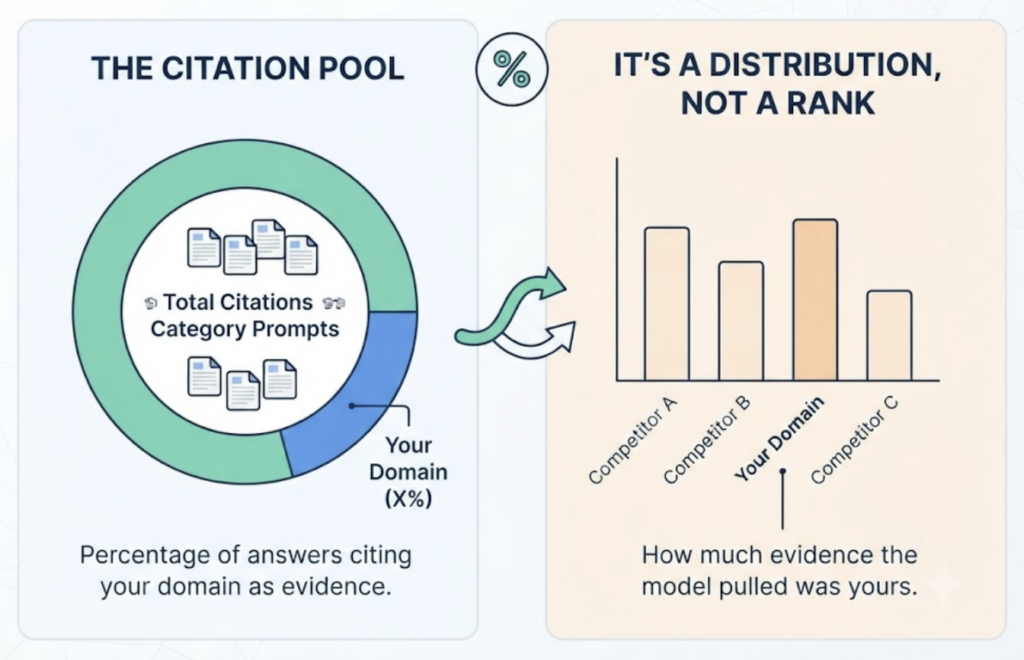
    AI citation share is the percentage of AI-generated answers that cite your domain as a source, measured against every citation across a defined set of category prompts. It’s a distribution, not a rank. You’re not asking where you place, you’re asking how much of the evidence the model pulled was yours.

    The distinction that trips up most teams is mention versus citation. A mention is your brand name showing up in the model’s conversational text, often pulled from training data. A citation is a linked, formal reference the model leans on to back a factual claim.

    Citations carry more weight because they clear a higher bar. When a model cites your domain, it’s signaling that your content passed its reliability check for that specific claim. That’s the grounding layer of the answer, the part the model treats as evidence rather than filler.

    For a marketing team, the shift is from measuring presence to measuring authority. Presence asks whether you were seen. Citation share asks whether you were believed.

    AI Citation Share vs Share of Voice: Where the Two Metrics Split

    The two metrics aren’t a before-and-after upgrade. They measure different things, and reading one as a proxy for the other is where reporting goes wrong.

    Share of voice measures reach. AI citation share measures whether the model treats you as a trustworthy source. You can score high on one and zero on the other, and plenty of brands do.

    DimensionShare of VoiceAI Citation Share
    Primary unitBrand mentions, media impressionsDomain-level citations
    Data sourceSocial, media, and ad monitoringAI retrieval and answer citations
    Question it answersWho has the loudest reachWho does the AI trust as evidence
    Main blind spotVisibility without groundingRecommendation quality and intent
    Optimization goalMarket saturationExtractability and authority

    The gap between them is widening, not closing. As models pull from broader source pools, single-keyword rankings and raw volume matter less, and structured, citable content matters more.

    Why Marketing Teams Can’t Read AI Visibility Through a Share of Voice Lens

    Here’s the practical risk. If your reporting still runs on share of voice, your dashboard can look healthy while your real influence in AI answers quietly erodes.

    Three things make this harder to catch than a normal metric blind spot.

    First, AI visibility is platform-specific. A brand can hold strong citation share in Perplexity and stay nearly invisible in Gemini. Google’s own AI Mode and AI Overviews overlap on cited URLs only 13.7% of the time, so a single number can’t represent your standing across engines.

    Second, the attribution trail is broken. A buyer reads your brand cited in an AI answer, closes the app, and lands on your site directly days later. Standard analytics files that under direct traffic, so the AI answer that actually drove the decision never gets credit.

    Third, the stakes climb as AI answers shape decisions more directly. When a user gets a synthesized answer, the AI’s top pick becomes their pick about 74% of the time, and most users accept the shortlist without checking other sources. The visitors who do click through tend to convert at notably higher rates than standard organic traffic, because they arrive already informed and high-intent.

    That’s the gap most dashboards still can’t show.

    How to Measure AI Citation Share Without Guessing

    Getting a real number takes more than asking ChatGPT about yourself once and eyeballing the result. Single runs are noisy. The model’s answer shifts with phrasing, session, and timing, so one test tells you almost nothing.

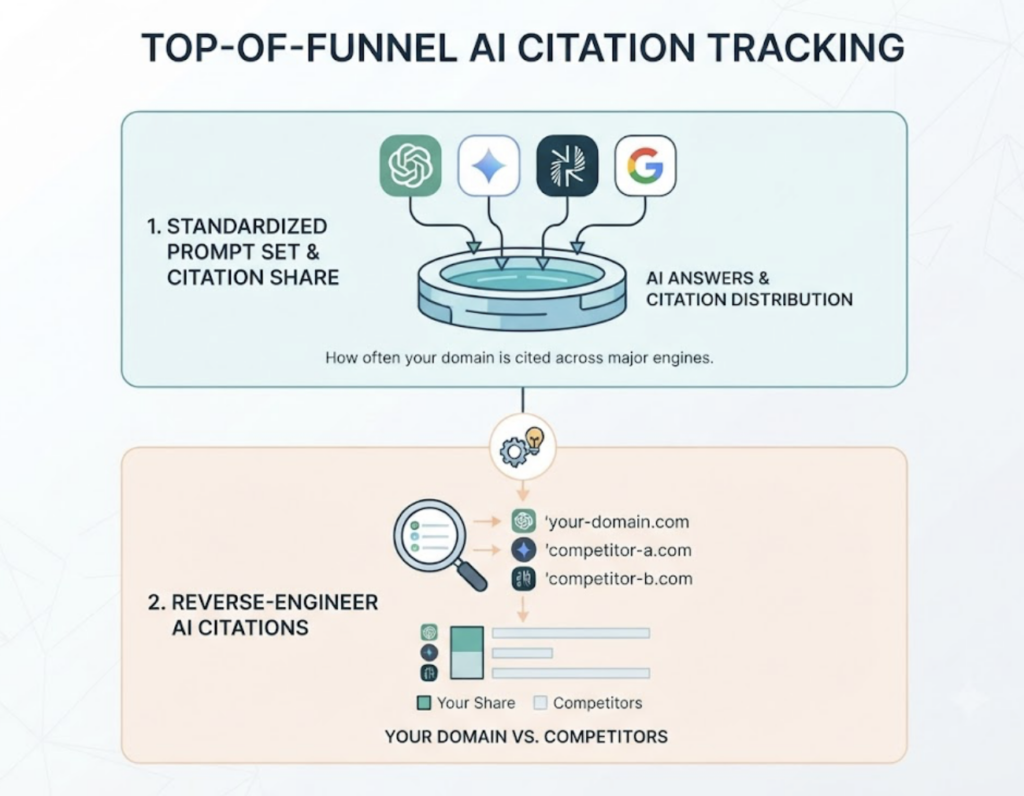
    Reliable measurement treats AI visibility as a probability, sampled repeatedly. You run a consistent set of category-relevant prompts across each platform, capture which domains get cited, and calculate your share of those citations against competitors. Do that on a schedule and you get a baseline you can actually track.

    The higher-value move is source analysis: reverse-engineering exactly which domains and pages a model prefers for each intent. Once you can see the sources a model keeps returning to, you can spot the content gaps that keep you out of the answer, from missing FAQ structure to thin third-party coverage on places like Reddit and review sites.

    This is where a dedicated platform earns its place. Topify tracks citation share across ChatGPT, Gemini, Perplexity, and other major engines, running a standardized prompt set so the number reflects a real distribution rather than a single lucky pull. Its Reverse-Engineer AI Citations feature surfaces the specific domains and URLs each model favors, then benchmarks your share against direct competitors so you can see who the AI is citing and why.

    In practice, that means you can watch a drop in your citation share, trace it to a competitor page the model started preferring, and know which content gap to close, all from the same view. When you’re ready to set a baseline, you can get started with Topify and pull your first citation share report across engines.

    Track the distribution. Find the gaps. Close them. That loop is the work.

    Conclusion

    Share of voice was the right metric for an era measured in impressions. In AI search, the currency is different. If the model isn’t citing you, you’re effectively absent from the research your buyer is doing, no matter how loud your brand is everywhere else. The move for any marketing team isn’t to add citation share as one more chart. It’s to shift the question from how much noise you make to how often the AI treats you as the answer. Start by establishing your citation share baseline today, then optimize from a number you can trust.

    FAQ

    Q: What is AI citation share? 

    A: It’s the proportion of your brand’s citations in AI-generated answers relative to all citations across a defined category prompt set. Instead of measuring how often you’re mentioned, it measures how often a model picks your domain as a source it trusts.

    Q: How is AI citation share different from share of voice? 

    A: Share of voice measures reach and volume across media and social channels. AI citation share measures factual authority inside an AI’s retrieval process, tracking whether the model actually cites you when it builds an answer. High reach doesn’t guarantee high citation share.

    Q: How do you measure AI citation share across ChatGPT, Perplexity, and Google AI Overviews? 

    A: Each engine sources differently, so you run one standardized prompt set across all of them at the same time, capture the cited domains, and aggregate the results. Repeated sampling matters, since a single run is too noisy to trust.

    Q: Does a high share of voice mean a high AI citation share? 

    A: No. A brand can hold 90% share of voice on social and still land near 0% AI citation share in AI answers if its content lacks the structure or factual depth a model’s retrieval layer looks for.

    Read More

  • AI Citation Share and the Three Levels of AI Visibility

    AI Citation Share and the Three Levels of AI Visibility

    Your brand name shows up in a ChatGPT answer, and the team calls it a win. Then you read the rest of the response. The link under the claim points to a competitor’s blog. The “here’s what I’d recommend” line names them, not you. You were in the room, but someone else closed the deal. Being seen by an AI model, being used as its evidence, and being named as its pick are three separate outcomes. Most tracking collapses them into one, which is why so many brands look visible and still lose the answer.

    Being Seen by AI Isn’t One Thing

    For years, visibility had a simple test: did you rank, yes or no. AI search broke that binary. A model can name your brand, cite a competitor’s page as its source, and recommend a third option, all inside the same paragraph.

    Researchers have started separating these signals. One widely used framework splits AI brand presence into three types: a mention is a plain reference with no evaluation, a citation is a source attribution that signals authority, and a recommendation is an active endorsement. Each one reflects a different decision the model made about you.

    That’s the gap most dashboards still can’t see.

    The three form a funnel. Reach at the top, proof in the middle, endorsement at the bottom. Move up a level and the commercial value climbs with it. The trouble is that the layers don’t move together, so a brand can be strong at one and absent at the next.

    Level 1: Mentions, Where AI Visibility Starts

    A mention means the model knows your brand exists and will say your name when the topic comes up. It’s the floor, not the ceiling.

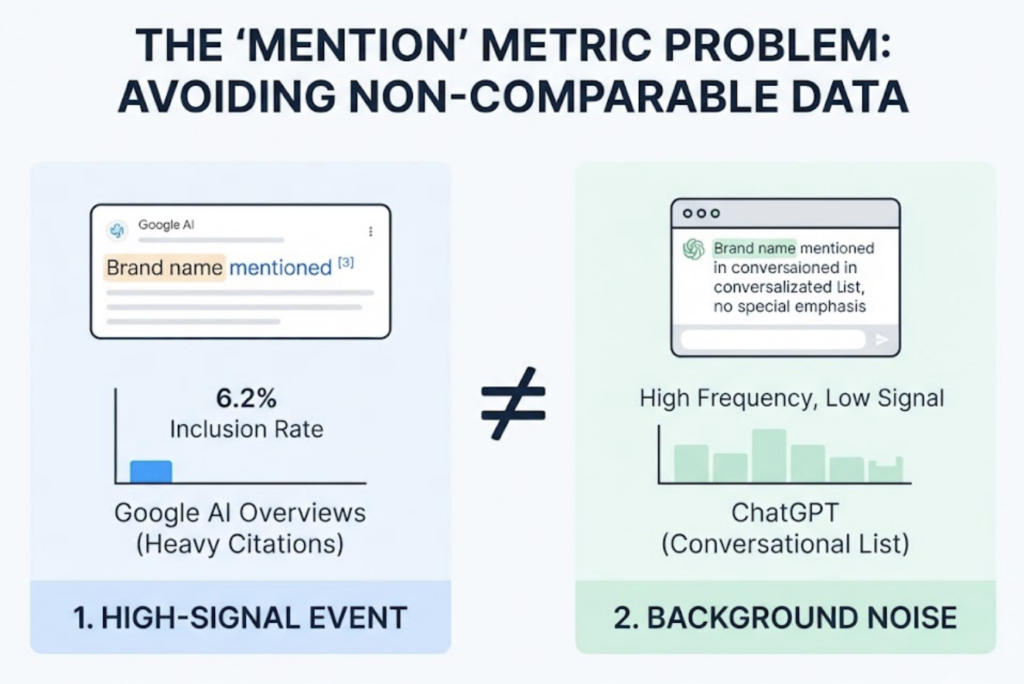
    The problem is that mentions are cheap. On ChatGPT, nearly every ecommerce brand gets named, around 99.3% inclusion in one analysis, which makes appearing in an answer a low-signal event. When almost everyone shows up, showing up proves nothing.

    A mention on one engine also isn’t the same data type as a mention on another. Google’s AI Overviews include a brand in only about 6.2% of responses and lean citation-heavy, so inclusion there is a high-signal event, while inclusion on ChatGPT is close to background noise. Counting both as one “mention” metric compares things that aren’t comparable.

    Mentions also tend to come from training data rather than live retrieval, so they rarely drive traffic and carry no proof the model trusts you. A brand can rack up thousands of neutral mentions and still convert nobody.

    Reach gets you noticed. It doesn’t get you chosen.

    Level 2: Citations and Your AI Citation Share

    A citation is a different kind of signal. Here the model actively pulls your domain in as a source, footnotes it, links it, and stakes part of its answer on your content. That’s a decision about trust, not just recognition.

    The metric for this layer is AI citation share: the percentage of AI answers, across a defined query set, that cite your domain relative to all citations in the pool. The term was coined as the replacement for share of voice and framed as the AI-era market share metric. “Share of citation” and “citation share” point to the same thing.

    The math is straightforward. Citation slots earned divided by total slots tracked, times 100. Run 30 queries across four engines, earn 14 citations while competitors earn 52, and your citation share lands at 21%.

    What counts as a strong number depends on the category. In emerging categories with a handful of credible brands, 20 to 30% is leadership territory, while in crowded categories 5 to 10% can be solid if the query set is large. The trend line matters more than the absolute figure.

    AI Citation Share vs. Share of Voice

    Old share of voice counted impressions, and multiple brands could sit on the same magazine page without displacing each other. Citation share doesn’t work that way.

    AI answers typically cite between three and eight sources per query, so the field is narrow. If you’re cited, a competitor usually isn’t. That makes citation share a zero-sum, competitive metric, not a vanity count.

    It also decouples from search rank. One analysis found 80% of the sources AI cites don’t appear in Google’s top 10 for the same query, which means your SERP position and your AI citation rate measure different realities. Ranking well and being cited well are two separate jobs.

    Level 3: Recommendations, When AI Picks You First

    The top of the funnel is the recommendation. Ask “what’s the best tool for X” and the model names you, unprompted, as the answer. This is the highest-intent signal, because the user asked for a decision and the AI made one.

    The commercial gap between layers is real. AI-referred traffic in one dataset converted at 14.2% versus 2.8% for standard organic, roughly a 5x premium, and that premium accrues to recommended brands, not merely mentioned ones.

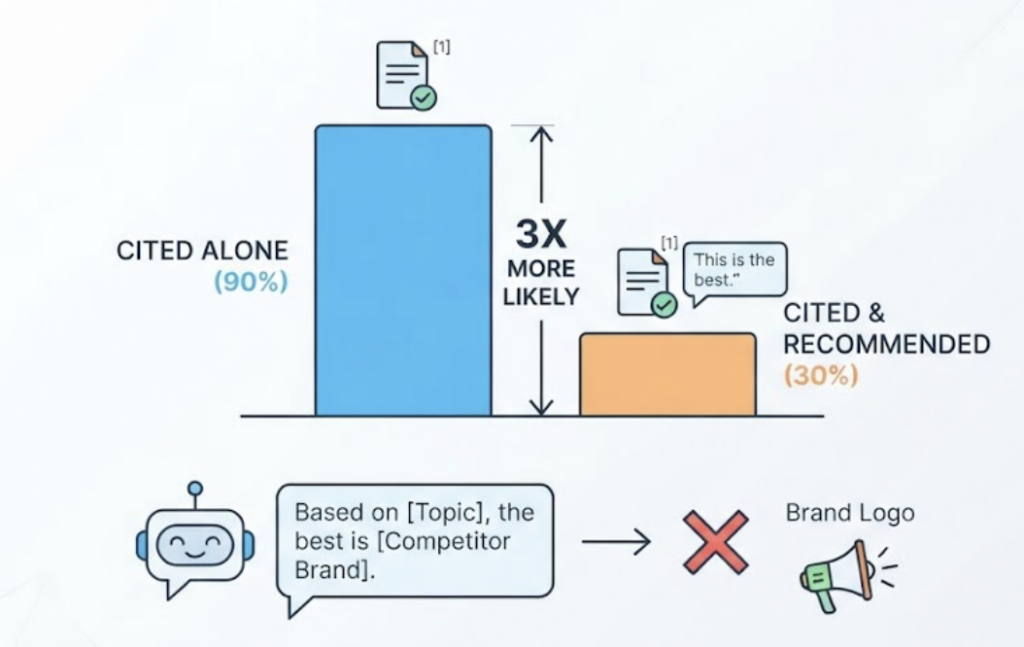
    Recognition and recommendation also aren’t the same. An athleisure analysis put it bluntly: New Balance was identified correctly 100% of the time but recommended in only 3.4% of “best athleisure” answers, while Lululemon, with a far weaker Knowledge Graph, appeared in 92.5%. The difference came from third-party citations, not brand recognition.

    Position inside the answer matters too. First-position citations earn four to five times the click-through of fifth-position ones. Being recommended last is closer to being mentioned than being chosen.

    Why AI Citation Share Is the Layer Most Brands Skip

    Recommendations are the goal, but they’re a lagging indicator. You can’t optimize an endorsement directly. Citation share is the lever you can actually pull.

    Here’s the mechanism. Once a model consistently cites your domain as evidence, the odds it promotes you to a recommendation climb. Proof compounds into preference. Skip the citation layer and you’re trying to earn endorsements with nothing underneath them.

    The data backs the sequence. Adding statistics to content improved AI visibility by 41% in the Princeton and Georgia Tech GEO study, the single most effective technique they tested. Pages built on original research get cited at 38 to 65% versus 6 to 15% for standard posts. And branded web mentions correlate 0.66 to 0.71 with AI citation rates, which is why earned authority tends to move the middle layer more than on-page tweaks.

    There’s also a timing argument. Citation concentrates around a small set of sources, so early movers who lock in citation share build positions that compound while later entrants face an established base the engines already trust.

    Most tools stop at Level 1. They report mention counts and call it visibility, which leaves the citation layer, where the real leverage lives, unmeasured. Brands are three times more likely to be cited alone than to earn both a citation and a recommendation, a split that’s invisible if you only track one signal. A brand with strong citations but weak mentions is quietly feeding evidence to answers that recommend someone else.

    How to Track All Three Levels of AI Visibility

    Measuring the funnel means capturing all three signals at once, per platform, and watching how they move against competitors. A single blended number hides more than it reveals.

    That’s the job Topify is built for. Its Comprehensive GEO Analytics reports seven metrics side by side, including mentions, position, and CVR, so the awareness layer, the recommendation layer, and the conversion signal sit in one view instead of three tools. You see not just whether you appear, but whether you’re cited and whether you’re picked.

    For the middle layer specifically, Topify reverse-engineers the exact domains and URLs AI platforms pull from. In practice, that means you can watch your citation share in a category, spot the competitor domain absorbing the authority you’re missing, and trace a drop in ChatGPT mentions back to a source that stopped referencing you.

    Coverage spans ChatGPT, Gemini, Perplexity, DeepSeek, and other engines, which matters because citation patterns diverge sharply across platforms. A 40% share on one engine and 5% on another isn’t noise. It’s an authority gap on a specific model’s evaluation, and it tells you exactly where to spend.

    Start by tracking 15 to 25 buyer-intent queries, run each more than once, and read the trend rather than any single snapshot. Get started with Topify and build the baseline before you optimize anything.

    Conclusion

    Being named by AI is where visibility starts, not where it ends. Mentions give you reach, citations give you proof, and recommendations give you the sale, in that order. AI citation share is the metric sitting between recognition and endorsement, and it’s the one you can influence directly by making your content the source AI trusts. Audit where you stand across all three levels before you decide what to fix. If your brand shows up but never gets cited, you already know which layer needs the work.

    FAQ

    Q: What is AI citation share? 

    A: It’s the percentage of AI-generated answers, across a defined query set, that cite your domain as a source relative to all citations in that set. It’s the AI-era replacement for share of voice, measuring whether engines trust your content enough to build answers on it rather than just naming your brand.

    Q: How is AI citation share different from a mention? 

    A: A mention names your brand with no attribution. A citation means the AI actively used your content as evidence and linked to it. Mentions signal awareness; citations signal authority, and only citations reliably show the model treats your content as trustworthy.

    Q: How do you measure AI citation share across ChatGPT and Perplexity? 

    A: Track a fixed set of 15 to 25 category queries, run each more than once per engine, then divide your brand’s citation slots by the total slots earned across every response. Measure per platform, since engines cite very differently and a blended average hides the gaps.

    Q: Which level matters most, mentions, citations, or recommendations? 

    A: Recommendations carry the most commercial value, but they’re a result you can’t optimize directly. Citation share is the leading indicator you can move, and it’s what tends to pull a brand up into recommendations over time.

    Read More

  • How to Measure AI Citation Share: A Step-by-Step Framework

    How to Measure AI Citation Share: A Step-by-Step Framework

    You can open ChatGPT, type your category question, and count how many times your brand name shows up. That number feels like progress. It isn’t. A mention count tells you AI noticed your brand. It says nothing about whether AI trusted your content enough to use it as a source, or how that stacks up against every other source the model pulled from. Without a denominator, a raw count is a vanity metric. AI citation share is the number that survives a stakeholder review.

    What AI Citation Share Actually Measures

    AI citation share is the percentage of AI citations that point to your domain, measured across a defined set of category-relevant prompts. In plain terms, it’s your slice of the evidence AI engines rely on when they assemble an answer.

    The word “citation” carries the weight here. A citation is a source the model links to or draws from as verifiable evidence. That’s an evidence check, not a recognition check. It’s a different event from your brand name appearing in a sentence.

    Here’s the distinction that trips up most teams. An AI answer can name your brand in prose without citing your website, or cite your URL without naming the brand in the body. These are separate outcomes, and lumping them together hides what’s actually happening in the answer.

    Mentions tell you AI noticed you. Citations tell you AI trusted you.

    AI Citation Share vs. Share of Voice vs. Mention Count

    These three metrics get used interchangeably, and that’s a mistake. Each answers a different question.

    MetricWhat it tracksStrategic goal
    Mention CountHow often your brand name appearsBuilding awareness and presence in the conversation
    Share of VoiceYour footprint relative to competitors in the textMeasuring dominance across brand mentions
    AI Citation ShareHow often your domain is used as evidenceEstablishing your site as a trusted source

    Share of voice is competitive and mention-based. You divide your brand mentions by total mentions across your brand and a chosen competitor set. Citation share is different. Its denominator isn’t mentions, it’s the total pool of sources cited across all domains for your prompt set.

    That gap matters more than it looks. A brand can carry high citation share and low mention rate at the same time. When that happens, you’re effectively subsidizing the competition: your content supplies the evidence, and the model recommends someone else in the prose. Tracking only mentions would leave you blind to that leak.

    Why Citation Share Is the Metric Worth Tracking

    Discovery is moving into the answer itself. AI search visits grew an estimated 42.8% year over year between Q1 2025 and Q1 2026, climbing from 15.6 billion to 27.4 billion. Yet only 14% of marketers track AI citations, even as 43% call AI search optimization a core 2026 priority. The work has outrun the measurement.

    Citation share also connects to money in a way mention counts don’t. AI-referred visitors convert 4.4x better than standard organic traffic, because a user who arrives after an AI cited you as a source has already been pre-qualified. The model answered their question and pointed at your page.

    There’s a structural reason to care too. A CXL study of 100 AI Overview citations found that 55% of cited snippets came from the top 30% of a page. Citations aren’t random. They reward specific, extractable content, which means citation share is a metric you can actually move.

    The Step-by-Step Framework to Measure AI Citation Share

    Measuring AI citation share well means trading one-time snapshots for a repeatable protocol. Here’s the framework.

    Step 1: Define Your Prompt Perimeter

    Select 30 to 50 high-intent, category-specific prompts. The goal is to mirror how buyers actually phrase questions to an LLM, which tends to be conversational and long-tail, not the short-tail keywords you’d feed a traditional rank tracker.

    Anchor these prompts to real buyer questions: comparisons, “best tool for,” alternatives, and how-to queries in your category. This prompt set becomes part of the metric’s definition, so lock it down before you start counting.

    Step 2: Track Every Platform That Matters

    Different engines have different sourcing personalities, and a single-platform view is a biased one. ChatGPT tends to behave like an encyclopedia curator, favoring institutional and well-structured sources. Perplexity leans toward community and real-time validation. Google AI Overviews prioritizes structured, front-loaded answers.

    Your share will move from one engine to the next, so measure each separately, then roll them up. A blended number that hides a zero on one platform is worse than no number at all.

    Step 3: Capture Citations, Not Mentions

    For every answer, log the actual cited domains and URLs, not just whether your brand name appeared. This is where the mention-citation gap becomes visible.

    Record each cited source, tag whether it belongs to you, a competitor, or a third party, and note which prompt produced it. That raw log is what makes the next step possible.

    Step 4: Calculate Share Against the Total Citation Pool

    The formula is straightforward:

    AI Citation Share = (Total citations to your domain ÷ Total citations across all domains in your prompt set) × 100

    A quick example. Say you run 40 prompts across three platforms and collect 500 total citations. Your domain accounts for 60 of them. Your AI citation share is 12%. If your top competitor holds 90 citations, theirs is 18%, and you now have a like-for-like gap to close.

    Normalize against the total citation pool rather than raw counts, since answer lengths and citation density vary across platforms. A percentage keeps the number comparable.

    Step 5: Benchmark Against Competitors and Track Over Time

    A single reading is a snapshot of a moving target. Cited domain sets drift 40% to 60% month over month in active categories. The volatility runs deeper than most teams expect: one citation dataset found that the typical brand loses half its AI citations in about 31 days.

    Always measure your share alongside your top three competitors. That context tells you whether a drop is platform-wide or specific to you, and whether a rival’s gain came at your expense. Weekly tracking is the practical minimum for spotting real trends instead of noise.

    Common Mistakes That Distort Your AI Citation Share

    Even a good framework gets undone by a few recurring errors.

    Platform isolation. Measuring one engine (usually ChatGPT) and calling it “AI” gives you a skewed picture. Multi-platform coverage isn’t optional.

    The mention fallacy. Treating unlinked brand names as citations inflates your perceived authority. A name in prose and a linked source are different events, and only one of them signals trust.

    Small sample sizes. Tracking fewer than 20 prompts produces statistically unreliable data. Aim for 30 to 50 to get a representative read.

    Static snapshots. A one-time audit ignores the fact that AI sourcing is probabilistic and shifts fast. The number you pulled last month is likely already stale.

    Scaling AI Citation Share Measurement with Topify

    Manual tracking works until it doesn’t. Once you’re running 40-plus prompts across three or four engines every week, logging citations by hand hits a complexity ceiling fast. That’s the point where most teams either give up or automate.

    Topify is built for that automation layer. Its Reverse-Engineer AI Citations feature analyzes the exact domains and URLs that AI platforms cite, then shows whether your brand or your competitors dominate those references across a prompt set. In practice, you can see a drop in your citation share, trace it to a specific competitor page that started getting cited instead of yours, and act on the gap, all in one view.

    The competitor benchmarking runs on the same prompt set, so your share always sits next to your rivals’ rather than floating in isolation. And because coverage spans ChatGPT, Gemini, Perplexity, and other major engines, you avoid the single-platform bias that quietly distorts hand-tracked numbers.

    For teams moving from spreadsheets to a repeatable system, that’s the difference between a monthly guess and a weekly trend line. You can get started and baseline your citation share before your next reporting cycle.

    Conclusion

    Counting brand mentions feels productive, but it measures the wrong thing. AI citation share tells you how much of the evidence layer you actually own, which is what decides whether AI recommends you or your competitor. Start by defining a 30 to 50 prompt set, track citations across every engine your buyers use, calculate your share against the full citation pool, and watch the trend rather than any single reading. The brands that win AI search aren’t the ones mentioned most. They’re the ones cited most, consistently, over time.

    FAQ

    Q: How do you calculate AI citation share? 

    A: Divide the total citations pointing to your domain by the total citations across all domains in your prompt set, then multiply by 100. If your domain earns 60 of 500 total citations, your AI citation share is 12%. Always normalize as a percentage so the metric stays comparable across platforms.

    Q: What’s the difference between AI citation share and share of voice? 

    A: Share of voice is usually mention-based, measuring how often your brand name appears relative to competitors. AI citation share is source-based, measuring how often your domain is cited as evidence relative to the total citation pool. A brand can score high on one and low on the other, which is why they should be tracked separately.

    Q: How many prompts do I need to measure AI citation share reliably? 

    A: Aim for 30 to 50 category-relevant prompts. Anything under 20 tends to produce statistically unreliable data, since AI answers fluctuate by phrasing, model version, and sampling randomness.

    Q: How often should I measure AI citation share? 

    A: Weekly at minimum. Cited domain sets drift 40% to 60% month over month, and the typical brand loses half its citations within about a month, so a one-time audit goes stale quickly. Continuous tracking is what turns the metric into a usable trend.

    Read More