Category: Comparisons

  • AI Crawler Robots.txt: Control Search, Training, and Answer Visibility Separately

    AI Crawler Robots.txt: Control Search, Training, and Answer Visibility Separately

    A security team blocks every bot with “AI” in its name and closes the ticket. Weeks later, marketing discovers that product pages no longer appear in conversational search, while ordinary search remains unchanged. The policy succeeded at reducing access, but it failed to distinguish model training from search discovery and user-requested retrieval.

    An AI crawler robots.txt policy needs more than a copied list of user agents. Providers increasingly separate search indexing, potential model training, and real-time user access into different bots or product tokens. Blocking one may preserve another, and a crawl block may not remove a URL that the system learned about elsewhere. The correct policy maps each access path to a business decision before any directive is deployed.

    Robots.txt Controls Crawling, Not Every Form of Discovery

    A robots.txt file tells compliant crawlers which URLs they may request. It is a crawl-management mechanism, not a universal privacy or removal system.

    Google’s robots.txt guidance warns that a disallowed page can still be indexed as a URL when other pages link to it. Because the crawler cannot read a blocked page, it also cannot see a noindex meta tag inside that page. OpenAI similarly notes that a blocked page may still be surfaced as a title and link when its URL is obtained from another provider or another page; its publisher guidance recommends noindex when the goal is to prevent that result.

    Private or sensitive content should therefore rely on authentication and access control, not a voluntary crawler file. Robots rules communicate preferences to identified bots. They do not make public content confidential.

    Separate four objectives before editing the file:

    1. Ordinary search crawling and indexing.
    2. Search or answer retrieval by an AI service.
    3. User-initiated fetching during a live request.
    4. Collection for potential model training.

    One global Disallow: / cannot express those distinctions.

    Provider Bot Names Map to Different Product Uses

    The current bot structure varies by provider. Use official documentation and review it regularly because names and affected products can change.

    Provider token or controlDocumented primary useWhat blocking can affectImportant boundary
    GooglebotGoogle Search crawlingSearch indexing and eligibilityRobots blocking is not a reliable removal method
    Google-ExtendedTraining future Gemini models and grounding in selected Gemini or Vertex experiencesNon-Search AI use covered by the tokenGoogle states it does not affect Google Search
    OAI-SearchBotDiscovery and inclusion in ChatGPT search summaries and snippetsChatGPT search visibility and citationPlacement is never guaranteed
    GPTBotCollection that may contribute to model trainingPotential future training useOpenAI documents it separately from search discovery
    ChatGPT user accessRetrieval triggered by a user’s requestAbility to access a page during the taskOperational behavior differs from search indexing
    Claude-SearchBotSearch indexing and search-result qualityClaude search visibility and accuracySeparate from model-training collection
    ClaudeBotCollection that may contribute to model developmentPotential future training useSeparate from user-requested access
    Claude-UserRetrieval at a user’s directionLive access to site content in a Claude taskBlocking may reduce user-directed visibility
    Bing NOCACHE or NOARCHIVEPage-level control for Bing Chat and related useHow content is included or linked in answersImplemented as meta controls, not a separate AI crawler

    The table is a policy map, not a promise about every product surface. Always check the current provider page before deployment.
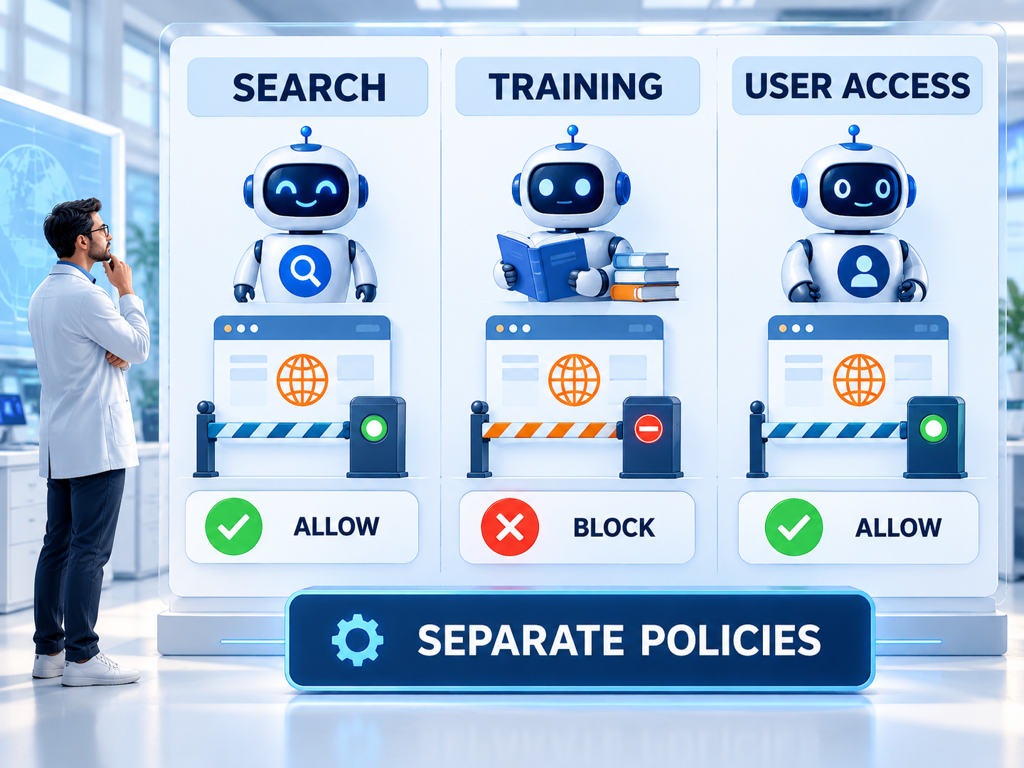
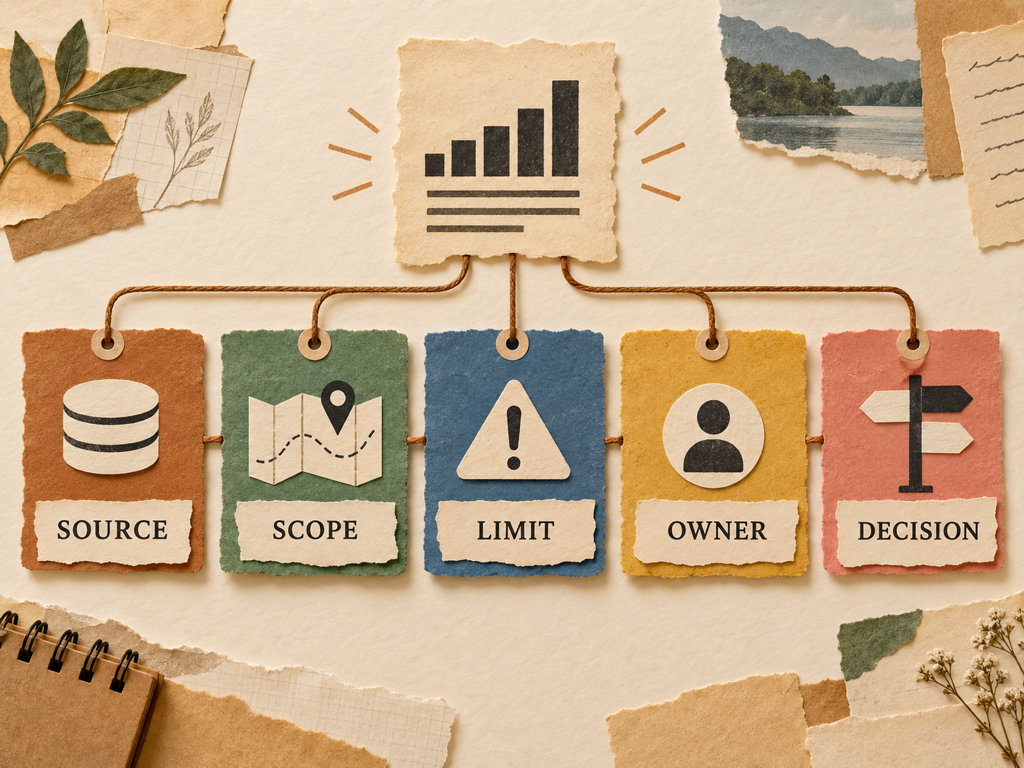
    Matrix connecting search, training, and user-requested AI bots to separate website decisions

    Googlebot and Google-Extended Solve Different Problems

    Googlebot is the crawler used for Google Search. Blocking it can prevent Google from reading page content and can damage ordinary Search visibility, including eligibility for generative features that rely on the Search index.

    Google-Extended is a product token in robots.txt. According to Google’s crawler documentation, it controls whether content crawled by Google may be used for training future Gemini models and for grounding in Gemini Apps and Grounding with Google Search on Vertex AI. It does not affect Google Search and is not used as a Search ranking signal.

    Google-Extended has no separate HTTP user-agent string. Existing Google crawlers fetch the content, while the token communicates a usage preference. A log-monitoring rule that expects a Google-Extended request header will therefore miss the documented mechanism.

    Google’s AI Overviews and AI Mode belong to Google Search. Site participation in those features is controlled through Search eligibility, preview directives, and Google’s generative AI Search setting, not through Google-Extended alone.

    OpenAI Separates Search Discovery From Potential Training

    OpenAI advises publishers to allow OAI-SearchBot when they want pages included in summaries and snippets in ChatGPT search. Its publisher and developer FAQ treats that bot separately from GPTBot, which publishers can disallow for pages they want excluded from potential training.

    This separation supports a common policy: allow search discovery while declining training collection. The exact robots file should still be reviewed by engineering and legal teams because path rules, wildcards, subdomains, and CDN behavior can change the outcome.

    OpenAI also describes user-driven access separately. A live ChatGPT request may cause a page fetch that is operationally different from building a search index. Decide whether your public documentation, support pages, or tools should remain accessible for those user-directed tasks.

    Allowing a crawler creates eligibility, not guaranteed visibility. OpenAI states that ChatGPT search placement depends on multiple factors intended to surface relevant and reliable information.

    Anthropic Uses Separate Training, Search, and User Bots

    Anthropic documents three robots: ClaudeBot, Claude-SearchBot, and Claude-User. Its crawler guidance maps them to model development, search quality, and user-requested access respectively.

    Blocking ClaudeBot signals that future site material should be excluded from training datasets. Blocking Claude-SearchBot can reduce visibility and accuracy in Claude search results. Blocking Claude-User prevents retrieval when a person asks Claude to access the site.

    The structure makes the policy choice explicit. A company can reject training collection while preserving search and user-requested access, or apply different rules to public marketing content and licensed archives.

    Anthropic states that its bots honor robots.txt and supports the non-standard Crawl-delay extension. Do not assume every provider interprets non-standard directives the same way.

    Bing Uses Page Controls Alongside Bingbot

    Microsoft’s approach includes existing search crawling plus page-level controls. Bing documented NOCACHE and NOARCHIVE behaviors for Bing Chat in 2023.

    Microsoft said pages without either control could be included in answers and potentially used in training. NOCACHE could allow a URL, title, and snippet to appear while limiting broader use. NOARCHIVE could prevent inclusion and linking in Bing Chat. When both were present, Microsoft said it would treat the page as NOCACHE.

    These behaviors are not interchangeable with blocking Bingbot. A crawler block can affect ordinary Bing discovery, while page meta directives communicate a more specific serving preference. Because the documentation predates later Copilot and AI Performance products, verify current behavior before implementing a new policy.

    Build Policies by Content Class, Not by Entire Domain

    Public documentation, product pages, subscriber articles, user profiles, licensed data, and internal portals should not inherit one undifferentiated AI policy.

    Create a content inventory with five fields: content class, access status, desired search visibility, desired answer visibility, and training preference. Then map each class to provider-specific controls.

    A typical policy might allow search and user-requested access to public documentation, disallow training collection for licensed reports, prevent all automated access to account pages, and leave ordinary search enabled for product pages. The exact choice depends on contracts, privacy obligations, infrastructure, and growth goals.

    Keep sensitive systems behind authentication. Do not publish them and expect robots.txt to supply security.

    Test the Effective File and the Resulting Visibility

    The policy is not complete when the text file is committed. Confirm that robots.txt is publicly reachable at each relevant host and subdomain, returns the expected status, and contains no CMS or CDN override.

    Test representative allowed and blocked paths. Inspect server logs for documented HTTP user agents where available, but remember that product tokens such as Google-Extended may not produce a separate request identity.

    Then measure outcomes. Search consoles can reveal changes in crawling, indexing, generative impressions, or citations. Answer-level checks can reveal whether pages and brands still appear for relevant prompts. Topify can support a fixed prompt sample across AI systems, allowing teams to compare visibility and cited sources before and after policy changes.

    The comparison should be directional. Different platforms refresh on different schedules, and a crawler-policy change may take time to affect discovery.
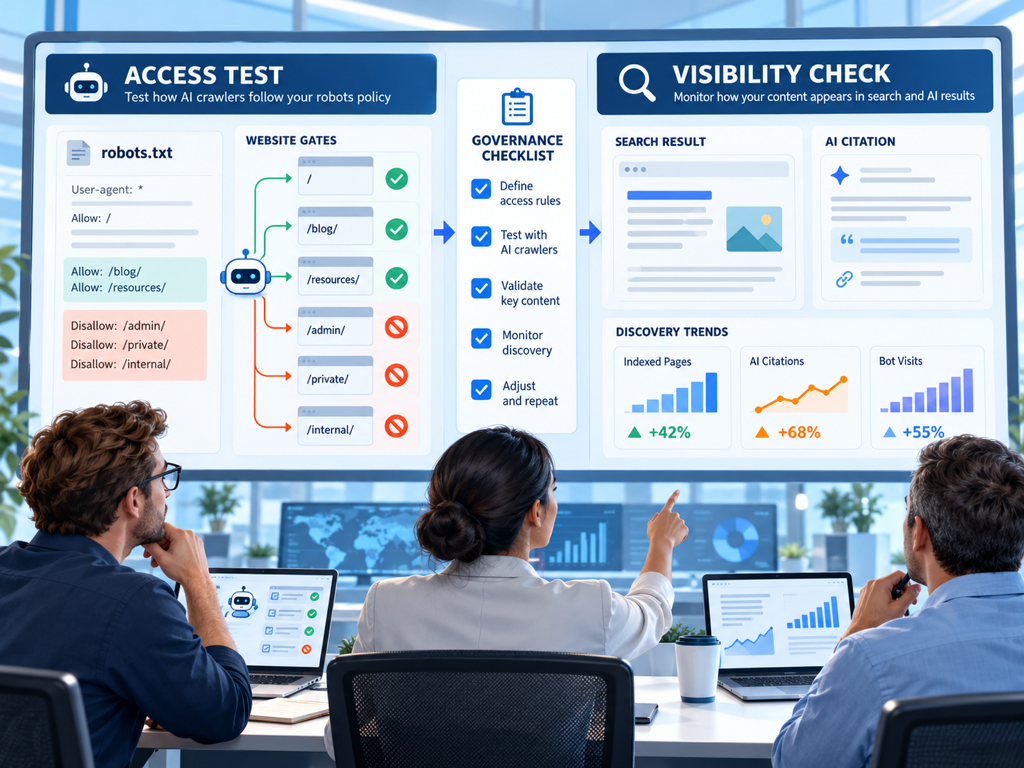
    Governance team testing a robots policy while monitoring search discovery and AI answer visibility

    Maintain an AI Access Registry Instead of a Static List

    Bot names, product boundaries, and control semantics evolve. A robots file copied from a one-year-old checklist can be technically valid and strategically wrong.

    Maintain a registry containing the provider, token, documented purpose, allowed paths, blocked paths, owner, approval date, documentation URL, test method, and next review date. Review it quarterly and whenever a provider announces a new search, shopping, agent, or training product.

    Version the policy and retain the previous file. A rollback is easier when the team knows which rule changed and what metric should recover.

    Finally, coordinate SEO, security, legal, infrastructure, and content owners. Robots policy is no longer only a crawl-budget task. It controls whether public evidence can participate in search, generated answers, user-directed tasks, and future models.

    Conclusion

    An AI crawler robots.txt policy works only when it separates search, answer retrieval, user-directed access, and potential training. Google, OpenAI, Anthropic, and Microsoft expose different tokens and page controls for these purposes. A single block can remove useful discovery while leaving the original governance concern unresolved.

    Start with content classes and desired outcomes. Map each provider’s current documentation to those decisions, implement the narrowest rule, and test both technical access and visibility. Keep private material behind authentication, keep a versioned registry, and review the policy as products change. The goal is not to allow or block “AI” as one category. It is to decide which systems may use which public content for which purpose.

    FAQ

    Does robots.txt keep a page private?

    No. Robots.txt communicates crawl preferences to compliant bots. Use authentication or other access controls for private content.

    Can I allow ChatGPT search but block OpenAI training?

    OpenAI documents OAI-SearchBot for search discovery and GPTBot for potential training separately, allowing publishers to express different preferences.

    Does blocking Google-Extended block AI Overviews?

    No. Google states that Google-Extended does not affect Google Search. AI Overviews and AI Mode depend on Search eligibility and Google’s generative Search controls.

    Why can a blocked URL still appear as a link?

    Systems may discover the URL through other pages or providers even when they cannot crawl its content. Use the provider’s supported indexing or removal control when link removal is the actual goal.
    Read More

  • GSC AI Report vs AI Visibility Trackers: What Each Can Prove

    GSC AI Report vs AI Visibility Trackers: What Each Can Prove

    Two dashboards show a rising AI line, but they are not measuring the same event. Google Search Console counts qualifying link impressions inside supported Google generative experiences. An AI visibility tracker observes generated answers for a defined prompt set and records whether a brand, competitor, or source appears. Calling both numbers “AI visibility” hides the difference that matters most.

    The right comparison is not which tool wins. It is which claim the data can support. A first-party impression report is strongest for Google exposure. A controlled answer monitor is strongest for prompt-level recommendations, citations, and cross-platform competition. Teams need a measurement contract before combining them.

    The Two Tools Observe Different Parts of the Journey

    Google’s Generative AI performance report records impressions when links to a verified property appear in supported generative AI features on Google Search. Google currently names AI Overviews and AI Mode, with views by page, country, device, date, and text-based or multimodal search type.

    An AI visibility tracker takes a different approach. It runs or observes a defined set of prompts across selected AI platforms, then structures the responses. Depending on the system, the output may include brand mentions, recommendation inclusion, ordered position, sentiment, citations, competitors, and changes over time.

    One is first-party platform reporting. The other is controlled observational measurement.

    That distinction should remain visible in every dashboard, calculation, and executive summary.

    Compare Capabilities Without Pretending the Metrics Match

    The table below describes the typical division of labor. Specific tracker features and platform coverage must be verified with the vendor.

    Measurement questionGSC generative AI reportAI visibility tracker
    Did links to my site appear in supported Google AI experiences?First-party impression dataMay observe citations, but not Google’s internal impression total
    Which pages received Google AI impressions?Page dimension, generally canonicalizedOnly pages visible in sampled answers
    Which prompt caused the exposure?No standard query table in the current reportExact tracked prompt is known
    Was my brand explicitly recommended?Not established by an impressionCan be coded from the answer
    Which competitors appeared?Not a report dimensionCan be recorded for the same prompt set
    Which sources were cited?Page exposure for your property, not a full citation mapCan capture visible cited URLs and domains
    What happened in ChatGPT or Perplexity?Out of scopeCan observe supported external platforms
    How much total market demand exists?Not market-wide demandPrompt-set observations are not total demand either
    Can the tool reveal an internal ranking signal?Google reports its own output, not an optimization formulaNo external tracker has Google’s internal AI or ranking metrics

    Google explicitly warns in its AI optimization guidance that third parties do not have access to Google’s internal ranking or AI systems. A tracker should describe what it observes, not imply privileged access.

    GSC Is Strongest for First-Party Google Exposure

    Use Search Console when the primary question concerns a verified site’s visibility in Google’s supported experiences. It provides a property-based baseline, canonical page reporting, geographic and device breakdowns, date trends, and an exportable first-party record.

    This makes GSC useful for questions such as:

    • Which canonical pages receive the most Google generative impressions?
    • Did text-based or multimodal exposure change?
    • Is the movement concentrated in one country or device?
    • Did a site-wide technical issue coincide with a drop?

    GSC also has established reporting conventions, including preliminary data markers, aggregation rules, row limits, and a public data anomalies log.

    Its limits are equally important. An impression does not prove that the brand was recommended, that a particular claim was used, or that the exposure produced a click. The current report does not function as a prompt library or a competitor response monitor.

    Trackers Are Strongest for Repeatable Answer Observation

    Use an AI visibility tracker when the question starts with a buyer prompt or generated answer. The tracker can keep the exact wording, platform, region, language, and observation date attached to the result.

    A stable prompt set can answer:

    • Does the brand appear for this decision?
    • Is it explicitly recommended or merely mentioned?
    • Which competitors share the answer?
    • Which cited domains support the response?
    • Does position or framing change across platforms and time?
    Two measurement lanes showing GSC counting first-party Google link impressions and a tracker observing prompt-level answers across platforms.

    The trade-off is sampling. A tracker observes the prompts and conditions selected by the team. It does not automatically represent every real user conversation. Generated answers are also variable, so one run is a snapshot rather than a durable rate.

    Good tracker reporting therefore discloses prompt-set size, selection method, platforms, regions, cadence, and version changes.

    Four Common Comparison Errors Distort the Story

    The first error is treating a GSC impression and a tracker mention as interchangeable units. One is a displayed link under Google’s rules; the other is coded content in a sampled answer.

    The second is comparing a property-wide GSC total with a narrow commercial prompt set. The scopes differ in both demand and intent.

    The third is claiming that a tracker “fills in” hidden Google queries. It can test relevant prompts, but it cannot reveal the complete private query stream behind Search Console totals.

    The fourth is merging the numbers into one score without an explicit model. Adding impressions, mentions, citations, and positions produces a number, but not necessarily a meaningful measure.

    Keep raw measures separate. Build a shared interpretation layer above them.

    Use a Measurement Contract to Join the Data

    Before creating a combined dashboard, define a contract for each field. Record its source, unit, scope, update frequency, owner, known limitations, and the decision it supports.

    Measurement contract linking each metric to its source, scope, limitation, owner, and business decision before dashboarding.

    A practical contract might contain:

    • Google AI impressions: GSC property aggregation, complete weekly period, split by search type.
    • Tracked prompt inclusion rate: percentage of approved prompts where the brand appears, based on repeated observations.
    • Recommendation rate: percentage with explicit product or brand recommendation under a documented coding rule.
    • Owned citation rate: percentage of observed answers containing a link to an owned domain.
    • Competitor overlap: frequency with which named competitors appear in the same prompt set.

    Do not call inclusion rate “share of all AI searches.” It is the share of a defined sample. Do not call GSC impressions “brand mentions.” They are link impressions.

    Reconcile Diverging Signals Instead of Choosing a Winner

    The two systems will sometimes move differently. That divergence can be informative.

    If GSC impressions rise while tracked inclusion is flat, Google demand or surface coverage may have expanded beyond the tracked prompt set. Check pages, countries, devices, and search type before changing the prompts.

    If tracked recommendations improve while GSC is flat, the gain may be occurring in ChatGPT, Perplexity, or a Google prompt sample too small to move property totals. Confirm platform scope and citations.

    If both fall, test shared explanations such as indexing, source availability, product changes, or market demand. Parallel movement still does not prove one common cause.

    If they contradict sharply, audit definitions, dates, filters, prompt versions, and reporting anomalies first. Measurement drift is often easier to fix than a speculative optimization program.

    Where Topify Fits in the Combined Stack

    Topify operates in the observational layer. Its current Prompt Discovery workflow focuses on prompt demand, brand visibility gaps, competition, and opportunity prioritization. Its monitoring use case can track how a defined prompt set produces mentions, recommendations, competitors, and citation patterns across supported platforms.

    Keep Google Search Console as the source of truth for Google’s own reported impressions. Use Topify to investigate the answer-level questions GSC does not expose and to extend the view beyond Google where supported.

    A sensible operating sequence is:

    1. Export the complete GSC baseline.
    2. Identify high-value pages, markets, and movement.
    3. Approve a stable prompt set representing the relevant buyer decisions.
    4. Monitor answer inclusion, recommendations, competitors, and citations.
    5. Investigate convergence or divergence with the measurement contract.

    This approach preserves the authority of each source and gives the team more diagnostic depth without inventing a universal metric.

    Conclusion

    The GSC AI report and AI visibility trackers are complementary because they observe different events. Search Console provides first-party Google link impressions for a verified property. A tracker provides controlled observations of prompts, generated answers, competitors, recommendations, and citations across its supported platforms.

    Use each tool for the claim it can support. Keep units separate, publish sampling and scope, and define a measurement contract before joining the views. When the signals diverge, investigate filters, coverage, and prompt selection instead of choosing whichever chart tells the preferred story.

    FAQ

    Is Google Search Console an AI visibility tracker?

    It is a first-party performance report for supported Google generative AI features. It does not provide the same prompt, competitor, recommendation, and cross-platform observations as a dedicated tracker.

    Can an AI visibility tracker access Google’s internal AI metrics?

    No external tracker has access to Google’s internal ranking or AI systems. Trackers observe outputs for defined prompts and conditions.

    Should GSC impressions and tracker mentions be combined into one score?

    Usually not as raw values. They use different units and scopes. Keep them separate unless a documented model explains the normalization and decision purpose.

    Which tool should a small team start with?

    Start with GSC for first-party Google exposure, then add a small stable prompt set when the team needs recommendation, citation, competitor, or non-Google visibility evidence.

    Read More

  • ChatGPT vs Google AI Shopping Visibility: What Makes Products Discoverable

    ChatGPT vs Google AI Shopping Visibility: What Makes Products Discoverable

    A merchant can keep one catalog, one product page, and one set of images, yet receive different treatment in ChatGPT and Google AI shopping experiences. One system may ask follow-up questions and build a buyer’s guide from merchant data plus the public web. Another may connect a conversational request to Google’s Shopping Graph, Merchant Center data, and visual search surfaces.

    The optimization mistake is assuming one universal AI shopping feed. The more useful model is a shared product-truth layer with platform-specific discovery paths. Brands need consistent identifiers, current commerce facts, useful pages, and credible external evidence, then separate measurement for how each experience selects and explains products.

    Both Experiences Start With Buyer Constraints, Not Short Keywords

    AI shopping requests often combine category, budget, use case, preferences, and exclusions. OpenAI says Shopping Research can ask follow-up questions about brands, sizes, performance, comfort, style, and price before starting a multi-step discovery process.

    Google describes conversational shopping in AI Mode similarly. A user can describe a need in natural language, refine the request, and receive visual product results rather than operating a fixed set of filters. Google’s visual AI Mode announcement ties those experiences to the Shopping Graph and frequently refreshed product listings.

    For merchants, the implication is simple: generic category relevance gets a product into the broad search space, while constraint coverage determines whether it remains a credible option.

    The Discovery Inputs Overlap but Are Not Identical

    OpenAI says Shopping Research may use merchant product data supplied through the Agentic Commerce Protocol, publicly available product information, and other relevant retail sources. The final guide can include top picks, trade-offs, side-by-side attributes, and links to merchants.

    Google’s shopping experiences draw on its own commerce ecosystem, including Merchant Center and the Shopping Graph, alongside indexed web information and visual understanding. Exact ranking and recommendation systems are not public, so marketers should avoid claiming a single deterministic formula.

    Input layerChatGPT Shopping ResearchGoogle AI shopping experiencesMerchant action
    Merchant catalogACP merchant data where availableMerchant Center and Shopping Graph ecosystemKeep identifiers, attributes, price, and availability current
    Public product pageCan read publicly available retail informationSearch-indexed page and product informationMake facts crawlable, specific, and consistent
    ImagesSupports visual product discovery and comparisonCentral to visual AI Mode, Lens, and shopping resultsUse representative, high-quality, variant-accurate images
    External evidenceMay use other relevant retail sourcesSearch and shopping systems can use broader web evidenceBuild legitimate reviews, editorial proof, and policy clarity
    Buyer interactionFollow-up questions and live refinementConversational refinement and visual explorationCover real constraints instead of keyword variants
    MeasurementObserve prompts, products, explanations, and merchant linksUse Merchant Center, Search Console, and answer observationKeep platform-specific baselines

    This table describes documented input categories, not hidden weights. No external tool can see the complete internal selection logic.

    Build One Product-Truth Layer Before Platform Tactics

    The shared foundation is accurate product truth. Every system should receive the same core identity and commerce facts even if the delivery format differs.

    Create a canonical record for product ID, title, brand, category, description, price, currency, availability, condition, variants, dimensions, materials, compatibility, shipping, returns, warranty, and primary image. Add regulated or category-specific attributes where needed.

    Resolve conflicts between the page, structured data, merchant feed, and ACP feed. A stale price on one surface or a mismatched variant image can weaken the buying experience and make measurement hard to interpret.

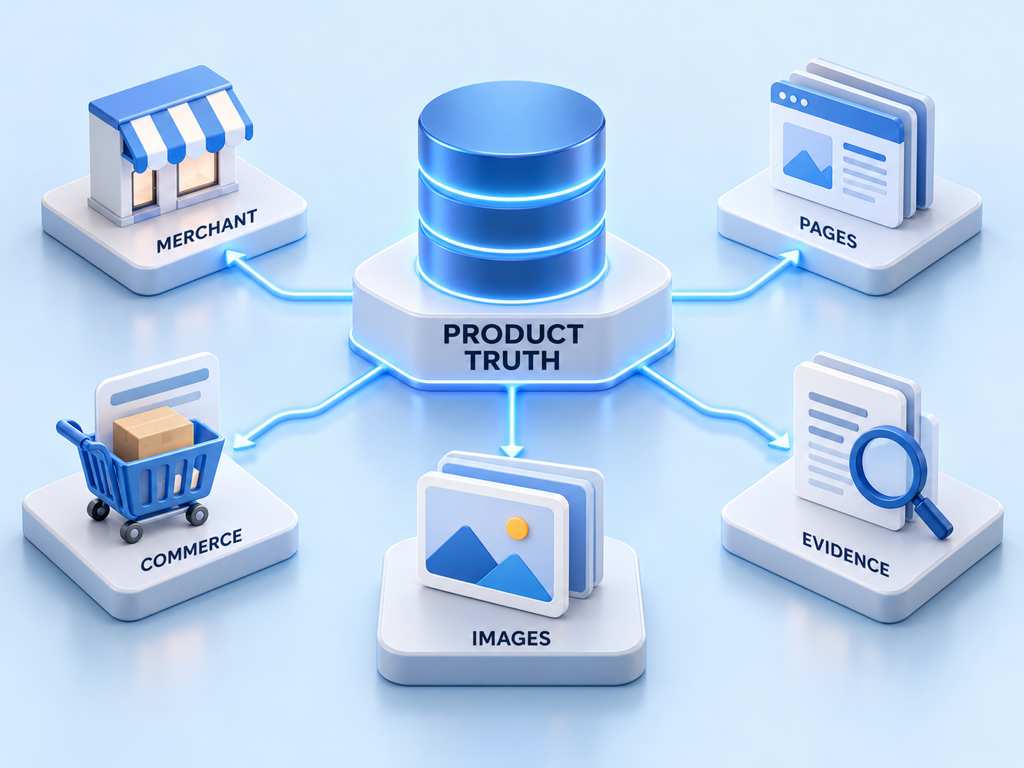
    Shared product-truth layer feeding ChatGPT merchant data, public pages, Google Merchant Center, images, and external evidence.

    Assign an owner and refresh cadence to every dynamic field. Price and stock may require near-real-time updates, while materials and dimensions change only with the product version.

    Make Product Pages Useful Beyond the Feed

    A feed is structured inventory, not the full explanation. Product pages should help a buyer understand fit, trade-offs, compatibility, and policies that a recommendation needs to summarize.

    Expose essential information in crawlable text. Use clear headings, concise attribute blocks, comparison tables, variant-specific images, and accessible alt text. Keep JavaScript interactions from hiding the only copy of a key fact.

    OpenAI notes that shopping information can still be incomplete or wrong and tells users to confirm final price, taxes, fees, shipping, availability, size, color, returns, and warranty on the retailer’s site. That makes the landing page the final source of truth even when discovery happens in an AI conversation.

    Do not write unsupported claims to sound recommendation-ready. Specific limitations build more trust than generic superlatives.

    Treat Images as Product Data, Not Decoration

    Visual shopping depends on accurate representation. Provide a high-resolution primary image, variant-specific views, scale, important details, and realistic use where helpful. Avoid promotional text overlays that obscure the item.

    Google’s image SEO guidance recommends crawlable HTML images, representative high-resolution previews, descriptive context, and useful alt text. Image URLs should be stable and accessible, with responsive markup that includes a fallback src.

    For each variant, align image, color, size, price, and availability. If a blue shoe image opens a generic page with the blue size unavailable, visibility may increase while customer trust falls.

    Use captions or nearby copy for facts a pixel cannot verify, such as dimensions, compatible devices, certification, or what is included in the box.

    External Evidence Shapes Confidence and Explanation

    AI shopping experiences may consult reviews, editorial sources, and other retail information to explain strengths and trade-offs. A merchant feed can establish what the product is and whether it is available; independent evidence can help support how it performs and for whom it fits.

    Build this evidence legitimately. Encourage authentic reviews, keep support and policy information current, publish verifiable testing methods, and make expert documentation easy to cite. Do not manufacture community posts, ratings, or endorsements.

    The right source depends on the question. A return-policy concern should resolve to the merchant’s current policy. A durability claim may need independent testing. A compatibility question may need official technical documentation.

    Audit Visibility With Platform-Specific Questions

    Do not use one score to hide different shopping journeys. Build a small prompt set from real buyer constraints and record the exact platform, region, date, product availability, and wording.

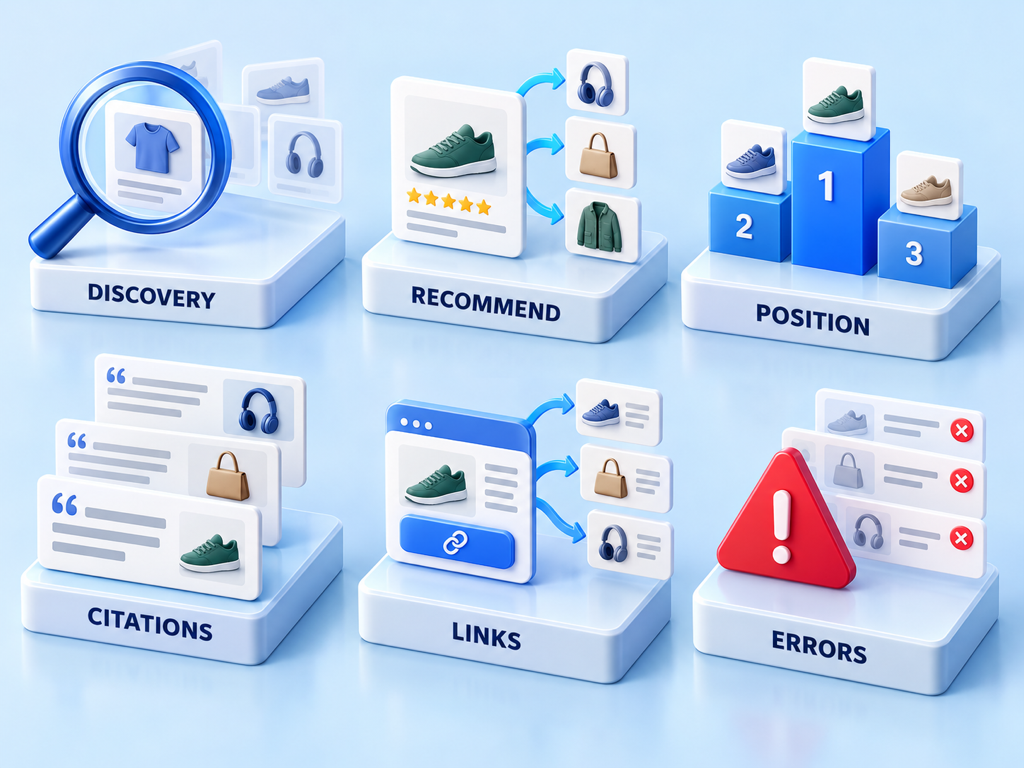
    Comparison scorecard separating discovery, recommendation, position, explanation, citation, and merchant-link outcomes for ChatGPT and Google AI shopping.

    Track at least:

    • product discovered or absent;
    • brand mentioned or explicitly recommended;
    • recommendation position when ordered;
    • stated rationale and trade-offs;
    • merchant link and destination;
    • source or citation when visible;
    • incorrect attributes or stale availability;
    • competitors appearing for the same constraint.

    Repeat observations because answers can vary. Preserve the same baseline prompts rather than adding new ones mid-comparison.

    For Google, pair answer observation with Merchant Center diagnostics and Search Console, including multimodal reporting where relevant. For ChatGPT, inspect the Shopping Research output, product comparisons, merchant links, and any visible sources. Neither view represents every shopper conversation.

    Use Topify as the Cross-Platform Observation Layer

    Topify can support the prompt and competitor layer after the product-truth foundation is stable. Use prompt discovery to identify high-value shopping questions, then monitor whether the brand appears, how it is positioned, which competitors recur, and which sources support the answer across available platforms.

    Keep platform-native diagnostics in their original systems. Topify does not replace Merchant Center’s feed errors or Google’s first-party impression data. Its role is to make the generated-answer layer comparable and repeatable.

    Start with a limited, approved prompt set split by category, constraint, and funnel stage. Review errors manually before assigning content or feed work. A missing recommendation may reflect true product fit, unavailable inventory, weak evidence, or normal response variation.

    The output should be an action queue tied to facts: fix a field conflict, add a missing product attribute, improve a destination page, investigate an external source gap, or gather more observations.

    Conclusion

    ChatGPT and Google AI shopping experiences share a need for accurate products, useful pages, strong images, and credible evidence, but their discovery inputs and reporting systems are not identical. Optimizing one universal “AI shopping feed” oversimplifies the problem.

    Build one canonical product-truth layer, distribute it through the appropriate merchant systems, and keep public pages consistent with every feed. Then measure each platform with the same buyer constraints but separate evidence. Cross-platform monitoring becomes useful only after platform-native diagnostics and product facts are trustworthy.

    FAQ

    What data does ChatGPT Shopping Research use?

    OpenAI says it may use ACP merchant product data, publicly available product information, and other relevant retail sources during multi-step discovery.

    Does Google AI Mode use Merchant Center data?

    Google connects conversational shopping experiences with its Shopping Graph ecosystem, where Merchant Center is a primary way for merchants to supply current product data.

    Is a product feed enough for AI shopping visibility?

    No. Feeds supply structured commerce facts, while public pages, images, policies, reviews, and independent evidence help answer fit and trade-off questions.

    How should brands compare ChatGPT and Google AI shopping visibility?

    Use the same stable buyer constraints, record platform-specific discovery and recommendation outcomes, and keep Merchant Center, Search Console, and ChatGPT observations as distinct evidence sources.

    Read More

  • GPT-6 vs Claude: Why Fable 5.1 Still Wins Coding Benchmarks

    GPT-6 vs Claude: Why Fable 5.1 Still Wins Coding Benchmarks

    Your engineering team just spent a week debating GPT-6 vs Claude for the next coding assistant rollout. Someone forwarded OpenAI’s launch table, where GPT-6 Astra beats Fable 5.1 on almost every row. Someone else forwarded an independent benchmark showing Fable 5.1 in first place. Both charts cite real numbers. Neither one tells you which model to actually pick.

    GPT-6 Astra vs Claude Fable 5.1: The Coding Numbers Don’t Agree

    OpenAI launched GPT-6 Astra on September 3, 2026, two days after Anthropic shipped Claude Fable 5.1. OpenAI’s own comparison table put Astra ahead on Terminal-Bench 4.0, 57.9% against 55.8%, and further ahead on DeepSWE v1.1, 74.1% against 67.4%, according to benchmark figures compiled by CometAPI.

    Artificial Analysis, a third-party evaluator with no stake in either lab, tells a different story. Its Coding Agent Indexscores Fable 5.1 at 70, three points ahead of Astra’s 67, running each model through its own dedicated harness, Claude Code for Fable and Codex for Astra. On the broader Intelligence Index, the gap widens: Fable 5.1 scores 66, Astra sits at 61.

    That’s the part most coverage skips. OpenAI tested Fable 5.1 on Astra’s launch evaluations. Anthropic never ran the reverse comparison in public. When a vendor grades its own competitor, the scoreboard tends to tilt toward the vendor doing the grading.

    BenchmarkGPT-6 AstraClaude Fable 5.1Tested by
    AA Coding Agent Index6770Artificial Analysis
    AA Intelligence Index6166Artificial Analysis
    Terminal-Bench 4.057.9%55.8%OpenAI
    DeepSWE v1.174.1%67.4%OpenAI
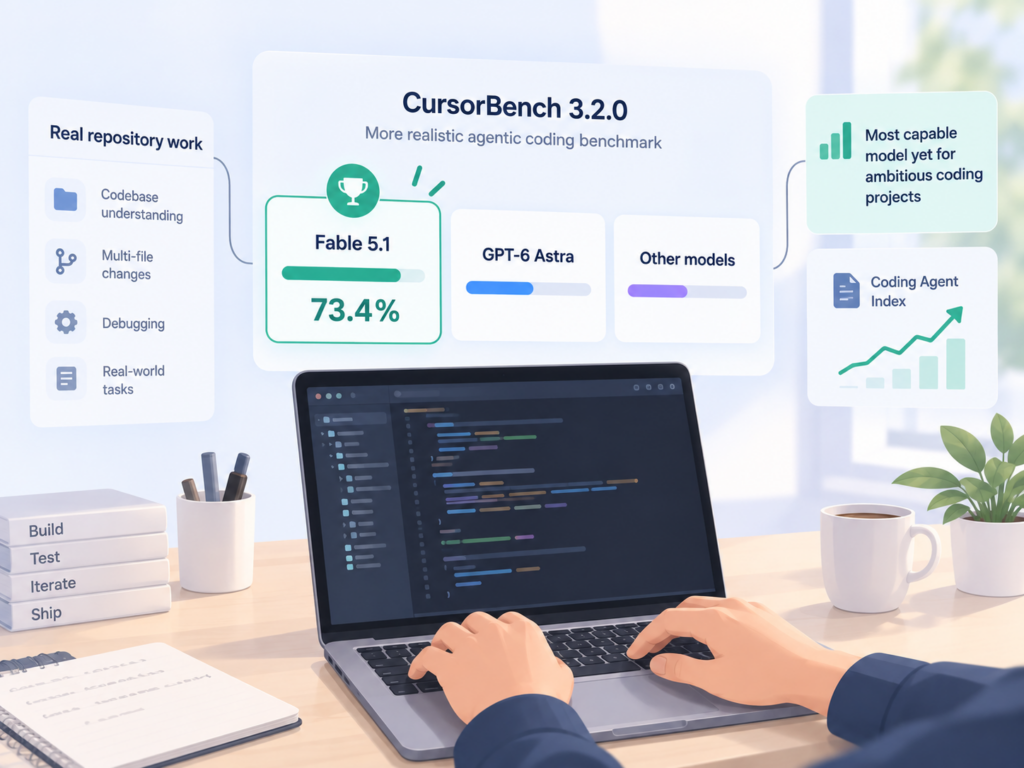
    CursorBench 3.2.0not published73.4%Anthropic

    The split is consistent: whoever runs the test tends to win it, or at least come closer to winning it. That alone should make any single-source coding claim worth a second look before it shapes a purchasing decision.

    What Fable 5.1 Actually Wins at Coding

    Independent testing keeps landing in Fable 5.1’s favor on the metrics built to simulate real agentic coding work, not isolated code snippets. On CursorBench 3.2.0, a benchmark meant to reflect day-to-day repository work, Fable 5.1 posts 73.4%. Anthropic describes it as its most capable model yet for ambitious coding projects, a claim the Coding Agent Index backs up at the aggregate level.

    The pattern holds on reasoning tasks with tools attached, too. On Humanity’s Last Exam with tool access, Fable 5.1 reaches 65.0% against Astra’s 57.2%, a reversal from most of the raw knowledge benchmarks where Astra leads.

    Here’s the thing: a three-point lead on one index and a five-point lead on another sound decisive until you notice both indices come from the same evaluator, running on the same day, using methodology neither lab controls.

    Cost per task tells a similar story once you factor in what a coding agent actually spends its budget on. Fable 5.1’s cache reads price out at $0.25 per million tokens, a rate Astra doesn’t match on any tier. For teams running agentic coding loops that reread the same repository context dozens of times per session, that pricing gap shows up directly in the monthly bill, not just in the benchmark table.

    Where GPT-6 Astra Pulls Ahead Instead

    Astra isn’t a weaker model. It’s a differently optimized one. On raw execution benchmarks published by OpenAI, Astra leads FrontierMath Tier 4 at 97.6% against Fable 5.1’s 87.8%, and it holds a similar edge on GPQA Diamond and AutomationBench.

    Token efficiency is where Astra genuinely separates itself. Per task, Astra costs less than half of Fable 5 for the same Coding Agent Index score, largely because it burns roughly a third of the tokens GPT-5.6 Sol needed for comparable output. That efficiency doesn’t survive contact with pricing, though: list rates for Astra rose 2.5x to $10 per million input tokens and $50 per million output tokens, identical to Fable 5.1’s rate card.

    The one place the pricing story flips is cache reads. Astra charges $1.00 per million cached tokens, four times Fable 5.1’s $0.25 rate. In a long agent loop that rereads the same system prompt and tool schema hundreds of times, that difference compounds fast. The same workload that favors Astra on a single-shot task can favor Fable 5.1 across a forty-step agent run.

    Astra also carries a surcharge most comparison charts leave out. Above 272,000 input tokens, its rate doubles on both input and cache reads, and output pricing rises 1.5x. Fable 5.1 applies no such surcharge at any context length. For teams working with large codebases or long documents, that difference changes which model is actually cheaper well before the benchmark scores come into play.

    The Real Lesson: Benchmarks Depend on Who’s Holding the Ruler

    Both claims are true. Astra wins more rows on OpenAI’s table. Fable 5.1 wins both flagship indices on the one evaluator with no vendor stake in the outcome. They’re measuring different workloads, different harnesses, and in some cases, different task sets entirely.

    This isn’t unique to these two models. It’s the structural reality of AI benchmarking in 2026. Every lab optimizes for the evaluations it controls, and every comparison table quietly encodes whose test you’re trusting.

    What This Means If You Only Optimize for One Engine

    The same distortion shows up outside coding benchmarks, and it’s more expensive when it happens to your brand. If your team only tracks how your product shows up in ChatGPT, you’re making the same mistake as trusting a single vendor’s benchmark table: you’re seeing one engine’s version of reality and calling it the whole picture.

    AI answer engines don’t cite, rank, or recommend brands the same way. A product that gets consistently surfaced in Perplexity’s answers might be nearly invisible in Gemini’s, and neither Google Search Console nor a single-platform tracker will tell you why. Topify was built around that gap, tracking visibility, sentiment, and position across ChatGPT, Gemini, Perplexity, DeepSeek, Doubao, Qwen, and other major AI platforms, so a blind spot in one engine doesn’t become a blind spot in your entire strategy.

    Tracking Visibility Across Engines, Not Just One

    In practice, this means a marketing team can see that a product is losing citations in one AI engine while gaining them in another, and trace the shift back to a specific source domain that stopped or started getting cited. Topify’s Dynamic Competitor Benchmarking applies the same logic used to sort out the Astra-versus-Fable debate: don’t trust one scoreboard, compare across all of them, and let the pattern across engines tell you what a single dashboard can’t.

    For teams managing content across multiple client brands or product lines, that cross-engine view often matters more than any single benchmark win. A brand that ranks first in ChatGPT recommendations but never gets mentioned in Claude’s answers is optimizing for half the market, often without knowing it.

    The parallel to the Astra-versus-Fable debate holds up under scrutiny. Just as OpenAI’s table and Artificial Analysis’s index disagree because they measure different workloads, a brand’s ChatGPT visibility score and its Perplexity visibility score can disagree because the two engines pull from different source domains and weigh citations differently. Treating either one as the full picture leads to the same error: optimizing for the ruler instead of the thing it’s supposed to measure.

    Conclusion

    There’s no clean winner between GPT-6 Astra and Claude Fable 5.1 on coding, and there won’t be one between any two frontier models going forward. The scoreboards will keep disagreeing because the labs keep building the tests. The practical move isn’t picking a side. It’s tracking your own workload against multiple independent measures, whether that’s coding benchmarks or your brand’s visibility across AI engines, so one vendor’s table never becomes your only source of truth.

    FAQ

    Q: Is GPT-6 Astra better than Claude Fable 5.1 for coding? 

    A: It depends on which benchmark you trust. OpenAI’s own launch table shows Astra ahead on Terminal-Bench and DeepSWE. Artificial Analysis, an independent evaluator, has Fable 5.1 ahead on its Coding Agent Index, 70 to 67.

    Q: Why do OpenAI and Artificial Analysis disagree on benchmark results? 

    A: Each organization runs its own harness, task set, and effort settings. OpenAI tested Fable 5.1 on evaluations built for Astra’s launch, while Anthropic reports its own separately measured results, so the two tables aren’t directly comparable.

    Q: Is GPT-6 Astra cheaper than Claude Fable 5.1? 

    A: List prices are identical at $10 per million input tokens and $50 per million output tokens. Astra is more token-efficient per task, but its cache read pricing is four times higher than Fable 5.1’s, which can offset the savings in long agent workflows.

    Q: Should brands optimize content for one AI engine or several? 

    A: Optimizing for a single engine creates the same blind spot as trusting one vendor’s benchmark table. Tracking visibility across multiple AI platforms gives a more accurate picture of where a brand actually stands.

    Read More

  • AI Mode Tracking vs Google Tracking: Where They Diverge

    AI Mode Tracking vs Google Tracking: Where They Diverge

    Your rankings haven’t moved in three months. Your organic clicks have. If you’re staring at a rank tracker that says “position 3, no change” while Search Console shows a steady decline, you’re not imagining a glitch. You’re looking at two different systems that happen to share a search bar.

    Google AI Mode doesn’t rank pages the way classic search does, and that gap is exactly why most SEO dashboards can’t see what’s actually happening to your traffic.

    Google Ranking Tracks Positions. AI Mode Tracks Something Else Entirely

    A traditional rank tracker works by simulating a search, scraping the results page, and recording where your URL lands in a list. Position 1 beats position 2. Simple, stable, and built for a page of ten blue links.

    AI Mode breaks that model completely. When someone activates AI Mode, Google’s AI reads across multiple sources and hands back one synthesized, conversational answer instead of a ranked list. There’s no number one, because there’s no ordered list to place you in.

    That’s the gap most SEO dashboards still don’t measure.

    Your brand can be woven into that answer, described accurately, and never show up in a single rank-tracking report. Or it can hold a top-three position on the classic results page and still be left out of the AI Mode conversation entirely.

    Three Ways AI Mode Results Behave Differently From Ranked Pages

    The differences aren’t cosmetic. They change what “visibility” even means.

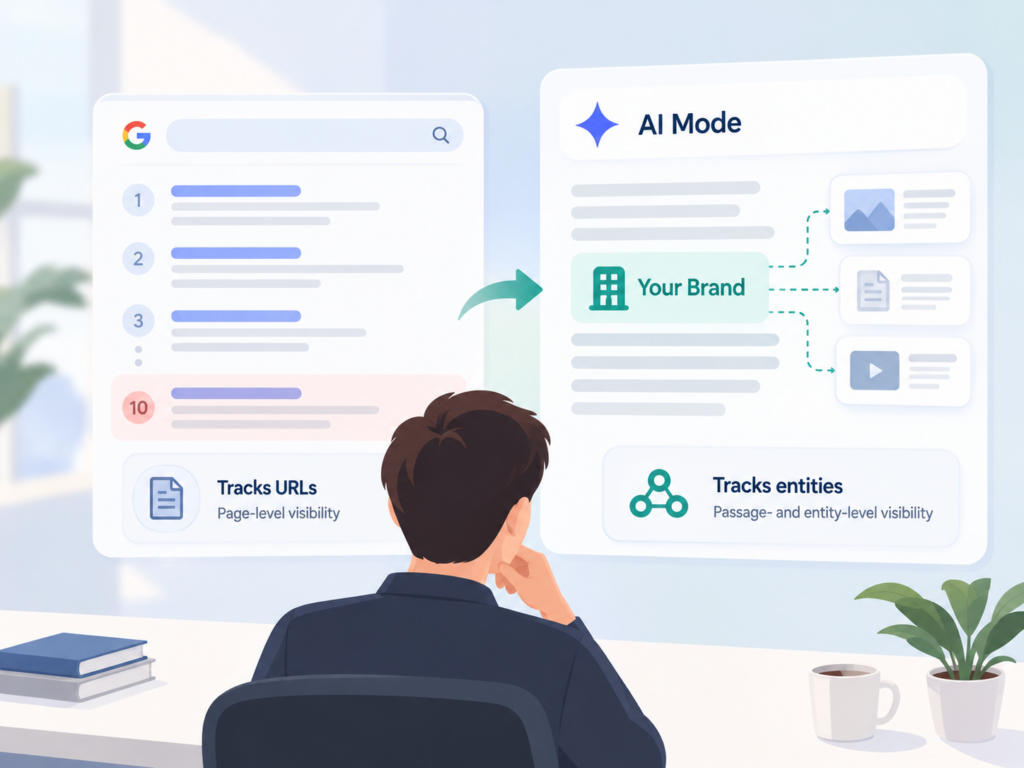
    Presentation. A ranked page is a list you scan. AI Mode is a narrative you read. Your brand can be referenced inside that narrative without a clickable link attached to it at all, which means a mention can happen with zero footprint in a traditional crawl.

    Unit of visibility. Classic tracking counts URLs. AI Mode counts entities. A page ranking outside the top ten can still see its parent brand cited inside an AI Mode answer, because the system pulls information at the passage and entity level rather than the page level.

    Volatility pattern. Search rankings shift with algorithm updates, usually over weeks. AI Mode answers shift with phrasing, context, and session history, sometimes within the same day. Two people asking the same question in slightly different words can get answers that cite different sources.

    The overlap between what AI Mode cites and what shows up in classic organic rankings is smaller than most teams assume. Depending on the study, AI Mode citations line up with the traditional top ten only 17% to 54% of the time, and the overlap between AI Mode citations and AI Overview citations, a related but separate surface, sits at just 13.7%. Three surfaces, three different citation lists, one search bar.

    SignalClassic Search RankingGoogle AI Mode
    Output formatOrdered list of linksSingle synthesized answer
    What’s measuredURL positionBrand or entity mention
    Retrieval methodPage-level rankingMulti-query synthesis across passages
    Overlap with top-10 organic100% by definition17% to 54%, varies by study
    Click behavior34% to 43% zero-click92% to 94% zero-click

    Why Your Rank Tracker Can’t See What’s Happening in AI Mode

    The technical reason is simple. A rank tracker is built to scrape a static results page and match your URL against it. AI Mode output isn’t cached the same way, isn’t structured as a list, and can vary between two identical queries run minutes apart.

    That mismatch has real consequences. Top-10 organic rankers accounted for 76% of AI Overview citations in mid-2025, but that share had dropped to roughly 38% by early 2026. Ranking well used to be a reasonable proxy for AI visibility. It’s becoming a weaker one every quarter.

    Meanwhile the traffic stakes keep rising. AI Mode has passed 1 billion monthly users, and 93% of those sessions end without a click to any external site. Independent clickstream analysis puts the zero-click rate for AI Mode specifically between 92% and 94%, compared with 34% to 43% for traditional search. Whatever share of that conversation your brand occupies, your analytics probably aren’t showing it.

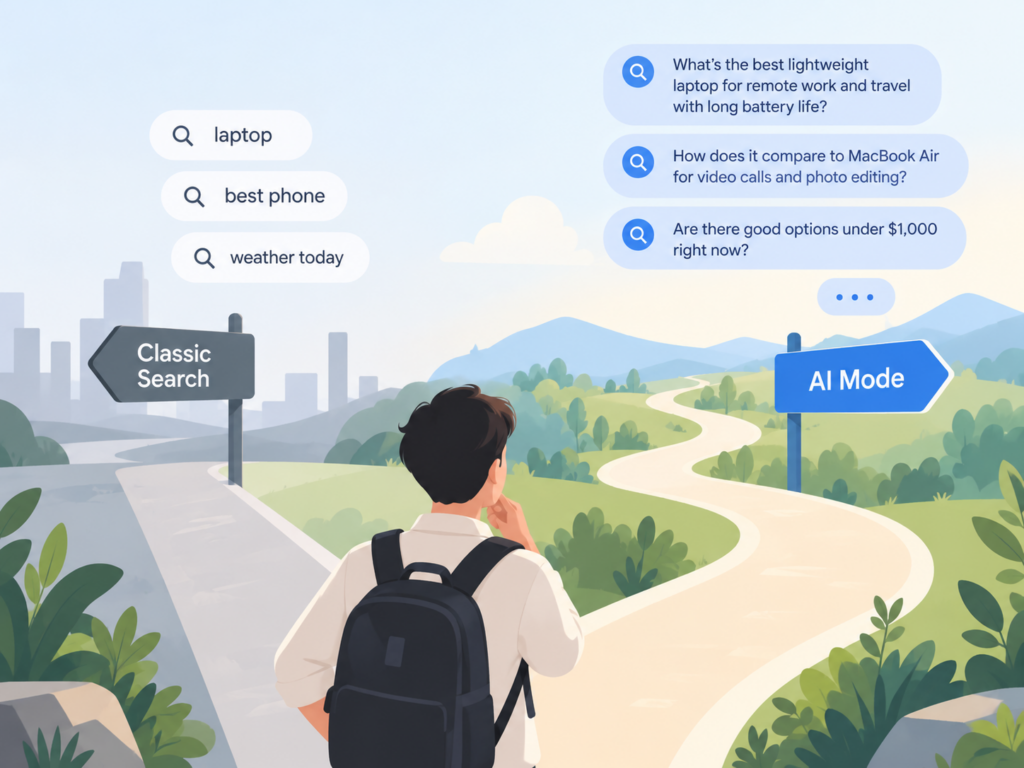
    Queries look different in AI Mode too. The average AI Mode query runs about 7.22 words, nearly double the 4.0-word average for classic Google search, and follow-up questions inside a single AI Mode session have been climbing fast. That longer, more conversational query pattern is exactly the kind of input a URL-matching rank tracker was never built to parse.

    What Tracking AI Mode Actually Requires

    If position isn’t the metric, what is? Four things matter more:

    • Mention rate. How often your brand shows up in AI Mode answers for the prompts that matter to your category, not just your target keywords.
    • Sentiment. Whether the mention describes you accurately and favorably, or gets your positioning wrong.
    • Source attribution. Which domains AI Mode actually cites when it talks about your space, and whether any of them are yours.
    • Relative position. Where you land against named competitors inside the same answer, since AI Mode often surfaces two or three options side by side.

    This is closer to brand monitoring than classic rank tracking, which is why most AI Mode trackers separate mention rate, citation share, and sentiment into distinct metrics rather than collapsing everything into a single rank number.

    Topify builds around that same logic. Its Visibility Tracking metric measures how often your brand actually appears across AI Mode and other major AI platforms, rather than assuming a strong organic rank will carry over. Position Tracking shows where you land relative to named competitors inside the same conversational answer, and Source Analysis breaks down which domains AI Mode is citing for your category, so you can see whether the gap is a content problem or a citation problem.

    None of that replaces classic SEO reporting. It sits next to it, covering the part of the funnel a URL-based crawler was never designed to see.

    How to Set Up AI Mode Monitoring Without Losing Sight of Traditional SEO

    Run both systems in parallel rather than picking one.

    Start with a fixed list of the prompts your buyers actually ask, not just your target keywords, since AI Mode queries tend to be longer and more conversational than a typical search box entry. Check those prompts on a regular cadence and log three things each time: whether you’re mentioned, how you’re described, and which sources got cited alongside you.

    Cross-reference that log against your traditional rank data monthly. If a keyword holds steady in classic rankings while its matching AI Mode prompts show declining mentions, that’s your early warning that the two systems have started to diverge for that topic.

    Topify’s One-Click Execution can shorten that loop. State the visibility goal in plain language, review the proposed content or citation strategy, and deploy it without building a manual workflow from scratch each time a gap shows up.

    Conclusion

    Google ranking and Google AI Mode are running two different games on the same platform. One rewards position in a list. The other rewards being named inside an answer the user never has to click past. Tracking only one of them means flying blind on the surface that’s already sending 1 billion people a month home without visiting a single website.

    FAQ

    Is AI Mode ranking the same as SEO ranking?
    No. Classic SEO ranking measures where a URL lands in an ordered list of results. AI Mode has no fixed order, so tracking it means measuring mention rate, sentiment, and citation share instead of position.

    How do you track brand mentions in Google AI Mode?
    Run a consistent set of buyer-relevant prompts through AI Mode on a regular schedule and log whether your brand is mentioned, how it’s described, and which sources are cited. Dedicated GEO platforms like Topify automate this across multiple AI engines at once.

    Why does my page rank well but not appear in AI Mode?
    AI Mode retrieves and synthesizes information at the passage and entity level rather than ranking whole pages, so strong keyword rankings don’t guarantee inclusion. Citation overlap between AI Mode and traditional top-10 rankings runs as low as 17% in some studies.

    Can traditional rank trackers monitor AI Mode results?
    Generally, no. Most rank trackers are built to scrape a static, list-based results page, while AI Mode output is conversational, dynamic, and varies by query phrasing, which requires a purpose-built AI visibility tool instead.

    Read More

  • Amazon vs Perplexity Ruling: Check If AI Shopping Agents Recommend You

    Amazon vs Perplexity Ruling: Check If AI Shopping Agents Recommend You

    Your team read about the Amazon vs Perplexity ruling as a legal update, filed it under “not my problem,” and moved on. That’s the wrong reaction. The Ninth Circuit didn’t just settle a fight between two companies. It confirmed that an AI shopping agent can operate on almost any retail site a user chooses, which means the real question isn’t whether these agents are allowed to shop anymore. It’s whether they mention your brand when they do.

    What the Ninth Circuit Actually Ruled on AI Shopping Agents

    The case started in November, when Amazon sued Perplexity over its Comet browser, alleging the tool covertly accessed customer accounts and violated the Computer Fraud and Abuse Act. A federal judge agreed in March 2026 and blocked Comet’s agentic shopping features on Amazon.

    That injunction didn’t last. On August 4, 2026, the Ninth Circuit Court of Appeals overturned it, ruling that Amazon was unlikely to win its core legal claim.

    The court’s reasoning is now known as the browser analogy. Comet takes a screenshot of what the user’s own browser sees, sends it to Perplexity’s servers, and sends navigation instructions back. Perplexity never talks to Amazon’s servers directly, so the judges compared it to Safari or Chrome: nobody accuses Apple of hacking Amazon just because someone uses Safari to shop there.

    That’s the first federal appellate ruling on whether an AI shopping agent can legally act on a user’s behalf online.

    Why This Ruling Widens the Lane for Every AI Shopping Agent

    This case was about Perplexity, but the logic isn’t Perplexity-specific. It applies to any agent that acts on a user’s instructions rather than accessing a retailer’s systems on its own.

    That’s a real narrowing of what a retailer’s terms of service can do. If a court won’t treat the agent’s operator as the one doing the accessing, blocking agents through lawsuits gets a lot harder.

    The timing matters, too. Adoption isn’t waiting on court decisions. Seventy percent of brands, retailers, and agencies are already testing or deploying an agentic storefront, and only 7% have no plans at all. On the consumer side, ChatGPT hit 900 million weekly active users in February 2026, and AI-referred traffic to US retail sites was still up 393% year over year in the first quarter.

    Ruling or no ruling, shoppers were already handing purchase decisions to agents. This decision just removed one of the few legal levers retailers had to slow that down.

    The Real Question: Does Your Brand Get Recommended by AI Shopping Agents

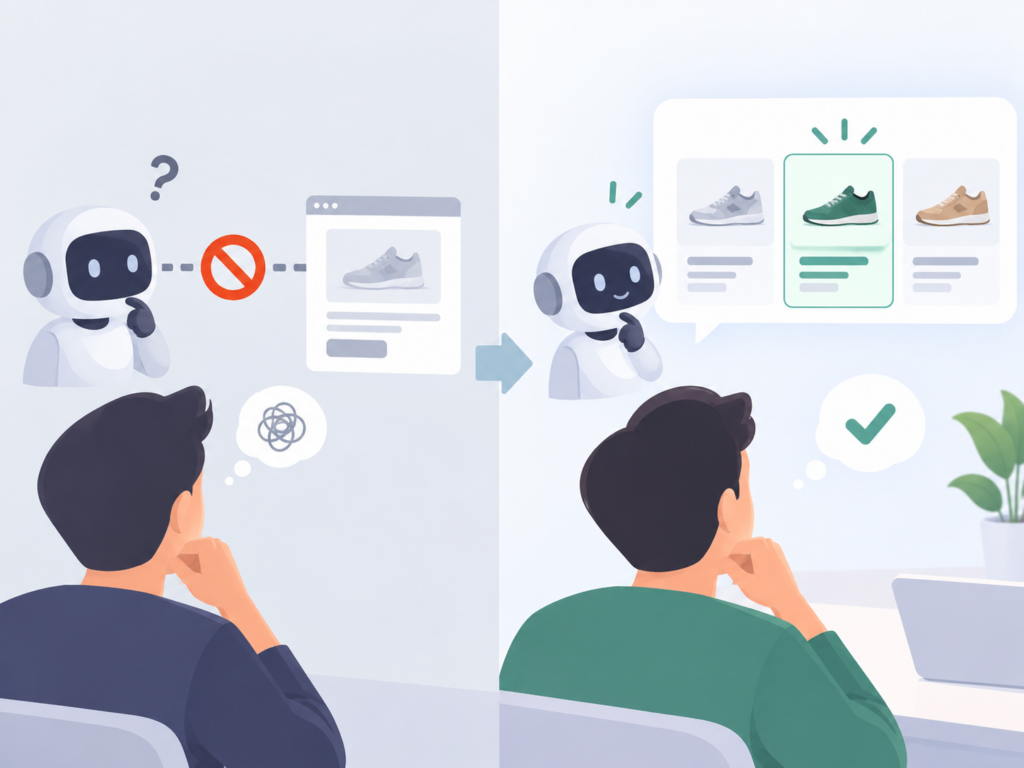
    Here’s the shift most marketing teams haven’t made yet. Before this ruling, the risk conversation was about access: could an agent even reach a product page. After it, the risk conversation is about relevance: does the agent mention your product at all.

    An AI shopping agent doesn’t rank products the way a search engine does. It reads product data, reviews, comparison content, and third-party sources, then decides what to say based on what it can find and trust. There’s no bid, no sponsored slot, no guaranteed placement.

    That’s a fundamentally different game than the one most brand and SEO teams have spent a decade optimizing for.

    The IBM Institute for Business Value found that 45% of consumers already use AI for part of their buying journey, and usage keeps climbing across every age group. Your domain authority, your keyword rankings, your ad spend on the retailer’s own platform: none of that tells you whether Perplexity or ChatGPT is quietly recommending a competitor instead of you.

    How to Measure Whether an AI Shopping Agent Recommends You

    Most teams’ first instinct is to type their own product name into ChatGPT and see what comes back. That’s a start, but it only tells you what happens when someone already knows to search for you.

    The more useful test runs the prompts a real shopper would type without your brand name in them. Category questions. Comparison questions. “Best X for Y” questions. Then check a few specific things:

    • Are you mentioned at all, and how often across repeated runs
    • Where you land in the list when you are mentioned
    • What tone the agent uses to describe you
    • Which sources the agent is pulling its information from

    Doing this by hand across ChatGPT, Perplexity, and Gemini, on a rotating set of prompts, tends to fall apart after the first week. That’s the part Topify is built to automate.

    For marketing teams tracking this across multiple platforms, Topify pulls visibility, sentiment, and position data into a single view. In practice, that means you can spot a drop in Perplexity mentions and trace it back to the exact source that stopped citing your brand, without running the prompts manually every morning.

    What to Do If Your Brand Is Invisible to AI Shopping Agents

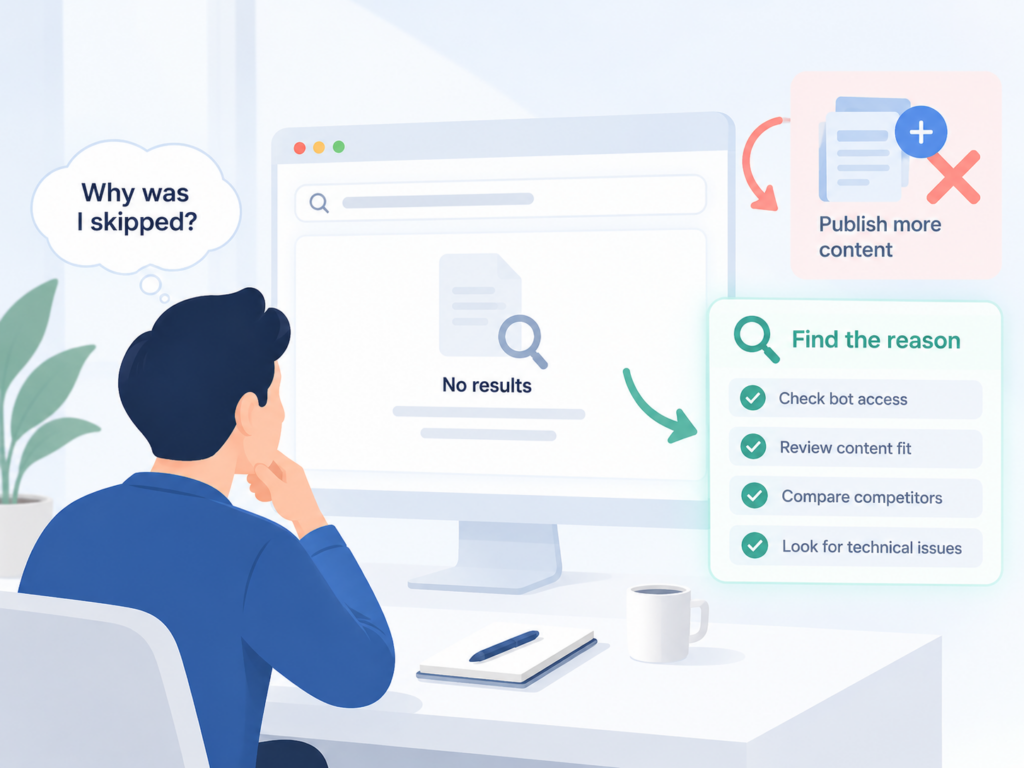
    If the test above comes back empty, don’t panic and don’t guess. The fix starts with finding out why the agent skipped you, not with publishing more content at random.

    Look at which domains the agent is actually citing when it answers category questions in your space. Often it’s a handful of comparison sites, review aggregators, or forum threads the agent trusts more than your own product pages.

    This is less about writing more and more about closing a specific gap. Topify’s source analysis reverse-engineers which URLs an AI platform is citing for a given prompt, so you know exactly where to place content or where to fix a data gap instead of publishing blind. Once you can see the gap, getting started with visibility tracking takes a few minutes, not a quarter-long project.

    Conclusion

    The Amazon vs Perplexity ruling settled a legal question, but it opened a business one. An AI shopping agent can now operate across the web with fewer legal roadblocks, and that means more of your category’s purchase decisions will run through an agent’s recommendation instead of a search results page. The brands that check their visibility now, before it becomes a quarterly fire drill, are the ones that’ll show up when it counts.

    FAQ

    Q: Is it legal for an AI shopping agent to browse and buy on a retail site without permission?
    A: The Ninth Circuit’s ruling in Amazon v. Perplexity found that when a user directs an AI shopping agent to shop on their behalf, it’s the user who is legally accessing the site, not the company that built the agent. This weakens a retailer’s ability to block agents through hacking-law claims, though the underlying case continues in lower court.

    Q: How do I know if ChatGPT or Perplexity recommends my product?
    A: Run realistic category and comparison prompts, without your brand name included, across each platform multiple times. Track whether you’re mentioned, where you rank in the answer, and how the agent describes you. A tool built for this, like Topify, automates the process across platforms instead of requiring manual checks.

    Q: What’s the difference between AI shopping agent visibility and traditional SEO rankings?
    A: Traditional SEO rewards keyword relevance and backlink authority within a search results page. AI shopping agent visibility depends on whether the agent’s underlying model finds and trusts information about your product when generating a conversational answer, which often draws from different sources than your top Google rankings.

    Q: Which AI platforms should I monitor for AI shopping agent visibility?
    A: At minimum, ChatGPT and Perplexity, since both now have active agentic shopping features and were directly involved in this ruling. Gemini and other emerging shopping assistants are worth adding as adoption grows across each platform.

    Read More

  • GPT-6 vs Claude vs Gemini: Why Brand Mentions Differ by Model

    GPT-6 vs Claude vs Gemini: Why Brand Mentions Differ by Model

    GPT-6 Astra rolled out to ChatGPT Plus, Pro, Business, and Enterprise plans this month, and your team probably ran the test everyone runs on a new model: ask it who leads your category. It named three competitors and skipped you. Someone then asked Claude the identical question and got a completely different list. That’s not a fluke, and it won’t get fixed by the next model update either. The gap comes from how each system decides what counts as a trustworthy answer, and that logic barely moved between GPT-5.6 and GPT-6 Astra.

    GPT-6 Doesn’t Reset the Brand Mention Problem

    A new flagship model tends to reset expectations. People assume smarter reasoning means fairer, more consistent answers about who deserves a mention.

    That assumption doesn’t hold. GPT-6 Astra launched in phases starting September 3, 2026, first to OpenAI’s cybersecurity-focused Daybreak program, then to paid ChatGPT tiers and the API. The rollout improved reasoning and agentic task performance. It did not touch the underlying question of which sources OpenAI’s model trusts enough to cite.

    Brand recognition in AI answers isn’t a capability problem. It’s a plumbing problem, and plumbing doesn’t upgrade itself just because the engine got faster.

    Why the Same Question Gets Three Different Answers

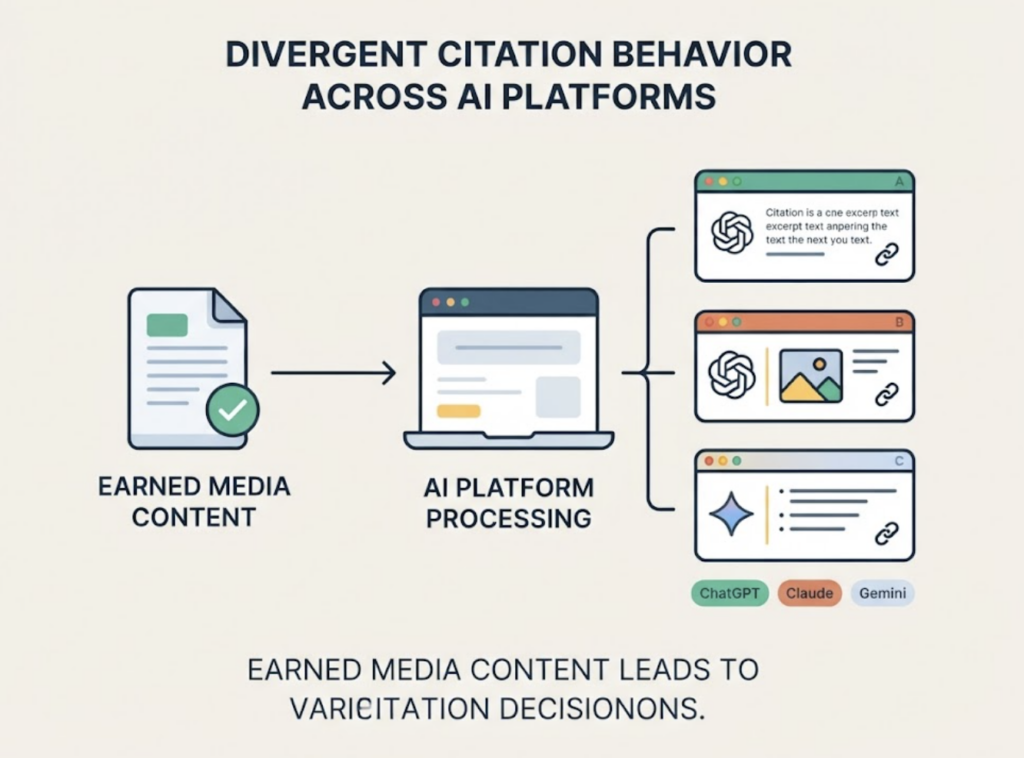
    Each AI platform treats citations as a different kind of decision. Muck Rack’s Generative Pulse research, based on more than 25 million cited links across ChatGPT, Claude, and Gemini, found that citation behavior varies meaningfully by platform even though all three lean on earned media for the bulk of what they cite.

    The frequency gap is the clearest signal. ChatGPT includes a citation in 96% of its responses but averages only around five sources per answer, which makes it a near-universal citer that doesn’t dig deep on any single answer. Claude is the opposite. It cites in roughly 55% of responses, but when it does, it pulls in an average of 13 sources, suggesting a higher bar for confidence before it names anything at all. Gemini lands in between, citing in about 82% of responses at an average of eight sources.

    That’s the mechanism behind the frustration. Your brand isn’t being judged by three versions of the same test. It’s being judged by three different tests with three different pass thresholds.

    PlatformShare of responses with a citationAverage sources per cited answer
    ChatGPT96%~5
    Gemini82%~8
    Claude55%~13

    Read that table as a filter, not a scoreboard. A high citation rate doesn’t mean a platform is more generous toward your brand specifically. It means the platform is more willing to cite something, and whether that something is you still depends on the sources it trusts.

    The Data Sources Behind Each Model’s Answers

    Citation frequency is only half the story. Where each model actually looks matters just as much, and the three systems don’t pull from the same information ecosystem. Gemini leans heavily on Google’s own search index and Knowledge Graph, so a brand that’s a well-verified entity in Google tends to get mentioned with more confidence. ChatGPT’s live retrieval runs through Bing, which means strong Google visibility doesn’t automatically carry over. Claude relies more on what it absorbed during training plus Brave Search for anything real-time, and it tends to favor academic, technical, and niche editorial sources over major wire coverage.

    One widely cited example makes this concrete. When three models were asked who makes the best pickup truck, ChatGPT recommended the Ram 1500 and named Cars.com as its source, while Claude picked the Ford F-150 without citing anything at all. Same category, same question, two different winners, two different evidentiary standards.

    PlatformPrimary retrieval sourceWhat tends to earn a mention
    GeminiGoogle Search index, Knowledge GraphVerified entity status, strong Google Business Profile, schema markup
    ChatGPTBing-based live searchReview-site coverage, consumer comparison content
    ClaudeTraining data plus Brave SearchAcademic, technical, and niche editorial sources over major wire coverage

    Notice that none of these levers overlap much. Optimizing for one platform’s information diet doesn’t automatically move the needle on the other two, and a content strategy built only around Google SEO will quietly under-serve Claude no matter how strong your rankings get.

    What Changed (and What Didn’t) When GPT-6 Astra Launched

    GPT-6 Astra’s early access went first to enterprise security customers, then expanded to consumer and business plans over the following days. The model brought real gains in agentic reasoning and computer-use tasks. None of that changes the retrieval pipeline that decides whether your brand shows up in a recommendation.

    Here’s the part that trips people up: model version numbers move fast, but citation architecture moves slowly. Expecting GPT-7 or the next Gemini refresh to quietly fix an uneven brand footprint is a bet against how these systems have actually evolved so far.

    Look at the release cadence itself. OpenAI shipped GPT-5.4, GPT-5.5, and GPT-6 Astra inside a single year, and in each case the headline improvements were reasoning, coding, and agentic task scores rather than a rebuilt citation or sourcing layer. Anthropic and Google have followed a similar pattern with their own releases. Capability and citation behavior are simply two different roadmaps, and only one of them shows up in a launch announcement.

    Why Watching One Platform Distorts the Picture

    Say your team only tracks ChatGPT because it has the largest user base. You’d see near-universal citation behavior and conclude that showing up there means you’re covered everywhere.

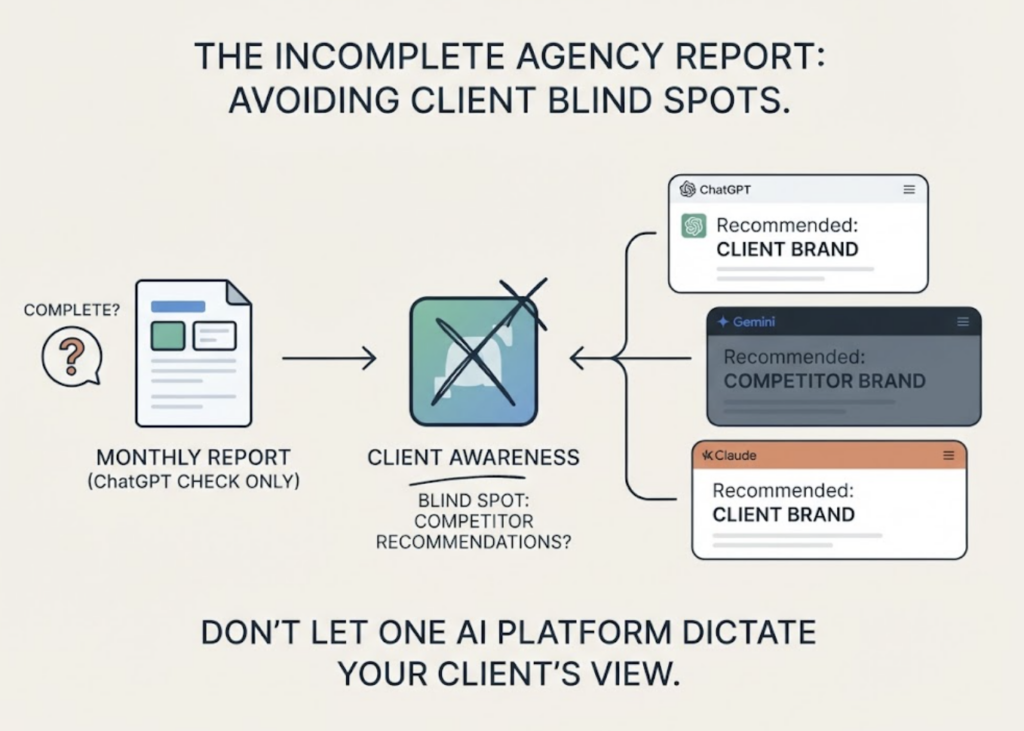
    That conclusion would be wrong. A brand can rank first in Gemini because it’s a strong entity in Google’s Knowledge Graph, then disappear entirely from Claude because it lacks the third-party editorial depth Claude’s higher citation bar demands. Single-platform monitoring doesn’t just miss data. It actively produces a false sense of security, and that’s a worse position than knowing nothing at all.

    The same logic runs in reverse for agencies managing several client brands. A monthly report built only from ChatGPT checks looks complete because ChatGPT answers almost every prompt with something. It says nothing about whether Gemini is quietly recommending a competitor to the exact same searchers, and a client who finds that gap on their own tends to ask why it wasn’t in the report.

    How to See Brand Recognition Across GPT-6, Claude, and Gemini

    Getting a real picture of GPT-6 vs Claude vs Gemini brand recognition means measuring the same prompts across all three at once, not sampling one and assuming it represents the rest.

    This is the specific gap Topify‘s Comprehensive GEO Analytics is built to close. It tracks visibility, sentiment, and position across GPT-6, Claude, Gemini, and other major AI platforms from a single dashboard, so a drop in one engine shows up next to what’s holding steady in another. In practice, that means catching a scenario where your brand is well-positioned in Gemini results but has quietly gone missing from Claude’s answers, then tracing that gap back to a specific source category Claude’s citation logic tends to favor.

    The trade-off is that no single-platform tool gives you this. Point solutions built around one model will always miss the two-thirds of the picture happening somewhere else. If you’re ready to see where your brand actually stands, you can get started with Topify and run the comparison across models directly.

    Conclusion

    GPT-6 Astra changed what these models can do, not how they decide who to mention. That distinction matters because it means the uneven brand recognition your team is seeing today isn’t a temporary bug waiting on the next release. It’s a structural feature of how ChatGPT, Claude, and Gemini each evaluate trust, and it calls for ongoing, cross-platform measurement rather than a one-time check after a launch headline.

    FAQ

    Q: Does GPT-6 Astra cite sources differently than GPT-5.6 did? 

    A: The rollout focused on reasoning, coding, and computer-use gains rather than a rebuilt citation system, so the underlying retrieval and sourcing behavior that shaped brand mentions in GPT-5.6 largely carries over into GPT-6 Astra.

    Q: Why does my brand show up in Gemini but not in Claude? 

    A: Gemini draws heavily on Google’s Knowledge Graph, so a well-verified Google entity often gets mentioned with confidence. Claude sets a higher bar for third-party evidence before it names a brand, so thinner editorial coverage can leave you out of its answers entirely.

    Q: Is it possible to rank well in ChatGPT and still lose customers to a competitor named by Claude? 

    A: Yes. Because each platform pulls from different sources and applies different citation thresholds, strong visibility in one model says very little about your standing in another, which is why single-platform tracking regularly misses real gaps.

    Q: How often should brands re-check AI visibility after a major model launch like GPT-6 Astra? 

    A: Treat model launches as a trigger to re-baseline, not a one-time check. Citation behavior can shift gradually as a new model’s retrieval sources mature, so ongoing tracking catches drift that a single post-launch snapshot won’t.

    Read More

  • GEO Visibility Checker vs Rank Tracker: Two Different Questions

    GEO Visibility Checker vs Rank Tracker: Two Different Questions

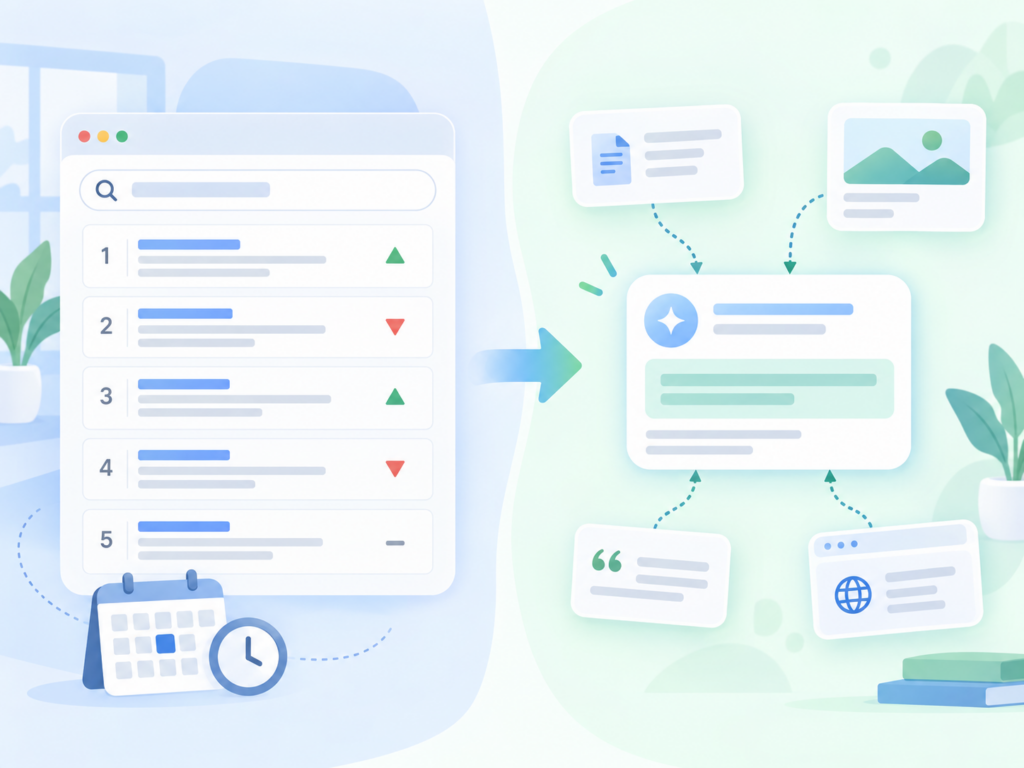
    Your team’s dashboard says you’re ranking on page one for your category’s biggest keyword. Then someone pastes a screenshot of ChatGPT recommending three competitors, and your brand isn’t one of them. Both things are true at the same time. A rank tracker and a GEO visibility checker are built to answer two different questions, and mixing them up is why so many teams feel blindsided the first time they actually look.

    What a Rank Tracker Actually Answers

    A rank tracker checks where a specific URL sits for a defined list of keywords inside Google’s organic results, refreshed daily or weekly depending on the plan. It’s built around one assumption: that a search results page is a stable, ordered list, and your job is to climb it.

    That assumption answers a narrow but useful question: where do we sit on page one for the terms we’ve chosen to watch? For years, that number was a fair proxy for visibility, because ranking well and getting seen were basically the same thing.

    They aren’t anymore. The overlap between what shows up in Google’s AI Overviews and what ranks in the organic top ten has dropped sharply, from roughly three-quarters down to somewhere between 17% and 54%, depending on the query set. A page one ranking no longer guarantees you show up where the answer actually gets read.

    Most rank trackers were built during an era when a search results page was a fixed grid, and a single crawl a day was enough to catch any real movement. That design still works well for its original job: telling a content team whether a new page is gaining or losing ground against a defined competitor set. It just wasn’t designed to look inside an AI-generated answer, because that answer isn’t a ranked list at all.

    What a GEO Visibility Checker Actually Answers

    A GEO visibility checker runs a different test entirely. Instead of tracking a position, it evaluates whether a brand gets mentioned, cited, or recommended when AI platforms answer a question, looking at signals like bot accessibility, structured data, and content that AI models can parse and trust.

    The question it answers is closer to: does AI bring us up at all, and how often? That’s a probabilistic outcome, not a fixed slot on a list. Repeated prompt runs on the same topic rarely return the same brand lineup in the same order, and fewer than 1 in 1,000 prompt runs produce an identical result. Rank, in the traditional sense, isn’t really the mechanism at play.

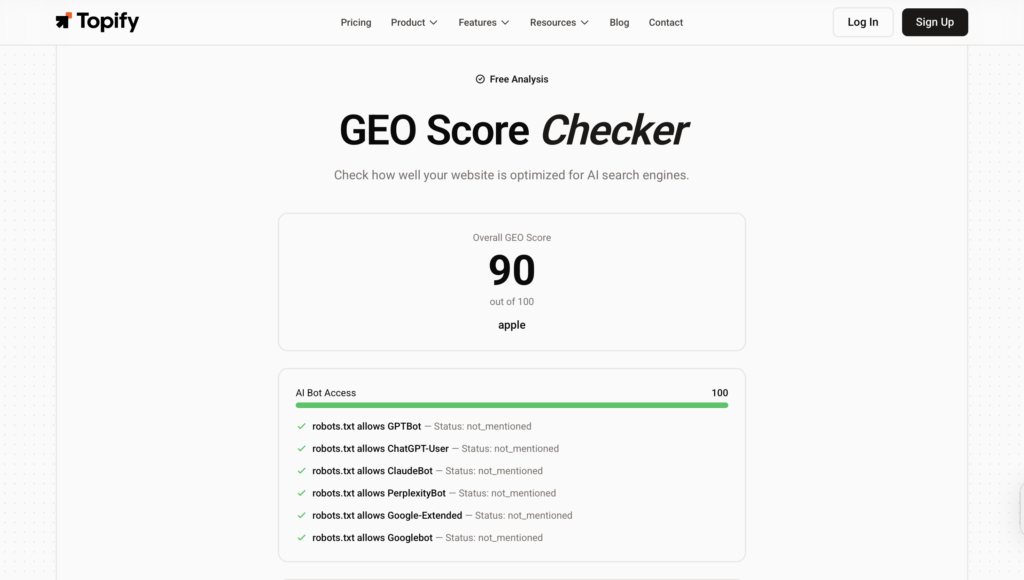
    You can check where your own site currently stands using Topify’s free GEO Score Checker, which takes under a minute and needs no signup. It’s worth running before deciding whether ongoing tracking is even necessary for your brand.

    The signals it’s reading are also different from a standard SEO checklist. Branded web mentions correlate far more strongly with AI Overview appearances than backlinks do, 0.664 compared with 0.218. That’s a meaningfully different set of levers than the ones most rank-tracking dashboards were ever built to show.

    A GEO score typically rolls up four separate signal groups rather than one number: whether AI crawlers and bots can actually access your pages, whether structured data exists for models to parse, whether the content itself answers the kind of question an AI would be asked, and how often your brand actually turns up across a sample of AI-generated answers. A weak result in any one group can drag the whole score down, even if the other three look fine, which is exactly why a single Google ranking can’t stand in for it.

    Side by Side: What Each Tool Actually Measures

    The clearest way to see the difference is to put both tools next to each other.

    Rank TrackerGEO Visibility Checker
    Core questionWhere do we rank for this keyword?Does AI mention or recommend us at all?
    Data sourceGoogle’s organic search resultsChatGPT, Perplexity, Gemini, Google AI Overviews, and similar
    Primary metricPosition, from #1 to #100Visibility score, citation rate, sentiment
    Update cadenceDaily or weeklyOne-time snapshot or continuous, depending on the tool
    What a good result meansYou appear near the top of a results pageYour brand shows up inside the answer itself

    Neither column replaces the other. A brand can rank first for its category and still be absent from every AI-generated answer on the same topic, and the reverse happens too.

    Why Teams End Up Needing Both

    Most teams still budget for only one side of that table. Only 14% of marketers currently track AI and LLM citation visibility, even though 43% already name AI search optimization as a core priority for the year.

    That gap between priority and practice is where visibility quietly leaks away.

    Teams that only run a rank tracker often miss the leak entirely, because the traffic numbers can look fine while brand credit disappears underneath them. A large share of AI brand mentions are what’s known as ghost citations, links that point to your site without naming your brand, and that pattern shows up in an estimated 73% of AI citations. You get the click. You don’t get remembered as the source.

    The opposite failure happens too. A team that runs one GEO check, sees a decent score, and stops there has no way to tell whether that score is improving, slipping, or getting overtaken by a competitor’s last content push. A snapshot is a fact about today. It isn’t a trend line.

    Picture a mid-size SaaS brand with stable page one rankings for its core keywords and a rank tracker dashboard that’s stayed green for months. Nobody on the team has a reason to look elsewhere. Then a competitor ships a round of structured FAQ content, starts showing up in ChatGPT’s answers for the exact category the brand thought it owned, and the first sign of trouble isn’t a ranking drop at all. It’s a sales rep noticing that a prospect mentioned a competitor’s name first, on a call where the brand’s own website ranked higher in Google the whole time.

    From a One-Time Score to Ongoing Tracking

    Once a GEO Score Checker confirms there’s a real gap worth closing, the next question is whether the work is actually paying off week over week. A single snapshot can’t answer that, because it has no memory of what your score looked like last month.

    This is the point where teams typically move from a free, point-in-time check to a dashboard that tracks visibility, sentiment, position, and citation source over time, across every major AI platform at once, rather than re-running a manual check on a recurring calendar reminder. Topify’s Comprehensive GEO Analytics is built for exactly that handoff: the same four signals the free checker samples once, monitored continuously, with alerts when a competitor starts showing up where you used to.

    The upgrade tends to pay for itself fast. Visitors who arrive through an AI citation convert at roughly 14.2% compared with 2.8% for standard search traffic, which means losing that channel quietly costs more than losing an equivalent amount of organic search traffic would.

    Conclusion

    A rank tracker and a GEO visibility checker were never meant to compete with each other. One tells you where you stand in a list of blue links. The other tells you whether an AI system chose to mention you at all. If your team only has an answer to the first question, run a free GEO score check this week and see how the second one looks.

    FAQ

    Q: Is a GEO visibility checker the same thing as a rank tracker? 

    A: No. A rank tracker measures your position in Google’s organic results for chosen keywords. A GEO visibility checker measures whether AI platforms mention, cite, or recommend your brand when answering a related question, which is a separate signal entirely.

    Q: Can I just use my existing rank tracker to cover AI search too? 

    A: Not fully. Some rank tracking platforms have added AI monitoring modules, but the underlying data source and metric are different from organic rank data, so a standalone GEO check still catches gaps a rank tracker’s dashboard won’t surface.

    Q: How often should I check my GEO visibility score? 

    A: A one-time check is a useful starting point, but AI answers shift as models update and competitors publish new content. Teams that treat AI visibility as a real channel typically move to continuous tracking rather than checking manually once and moving on.

    Q: What does a GEO visibility checker actually measure?

    A: It typically evaluates a mix of signals, including whether AI crawlers can access and parse your site, whether your content includes structured data AI models can read, and how often your brand appears across sampled AI-generated answers.

    Read More

  • Free GEO Checkers Compared: Where They Measure Differently

    Free GEO Checkers Compared: Where They Measure Differently

    You ran your site through three different free GEO checkers last week. One gave you a 41. Another said 78. The third didn’t score you at all, it just flagged twelve robots.txt lines and called it a day. None of them agreed on what “good” looks like, and the report you now have to explain to your team doesn’t tell a coherent story. That’s not because one tool is wrong. It’s because none of them are measuring the same thing.

    What a Free GEO Checker Actually Claims to Measure

    Most tools in this category test some mix of four signals: whether AI crawlers can reach your pages, whether your structured data is readable, whether your content carries authority signals, and whether you already show up in AI answers. The catch is that no two checkers weight these four the same way, and some only test one of them.

    Bot access alone is messier than it looks. A crawl across 1,744 sites found that 9.9% block GPTBot outright, and 13.7% block at least one AI crawler through robots.txt. A separate live-fetch test found the gap runs deeper than policy files suggest: on real page loads, GPTBot’s pass rate sits at 44.4%, a 33-point drop from a normal browser request. A checker that only reads your robots.txt file and one that actually fetches the page like a crawler would will often hand you two different verdicts on the same site.

    That’s the first place free tools disagree, and you haven’t even opened a dashboard yet.

    If you want to see where your own site lands on that layer without guessing which checker to trust, Topify‘s GEO Score Checker runs all four signals in one pass and returns a single snapshot in under a minute, no signup required.

    Quick Comparison: What Each Type of Free Checker Actually Scores

    Free GEO checkers generally fall into a handful of categories, and each one is built to answer a narrower question than “how visible am I to AI.”

    Checker TypeWhat It Actually ScoresWhat It Tends to Miss
    Bot-access scannersWhich AI crawlers are disallowed in robots.txtWhether the blocked bot is a training crawler or a live-answer bot, which changes the risk entirely
    Multi-platform site crawlersCitability across several AI platforms from a full site crawl, sometimes checking a dozen or more crawler types at onceDoesn’t separate live-fetch access from bulk training-crawl access, so the two get blended into one number
    Dashboard-style visibility checkersA per-model score alongside schema completeness and entity recognitionOne aggregated headline number can hide which specific platform you’re actually losing
    Workflow-embedded gradersStructural extraction and content-side signals, since these tools live inside content platforms built for writersWeak on the technical crawler-access layer, since that’s not what the tool was designed to catch
    Four-dimension composite checkersBot access, structured data, content authority signals, and platform visibility together, in one scoreNothing structurally, this is the category built to close the gap the others leave open

    None of these tools is measuring the same thing, so lining up two scores side by side is closer to comparing apples to crawler logs than comparing the same test twice.

    Where the Disagreements Actually Come From

    The first mismatch is crawler scope. A checker that reports on GPTBot and ClaudeBot, the bots used mainly for training, will show a different number than one that reports on ChatGPT-User and Claude-User, the bots used to answer a live question. In the same census of top sites, live-fetch bots were blocked at roughly a third the rate of bulk training crawlers. Two checkers that each measure “bot access” honestly can land on opposite conclusions about the exact same site, depending on which bot list they check.

    The second mismatch is schema depth. Some checkers grade structured data as a single completeness percentage. Others break it into FAQ schema, Organization schema, and product schema separately, then average unevenly across the three. A site with strong Organization markup and no FAQ schema can score high on one tool and mediocre on another, for the exact same page.

    That gap isn’t a bug in either tool. It’s two different definitions of “complete.”

    The third mismatch is platform weighting. A checker built around a single AI engine treats a gap on a different platform as a footnote. A checker built to test several platforms at once treats that same gap as a core finding. Since AI referral traffic and citation behavior vary sharply by platform, a tool that only samples one engine is, by design, blind to the others.

    From a One-Time Score to Continuous Monitoring

    A free checker answers one question: where do you stand today. It doesn’t tell you whether last month’s schema fix actually moved your visibility on a specific platform, or whether a competitor’s content update just pushed you out of an answer you used to own.

    CapabilityFree GEO CheckerTopify Platform
    Check frequencyOne-time snapshotContinuous monitoring
    Dimensions trackedBot access, schema, or visibility, rarely all four togetherFull GEO analytics plus sentiment and citation tracking
    Historical trendNoneFull trend history with alerts
    Competitor benchmarkingNot includedReal-time competitor tracking
    Platform breakdownAggregated or partialPer-platform, across ChatGPT, Perplexity, Gemini, and AI Overviews
    Optimization actionsDirectional guidanceSpecific, prioritized execution steps

    The checker tells you where you stand. Comprehensive GEO Analytics tells you which direction you’re moving, and why.

    Most teams run the free score first to confirm there’s a real gap worth closing, then start a free trial or check Topify’s pricing once they decide the gap needs ongoing attention rather than a one-time fix.

    Conclusion

    The scores disagree because the tools disagree on what to measure, not because one of them got your site wrong. A bot-access checker and a schema checker can both be accurate and still tell you completely different things. Use a free checker to establish your baseline, then decide whether the gap it found is a one-time fix or an ongoing drift. Run the free GEO checker once to see where you stand today, and treat that number as the reason to keep watching, not the end of the conversation.

    Frequently Asked Questions

    Why do free GEO checkers give different scores for the same website? 

    Each checker tests a different combination of signals, such as bot access, schema, or platform visibility, and weights them differently. A tool that only reads robots.txt will disagree with one that scores several AI platforms individually. Neither score is wrong, they’re measuring different layers of the same problem.

    Which free GEO checker should I trust? 

    No single one, on its own. A checker that covers bot access, structured data, content signals, and platform visibility together, like Topify’s GEO Score Checker, gives you one consistent baseline instead of stitching together three partial reports that don’t agree.

    How is a GEO score different from a traditional SEO score? 

    An SEO score typically measures keyword rankings and backlink authority in classic search results. A GEO score measures whether AI crawlers can access your content, whether your structured data is machine-readable, and whether AI platforms actually cite or recommend your brand in generated answers.

    What’s the real difference between a free checker and a paid GEO platform? 

    A free checker gives you a one-time snapshot. A platform like Topify tracks the same dimensions continuously, benchmarks you against competitors, and flags when your visibility shifts on a specific platform, instead of asking you to rerun a manual check every few weeks to catch drift.

    Read More

  • Free GEO Audit vs Paid Monitoring: What You Get at Each Stage

    Free GEO Audit vs Paid Monitoring: What You Get at Each Stage

    You ran a free GEO audit last week. The report gave you a score, flagged a couple of missing schema fields, and told you your brand showed up in three of ten ChatGPT answers. Then you closed the tab, because a single number doesn’t tell you if that score is climbing or sliding, or what to do about it on Monday morning.

    That gap between “here’s your score” and “here’s what changed and why” is exactly where most teams get stuck deciding if a one-time audit is enough, or if it’s time to pay for something that runs in the background.

    What a Free GEO Audit Actually Checks

    A free GEO audit is built to answer one question fast: how visible is your brand right now. Tools like Topify‘s GEO Score Checker run a single scan and return a score built from four signal groups: bot access, structured data, content signals, and current visibility. You get a number, a breakdown of what’s dragging it down, and a list of fixes, without creating an account.

    That’s genuinely useful as a starting point. It tells you whether AI crawlers can reach your pages, whether your schema markup is doing its job, and roughly where you stand against a baseline most brands have never bothered to check. For a team that hasn’t looked at AI visibility at all, that first scan is usually the moment the problem stops being abstract.

    Free doesn’t mean shallow, either. It just means the scan happens once, on demand, and stops there.

    Most free checkers on the market work the same way, whether they’re general SEO tools adding an AI layer or dedicated GEO products. You plug in a domain, the tool crawls it and runs a handful of prompts against one or two AI platforms, and you get a report back within a minute or two. No credit card, no login wall, no waiting on a sales call. That accessibility is the entire point. It’s designed to lower the barrier to the first data point, not to replace a reporting system.

    Where One-Time Audits Fall Short

    The catch is timing. A free audit captures a single moment, and AI answers don’t hold still the way a Google ranking does. Only about 30% of brands stay visible in back-to-back responses to the same query, which means the citation your audit caught on Tuesday can be gone by Thursday, and the report in your inbox won’t say so.

    A score tells you where you stood. It doesn’t tell you where you’re headed.

    Response patterns can shift within days, especially on Perplexity and Gemini, and teams relying on a single scan tend to notice a drop only after the fact, often weeks after it actually happened. Free tools reinforce this by design: even the ones that offer an ongoing tier usually cap prompt volume, refresh frequency, or engine coverage well below what a paid plan runs. That’s not a flaw. It’s the trade-off that keeps a free tool free.

    Engine coverage tends to be the second blind spot. A free scan usually checks one or two platforms, most often ChatGPT, and calls it done. But brand mentions on Perplexity, Gemini, and Google AI Overviews can move independently of each other, since each engine weighs citations and freshness differently. A brand that looks solid on a ChatGPT-only free scan can still be losing ground on Perplexity without anyone noticing, simply because nothing was watching that surface in the first place.

    Free GEO Audit vs Paid Monitoring: A Side-by-Side Look

    Laid out next to each other, the two approaches aren’t competing for the same job. One answers “where do I stand today,” the other answers “what’s changing and why.”

    DimensionFree GEO AuditPaid Monitoring
    Data freshnessOne-time snapshotRefreshed on a set schedule
    Platform coverageTypically 1 to 2 platformsChatGPT, Gemini, Perplexity, and others tracked in parallel
    Competitor trackingNot includedSide-by-side benchmarking
    Sentiment analysisNot includedTracked and trended over time
    Citation source trackingBasic overviewDomain-level source analysis
    Trend detectionNo history to compareWeek-over-week and month-over-month
    ReportingSingle PDF or score pageOngoing dashboard, exportable
    CostFreePaid plans, starting around $99/mo on Topify’s Basic tier

    The free column isn’t there to look weak. It’s there because most brands genuinely don’t need the paid column yet, and the table above is meant to help you tell which side of that line you’re on.

    What Paid Monitoring Adds: Continuous Visibility, Not a Snapshot

    Paid monitoring exists to answer the question a single audit can’t: what changed, and why. Comprehensive GEO Analyticstracks seven metrics side by side, visibility, sentiment, position, volume, mentions, intent, and CVR, so a drop in ChatGPT mentions can be traced back to the specific source that stopped citing your brand instead of staying a mystery.

    In practice, this turns AI visibility into a channel you report on the same way you’d report organic traffic or paid conversions. A marketing manager can pull up a trend line instead of re-explaining a single audit score in a meeting three months later. If your team has reached the point of needing that kind of reporting, you can get started with Topify directly from a live dashboard rather than rerunning a manual scan every few weeks.

    The seven-metric structure also matters for a reason that’s easy to miss. A visibility number on its own doesn’t tell you if AI is describing your brand accurately. Pairing it with sentiment and position data does, which is the layer a one-time audit was never built to capture.

    Picture the difference in a real week. With a free audit, you’d notice your visibility score dropped the next time you happened to run the scan, maybe a month later, with no clue what caused it. With ongoing monitoring, the same drop shows up the day it happens, tied to a specific prompt, a specific competitor gaining ground, and a specific source AI started citing instead of yours. One approach leaves you guessing. The other gives you a starting point for a fix.

    Signs You’ve Outgrown the Free Audit

    A few patterns tend to show up right before a team decides a free scan isn’t cutting it anymore.

    • More than one person on your team has asked “how are we doing in AI search,” and you keep rerunning the same free scan to answer them
    • You’ve noticed a competitor gaining ground in AI answers but can’t explain when it started or why
    • A client or exec wants a monthly AI visibility number, not a one-off report handed over once
    • Your last audit score moved and you have no way to tell which fix, if any, caused it

    A free audit can tell you what’s true today. It can’t tell you why it changed.

    None of these signs mean the free tool failed you. They mean the question you’re being asked has changed from “are we visible” to “what’s driving the trend,” and that second question needs a different kind of tool to answer.

    Conclusion

    A free GEO audit is the right first move for almost every brand. It’s fast, it costs nothing, and it turns a vague worry into an actual number you can act on. The point where it stops being enough is the point where you need to explain a trend instead of a single score, whether that’s to your own team or a client asking for proof.

    At that stage, moving from a one-time scan to ongoing monitoring isn’t about buying more features. It’s about matching the tool to the question you’re actually being asked.

    FAQ

    Q: How often should I run a free GEO audit? 

    A: Monthly at minimum. AI citation patterns can shift within days on platforms like Perplexity and Gemini, so a scan from three months ago tells you less than you’d think.

    Q: Can a free GEO audit replace paid monitoring for a small team? 

    A: For a team just getting started, often yes. Once you’re tracking competitors or reporting trends to stakeholders on a recurring basis, a one-time scan usually falls short.

    Q: Does the data from a free audit carry over when I move to paid monitoring? 

    A: In most cases, yes. Platforms that offer both, like Topify, use the same underlying signals for the free scan and the paid dashboard, so your first audit becomes a baseline rather than a throwaway report.

    Q: Is a GEO audit the same thing as ongoing AI visibility monitoring? 

    A: No. An audit is a single measurement taken at one point in time. Monitoring tracks that same measurement continuously and flags changes as they happen.

    Read More