Category: Comparisons

  • AEO Tools Compared: Tracking AI Answer Visibility

    AEO Tools Compared: Tracking AI Answer Visibility

    You open your SEO dashboard on Monday. Traffic looks fine. Then you ask ChatGPT the same question your customers ask, and your brand isn’t in the answer. Your competitor is.

    That gap is what AEO tools are built to close. Picking the right one is harder than it should be, because most comparison lists rank on the wrong things.

    Most AEO Tool Comparisons Rank on the Wrong Metrics

    If a tool tracks ChatGPT, Gemini, and Perplexity, the average comparison list calls it complete. That’s where the problem starts.

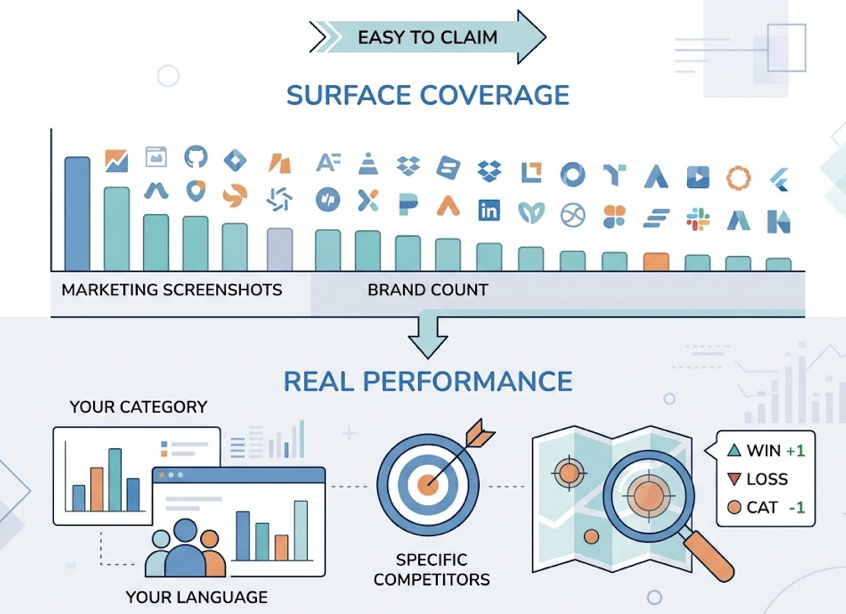
    Real differentiation lives in three places: the quality of the prompt set being tracked, the depth of source attribution behind each cited answer, and how fast the tool moves from observation to action.

    Surface coverage is easy. The number of brands that show up in a vendor’s marketing screenshots tells you almost nothing about how the tool performs in your category, in your language, against your specific competitors.
    Here’s what actually matters in 2026.

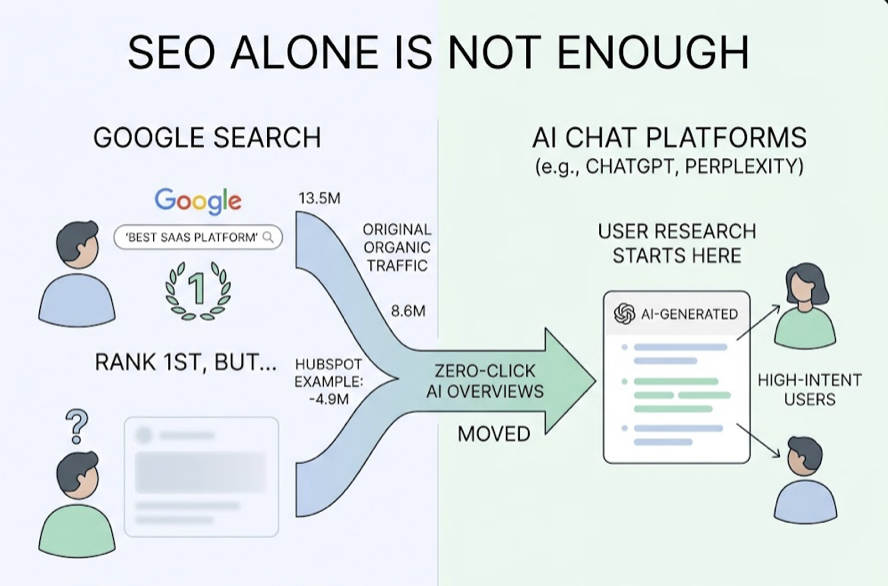
    When AI Overviews appear in a Google result, organic CTR drops from 1.76% to 0.61%, a 61% decline. Paid CTR drops harder, falling 68%. In Google’s AI Mode, the zero-click rate hits 93%. ChatGPT search runs at 98.7%.

    So traffic isn’t disappearing. It’s getting absorbed into answers. And the brands cited inside those answers see organic CTR 35% higher and paid CTR 91% higher than uncited brands.

    The job of an AEO tool is to tell you, in detail, which of those answers your brand shows up in, and why.

    AEO Tools at a Glance: Coverage, Pricing, Core Tracking

    Six platforms dominate the AEO conversation right now. Each solves a different shape of the problem.

    ToolAI Platforms CoveredStarting PriceCore StrengthBest Fit
    TopifyChatGPT, Gemini, Perplexity, DeepSeek, Doubao, Qwen + others$99/moMulti-language coverage, source analysis, agency-readyAgencies, cross-border brands, SaaS
    ConductorMajor LLMs + traditional searchCustomUnified SEO + AEO record-of-truthEnterprise teams
    Profound10+ engines including Grok, DeepSeek$99–399/moCompliance certifications, query fanoutHealthcare, finance, legal
    AthenaHQ8+ engines$295/mo + creditsUnlimited seats, Action CenterHigh-volume execution teams
    VismoreMajor LLMsCustom72-hour insight-to-publish loopTeams running many sites
    OmniaChatGPT, Perplexity, Google AIMid-marketPlain-English action plansSMBs without analysts

    Pricing tells half the story. The bigger split is execution philosophy: some tools stop at the dashboard, others push you toward an action.

    Topify: Full-Spectrum AEO Tracking Across Major AI Platforms

    Topify sits in a peculiar position. Its pricing starts at agency-friendly levels, but its tracking depth is closer to what enterprise platforms charge $500+ a month for.
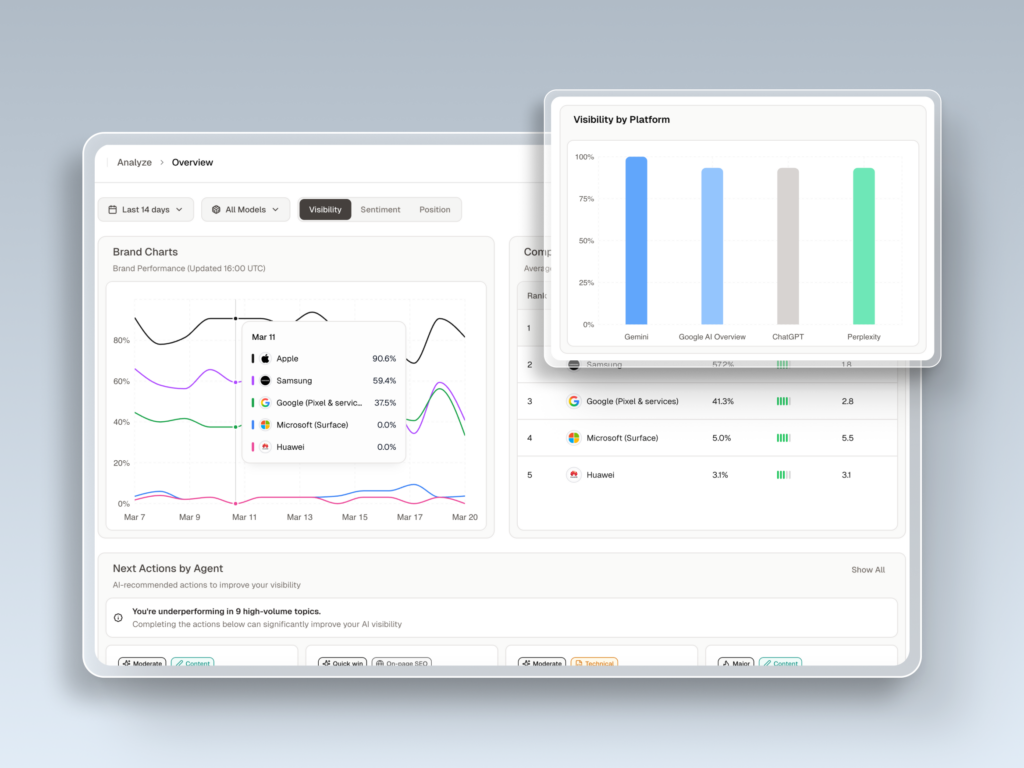
    The thing that stands out is coverage breadth. Topify monitors ChatGPT, Gemini, Perplexity, DeepSeek, Doubao, and Qwen. That list matters more than it looks. If your brand operates in any market where Mandarin or cross-border discovery is part of the funnel, Doubao and Qwen aren’t a nice-to-have. Most competing tools in this comparison don’t track them at all.

    Three capabilities define how Topify is actually used.

    Visibility tracking across seven metrics. Topify scores brand presence on visibility, volume, position, sentiment, mentions, intent, and conversion visibility rate (CVR). The CVR metric is unusual. It estimates how likely an AI mention is to translate into downstream interaction, rather than treating every mention as equal. A neutral fact-mention and a positive recommendation get weighted differently.

    Source analysis. When AI engines cite something, Topify reverse-engineers the URL behind the citation. Was it a Reddit thread? A G2 review? A trade publication? Industry research suggests citations from third-party domains carry roughly 6.5x the weight of self-published content. Knowing where AI is pulling from is where the optimization budget should go.

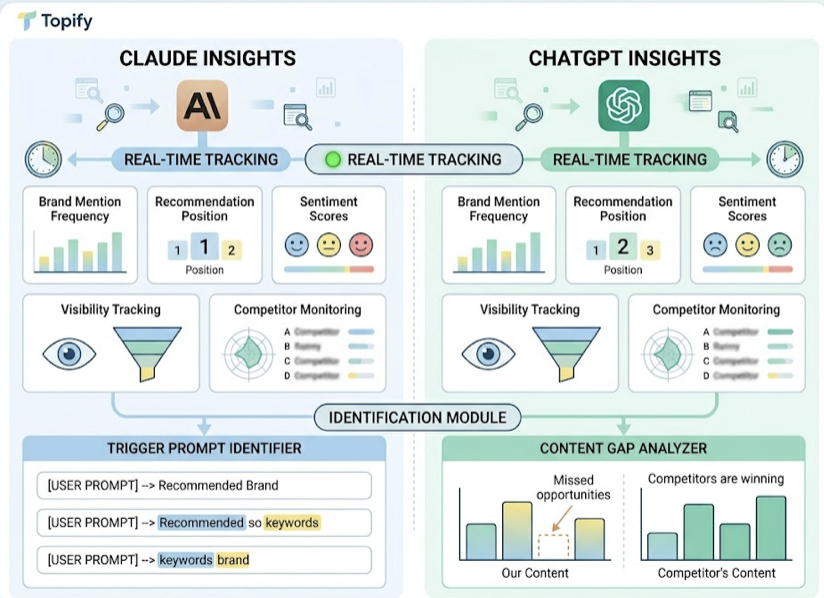
    Competitor monitoring. Topify auto-detects which brands AI engines surface alongside yours and tracks their position, sentiment, and citation share over time.

    That’s the dashboard side. The piece that matters for time-strapped teams is execution. Topify’s One-Click Execution lets you state a goal in plain English, review a proposed strategy, and deploy without a manual workflow.

    Pricing runs $99/mo for the Basic tier (100 prompts, 4 projects, 4 seats), $199/mo for Pro (250 prompts, 8 projects, 10 seats), and $499/mo+ for Enterprise with a dedicated account manager.

    For agencies, the multi-project architecture is what closes the deal. You’re not rebuilding a prompt set every time a new client signs.

    What Topify Tracks That Most Tools Don’t

    Two things, really.

    The Mandarin-language AI ecosystem (Doubao, Qwen, DeepSeek) is invisible to most Western AEO tools. If your brand has any APAC exposure, that gap is where you’re losing visibility you didn’t know you had.

    And the closed loop between visibility data and content execution. Most AEO tools tell you what’s happening. Topify generates the strategy and pushes it live.

    Other AEO Tools Worth Knowing

    Each of the following solves a specific shape of the problem. None replaces another cleanly.

    Conductor is built for enterprises that need a single source-of-truth across SEO and AEO. Its AgentStack lets teams pull search intelligence directly inside ChatGPT, Claude, and Copilot. The Content Agent claims an insight-to-publish window of under two minutes. The trade-off is custom enterprise pricing, which puts it out of reach for smaller teams.

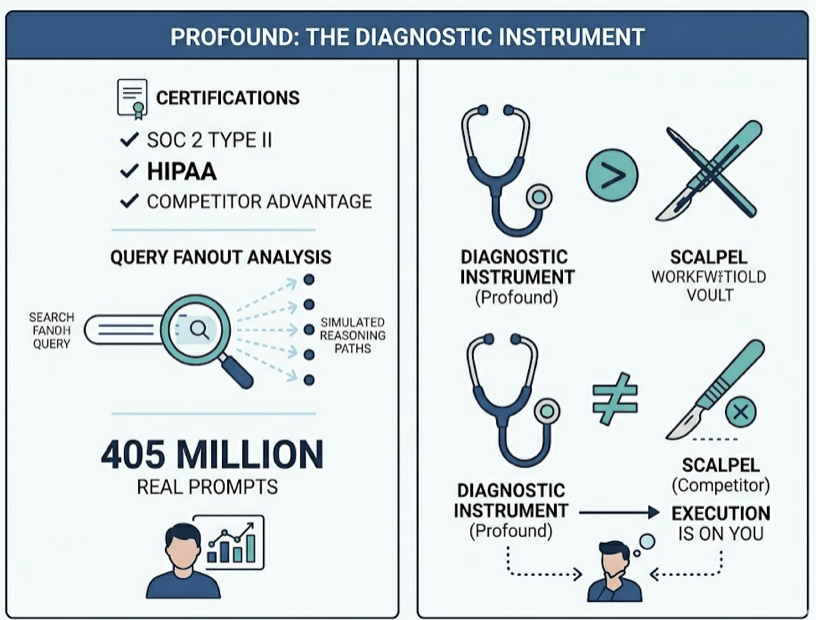
    Profound is the tool of choice for regulated industries. It carries SOC 2 Type II and HIPAA certifications, which most competitors don’t have. Its Query Fanout Analysis simulates the reasoning path AI engines take before generating an answer, going deeper than surface citation counts. The platform analyzed over 405 million real prompts to build its baseline. The limitation: Profound is a diagnostic instrument, not a scalpel. It tells you what’s wrong; execution is on you.
    AthenaHQ sells on unlimited scale: unlimited seats, unlimited response analyses, no cap on data history. Its Action Center converts visibility data into specific instructions, namely which pages to update, which keywords to build pillars around, and which third-party sites to pursue for citations. Pricing runs $295/mo plus credit-based usage.

    Vismore is built for teams managing dozens or hundreds of sites. The grid-style UI handles bulk visibility tracking, and its 72-hour insight-to-publish loop pushes content directly to Reddit, Medium, or LinkedIn. Those are the surfaces where industry data shows AI citations are 6.5x more likely to land than on owned domains.

    Omnia simplifies. It tracks ChatGPT, Perplexity, and Google AI features, then turns the data into an impact-ranked action plan. Users report AI engine traffic gains of 30 to 45% within weeks of implementing its recommendations. For SMBs without a dedicated analyst, that simplicity is the feature.

    How to Pick the Right AEO Tool for Your Stack

    The honest answer: it depends on where you’re losing visibility, not which tool has the most features.

    If you’re a single brand operating mostly in English, Omnia or AthenaHQ will give you a fast read on the gap. Both are designed to surface action items without requiring deep AEO fluency.

    If you’re an agency managing multiple clients, Topify‘s multi-project architecture and source-attribution depth are hard to beat at the price. The 30-day trial covers ChatGPT, Perplexity, and AI Overviews tracking, which is enough to validate the workflow before committing.

    If you’re a cross-border brand, or your audience touches Mandarin-speaking markets, Topify is the only platform in this comparison that natively tracks Doubao, Qwen, and DeepSeek alongside Western AI engines.

    If you operate in healthcare, finance, or legal, Profound’s compliance posture isn’t optional. Its query fanout analysis is also genuinely the deepest semantic diagnostic on this list.

    If you’re an enterprise marketing team that needs to merge SEO and AEO into a unified record, Conductor is built for that workflow.

    A common mistake: picking the tool with the most features. Most teams use 20% of the dashboard and pay for the other 80%. Start with the prompt set that matches how your customers actually search, then pick the tool that tracks that set with the most depth.

    Conclusion

    AEO tools don’t differ much in whether they can track AI answers. They differ in what they track, how deeply, and what they let you do next.

    Coverage breadth matters. Source attribution matters more. Execution speed is what closes the loop.

    If you’re picking one tool to start with, Topify gives you a low-risk place to begin: multi-language coverage, source analysis depth, and agency-friendly pricing in one platform. Tools like Conductor and Profound are worth adding once your AEO operation matures into a category-specific or compliance-driven need.
    The brands that win in 2026 won’t be the ones running the most prompts. They’ll be the ones acting on what those prompts reveal.

    FAQ

    What is an AEO tool, and how does it differ from SEO software?

    An AEO tool tracks how AI engines like ChatGPT, Perplexity, and Gemini mention your brand in their generated answers. SEO software tracks rankings on traditional search results. The two are related but measure different things. AEO is about citation share inside AI responses, not link position on a results page.

    Which AI platforms should an AEO tool track?

    At minimum: ChatGPT, Gemini, and Perplexity. If your audience touches Mandarin-speaking markets or cross-border ecommerce, add DeepSeek, Doubao, and Qwen. The brands losing visibility silently are usually losing it on engines no one is measuring.

    How accurate is AI answer visibility tracking?

    It depends on the methodology. API-based tools pull data directly from LLM endpoints, which produces more stable results than scraping-based tools. Even so, AI answers are probabilistic. The same prompt can return different citations across requests. Reputable AEO tools run multiple samples and average the results.

    Can AEO tools track competitor mentions in ChatGPT?

    Yes. Tools like Topify auto-detect competitor brands in tracked prompts and show their visibility, sentiment, and position over time. The depth varies. Some tools show which competitors appear, others explain why.

    What does an AEO platform typically cost in 2026?

    Entry-level plans for individual brands start around $99/mo. Mid-market platforms run $200 to $500/mo. Enterprise platforms with custom integrations and dedicated support typically start at $499/mo and go up from there. Per-prompt pricing is common at the higher tiers.
    Read More

  • AEO vs SEO: Why AI Search Changed the Rules

    AEO vs SEO: Why AI Search Changed the Rules

    As AI engines replace traditional search for millions of queries, brands that optimize only for Google are becoming invisible where it matters most.

    You’ve built a solid SEO strategy. Your brand ranks on page one. Traffic holds steady in Google Search Console. And then someone asks ChatGPT for the best tool in your category. Your name doesn’t come up once.

    That’s not a fluke. It’s a structural problem.

    The rules of digital visibility have split into two separate games. Search Engine Optimization was built to win one of them. Answer Engine Optimization (AEO) is what you need to win the other. Right now, most brands are only playing one.

    Google Ranks Pages. AI Engines Pick Winners.

    Traditional SEO was built around one idea: get indexed, get ranked, get clicked. The logic made sense for two decades. Google’s algorithm rewarded keyword relevance, backlink authority, and technical compliance. Check the right boxes, move up the list.

    AI search engines work differently. When someone asks ChatGPT or Perplexity a question, the engine doesn’t return a list of links. It synthesizes an answer and cites the sources it trusts most. The question shifts from “who ranks highest?” to “who does the AI choose to quote?”

    That’s a fundamentally different optimization problem.

    Logic ComponentTraditional SEOAEO
    Primary GoalRank at the top of a results listBe the cited source in a synthesized answer
    Core MetricClicks, impressions, SERP positionCitation share, brand mentions, sentiment
    Optimization FocusKeyword density, backlink volumeSemantic clarity, entity structure, consensus
    Authority SignalDomain Authority, PageRankFactual accuracy, E-E-A-T, cross-platform proof
    User InteractionSearch → Click → Website visitQuestion → Direct AI response → Brand trust

    The algorithm didn’t just change. The object you’re optimizing for changed.

    The Overlap Number That Should Worry Every Marketing Team

    Here’s a concrete data point to anchor this shift.

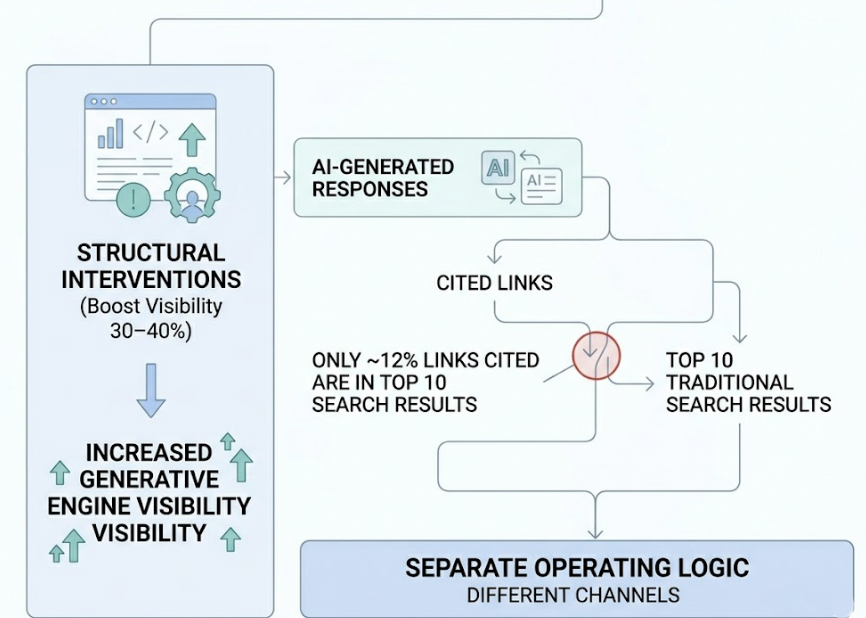
    In 2024, roughly 70% of URLs appearing in AI citations also showed up in Google’s top 10 results. By 2026, that overlap has collapsed to under 20%. For ChatGPT specifically, the URL overlap with Google’s top 10 is down to 8%. For Gemini, it’s 6%.

    A brand with strong Google rankings has, at best, a single-digit probability of appearing in AI-generated answers on those platforms.

    Only Google’s own AI Overviews maintain a high correlation at 76%, because they’re designed to summarize the existing search index. Every other major AI engine has effectively built its own citation logic, independent of where you rank on Google.

    Zero-click searches now exceed 65% in many categories. Users get their answer directly from the AI and never visit a page. If you’re not the cited source, you don’t exist in that interaction.

    What AEO Actually Optimizes For (It’s Not Keywords)

    AEO isn’t about feeding keywords to a crawler. It’s about making your brand the most extractable, trustworthy source available when an AI builds its answer.

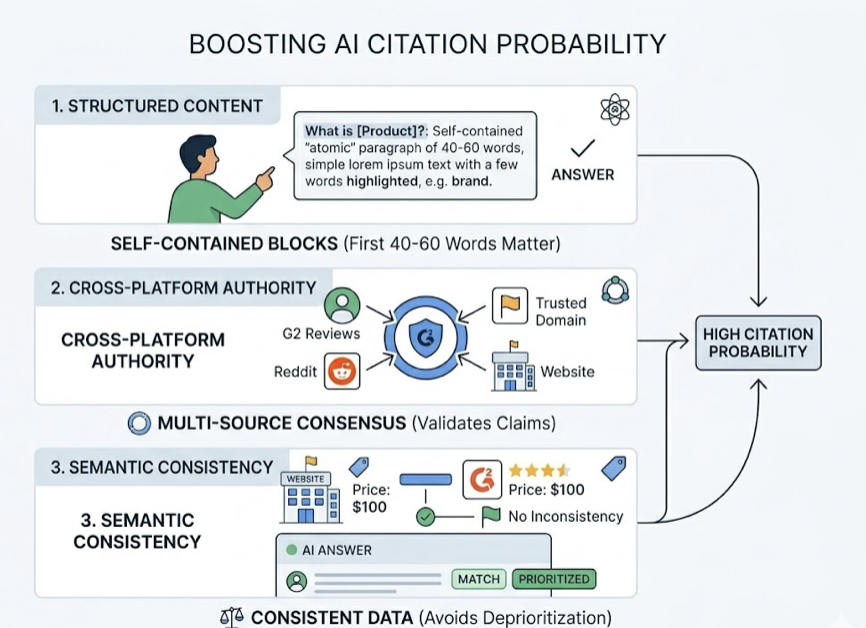
    Three things drive citation probability. First, structured content: AI models prefer “atomic” paragraphs broken into self-contained blocks that answer one question without requiring surrounding context. The first 40-60 words of any section are often decisive. Second, cross-platform authority: AI engines use multi-source consensus to validate claims. If multiple trusted domains, G2 profiles, Reddit threads, and industry publications all point to the same factual claim about your brand, citation probability rises. Third, semantic consistency: if your pricing on your website contradicts what’s on a review platform, an AI model will flag the inconsistency and deprioritize your brand.

    AEO doesn’t replace SEO. It sits on top of it. Without a solid technical foundation, AI engines won’t trust your site enough to cite it in the first place.

    Why Your Google Rank Doesn’t Transfer to ChatGPT

    This is where a lot of marketing teams hit a wall. The SEO investment they’ve built over years feels like it should count for something in AI search. Often, it doesn’t, and here’s the mechanism behind that.

    Traditional search uses vector-based keyword matching and link-based authority scores. AI search uses Retrieval-Augmented Generation (RAG): the model retrieves chunks of text from multiple sources, performs consensus validation, and synthesizes a response. If your content lacks clear entity signals and third-party corroboration, the AI retriever skips it, regardless of your Google ranking.

    AI models also carry biases that SEO was never designed to address. Perplexity prioritizes content updated within the last 30 days, regardless of organic ranking. Narrative-heavy content, the standard in traditional SEO, is often passed over in favor of reference-style content with a higher ratio of facts to words.

    There’s also a blind spot many brands discover too late: some inadvertently block AI crawlers like GPTBot and PerplexityBot in their robots.txt file while allowing Googlebot. Their site is technically invisible to the very models they most need to influence.

    What the Princeton Data Says About AEO Techniques That Actually Work

    The first peer-reviewed evidence came from a landmark Princeton University study titled “Generative Engine Optimization,” which introduced a benchmark called GEO-bench to measure how specific content changes affect citation rates.

    The results were unambiguous.

    AEO TechniqueVisibility IncreaseWhy It Works
    Cite Sources+115.1%Shows the AI where the claim came from
    Expert Quotations+41.0%Signals authority through named provenance
    Add Statistics+37.0%Converts vague claims into extractable facts
    Keyword StuffingNegativePenalized as low information-gain content

    Citing credible external sources more than doubled citation probability for brands originally sitting in the 5th position on search results. The AI effectively rewards a scholarly approach to content over a traditional marketing approach.

    Keyword stuffing, the defining tactic of early-2000s SEO, was the single least effective method and in some cases actively reduced visibility below non-optimized baseline content.

    That’s not a subtle difference. That’s a complete reversal of what used to work.

    The Brand That Cracked AEO First

    In the project management software category, Asana scores 12/12 across multi-platform AI visibility tests. Monday.com follows at 11/12. ClickUp at 10/12.

    These aren’t just well-known brands. They’ve built content architecture that AI engines specifically prefer.

    Asana maintains what analysts call a “Comparison Hub”: dedicated, structured pages for every major competitor. These pages aren’t marketing copy. They’re organized around the exact entities and relationships AI systems look for, including features, integrations, pricing, and category definitions. The AI retriever finds a clean, extractable chunk and cites it.

    ClickUp earns citations by positioning itself as the source of truth for the entire category, not just its own product. A Perplexity recommendation for ClickUp often points directly to a ClickUp blog post titled “Top 10 AI Tools for Startups.” The brand trained AI engines to see it as a category authority, not just a vendor.

    82-85% of citations in AI responses come from third-party sources. Your own website, no matter how well-optimized, is only part of the equation. Perplexity alone pulls 46.7% of its citations from Reddit and community forums. Winning at AEO means winning on platforms you don’t own.

    How to Know If You Have an AEO Visibility Problem Right Now

    Three questions cover most of the diagnostic work.

    When you ask ChatGPT or Perplexity for a recommendation in your category, does your brand appear? If not, you have a visibility gap. When your brand is mentioned, is your own domain cited as the source, or is the AI pulling from a competitor’s blog or a third-party review? If it’s the latter, you have a citation authority problem. Are your competitors appearing in AI responses for your highest-intent queries while you’re absent?

    The challenge is that traditional SEO tools can’t answer these questions. Google Search Console doesn’t track whether ChatGPT recommended your brand today.

    Topify was built for exactly this layer. It tracks brand visibility across ChatGPT, Perplexity, Gemini, and other major AI platforms, using a methodology called Synthetic Probing to run thousands of query variations and calculate a statistically significant Share of Voice. Instead of guessing, you get a number.

    Topify’s Source Analysis goes further. It reverse-engineers which URLs AI engines are actually citing when they mention your category. If a competitor keeps appearing because of a specific Reddit thread or a niche industry listicle, Topify surfaces that source directly. Passive monitoring becomes active competitive intelligence.

    For teams that need to act quickly, Topify’s One-Click Execution lets you define AEO goals in plain English and deploy a strategy without manual workflows. New or refreshed content can enter AI citation pools in as little as 3-5 days, compared to 3-6 months for Google ranking movement.

    That’s the gap, spelled out in time: weeks vs. months.

    Conclusion

    SEO isn’t dead. It’s still the foundation. But it’s no longer sufficient.

    The brands that will lead the next five years aren’t just optimizing for keywords. They’re optimizing for answers. They’re structuring content for extraction, building authority across platforms they don’t own, and measuring visibility where their customers are actually asking questions.

    AEO is not a future trend. It’s the current playing field.

    Start by measuring. Check whether your brand appears when an AI gets asked about your category. If it doesn’t, you now know why, and you know what to fix.

    FAQ

    Is AEO the same thing as GEO?

    They’re closely related but not identical. AEO (Answer Engine Optimization) is the broader practice of structuring content for direct answers across search assistants, featured snippets, and AI chatbots. GEO (Generative Engine Optimization) is a more specific subset, popularized by the Princeton study, focused on earning brand citations within narrative summaries generated by LLMs like ChatGPT and Perplexity.

    Do I still need SEO if I’m doing AEO?

    Yes. AEO doesn’t replace SEO; it extends it. Without a strong technical SEO foundation, AI engines won’t trust your site enough to cite it. Think of SEO as the prerequisite and AEO as what you build on top.

    How long does AEO take to show results?

    Faster than most teams expect. New or refreshed content can enter AI citation pools in 3-5 days. Brands tracking their AI visibility with platforms like Topify have reported measurable lifts in AI mentions within weeks, not months.

    Which AI platforms should I prioritize first?

    It depends on your audience. For B2B SaaS, Perplexity and ChatGPT are the highest-leverage platforms: they’re used heavily for vendor research and shortlist building. For local businesses, Google AI Overviews and Gemini matter most because of their integration with local search and maps.

    What’s the single highest-ROI AEO change a brand can make today?

    Based on the Princeton research, adding credible citations to your existing content delivers the highest lift (+115.1% citation rate increase). It doesn’t require a full content overhaul. Pick your five most important category pages and add external references to every major factual claim.

    Read More

  • AEO vs GEO vs SEO: What Marketers Get Wrong

    AEO vs GEO vs SEO: What Marketers Get Wrong

    Your Google rankings are solid. Your content calendar is consistent. Your domain authority keeps climbing. Then a potential customer opens ChatGPT, types “best tool for [your category],” and gets a confident five-item list. Your brand isn’t on it.

    That’s not an SEO problem. It’s a signal that SEO and AI search operate on different logic entirely. And most marketers don’t realize there are now two distinct disciplines sitting above SEO: AEO and GEO. They’re not synonyms, and confusing them leads to wasted effort.

    Three Terms, Three Different Jobs

    The fastest way to understand these three disciplines is by what each one is actually trying to accomplish, not how they’re defined in a blog post.

    DimensionSEOGEOAEO
    Target PlatformGoogle, Bing, YahooChatGPT, Gemini, Perplexity, ClaudeVoice assistants, Featured Snippets, AI Overviews
    Optimization ObjectWebpages and domain authorityCitations, brand mentions, narrative synthesisDirect answers, “Position Zero,” extractable facts
    Primary LogicLexical and technical relevanceRecommendation and brand authorityImmediate information extraction
    Success MetricOrganic traffic, SERP rank, CTRCitation frequency, Share of Model, brand sentimentFeatured answer wins, voice search selection, zero-click impressions

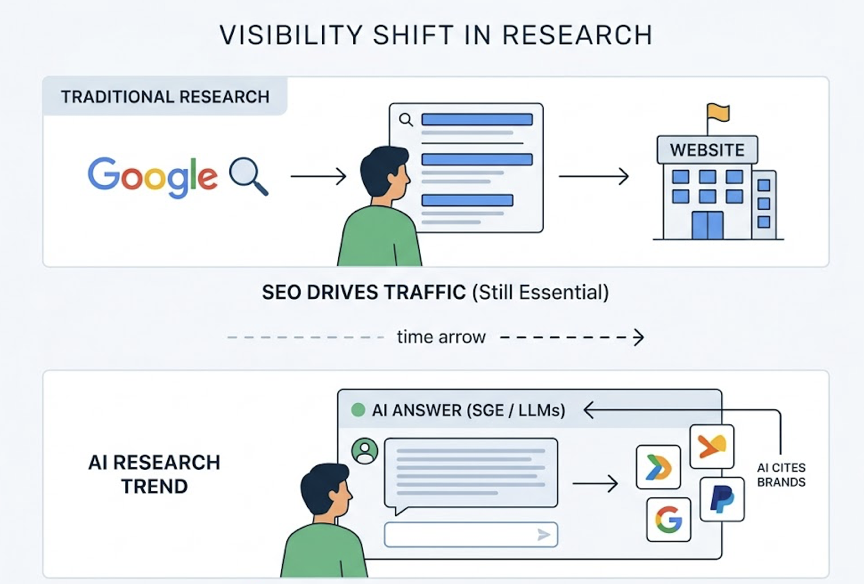
    These aren’t competing strategies. They’re layers. SEO gets you found during deep research. AEO makes you the immediate answer to a direct question. GEO makes you the trusted recommendation inside a longer AI-generated response.

    Get the layer wrong and you’re optimizing for an outcome you weren’t even targeting.

    SEO Is Still Alive. Just Not in the Room It Used to Own.

    Traditional SEO hasn’t died. But its territory has shrunk.

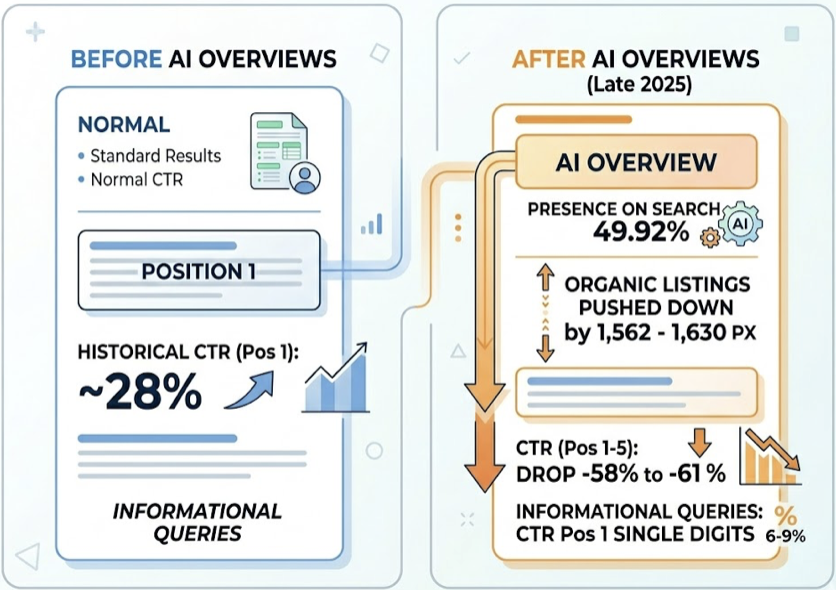
    By late 2025, AI Overviews were appearing on nearly 49.92% of all search results, pushing traditional organic listings down the page by an average of 1,562 to 1,630 pixels. For positions 1 through 5, click-through rates dropped 58% to 61%. Before AI Overviews, position 1 historically captured around 28% of clicks. That number has been cut to single digits for informational queries.

    Zero-click searches climbed from 56% to 69% between 2024 and 2025. Users are finding sufficient answers in AI-generated summaries and stopping there.

    SEO still matters. But its role has shifted. In 2026, ranking in the top 10 isn’t the final destination. It’s the entry requirement to be considered as a source for AI citation. About 92.36% of AI Overview citations come from domains already ranking in the top 10. If you’re not ranking, you’re not even in the pool.

    That’s the boundary. SEO gets you into the pool. GEO and AEO determine whether you get picked.

    GEO Is What Happens When AI Generates the Answer

    Generative Engine Optimization works differently from anything SEO practitioners are used to.

    In a traditional SEO model, the machine indexes your page and ranks the URL. In a GEO model, the AI doesn’t send users to your page. It reads a passage, evaluates its credibility against other sources, and writes your brand into a synthesized response. The “win” isn’t a click. It’s a citation, a mention, or a narrative inclusion.

    Here’s what makes GEO operationally different:

    Entity consistency beats keyword density. AI systems don’t see websites; they recognize entities. Your brand name, description, service category, and positioning need to be identical across every surface the AI encounters: your blog, LinkedIn, Reddit, G2, industry publications. Inconsistency fragments the AI’s understanding of what you are and breaks the trust required for citation.

    Structured content gets cited 2.8 times more often. Clear headings, bullet lists, and comparison tables reduce what researchers call “information friction.” An AI model parsing your content to form a response prefers content that’s already organized for extraction.

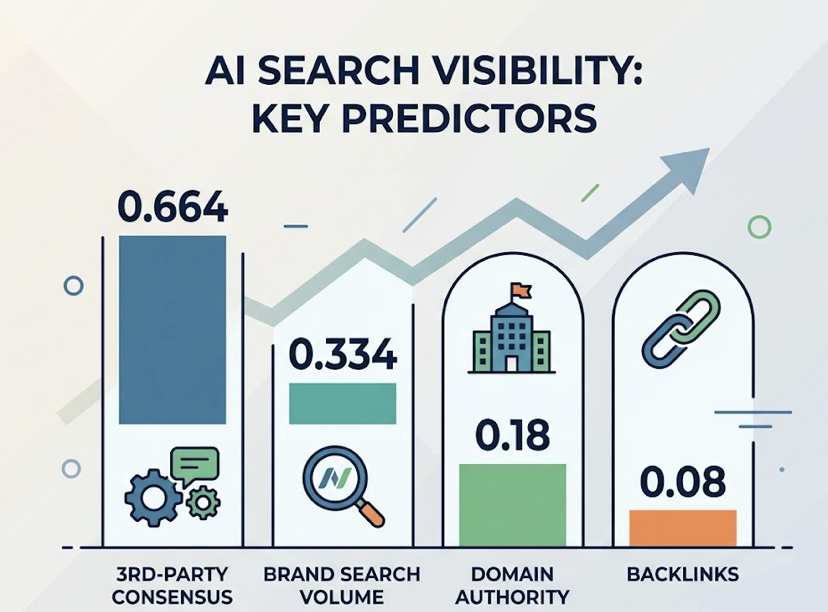
    Third-party mentions drive model confidence. A Princeton study found that brand search volume has a 0.334 correlation with model confidence in recommendations. GEO isn’t just an on-page strategy. It’s an ecosystem play. Earned media, community engagement on Reddit and Quora, and consistent third-party reviews all feed the AI’s recognition logic.

    GEO is also probabilistic. You’re not winning a single slot. You’re increasing the likelihood that your brand appears somewhere in a longer response, alongside competitors, when users ask complex multi-step questions.

    AEO Isn’t GEO with a New Name

    This is where most marketers lose the thread.

    AEO, Answer Engine Optimization, has the same target audience as GEO (AI-mediated queries) but a completely different goal. GEO wants your brand to be the recommendation. AEO wants your content to be the answer.

    That’s a different optimization target entirely.

    AEO is binary. You either win the answer slot, the featured snippet, the voice assistant response, or you lose it. There’s no partial credit. It’s designed for direct factual queries: “What is AEO?” “How does [product category] work?” “What’s the difference between X and Y?”

    The content requirements reflect this:

    • Answer placement in the first 40-60 words. AI systems extracting a direct answer don’t scroll. The answer needs to be in the opening of the section, not buried three paragraphs in.
    • Schema markup for extraction signals. FAQPage and HowTo schema explicitly tell machines where the answer lives.
    • Simpler sentence structures. A Flesch readability score of 60-70 reduces the risk of AI models misinterpreting context during summarization.

    AEO targets voice assistants (Alexa, Siri), Google’s featured answer boxes, and the zero-click response at the top of an AI Overview. GEO targets ChatGPT, Gemini, and Perplexity when users are doing multi-step conversational research.

    Different platform. Different query type. Different content strategy.

    Where They Overlap and Where They Don’t

    All three disciplines share a technical foundation. Fast load speeds, mobile responsiveness, and strong E-E-A-T signals (Experience, Expertise, Authoritativeness, Trustworthiness) are table stakes across the board.

    The divergence starts in how you research, what you produce, and how you measure results.

    OperationSEO FocusGEO FocusAEO Focus
    ResearchKeyword volume and difficultyConversational promptsQuestion intent: How, Why, What
    ContentPage-level depthPassage-level synthesisConcise fact extraction
    TechnicalSite speed, XML sitemapsRobots.txt / LLMs.txt accessFAQ / HowTo schema
    MonitoringGoogle Search Console rankingsAI citation frequencyAnswer slot ownership
    AuthorityBacklinks, domain ratingThird-party reviews, entity mentionsNiche expertise, featured snippets

    The critical shift is in monitoring. SEO results are visible in Google Search Console. GEO and AEO performance happens in the “black box” of AI models. You don’t see it in your analytics unless you’re explicitly tracking it.

    80% of LLM citations come from sources that don’t rank in the top 100 for the original keyword. That statistic matters because it means GEO and SEO authority are decoupled. You can rank on page one of Google and still be invisible to ChatGPT. You can be cited frequently by Perplexity and barely appear in Google’s top 50.

    These are different ecosystems, even when they intersect.

    What This Means for Your 2026 Strategy

    The right allocation depends on where your audience’s decision-making process actually happens.

    If your category’s users still rely primarily on Google for research, SEO remains the priority. But ignoring GEO is a compounding risk: the more queries shift to conversational AI, the more invisible you become to users in the research phase, even while your Google rankings hold steady.

    If your category is in SaaS, B2B, or complex e-commerce, AEO and GEO are no longer experimental channels. They’re core brand visibility strategy. Visitors arriving from AI recommendations convert at 14.2%, compared to the 2.8% benchmark for traditional organic traffic. That conversion gap alone justifies the resource allocation.

    The challenge is measurement. Traditional analytics tools weren’t built to track AI citations. There are no impressions logged when ChatGPT mentions your brand. No click recorded when Gemini recommends your product. The same brand can experience a 46-fold gap in citation rates across different AI platforms, meaning high visibility on one model and near-zero visibility on another, with no signal of that gap in your existing dashboards.

    Topify addresses this directly by monitoring brand presence across ChatGPT, Perplexity, Gemini, Claude, and DeepSeek simultaneously. It tracks the seven metrics that matter for AI visibility: visibility, sentiment, position, volume, mentions, intent, and Conversion Visibility Rate (CVR). When the system identifies an answer gap, a scenario where a competitor is being recommended and your brand is invisible, it can surface the specific sources the AI is using to form that response and flag where the citation chain breaks down.

    For teams that have been optimizing for SEO alone, this level of visibility is genuinely new information. It answers the question your current toolset can’t: not “how does Google see us,” but “what does AI say about us, and why?”

    Conclusion

    SEO, GEO, and AEO aren’t three names for the same discipline. They target different platforms, serve different query types, and require different operational focus. Treating them as interchangeable is how brands end up with strong Google rankings and zero presence in AI-generated recommendations.

    In 2026, the marketers with the clearest path forward aren’t abandoning SEO. They’re building the two layers above it. Start by understanding which of your audience’s queries are already being resolved by AI, then map those to the discipline that governs that answer slot. The brands winning in AI search aren’t doing more SEO. They’re doing a different kind of work entirely.


    FAQ

    Q: Is AEO just another word for GEO?

    A: No. Both target AI-mediated queries, but AEO focuses on providing the answer itself through direct extraction, while GEO focuses on earning brand mentions within a synthesized narrative. AEO targets voice assistants and featured snippets. GEO targets LLM-driven chat and summaries. The content format, target platform, and success criteria are all different.

    Q: Do I need to choose one or run all three?

    A: The modern strategy runs all three simultaneously. They’re layers, not alternatives. SEO builds the trust foundation and keeps you in the citation pool for AI Overviews. AEO captures users seeking direct answers. GEO captures users engaged in multi-step conversational research. Skipping any layer creates a visibility gap somewhere in the user journey.

    Q: How do I know if my brand shows up in AI answers?

    A: Standard analytics won’t tell you. AI citations don’t generate trackable clicks or impressions in Google Search Console. You need a tool built specifically to run automated simulations across LLM APIs and record brand mentions, sentiment, and citation frequency. Platforms like Topify track this across multiple AI models simultaneously and surface the sources driving or blocking your AI visibility.

    Q: My SEO rankings are strong. Does that mean my GEO is strong too?

    A: Not necessarily. While about 92.36% of AI Overview citations come from top-10 domains, general LLM citation logic is more decoupled from traditional rankings. Research shows 80% of LLM citations come from sources that don’t rank in the top 100 for the original keyword. Strong SEO authority is a useful signal, but it doesn’t guarantee AI visibility across ChatGPT, Gemini, or Perplexity.


    Read More

  • G2 AEO Tools Compared: Topify vs Profound vs AirOps vs Otterly

    G2 AEO Tools Compared: Topify vs Profound vs AirOps vs Otterly

    G2 now lists 248 products in the AEO category. That number grew from just 7 tools in early 2025, a jump of over 2,000% in under a year. If you’ve tried to shortlist options on the platform recently, you already know the problem: the category is too crowded to evaluate by browsing.

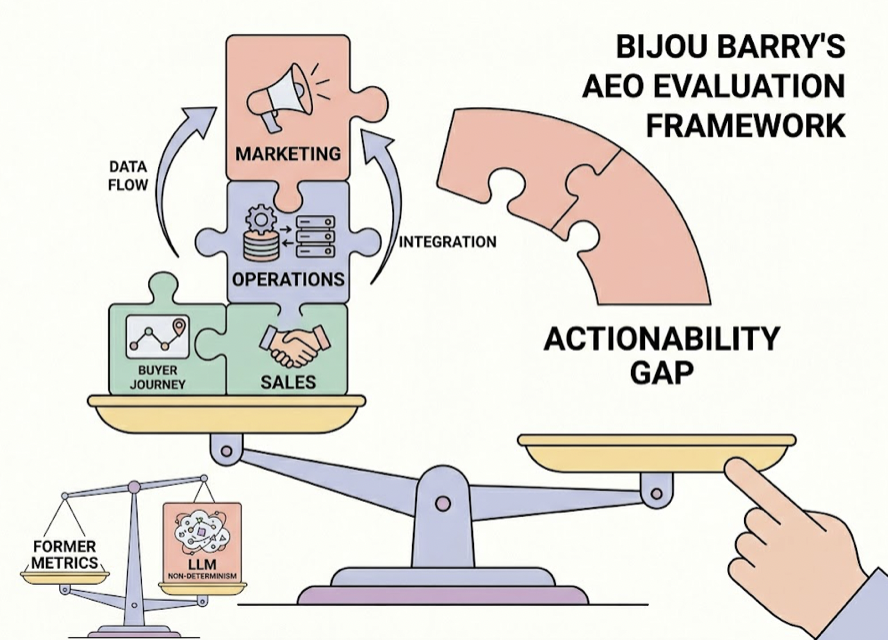
    Here’s the shortcut most buyers miss. G2’s AI Principal Analyst, Bijou Barry, has already mapped out how to evaluate this category. Her framework breaks AEO tools into three buyer dimensions: Marketing (category positioning and content visibility), Operations (integrating AEO data into the AI tool stack), and Sales (understanding how AI influences the buyer discovery journey). The majority of the 248 listed tools cover only one or two of these dimensions, which creates what Barry calls an “actionability gap.”

    This comparison runs four of the most actively reviewed tools through that same framework: Topify, Profound, AirOps, and Otterly.AI. The goal isn’t to declare a winner. It’s to match each tool to the team type it actually serves.

    What G2’s Analyst Framework Actually Measures

    Barry’s three dimensions aren’t about features. They’re about where in your organization the data needs to land.

    The Marketing dimension is about category share. Which prompts trigger your brand? How often does your brand appear versus competitors across ChatGPT, Gemini, and Perplexity? This matters because only 11% of cited domains appear consistently across both ChatGPT and Perplexity for identical queries, meaning fragmented tracking gives you an incomplete picture.

    The Operations dimension is about closing the loop. Seeing that your brand is invisible is one thing. Having a system that moves from that insight to a content fix, without manual re-routing through spreadsheets and Jira tickets, is another entirely.

    The Sales dimension is the least covered. AI models are increasingly acting as pre-sales agents, handling initial feature comparisons before a buyer ever requests a demo. Sales teams need metrics that connect AI recommendations to actual pipeline influence, not just mention counts.

    Most tools do the first dimension reasonably well. Few address all three.

    The 4 Tools at a Glance

    ToolG2 ScorePrimary UsersBarry DimensionsExecution Layer
    Topify5.0Growth teams, marketing agenciesMarketing, Ops, SalesOne-click AI agent
    Profound4.6Fortune 500, regulated industriesMarketing, SalesNone (data export only)
    AirOps4.6Content ops, enterprise teamsMarketing, OpsWorkflow automation
    Otterly.AI4.9SMBs, solo marketersMarketing onlyNone

    Two patterns stand out immediately. Otterly leads on satisfaction score but covers only one dimension. Topify is the only tool that addresses all three while also providing an execution layer.

    Marketing Dimension: Tracking Category Visibility

    This is where all four tools compete most directly.

    Topify tracks brand performance through a 7-metric framework: Visibility, Volume, Position, Sentiment, Mentions, Intent, and CVR. The platform runs this across 10+ AI platforms simultaneously, including ChatGPT, Gemini, Perplexity, DeepSeek, Doubao, and Qwen. Its “Answer Placement Score” weights citations by their narrative position, a brand mentioned as the first recommendation carries more authority than a footnote, and tracks accordingly. Topify also reverse-engineers competitor citations to identify which source URLs AI engines are prioritizing in their responses.

    Profound is the deepest research tool in this group. Its dataset covers over 400 million real user conversations, allowing teams to do high-resolution prompt-level research. It normalizes results across 10+ platforms and provides strong “Share of Voice” and “Citation Share” reporting. The catch is that Profound operates as a pure data output system. Marketing teams typically export insights into separate content management tools, which creates a bottleneck in high-velocity environments.

    Otterly.AI earns its 4.9/5 G2 rating by making the first dimension genuinely easy. At $29/month entry pricing, it monitors brand mentions across ChatGPT, Perplexity, and Google AI Overviews with setup measured in minutes. That said, it monitors the final AI output but doesn’t analyze the underlying retrieval mechanisms that built those answers. You’ll know that you were cited, not why.

    AirOps approaches marketing visibility through content performance. Its “Visibility Score” unifies AI search and SEO performance at the page level, showing which blog posts and landing pages are being picked up as citation sources. It’s less built for competitive tracking and more for teams that want to see their own content’s indexing performance.

    For teams that need to understand category positioning at scale, Topify and Profound lead. Topify adds the execution layer; Profound adds the research depth.

    Operations Dimension: From Insight to Action

    This is where the field narrows sharply.

    Topify built its operations capability around the “actionability gap” directly. Its One-Click Agent Execution lets teams identify a visibility gap and deploy optimized content to close it within the same platform. No separate briefing process. No manual handoff. The system uses direct browser capture rather than API snapshots, targeting 95-98% citation accuracy, which means operations teams aren’t reacting to stale data.

    AirOps is the strongest alternative for content operations specifically. Pages not updated quarterly are three times more likely to lose citations, and AirOps is built to solve exactly that problem. It routes underperforming pages into automated refresh cycles and connects insight data directly to bulk content production. The trade-off is setup time, often a month to implement effectively, plus significant ongoing maintenance.

    Profound provides deep technical diagnostics via Agent Analytics, which tracks AI crawler behavior through CDN logs. But it doesn’t act on those insights natively. Operations teams use it as a high-resolution lens and then manually translate reports into execution tasks elsewhere.

    Otterly.AI has no meaningful integration or execution capability. Its primary export is a Google Looker Studio connector, limited to higher-tier plans. For teams that need automated AEO responses or CMS integration, Otterly’s monitoring-only approach hits a ceiling quickly.

    If your operations team’s bottleneck is moving from data to deployment, Topify is the cleaner path. AirOps is a strong second for teams that define operations as content production at scale.

    Sales Dimension: Does AI Influence Your Pipeline?

    Only two tools in this comparison engage with the sales dimension at all.

    Topify is built around Conversion Visibility Rate (CVR) as a core metric. CVR estimates the likelihood that an AI-generated answer will drive a user toward a brand interaction. The underlying data makes this worth paying attention to: AI-referred search converts at a rate 803% higher than traditional organic search (14.2% vs 2.8%). Topify’s Position Tracking and Sentiment Polarity analysis add further sales context, ensuring teams can validate whether AI models are associating the brand with its correct value propositions during the decision stage. Sales leaders get a metric that justifies AEO investment in quarterly reviews.

    Profound maps the sales dimension through “Conversation Intent” data and “Query Fanouts” analysis. This lets teams trace how a single prompt, say “best CRM for healthcare,” breaks into a chain of sub-queries that map the buyer’s reasoning journey. The “Brand Relevant Prompts” feature identifies which AI conversations are already mentioning competitors. It’s powerful research, but Profound doesn’t connect these intent signals to actual conversion numbers natively. The link to pipeline impact is analytical, not quantitative.

    AirOps can track AI-attributed signups but lacks intent volume analysis or qualitative sentiment scoring for sales contexts. Otterly has no capability in this dimension.

    For sales and growth teams that need to show AI’s actual impact on pipeline, Topify is the only tool in this group with a native metric designed for that conversation.

    The Full Comparison: All Three Dimensions Scored

    CapabilityTopifyProfoundAirOpsOtterly
    Multi-engine monitoring10+ platforms10+ platforms30+ platforms4-6 platforms
    Barry: Marketing dimension✓ Full✓ Full✓ Partial✓ Basic
    Barry: Ops dimension✓ FullPartial (no execution)✓ Full✗
    Barry: Sales dimension✓ CVR + PositionPartial (intent data)✗✗
    Execution layerOne-click AI agentNoneWorkflow automationNone
    Data collection methodDirect browser captureRendered capture + APIPrompt-based pollingAPI snapshot
    Entry pricing$99/mo$99/mo$199/mo$29/mo
    G2 satisfaction score5.04.64.64.9

    The pattern across all three dimensions is consistent. Topify and AirOps are the two tools that offer both monitoring and execution. The key difference is focus: Topify optimizes for cross-functional coverage and agentic deployment, AirOps optimizes for content production governance at enterprise scale.

    Which Tool Fits Your Team

    Start with Otterly if your team’s primary need is proving to clients or leadership that AI mentions exist. At $29/month, it’s the fastest path to a monitoring baseline. You’ll outgrow it if you need to understand or act on what you’re seeing.

    Choose AirOps if your operations team manages a large content library and the main bottleneck is refresh velocity. AirOps connects insight to production in a way no other tool in this group matches, but plan for a real implementation investment.

    Use Profound if you’re in a Fortune 500 environment with procurement cycles and need audit-grade research data (400M+ prompts, SOC 2, HIPAA compliance). It’s the strongest research platform in the category. Pair it with an execution tool if you need to act on the data inside your organization.

    Pick Topify if your team needs to cover all three buyer dimensions without stitching together multiple platforms. Its G2-reviewed feature set spans visibility tracking, automated deployment, and CVR-based sales impact in a single framework. It’s particularly well suited for growth teams and agencies that report on AEO performance across functions and need to show direct business impact.

    The case for a unified platform is practical. Every tool you add to the stack creates a translation cost: exporting data, briefing another team, waiting for execution, checking if it worked. Tools that close that loop internally tend to generate faster returns.

    Conclusion

    G2’s 248-product AEO category is mostly first-generation monitoring tools. They’ll tell you whether you were mentioned. Most won’t tell you why, and almost none will help you fix it.

    Bijou Barry’s three-dimension framework cuts through that noise effectively. Marketing, Operations, and Sales are genuinely different problems, and the tool that covers all three while providing an execution layer is a short list of one in this comparison.

    If you’re starting the evaluation process, Topify’s page shows how its feature set maps across all three dimensions, with user reviews organized by team type.

    Frequently Asked Questions

    What does AEO mean in G2’s software category? 

    Answer Engine Optimization (AEO), also referred to as Generative Engine Optimization (GEO), covers tools that improve a brand’s visibility and positioning within AI-powered search engines and LLM chatbots. G2 requires qualifying tools to offer AI visibility tracking, sentiment analysis, LLM ranking insights, and competitor benchmarking.

    How is Topify different from Profound on G2? 

    Topify combines a 7-metric visibility framework with one-click agentic content deployment, covering all three of G2’s buyer dimensions. Profound is a deep research platform with over 400 million real prompt data points and strong enterprise compliance credentials, but it doesn’t include a native execution layer. Teams that need insights acted on automatically will find Topify’s integrated approach more practical.

    Can AirOps be used for answer engine optimization? 

    Yes, with a specific use case. AirOps connects AI search visibility data to bulk content production workflows, making it a strong choice for teams managing large content libraries. It covers G2’s Marketing and Operations dimensions but doesn’t address the Sales dimension or provide real-time agentic deployment.

    Is Otterly listed on G2? 

    Yes. Otterly.AI holds a 4.9/5 satisfaction score in the AEO category and is widely used by agencies and small businesses. Its $29/month entry tier is among the most accessible in the category. It covers G2’s Marketing dimension only.

    Which G2 AEO tool covers both monitoring and execution? 

    Topify and AirOps both offer monitoring plus execution. Topify uses a one-click AI agent for rapid optimization across all three buyer dimensions. AirOps uses workflow automation specifically for large-scale content operations. For teams that need Sales dimension coverage alongside the other two, Topify is currently the only option in this comparison.

    Read More

  • GEO Score Checker: Which Free Tool Actually Fixes You

    GEO Score Checker: Which Free Tool Actually Fixes You

    You run a free GEO score checker. Your brand scores a 42.

    Now what?

    That’s the moment most tools abandon you. You’ve got a number, a vague sense of underperformance, and zero clarity on what to actually change. The score isn’t the problem. The missing roadmap is.

    This comparison breaks down the leading free GEO tools across four dimensions that matter: what they detect, whether they tell you what to fix, whether they track changes over time, and whether they show you what your competitors are doing differently.

    Your GEO Score Is 42. Here’s Why That Tells You Almost Nothing

    A score of 42 doesn’t tell you why you’re invisible to AI.

    There are at least three distinct root causes behind a low GEO score, and each one requires a completely different fix:

    The technical parsing gap. Your content might be authoritative, but structured in a way that AI crawlers and RAG systems can’t extract effectively. Heavy JavaScript, missing heading hierarchy, no FAQ schema.

    The authority deficit. Your site looks great, but AI models verify “truth” through third-party signals. If you’re not mentioned on Reddit, G2, or industry publications, the model has no external validation to cite.

    The semantic mismatch. You’re optimizing for keywords with high traditional search volume, but those aren’t the conversational prompts people actually type into ChatGPT or Perplexity.

    A score of 42 could mean any of these three things. Or all of them at once. A tool that only shows the number gives you nothing to act on.

    What a GEO Score Actually Measures

    The most useful GEO scoring frameworks evaluate at least five dimensions simultaneously:

    DimensionWhat It MeasuresWhy It Matters
    Visibility (Presence Rate)How often your brand appears across AI responses for tracked promptsDetermines whether you enter the model’s consideration set at all
    SentimentEmotional tone and framing when the AI describes your brandAffects recommendation probability and long-term model trust
    PositionYour rank order in AI-generated comparison listsAI summaries give disproportionate depth to the top 3 results
    Source CredibilityAuthority of third-party domains that cite your brandModels prioritize publisher consensus and community validation
    Structural IntegrityH-tags, FAQ schema, tables that enable easy data extractionFundamental for RAG systems to “clip” relevant information

    Research by Aggarwal et al. found that the strongest GEO improvements come from adding statistics and expert quotations to content, not from keyword variations. Traditional SEO tactics like keyword stuffing have negligible impact on AI visibility. The ranking logic has fundamentally shifted.

    That’s why a single composite score, without dimension-level breakdown, is a diagnostic dead-end.

    The Blind Spots Most Free GEO Tools Share

    The surge in free checkers has made GEO scoring accessible. It’s also created a new kind of problem.

    The one-platform bias. Many free tools only test ChatGPT. But ChatGPT, Perplexity, Gemini, and Claude don’t “read the same internet.” Perplexity, for instance, pulls heavily from Reddit, which accounts for 46.7% of its top citations. A brand that appears consistently in ChatGPT responses may be completely absent on Perplexity. A score based on one model is a partial picture at best.

    Output without advice. Most tools give you a total score and stop there. If your Sentiment Score is 50 out of 100, you need to know which specific third-party source is dragging it down. Without that, you’re left guessing between a PR campaign, a schema fix, or a content rewrite.

    The snapshot problem. Research shows that only about 30% of brands maintain consistent visibility across multiple regenerations of the same query. Model drift and stochastic variation in token generation mean a score captured in the morning can be meaningless by afternoon. A single-point snapshot isn’t a strategy input.

    These aren’t minor gaps. They’re the reason teams spend weeks debating where to start while their competitors keep picking up citations.

    Free GEO Tools, Compared Across Four Dimensions

    Here’s how the leading tools stack up on the criteria that actually matter for decision-making:

    ToolMulti-Platform CoverageFix RecommendationsCompetitor CitationsContinuous Tracking
    HubSpot AEO GraderChatGPT, Gemini, PerplexityGeneral written interpretationLimitedNo
    Mangools AI Search Grader8+ models (incl. Claude, Llama)Low, focus on visibility scoresBasic ranking comparisonNo
    Geoptie GEO AuditMulti-engine readinessHigh, 6-dimension breakdownNo direct trackingNo
    Frase GEO Score CheckerChatGPT, Perplexity, ClaudeSpecific (citability, key takeaways)NoNo
    Topify GEO Score CheckerFull ecosystem (incl. DeepSeek, Doubao)Prioritized action feedDeep, source URL analysisYes

    Each tool occupies a different niche. HubSpot’s AEO Grader works well for a one-time “board-ready” overview of how AI characterizes your brand, whether as a market leader or a traditional player. Mangools functions as the rank tracker of the AI era: broad model coverage, simple visibility signals, no execution layer. Geoptie offers the most technically thorough free audit for structural readiness, though it doesn’t track changes or surface competitor data. Frase focuses specifically on URL-level citability, useful for optimizing individual pieces of content.

    The pattern across all four: they diagnose. They don’t prescribe.

    What Topify’s GEO Score Checker Does Differently

    The core gap in most free tools is what happens after the score. Topify’s GEO Score Checker is built around closing that gap specifically.

    It starts with broader coverage. The tool evaluates brand visibility across ChatGPT, Gemini, Perplexity, DeepSeek, Doubao, and other major AI platforms. That matters because a visibility gap on one platform and not another usually points to a specific type of fix, whether that’s structured data, third-party mentions, or content format.

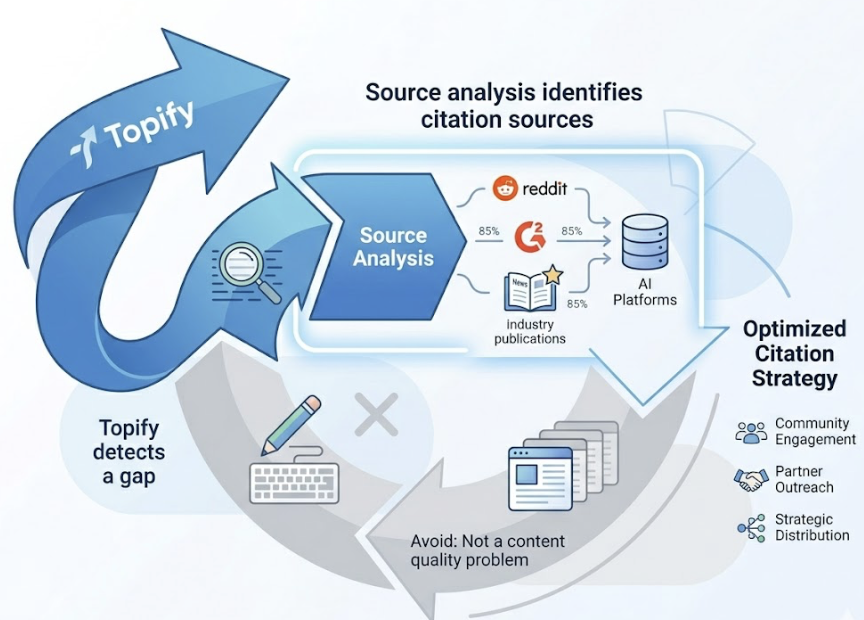
    The more significant difference is the action layer. When Topify detects a gap, it doesn’t just flag it. Its Source Analysis identifies the exact URLs and domains AI platforms are citing when they answer queries in your category. For a B2B SaaS brand, this might reveal that 85% of citations come from Reddit, G2, and industry publications, not from brand-owned content. That’s not a content quality problem. It’s a citation network problem, and it calls for a specific outreach strategy, not more blog posts.

    The platform tracks changes over time. Every content update or new citation feeds back into the visibility metrics, so you can see whether a specific fix actually moved the score before deciding to scale it. The optimization loop is closed, not open-ended.

    Topify’s seven-metric framework (visibility, mentions, sentiment, position, volume, intent, and CVR) connects AI search data to downstream revenue signals. That’s the bridge most free tools don’t build.

    Scores without a fix roadmap are just noise.

    The Right Tool Depends on Where You’re Trying to Go

    Not every team needs an execution platform. Here’s a straightforward way to think about the decision:

    If you want situational awareness: Any free tool gives you a baseline. HubSpot or Mangools work fine for understanding where you stand before a strategy conversation or a leadership review.

    If you’re trying to move the number: You need something that tells you which fix produces the fastest score improvement, tracks whether it worked, and shows you what competitors are doing to earn the citations you’re missing. Free snapshot tools can’t do that.

    The gap between these two scenarios is the difference between knowing your brand scores a 42 and knowing that fixing your schema on three specific pages would push you past a competitor who’s currently getting cited for 68% of the queries in your category.

    Who Gets the Most Value from Topify’s GEO Score Checker

    B2B SaaS brands where AI search is already influencing pipeline. Buyers are using ChatGPT and Perplexity to evaluate software before they ever visit a vendor site. Topify helps SaaS teams maintain a coherent semantic footprint across feature pages, comparison content, and documentation, so AI systems understand exactly what the product does and who it’s built for.

    Marketing and SEO agencies managing multiple clients. Daily prompt testing across dozens of models doesn’t scale manually. Topify’s multi-project management and one-click execution give agencies a way to deliver measurable AI visibility improvements without adding headcount.

    SEO teams transitioning from traditional search. Teams moving from “ten blue links” to “AI citations” need a tool that bridges both worlds. Topify integrates technical signals like schema and crawlability with AI-native signals like sentiment and source citation patterns, which means one platform instead of a fragmented stack.

    FAQ

    What is a GEO score and how is it calculated? A GEO score measures how visible and trustworthy a brand is within AI-generated answers. Most professional tools calculate it as a weighted average across visibility (frequency of appearance), sentiment (tone of description), position (rank in AI-generated lists), and source credibility (authority of cited URLs).

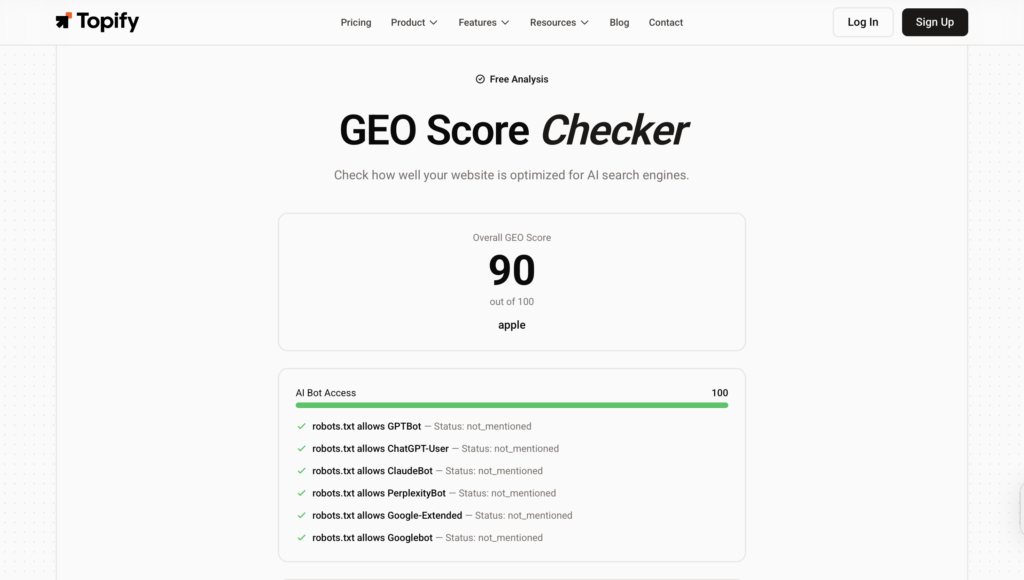
    Are there any truly free GEO score checkers? Yes. HubSpot AEO Grader, Geoptie GEO Audit, Mangools AI Search Grader, and Frase all offer free tiers that work well for baseline audits. Topify also offers a free GEO Score Checker at topify.ai/tools/geo-score-checker with prioritized fix recommendations, which goes further than the purely diagnostic tools.

    How often should I check my GEO score? More often than most teams think. Research suggests only about 30% of brands maintain consistent AI visibility across multiple regenerations of the same query, due to model drift. A practical cadence: weekly for top-priority prompts, monthly for citation trends and sentiment shifts, quarterly to connect GEO metrics to pipeline and branded search lift.

    What’s the difference between a GEO score and an SEO score? SEO scores measure demand capture through backlink volume, crawlability, and link rankings. GEO scores measure demand influence: how likely an AI is to cite your content based on its factual density, authoritative tone, and structural clarity. Different signals, different optimization strategies.

    Can a GEO tool tell me which fixes to prioritize? Most diagnostic tools, like HubSpot or Mangools, can tell you your score is low but can’t tell you what to change first. Tools with an execution layer, like Topify, analyze visibility gaps against competitor citation data to surface a prioritized action feed, showing exactly which changes move the score fastest.

    Conclusion

    A GEO score is the start of a conversation, not the end of one. The question isn’t whether your score is 42. It’s whether your tool can tell you what to do about it, in what order, and how to verify it worked.

    Free tools are genuinely useful for establishing a baseline or building the case for a GEO investment. But if you’re tasked with actually improving AI search visibility, you need something that closes the loop between data and execution.

    Topify’s GEO Score Checker is worth starting with, specifically because it doesn’t stop at the number.

    Read More

  • GEO Score vs. AI Visibility Score: Why You Need Both

    GEO Score vs. AI Visibility Score: Why You Need Both

    Most brands now know they need to show up in AI answers. So they run a GEO audit, fix their schema markup, tighten their headings, and call it done.

    That’s half the work. And it’s the easier half.

    A GEO Score tells you whether your content is readable to an AI. An AI Visibility Score tells you whether AI actually recommends you. Those are two very different things, and confusing them is one of the most expensive mistakes you can make right now.

    Your GEO Score Is a Readiness Snapshot, Not a Performance Report

    A GEO Score measures how well your content is structured for AI retrieval. Think of it as a technical audit: can a model’s crawler access your site, parse your headings, extract discrete fact units, and trust what it finds?

    The evaluation typically covers five areas: crawler accessibility, semantic structure, entity declaration via Schema markup, factual density, and metadata freshness. Each one maps to a specific stage of how Retrieval-Augmented Generation (RAG) systems process a page before deciding whether to cite it.

    This is genuinely useful. Content that fails these checks is unlikely to get picked up regardless of how authoritative the brand is. Research from the foundational Princeton GEO study found that adding verifiable statistics to content can lift citation rates by 31% to 37%, and expert quotations can push that figure higher.

    But here’s the thing: passing these checks doesn’t mean you get cited. It means you’re eligible to be cited.

    You can check where your content stands right now with Topify’s GEO Score Checker, which runs 22 technical checks across content quality, AI readiness, technical structure, and authority signals.

    What AI Visibility Score Actually Captures

    AI Visibility Score measures something else entirely: how often your brand actually appears in AI-generated answers across real platforms like ChatGPT, Gemini, and Perplexity.

    It’s expressed as a share of citations for a defined set of category prompts. And the numbers are stark. Industry tracking data from 2026 shows the median brand sits at roughly 0.3% AI Visibility. Top performers in competitive categories reach 12% to 30%. That gap isn’t a rounding error; it’s the difference between being part of the AI conversation and being invisible to it.

    AI Visibility also captures dimensions a GEO Score can’t touch: where you rank within an answer (first mention vs. buried alternative), how AI describes your brand over time, and which specific user intents cause you to appear or disappear.

    The Gap Most Teams Don’t See Coming

    A 2026 analysis of 1,528 company reports found that the correlation between technical GEO Score and real-world AI Visibility was just 0.080. The correlation between brand authority (presence across high-credibility third-party sources) and AI Visibility was 0.386, nearly five times higher.

    That’s not a small gap. That’s a different variable entirely.

    The reason comes down to how LLMs actually select sources. They don’t just retrieve the cleanest content; they cross-reference claims across multiple independent sources before committing to a citation. If your brand makes a strong claim on your own domain but that claim isn’t corroborated by analyst reports, review platforms, or editorial coverage, the model often discards it.

    A brand with high authority and a mediocre GEO Score averaged 0.651 AI Visibility in that same study. A brand with a high GEO Score but low authority averaged 0.548. Technical readiness without off-page trust consistently underperforms.

    Why the Slot Competition Makes This Urgent

    Traditional search gives you ten blue links. AI answers give you two to five citation slots, sometimes fewer.

    That scarcity changes the stakes. Ranking first on Google for a query doesn’t protect you if the LLM synthesizing that same query picks three other sources instead. You can be a market leader in traditional search and functionally invisible in AI answers simultaneously.

    This isn’t a hypothetical edge case. It’s what the data shows for most brands right now.

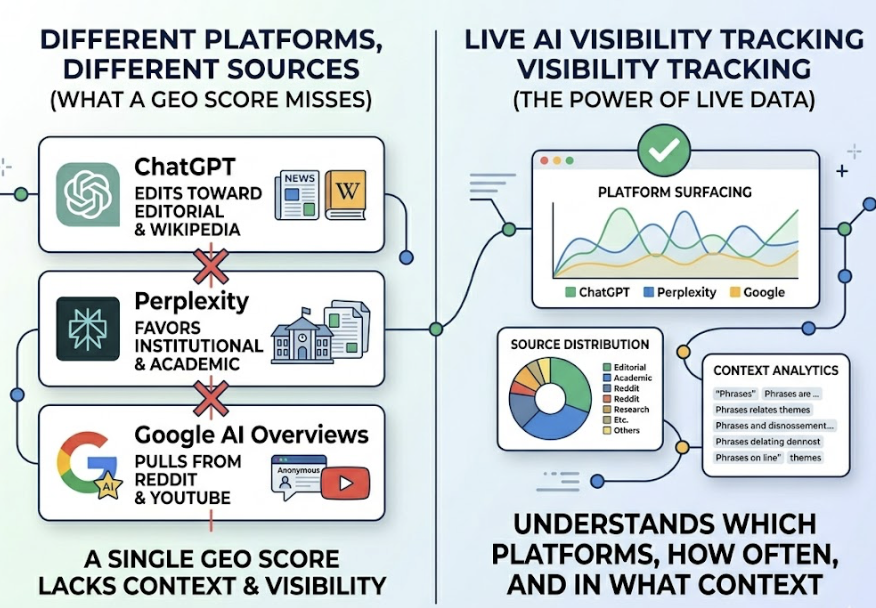
    The other complication: different AI platforms cite differently. ChatGPT skews toward editorial sources and Wikipedia. Perplexity heavily favors institutional and academic sources. Google AI Overviews pulls heavily from Reddit and YouTube. A GEO Score doesn’t tell you which platforms are surfacing your brand, how often, or in what context. Only live AI Visibility tracking does.

    How to Use Both Together

    The two metrics work as a sequence, not a choice.

    Start with your GEO Score. It tells you whether the technical foundation is in place: whether bots can crawl your pages, whether your content is chunked in a way that RAG systems can extract, whether your schema markup helps the model understand what your brand actually does. Fixing GEO Score gaps is table stakes; it’s what gets you into the retrieval pool.

    Then track your AI Visibility. This tells you what’s actually happening once you’re in that pool. Are you being selected? In which contexts? For which intents? Against which competitors? These questions can’t be answered by a technical audit.

    GEO ScoreAI Visibility Score
    What it measuresContent readiness for AI retrievalActual citation frequency in AI answers
    Type of metricStatic snapshotDynamic, ongoing
    Update frequencyOn-demand auditContinuous tracking
    Primary actionFix technical and content gapsOptimize off-page authority and citation share
    Tells youWhether AI can cite youWhether AI does cite you

    Use Topify’s GEO Score Checker to run the technical diagnostic. Then use Topify’s AI Visibility Checker to track how your brand is actually showing up across ChatGPT, Gemini, Perplexity, and other major platforms in real time.

    The path from readiness to actual visibility becomes a lot clearer when you can see both numbers side by side.

    Conclusion

    A good GEO Score and strong AI Visibility aren’t the same thing, but you need both. The GEO Score tells you whether AI can pick up your content. The AI Visibility Score tells you whether it does. Most brands are investing in readiness and stopping there, which explains why the median brand’s AI Visibility sits at just 0.3% while top performers are at 12% and climbing.

    Start with the technical foundation. Then track the real-world results. The gap between those two numbers is where your actual opportunity lives.

    FAQ

    Is GEO Score the same as AI Visibility?

    No. GEO Score measures whether your content is technically structured for AI retrieval. AI Visibility Score measures whether AI systems actually cite your brand in their answers. A brand can score well on the former and still have near-zero performance on the latter.

    How often should I check each metric?

    Run a GEO audit when you publish or significantly update content, and after major site changes. AI Visibility needs continuous tracking because AI citation behavior shifts as models update, competitors publish new content, and platform sourcing patterns evolve.

    What’s a realistic AI Visibility benchmark to aim for?

    The median brand sits around 0.3%. Reaching 2% to 10% puts you in the category presence tier; you’re appearing in comparison contexts and long-tail queries. Top-tier performers consistently hit 12% and above. The right benchmark depends on your vertical and competitive set.

    Can I improve AI Visibility without improving my GEO Score first?

    Partially. Off-page authority signals (analyst coverage, editorial mentions, review platform presence) drive visibility independently of on-page technical quality. But brands with both tend to outperform brands that focus on only one. Technical readiness removes friction; authority creates preference.

    Why do different AI platforms show different visibility results?

    Each platform has distinct sourcing behavior. ChatGPT pulls broadly from editorial and corporate sources; Perplexity skews academic and institutional; Google AI Overviews leans heavily on Reddit and user-generated content. A single GEO audit can’t account for these platform-specific citation patterns. Cross-platform tracking is the only way to see where you actually stand.

    Read More

  • AI Citations vs. Brand Mentions: Not the Same

    AI Citations vs. Brand Mentions: Not the Same

    Your brand monitoring dashboard shows solid numbers. Mentions are up. Sentiment is mostly positive. Reach looks healthy.

    Then someone on your team asks ChatGPT for the top tools in your category, and your brand doesn’t appear once.

    That’s not a monitoring failure. That’s a monitoring blind spot. The two systems track fundamentally different things, and conflating them is quietly costing brands their position in the one channel that’s growing fastest.

    Your Brand Monitor Can’t Read ChatGPT’s Mind

    Traditional brand monitoring runs on a simple logic: crawl the web, look for strings that match your brand name, count them up.

    That works fine when information lives on static pages. It fails completely when information is synthesized on the fly.

    When a user asks ChatGPT “what’s the best CRM for a 50-person manufacturing company,” no webpage is displayed. Instead, the model pulls fragments from its training data and from real-time sources via RAG (Retrieval-Augmented Generation), then generates a response that never existed as a webpage to begin with. Your crawler has nothing to crawl. Your keyword alert has nothing to trigger.

    That’s the gap.

    And it’s not a technical edge case. It’s the default experience for millions of users making purchase decisions right now.

    What an AI Citation Actually Is

    In the AI context, “citation” means something more specific than “your brand got mentioned.”

    A citation has two components: the source domain or URL that the AI pulled from, and the position of that reference inside the answer. Both matter. Neither shows up in your brand monitoring report.

    What makes this genuinely tricky is that citations and brand mentions can be completely decoupled. Two scenarios illustrate this well.

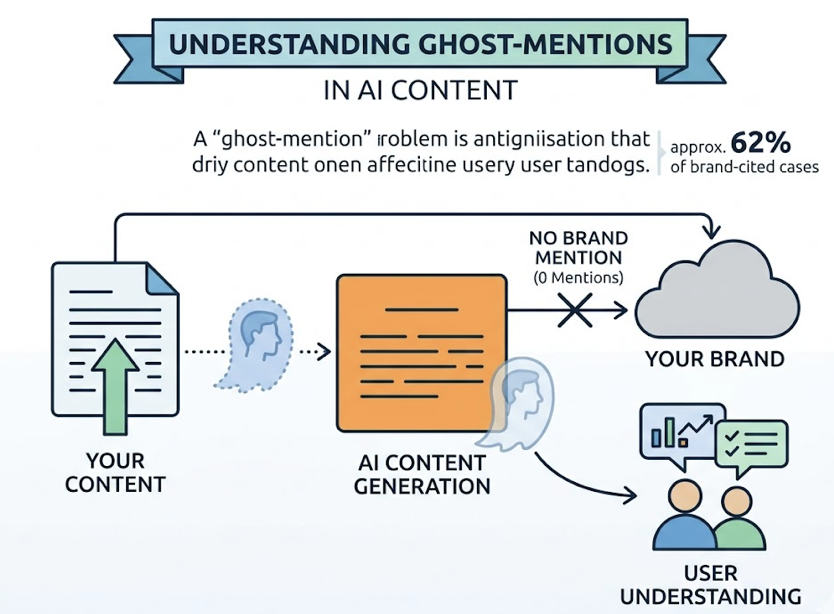
    The first is what researchers call a ghost-mention: AI adopts your content, links back to your domain, but never says your brand name in the generated text. Studies suggest this happens in roughly 62% of cases where brand content is cited. Your monitoring report shows zero mentions. Meanwhile, your content is actively shaping how users understand the market.

    The second is the inverse: AI mentions your brand name, but the source it’s actually citing is a competitor’s review or a third-party blog. You got the mention. Someone else framed the narrative.

    Neither of these dynamics is visible to traditional monitoring tools.

    Position Inside the Answer Matters More Than Presence

    Not all citations carry equal weight. Being named first in a direct recommendation is categorically different from appearing in a list of “also worth considering” options at the end of an AI response.

    A brand recommended in the opening paragraph carries high conversion potential. AI is treating it as the default answer. A brand mentioned in a footnote sits at the opposite end: technically present, functionally invisible. And a brand cited as a cautionary example or outdated alternative is actively damaging.

    Position tracking, then, isn’t a nice-to-have metric. It determines whether your AI presence is building pipeline or eroding perception.

    Brand Mention Tracking: Where It Still Works (And Where It Stops)

    Traditional monitoring tools aren’t obsolete. They’re just scoped to a different information ecosystem.

    For social listening, news monitoring, and historical sentiment analysis, platforms like Semrush and social intelligence tools still do the job well. If your brand runs into a crisis on X or Reddit, those tools surface it fast. If you need to understand how brand perception has shifted over a decade, the data depth is there.

    The ceiling arrives the moment a user opens a chat interface.

    DimensionBrand Mention TrackingAI Citation Tracking
    Data sourceSocial, news, static webLLM-generated responses, RAG sources
    What’s trackedBrand name stringsPrompt results, source domains, citation weight
    Core metricMentions, share of voiceCitation rate, answer position
    SEO linkageMeasures traditional SERP rankingMeasures GEO (Generative Engine Optimization) effectiveness
    Platform coverageTwitter/X, Reddit, news sitesChatGPT, Gemini, Perplexity, AI Overviews
    Ranking insight❌✅
    Content gap discovery❌✅
    Blind spotClosed AI conversations entirelyNon-retrieval model training data

    The gap isn’t about which tool is better. It’s about which channel your customer is using.

    5 Questions Your Brand Monitor Can’t Answer

    These aren’t hypothetical gaps. They’re active intelligence failures happening inside most marketing orgs right now.

    Who does ChatGPT recommend first when someone asks about your category? If a competitor consistently occupies the primary recommendation slot while you appear in the “honorable mention” section, your brand premium is eroding with every AI conversation. Traditional monitoring won’t show that.

    Which domains does Perplexity pull from most often in your niche? Different AI engines have different source preferences. Perplexity tends to favor dense technical documents and PDFs. ChatGPT often leans toward Wikipedia and Reddit consensus. Knowing which domains hold “privileged” status in your category tells you where to build content authority. Brand monitoring only tells you which domains have high traffic.

    Is your brand being framed as a leader or as the legacy option? AI doesn’t just mention brands, it assigns them roles. A response that says “Brand X has been around longer, but Brand Y is leading on AI-native features” is a citation that actively positions you as behind the curve. That kind of semantic framing is nearly impossible to quantify with traditional sentiment tools.

    Which competitor content is AI pulling from more than yours? This is the content gap made visible. If a competitor’s blog post on “industry standards” is being cited repeatedly across AI engines, their content structure is better matched to what AI extracts: clear H2s, tables, direct answers. You can reverse-engineer their strategy by analyzing what’s being cited and why.

    Are your AI mentions actually converting? Referral traffic from ChatGPT converts at 15.9%, roughly 9x the rate of traditional search traffic. That number is significant, but only if you can trace which citation paths are driving it. Brand monitoring shows traffic volume. AI citation tracking shows the recommendation chain that created intent.

    Brand monitoring answers yesterday’s questions.

    Do You Actually Need Both? Honest Answer

    It depends on where your customers are making decisions, not on what tools your team is already comfortable with.

    If your audience is primarily discovering brands through social content, industry newsletters, and live events, traditional monitoring still carries most of the weight. AI citation tracking becomes a secondary layer for building long-term authority.

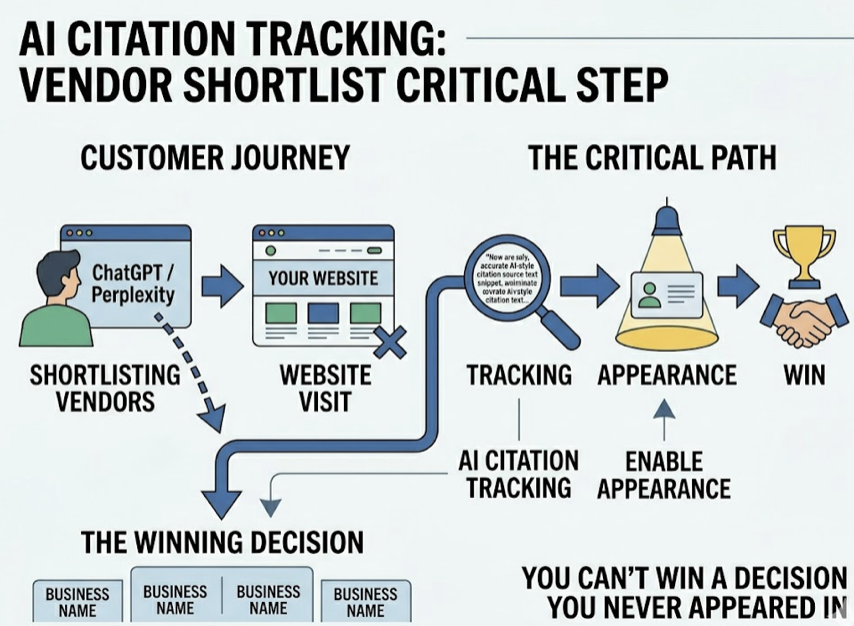
    If your audience is using ChatGPT or Perplexity to shortlist vendors before they ever visit your website, which is increasingly true in B2B software, professional services, and high-consideration consumer categories, AI citation tracking is no longer optional. You can’t win a decision you never appeared in.

    The practical test: check whether your website analytics show meaningful referral traffic from AI platforms. If it’s there and growing, you’re already in the game. If it’s absent, you may be invisible in conversations where competitors are being recommended daily.

    Start by auditing how your customers actually describe their research process, not how you assume they do.

    How to Start Tracking AI Citations Without Rebuilding Your Stack

    The barrier to entry is lower than most teams assume. You don’t need to replace existing tools. You need to add a layer that sees what they can’t.

    Step 1: Shift from keywords to prompts. Stop tracking brand name strings. Start tracking the questions your customers are actually asking AI. “CRM software” is a keyword. “What CRM is best for a 50-person manufacturing company?” is the prompt your buyer typed last Tuesday. That shift in framing changes everything about what you measure.

    Step 2: Run cross-platform tests. A single manual check of ChatGPT tells you almost nothing. AI responses vary by account, region, and session. What matters is statistical visibility across thousands of automated queries run through clean synthetic accounts, spanning ChatGPT, Gemini, Perplexity, and AI Overviews. Manual spot-checks introduce too much variance to be actionable.

    Step 3: Analyze the sources, not just the results. This is where the real intelligence lives. When AI cites a competitor’s page over yours, what does that page have that yours doesn’t? Schema markup? A comparison table? A direct FAQ block? Topify‘s Source Analysis feature surfaces exactly this: which domains AI is pulling from, why they’re being preferred, and what structural gaps in your content are costing you citations. The output isn’t a report, it’s a specific GEO action item.

    One-Click GEO Execution then takes that intelligence and generates the missing content elements, FAQ blocks, data tables, structured H2s, directly optimized for AI extractability. It closes the loop between insight and action without requiring a full content overhaul.

    One more thing worth knowing: 76.4% of pages that appear in top ChatGPT citations were updated within the past 30 days. AI citation patterns shift fast. Quarterly audits won’t cut it. This is a continuous monitoring problem, not a one-time analysis.

    Conclusion

    Brand monitoring and AI citation tracking aren’t competitors. They’re instruments calibrated for different channels, and the channel split between traditional web and AI conversation is only widening.

    The strategic question isn’t which tool to keep. It’s whether your current intelligence setup can tell you what AI says about your brand when a buyer asks, and whether you’re in the recommendation or invisible to it.

    If you don’t know the answer to that, the gap is already costing you.

    FAQ

    Is AI citation the same as a backlink? 

    No. A backlink is a physical link between two webpages, used in Google’s authority algorithm. An AI citation is a model’s acknowledgment of a source during response generation. AI can cite a brand-new page with zero backlinks if that page answers a prompt clearly and directly. The selection criteria are different: authority versus answerability.

    Can I track AI citations manually? 

    You can run spot checks, but they won’t be reliable. AI responses vary by account, geography, and session temperature. What you see from your laptop doesn’t represent the average experience across millions of users. Professional tracking uses large-scale synthetic probing: thousands of automated queries through randomized clean accounts to produce statistically meaningful visibility scores.

    Does being cited by AI always mean more traffic? 

    Not always. AI is increasingly delivering “zero-click” answers. But a citation still builds brand authority and cognitive presence. If AI consistently names your brand as the primary recommendation in a category, that recognition influences decisions even when users don’t click through. The brand impression compounds over time.

    How quickly do AI citation patterns change? 

    Very quickly. Model weight updates and RAG index refreshes can shift citation patterns within days. That 76.4% figure for recently-updated pages isn’t a coincidence. AI engines tend to favor fresh, well-structured content. This means citation tracking needs to be a continuous process, not a quarterly reporting exercise.

    Read More

  • 4 Free GEO Score Checkers: What Each One Actually Measures

    4 Free GEO Score Checkers: What Each One Actually Measures

    Most SEOs searching for a GEO score checker grab the first free tool that shows up and run a quick audit. The problem isn’t finding a tool. It’s not knowing what the score actually reflects.

    These four tools each measure a different dimension of the same problem. Frase focuses on structural extraction. SnowSEO prioritizes trust signals. Keywordly embeds GEO into a full SEO workflow. Readdy flags the technical barriers that block AI crawlers entirely. They’re not interchangeable. And depending on what you’re trying to fix, picking the wrong one means you’re optimizing for the wrong layer.

    Here’s a clear breakdown of what each tool actually does, and where each one stops.

    Last Year’s GEO Playbook No Longer Explains AI Visibility

    A year ago, “GEO optimization” largely meant cleaning up your headings and adding a few statistics. That still matters. But it doesn’t explain why brands that rank #1 on Google are consistently ignored by ChatGPT and Perplexity.

    Research from Princeton University and Georgia Tech found that specific structural interventions can boost generative engine visibility by 30-40%. But they also surfaced a more uncomfortable finding: only about 12% of links cited in AI-generated responses also appear in the top 10 traditional search results. The two channels are operating on separate logic.

    That’s the shift most free GEO checkers haven’t caught up to yet.

    Generative engines run content through three distinct filters before a source ever gets cited. First, they parse the structure. Then, they evaluate credibility signals. Finally, and this is the layer most tools skip entirely, they check whether your brand has broader consensus across the web. A perfect score on layer one doesn’t protect you if layer three is empty.

    The 4 Free GEO Score Checkers, Side by Side

    ToolGEO Score FocusE-E-A-T AnalysisFull SEO WorkflowBrand AI Citation MonitoringFree Tier
    FraseStructural + citation-readinessLimited (sourcing check)Research to BriefNoYes
    KeywordlyMulti-factor (0-100)Moderate (Pillar 1 of 3)Full SEO integrationNoYes
    SnowSEOE-E-A-T-centricComprehensive (28 signals)Audit to Fix PlanNoYes
    ReaddyTechnical extraction + crawlabilityMinimalInstant diagnosticNoYes
    Topify GEO Score CheckerBrand + content layer combinedConsensus-basedCitation to PipelineYesYes

    The “Brand AI Citation Monitoring” column is empty for the first four tools. That’s not a gap in their features. It’s a different product category. Content-layer checkers and brand-layer trackers solve different problems. The rest of this article explains both.

    Frase: Built for Writers Who Need to Know If Their Content Will Get Cited

    Frase scores your content against what a generative engine’s parser is actually looking for. Its free GEO checker produces five sub-scores: Citability (unique, quotable facts), Content Structure (heading hierarchy and modularity), Clear Definitions (explicit explanations designed for direct extraction), Key Takeaways (summary sections AI can pull verbatim), and Data & Citations (grounding in external research).

    What makes Frase useful in practice is its competitive SERP layer. It identifies “content gaps,” questions that your competitors answer but your content doesn’t. Generative engines tend to skip thin pages that only partially cover a topic. Frase quantifies exactly how thin yours is.

    Its limitation is scope. Frase audits what’s on your page. It has no view into whether AI engines are actually recommending your brand in live queries. For content editors doing pre-publish checks, it’s the right call. For teams troubleshooting why a well-ranked page isn’t appearing in AI answers, it stops short.

    Keywordly Treats GEO as the Natural Next Step After SEO

    Keywordly’s GEO Score Analyzer outputs a 0-100 rating across three pillars: Authority, Credibility, and Structure. It’s the most SEO-native tool in this comparison, built for teams that don’t want to manage a separate GEO workflow alongside their existing content operations.

    Its standout feature is “fan-out query” detection. When a generative engine processes a prompt, it typically generates sub-questions to build a more complete answer. Keywordly identifies those latent queries, so writers can optimize for the full “prompt universe” around a topic rather than a single keyword. That shift from keyword-matching to semantic coverage is exactly how LLMs decide whether a page is comprehensive enough to cite.

    The trade-off is depth on the GEO scoring side. Because Keywordly is integrating GEO into a broader SEO workflow, its brand visibility signals are moderate rather than comprehensive. It’s the right tool for volume-focused content teams making the transition to AI-first search. It’s not the right tool for diagnosing why your brand specifically isn’t appearing in ChatGPT responses.

    SnowSEO Checks 28 E-E-A-T Signals. Most Tools Check Three.

    SnowSEO is the most rigorous free option for brands where trust is a strategic requirement, including healthcare, finance, legal, and any YMYL category where AI models apply extra scrutiny to their sources.

    Its GEO-Score audit runs across 22 factors grouped into 4 pillars, with a prioritized fix plan showing which signals to address first. The 28 individual E-E-A-T checks include author credentials and bylines, content freshness, non-stock imagery, and implementation of llms.txt, the machine-readable file that functions as a direct directive to AI crawlers for more efficient site-wide understanding.

    SnowSEO also captures something important about how generative engines evaluate sources at scale. If a site has inconsistent entity definitions or outdated facts across multiple pages, the AI’s confidence in that domain drops across the board. A single optimized pillar page isn’t enough. SnowSEO flags the inconsistencies that undermine site-wide trust.

    For editorial teams and regulated publishers, it’s the most thorough free audit available. For marketing teams troubleshooting brand-level AI visibility, it answers a different question than the one they’re actually asking.

    Readdy Finds the Technical Blocks That Everything Else Ignores

    Readdy’s GEO Score Checker focuses on a problem the other tools assume isn’t there: whether AI crawlers can actually access your site in the first place.

    Their research found that approximately 30% of websites block AI crawlers including GPTBot, ClaudeBot, and PerplexityBot due to outdated robots.txt directives. A brand could score 92/100 on Frase and still be completely invisible to generative engines because the infrastructure never let them in. Readdy checks for that before anything else.

    It’s the fastest option in this comparison. No account required, instant results, clear output. What it doesn’t offer is editorial depth. It won’t tell you whether your content is well-structured or whether your E-E-A-T signals are strong. It tells you whether the door is open.

    Use Readdy as the first check in any technical SEO audit. Use one of the other tools for what comes after.

    Your Content Score and Your Brand Visibility Are Two Separate Numbers

    Here’s the finding that most content audits miss entirely.

    A brand can score 87/100 on Frase. Clean structure, good fact density, no crawl blocks. And Topify’s tracking shows 0% Share of Voice across 40 category-level prompts in their industry. The content is optimized. The brand isn’t visible. Those are two different problems.

    The reason is how generative engines actually select sources. According to data from AI citation analysis, consensus across third-party platforms has a predictive correlation of 0.664 with AI visibility. Brand search volume correlates at 0.334. Domain authority and backlinks? Between 0.08 and 0.18. Traditional authority metrics are poor predictors of AI citation behavior.

    Generative engines prioritize sources that have demonstrated consensus across the web, Reddit threads, niche review sites, news coverage, and third-party comparisons. That’s not content GEO. That’s brand GEO. And no structural audit tool measures it.

    Topify’s GEO Score Checker is where that layer becomes measurable. It tracks actual brand mentions in generative responses across ChatGPT, Gemini, Perplexity, and other major AI platforms, calculating Share of Voice for specific buying-intent prompts. It also runs Sentiment Analysis alongside visibility, because a brand cited frequently in negative contexts (described as “expensive” or “complex”) suffers in recommendation environments even when the mention count is high.

    The Topify platform also reverse-engineers citations, showing exactly which third-party domains AI models pull from when recommending brands in your category. That tells you where your brand needs to show up in the broader web ecosystem, not just on your own site.

    Early data suggests AI referral visitors convert at roughly 5x the rate of traditional search traffic. The brands that capture that channel aren’t necessarily the ones with the highest content GEO scores. They’re the ones with the strongest brand-layer presence.

    Which Tool Should You Start With?

    The right starting point depends on what you’re actually trying to diagnose.

    ScenarioRecommended Tool
    Pre-publish audit on a single URLFrase or Readdy
    Suspected crawl block or technical barrierReaddy first
    GEO integrated into existing SEO content workflowKeywordly
    YMYL content or E-E-A-T is your primary concernSnowSEO
    Diagnosing why AI doesn’t recommend your brandTopify GEO Score Checker
    Ongoing brand visibility tracking across AI platformsTopify

    In practice, most teams need more than one. Readdy and Frase cover the pre-publish content layer. Keywordly fits teams scaling content production with GEO built in. SnowSEO is the authority on trust signals. And Topify covers the dimension none of the others touch.

    High content GEO scores are table stakes. Brand-level AI citation is the actual outcome.

    Conclusion

    The four free GEO score checkers in this comparison are all useful. They’re also measuring different things. Frase scores citation-readiness. Keywordly builds GEO into your SEO workflow. SnowSEO audits E-E-A-T at depth. Readdy catches the crawl blocks that silently exclude your site from AI discovery.

    What none of them track is whether your brand actually appears when users ask AI engines to recommend a solution in your category. That’s the Topify GEO Score Checker’s purpose, and it’s a different data layer entirely.

    Start with the tool that matches your bottleneck. Then ask the question the content scores don’t answer: when someone asks ChatGPT what to use, does your brand come up?

    FAQ

    What is a GEO score? 

    A GEO score rates how well your content is positioned to be extracted and cited by generative AI engines like ChatGPT, Gemini, and Perplexity. Most tools score factors like structural clarity, factual density, and E-E-A-T signals. Scores above 70 are generally considered solid; above 85 is strong. Below 60 usually means the content needs structural work before it’s citation-ready.

    Is a GEO score the same as an SEO score? 

    No. An SEO score evaluates keyword relevance and backlink signals for traditional ranking. A GEO score evaluates “citable potential,” how easily an AI can extract and verify a specific fact from your content. A page can rank #1 on Google with a low GEO score, and vice versa. The two metrics reflect two separate algorithmic systems.

    Can a high GEO score guarantee AI visibility? 

    No. A high score means your content is structurally eligible for citation. Actual visibility depends on the brand citation layer, whether the AI’s training data and web-consensus signals identify your brand as trustworthy. You can have a perfect content GEO score and zero AI recommendations if your brand lacks third-party consensus.

    Do I need a paid tool to check my GEO score? 

    Free tools work well for auditing specific pages. Frase, SnowSEO, Readdy, and Keywordly all offer free tiers that cover content-layer analysis. Daily tracking across 100+ prompts, historical trend data, and sentiment monitoring typically require a paid platform.

    What’s the difference between content GEO and brand GEO? 

    Content GEO is the structural and factual optimization of your own pages. Brand GEO is how your brand appears across the broader web, including news coverage, Reddit discussions, and third-party reviews. AI models weight consensus heavily when deciding what to recommend. You need both layers to be visible in generative search.

    Read More

  • GEO Score vs SEO Score: They’re Not the Same

    GEO Score vs SEO Score: They’re Not the Same

    You’ve spent years building domain authority. Your DA is 75. You rank on page one for a dozen competitive keywords. Then someone asks ChatGPT to recommend the top tools in your category, and your brand doesn’t appear once.

    That’s not a bug. That’s the gap between SEO Score and GEO Score, and it’s costing brands more visibility than they realize.

    Your Domain Authority Means Nothing to ChatGPT

    Here’s the thing most marketers still haven’t fully processed: large language models don’t consult your backlink profile when deciding what to cite. They don’t check your DA, your PageRank, or your Core Web Vitals. Those signals were built for crawler-based engines. Generative AI operates on a completely different logic.

    What AI models look for is “topical entity density” and “information gain.” A niche site with focused, data-rich content and frequent citations within its field can outrank a DA-80 domain in AI-generated answers. High domain authority is a Google signal. It’s not a GEO signal.

    That’s the foundational misread most brands make: they assume GEO is just SEO with a new name. It’s not. They measure entirely different capabilities.

    What SEO Score Actually Measures

    SEO Score reflects a page’s potential to rank in traditional search results. Tools like Moz, Ahrefs, and SEMrush evaluate it across a few consistent dimensions: technical health (Core Web Vitals, mobile-friendliness, HTTPS), content relevance (keyword alignment, heading structure), backlink profile, and crawlability.

    The underlying logic is simple. Help Google or Bing determine whether this page deserves a top-10 position for a given query. SEO Score is the answer to that question, expressed as a number.

    Its strengths are real. Organic traffic growth, click-through rate optimization, keyword ranking maintenance: these are all downstream of a healthy SEO Score. But SEO Score tells you nothing about whether an AI will cite you. That’s a separate question entirely.

    What GEO Score Actually Measures

    GEO Score measures the probability that your content gets cited in an AI-generated answer. It’s a machine-readability metric, not a human-popularity metric.

    The specific signals that drive GEO Score fall into five categories. Bot accessibility: whether AI crawlers like GPTBot and ClaudeBot can actually access your content. Entity authority: how frequently your brand is mentioned across high-trust sources like Reddit, Wikipedia, and niche forums. Vector readiness: how well your content can be chunked and retrieved by RAG (Retrieval-Augmented Generation) systems. Factual provenance: the presence of statistics, authoritative citations, and verifiable data. Structure: whether you’re using Q&A formats, clear definitions, and schema markup that AI parsers can extract without friction.

    Princeton University research confirmed the weight of these signals. Across 10,000 queries, content that cited authoritative sources saw a 40% boost in AI visibility. Adding statistics drove a 37% increase. Expert quotations added 30%. The research also found that websites ranked fifth in traditional search saw a 115% visibility jump when they applied citation-based GEO tactics, while top-ranked sites that ignored GEO actually lost ground.

    That’s the equalizer effect. GEO doesn’t care who had the most backlinks five years ago.

    You can get an immediate baseline read on where your site stands with Topify’s GEO Score Checker. It runs a multi-dimensional analysis and gives you a starting point before you touch anything else.

    Side by Side: What Separates the Two Scores

    DimensionSEO ScoreGEO Score
    MeasuresSearch engine ranking potentialProbability of AI citation
    Core signalsBacklinks, DA, keyword densityContent structure, entity authority, factual density
    Optimization goalTop 10 “blue links”Cited as source in AI-generated answers
    Primary toolsMoz, Ahrefs, SEMrushGEO Score Checker, Topify
    Conversion mechanismClick on a ranked linkClick on a citation inside an AI response
    StabilityRelatively stableHighly dynamic, shifts with model updates
    Strategic focusTechnical health + authorityInformation gain + machine-readability

    One more difference worth calling out: AI-referred visitors convert at approximately 14.2%, compared to 2.8% for traditional organic search. That’s a five-fold gap. Users who click a citation in a ChatGPT or Perplexity response have already been pre-qualified by the AI’s synthesis. They’re not browsing. They’re deciding.

    Why “Both” Is Not Optional in 2026

    Some teams have responded to the rise of AI search by pivoting fully to GEO. That’s the wrong move, and the data makes it clear why.

    As of early 2026, AI search tools have captured between 12% and 15% of global search market share, up from roughly 5% at the start of 2025. Gartner projects that traditional search volume will decline 25% by the end of 2026. That’s a real and measurable shift. But 75-85% of queries still go through traditional engines.

    More importantly, the two channels are technically interdependent. ChatGPT sources approximately 87% of its citations from the top 10 Bing organic results. Google’s Gemini AI Overviews primarily cites pages that already rank in the top 10 on Google. If your site doesn’t have basic SEO health, it may never enter the retrieval pool that generative models draw from.

    On the flip side, SEO alone won’t save you. A brand can rank first on Google for a competitive keyword and remain completely invisible in ChatGPT or Perplexity, platforms where an increasing share of high-intent users are starting their research. The HubSpot case made this concrete: the company saw organic traffic drop from 13.5 million to 8.6 million as top-of-funnel informational queries were captured by zero-click AI overviews. The traffic didn’t disappear. It moved channels.

    The bottom line: SEO Score and GEO Score aren’t competing metrics. They’re parallel ones. Ignoring either means you’re leaving a meaningful portion of your addressable market on the table.

    GEO Score Is a Baseline, Not a Monitoring System

    Here’s where a lot of teams get stuck. They run a GEO Score check, feel good about the number, and move on. But a GEO Score is a static snapshot. It reflects your content’s cite-worthiness at a single point in time.

    The actual AI citation landscape is volatile. The same prompt that surfaces your brand today may surface your competitor tomorrow if they publish fresher data or a more concise answer. AI platforms update their retrieval logic. New prompts emerge. Competitors optimize in real time.

    That’s the limitation the score can’t solve on its own.

    The brands that are pulling ahead in 2026 are treating GEO as a continuous monitoring problem, not a one-time audit. That means tracking not just whether you have a high score, but whether you’re actually appearing in AI responses, how often, where in the response, and with what sentiment.

    Topify tracks exactly that across ChatGPT, Perplexity, Gemini, DeepSeek, and other major AI platforms using seven core metrics: Visibility Rate (how often you appear across relevant prompts), Position Score (where in the recommendation order), Sentiment Score (tone of the AI’s description), Intent Coverage (spread across informational, comparative, and transactional queries), Source Citation Frequency (which of your URLs are being pulled), Share of Voice benchmarked against competitors, and Conversion Visibility tied to referral traffic.

    The workflow that makes sense right now: use a GEO Score Checker to establish your content baseline, then use Topify to track whether that baseline is translating into actual citations, and where those citations are shifting over time.

    Most brands currently have an AI citation rate near zero. Reaching 10-12% citation frequency across relevant category queries is considered top-tier performance for 2026. You can’t close that gap if you don’t know where you’re starting from or how it’s moving.

    Conclusion

    GEO isn’t SEO rebranded. It’s a separate measurement of a separate capability: can an AI find your content, understand it, trust it, and cite it in the answers it generates for your potential customers?

    The misunderstanding that GEO is just “SEO 2.0” is exactly what lets more agile brands with smaller domains outrank legacy players in AI-generated responses. You don’t need ten years of link building to win on Perplexity. You need factual density, structural clarity, and consistent presence across the right information channels.

    Check your GEO Score first with Topify’s GEO Score Checker to see where you stand today. Then build the monitoring layer to track where you’re moving, because in a landscape where AI models update their retrieval logic without announcement, a one-time score is just the starting line.

    FAQ

    Q: Is GEO Score the same as AEO (Answer Engine Optimization) score?

    They’re closely related but not identical. AEO focuses on becoming the direct answer: featured snippets, voice assistant responses, zero-click results. GEO is broader. It covers how AI models perceive and recommend your brand across conversational interactions generally, including the technical RAG pipeline that governs retrieval. Think of AEO as a subset of GEO, focused on format and conciseness.

    Q: Can I have a high GEO Score but a low SEO Score?

    Yes. A site with excellent, well-structured, data-rich content can score well on GEO while having a thin backlink profile that limits Google rankings. That brand might get cited regularly by Perplexity or Claude, while remaining invisible in Google’s AI Overviews, which skews heavily toward existing top-10 organic results. The scores measure different things and don’t move in lockstep.

    Q: How often should I check my GEO Score?

    A static GEO Score check is worth doing at least monthly. But in competitive sectors like SaaS, fintech, or B2B software, monthly snapshots aren’t enough to catch shifts in citation patterns as they happen. Real-time monitoring through a platform like Topify is the more useful setup for brands where AI visibility directly affects lead generation.

    Q: What’s a good GEO Score to aim for?

    There’s no universal benchmark, but context matters: most brands are currently at near-zero AI citation rates. Reaching 10-12% citation frequency across relevant category prompts puts you in the top tier for 2026. The GEO Score tells you whether your content is structurally ready to be cited. Hitting that citation rate is a function of ongoing optimization.

    Q: Does improving my SEO Score automatically improve my GEO Score?

    Not necessarily. Building more backlinks improves your Google rankings but doesn’t make your content more machine-readable. If your top-ranked pages are dense, unstructured text without statistics, clear definitions, or cited sources, your GEO Score will stay low regardless of your domain authority. The two scores require distinct optimization work.

    Read More

  • Claude 4.7 vs GPT-5.5: Who Actually Wins in 2026?

    Claude 4.7 vs GPT-5.5: Who Actually Wins in 2026?

    Both launched within a week of each other. Both offer a 1,000,000-token context window. Both charge $5.00 per million input tokens. On paper, the spec sheet makes the choice look like a coin flip.

    It isn’t.

    Beneath the pricing parity, a measurable performance gap has emerged across benchmarks, real-world coding tasks, and total cost of ownership. The difference between choosing the right model and the wrong one isn’t bragging rights — for teams running high-volume agentic workflows, it can translate to a cost variance of over 300% in production.

    Here’s what the data actually shows.

    The Claude 4.7 vs GPT-5.5 Spec Sheet: What Parity Looks Like (and Where It Ends)

    Claude Opus 4.7 launched on April 16, 2026. GPT-5.5 followed seven days later on April 23. Both arrived with identical context windows and the same entry-level API rate.

    SpecificationClaude Opus 4.7GPT-5.5
    Release DateApril 16, 2026April 23, 2026
    Context Window1,000,000 tokens1,000,000 tokens
    Max Output128,000 tokens128,000 tokens
    Input ModalitiesText, Image, PDF, CodeText, Image, Audio, Code
    Core ArchitectureAdaptive ThinkingAgentic Reasoning (“Spud”)

    The surface-level similarity is intentional. Both Anthropic and OpenAI have converged on the same frontier spec as a baseline. The actual differentiation lives in architecture, and that difference shows up fast when you push either model into production.

    Benchmark Scores: Where Claude 4.7 Leads and Where GPT-5.5 Pulls Ahead

    The 2026 benchmark landscape reveals a pattern of “specialized dominance” rather than one clear winner across all tasks. Claude Opus 4.7 holds a consistent edge in hard scientific reasoning and precision engineering. GPT-5.5 dominates in autonomous tool use and terminal-based orchestration.

    BenchmarkClaude Opus 4.7GPT-5.5Winner
    GPQA Diamond94.2%93.6%Claude (+0.6%)
    HLE (no tools)46.9%41.4%Claude (+5.5%)
    HLE (with tools)54.7%52.2%Claude (+2.5%)
    SWE-Bench Pro64.3%58.6%Claude (+5.7%)
    FinanceAgent v1.164.4%60.0%Claude (+4.4%)
    Terminal-Bench 2.069.4%82.7%GPT (+13.3%)
    τ²-Bench (Telecom)88.6%98.0%GPT (+9.4%)
    ARC-AGI-268.3%83.3%GPT (+15.0%)
    OSWorld-Verified78.0%78.7%GPT (+0.7%)
    MMMU (Vision)91.5%~92.4%GPT (slight)

    The margin that matters most for engineering teams: SWE-Bench Pro at 64.3% for Claude vs. 58.6% for GPT-5.5 is a 5.7-point gap in real-world codebase navigation. For autonomous tool orchestration, GPT-5.5’s Terminal-Bench 2.0 score of 82.7% versus Claude’s 69.4% is a 13-point lead that compounds across every automated pipeline run.

    Neither model is universally superior. The question is which benchmark reflects your actual workflow.

    Claude 4.7’s “Adaptive Thinking” vs GPT-5.5’s “Spud” Architecture

    Claude Opus 4.7 introduces Adaptive Thinking, a mechanism that dynamically allocates internal reasoning tokens based on prompt complexity. In practice, it pauses on ambiguous architectural decisions rather than charging forward with a potentially destructive assumption.

    GPT-5.5’s “Spud” architecture is optimized for momentum. It’s designed to keep tasks moving as an autonomous agent, which makes it faster at execution but more likely to miss edge cases that require deliberate internal verification.

    On ARC-AGI-2 — a test of novel out-of-distribution reasoning — GPT-5.5 scores 83.3% vs Claude’s 68.3%. That’s a meaningful lead in “cold start” logic. For multi-step architectural refactoring that requires domain knowledge already in context, Claude’s thoroughness pays off.

    The Real Pricing Comparison: Why $5/MTok Tells Half the Story

    Both models list at $5.00 per million input tokens. That number is accurate and also almost irrelevant for high-volume users.

    Pricing DimensionClaude Opus 4.7GPT-5.5Impact
    Input (per 1M tokens)$5.00$5.00Parity on short context
    Output (per 1M tokens)$25.00$30.00GPT is 20% higher per output token
    Long Prompt Surcharge2x above 200K tokensNoneClaude: $10/MTok input, $37.50/MTok output
    Prompt Caching90% savingsAvailable (variable)Critical for RAG/coding agents
    Batch Discount50%50%Standard for async workflows
    Tokenizer Efficiency1.0x–1.35x baseline~0.6x (optimized)GPT is ~2x more efficient per string

    Claude 4.7’s new tokenizer improves accuracy but reduces token density. For the same Python code or English text, Claude can consume between 1.0x and 1.35x more tokens than its previous generation. GPT-5.5 runs in the opposite direction: it produces 72% fewer output tokens than Claude 4.7 for identical tasks.

    That efficiency gap compounds fast. A software engineering agent running 500 tasks per day hits an estimated monthly cost of ~$4,050 on Claude Opus 4.7 without caching. The same workload on GPT-5.5, factoring in token efficiency and the absence of long-prompt surcharges, comes in significantly lower.

    One important offset: Claude’s 90% prompt caching discount is aggressive. For RAG workflows or agentic loops with high context reuse, that discount can partially close the efficiency gap.

    Speed and Reliability: The Latency Gap That Shapes User Experience

    Time-to-first-token (TTFT) has split into two separate metrics in 2026: one for interactive experiences, one for background automation. Claude and GPT-5.5 are optimized for opposite ends of that spectrum.

    Claude Opus 4.7 streams its first token in approximately 0.5 seconds. For live customer support, real-time coding assistance, or chat interfaces, that speed creates a near-instant response feel. GPT-5.5’s TTFT baseline sits around 3.0 seconds — acceptable for background agents, but noticeably sluggish for interactive use cases.

    For enterprises concerned about vendor stability: Anthropic is projected to reach positive cash flow by 2027, backed by enterprise partnerships via Amazon Bedrock and Google Cloud. OpenAI serves 900 million weekly active users but is projected to burn $14 billion in 2026, with cumulative losses potentially reaching $115 billion by 2029. GPT-5.5’s “Priority” tier (at 2.5x standard cost) provides SLA-backed reliability for mission-critical workloads — but that’s an additional budget line worth factoring into enterprise procurement decisions.

    Where Claude 4.7 Wins: The Case for Precision Over Speed

    Claude Opus 4.7 is the better tool when the cost of a mistake is high.

    Its 64.3% score on SWE-Bench Pro makes it the most reliable option for multi-file architectural changes where a single regression bug can block a release. It maintains stronger coherence for projects exceeding 10,000 lines of code, with higher retrieval accuracy for context buried in the middle of long files.

    For legal and financial analysis, Claude’s self-verification mechanism — double-checking citations and logic before finalizing a response — measurably reduces hallucination rates compared to the more execution-forward GPT-5.5.

    For content and marketing teams, Claude 4.7 holds an edge in long-form writing. It maintains structural integrity for documents exceeding 1,500 words and adheres more reliably to “negative constraints” — if you tell it not to use certain terms or writing styles, it sticks to those instructions with greater fidelity than GPT-5.5.

    Its 3.75-megapixel vision input also makes it the stronger choice for extracting data from dense financial charts, medical diagrams, or complex architectural blueprints.

    Where GPT-5.5 Wins: The Case for Velocity and Scale

    GPT-5.5 is the better tool when throughput matters more than thoroughness.

    Its 82.7% on Terminal-Bench 2.0 is the benchmark that defines agentic workflow performance in 2026. For data pipelines, server maintenance, and multi-step web research with browsing tools, GPT-5.5 is the safer operator. Its native integration with Google Sheets and Excel allows it to function as a junior analyst — building workbooks, linking formulas, and generating dashboards without human intervention.

    The token efficiency advantage is compounding at scale. For teams running millions of tokens per day in background loops, Claude’s long-prompt surcharge and higher tokenizer density make GPT-5.5 the only economically viable option for large production pipelines. Paying 20% more per output token is manageable at low volume; it becomes a budget problem at enterprise scale.

    For audio input workflows, GPT-5.5’s native audio modality support is also a structural advantage Claude 4.7 doesn’t yet match.

    Which Model to Use: A Decision Guide by Team Type

    The right choice depends on what you’re optimizing for: precision or throughput, interactive latency or batch efficiency, vendor stability or ecosystem depth.

    For developers and technical teams: Default to GPT-5.5. Its speed, token efficiency, and tool orchestration performance make it the better general-purpose operator for coding agents and CI/CD pipelines. Switch to Claude 4.7 for architectural refactors, security audits, or any multi-file reasoning where a single mistake has downstream costs.

    For marketing and content teams: Default to Claude 4.7. Its long-form writing quality, negative constraint adherence, and deep document analysis are currently ahead of GPT-5.5 for whitepaper-grade content. Use GPT-5.5 for high-volume data analysis, competitor research synthesis, or spreadsheet automation.

    For enterprise IT procurement: Claude 4.7 carries lower long-term vendor risk, given Anthropic’s financial trajectory and Constitutional AI safety framework. If your organization is already deep in the OpenAI ecosystem and needs high-throughput consumer-facing access, GPT-5.5 Priority remains viable — but budget the 2.5x premium.

    The optimal strategy for 2026 isn’t picking one. Leading engineering teams are implementing model routing layers: GPT-5.5 for execution and information gathering, Claude 4.7 for review and high-stakes logic verification. The two models are increasingly used as complements, not competitors.

    Your Brand’s Visibility Across Both Models: The Metric You’re Not Tracking

    Choosing between Claude 4.7 and GPT-5.5 is a model selection decision. But there’s a separate question most teams aren’t asking yet: which model is recommending your brand, and how?

    AI engines like ChatGPT and Claude are now responsible for over 50% of B2B software research in 2026. A brand may be the default recommendation in GPT-5.5 because it has strong structured directory presence, while being ignored by Claude 4.7 because it lacks narrative clarity in long-form sources. That visibility gap is invisible to traditional SEO dashboards.

    Topify tracks brand mention frequency, recommendation position, and sentiment scores across both Claude and ChatGPT in real time. Its Visibility Tracking and Competitor Monitoring features let marketing teams identify exactly which trigger prompts lead to a recommendation and which content gaps are causing Claude or GPT to surface a competitor instead.

    As both models continue to iterate, their recommendation maps shift. Monitoring both separately gives teams the data to close the visibility gap before it becomes a revenue gap.

    Conclusion

    The 2026 model decision isn’t about which system has the better MMLU score. It’s about matching architecture to workload. GPT-5.5’s token efficiency, tool orchestration, and execution speed make it the engine for automated, high-volume pipelines. Claude 4.7’s reasoning depth, self-verification, and long-form precision make it the right tool for work where a single error carries real cost.

    For most teams, the answer is both: GPT-5.5 as the operator, Claude 4.7 as the reviewer. The next layer of competitive advantage isn’t choosing between them — it’s tracking how each model presents your brand to the millions of users who now start their research in AI search rather than Google.

    FAQ

    Q: Is Claude 4.7 better than GPT-5.5 for coding? 

    A: It depends on the task type. Claude 4.7 leads in code review, architectural refactoring, and catching subtle edge cases (SWE-Bench Pro: 64.3% vs 58.6%). GPT-5.5 is the stronger operator for high-velocity feature builds, tool orchestration, and automated pipelines (Terminal-Bench 2.0: 82.7% vs 69.4%). For most engineering teams, the optimal approach is using both in sequence.

    Q: Which model has lower API costs in 2026? 

    A: Both start at $5/MTok input, but GPT-5.5 is significantly cheaper for long-context and high-volume workloads. It produces 72% fewer output tokens for identical tasks and carries no surcharge for prompts over 200K tokens. Claude 4.7 applies a 2x premium on long prompts ($10/MTok input, $37.50/MTok output), which becomes a major budget factor in large codebases or document-heavy workflows.

    Q: Can I use both Claude 4.7 and GPT-5.5 in the same workflow? 

    A: Yes, and it’s increasingly standard practice. The 2026 best-practice pattern is model routing: GPT-5.5 handles information gathering, drafting, and execution; Claude 4.7 handles final logic verification, architectural review, and polishing. The two models’ complementary strengths make them more effective in combination than either is alone.

    Q: How do I know which AI model recommends my brand more often? 

    A: Platforms like Topify track brand mention frequency and recommendation position across both Claude and ChatGPT separately, providing real-time visibility scores and sentiment analysis. This data is not available through traditional SEO tools, which don’t measure how generative models present your brand in their answers.

    Read More