Category: Knowledge

  • Most AI Rank Checkers Give You a Number That Means Nothing

    Most AI Rank Checkers Give You a Number That Means Nothing

    Your weekly report says “AI rank: #3.” Last week it said #5. Your VP asks the obvious question: what did we do right?

    You don’t have an answer. Not because you didn’t do the work, but because the AI rank checker that produced the number can’t tell you which prompts it tested, how often it sampled, or why the position moved. The number exists. Its meaning doesn’t.

    This isn’t a tooling inconvenience. It’s a measurement model imported from a world that no longer applies. Here’s why the single-score approach breaks down in AI search, and what a rank actually needs to include before you can act on it.

    The Number on Your AI Rank Checker Dashboard Is an Average of Averages

    Traditional rank trackers were built for a deterministic system. Google returned ten blue links, your URL sat in one position, and that position was defensible and repeatable. Ask again tomorrow, get roughly the same answer.

    AI search doesn’t work like that. Large language models are probabilistic systems built on retrieval-augmented generation. Temperature settings, parallel GPU processing, and real-time index refreshes mean the same prompt can produce different answers within the same hour. Research from Equal Experts on LLM non-determinism confirms what anyone who’s re-run a ChatGPT query already suspects: generation isn’t exactly reproducible, by design.
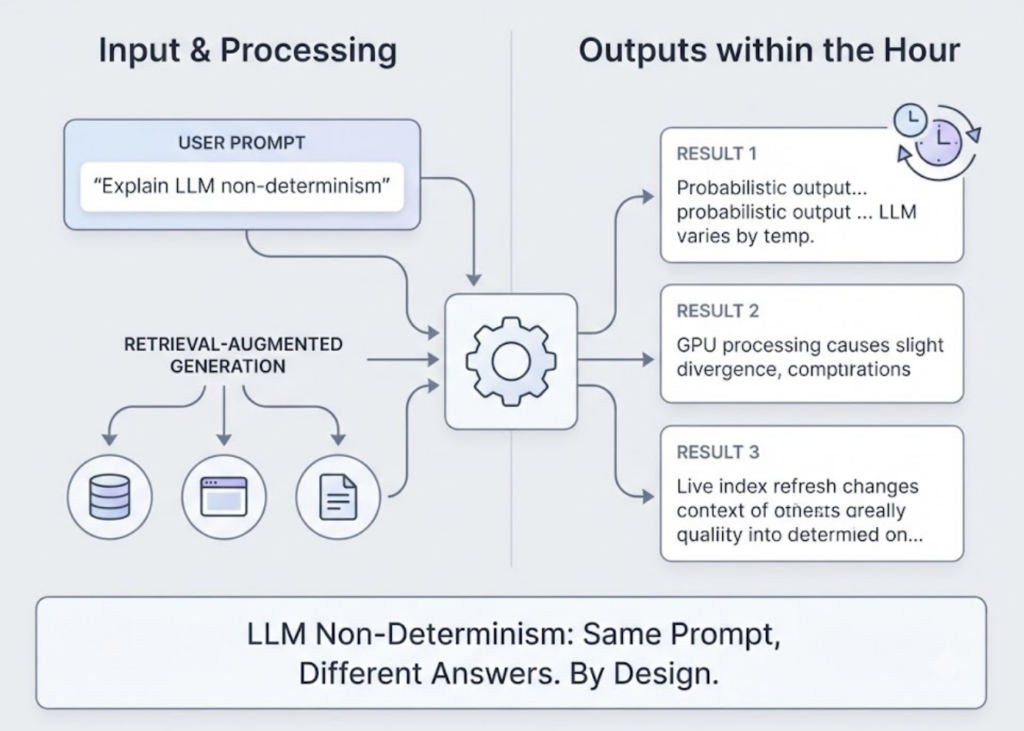
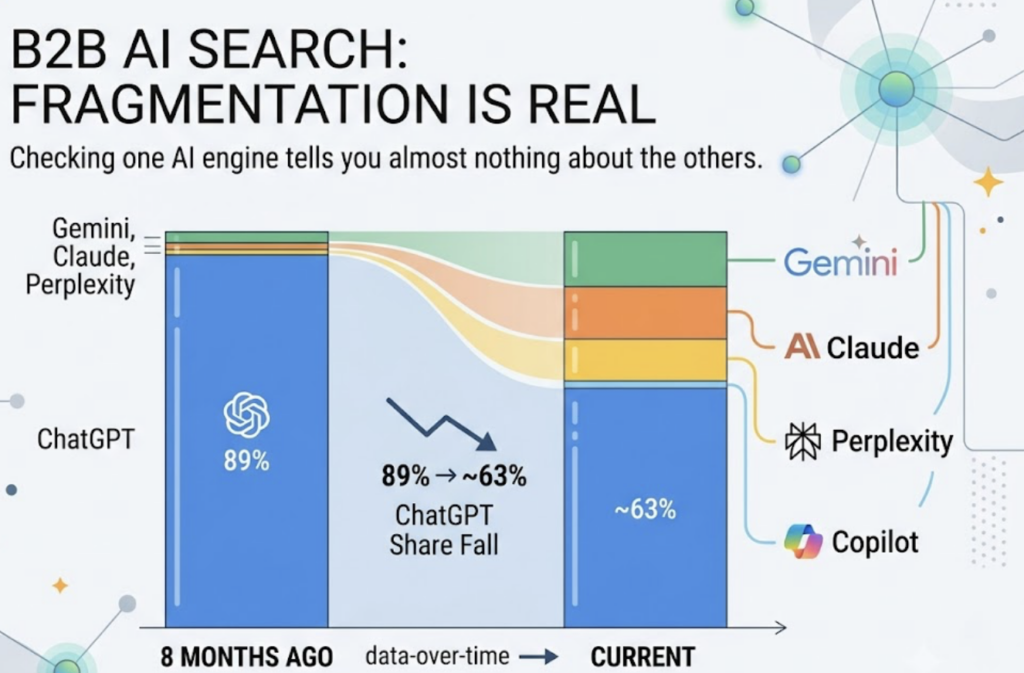
    The instability runs deeper than answer wording. According to a 2026 Digital Authority Partners analysis, only 10.6% of URLs cited by AI engines persist across a 28-day window. Put differently, 89% of AI visibility wins are gone within a month. Citation behavior is a flow, not a stock.

    Now consider what most AI rank checkers do with that volatility. They query a small, static set of prompts, at a handful of sampling times, on one or two platforms. Then they compress everything into a single number.

    That number is noise wearing the costume of a metric.

    A “rank #3” snapshot can convince a team they’re winning while the brand is absent from 80% of relevant variations of the same query. The tool isn’t lying. It’s just answering a question nobody should be asking: “where did we rank in one sample, at one moment, on one phrasing?”

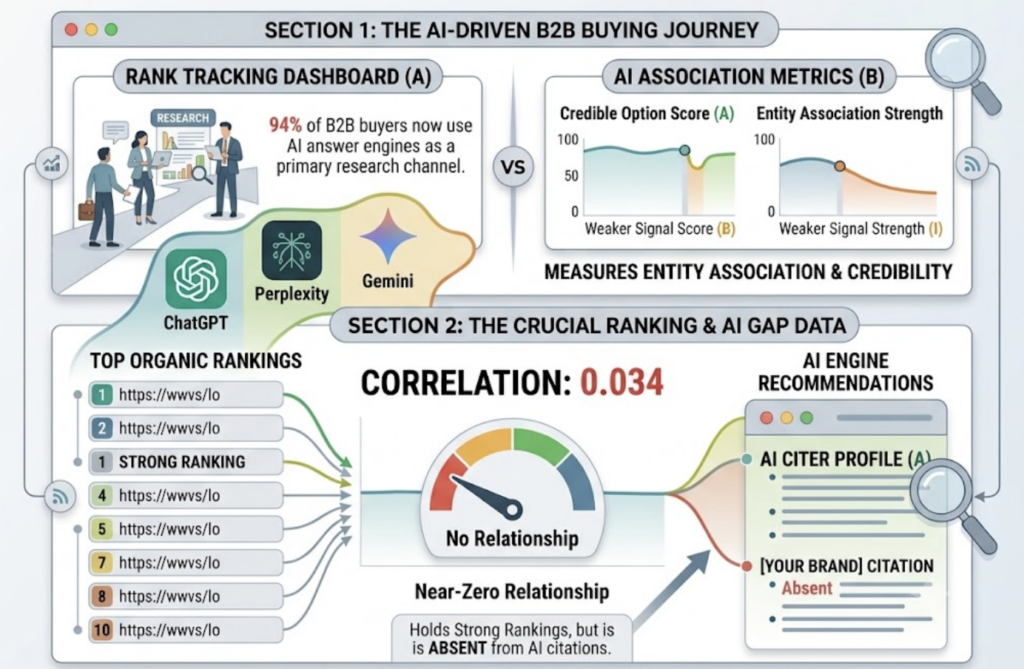
    Ranking Position and Getting Mentioned Are Two Different Games

    Here’s the structural shift most rank trackers miss entirely. In traditional SEO, ranking and visibility were the same thing: if you weren’t in the top 10, you were invisible. In AI search, they’ve split into two separate questions.

    The first question is whether you appear at all. Mention rate, the percentage of relevant prompts where AI names your brand, is the gating metric. The second question is where you appear when you do. Position only matters after inclusion is solved.

    A single rank score collapses these into one number, and the collapse hides the failure mode that matters most. A brand can hold “position #2” on the three prompts a tool happens to test while being completely absent from the dozens of adjacent prompts real buyers actually ask.

    There’s a second split hiding inside the first: mentioned is not the same as cited. Yext’s research across 17.2 million citations shows AI engines treat naming a brand in text and linking to it as a source as distinct behaviors. An AI answer can rank your brand #2 in a listicle-style response without citing your website once. If the goal is traffic or authority signals, that’s a zero-click event your rank checker records as a win.

    Track it. Decompose it. Then decide what to fix.

    Three Things a Single Score Can’t Tell You

    Even a statistically clean score would still be an abstraction. Three performance drivers disappear inside it.

    Which prompts the number came from

    Appearing first for 100 low-intent research queries is mathematically great for a rank checker and commercially worthless for you. Prompt intent isn’t a nuance here, it’s the whole game.

    Research on citation stability shows the pattern clearly. Discovery prompts carry the highest volatility, because AI engines experiment with options. Comparison prompts are more stable, since AI leans on structured comparison data. Validation prompts are the harshest of all: AI prioritizes proven, authoritative, fact-checked sources when a user is confirming a decision.

    The strategic implication is uncomfortable. A brand can post a strong average rank built entirely on volatile discovery prompts while failing to appear in the validation prompts where purchase decisions actually get made. The dashboard shows green. The pipeline shows nothing.

    Why the number moved

    A score change is an effect, not a cause. When an AI engine drops your brand, it’s typically because it found a fresher or more authoritative source for the same claim. The cause lives in the citation layer: which domains the AI pulls from, and whether yours got displaced.

    Rank checkers report the score changed. They rarely tell you the source was overtaken. Without source attribution, every fluctuation triggers the same unproductive ritual: someone asks why, nobody knows, everyone waits to see if next week’s number recovers on its own.

    How AI describes you when it does mention you

    Position captures where you appear. It says nothing about the frame. An AI answer can rank your product #1 while describing it as “a low-cost budget alternative,” which is a quiet disaster if you’ve spent two years positioning as enterprise-grade.

    This narrative layer, what some researchers call the brand’s narrative footprint, is invisible to any tool that reduces AI presence to a coordinate. Sentiment and framing determine whether a mention builds your positioning or erodes it.

    What a Meaningful AI Rank Actually Requires

    Strip away the single-score abstraction and a workable measurement framework has five requirements. None of them is exotic. All of them are absent from most AI rank checkers.

    RequirementWhat it means in practiceWhat the single score hides
    Prompt-level granularityEvery data point traces to a specific, visible promptWhether the prompts tested carry any buyer intent
    Mention rate before positionInclusion tracked separately from orderingAbsence across the majority of relevant prompts
    Longitudinal samplingRepeated tests that smooth out non-determinismWhether a rank is signal or single-sample noise
    Citation source attributionWhich domains the AI cites, and when yours is displacedThe cause behind every score movement
    Sentiment and framingHow the AI characterizes the brand in each answerNarrative drift that contradicts your positioning

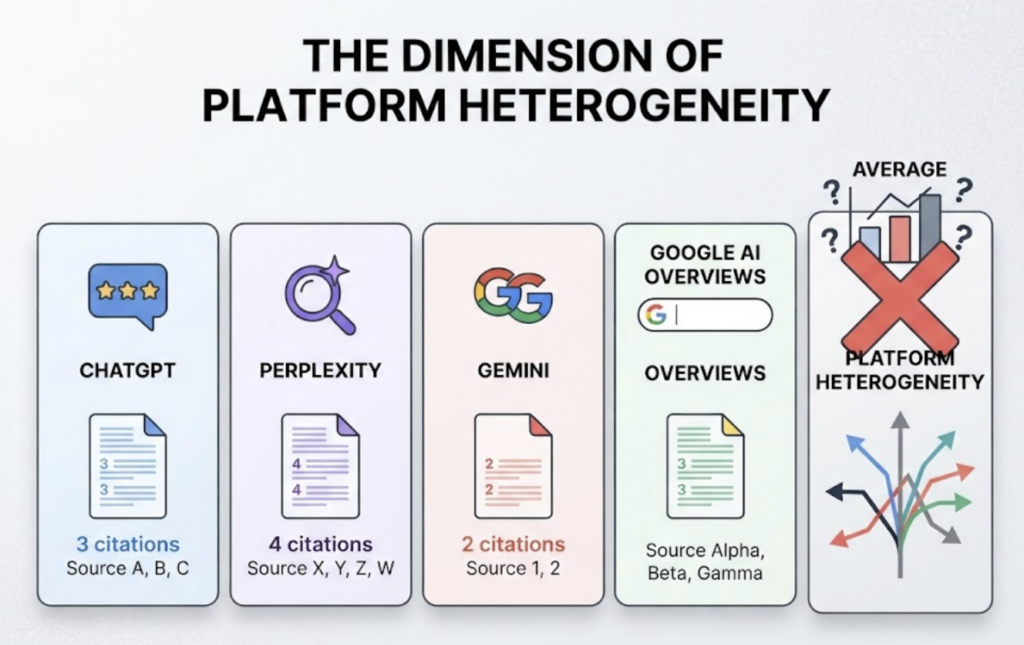
    Add one more dimension across all five: platform heterogeneity. ChatGPT, Perplexity, Gemini, and Google AI Overviews cite differently and rarely agree. A number averaged across platforms, or worse, sampled from just one, tells you almost nothing about the others.
    This is the bar. A tool that clears it gives you answerable questions instead of a floating number.

    How Topify Turns a Meaningless Number into Seven Answerable Questions

    Once you’ve accepted that “rank” needs to be decomposed, the practical question is what to decompose it into. Topify approaches this with a seven-metric matrix inside its Comprehensive GEO Analytics: visibility, sentiment, position, volume, mentions, intent, and CVR. Each metric maps to one of the failure modes above.

    Position Tracking handles ranking the way AI search actually requires: at the prompt level, relative to named competitors, sampled repeatedly rather than snapshotted. Instead of “your rank is #3,” you see which specific prompts place you where, and against whom. That’s the difference between a score and a diagnosis.

    Source Analysis answers the “why did it move” question directly. It tracks the exact domains and URLs each AI platform cites for your prompt set, so when your mention rate drops, you can see which source displaced yours instead of guessing. Given that roughly nine in ten cited URLs churn within a month, this layer is where most of the actionable signal lives.

    AI Volume Analytics addresses the intent problem. It surfaces which prompts carry real query volume and buyer intent, so you’re not optimizing your average by winning prompts nobody commercially relevant is asking. Sentiment scoring runs alongside, flagging when AI engines frame your brand in ways that contradict your positioning.

    Coverage spans ChatGPT, Gemini, Perplexity, Google AI Overviews, DeepSeek, and other major engines, which matters because cross-platform disagreement is the norm, not the exception. The Basic plan runs $99/month with 100 tracked prompts and 9,000 AI answer analyses, and there’s a 30-day trial if you’d rather validate against your own prompt set before committing. For teams still earlier in the process, this open reference list of free GEO tools is a reasonable place to benchmark what free checkers can and can’t see.

    The point isn’t that more metrics are automatically better. It’s that these specific seven correspond to questions a VP will actually ask, and a single rank number answers none of them.

    How to Audit the AI Rank Checker You’re Already Using

    You don’t need to switch tools to start fixing this. Start by auditing the one you have against five questions:

    1. Can you see the exact prompts behind every number? If the prompt set is hidden or fixed, the score is untraceable.
    2. Does it separate mention rate from position? If one number covers both, you can’t tell absence from low ranking.
    3. Does it distinguish mentions from citations? A brand named in text without a linked source is a zero-click event, not a traffic win.
    4. How often does it sample? Point-in-time snapshots can’t smooth out LLM non-determinism. Look for repeated, longitudinal testing.
    5. Which platforms does it cover? Performance is rarely consistent across ChatGPT, Perplexity, Gemini, and AI Overviews. One platform is an anecdote.

    If your current tool fails three or more of these, the number it gives you each week isn’t measuring your AI visibility. It’s measuring the tool’s sampling artifacts.

    Conclusion

    The next time someone asks what your AI rank means, you should be able to answer in specifics: which prompts, what mention rate, which sources, what framing, across which platforms. If your tool can’t support that answer, the number on the dashboard was never information. It was decoration.

    Start with the five-question audit above. Then rebuild your reporting around mention rate and citation sources first, position second. The teams treating AI visibility as a decomposable system, rather than a single score to celebrate or panic over, are the ones who’ll know what they did right when the number moves.

    FAQ

    Q: What is an AI rank checker?
    A: An AI rank checker is a tool that tracks where a brand appears in AI-generated answers across platforms like ChatGPT, Perplexity, and Google AI Overviews. Basic checkers output a single position or score. More complete platforms decompose that into prompt-level position, mention rate, citation sources, and sentiment.

    Q: Why do AI rankings change every time I check?
    A: LLMs are non-deterministic by design. Temperature settings, parallel processing, and continuous index updates mean identical prompts produce varying answers. Research shows only about 10.6% of AI-cited URLs persist across 28 days, so single-sample rankings are largely noise. Repeated longitudinal sampling is the only way to separate signal from variance.

    Q: What’s the difference between AI search ranking and brand mentions?
    A: They’re independent metrics. Mention rate measures how often your brand appears at all across relevant prompts, while ranking measures your position when you do appear. A brand can rank #2 on a few tested prompts while being absent from most others. Mention rate is the gating metric; position matters only after inclusion.

    Q: What does an AI visibility score mean?
    A: On its own, usually very little. A visibility score is an aggregate abstraction that compresses prompt selection, sampling frequency, platform coverage, and citation behavior into one number. It becomes meaningful only when you can trace it back to specific prompts, mention rates, and cited sources.
    Read More

  • ChatGPT Runs Ads, Perplexity Won’t: AI Rank Checker Impact

    ChatGPT Runs Ads, Perplexity Won’t: AI Rank Checker Impact

    You run your category prompt through ChatGPT and a competitor shows up in the answer. Six months ago, that meant one thing: the model’s retrieval layer picked them organically. Now it might mean something else entirely. They could have paid for that placement. Your traditional rank tracker has one column for “position.” AI search just split into two ranking systems, paid and organic, and most tools can’t tell you which one you’re looking at. That’s the gap an ai rank checker has to close in 2026.

    Two AI Platforms Just Split the Definition of Ranking

    In the span of five weeks, the two most-watched AI search companies took opposite bets on the same question: should answers carry ads?

    OpenAI moved first. The company announced ChatGPT advertising on January 16, 2026, with the US rollout starting in early February for users on the Free and $8/month Go tiers. Plus, Pro, Team, and Enterprise subscribers stay ad-free. Sponsored units appear alongside responses, matched to conversation context rather than keyword bids.

    Perplexity went the other way. On February 18, 2026, the company abandoned advertising entirely and committed to a subscription-only model. This wasn’t a company that never tried ads. Perplexity was among the first to test sponsored placements back in 2024, then spent a year phasing them out. One executive put the reasoning bluntly: “the challenge with ads is that a user would just start doubting everything.”

    The result is a structural fork. “Ranking” in ChatGPT now means two different things depending on whether money changed hands. Ranking in Perplexity means exactly one thing: the retrieval system judged your brand worth citing.

    Your measurement stack has to handle both realities at once.

    Inside ChatGPT’s Ad Machine and What an AI Rank Checker Sees

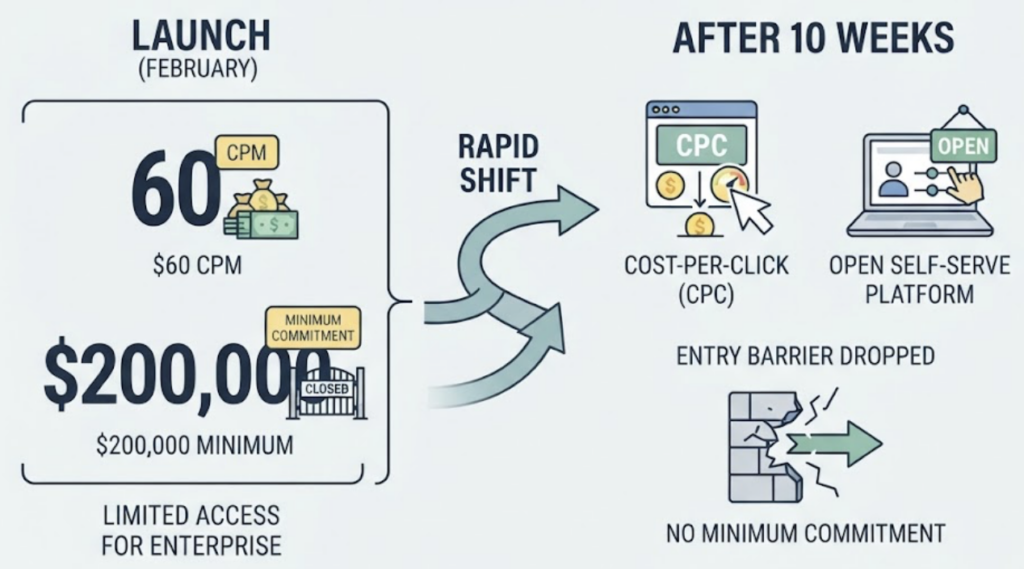
    The speed of ChatGPT’s ad expansion caught most marketing teams flat-footed. The February launch started at $60 CPM with a $200,000 minimum commitment, pricing that limited buyers to a narrow set of enterprise brands. Within ten weeks, OpenAI shifted to cost-per-click bidding, opened a self-serve platform, and dropped the entry barrier entirely.

    Penetration followed. By late May 2026, monitoring data put ads in 49.1% of US ChatGPT responses, with CPCs running $3 to $5 for general categories and $8 to $18 for software and finance. For comparison, that US ad rate is roughly 24 times Google’s classic SERP rate.

    Here’s what this means for anyone checking AI rankings. The same prompt now produces different visible results depending on who’s asking. A free-tier user sees sponsored units a paid subscriber never encounters. A brand that “appears in ChatGPT” might be renting that presence week to week, while its organic mention rate sits at zero.

    OpenAI maintains that ads don’t influence the actual answers. Take that at face value, and the implication is still sharp: paid slots and organic mentions are separate inventory, governed by separate rules.

    Why Paid Placement Isn’t the Ranking You Should Track

    A paid slot is a lease. It lasts as long as the budget does, it’s visible to only part of the user base, and it disappears the moment a competitor outbids you.

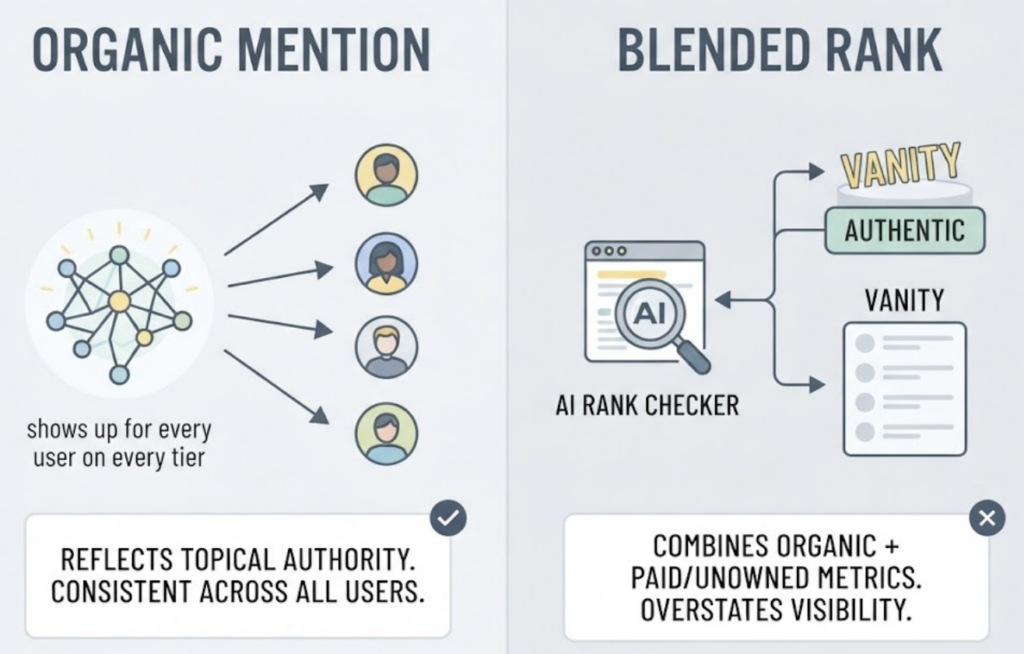
    An organic mention is different. It reflects what the model’s retrieval and synthesis layers concluded about your topical authority, and it shows up for every user on every tier. When an ai rank checker reports your position, the number only means something if it’s measuring this second category. Blending the two produces a vanity metric that overstates visibility you don’t actually own.

    Perplexity’s Zero-Ad Bet Makes Organic Rank the Only Rank

    Perplexity’s retreat looks less risky once you see the numbers behind it. Advertising never became meaningful revenue for the company; the business runs on subscriptions ranging from $20 to $200 per month, and leadership has said usage-based subscriptions represent the right long-term model for AI.

    That subscriber base skews toward exactly the audience B2B marketers struggle to reach: professionals in finance, legal, healthcare, and consulting who pay for accuracy. There is no sponsored path in front of them. Every brand that appears in a Perplexity answer earned the citation through content the engine deemed authoritative.

    On a zero-ad platform, citation share is the entire game.

    This changes what tracking should measure. Position still matters, but the deeper signal is which domains and URLs Perplexity pulls into its synthesis, how often your brand appears across a prompt set, and whether the surrounding sentiment helps or hurts. A negative citation on a trust-first platform can do more damage than absence.

    How to Rebuild Your AI Rank Checking Stack for a Split Market

    Traditional rank trackers were built for deterministic results: one query, one ordered list, one position per domain. Generative answers break every one of those assumptions, and the ad split breaks them further. A stack built for 2026 needs four capabilities.

    Platform-specific tracking. ChatGPT and Perplexity now run on different commercial logic, so their numbers can’t be averaged into one score. You need separate baselines per engine, plus visibility into how ad-supported and ad-free ChatGPT tiers differ.

    Paid versus organic segregation. Any tool that can’t tell a sponsored unit from an organic mention will inflate your visibility data. This distinction should be a first-class field in every report, not a footnote.

    Citation intelligence. The focus shifts from “what position” to “which sources.” Knowing that Perplexity cites a competitor’s comparison page in 40% of category prompts tells you exactly what content to build.

    Sentiment and context. Presence without favorable framing is a liability. Tracking has to capture how the model describes you, not just whether it does.

    For teams putting this into practice, Topify covers all four layers in one platform. Its Position Tracking monitors where your brand lands in AI answers relative to competitors, measured on the organic side rather than the rented one. Visibility Tracking runs the same prompt sets across ChatGPT, Perplexity, Gemini, and other engines so the platform-by-platform divergence becomes visible instead of averaged away. Source Analysis reverse-engineers the exact domains AI platforms cite, which is the practical answer to winning Perplexity’s zero-ad environment. And Competitor Monitoring shows whether a rival’s sudden ChatGPT presence comes from earned authority or an ad budget, which determines whether you should respond with content or with spend.

    If you want to gauge the problem before committing to a platform, a set of free GEO tools can establish a quick baseline of where your brand currently stands.

    What This Split Means for Your 2026 Visibility Budget

    The temptation is to treat ChatGPT ads as the fast lane and skip the slower organic work. The economics argue against that as a standalone strategy.

    AI referral traffic is still a small slice of total web traffic, but industry benchmark studies through 2026 have measured conversion rates around 14.2% for IT and B2B services from AI referrals, versus roughly 2.8% from traditional Google organic. High intent, small volume, outsized value per visit. Paid slots capture some of that intent, but only on one platform, only for ad-tier users, and only while you keep paying.

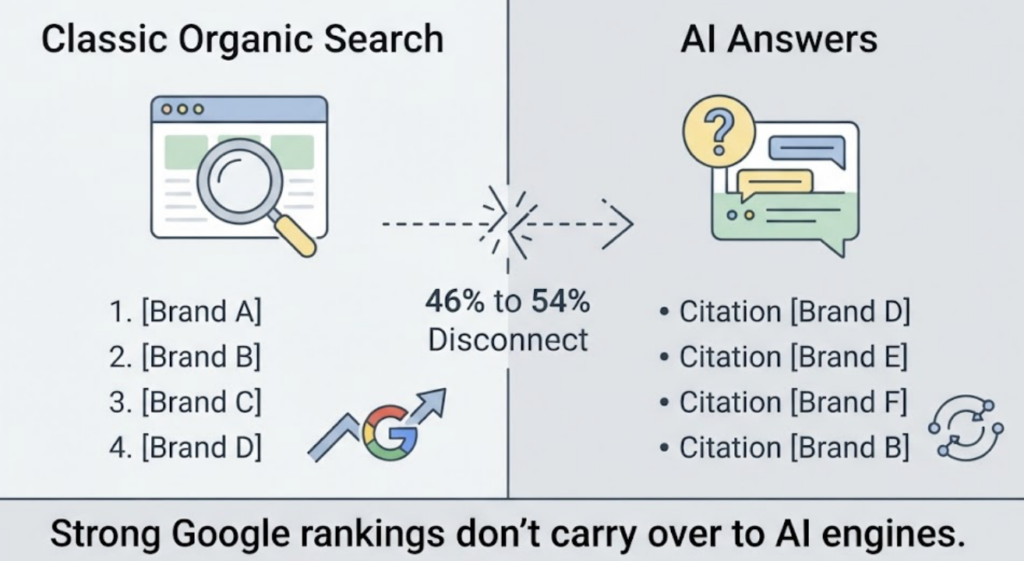
    Meanwhile, the same benchmark research points to a 46% to 54% disconnect between brands cited in classic organic search and brands cited in AI answers for identical queries. Strong Google rankings don’t carry over. AI engines tend to favor structured, extractable content: question-based headers, schema markup, self-contained comparisons.

    So the rational budget is a dual strategy. Use paid ChatGPT placements tactically for a handful of high-intent prompts where immediate presence justifies the CPC. Put the durable investment into GEO, the content and authority work that earns organic citations across every engine, including the ones where visibility can’t be bought.

    The more ad inventory floods ChatGPT, the more scarce and valuable the organic slot becomes.

    Conclusion

    The ChatGPT-Perplexity split isn’t a temporary divergence. It’s two viable business models pulling AI search in opposite directions, and it permanently forked the meaning of “ranking.” From here on, an AI visibility number without a paid-or-organic label is incomplete data.

    The practical first step costs nothing: baseline your current organic presence across both platforms, per prompt, before spending a dollar on placements. Start with a free visibility check, identify where competitors are earning citations you’re not, and let that gap set your content priorities for the next quarter.

    FAQ

    Q: What does an ai rank checker track in ChatGPT versus Perplexity?
    A: In ChatGPT, it should track organic mentions and positions separately from sponsored units, since roughly half of US responses now carry ads. In Perplexity, where no ads exist, it tracks citation frequency, position relative to competitors, and the source URLs the engine pulls from.

    Q: Do ChatGPT ads affect the organic recommendations in answers?
    A: OpenAI states that sponsored units don’t influence the answer content itself. Ads appear as labeled units alongside responses. Organic mentions are still determined by the model’s retrieval and synthesis process, which is why the two need separate measurement.

    Q: How do I check my brand’s AI search ranking for free?
    A: Start with manual spot checks across your top 10 to 20 category prompts on both platforms, then use free GEO tools to establish a baseline before investing in continuous monitoring. Manual checks miss volatility, so treat them as a snapshot rather than a tracking system.

    Q: Is a Perplexity ranking more valuable now that the platform has no ads?
    A: For high-intent professional audiences, often yes. Perplexity’s subscribers pay $20 to $200 monthly for accuracy, and every brand appearance is organically earned. A consistent citation there signals topical authority that no budget can replicate.

    Read More

  • AI Query Tracking Service: How It Works and What It Costs

    AI Query Tracking Service: How It Works and What It Costs

    Spend an afternoon researching AI query tracking services and you’ll hit the same wall most marketing leads do: every vendor defines the category differently. One platform tracks 50 prompts on ChatGPT only. Another promises “full LLM coverage” without saying what that means. Pricing runs from $49 to over $4,000 a month, and the feature lists don’t map to each other, so you can’t compare quotes side by side.

    The confusion isn’t your fault. The category is barely three years old, and vendors are still inventing the vocabulary. But underneath the marketing noise, these services all do the same fundamental job, and once you understand that job, evaluating them takes an hour instead of a week.

    What an AI Query Tracking Service Actually Tracks

    An AI query tracking service monitors what large language models say about your brand when users ask buying-intent questions. It sends a defined set of prompts to platforms like ChatGPT, Perplexity, and Gemini on a schedule, then parses each response to record whether your brand appeared, where it ranked, how it was described, and which sources the AI cited.

    That sounds like rank tracking with extra steps. It isn’t.

    Traditional rank trackers monitor a static page of results: keyword in, ten blue links out, same for everyone. AI answers are non-deterministic. LLMs are stochastic by design, which means the identical prompt can produce different responses depending on model updates, temperature settings, and the platform’s retrieval process. A single manual check tells you almost nothing. Professional services solve this with multi-sample polling: querying the same prompt repeatedly over time to establish a statistically meaningful visibility baseline instead of a lucky (or unlucky) snapshot.

    This is the core distinction to hold onto during vendor evaluations. If a tool can’t explain its sampling methodology, it’s a screenshot generator, not a tracking service.

    How Does an AI Query Tracking Service Work? The 4-Step Pipeline

    Under the hood, most professional platforms run the same pipeline. Here’s what happens between “add your brand” and “view your dashboard,” using a fictional CRM startup as the running example.

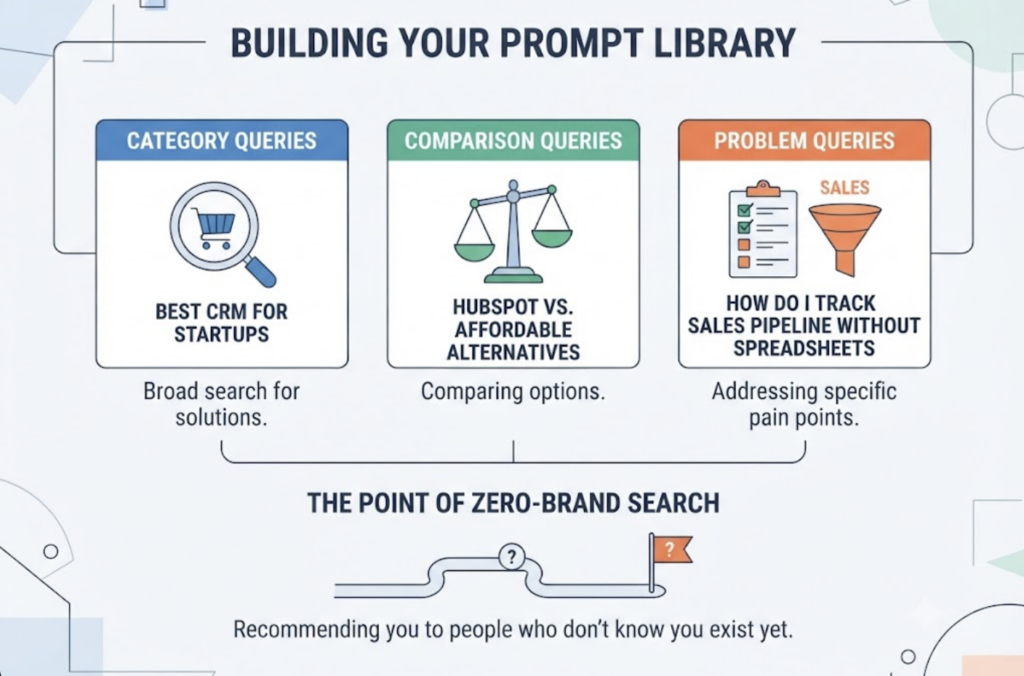
    Step 1: Prompt Set Design

    The service builds a library of prompts that mirror the buyer journey. For the CRM startup, that includes category queries (“best CRM for startups”), comparison queries (“HubSpot vs. affordable alternatives”), and problem queries (“how do I track sales pipeline without spreadsheets”). The brand name appears in almost none of them, which is the point. You’re testing whether AI recommends you to people who don’t know you exist yet.

    Step 2: Multi-Engine Polling

    The platform queries each prompt across major engines on a recurring schedule, typically daily or weekly. Coverage matters here because ecosystems behave differently: Perplexity leans heavily on citations, ChatGPT on training data plus browsing, Gemini on Google’s index. A brand can be visible on one engine and absent on another.

    Step 3: Semantic Parsing

    Each raw response gets parsed for four signals: mention frequency (did the brand appear), salience (did it land in the top portion of the answer, the prime real estate users actually read), sentiment (positive, neutral, or negative framing), and citation mapping (which URLs the AI referenced as evidence).

    Step 4: Trend Aggregation

    Individual samples get normalized into rolling averages, usually over 30 days, to filter model-induced noise from genuine shifts. If the CRM startup’s visibility drops 15 points in a week, aggregation tells you whether that’s random variance or a competitor’s new content pulling citations away.

    How to Measure Results: The 5 Metrics That Matter

    Once tracking runs, the question becomes what “good” looks like. These are the core AI visibility metrics that answer-engine optimization teams have standardized around, with rough health benchmarks.

    MetricWhat It MeasuresHealth Signal
    Visibility Rate% of tracked prompts where your brand is mentionedAbove 40% on category-specific queries
    Average PositionWhere your brand appears in the recommendation listTop 3 for high-intent queries
    Sentiment ScoreThe tone of your brand’s descriptionNeutral to positive; negative framing signals content gaps
    Citation Share% of responses citing a given source (your blog, G2, etc.)Higher share means the AI treats that source as authoritative
    Conversion SignalBranded search or traffic lift after AI mentionsShould correlate with visibility spikes

    One practical note: citation share is the metric teams most often ignore and most often regret ignoring. It tells you which third-party sites are feeding the AI’s opinion of your category. That’s actionable in a way raw mention counts aren’t, because you can pitch, publish, or partner your way into those sources.

    Why an Enterprise LLM Visibility Platform Differs from a Basic Tracker

    The market splits into two tiers, and the gap between them is wider than the pricing pages suggest.

    Basic trackers, typically $49 to $150 per month, monitor mention frequency across one or two platforms. For a solo founder checking whether ChatGPT knows their product exists, that’s often enough.

    An enterprise LLM visibility platform solves a different problem. Larger organizations need multi-brand and multi-market support, API access to pipe data into existing BI dashboards, team seats with role permissions, and automated competitor detection rather than manually maintained lists. The defining enterprise capability is citation gap analysis: reverse-engineering which sources make your competitors visible, so you know exactly which publications or review sites to target.

    Here’s how the tiers compare in practice:

    CapabilityBasic TrackerEnterprise LLM Visibility Platform
    Engine coverage1-2 platforms4+ platforms, including regional engines
    Prompt volume50-100/monthCustom, often 250+
    Competitor trackingManual or noneAutomated detection and benchmarking
    Citation analysisMention counts onlyFull citation supply chain mapping
    Team workflowsSingle userMulti-seat, multi-project, API access

    The honest guidance: don’t buy enterprise capabilities you won’t use. But if you manage more than one brand, operate in multiple markets, or report to stakeholders who ask “why did this change,” the basic tier will frustrate you within a quarter.

    Best Tools for AI Query Tracking in 2026

    The vendor field has grown crowded enough that roundups of AI search monitoring tools now cover a dozen or more options, ranging from lightweight mention counters to full optimization suites. Rather than list everything, it’s more useful to look at what a complete platform includes, using one as the reference case.

    Topify covers the full pipeline described above and adds the layers that basic trackers skip. It tracks prompt-level visibility across ChatGPT, Gemini, Perplexity, and DeepSeek, plus regional engines like Doubao and Qwen, which matters for brands with audiences outside North America. Monitoring spans seven metrics: visibility, sentiment, position, volume, mentions, intent, and conversion visibility rate.

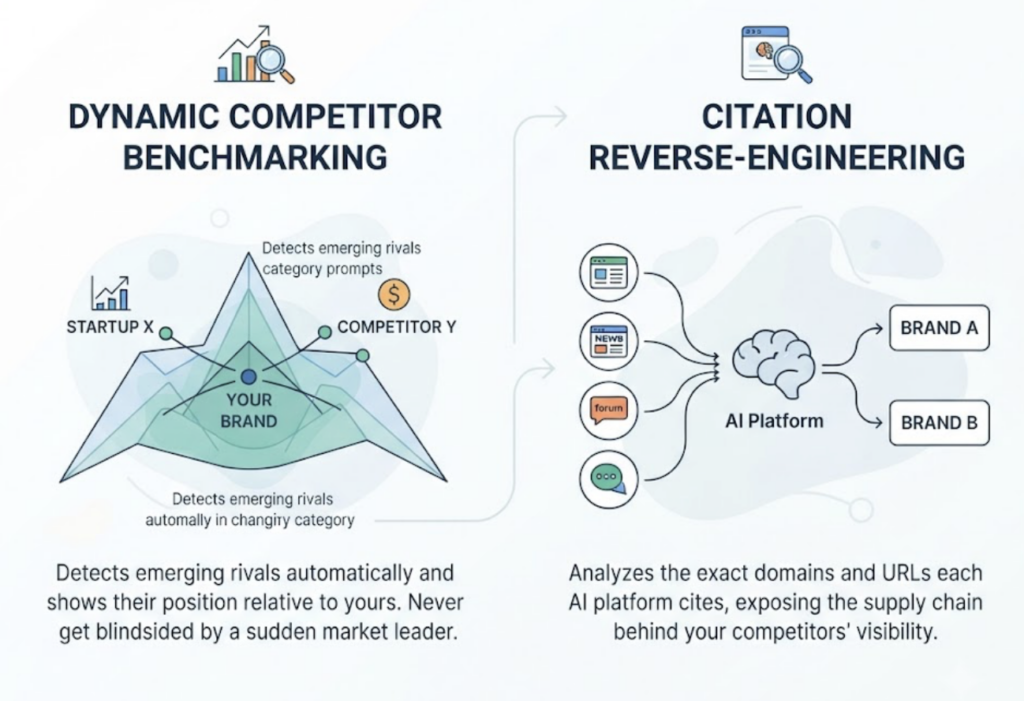
    Two capabilities stand out for teams past the “are we visible” stage. Dynamic competitor benchmarking detects emerging rivals automatically and shows their position relative to yours, so you’re not blindsided by a startup that suddenly dominates your category prompts. And citation reverse-engineering analyzes the exact domains and URLs each AI platform cites, exposing the supply chain behind your competitors’ visibility.

    For teams that want execution alongside measurement, the platform’s agent can propose and deploy GEO strategies from plain-English goals. That’s a meaningful difference from tools that stop at dashboards.

    Other tools in the category serve narrower needs well: some focus purely on Google AI Overviews, others on single-engine mention alerts at lower price points. The fit depends on how many engines your audience uses and whether you need the citation layer.

    A 7-Point Checklist Before You Buy

    Run every vendor demo against this list. It compresses the evaluation from weeks to a single call.

    1. Engine coverage. Does it track every platform your audience actually uses, including regional ones if you sell internationally?
    2. Prompt quota. How many prompts per month, and what does expansion cost? Under 100 is tight for most mid-size brands.
    3. Sampling frequency. Daily or weekly polling with aggregation, not one-off snapshots.
    4. Competitor tracking. Automated detection, or a manual list you’ll forget to update?
    5. Citation analysis. Can you see which sources drive AI answers, or just whether you were mentioned?
    6. Data access. Export, API, or dashboard-only? Dashboard-only becomes a bottleneck once leadership wants the numbers in their own reports.
    7. Pricing transparency. Published tiers you can budget against, or “book a call” pricing that hides the real cost?

    If a vendor fails on points 3 or 5, keep looking. Those two separate measurement from guesswork.

    Common Mistakes That Skew Your Tracking Data

    Even with the right tool, three errors reliably corrupt AI visibility programs.

    The single-sample bias. Someone on the team asks ChatGPT about the category once, screenshots the answer, and the screenshot becomes strategy. Model volatility makes any single response unreliable. Always work from aggregated data across multiple samples.

    Tracking only brand-name queries. If every prompt contains your brand name, your visibility rate will look great and mean nothing. The revenue-relevant queries are category ones (“best cloud accounting software”) where you should appear but the user never typed your name.

    The SEO-to-AEO fallacy. Teams assume Google logic transfers: build links, watch AI mentions rise. It doesn’t work that way. Strong domain authority and backlink profiles often coexist with zero AI mentions, because LLMs weigh semantic authority, clear Q&A structure, and third-party social proof over link density. Your rank tracker and your query tracker will regularly disagree, and both will be right about what they measure.

    That third mistake is the expensive one. It leads teams to spend another quarter on link building when the actual gap is structural content and citation coverage.

    AI Query Tracking Service Pricing: What You’ll Actually Pay

    Pricing has coalesced around prompt volume and engine coverage, with three consistent tiers across the market:

    • Entry level ($49-$199/mo): 50-100 prompts, often single-engine focus. Fine for validation, limiting for strategy.
    • Professional ($200-$500/mo): Multi-engine coverage, sentiment analysis, basic competitor tracking.
    • Enterprise ($500-$4,000+/mo): Custom prompt volume, API access, agency workspaces, dedicated support.

    As a concrete reference point, Topify’s pricing runs Basic at $99/month (100 prompts, ChatGPT, Perplexity, and AI Overviews tracking, 4 projects), Pro at $199/month (250 prompts, 10 seats), and Enterprise from $499/month with a dedicated account manager. Multi-engine tracking and competitor benchmarking are included below the $200 line, which undercuts the market’s typical professional tier.

    Budget guidance: start where your prompt volume actually sits. A focused brand tracking 100 high-intent prompts learns more than a sprawling program tracking 500 vague ones.

    How to Improve Your Numbers: A 90-Day Strategy

    Tracking without action is just expensive anxiety. Here’s the strategy sequence that turns data into visibility gains.

    Days 0-30: Baseline. Audit your top 100 high-intent prompts across major engines. Record your visibility rate, average position, and sentiment against your top three competitors. Resist optimizing anything yet; you need clean baseline data first.

    Days 31-60: Citation gap analysis. Map the citation supply chain. If competitors keep getting cited by specific review sites or industry publications that ignore you, those sites are your target list. Prioritize content partnerships, PR outreach, or review-platform presence there.

    Days 61-90: Structural optimization. Restructure key pages to be answer-friendly: clear FAQ sections, transparent pricing tables, expert author bylines. Then watch the next tracking cycle for movement. Visibility shifts typically lag content changes by weeks, so aggregated trend data (not daily checks) tells you whether it worked.

    Then the cycle repeats: expand the prompt set, refine, remeasure.

    Conclusion

    The vendor confusion that makes this category hard to shop is mostly surface-level. Every AI query tracking service does the same core job: sample AI answers systematically, parse them for brand signals, and aggregate the noise into trends. The real differences live in engine coverage, citation analysis depth, and whether pricing scales with your prompt volume.

    Run the 7-point checklist against any shortlist and the decision usually makes itself. If you want to see what prompt-level tracking looks like on your own brand before committing budget, you can start with Topify and have baseline data within the first tracking cycle.

    FAQ

    Q: What is an AI query tracking service?
    A: It’s a platform that repeatedly sends buying-intent prompts to AI engines like ChatGPT, Perplexity, and Gemini, then parses the responses to measure whether your brand is mentioned, where it ranks, how it’s described, and which sources the AI cites.

    Q: How much does an AI query tracking service cost?
    A: Entry-level plans run $49-$199/month for limited prompts, professional tiers $200-$500/month with multi-engine coverage, and enterprise plans $500-$4,000+/month. Topify starts at $99/month with multi-engine tracking included.

    Q: How is an enterprise LLM visibility platform different from a basic tracker?
    A: Enterprise platforms add multi-brand support, API access, automated competitor detection, team workflows, and citation gap analysis. Basic trackers typically count mentions on one or two engines.

    Q: How often should AI queries be sampled?
    A: Daily or weekly, then aggregated over a rolling window such as 30 days. AI responses are non-deterministic, so single checks produce unreliable data.

    Read More

  • AI Query Tracking Solution: What It Is and How It Works

    AI Query Tracking Solution: What It Is and How It Works

    Your keyword rankings look fine. Your domain authority hasn’t moved. But when a buyer asks ChatGPT for recommendations in your category, you have no idea whether your brand shows up, where it lands, or how the AI describes you. That blind spot is getting expensive: as of 2026, over 60% of information-seeking queries resolve inside the AI interface without a single click. The dashboards you’ve relied on for a decade weren’t built to measure any of this.

    What an AI Query Tracking Solution Actually Tracks

    An AI query tracking solution is a system that audits how your brand appears inside the generative outputs of AI platforms like ChatGPT, Perplexity, Gemini, and Google AI Overviews. Instead of monitoring where a URL ranks on a results page, it monitors whether your brand gets mentioned, recommended, or cited when someone asks an AI a buying question.

    The distinction matters because the two systems behave differently. Traditional rank tracking watches a deterministic list: your page either holds position #4 or it doesn’t. AI answers are probabilistic. Models use temperature settings and contextual awareness, so the same prompt can return different brand recommendations across consecutive sessions.

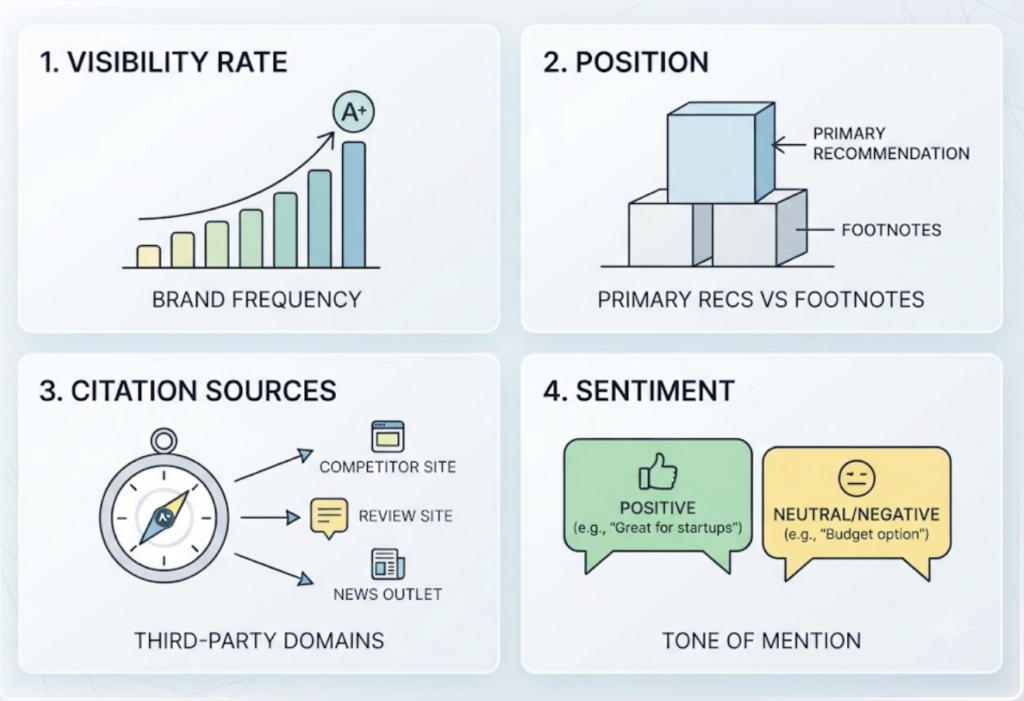
    In practice, a solid tracking setup measures four things: how often your brand appears for a given prompt (visibility rate), whether you’re the primary recommendation or a footnote (position), which third-party domains the AI cites as evidence (citation sources), and the tone of the mention (sentiment). “Great for startups” and “a budget option” are both mentions. They’re not the same outcome.

    Rank Trackers Told You Where You Stood. AI Answers Don’t Work That Way.

    Tools built for the SERP era have started bolting on AI features. A rank ranger AI Overviews tracker, for example, treats Google’s AI Overviews as another SERP feature to monitor, similar to a featured snippet or an image pack. That’s genuinely useful if your goal is defending Google click-through.

    It’s also where the coverage stops.

    The SERP-first approach runs into three walls. First, platform blindness: it ignores conversational engines like Perplexity and ChatGPT, where the discovery journey starts and ends outside of Google entirely. Second, it detects whether a link exists but not what the answer says. It can’t tell you if the AI calls your product “expensive” or “premium,” and that semantic difference shapes buyer perception more than the link itself. Third, it assumes stability. SERP positions hold steady for days; AI visibility shifts between sessions, which means a single snapshot is closer to a coin flip than a measurement.

    None of this makes SERP trackers obsolete. It makes them incomplete. They answer “where do I rank on Google” while the newer question is “what does AI say about me everywhere.”

    How an AI Query Tracking Solution Works, Step by Step

    Most professional systems follow the same four-step cycle, repeated on a schedule.

    Step 1: Build a prompt library. Tracking starts with queries that mirror real buyer journeys, like “best [product] for [industry]” or “alternatives to [competitor].” Generic prompts produce generic data. Decision-stage prompts produce data you can act on.

    Step 2: Sample across engines. The system runs those prompts on ChatGPT, Perplexity, Gemini, and AI Overviews on a daily or weekly cadence. Because outputs vary, one pass means nothing. Repeated sampling across platforms reveals where the engines agree about your category and where they diverge.

    Step 3: Parse the responses. NLP-based analysis converts raw answer text into structured data: mentions, position, sentiment, and the specific sources cited. This is the step that separates a tracking solution from someone manually pasting prompts into a chat window.

    Step 4: Attribute the gaps. When visibility is zero, the system should tell you why. Sometimes the cause is weak topical authority on your own site. More often, it’s absence from the third-party platforms the AI actually trusts, like review sites, forums, or trade publications.

    Platforms like Topify run this cycle across seven metrics (visibility, sentiment, position, volume, mentions, intent, and CVR), which means a drop in ChatGPT mentions can be traced back to a specific source that stopped citing your brand, inside the same dashboard.

    How to Measure Whether Your AI Query Tracking Is Working

    Raw answer data becomes useful when it’s compressed into a few KPIs your team can review weekly. Four have emerged as the industry standard:

    Mention rate is the existence metric. If a prompt triggers your category and your brand isn’t in the answer, you have an inclusion gap, and nothing else matters until it’s closed.

    Average position measures salience. Being recommended first versus fifth changes both perception and the probability a user acts on it.

    Citation share tracks how often your owned or earned assets appear as the evidence behind an AI’s claim. This is the metric SERP tools skip entirely.

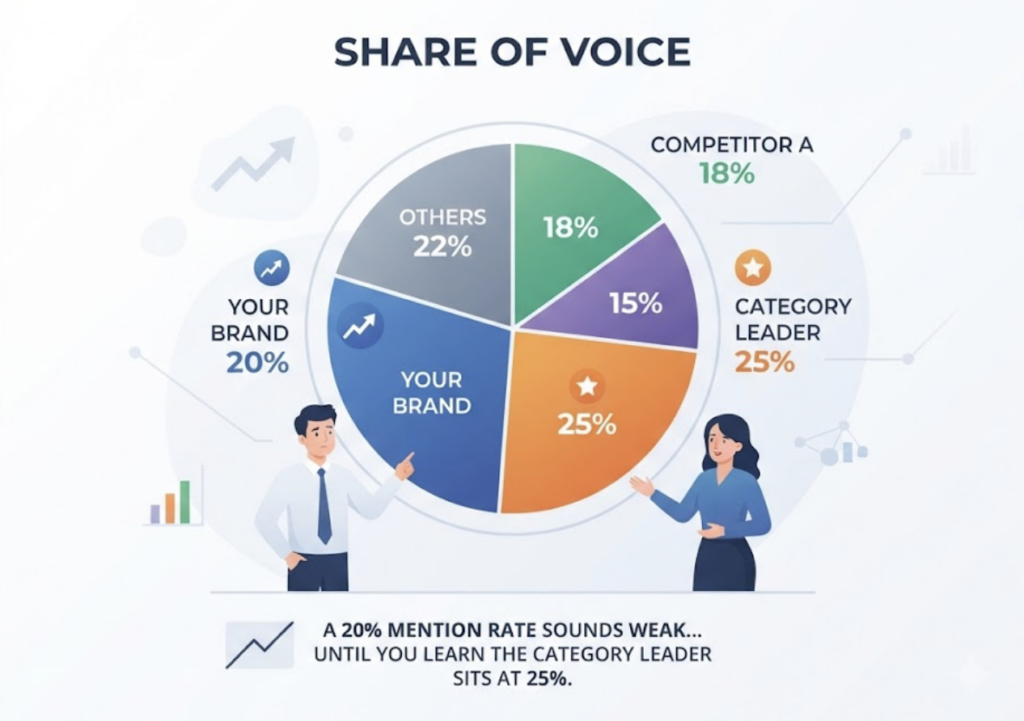
    Share of voice puts your presence in context against competitors within the same prompt cluster. A 20% mention rate sounds weak until you learn the category leader sits at 25%.

    Measure all four against a baseline, then review the trend over a rolling window rather than reacting to any single day’s output.

    Best Tools for an AI Query Tracking Solution in 2026

    The market splits into two camps: SERP-first tools that added AI features, and AI-first platforms that treat the LLM as the primary surface.

    ToolFocusPricingBest For
    TopifyCross-platform AI visibility, citation analysis, executionFrom $99/moBrands needing prompt-level insights and citation gap analysis
    Rank Ranger AI Overviews trackerGoogle SERP + AIO monitoringTieredTeams optimizing primarily for Google SERP features
    General SERP suites with AI add-onsRank tracking with partial AIO dataVariesTeams not yet ready to track conversational platforms

    Topify is the strongest fit for teams that want the full loop rather than another report. It tracks brand mentions at the prompt level across ChatGPT, Gemini, Perplexity, DeepSeek, and other major engines, then layers on the citation analysis piece: reverse-engineering the exact domains and URLs each platform cites when answering questions in your category.

    That citation layer is where it pulls ahead in day-to-day use. If a competitor keeps getting validated by G2 or a niche trade journal and your brand doesn’t appear there, Topify maps that specific missing link, effectively telling your team where to aim PR and content effort to teach the AI your brand is an authority. Tracking tells you the score. Source gaps tell you the next move.

    Pricing starts at $99/mo on the Basic plan, which covers ChatGPT, Perplexity, and AI Overviews tracking with 100 prompts and 9,000 AI answer analyses, enough to run the “Core 50” strategy below with room to spare. Plans scale by usage rather than enterprise bundles, so you can start small and expand as the data proves out.

    The rank ranger AI Overviews tracker approach still makes sense as a complement if Google remains your dominant channel. Just don’t mistake AIO coverage for AI coverage.

    Common Mistakes That Undermine an AI Query Tracking Solution

    Trusting a single sample. Running one manual query and treating the answer as truth is the most common failure. AI outputs vary by session. Use a rolling average, typically a 30-day window, before drawing conclusions.

    Ignoring the citation supply chain. Teams optimize their own site while the AI pulls its evidence from third-party review platforms. If you’re invisible on the sources the AI trusts, you’ll stay invisible in the answer, no matter how good your on-site content gets.

    Writing for keyword density. LLMs parse intent, not keyword counts. Content stuffed with “SEO-ese” reads as low-trust. Clear definitions, concise headings, and authoritative data tables perform better because they’re easier for models to extract and cite.

    Freezing the prompt set. Buyer language shifts, and so do the prompts that matter. A tracking setup that never adds new queries slowly measures yesterday’s market.

    A quick checklist before you trust your data: 50+ decision-stage prompts, at least three platforms sampled, weekly cadence minimum, citation sources logged, and a competitor set defined for share of voice.

    Conclusion

    The gap between “my rankings are fine” and “AI never mentions my brand” is the defining measurement problem of this search era, and it won’t show up in any dashboard built for blue links. The fix is straightforward to start. Define your Core 50 high-intent prompts. Sample them across ChatGPT, Perplexity, and AI Overviews for 30 days to establish a baseline. Then audit the sources AI cites for your competitors and close the gaps one by one. If you’d rather not build that pipeline manually, you can get started with Topify and have baseline data within the first week.

    FAQ

    Q: What is an AI query tracking solution?
    A: It’s a system that monitors how a brand appears in AI-generated answers across platforms like ChatGPT, Perplexity, and Google AI Overviews. It measures mention rate, position, sentiment, and citation sources at the individual prompt level, rather than tracking URL rankings on a results page.

    Q: How much does an AI query tracking solution cost?
    A: Entry pricing typically starts around $99/mo for prompt-level tracking across major platforms, with usage-based tiers as prompt volume grows. SERP-first tools with AI Overviews add-ons use tiered pricing that varies by plan, but they generally don’t cover conversational platforms.

    Q: Is a rank ranger AI Overviews tracker enough for AI search monitoring?
    A: It covers one surface: AI Overviews inside Google. It won’t show how ChatGPT or Perplexity describe your brand, and it detects link presence rather than sentiment or salience. Most teams pair SERP tracking with an AI-first platform for full coverage.

    Q: How often should you sample AI answers?
    A: Weekly at minimum, daily for competitive categories. Because AI outputs are probabilistic, judge trends on a rolling 30-day average rather than any single query result.

    Read More

  • AI Search Monitoring Tool: What It Is and How to Choose

    AI Search Monitoring Tool: What It Is and How to Choose

    Your domain rating is 72. Your core keywords sit on page one. By every metric your SEO stack reports, the brand looks healthy. Then a prospect asks ChatGPT for the top platforms in your category, and the answer lists three competitors, cites a review site you never optimized for, and skips you entirely. None of your current tools flagged it, because none of them were built to look.

    That blind spot is exactly what an AI search monitoring tool exists to close. Understanding what these platforms measure, how they work, and what they cost is the difference between buying a dashboard and buying an advantage.

    What an AI Search Monitoring Tool Actually Tracks

    An AI search monitoring tool systematically audits what generative AI platforms like ChatGPT, Perplexity, Gemini, and Google AI Overviews say about your brand. Instead of tracking where a URL ranks on a results page, it tracks whether and how a brand appears inside synthesized AI answers.

    The shift matters because the answers are replacing the links. AI search traffic has grown by more than 500% year over year, and over 60% of information-seeking queries now resolve without a single click to an external website. When the answer is the destination, presence inside that answer becomes the metric.

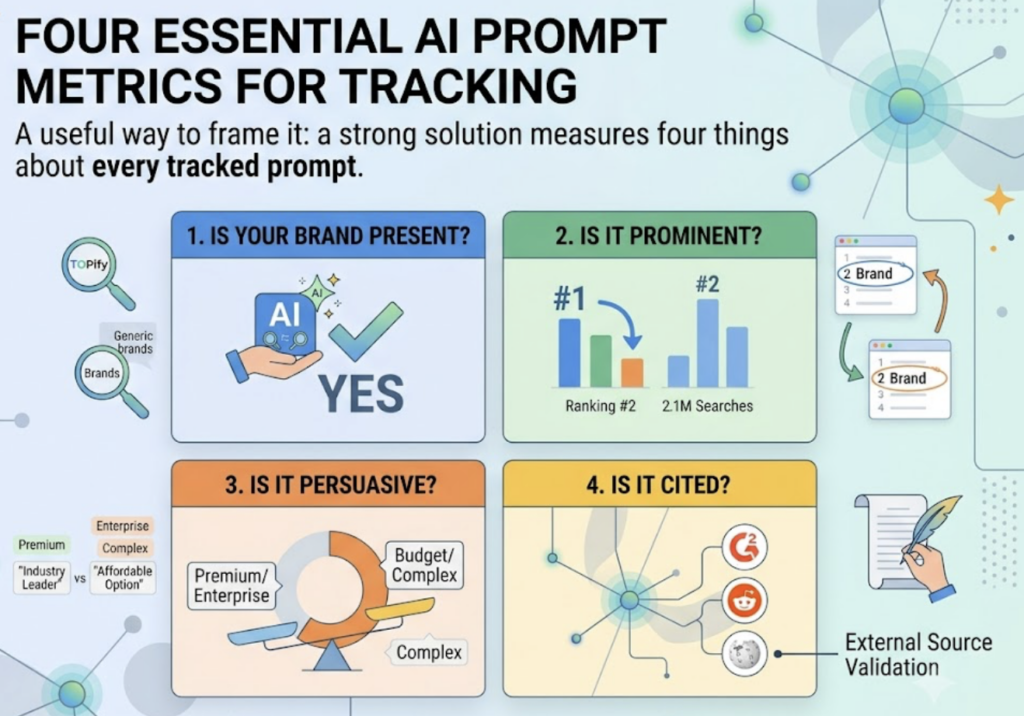
    In practice, a monitoring platform evaluates four things for every tracked prompt. Is the brand present in the response at all? Is it prominent, meaning early in the list rather than buried at the end? Is it persuasive, framed with language that matches your positioning? And is it cited, backed by sources like G2, Reddit, or industry publications that the model treats as authoritative?

    Traditional rank trackers can’t answer any of those questions. There’s no fixed position 1 through 10 in a ChatGPT response, no official reporting API, and no guarantee the same question returns the same answer twice.

    How Does an AI Search Monitoring Tool Work Behind the Dashboard

    The mechanics follow a consistent pipeline. The tool starts with a prompt library, a set of high-intent queries your buyers actually ask, such as “best [category] software” or “[Brand] vs. [Competitor].” It then runs those prompts against each AI platform on a schedule, parses every response for brand mentions, position, sentiment, and cited sources, and aggregates the results into trend lines.

    The scheduling part is not a convenience feature. It’s the whole point.

    LLMs are probabilistic, not deterministic. Research shows that even at zero temperature settings, responses still vary between runs. A single manual check captures one data point from what is actually a distribution, which is why serious tools sample repeatedly and report rolling 7-day or 30-day averages instead of snapshots.

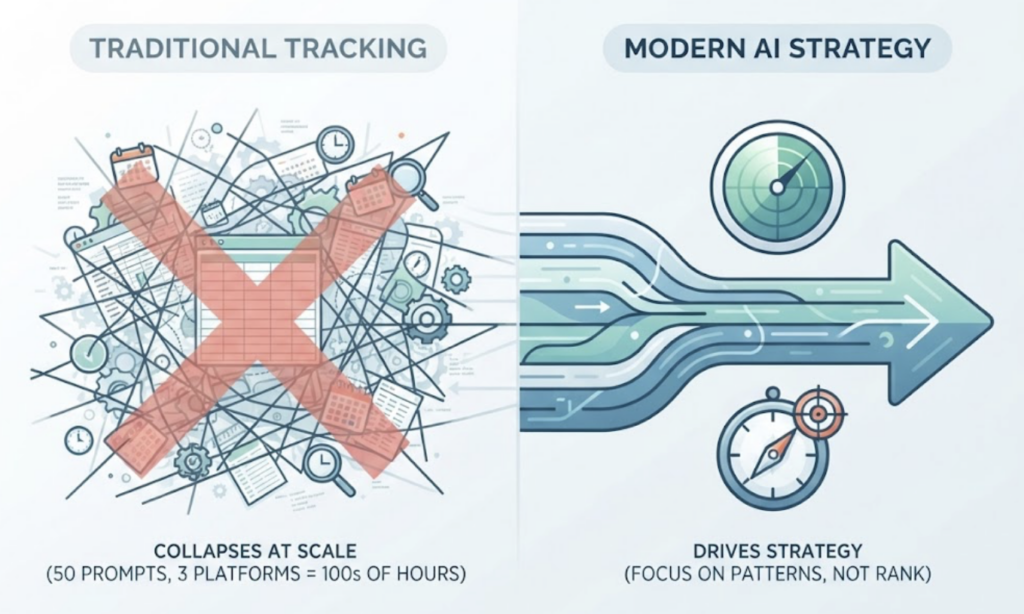
    That’s also why spreadsheet-based tracking collapses at scale. Monitoring even a modest cluster of 50 prompts across three AI platforms consumes dozens of manual hours every week, and the resulting snapshots go stale within days as models update their indexes. As the ROI·DNA team puts it, treating volatile AI performance like a static SEO rank means chasing noise instead of driving strategy.

    Why an AI Overview Monitoring Tool Belongs in the Same Stack

    Google AI Overviews and standalone AI assistants are two different battlegrounds, but they demand one unified measurement approach. An ai overview monitoring tool tracks when Google’s generative summaries appear for your target queries, whether your brand or domain gets cited inside them, and how that placement shifts over time.

    The stakes are asymmetric. An AI Overview sits above every organic result, so even a page-one ranking can lose most of its clicks to a summary that cites someone else. Meanwhile, ChatGPT and Perplexity operate on entirely different citation logic, often pulling from review platforms and community discussions rather than your own domain.

    Monitoring only one surface means seeing half the picture.

    This is why platform coverage should be the first filter in any tool evaluation. A tool that tracks ChatGPT but ignores AI Overviews misses the surface with the largest search volume. A tool that only watches Google misses the assistants where high-intent product research increasingly starts.

    How to Measure Results From an AI Search Monitoring Tool

    Raw mention counts are vanity metrics. A useful measurement framework tracks four dimensions that map directly to business questions.

    Visibility rate answers “how often do we show up.” It’s the percentage of relevant AI responses that include your brand, tracked per prompt cluster and per platform.

    Position answers “how early do we show up.” This matters more than most teams expect, because AI models concentrate attention on the first 30-40% of a response, making early mentions disproportionately valuable for consideration.

    Sentiment answers “how are we framed.” An AI describing your enterprise product as “budget-friendly” is a positioning problem no traffic report will surface.

    Source attribution answers “why does the AI say this.” Tracking which domains fuel AI answers reveals the upstream supply chain. If ChatGPT cites G2 to validate recommendations in your category, your G2 presence matters as much as your own website.

    The measurement sequence matters as much as the metrics: establish a baseline first, watch trends over rolling windows, then attribute changes to specific citation or content shifts. Platforms like Topify formalize this into seven tracked dimensions, adding volume, intent, and conversion visibility rate on top of the core four, so a drop in ChatGPT mentions can be traced to the specific source that stopped citing you.

    The Checklist for Picking the Best AI Search Monitoring Tool

    The market is crowded and the demos all look similar. This checklist separates tools that measure from tools that merely display.

    1. Cross-platform coverage. ChatGPT, Gemini, Perplexity, and Google AI Overviews at minimum. Single-platform tools produce single-platform blind spots.
    2. Prompt capacity that fits your funnel. You’ll want room for at least 25-50 decision-stage prompts per brand, with headroom to expand.
    3. Sampling frequency and rolling averages. Daily or near-daily sampling with 7/30-day trend views, not one-off snapshots.
    4. Competitor benchmarking. Share of voice at the prompt level, not just your own numbers in isolation.
    5. Citation and source analysis. The tool should show which domains AI engines cite, and where competitors are cited but you aren’t.
    6. A path from data to action. Insights that connect to content strategy, not rows in a database.
    7. Transparent pricing. Per-prompt and per-platform costs you can calculate before the sales call.

    There’s also a build-versus-buy question worth settling early. Some engineering-heavy teams consider scraping AI platforms themselves, but the economics rarely work out: fragile APIs, ongoing maintenance debt, and cloud costs typically exceed a commercial subscription, and the output is often a data silo nobody acts on.

    Against this checklist, Topify tends to stand out as the option built for the full loop rather than just the monitoring step. It tracks brand presence across ChatGPT, Gemini, Perplexity, DeepSeek, and other major engines, benchmarks share of voice against auto-detected competitors, and reverse-engineers the exact URLs each platform cites, mapping the gap between sources that mention your rivals and sources that ignore you.

    The differentiating layer is execution. Instead of exporting findings into a separate workflow, you can define a goal in plain English, review the proposed strategy, and deploy it with one click. For teams whose real constraint is time rather than data, that closed loop is the difference between a report and a result. You can get started with a 30-day trial to establish a baseline before committing.

    Common Mistakes That Waste Your Monitoring Budget

    Even with the right tool, teams sabotage their own data in predictable ways.

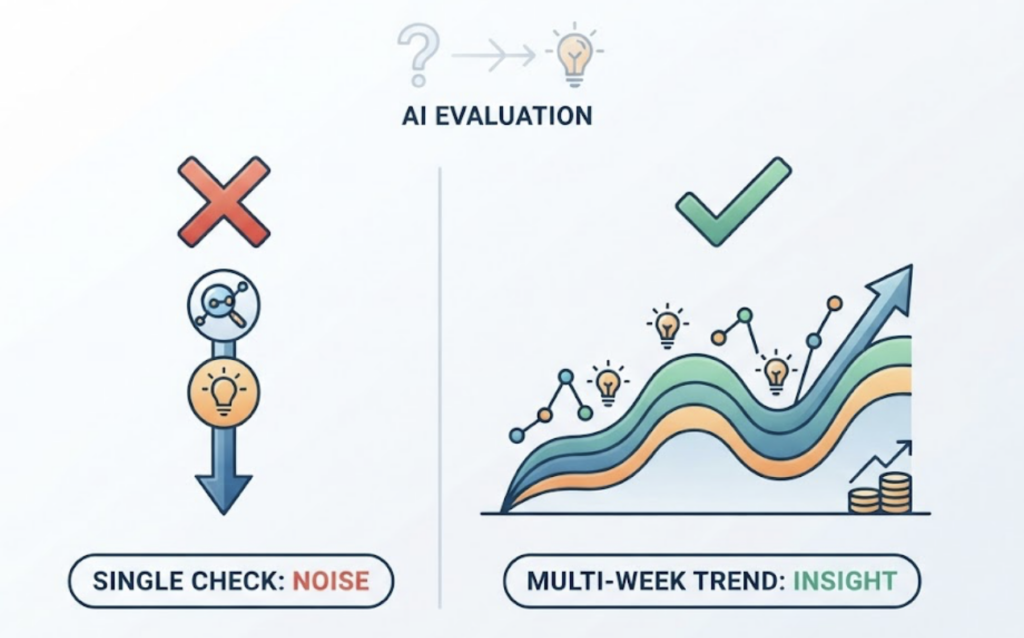
    Judging from a single check. One query, one answer, one conclusion. AI responses vary run to run, so any decision made from a single sample is a decision made from noise. Fix: only act on rolling multi-week trends.

    Building a prompt library that’s too narrow. Ten branded prompts tell you nothing about the category conversations where buyers actually discover alternatives. Fix: weight the library toward unbranded, decision-stage queries.

    Counting mentions while ignoring framing. Showing up as “a cheaper alternative to [Competitor]” is not the same as showing up as the recommended pick. Fix: review sentiment and position alongside visibility rate.

    Monitoring without acting. Dashboards that never change a content calendar are an expense, not an investment. Fix: tie every monthly review to at least one citation-building or content action.

    Forgetting AI Overviews. Teams fixated on ChatGPT routinely miss the generative surface sitting on top of their existing Google traffic. Fix: treat AI Overview tracking as non-negotiable scope.

    AI Search Monitoring Tool Pricing: What You’ll Actually Pay

    Most commercial platforms cluster into three bands. Entry plans run roughly $99-199 per month, mid-tier plans with larger prompt capacity and more seats land around $200-500, and enterprise plans with dedicated support start at $500 and climb from there.

    Topify’s pricing follows a usage-based structure designed to start small and expand with proven value:

    PlanPriceWhat’s included
    Basic$99/mo, save 17% yearly30-day trial, ChatGPT, Perplexity and AI Overviews tracking, 100 prompts, 9,000 AI answer analyses, 4 projects, 4 seats
    Pro$199/mo, save 17% yearly250 prompts, 22,500 AI answer analyses, 8 projects, 10 seats
    EnterpriseFrom $499/mo, save 16% yearlyDedicated account manager, custom scope

    The smarter comparison isn’t monthly price. It’s cost per tracked prompt per platform. A $99 plan covering 100 prompts across three engines works out to roughly $0.33 per prompt-platform per month, a fraction of what the equivalent manual tracking hours would cost in salary. Bottom line: price the coverage, not the sticker.

    Conclusion

    The gap this article opened with, a healthy SEO dashboard next to an invisible AI presence, doesn’t close on its own. AI visibility is now a distinct metric system with its own volatility, its own citation supply chain, and its own tooling.

    The practical path is short: define 25-50 decision-stage prompts, measure your baseline presence across ChatGPT, Perplexity, and AI Overviews, audit which sources feed the answers, and move to tool-based tracking before the manual hours pile up. Monitoring is the starting point. What you change because of it is the strategy.

    FAQ

    Q: What is an AI search monitoring tool? 

    A: It’s a platform that automatically queries AI engines like ChatGPT, Perplexity, Gemini, and Google AI Overviews with buyer-relevant prompts, then measures whether your brand appears, where it’s positioned, how it’s framed, and which sources the AI cites. It replaces manual spot-checks with longitudinal trend data.

    Q: How do I improve the results my AI search monitoring tool reports? 

    A: Work upstream. Use source attribution data to find the domains AI engines cite in your category, then build presence there through reviews, contributed content, and structured, cite-able pages on your own site. Improvements typically show in visibility trends over 30-90 days, not overnight.

    Q: What are examples of what an AI search monitoring tool catches? 

    A: Typical finds include a competitor entering the top three recommendations for your core prompt, Perplexity describing your premium product as “budget,” a review site becoming the dominant citation source in your category, or your brand disappearing from AI Overviews after a model update.

    Q: What’s a good starting strategy for AI search monitoring? 

    A: Start with a focused library of 25-50 decision-stage prompts, sample across at least three platforms, and let a 30-day baseline accumulate before making changes. Then run a monthly loop: review trends, identify one citation gap, act on it, and measure the shift in the next cycle.

    Read More

  • AI Search Monitoring Platform: What It Tracks and Why

    AI Search Monitoring Platform: What It Tracks and Why

    Your team got the directive: start monitoring AI search. So you pulled up a few options, and that’s where it got murky. One tool claims to track ChatGPT mentions. Another counts citations. A third shows a “visibility score” with no explanation of how it’s calculated. Each one measures something different, and none of them agrees on what an AI search monitoring platform should even do. The result is a report you can’t defend in a meeting, because you’re not sure the number reflects whether AI is actually recommending your brand.

    What an AI Search Monitoring Platform Actually Is

    An AI search monitoring platform is a system that tracks how your brand shows up inside the answers large language models generate. That’s the core distinction. It doesn’t watch URLs or SERP positions the way a traditional SEO rank tracker does. It reads what ChatGPT, Perplexity, Gemini, and Google AI Overviews actually say when someone asks a question in your category.

    The shift is from keyword-centric tracking to prompt-centric observation. Traditional rank tracking measures fixed positions in a static results page. AI search is probabilistic. A brand can rank #1 on Google and still be invisible in the synthesized answer an LLM hands a buyer.

    So the question an AI search monitoring tool answers isn’t “where do I rank.” It’s whether the model mentions you, cites you with a link, and recommends you over a competitor. Some teams call this Share of Answer rather than share of rankings.

    That reframing is the whole point.

    How an AI Search Monitoring System Works

    Most platforms run a three-stage pipeline built to handle the non-deterministic behavior of AI answers.

    First, prompt sampling. Instead of monitoring thousands of static keywords, the system works from a curated prompt portfolio, typically 50 to 100 high-intent questions that map to the buyer’s journey. These are the questions real users actually type, not head terms.

    Second, cross-platform polling. ChatGPT, Gemini, Claude, and Perplexity each run different retrieval pipelines and weight sources differently. A monitoring system polls them concurrently, because a brand that’s well-cited in Perplexity can be missing entirely from AI Overviews.

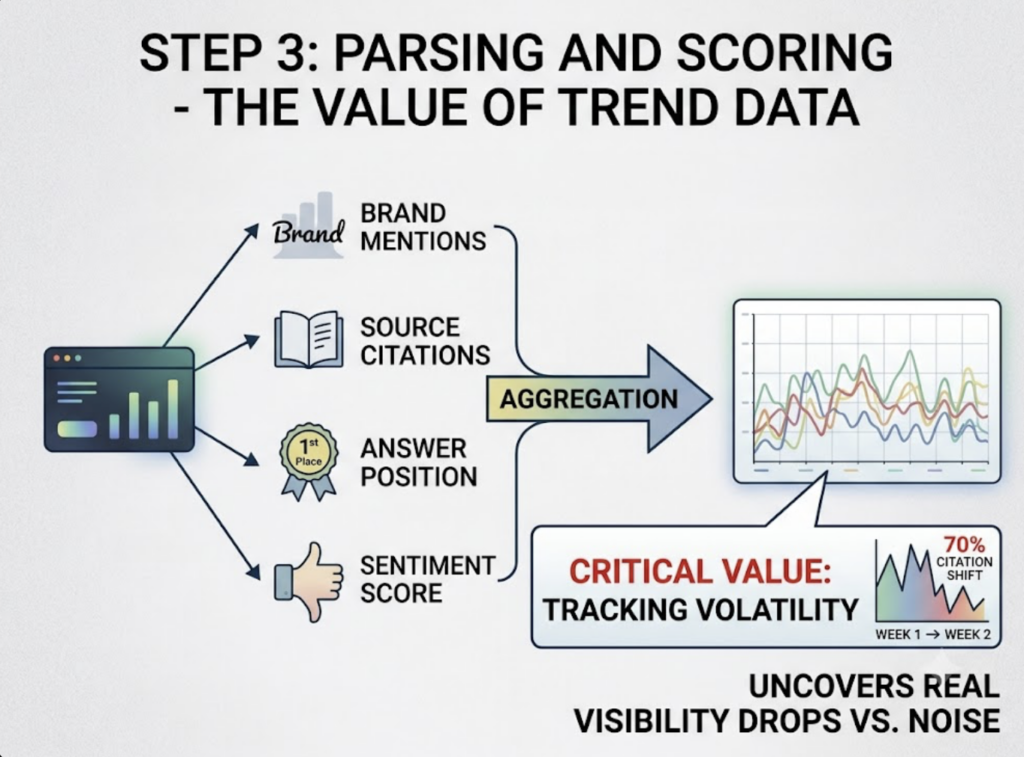
    Third, parsing and scoring. Raw responses get parsed for brand mentions, source citations, answer position, and sentiment, then aggregated into time-series trends. That last part matters more than it sounds. Citation patterns in AI search can shift by up to 70% in a single week as engines update their RAG logic. Without trend data, you can’t separate temporary noise from a real visibility drop.

    A snapshot tells you where you stood on Tuesday. A monitoring system tells you whether you’re drifting.

    What an AI Search Monitoring Dashboard Should Measure

    Here’s where a lot of dashboards go soft. They show you volume and raw mention counts because those numbers are easy to display, not because they tell you anything useful.

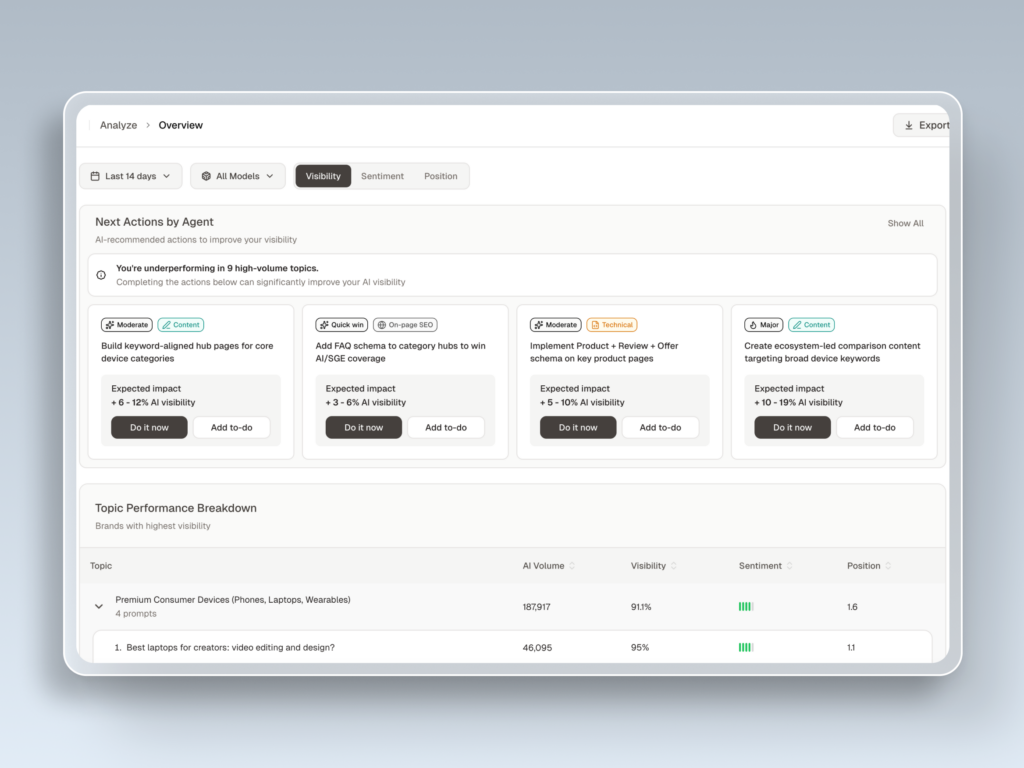
    A worthwhile AI search monitoring dashboard shifts focus from traffic volume to entity authority. The metrics that matter map to specific business questions:

    MetricThe question it answers
    Visibility RateIs the brand present in the conversation at all?
    Citation ShareDoes the AI trust the brand enough to link to it?
    PositioningDoes the brand land in the main summary or a buried footnote?
    SentimentHow does the model frame the brand’s authority?
    Share of VoiceHow does the brand compare to competitors in AI answers?

    One metric sits above the rest for proving ROI: AI referral traffic, tracked through utm_source tagging. Visibility is the leading indicator. Referral traffic is the bottom line. Good AI search monitoring analytics connect the two, so you can show that a rise in citation share actually moved real visits.

    Common Mistakes in AI Search Monitoring

    Four mistakes show up over and over, and most of them come from importing old SEO habits into a new channel.

    Single-platform bias. Monitoring only ChatGPT ignores the sourcing logic of Perplexity and Google AI Overviews, which pull from different places. You end up optimizing for one model’s quirks and calling it coverage.

    Vanity metric obsession. Counting raw mentions without checking whether they’re linked gives a false sense of security. An unlinked mention rarely sends traffic, and it rarely signals the kind of trust that gets you recommended again.

    Ignoring citation drift. As RAG pipelines update, brands cycle in and out of the authoritative source list. Teams that treat AI visibility as a one-time snapshot miss the moment a model quietly drops them.

    Static keyword reliance. Forcing traditional keyword lists onto AI search, instead of optimizing for natural-language questions and entity authority, produces content the models don’t retrieve.

    That’s the gap most dashboards quietly skip.

    How to Choose the Best AI Search Monitoring Solution

    Pick a tool by what it measures, not by how its dashboard looks. Measurement methodology is where these solutions actually diverge.

    Run any AI search monitoring solution through five questions before you commit:

    Evaluation dimensionWhy it matters
    Engine coverageDoes it include ChatGPT, Perplexity, Gemini, and AI Overviews, not just one?
    Citation layerCan it separate a passing mention from a trusted, linked source?
    Drift trackingWill it flag when an AI drops your brand from its answers?
    Competitor benchmarkingCan it show your relative authority inside the category?
    Actionable insightsDoes the data map to specific fixes like schema, FAQ structure, or entity authority?

    Use it as a literal checklist. A platform that nails coverage but can’t tell you why a competitor got cited will leave you monitoring a problem you can’t act on.

    Where Topify Fits as an AI Search Monitoring Platform

    Map those five criteria onto an actual product and you get a sense of what an integrated system looks like.

    Topify is built as a GEO platform rather than a standalone monitor, which mostly shows up in how it closes the gap between a signal and a fix.

    Its Comprehensive GEO Analytics tracks seven dimensions of AI visibility in one view: visibility, sentiment, position, volume, mentions, intent, and CVR. That covers the metrics worth measuring and adds a conversion-oriented layer most monitoring tools skip.

    Competitor benchmarking runs in real time, so you can see exactly where a rival is winning citations you’re not. Source analysis goes a step further and reverse-engineers why an AI chose that competitor, building an authority map you can point content at.

    Then there’s the part that separates monitoring from optimization. Topify’s one-click execution turns a visibility gap into a content brief, so the same platform that spots the problem helps you act on it. For teams tracking visibility across four engines at once, having detection and action in one place tends to cut the lag between noticing a drop and fixing it.

    Detection without action is just a prettier report.

    Turning Monitoring into a GEO Strategy

    Monitoring is the starting line, not the finish. The teams that improve their AI search results treat every visibility gap as a content opportunity rather than a status update.

    The strategy is a loop. Define a prompt portfolio around real buyer intent. Monitor across all major engines at once. When a gap shows up, trace it to its cause through source analysis, ship the content or schema fix, then re-test to confirm the model picked it up.

    The brands that pull ahead are the ones optimizing for consistency over snapshots. Citation authority compounds. A source an AI trusts this month tends to get pulled again next month, which is how a brand moves from occasional mention to default recommendation.

    Conclusion

    Choosing between AI search monitoring tools feels hard because they don’t measure the same things. The fix is to decide what you need to track before you shop. Stop chasing rankings and start tracking citations.

    Define a prompt portfolio based on buyer intent. Monitor every major engine at once, not just the one you use personally. Treat each visibility gap as a chance to strengthen your entity authority, and watch trends instead of snapshots. Do that, and the report you bring to the next meeting stops being a guess. It becomes evidence of whether AI is recommending your brand, plus a clear plan for the spots where it isn’t.

    FAQ

    Q: How much does an AI search monitoring platform cost? 

    A: Pricing varies widely by coverage and depth. Entry-level monitoring tools start low, while integrated GEO platforms that include execution sit higher. Topify’s self-serve plans begin at $99/month for the Basic tier, which covers ChatGPT, Perplexity, and AI Overviews tracking with 100 prompts, then scale through Pro and Enterprise. The right number depends less on sticker price and more on how many engines and prompts you need to track. Current tiers are on the Topify pricing page.

    Q: What are some examples of what these platforms track? 

    A: Common examples include visibility rate (whether you appear), citation share (whether the AI links to you), answer position, sentiment, and share of voice against competitors. More advanced systems also track AI referral traffic through utm_source tagging to tie visibility back to real visits.

    Q: How is an AI search monitoring tool different from an SEO rank tracker? 

    A: A rank tracker measures fixed positions in a static results page. An AI search monitoring tool reads the natural-language answers LLMs generate, which are probabilistic and change week to week. One tells you where a URL ranks. The other tells you whether AI mentions and recommends your brand at all.

    Q: How do I improve my AI search monitoring platform results once I’m tracking them? 

    A: Start with the gaps the data surfaces. Find the prompts where competitors get cited and you don’t, then optimize for natural-language questions, entity authority, and structured formats like FAQ and schema. Re-test after each change to confirm the engines picked it up, since improvement here is iterative, not one-and-done.

    Read More

  • What an AI Prompt Tracking Dashboard Actually Shows You

    What an AI Prompt Tracking Dashboard Actually Shows You

    Your team checks Google rankings every week, and the report comes back green. Then a buyer opens ChatGPT, types a question your product was built to answer, and reads back five recommendations. None of them is you. That happened on Tuesday, and probably again on Thursday, and you have no record of either, because nothing in your stack watches what AI says when someone asks. Rankings tell you where you sit in a list of links. They say nothing about whether an AI engine names you when it writes the answer.

    What an AI Prompt Tracking Dashboard Tracks That Rankings Can’t

    An AI prompt tracking dashboard monitors how large language models answer a defined set of buyer questions, and records whether your brand shows up in those answers. Instead of a keyword and a position, you’re watching a question like “what’s the best tool for AI visibility” and checking three things: did the model mention you, did it recommend you, and where did you land relative to competitors.

    That’s a different measurement problem than search ranking. Keyword tracking monitors a fixed phrase against a fixed list. Prompt tracking monitors how a model synthesizes an answer, which changes by platform, by phrasing, and even by run.

    The gap between the two channels is wider than most teams expect. Research from SISTRIX found that roughly 80% of LLM citations don’t rank in Google’s top 100 results. Your rankings can be healthy while your AI presence is empty.

    That’s the part most dashboards were never built to see.

    How an AI Prompt Tracking Dashboard Actually Works

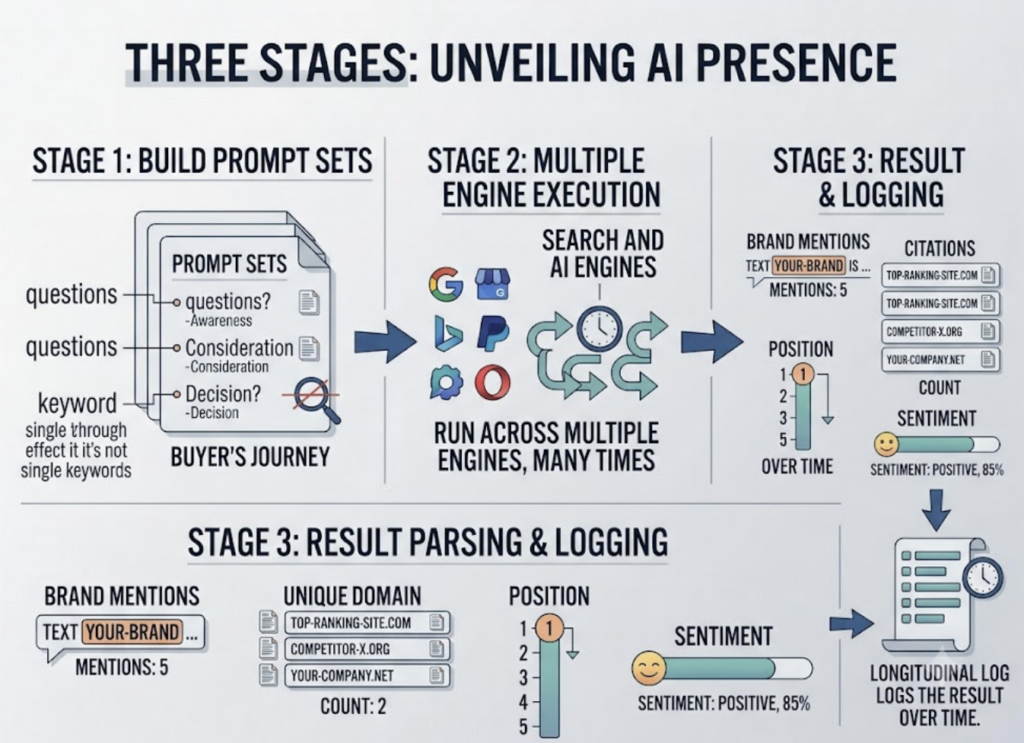
    Under the hood, the process runs in three stages. First, you build prompt sets, which are groups of questions that map to the buyer’s journey rather than single keywords. Second, the system runs those prompts across multiple engines, often many times. Third, it parses each answer for brand mentions, citations, position, and sentiment, then logs the result over time.

    The reason for running the same prompt repeatedly is the query fan-out effect. LLMs interpret a question like “what’s the best running shoe for snow” slightly differently on each pass, so a single check tells you almost nothing. You need multiple runs to know whether your visibility is reliable or just a lucky sample.

    Platform behavior adds another layer. Google AI Overviews tend to favor structured formats like FAQ and HowTo content, while Perplexity tends to reward original research and deep data. A prompt that surfaces your brand in one engine can ignore it entirely in another.

    And the data goes stale fast. SISTRIX data shows Google AI Mode replaces about 56% of cited domains every week, while ChatGPT churns roughly 74%. A dashboard that updates monthly is reporting on a reality that no longer exists.

    How to Measure It: Six Metrics That Beat a Mention Count

    Counting mentions is the vanity metric of GEO. It tells you that you exist somewhere, not whether you’re winning. Most teams that take AI visibility seriously track six core metrics instead.

    Share of answers tells you whether you have a visibility problem at all. Third-party mention measures how large your footprint is across answers you don’t control. Information correctness checks whether the AI is describing your brand accurately, since a frequent mention that calls a premium product “budget-friendly” is a problem, not a win.

    The other three are about quality and reliability. Recommendations track whether the model actively prefers you, not just names you. Multi-surface tracking confirms your visibility holds across ChatGPT, Perplexity, Gemini, and AI Overviews. Multi-run consistency confirms it holds across repeated checks rather than appearing once and vanishing.

    One distinction matters across all six: a brand mention is when the AI names your company, while a citation is when it links back to you. Both signal visibility, but only the citation drives direct traffic.

    Where AI Prompt Tracking Dashboards Fit Among GEO Trackers

    A prompt dashboard is one view inside the broader category of generative engine optimization (GEO) trackers. The market has split into two types, and the right pick depends on how your team already works.

    Broad SEO suites fold AI data into an existing search workflow. Dedicated GEO platforms go deeper on citation analysis and prompt-level optimization, and some add execution on top of measurement. Here’s how the categories compare.

    Tool typePlatform coverageMetric depthExecution built in
    Broad SEO suite (e.g. Semrush AI Toolkit, SE Ranking)AI data added to existing search reportsMention and basic citation trackingNo, reporting only
    Single-platform monitorUsually one engineMentions, limited position dataNo
    Dedicated GEO platform (e.g. Topify, AthenaHQ, Frase)Multiple engines in one viewFull metric set plus source and competitor analysisVaries by platform

    If you only need to confirm AI data alongside your keyword reports, a suite is enough. If you need to understand why an AI cites a competitor and then act on it, a dedicated platform like Topify covers more of the workflow in one place.

    Common Mistakes That Turn Prompt Tracking Into Noise

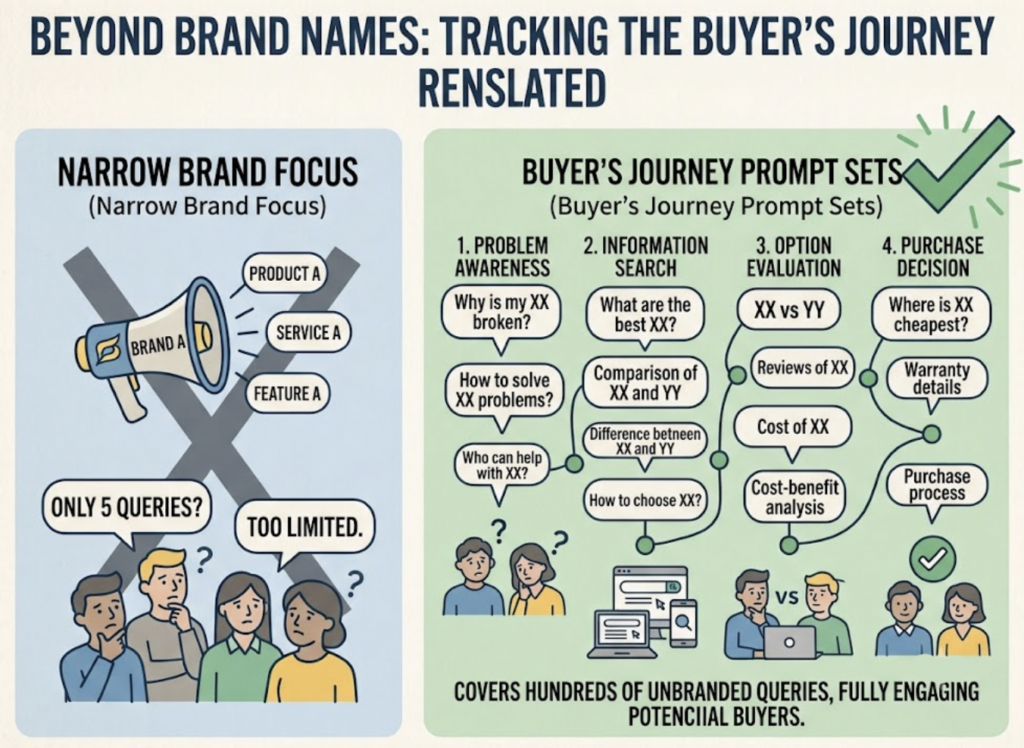
    The most common error is a prompt set that’s too narrow. Tracking five branded queries feels productive, but real buyers ask hundreds of unbranded questions, and that’s where you’re either present or invisible. Build prompt sets around the buyer’s journey, not around your product name.

    The second mistake is monitoring a single platform. Coverage on ChatGPT says nothing about Perplexity, and the two cite very different sources. Track every engine your audience actually uses.

    The third is measuring mentions while ignoring position and source. Being named last in a list of seven is not the same as being the top recommendation, and a dashboard that flattens the two hides the gap. Pull position and citation data, not just a count.

    The fourth is letting data go stale. Given weekly churn rates above 50%, a quarterly snapshot is closer to fiction than measurement.

    What a Strong AI Prompt Tracking Setup Looks Like in Practice

    A working setup starts before the dashboard. You first surface the high-value prompts that actually drive decisions in your category, then watch how the engines answer them, then trace why a given source keeps getting cited. Topify runs this as a connected loop: High-Value Prompt Discovery surfaces the questions worth tracking, Comprehensive GEO Analytics scores your presence across seven metrics including visibility, sentiment, position, and CVR, Dynamic Competitor Benchmarking shows who the engines recommend instead of you, and Reverse-Engineer AI Citations exposes the exact domains feeding those answers. The point isn’t more charts. It’s seeing a drop in ChatGPT mentions and tracing it to a specific source that stopped citing you, inside one view.

    This matters because the channel converts. Buyers who arrive through an LLM answer are reportedly 4.4x more likely to convert than traditional search visitors, and with roughly 68% of Google searches now ending without a click, the AI answer is increasingly the only impression a buyer gets.

    On price, the entry point is lower than most teams assume. Topify’s Basic plan starts at $99/month with a 30-day trial and covers ChatGPT, Perplexity, and AI Overviews tracking across 100 prompts. If you want to test the loop before committing, you can get started and run your own prompt set first.

    A Checklist Before You Commit to a Dashboard

    Run any tool through these seven questions before you buy:

    1. Does it cover every AI engine your audience uses, not just one?
    2. Does it report position and citation, or only mention counts?
    3. Can it discover high-value prompts, or do you supply every query yourself?
    4. Does it track competitors in the same answers, side by side?
    5. Can it show which source domains feed the AI’s citations?
    6. Does it run prompts multiple times to confirm consistency?
    7. Is the pricing transparent, with a trial to validate before you scale?

    A tool that clears most of these is measuring the channel. One that doesn’t is mostly counting mentions.

    Conclusion

    Rankings answer a question buyers stopped asking. The one that matters now is whether an AI engine names you when someone describes their problem, and that’s exactly what an AI prompt tracking dashboard is built to show. Start by listing the 20 to 30 unbranded questions your best customers actually ask, run them across every engine that matters, and watch position and citation, not just mentions. The brands that treat AI visibility as its own measured channel will keep showing up in the answer. The ones still reading green ranking reports won’t know they’ve gone missing.

    FAQ

    Q: What is an AI prompt tracking dashboard? 

    A: It’s a tool that monitors how AI engines like ChatGPT, Perplexity, and Google AI Overviews answer a defined set of buyer questions, and records whether your brand is mentioned, recommended, cited, and where it ranks against competitors. Unlike keyword tracking, it measures presence inside generated answers rather than position in a link list.

    Q: How do you improve your AI prompt tracking dashboard results? 

    A: Widen your prompt set to cover unbranded buyer questions, publish content in formats the engines reward (clear data, expert-aligned structure, FAQ and HowTo schema), and use citation analysis to find the source domains that AI engines trust, then earn placement in them. Then re-run and watch position move.

    Q: How much does an AI prompt tracking dashboard cost? 

    A: Pricing ranges widely. Entry-level dedicated platforms start around $99/month, with mid tiers near $199/month for more prompts and seats, and enterprise plans running higher for dedicated support. Most credible tools offer a trial so you can validate coverage before committing.

    Q: What does a good AI prompt tracking dashboard example look like? 

    A: A strong example surfaces high-value prompts automatically, scores visibility across multiple engines and several metrics, places competitor performance next to yours, and traces which source domains drive the citations, all in a single view rather than scattered reports.

    Read More

  • AI Prompt Tracking Solution: What to Track and Why

    AI Prompt Tracking Solution: What to Track and Why

    Your team opens ChatGPT, types in your category’s top question, and screenshots whether your brand shows up. Then Perplexity. Then Gemini. Then again next week, because the answers keep moving. Tracking even 50 prompts across three AI platforms this way burns dozens of hours a week, and the spreadsheet you’re building is stale before you finish it.

    The harder problem isn’t checking once. It’s knowing whether what you saw was a real trend or just model noise.

    What an AI Prompt Tracking Solution Actually Monitors

    Start with the word “prompt,” because it confuses people. An AI prompt tracking solution has nothing to do with prompt engineering or writing instructions for a model. It tracks the outputs of real user queries, the high-intent questions buyers actually ask AI tools, like “best [category] software” or “[your brand] vs [competitor].”

    The job is to audit how the AI answers those questions, at scale, over time.

    A useful way to frame it: a strong solution measures four things about every tracked prompt. Is your brand present in the answer at all? Is it prominent, meaning where does it land in the list? Is it persuasive, meaning how does the model frame you, premium or budget, enterprise or complex? And is it cited, meaning which external sources, like G2, Reddit, or Wikipedia, does the AI lean on to validate the recommendation?

    That fourth dimension is the one most teams skip. It’s also where the leverage is.

    Why Manual AI Prompt Tracking Falls Apart Fast

    Manual, spreadsheet-based tracking hits three walls that no amount of effort fixes.

    The first is volatility. LLMs are probabilistic, not deterministic. Even with temperature pinned low, responses still drift between runs, so a single manual spot-check captures one data point when actual visibility is a distribution. You need a rolling average, a 7- or 30-day window, to separate a meaningful shift from random variance.

    The second is scale. Checking a modest cluster of 50 prompts across three engines, every week, eats dozens of hours of senior marketing time. That’s expensive labor spent copying answers into cells.

    The third is the snapshot trap. AI platforms update their indexes and reasoning logic constantly, so today’s screenshot is often obsolete within days.

    Treat AI performance like a static SEO rank and you’ll spend your time chasing noise instead of driving growth.

    That’s the gap a real system is built to close.

    What a Real AI Prompt Tracking Tool Has to Measure

    Most dashboards reduce AI visibility to a single number. A serious AI prompt tracking tool refuses to do that, because one number hides everything you’d actually act on.

    Here’s what the analytics layer has to break out.

    Visibility, Position, and Sentiment in One View

    Visibility rate is the share of relevant AI answers that mention your brand at all. It’s the baseline, not the finish line.

    Position, or salience, is the order of mention. This one matters more than it looks. AI models tend to weight the first 30 to 40% of an answer most heavily, so being named last in a list of seven is closer to invisible than it feels.

    Sentiment, or framing, is the qualitative read: does the model call you “the enterprise option” or “a cheaper alternative”? Two brands can share the same visibility rate while one gets described in language that quietly kills deals.

    Source-Level Analytics, Not Just a Dashboard Number

    Then there’s source attribution, the citation supply chain. This tracks which domains feed the AI’s answer about your category.

    It reframes the whole problem. If an AI cites a specific review site or industry journal when recommending tools in your space, your real optimization target isn’t only your own domain. It’s earning presence on the sources the model already trusts. A dashboard that shows your visibility score but hides which sources moved it leaves you optimizing blind.

    From Dashboard to Platform: What a Complete AI Prompt Tracking System Does

    Measurement is table stakes. The reason to graduate from a basic tool to a full AI prompt tracking platform is execution, turning the data into a decision you can ship the same day.

    This is where Topify is built differently. Instead of stopping at rows in a database, it runs a closed loop from discovery to action.

    It starts with High-Value Prompt Discovery. Rather than asking you to guess which 50 prompts to track, the system surfaces high-volume questions in your category where your brand is currently dark, then keeps surfacing new ones as AI recommendation patterns shift. You’re not maintaining a static prompt library by hand.

    From there, the analytics run across seven dimensions, visibility, sentiment, position, volume, mentions, intent, and CVR, so a drop in ChatGPT mentions can be traced to a specific cause rather than logged as a mystery.

    Competitor benchmarking sits in the same view. You see your share of voice against rivals at the individual prompt level, which is far more useful than a category-wide average, plus emerging competitors as AI starts naming them.

    The source layer is what ties it together. The platform reverse-engineers the exact domains and URLs the AI cites, so if a competitor is being referenced by a publication that ignores you, the gap maps straight to a content target. From there, you can move on a strategy with one-click execution instead of routing findings through three more meetings.

    For a marketing team, the practical difference is simple. A monitoring dashboard tells you that you’re losing. A complete system tells you where, why, and what to publish next.

    You can get started with Topify on a 30-day trial that covers ChatGPT, Perplexity, and Google AI Overviews tracking.

    Build Your Own AI Prompt Tracking System or Buy One?

    If you have engineers, building an in-house AI prompt tracking software stack looks tempting. Query a few model APIs, parse the responses, store the results. How hard could it be?

    Harder than it looks, and the cost is mostly hidden. The build versus buy math rarely favors building once you account for ongoing maintenance rather than the first prototype.

    FactorSelf-built systemSpecialized platform
    Data integrityFragile APIs, growing maintenance debtScalable, high-availability architecture
    Engine coverageHard to sustain across 5+ platformsCross-platform sync out of the box
    Hidden costsEngineering time, API spend, cloud overheadPredictable subscription
    ActionabilityOften ends as data silosBuilt-in gap and content analysis

    The pattern most teams hit is the data-silo trap. The pipeline works, the numbers land in a database, and then nobody has time to turn rows into decisions because they’re busy keeping the pipeline alive.

    Bottom line: for most teams, buying frees you to spend your hours applying the data, citation building, content pruning, repositioning, instead of repairing infrastructure.

    Conclusion

    AI visibility is the new baseline, and you can’t manage what you only glance at once a week. The path forward is concrete: define a library of 25 to 50 decision-stage prompts, measure where your brand is currently invisible, audit which sources feed the AI’s recommendations, then move to a tool-based system so you’re watching trends instead of snapshots.

    The goal isn’t a prettier dashboard. It’s knowing, with enough confidence to act, exactly where your brand stands the next time a buyer asks an AI for a recommendation.

    FAQ

    Q: What are the best tools for monitoring brand visibility in AI search results? 

    A: Look for a tool that tracks across multiple engines (ChatGPT, Perplexity, Gemini, Google AI Overviews) rather than one, breaks visibility into position and sentiment instead of a single score, and shows the sources behind each answer. Platforms like Topify combine prompt-level tracking with source analysis and competitor benchmarking in one place.

    Q: What are AI search optimization tools? 

    A: They’re platforms that measure and improve how AI engines represent your brand in their answers, often called GEO (Generative Engine Optimization) or AEO tools. Unlike traditional SEO software focused on Google rankings, they track mentions, citations, and framing inside generative responses.

    Q: What are the best tools for monitoring generative AI search results? 

    A: The strongest options monitor a defined prompt set continuously, use rolling averages to filter out model noise, and connect findings to action, like flagging which content or citations to build next. Continuous monitoring matters more than a one-time audit because generative answers shift week to week.

    Q: What are the best AI search optimization tools for improving brand visibility? 

    A: Prioritize tools that close the loop between data and execution. Tracking alone shows where you’re invisible; the ones that move the needle also surface high-value prompts, map citation gaps to specific sources, and let you act on a strategy quickly rather than just exporting a report.

    Read More

  • AI Prompt Tracking Tool: What It Is and How It Works

    AI Prompt Tracking Tool: What It Is and How It Works

    Your keyword rankings held steady all quarter. Domain authority’s up. Organic traffic looks fine on the dashboard. Then a prospect types “best tool for my category” into ChatGPT, reads the three names it recommends, and yours isn’t one of them. Nothing in your SEO stack flagged it, because rank trackers were built to watch a results page, not the inside of an AI answer. That blind spot is where a different kind of tracking comes in, one that measures what models actually say about you when nobody’s watching the SERP.

    What an AI Prompt Tracking Tool Actually Tracks

    An AI prompt tracking tool monitors how a brand shows up inside AI-generated answers, measured at the level of individual prompts. A prompt is the real question a user asks an assistant, like “what’s the best CRM for a small sales team.” The tool watches whether your brand appears in the response to that prompt, where it lands, and how it’s described.

    That’s a different unit of measurement than traditional SEO. A keyword rank tracker tells you your page sits at position 4 for a search term. It says nothing about whether ChatGPT names you when someone asks for a recommendation. The link and the answer are separate worlds now.

    The shift is big enough to matter. AI-driven search jumped from under 10% of interactions in 2023 to roughly 30% by 2026. And according to Similarweb, searches ending without a click rose from 56% to 69% once AI answers started landing at the top of results. When the answer is the destination, being named inside it is the new front page.

    So at the prompt level, these tools typically track four things: how often you’re mentioned, where you sit in the answer, how the model frames you, and which sources it cites to back the claim. Put simply, it answers a question your SEO reports can’t. When AI talks about your category, does it mention you, and what does it say?

    How an AI Prompt Tracking Tool Works Under the Hood

    Under the hood, prompt tracking runs a loop. It starts with a prompt library, a curated set of questions that mirror how real buyers research. These aren’t keywords. They’re full questions like “X vs Y” or “best solution for this use case,” because that’s how people actually talk to assistants.

    Next, the tool runs those prompts across multiple engines on a schedule. ChatGPT, Perplexity, Gemini, and Copilot each retrieve and rank information differently, so checking one tells you almost nothing about the others. The fragmentation is real. ChatGPT’s share of B2B AI referrals fell from 89% to about 63% in roughly eight months as Gemini, Claude, and Perplexity absorbed the rest.

    Track one platform and you’re measuring a third of the picture.

    Then it parses the output. Using language processing, the tool pulls out brand mentions and, just as important, the citation chain, the source URLs the model leaned on to build its answer. Those citations are the closest thing GEO has to a backlink graph.

    Here’s the part that trips people up. AI answers aren’t deterministic. The same prompt can return different results across sessions because of model updates, memory features, and randomness in how text gets generated. A single check is a snapshot of noise. So a decent tool computes a rolling average over 7 to 30 days, which is what turns scattered readings into a trend you can act on.

    The Metrics That Tell You If You’re Visible or Invisible

    Raw mentions feel satisfying, but one number rarely tells the truth. Knowing how to measure AI search performance means watching a few metrics together.

    Visibility rate is the starting point: the percentage of your tracked prompts where the brand shows up at all. Share of voice puts that in context by comparing your presence against direct competitors for the same prompts. You can be mentioned 40% of the time and still be losing if a rival hits 70%.

    Position matters too, and it’s where the idea of an ai visibility rank tracker becomes literal. Being named last in a list of eight, or buried under a “you might also consider” aside, isn’t the same as being the first recommendation. Salience inside the answer is the new ranking.

    Then there’s sentiment, or framing. A model can mention you accurately and still cast you as the budget option when you sell premium. And citation strength tells you which sources the AI trusts to talk about you, because fixing those sources is often how you move the other numbers.

    The trap is measuring any one of these alone. A visibility spike means little if sentiment is sliding or a competitor’s share of voice is climbing faster. Read them as a set.

    What Most Teams Get Wrong When They Start Tracking

    Most early GEO programs fail in predictable ways.

    The first is treating prompts like keywords. Teams port their old keyword list straight into the prompt library, either too broad (“CRM”) or too granular to match how anyone actually asks an assistant. Prompts are conversations, not search strings.

    The second is single-platform bias. Monitoring only ChatGPT ignores the citation-first behavior that drives Perplexity and the integrated answers inside Gemini and Google AI Overviews, which now surface on a large share of informational queries. Different engines, different rules.

    Third is static monitoring. Checking once a month feels efficient and produces garbage data, because models update and citation patterns drift on a scale of weeks, not quarters.

    And fourth is the attribution gap. Plenty of teams watch AI visibility rise and never connect it to branded search volume or organic traffic, so the work never earns its budget. Roughly 25% of B2B buyers now use generative AI for vendor research before they build a shortlist. If you can’t tie visibility to that pipeline, you can’t defend the spend.

    Best AI Prompt Tracking Tools and What Separates Them

    Search “AI prompt tracking tool” and you’ll find two broad types, and they’re not interchangeable. Before comparing names, it helps to know what actually separates them: engine coverage, whether the tool finds high-value prompts for you or makes you guess them, depth of citation analysis, and whether it stops at a dashboard or helps you act.

    That last point is the real divide. Lightweight monitors tell you what happened. Comprehensive platforms tell you what to do next.

    ApproachEngine coverageWhat it surfacesWorkflow
    Monitoring-only toolsOften one or two enginesMention and visibility snapshotsReporting stops at the dashboard
    Comprehensive GEO platforms, like TopifyChatGPT, Gemini, Perplexity, and morePrompts, citations, competitor gapsMonitor, analyze, then act

    Topify sits in the second group. It tracks brand performance across major engines through seven metrics, visibility, sentiment, position, volume, mentions, intent, and CVR, so you’re not stitching separate readings together. Its prompt discovery surfaces the high-volume questions worth tracking instead of leaving you to guess them. And its source analysis reverse-engineers the exact domains and URLs an engine cites, so when your visibility drops you can trace it to a specific citation that stopped pointing your way, then fix the content or earn the mention. For a sense of the free diagnostics available for this kind of work, Topify keeps a public reference of GEO free tools.

    Other monitoring tools cover the basics well and can be the right call for a small team testing the water. The difference shows up when you need to move a number, not just watch it.

    A Checklist for Choosing and Improving Your Setup

    If you’re setting this up from scratch, a simple sequence keeps it useful.

    1. Build a prompt library of 50 to 100 questions that mirror the buyer journey: comparisons, pain-point queries, and category research. Map them to how people actually ask, not to your keyword sheet.
    2. Set a baseline. Track visibility and share of voice for 30 days across ChatGPT, Perplexity, and Google AI Overviews before you judge any movement.
    3. Audit citations. Find the authority domains, review sites, forums, industry publications, that engines lean on for your top prompts. These are your targets.
    4. Close the gaps. Use the tool’s gap analysis to restructure landing pages so a model can parse them as the definitive source, not a maybe.
    5. Watch the competition. Track your top three rivals so you can see how their framing differs from yours and where they’re winning prompts you aren’t.

    Improving the numbers follows from the audit. If a competitor owns a prompt because three review sites cite them and none cite you, the strategy is earning those citations, not rewriting your homepage for the tenth time. When you’re ready to run this as a live loop rather than a one-off check, you can get started with a tracked prompt set and expand from there.

    What an AI Prompt Tracking Tool Costs

    Pricing in this category follows the work the tool does, not a flat rate. Most vendors meter on prompt volume, tracked engines, seats, and analysis depth, which is why two tools with similar dashboards can sit a tier apart.

    Across a survey of 34 AI search visibility tools, entry plans cluster around a $79 median while the top public tier lands near $400, and prompt volume is the single biggest reason a plan steps up. Pure monitoring tools tend to run cheaper than platforms that also handle execution. A separate analysis of 20 tools puts the practical range for most teams at $79 to $149 a month, with sticker prices stretching from $20 to several thousand at the enterprise end.

    For reference, Topify’s Basic plan runs $99 a month and covers ChatGPT, Perplexity, and AI Overviews tracking with 100 prompts and a 30-day trial, while Pro at $199 lifts that to 250 prompts. Full tiers sit on the Topify pricing page. The sensible approach is the one buyers use across the category: start small, confirm that visibility moves real traffic, then scale the prompt count as the value shows up.

    Conclusion

    Traditional rank trackers still do their job. They just can’t see the layer where more and more buying decisions now start, inside an AI answer where your brand is either named or invisible. An AI prompt tracking tool fills that gap by measuring what models say about you, across engines, over time.

    The practical first step is small. Pick 50 prompts that match how your buyers ask, track them for a month across the engines they use, and see where you actually stand. You can’t improve a number you’ve never measured.

    FAQ

    Q: What is an AI prompt tracking tool, in plain terms? 

    A: It’s an analytics tool that checks whether AI assistants mention and recommend your brand when users ask real questions. Instead of measuring where your link ranks on Google, it measures how you show up inside the answer ChatGPT, Perplexity, or Gemini generates.

    Q: How is an AI prompt tracking tool different from an SEO rank tracker? 

    A: A rank tracker watches your position on a search results page. A prompt tracker watches your presence inside an AI-generated response: whether you’re mentioned, where you sit in the answer, how you’re framed, and which sources the model cites. One looks at the list of links, the other looks at what replaced the list.

    Q: How do you measure success with one? 

    A: Watch a few metrics together rather than chasing a single count. Visibility rate shows how often you appear, share of voice compares you to competitors, position shows where you land in the answer, and sentiment shows how you’re described. A rise in one means little if another is falling.

    Q: How much does an AI prompt tracking tool cost? 

    A: Most teams land in the $79 to $149 a month range, with entry plans commonly near a $79 median and enterprise tiers running several hundred and up. Pricing usually scales with prompt volume and engine coverage, so a small tracked set costs far less than monitoring hundreds of prompts across every platform.

    Read More

  • AI Response Monitoring Dashboard: What to Track

    AI Response Monitoring Dashboard: What to Track

    Your team checks ChatGPT on Monday, Perplexity on Wednesday, and Gemini whenever someone remembers. Each answer gets pasted into a spreadsheet nobody trusts by Friday. One week your brand shows up in the recommendation. The next week it’s gone, and no one can say what changed. Checking AI answers by hand scales badly, and it tells you almost nothing about the trend underneath. The problem was never running the checks. It’s seeing all of them in one place, over time, with enough detail to act on. That’s what an AI response monitoring dashboard is supposed to do, and where most fall short.

    What AI Response Monitoring Software Actually Tracks

    AI response monitoring software tracks how AI models describe and recommend your brand, not where a page ranks. Rank tracking answers “where do I appear in the list.” AI response monitoring answers a different question: does the model mention you at all, how does it describe you, and is the sentiment in your favor.

    That distinction matters more than it sounds. AI engines synthesize one answer from many sources. You’re either inside that synthesized answer or you’re not. There’s no position 7 to climb toward.

    This is where a lot of teams get caught. Research on the B2B buying journey found that 94% of B2B buyers now use AI answer engines like ChatGPT, Perplexity, and Gemini as a primary research channel. Yet the correlation between Google rankings and AI citation probability runs as low as 0.034, close to none. A brand can hold strong organic rankings and still be absent from every AI recommendation in its category.

    Call it the invisibility gap. Your SEO dashboard says you’re winning. The AI answer your buyer actually reads never names you.

    How an AI Response Monitoring Dashboard Works

    AI search is non-deterministic. The same prompt returns different answers depending on context, model version, and session history. That’s why a single manual check tells you so little. One analysis found citation overlap between platforms can sit as low as 11 to 12%, so a spot check on one engine, on one day, is closer to a coin flip than a measurement.

    A monitoring dashboard replaces the spot check with a system. The pipeline usually runs in three stages.

    First, prompt universe mapping. You define a golden set of high-intent prompts that mirror how buyers actually query AI: category questions, comparison questions, and problem-based questions.

    Second, cross-platform sampling. The system runs those prompts across engines on a schedule, not when someone remembers.

    Third, entity parsing. Natural language processing pulls structured data out of the unstructured answers: whether you’re mentioned, how you’re positioned against competitors, and which third-party domains the model cited as proof.

    The output is the part that matters. Instead of a spreadsheet of pasted text, you get a trend line for each metric, per engine, over time. That’s the difference between knowing your mention rate dropped and guessing that it might have.

    The Metrics That Separate Noise From Real Signal

    Counting mentions is where most dashboards stop. It’s also where they go wrong. A mention with no sentiment or position attached can hide the fact that you’re being described as the expensive option or the last resort.

    Useful AI response monitoring analytics track seven dimensions, not one:

    MetricWhat it tells you
    Visibility / mention rateShare of prompts where your brand shows up
    PositioningWhether you’re the primary pick or a footnote
    SentimentThe tone of the description, leader vs. expensive
    Share of voiceYour mentions vs. competitors in category answers
    Citation source authorityWhich domains the AI trusts to validate you
    Intent alignmentWhether the answer matches a high-intent buyer stage
    Conversion likelihoodA proxy for whether the citation drives real traffic

    This is the model Topify built its dashboard around. Its Comprehensive GEO Analytics view consolidates visibility, sentiment, position, volume, mentions, intent, and a conversion visibility rate into one screen. In practice, that means you can watch your mention rate drop on Perplexity and trace it to a specific source domain that stopped citing you, without leaving the dashboard.

    The metric you skip is usually the one that explains the number you care about.

    Where Most AI Response Monitoring Tools Fall Short

    Plenty of tools claim to monitor AI answers. The gap shows up in what they ignore.

    Single-engine blindness is the most common. A tool that only watches ChatGPT misses the distinct sourcing behavior of other engines. Perplexity leans on community signals. Gemini leans institutional. Watch one and you’ve measured a third of the picture.

    Mention counting without context is the next trap. A rising mention count looks like progress, right up until you read the sentiment and find the model calls you a budget alternative.

    Then there’s the stale snapshot problem. Citation patterns drift week to week. A tool that samples occasionally catches the drift only after it’s already cost you pipeline.

    And the one teams ignore most: citation sources. AI models recommend based on consensus across third-party domains. Skip your reputation on the sites the model trusts, like G2 or industry media, and you starve it of the data it needs to recommend you.

    How to Choose an AI Response Monitoring Solution

    A good AI response monitoring solution earns its place against a short checklist, not a long feature list. Five things matter.

    RequirementWhy it matters
    Engine coverageAt least 4 major platforms, or you’re measuring a fraction
    Metric depthSentiment and position, not just a yes/no mention
    Citation analysisShows which domains drive your citations
    Competitive benchmarkingTracks rivals in the same prompt set
    ActionabilityTurns data into a clear next step, not a log to read

    The last row is where most platforms stop short. A dashboard full of numbers and no instruction on what to do next still leaves the work to you.

    This is the line Topify draws between data and action. Beyond the seven-metric view, it benchmarks competitors in real time across your prompt set and analyzes the exact domains and URLs each engine cites, so you can see whether you or a rival owns those references. Its one-click execution then turns a finding into a deployed GEO strategy, stated in plain English and launched without a manual workflow.

    For a marketing team, the test is simple. Can the tool tell you not just that your visibility dropped, but what to change and on which platform?

    What AI Response Monitoring Software Costs

    AI response monitoring software pricing tends to track three things: how many prompts you monitor, how many engines you cover, and how many AI answers the platform analyzes each month.

    Topify’s pricing starts at $99 a month on the Basic plan, which covers ChatGPT, Perplexity, and AI Overviews tracking, 100 prompts, and 9,000 AI answer analyses, with a 30-day trial. The Pro plan at $199 a month raises that to 250 prompts and 22,500 answer analyses. Enterprise starts at $499 a month with a dedicated account manager.

    The math worth running isn’t the subscription. It’s the cost of staying invisible while 94% of your buyers research in AI. A plan that surfaces one prompt where a competitor replaced you can pay for itself in a single recovered deal.

    You can get started and scale once the value is clear.

    Conclusion

    The manual approach, checking each engine by hand and hoping the spreadsheet holds up, doesn’t fail because teams aren’t diligent. It fails because AI answers shift faster than anyone can track them one screenshot at a time. An AI response monitoring dashboard fixes the problem at its root: it watches every engine on a schedule, structures what they say, and shows you the trend with enough detail to act. Start by mapping the prompts your buyers actually ask, baseline your share of voice, then watch what moves. The brands that win in AI search are the ones measuring it before their pipeline tells them to.

    FAQ

    Q: How do you improve AI response monitoring results?
    A: Start with a baseline scan to find prompts where competitors are mentioned and you’re not. Then refine the content AI parses for those topics, using structured data, FAQ-style answers, and clear statistics, and build authority on the third-party domains the engines already cite. Re-monitor each cycle to confirm the change moved your share of voice.

    Q: What’s an example of AI response monitoring software in action?
    A: A team notices its mention rate on Perplexity fell over two weeks. The dashboard traces it to a review site that stopped citing the brand. They prioritize that domain, the citation returns, and the mention rate recovers on the next sampling cycle. The dashboard turned an invisible drop into a fixable task.

    Q: What should be on an AI response monitoring checklist?
    A: Coverage of at least four engines, metric depth beyond binary mentions, citation source analysis, competitor benchmarking in the same prompt set, and a clear action layer that tells you what to change.

    Q: What’s a good strategy for AI response monitoring?
    A: Treat monitoring as the diagnostic half of a cycle: baseline your share of voice, run a gap analysis against competitors, refine content and authority on the domains AI trusts, then re-monitor to measure impact. Monitoring without a strategy loop is just watching the number move.

    Read More