Category: Article

  • How to Write Content That LLMs Actually Cite

    How to Write Content That LLMs Actually Cite

    Your blog post ranks third on Google for a high-intent buyer keyword. Organic traffic is steady. Then a prospect types the same question into ChatGPT and gets a five-brand recommendation. Your brand isn’t on it.

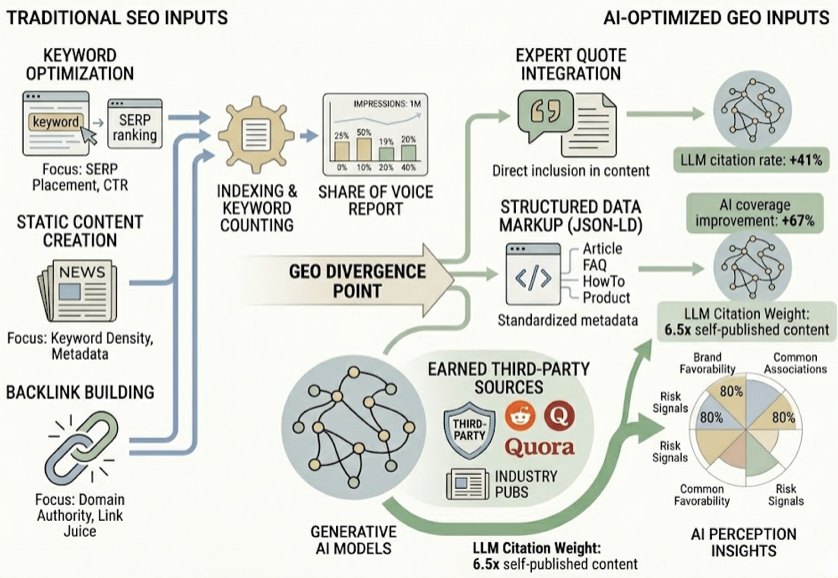
    That’s not a ranking failure. It’s a content format failure. In mid-2025, roughly 76% of URLs cited in AI Overviews also ranked in the organic top 10. By February 2026, that overlap collapsed to 38%. The signals that earn a Google ranking and the signals that earn an LLM citation are splitting apart, and most content teams are still writing for only one side.

    The gap has a name: the Invisibility Gap. And closing it starts with how you structure your content.

    Google Rewards Keywords. LLMs Reward Clarity.

    Traditional SEO content follows a familiar formula: match the keyword, build backlinks, optimize meta tags, and climb the SERP. That formula still works for Google. It doesn’t work for the retrieval systems powering ChatGPT, Perplexity, and Gemini.

    Here’s the difference. Google’s algorithm ranks pages. LLMs extract passages. When a generative engine receives a query, it doesn’t return a list of links. It runs a Retrieval-Augmented Generation (RAG) pipeline that converts the query into a vector, searches a live index, pulls 200 to 500 candidate URLs, scores individual passages for factual density and entity clarity, and then synthesizes a single answer from the top-scoring chunks.

    Google’s AI Overviews, for example, narrow approximately 500 candidate pages down to 5 to 15 cited URLs. The selection criteria aren’t page-level authority metrics like Domain Rating. They’re passage-level qualities: semantic completeness, verifiable claims, and clear entity definitions.

    That changes what “good content” looks like.

    DimensionTraditional SEO ContentGEO-Optimized Content
    Primary GoalRank in top 10 linksEarn inline citations
    Core LogicKeyword density + backlinksFactual density + structure
    User BehaviorClick-through to websiteSynthesized answer in interface
    Success MeasureCTR and organic trafficVisibility Score and Sentiment

    The practical implication: a page ranking at position 50 can still get cited in an AI Overview if it contains a highly specific, factual answer that top-ranking pages lack. Position doesn’t guarantee citation. Content quality at the passage level does.

    The Information Gain Problem: Why Most Content Gets Ignored

    The single biggest factor separating cited content from ignored content in 2026 is Information Gain, the measure of genuinely new, unique, and verifiable insight that a piece of content adds to what already exists on the web.

    LLMs are trained on (or retrieve from) massive text corpora. When your content says roughly the same thing as the other 30 articles on the topic, the model has no reason to cite yours specifically. It absorbs the information and attributes it to nobody.

    Research from Princeton University, Georgia Tech, and the Allen Institute for AI, published at the 2024 ACM SIGKDD conference, quantified this effect. Their findings show that adding expert quotations to content increases AI visibility by 41%. Including original statistics provides a 32% boost. Citing authoritative third-party sources lifts visibility by 30%.

    The “5-to-7 Rule” offers a practical benchmark: competitive content in 2026 needs five to seven distinct, original, attributable insights to have a realistic shot at citation. An “insight” means something specific enough to be quoted, like a proprietary data point, a coined framework, or an expert opinion that the LLM couldn’t have generated from its own training data.

    Content that merely rephrases existing information scores low on Information Gain and gets absorbed. Content that introduces new data points becomes citable.

    Four Pillars of Content That LLMs Actually Extract

    LLMs don’t read content the way humans do. They parse it for machine-readable signals and extractable facts. Writing for both audiences requires a framework that bridges human readability with machine retrieval.

    Pillar 1: Answer-First Architecture

    Generative engines favor content that addresses the query directly in the opening section. The practical rule: lead every H2 with a 40 to 60 word “atomic” answer that directly responds to the question the heading implies.

    This gives the RAG system a high-confidence snippet it can extract and serve as a direct response, with your URL as the cited source. Pages that bury the answer under three paragraphs of context lose to pages that lead with it.

    Pillar 2: Entity Clarity Through Structure

    Every section needs clear subject-verb-object (SVO) structures. LLMs use these to map “triples” into their knowledge graphs. Instead of writing “it provides better results,” write “[Product Name] increases [Metric] by [Percentage].”

    Proper semantic HTML matters here too. Content with a clear H1-to-H4 hierarchy has a 40% higher parsing probability than flat, unstructured text. The model needs to understand what each section is about before it can decide whether to cite it.

    Pillar 3: Third-Party Consensus

    AI models trust external sources more than brand-owned content. The data is stark: earned media like Reddit threads, industry publications, and G2 reviews are cited at a rate of 72% to 92% in branded queries. Brand-owned blog content? Less than 27%.

    That doesn’t mean your blog doesn’t matter. It means your blog alone isn’t enough.

    The “Consensus Signal” triggers when an AI scans multiple independent sources and finds agreement. If your product is consistently described the same way across Reddit, YouTube, G2, and industry forums, the AI gains the confidence to recommend it. Your blog provides the canonical definition. External sources provide the validation.

    Pillar 4: Freshness and Verifiability

    Generative engines show a significant bias toward recent information. Content updated within the last 30 days is 3.2 times more likely to be cited than stale content. For Google AI Overviews, the highest citation rates appear for content between 30 and 89 days old.

    This means core evergreen pages need to become “living documents,” refreshed every two to four weeks with new statistics, recent developments, and updated dateModified schema timestamps.

    How to Rewrite Existing Content for AI Visibility

    You don’t need to start from scratch. The highest-ROI move is auditing and restructuring content you already have. Here’s the process.

    Step 1: Identify high-value pages. Start with pages that already rank on Google but aren’t being cited by AI. These have proven topical relevance. They just need structural upgrades to become citable.

    Step 2: Add atomic answers. For each H2, write a 40 to 60 word direct answer to the question the heading implies. Place it immediately under the heading, before any context or background.

    Step 3: Inject original data. Every section needs at least one verifiable, specific claim. Proprietary survey results, original benchmarks, or expert quotes all qualify. Generic statements like “many companies are adopting AI” don’t.

    Step 4: Implement technical signals. Add FAQ, HowTo, or Product schema markup. Implementing these structured data types increases citation likelihood by 28% to 40%. Product schema alone drives a 73% higher selection rate in AI retrieval pipelines.

    Step 5: Refresh consistently. Set a 14 to 30 day update cadence for your highest-priority pages. Even small additions, like a new statistic or an updated comparison, signal freshness to AI crawlers.

    One pattern worth watching: YouTube’s share of social citations has doubled from 19% to 39% as models like Gemini prioritize multi-modal content. If you’re producing blog content on a topic, a companion video with an SEO-optimized transcript extends your citation surface into a channel most competitors are ignoring.

    AI Visibility Tracking: Measuring Whether Your GEO Content Works

    Traditional analytics can’t tell you whether AI is citing your content. Google Analytics tracks clicks. Search Console tracks rankings. Neither tracks whether ChatGPT mentioned your brand in a recommendation, or what Perplexity said about your pricing.

    That’s the gap ai visibility tracking fills.

    The core framework for measuring GEO content performance includes seven metrics. Visibility Score measures how often your brand appears across a universe of relevant prompts, with a 2026 benchmark of 60% or above for core categories. Recommendation Position tracks where you land in the AI’s response, since being first carries an implicit endorsement that third or fourth position lacks. Sentiment Velocity catches shifts in how the AI describes your brand before they compound into reputation problems. Source Citations reverse-engineer the specific URLs influencing the AI’s opinion. Conversion Visibility Rate estimates the economic value of each mention. Entity Confidence measures how accurately the AI distinguishes your brand from competitors. And Hallucination Monitoring alerts you when an LLM fabricates false claims.

    For content teams running a GEO content strategy, the most actionable loop connects Source Citations back to content decisions. If you discover that Perplexity cites a competitor’s blog post in 40% of relevant answers, you know exactly what content gap to close. If your own article is being cited but with negative sentiment, you know which page to rewrite.

    Topify runs this loop across ChatGPT, Gemini, Perplexity, DeepSeek, and other major platforms. It tracks all seven metrics in a unified dashboard, surfaces competitor positioning in real time, and continuously identifies new high-value prompts as AI recommendation patterns shift. For teams that need to connect GEO content output to measurable visibility changes, Topify’s Source Analysis traces which specific URLs the AI is citing, so you can validate whether a content rewrite actually moved the needle.
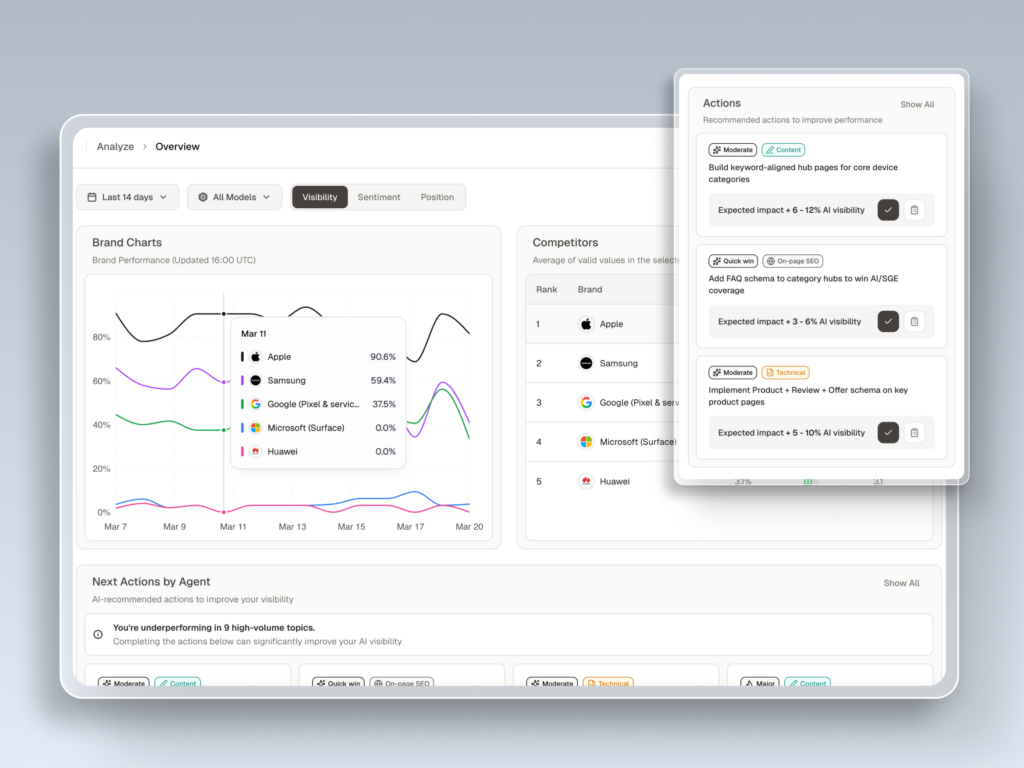
    The economics reinforce the investment. AI search traffic converts at an average rate of 14.2%, compared to 2.8% for traditional organic search. That’s a 5x advantage, which means even modest improvements in ai visibility tracking metrics translate to outsized revenue impact.

    Three Mistakes That Quietly Kill AI Visibility

    Mistake 1: Treating Google Rankings as a Proxy for AI Citations

    The overlap between organic rankings and AI citations dropped from 76% to 38% in less than a year. Teams that only monitor SERP positions are watching half the screen while the other half decides their market share. AI visibility requires its own measurement stack.

    Mistake 2: Scaling Content with AI Without Adding Information Gain

    Using LLMs to generate content at scale sounds efficient until every article reads like a reworded version of the same five sources. Models recognize content with low Information Gain and deprioritize it during retrieval. The fix isn’t to stop using AI for drafting. It’s to ensure every piece includes original data, expert perspectives, or proprietary frameworks that the model couldn’t have written on its own.

    Mistake 3: Checking AI Visibility Once and Forgetting About It

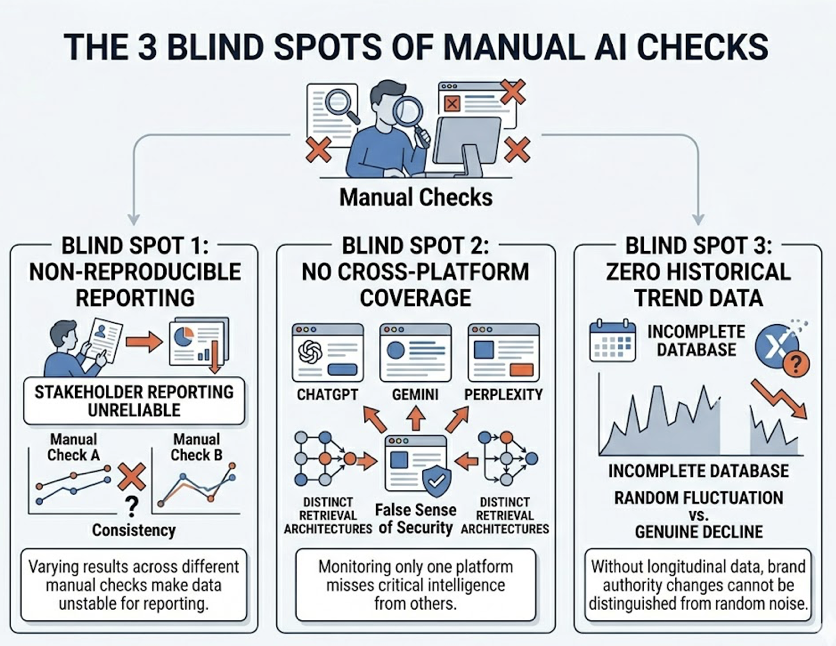
    AI responses are probabilistic. The same prompt can return different brands depending on model updates, data refreshes, and retrieval architecture changes. A single audit tells you where you stood on one day. Continuous ai visibility tracking tells you where you’re trending, and that trend line is what drives strategy.

    Conclusion

    The content that earns AI citations in 2026 isn’t fundamentally different from good content. It’s specific, structured, verifiable, and fresh. The difference is that traditional SEO let you get away with being vague. Generative engines don’t.

    The framework comes down to three moves: write with answer-first architecture and original data so LLMs can extract and cite your content, build third-party consensus so the AI trusts what you’re saying, and track visibility across AI platforms so you know whether it’s working. The brands closing the Invisibility Gap aren’t doing anything mysterious. They’re just measuring what most teams still can’t see.

    FAQ

    Q: What’s the difference between SEO content and GEO content?

    A: SEO content is optimized for page-level ranking signals like keywords and backlinks. GEO content is optimized for passage-level extraction by LLMs, focusing on factual density, clear entity definitions, and answer-first structure. The best content does both, but the optimization targets are different.

    Q: How do I know if my content is being cited by AI?

    A: You can’t tell from traditional analytics. You need a dedicated ai visibility tracking platform that monitors your brand’s appearance across AI search engines like ChatGPT, Perplexity, and Gemini. Topify tracks citation sources, visibility scores, and sentiment across multiple AI platforms in real time.

    Q: Does optimizing for LLMs hurt my Google rankings?

    A: No. The structural improvements that make content citable by LLMs, such as clear headings, direct answers, schema markup, and fresh data, also tend to improve traditional SEO performance. The two strategies are complementary, not competing.

    Q: How often should I track AI visibility?

    A: Weekly at minimum. AI responses are non-deterministic, meaning the same prompt can return different results across sessions. Continuous tracking establishes a statistical baseline and catches visibility drops before they compound.
    Read More

  • 7 Tactics That Got Our Client Cited 4× More in ChatGPT

    7 Tactics That Got Our Client Cited 4× More in ChatGPT

    Your domain authority is 65. Your top pages rank on page one for every target keyword. Your content team publishes twice a week. Then you type your core product category into ChatGPT and get back a confident, five-brand recommendation list. Your brand isn’t on it.

    That’s not a content quality problem. It’s a visibility gap that traditional SEO metrics were never built to detect. When we ran a full AI visibility tracking audit for a mid-market SaaS client last quarter, we found they appeared in only 6% of the high-intent prompts in their category. Their closest competitor showed up in 31%. Over the next 90 days, seven specific tactics closed that gap and pushed their citation rate to 4× the original baseline.

    Here’s what we did, step by step.

    Most Brands Track SEO Rankings but Miss What AI Actually Cites

    The disconnect between Google rankings and AI recommendations is wider than most marketing teams realize. Roughly 60% of all Google searches now resolve without a click to an external website. When AI Overviews trigger, that figure climbs to 83%. In conversational AI modes, it reaches 93%.

    That means the majority of discovery and evaluation is happening inside AI-generated answers, not on your website. And the clicks that do come from AI sources carry disproportionate value. AI-referred visitors convert at rates up to 23 times higher than standard organic traffic, because the intent is already compressed by the time they arrive.

    The problem is measurement. Legacy SEO tools track rank, traffic, and backlinks. They don’t tell you whether ChatGPT mentioned your brand, how Perplexity framed your product, or which sources Gemini cited instead of yours. Without AI visibility tracking, you’re optimizing for a channel that’s shrinking while ignoring the one that’s growing.

    Our client’s starting point looked strong on paper: high DA, solid keyword positions, consistent publishing cadence. But when we mapped their AI visibility across 150 prompts on ChatGPT, Perplexity, and Gemini, the picture was different. Six percent citation rate. Negative sentiment on two platforms. Zero presence in comparison prompts.

    That baseline became the starting line.

    Tactic 1: Map the Prompts That Actually Drive AI Citations

    Not all prompts are created equal. The average Google keyword is about four words. The average AI prompt runs closer to 23 words, packed with qualifiers like budget constraints, company size, and use-case specifics. Treating AI prompts like keywords is the first mistake most teams make.

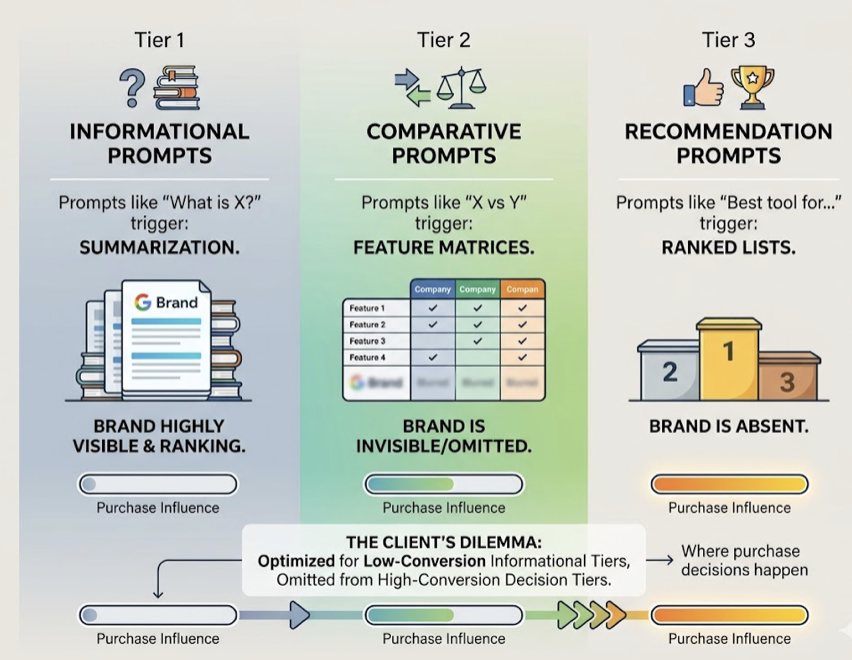
    We categorized prompts into three tiers based on citation behavior. Informational prompts (“What is X?”) trigger summarization. Comparative prompts (“X vs Y”) trigger feature matrices. Recommendation prompts (“Best tool for…”) trigger ranked lists. Our client’s content was optimized for informational queries but almost invisible in the recommendation and comparison tiers, which is where purchase decisions happen.

    The fix started with prompt discovery. Using Topify’s High-Value Prompt Discovery, we identified 40+ prompts in the client’s category where competitors consistently appeared but the client didn’t. Each prompt was scored by query volume, competitive density, and commercial intent. The top 20% of those prompts, the ones with high “qualifier density” around specific use cases and buyer profiles, became the content roadmap.

    Targeting these long-tail, high-intent prompts let the client bypass the “big brand bias” that dominates broader queries. Within three weeks, new content built for these specific prompts started appearing in AI answers.

    Tactic 2: Reverse-Engineer What AI Cites for Your Competitors

    Generative engines don’t rank pages. They retrieve sources through a process called Retrieval-Augmented Generation (RAG), which pulls from a corpus of trusted web documents to ground each response. To show up in that response, your content needs to be in the retrieval pool and match the extraction patterns the model prefers.

    Here’s the uncomfortable reality: approximately 85.5% of AI citations in informational and evaluation queries come from third-party sources like Wikipedia, Reddit, G2, and tier-1 media outlets. Brand-owned domains account for less than 10% of citations. If your GEO strategy only optimizes your own website, you’re competing for a fraction of the citation pipeline.

    We used Topify’s Source Analysis to map exactly which URLs each AI platform cited for the client’s top 30 prompts. The pattern was clear: competitors dominated not because their product pages were better, but because they had coverage on the specific G2 comparison pages, Reddit threads, and niche industry blogs that models treated as high-confidence sources.

    That analysis became the targeting list for Tactics 3 through 5.

    Tactic 3: Restructure Content for AI-Preferred Formats

    Structural optimization is one of the highest-leverage moves in GEO, and it’s often overlooked. Research into what’s called Structural Feature Engineering (GEO-SFE) shows that formatting changes alone, without altering the underlying claims, can yield a 17.3% improvement in citation rates.

    Why? Transformer-based LLMs parse text through attention mechanisms that respond to structural signals. Unstructured prose causes attention dispersion. Segmented, hierarchical text with clear headings and self-contained blocks focuses the model’s attention on the relevant section.

    The specific changes that moved the needle for our client:

    Structural ChangeCitation Impact
    Question-style H2/H3 headings+22% lift
    Pricing and feature comparison tables+47% to +51% lift
    Pros/cons lists on product pages+38% lift
    Answer-first formatting (key facts in first 200 words)+27% lift
    FAQ sections with schema markup+71% lift

    There’s a sweet spot for answer blocks: 134 to 167 words. Blocks shorter than that lack the information density models need. Blocks exceeding 300 words suffer from attention degradation in the middle. We restructured the client’s top 15 pages to fit this pattern, converting marketing copy into data-dense, table-heavy content that AI retrievers could extract cleanly.

    The shift is less about writing differently and more about formatting for machine extraction. Think “data tabulization” over “marketing fluff.”

    Tactic 4: Build Entity Authority Through Trust Anchors

    In generative search, AI systems prioritize “entities,” formally recognized concepts, over keywords. Authority isn’t just about backlink volume anymore. It’s about the consistency of signals across what models treat as “truth anchors.”

    Wikipedia sits at the top of that hierarchy. It comprises 3-4% of model training data and accounts for nearly 47.9% of ChatGPT’s top-ten citation share. Wikidata, with its structured Q-IDs, provides the metadata layer models use for entity resolution. If your brand doesn’t have a stable identifier in these systems, LLMs have lower confidence when attributing facts to you.

    Our client didn’t have a Wikipedia page. So we focused on three proxy strategies:

    First, we ensured the client’s Wikidata profile was complete, with sameAs links to social profiles, Crunchbase, and industry directories. Second, we secured mentions within existing high-authority Wikipedia articles relevant to their category. Third, we prioritized third-party review coverage on G2 and Capterra, which function as consensus validators. Research suggests brands with strong third-party review profiles see roughly a 3× citation multiplier compared to those without.

    Consistency matters here. If your website says “enterprise-grade platform” but G2 reviews describe you as “good for small teams” and your LinkedIn bio says something else entirely, the model flags the conflicting signals and defaults to a better-corroborated competitor.

    Tactic 5: Close the Source Gap Between You and Competitors

    The “Source Gap” is the structural disadvantage that exists when competitors control the third-party surfaces AI models retrieve from. Since 85% of citations come from external domains, your AI visibility is largely determined by your coverage on listicles, comparison engines, and community forums you don’t own.

    Closing this gap requires what we call “Machine Relations,” a digital PR strategy focused specifically on the URLs that AI already trusts for your category.

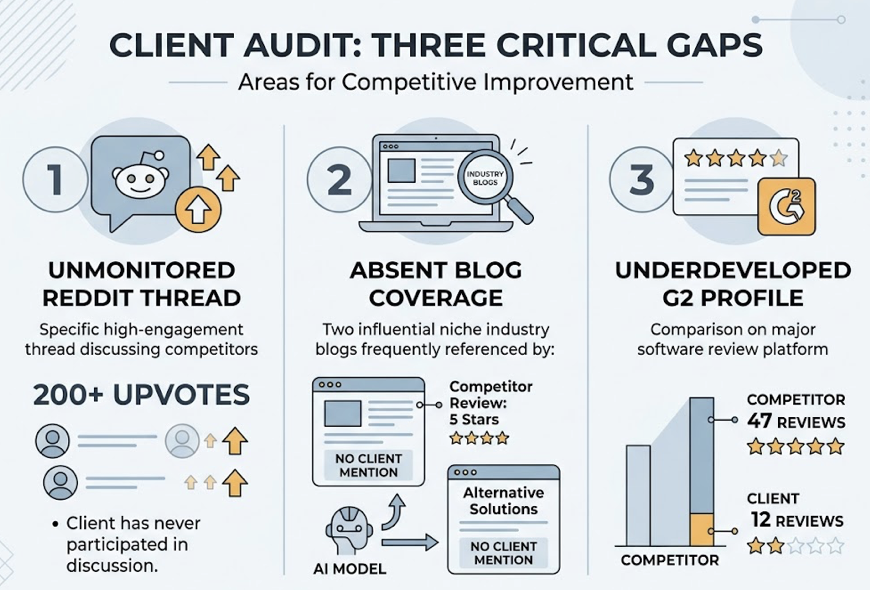
    For our client, the audit revealed three critical gaps. First, competitors were being cited from a specific Reddit thread with 200+ upvotes that the client had never participated in. Second, two niche industry blogs that models consistently retrieved had published competitor reviews but had no coverage of the client. Third, the client’s G2 profile had 12 reviews versus a competitor’s 47.

    The playbook was targeted:

    We developed authentic Reddit participation in high-visibility threads. We pitched contributed content to the two niche publications. We launched a structured review acquisition campaign on G2.

    Topify’s Competitor Monitoring flagged when new competitors entered the AI recommendation set, showing which specific URL the model referenced to justify the inclusion. That let the team respond within days, not months, securing a “corrective” placement before the next model refresh.

    Tactic 6: Maintain Citation Velocity with a Refresh Cadence

    Content in AI search has a half-life. Research shows that 50% of content cited by AI is less than 13 weeks old. AI-cited pages are on average 25.7% fresher than traditionally ranked organic content. This creates the “13-week rule”: content not refreshed quarterly is three times more likely to lose its citation position.

    Our client had several pages ranking well in traditional search that hadn’t been updated in over a year. In AI search, those pages were effectively invisible.

    We implemented a tiered refresh cadence:

    Content TypeRefresh FrequencyWhat Gets Updated
    Core product comparisonsMonthlyCurrent-year data, pricing, new features
    Category explainersEvery 8-12 weeksRecent research, updated FAQ blocks
    Thought leadershipQuarterlyNew examples, emerging trends
    Evergreen guidesBi-annuallyStatistics, relevance check

    Cosmetic date changes don’t work. Models detect and ignore them. A meaningful update requires replacing outdated statistics with current-year data, adding references to recent research, and expanding sections with new FAQ blocks addressing emerging questions. Content updated within 30 days receives up to 6× more AI citations than content over 12 months old.

    The ROI of operationalized maintenance is measurable. Within four weeks of the first refresh cycle, three previously invisible pages started appearing in AI answers.

    Tactic 7: Track, Measure, and Iterate with AI Visibility Tracking

    The non-deterministic nature of generative responses, where a single prompt can yield different outputs across different models and different days, makes legacy rank tracking obsolete. You can’t manage what you don’t measure, and measuring AI visibility requires a fundamentally different framework.

    Effective ai visibility tracking operates across seven core indicators:

    Visibility Score: The percentage of target prompts where the brand appears. Category leaders typically maintain 30-45%.

    Sentiment Score: A 0-to-100 scale measuring whether AI framing is positive, neutral, or negative. Scores below 40 indicate a reputation problem that can disqualify a brand from high-intent shortlists.

    Position Rank: The relative order of mentions in multi-brand lists. First-mentioned brands earn significantly higher trust and click-through.

    Volume Analytics: Monthly demand for topics specifically within AI interfaces, surfacing “dark queries” invisible to traditional keyword tools.

    Mentions Rate: Raw frequency of brand names within answer text, tracking awareness even without direct links.

    Intent Alignment: Whether AI correctly associates the brand with its target customer profile and primary use case.

    Conversion Visibility Rate (CVR): A predictive measure of how likely the brand’s visibility is to drive action. AI-referred traffic converts at an average of 14.2%, a 5.1× advantage over traditional search.

    For our client, we tracked all seven weekly using Topify’s Comprehensive GEO Analytics dashboard across ChatGPT, Perplexity, and Gemini. The measurement loop connected directly to execution: when citation drift showed a drop on a specific prompt cluster, we traced it to a competitor’s new G2 review and responded with a targeted content update within 48 hours.

    That feedback loop, discovery to optimization to measurement, is what turned a one-time improvement into sustained 4× growth.

    Conclusion

    The gap between brands that dominate AI recommendations and those that remain invisible comes down to systems, not luck. The seven tactics here follow a logical chain: discover the right prompts, analyze what AI already trusts, restructure your content for extraction, build entity authority, close the source gap, maintain freshness, and measure everything continuously.

    None of this is a one-time project. Citation patterns shift as models retrain and retrieval algorithms evolve. The brands that treat ai visibility tracking as an ongoing discipline, benchmarking Visibility, Sentiment, and Position weekly, will control the recommendations that define discovery in 2026 and beyond. Get started with Topify to see where your brand stands today.

    FAQ

    Q: What is AI visibility tracking? 

    A: AI visibility tracking is the process of monitoring how often and how favorably your brand appears in AI-generated answers across platforms like ChatGPT, Perplexity, and Gemini. It measures metrics like citation rate, sentiment, mention frequency, and recommendation position, none of which traditional SEO tools capture.

    Q: How long does it take to see results from AI citation optimization? 

    A: Structural content changes and technical fixes (like unblocking AI crawlers) can produce results within days. Broader tactics like entity authority building and source gap closure typically show measurable improvement within 4 to 12 weeks, depending on the competitiveness of the category.

    Q: Can you track brand mentions in ChatGPT? 

    A: Yes. Tools like Topify simulate thousands of prompts across ChatGPT and other AI platforms, tracking your brand’s mention frequency, recommendation position, and sentiment in each response. This replaces the manual approach of typing queries one by one.

    Q: What’s the difference between SEO and GEO? 

    A: SEO optimizes for ranking on search engine results pages. GEO (Generative Engine Optimization) optimizes for being cited, recommended, and accurately described inside AI-generated answers. The key metrics shift from organic rank and CTR to citation share, visibility score, and AI sentiment.

    Read More

  • Audit Your Brand’s AI Visibility in 30 Min

    Audit Your Brand’s AI Visibility in 30 Min

    Your domain authority is 70. Your keyword rankings are solid. Your SEO dashboard looks healthy by every traditional metric. Then someone asks Perplexity, “What’s the best tool for [your category]?” and your brand doesn’t appear anywhere in the answer.

    That gap between Google rankings and AI search recommendations is where revenue quietly disappears. ChatGPT referral traffic converts at 15.9%, nine times the baseline for traditional Google organic. When your brand is absent from those answers, you’re not losing impressions. You’re losing pre-qualified buyers.

    The good news: you can map exactly where you stand across AI search engines in 30 minutes. Here’s how.

    What AI Visibility Tracking Actually Measures (and What SEO Tools Miss)

    AI visibility tracking is the practice of measuring how often, how prominently, and how accurately a brand appears in the outputs of generative models like ChatGPT, Perplexity, Gemini, and Google AI Overviews.

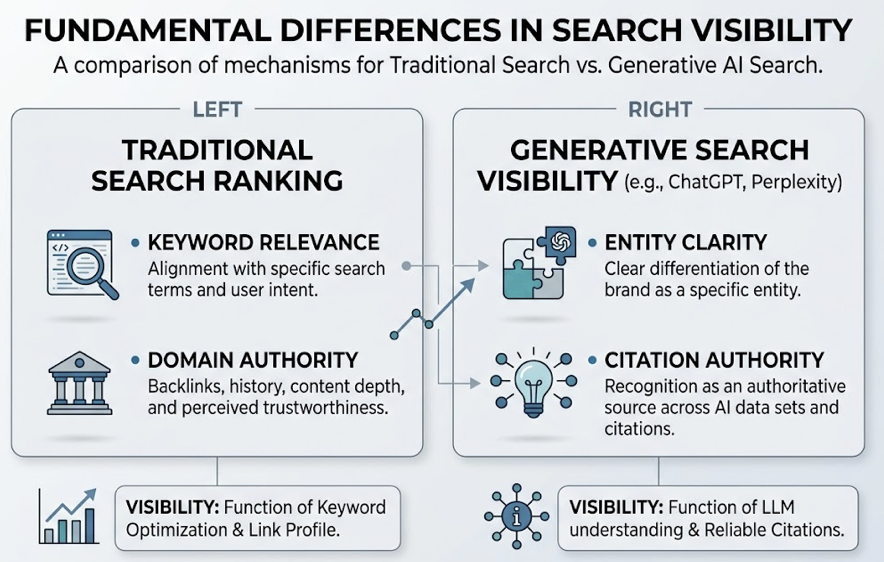
    That might sound similar to traditional rank tracking, but the mechanics are fundamentally different. In traditional search, visibility is a function of domain authority and keyword relevance. In generative search, visibility depends on what researchers call “entity clarity” and “citation authority.” A brand can hold the #1 Google position for a high-volume keyword and still be completely absent from a ChatGPT response for the same category query.

    The disconnect happens because generative engines use Retrieval-Augmented Generation (RAG) to prioritize information that shows cross-platform consensus and semantic density, not traditional ranking signals.

    Here’s what a professional AI visibility tracking framework actually measures:

    MetricWhat It Tells You
    Brand PresencePercentage of category-relevant prompts where your brand is mentioned
    Citation ShareHow often AI models link to your owned or earned media
    Sentiment PolarityThe evaluative tone the AI uses when describing your brand
    Position ProminenceWhere your brand appears in the answer (first recommended vs. buried)
    Narrative AccuracyWhether the AI’s description matches your actual features and pricing

    Tools like Google Analytics, Ahrefs, and Semrush were built to track clicks and link-based authority. They’re blind to the internal narrative logic of an LLM. While organic rankings influence what a generative engine might “see,” they don’t dictate what the engine will “say.”

    That’s the gap Topify was built to close, providing cross-platform tracking of brand mentions, citation patterns, sentiment, and positioning across every major AI engine.

    Why Most Brands Fail Their First AI Visibility Audit

    Before walking through the audit framework, it’s worth understanding why most initial attempts produce misleading results. Three failure patterns show up consistently.

    Treating LLMs like search engines. Generative models are probabilistic, not deterministic. The same prompt can produce different answers for users in London versus San Francisco, and even the same user can get different results across sessions. Searching a couple of prompts on ChatGPT and treating those results as representative is like polling two people and calling it a survey.

    A professional audit needs a multi-sample methodology: running prompts through multiple geographic nodes to capture a statistically meaningful baseline.

    Platform myopia. Most brands check ChatGPT and stop there. Research shows that only 11% of cited domains are shared across ChatGPT, Perplexity, Gemini, and Google AI Overviews. Dominance on one platform guarantees nothing on another.

    Ego-centric tracking. Auditing your brand in isolation, without benchmarking against competitors, misses the most actionable signal. In the generative era, AI visibility is a zero-sum game. If a model recommends three competitors and excludes you, that’s a definitive signal of an authority gap in the model’s retrieval cache.

    The 30-Minute AI Visibility Audit: Step by Step

    This framework is designed to be repeatable. Run it monthly or trigger it after major product launches, PR campaigns, or known AI model updates. Here’s the time breakdown: 5 + 10 + 10 + 5 minutes.

    Step 1: Define Your Audit Scope, 5 Minutes

    The foundation of any AI visibility audit is the prompt library. Select 3 to 5 core “category prompts” that reflect how a prospective customer would actually search for a solution.

    Tag each prompt by intent: Informational (“What is [category]?”), Commercial (“Best [category] for small business?”), or Comparison (“[Brand] vs [Competitor]”). Then define 3 to 5 direct competitors as your primary tracking entities.

    Platform selection matters. Your audit should cover at least ChatGPT, Perplexity, Gemini, and Google AI Overviews. Zero-click rates tell the story of where users actually get their answers: Perplexity at 93%, Google AI Mode at 88%, ChatGPT Search at 82%. Skipping any of these leaves a blind spot.

    Step 2: Check Your AI Visibility Across Platforms, 10 Minutes

    Run your prompt set across each platform and document where your brand falls into one of four categories:

    • Directly Recommended: Named as a top-tier solution.
    • Mentioned: Included in the narrative but not as a primary pick.
    • Cited: Used as a reference source with a link.
    • Absent: Completely missing from the conversation.

    Doing this manually for 5 prompts across 4 platforms means reviewing 20 responses and cataloging every brand mention. It’s possible for a limited scope, but it doesn’t scale.

    Topify’s Visibility Tracking automates this entire step. It monitors brand mentions across ChatGPT, Gemini, Perplexity, DeepSeek, and other major AI platforms, scoring each appearance across seven key metrics: visibility, sentiment, position, volume, mentions, intent, and CVR. What takes 10 minutes manually takes seconds with the right tooling.

    One data point worth noting: content updated within the last three months is roughly twice as likely to be cited by retrieval-augmented AI engines like Perplexity. If your audit reveals low visibility, freshness could be the first variable to investigate.

    Step 3: Analyze Sentiment and Positioning, 10 Minutes

    Showing up is only half the story. What the AI says about your brand matters just as much.

    In this step, examine three things. First, identify the specific themes the AI associates with your brand. Are you described as “innovative but expensive”? “Reliable but legacy”? These sentiment drivers directly shape how potential buyers perceive you before they ever visit your site.

    Second, benchmark your sentiment against competitors. If a rival’s sentiment score is consistently higher across prompts, that’s a content gap, not a branding problem.

    Third, check for hallucinations. Across major models, hallucination rates range from 15% to 52% depending on the model and query type. These errors fall into categories that directly hurt conversion: fabricated features, omitted differentiators, outdated pricing, and misattributed capabilities.

    Topify’s Sentiment Analysis provides daily breakdowns of how each AI platform characterizes your brand, with a 0-to-100 sentiment score tracked over time. Its Competitor Monitoring feature detects every brand the AI mentions alongside yours, comparing visibility, sentiment, and position side by side.

    Step 4: Identify Citation Sources, 5 Minutes

    The final step is reverse-engineering the AI’s “trust graph.” Which third-party sources is the AI citing when it forms opinions about your category?

    This matters because third-party sources are cited 6.5 times more often than brand-owned pages in AI answers. Earned media accounts for roughly 48% of citations, while your own blog contributes around 23%. If a competitor has coverage on Gartner, Forbes, or a top industry subreddit and you don’t, the AI will naturally treat them as more authoritative.

    Reddit alone accounts for approximately 21% of citations in Google AI summaries. Brands that ignore community platforms are forfeiting their authority to the most vocal users on the internet.

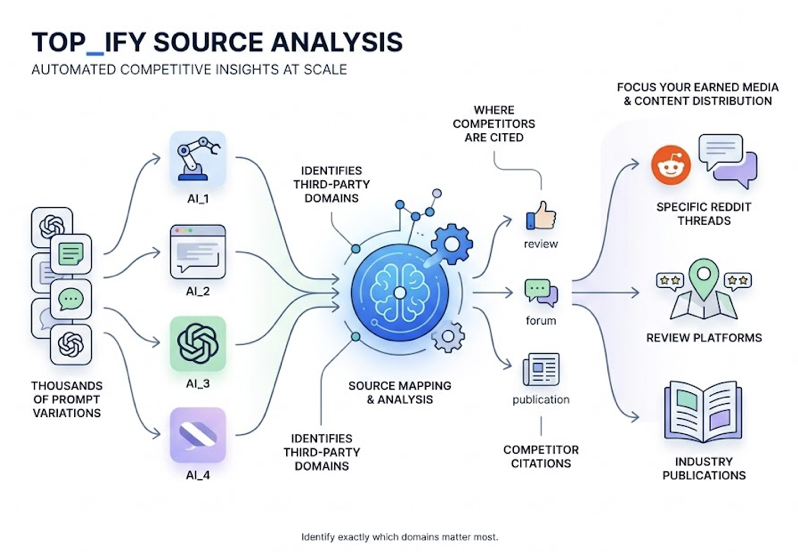
    Topify’s Source Analysis feature maps exactly which domains and URLs each AI platform cites for your category. You can see at a glance whether your brand’s owned content is in the citation mix, or whether third-party sources are shaping the narrative without your input.

    div data-topify-widget=”report-generator”>

    Turning Audit Data into a GEO Action Plan

    You’ve now collected four layers of data: visibility baseline, competitor positioning, sentiment accuracy, and citation sources. The next step is prioritizing where to act.

    Not all gaps are equally urgent. Here’s a triage framework based on common audit outcomes:

    Audit FindingPriority ActionGEO Strategy
    Low visibility across platformsRetrieval OptimizationCreate “GEO-ready” content with statistics, structured citations, and clear entity markup. Ensure GPTBot and PerplexityBot aren’t blocked by robots.txt.
    Mentioned but negative sentimentSentiment RepairAddress specific sentiment drivers (pricing confusion, outdated info) and build third-party consensus on review sites.
    Competitors winning citationsDigital PR + CommunitySecure mentions in publications and Reddit threads the AI already trusts.

    The data on GEO content strategies is concrete. Research shows that adding precise statistics to content can increase visibility by up to 65.5% in category queries. Including inline citations to credible external reports boosts visibility by up to 132.4% in informational queries. Rewriting content in a more authoritative tone lifts visibility by 89.1% in specific domains.

    On the structural side, AI models tend to prefer content organized into 120 to 180-word “atomic” sections rather than long, undifferentiated blocks of text. Implementing Schema Markup (Organization, FAQ, Author) provides the explicit metadata that helps AI crawlers identify and link entities correctly.

    Topify’s One-Click Agent Execution bridges the gap between audit data and action. Once a visibility gap is detected, the platform’s AI agent analyzes content gaps against competitor citations, drafts GEO-optimized content including schema markup and data tables, and deploys directly. It turns a diagnostic report into a production-ready content brief.

    AI Answers Change Faster Than Google Rankings. Your Audit Schedule Should Too.

    An AI visibility audit isn’t a one-time project. The generative search environment is significantly more volatile than traditional search.

    Data from 2026 shows that Google’s core updates and AI model recalibrations can shift up to 80% of top-three results in a single cycle. On top of that, there’s a “freshness gap”: Perplexity updates its index constantly, while ChatGPT may rely on training data several months old. Your brand’s position on one platform can shift without any corresponding change on another.

    Monthly audits are the baseline for maintaining narrative control. Immediate audits should be triggered by major product launches, PR crises, or known AI model updates.

    For teams that need more than monthly snapshots, Topify offers continuous monitoring. It alerts brands to citation drops or sentiment shifts in real time, so marketing teams can address inaccuracies or competitor incursions before they become entrenched in the model’s retrieval cache.

    Conclusion

    The gap between Google rankings and AI search recommendations is where the next generation of brand competition plays out. A brand can rank first on Google and be invisible to the AI engines where 900 million weekly active users now look for answers.

    The 30-minute AI visibility tracking audit outlined here gives you a structured, repeatable process to measure where you stand. Track presence, sentiment, and citations across platforms. Benchmark against competitors. Then act on the gaps with a clear GEO strategy.

    The brands that build this diagnostic muscle now will compound their authority advantage. In an era where decisions are made inside the chat box, the most valuable asset isn’t traffic. It’s the informed trust of the AI models your buyers rely on.

    Get started with Topify to run your first AI visibility audit today.

    FAQ

    Q: What is AI visibility tracking?

    A: AI visibility tracking is the process of measuring how often your brand gets mentioned, how it’s described, and where it ranks in the outputs of generative AI engines like ChatGPT, Perplexity, and Gemini. It goes beyond traditional SEO metrics to capture presence, sentiment, citation share, and positioning across AI-generated answers.

    Q: Can I audit my brand’s AI visibility without a paid tool?

    A: You can run a basic manual audit by entering category prompts into ChatGPT, Perplexity, and Gemini and documenting the results. The limitation is scale: AI outputs are probabilistic and vary by session and geography, so manual checks give you a snapshot, not a trend. Professional tools like Topify automate this across thousands of prompts and multiple platforms simultaneously.

    Q: Which AI platforms should I track for brand visibility?

    A: At minimum, cover ChatGPT, Perplexity, Gemini, and Google AI Overviews. Each runs a different retrieval pipeline, and only 11% of cited domains overlap across platforms. A brand can be a category leader on ChatGPT and completely absent from Perplexity.

    Q: How often do AI search recommendations change?

    A: More often than traditional Google rankings. AI model recalibrations and retrieval index updates can shift up to 80% of top-three results in a single cycle. Monthly audits are a reasonable baseline, with immediate checks after major product launches or known model updates.

    Read More

  • How AI Picks Which Brands to Cite

    How AI Picks Which Brands to Cite

    Inside the Ranking Logic of ChatGPT, Perplexity, and Gemini

    Your team spent six months building content, earning backlinks, and climbing Google rankings. Then a potential customer asked ChatGPT, “What’s the best tool for [your category]?” and got a list of five recommendations. Your brand wasn’t on it.

    The disconnect isn’t a fluke. Research shows the correlation between a high Google ranking and being cited in a ChatGPT response is just 0.034. That’s nearly random. Your SEO dashboard says everything is fine. The AI engines say you don’t exist.

    The brands that do get cited aren’t always the ones with the strongest domain authority. They’re the ones whose data is structured, validated across third-party sources, and formatted in ways that AI retrieval systems can actually extract. Understanding that logic is the first step toward fixing it.

    Your Google Rankings Don’t Decide What AI Recommends

    Here’s the assumption most marketing teams still operate under: if we rank on the first page of Google, AI search engines will recommend us too.

    That assumption is wrong.

    Traditional SEO is built on backlinks, domain authority, and keyword density. Generative engines like ChatGPT, Perplexity, and Gemini use a completely different retrieval logic. They don’t rank websites. They synthesize factual claims from a diverse ecosystem of sources, then assemble a response based on which entities have the highest “semantic density” and cross-platform validation.

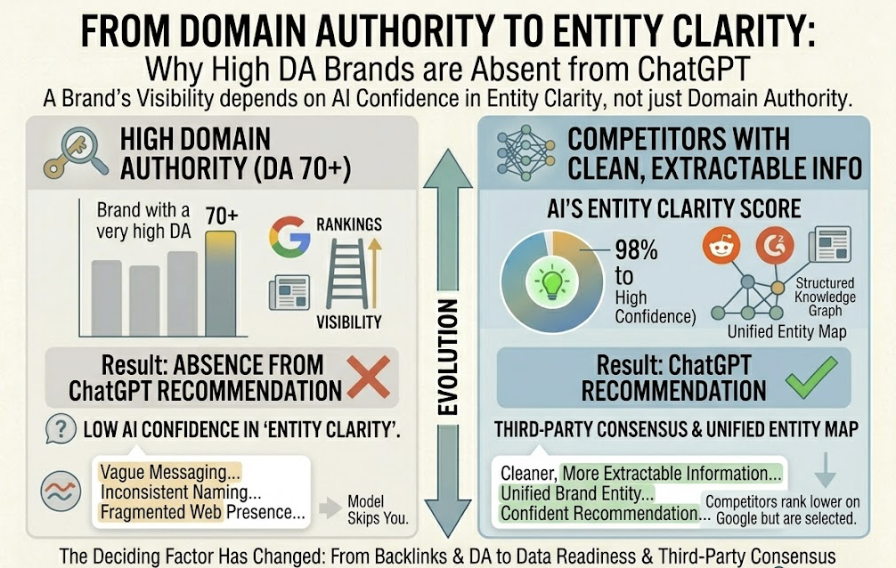
    A brand with a DA of 70+ can be entirely absent from a ChatGPT recommendation for its core product category. Not because the content is bad, but because the AI’s confidence in that brand’s “entity clarity” is low. If your messaging is vague, your naming inconsistent, or your presence fragmented across the web, the model skips you in favor of competitors who may rank lower on Google but present cleaner, more extractable information.

    DimensionTraditional Search (Google)Generative Search (ChatGPT/Perplexity)
    Primary GoalRanking in top 10 blue linksInclusion in synthesized answer
    Authority ProxyBacklinks and DAThird-party consensus and earned media
    User InteractionClick-through to websiteZero-click information consumption
    Optimization FocusKeywords and technical SEOEntity binding and answerability

    The shift is structural, not incremental. It demands a different optimization framework entirely: Generative Engine Optimization, or GEO.

    What ChatGPT, Perplexity, and Gemini Actually Look For

    The generative search market isn’t a monolith. Each platform has its own retrieval architecture, source preferences, and citation patterns. A study found that only 11% of cited domains appeared across multiple AI platforms, which means a single optimization strategy won’t cover all three.

    ChatGPT uses a Retrieval-Augmented Generation (RAG) pipeline that queries the Bing index in real time. It favors depth and comprehensiveness, typically providing between 3.5 and 8 citations per response. It leans heavily on authoritative “earned media,” encyclopedic sources, and high-authority industry publications. If your brand is well-covered in third-party reviews and industry roundups, ChatGPT is more likely to surface you.

    Perplexity operates as a search-first retrieval engine with clear, numbered inline citations. It’s the most sensitive to content freshness: content updated within the last 30 days has an 82% citation rate, while content older than six months sees a steep drop. Perplexity also shows a willingness to cite smaller, specialized niche blogs over high-DA generalists if the data is more precise.

    Gemini and AI Overviews draw from Google’s two decades of crawl history and its Knowledge Graph. Gemini inherits Google’s E-E-A-T signals but applies a different authority weighting than the traditional ranking algorithm. While AI Overviews have high semantic overlap with standard Google results, the URL overlap is just 13.7%.

    FeatureChatGPTPerplexityGemini / AI Overviews
    Search PartnerBingProprietary + Bing HybridGoogle Index / Knowledge Graph
    Avg Citations7.9221.878.34
    Source PreferenceWikipedia, High-DA PublishersNiche Experts, Recent DataOfficial Brand Sites, Knowledge Entities
    Optimization FocusDepth, Multi-turn ContextFreshness, Claim-Source LinksE-E-A-T, Schema, Brand Profiles

    That divergence is exactly why ai visibility tracking across all three platforms matters. A brand might perform well on ChatGPT and be completely invisible on Perplexity because its content is six months stale.

    5 Signals That Get a Brand Into AI Answers

    Transitioning from traditional SEO to GEO means focusing on five signals that compel an AI engine to trust, retrieve, and cite a brand.

    Signal 1: External Validation Through Earned Media

    AI engines show a systematic bias toward third-party sources over brand-owned content. A brand mentioned consistently on Reddit, industry news sites, and review platforms like G2 is roughly 2.8x more likely to be cited than a brand that only publishes on its own domain. For LLMs, trust is built through consensus across diverse source types, not through self-promotion.

    What to do: Audit your third-party descriptions on review sites, directories, and forums. AI reflects these sources more than your website’s marketing copy.

    Signal 2: Structured, Extractable Content Architecture

    The physical layout of your content determines its “extractability.” AI systems prefer what researchers call “Answer Capsules,” modular 40 to 60 word paragraphs that directly answer a query at the beginning of a section. Content using consistent heading hierarchies and structured data (FAQ, Article, Product schema) sees a 44% to 67% increase in citation likelihood.

    What to do: Restructure H2 headers to match common user queries and follow immediately with a direct, answer-first paragraph.

    Signal 3: Entity-Category Binding

    AI visibility is, at its core, a classification problem. The model needs to confidently bind your brand name to its industry category. If your messaging says “we provide innovative solutions” instead of “we build project management software for remote teams,” the AI lacks the structured confidence to recommend you for a specific need.

    What to do: Use consistent naming and clear service descriptors across all digital platforms to reinforce the co-occurrence of your brand with industry-specific terminology.

    Signal 4: Sentiment Consistency Across Sources

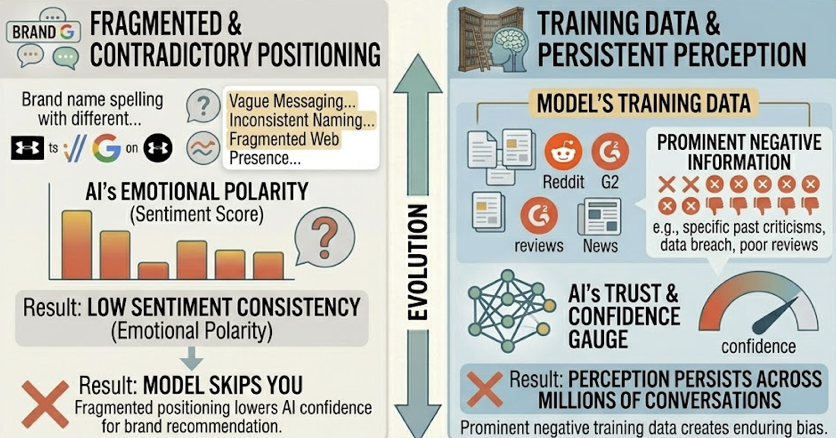
    AI models evaluate what’s called “Sentiment Consistency,” the emotional polarity of how a brand is discussed across reviews, social media, and news. If negative information was prominent in the model’s training data, that perception can persist across millions of conversations. Fragmented or contradictory positioning lowers the model’s confidence in recommending the brand.

    What to do: Monitor “Semantic Drift” monthly. If AI characterizations of your brand diverge from your actual positioning, you need to fix the inputs (third-party sources) rather than trying to correct the output directly.

    Signal 5: Information Freshness and Recency

    For RAG-driven search, recency is a primary retrieval trigger. Perplexity gives a massive boost to content published within the last 30 days. Adding visible “Last Updated” dates and current statistics can lift citation rates by 47%.

    What to do: Implement a quarterly update cycle for your highest-value pages. Freshness isn’t optional anymore.

    SignalMechanismMeasured Impact
    Earned MediaConsensus across multiple platforms6.5x more weight than brand-owned content
    StructureAnswer Capsules and FAQ Schema67% improvement in AI coverage
    Entity BindingSchema and category co-occurrenceHigher likelihood of appearing in shortlists
    SentimentPolarity scores across the webInfluences how favorably the AI recommends you
    FreshnessdateModified and datePublished schema82% citation rate for content under 30 days old

    Why Most Brands Can’t See Whether AI Is Citing Them

    Here’s the thing: even if you’ve optimized for all five signals, you still can’t measure the results using traditional analytics.

    Google Analytics 4 is built to track browser sessions and cookie-based interactions. Generative engines bypass both. AI bots don’t execute JavaScript, which makes them invisible to standard tracking pixels. Over 70% of AI referrals arrive without referrer headers because users copy-paste URLs from AI chats rather than clicking them.

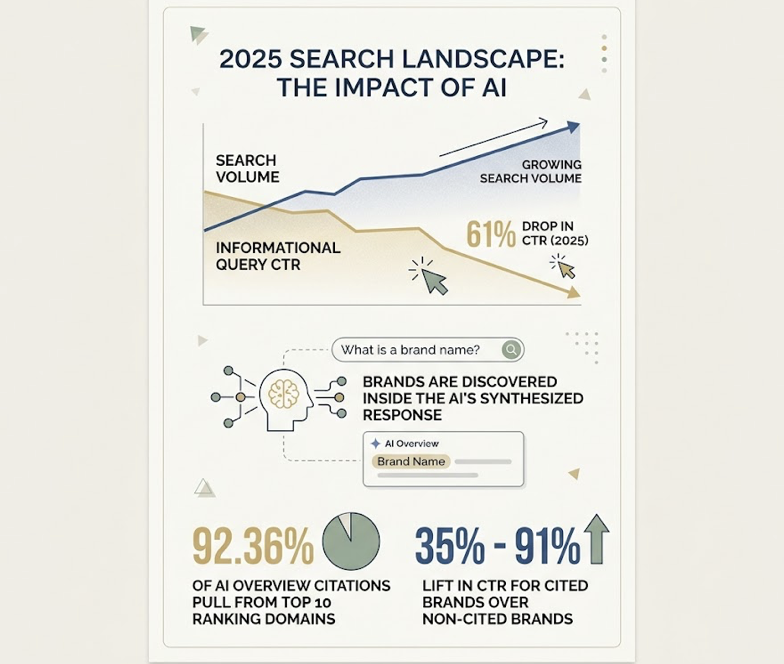
    The result is a “dark funnel.” Google’s AI Overviews now appear in over 13% of queries, yet they’ve caused organic click-through rates to drop by 61%. Prospects research your brand in a ChatGPT answer, form purchase intent, and later search your brand name directly. GA4 misattributes this to “Direct” or “Branded Search.”

    That’s the Influence-Attribution Gap. Traditional models measure visits. In the AI era, the real metric is influence. A brand can be the top recommendation in a ChatGPT answer, receive zero clicks, and still drive significant downstream revenue.

    To close that gap, you need ai visibility tracking: a shift from session-based metrics to Citation Rate (how often the brand is cited) and Share of Model (visibility relative to competitors).

    How AI Visibility Tracking Closes the Gap

    AI visibility tracking is the continuous monitoring of how a brand appears, ranks, and is described across generative platforms. It provides a standardized view based on core metrics: visibility frequency, recommendation position, sentiment score, query volume and intent, and citation source mapping.

    Topify tracks these seven metrics across ChatGPT, Gemini, Perplexity, DeepSeek, Doubao, Qwen, and other major AI platforms. That coverage matters because a brand’s visibility profile differs significantly across platforms. Knowing you rank well in ChatGPT tells you nothing about whether Gemini is recommending a competitor for the same query.

    Here’s a practical scenario. A marketing team uses Topify to track 200 high-intent prompts. They discover a significant “Citation Gap”: a competitor is cited in 70% of responses while they appear in only 15%. Using Source Analysis, the team reverse-engineers those citations and finds that the competitor’s visibility is being driven by a series of Reddit threads and niche industry reviews. That tells the team exactly which third-party domains to target for their earned media strategy. Instead of guessing, they’re closing the gap with data.

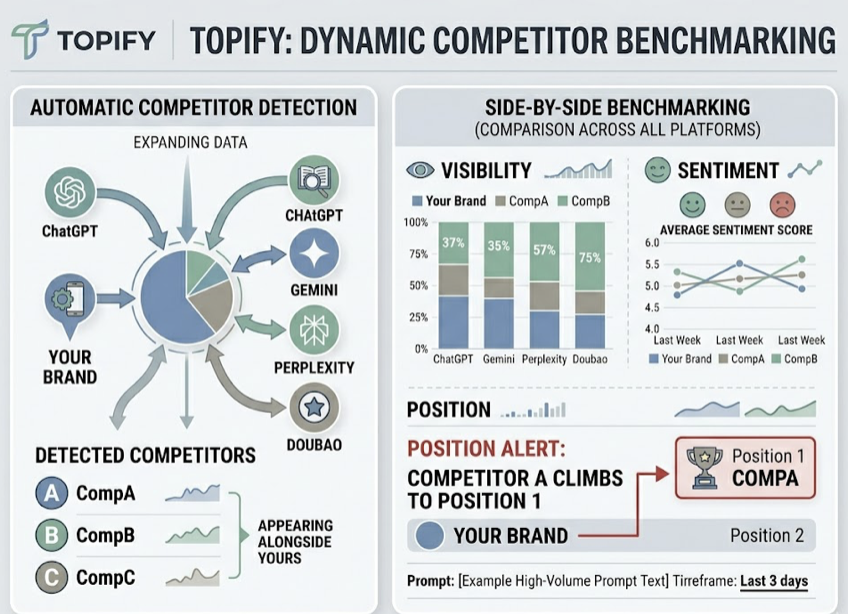
    The Competitor Monitoring feature handles benchmarking systematically, automatically detecting which competitors appear alongside your brand and tracking how that shifts over time. And Sentiment Analysis scores how the AI characterizes your brand on a 0-100 scale, so you can see not just whether you’re mentioned, but whether the AI is positioning you as a recommendation or a cautionary example.

    Topify’s Basic plan starts at $99/mo, covering 100 prompts and 9,000 AI answer analyses, which makes professional-grade ai visibility tracking accessible for mid-sized teams.

    Three Steps to Start Tracking Your Brand’s AI Visibility

    Step 1: Discover Your High-Value Prompts

    Unlike traditional SEO keywords (averaging 4 words), AI queries are conversational prompts averaging 23 words, filled with specific qualifiers like budget, use-case, and company size. The first step is identifying 50 to 200 high-intent prompts your target audience actually asks AI platforms. Topify’s High-Value Prompt Discovery surfaces the exact conversational clusters that have volume and currently trigger recommendations in your category.

    Step 2: Establish Your Baseline

    Before automating, run “Manual Spot-Checks.” Ask 10 to 20 variations of a buyer-intent question across ChatGPT, Perplexity, and Gemini. Record whether your brand appears, its position, and whether the description is accurate. Look for Semantic Drift: if the AI’s characterization of your brand diverges from your positioning, that’s a distortion you need to fix through updated content inputs.

    Step 3: Move to Continuous Automated Monitoring

    AI models update frequently and their retrieval caches are dynamic. Visibility isn’t a static rank. Transition from manual checks to Topify’s automated dashboard, which tracks the 7 core metrics in real time. This lets teams respond immediately if a competitor gains a citation advantage or if an AI begins to hallucinate incorrect pricing or features.

    Conclusion

    AI engines aren’t random recommendation machines. They’re retrieval systems that favor entities with high structural clarity, cross-platform validation, and content freshness. The brands that get cited are the ones that have optimized for these signals, not just for Google’s blue links.

    The first step to optimization is sight. You can’t optimize what you can’t measure. AI visibility tracking is the only way to expose the Citation Gaps and Entity Inconsistencies that lead to brand invisibility. Start by understanding which prompts matter, where you stand today, and what your competitors are doing differently.

    The gap between “ranking on Google” and “being recommended by AI” is only growing. The brands that close it first will own the consideration set where modern buyers actually make decisions.

    FAQ

    What is ai visibility tracking?

    It’s the systematic process of monitoring how often, where, and with what sentiment a brand is mentioned and cited across generative engines like ChatGPT, Perplexity, and Gemini. It shifts measurement from clicks and sessions to citation rate and share of voice in AI answers.

    How often do AI search engines update their brand recommendations?

    Recommendations can shift in real time as the retrieval layer indexes new web content. Perplexity is especially sensitive to content published within the last 30 days. Other platforms update less frequently but still reflect changes in third-party source coverage.

    Can I improve my chances of being cited by ChatGPT?

    Yes. Use Answer Capsules (40 to 60 word modular answers), ensure your site uses server-side rendering (AI bots struggle with JavaScript), and secure mentions on high-authority third-party platforms like Reddit, G2, and industry publications.

    What’s the difference between SEO and GEO?

    SEO optimizes for a ranked list of links to drive website traffic. GEO optimizes for inclusion and citation within a synthesized, conversational answer to drive brand influence and purchase intent.

    Read More

  • How to Measure Share of Voice in AI Search

    How to Measure Share of Voice in AI Search

    Your SEO dashboard says keyword rankings are at an all-time high. But the sales pipeline tells a different story: qualified leads are decelerating, and a growing chunk of direct traffic can’t be traced back to any campaign. The disconnect isn’t a reporting bug. It’s a measurement gap.

    In early 2026, 73% of B2B buyers use conversational AI assistants during vendor research and shortlisting. Meanwhile, zero-click searches have climbed past 65% overall, with informational queries hitting a 74% zero-click threshold. The buyers are still searching. They’re just getting their answers, comparisons, and recommendations inside ChatGPT, Perplexity, and Gemini before they ever reach your site.

    Traditional Share of Voice metrics, built on ad impression shares, organic rankings, and media mentions, can’t see any of this. What follows is a framework for measuring the metric that can.

    Why Traditional Share of Voice Fails in AI Search

    Traditional SOV models assume a multi-link environment. Ten or more organic results compete for clicks on a standard search page, and a brand ranking fifth still captures a predictable share of attention. Generative search collapses that model into a single, synthesized narrative. The AI typically mentions three to five brands, and frequently delivers just one primary recommendation.

    That makes AI search visibility binary. You’re either woven into the response, or you’re absent.

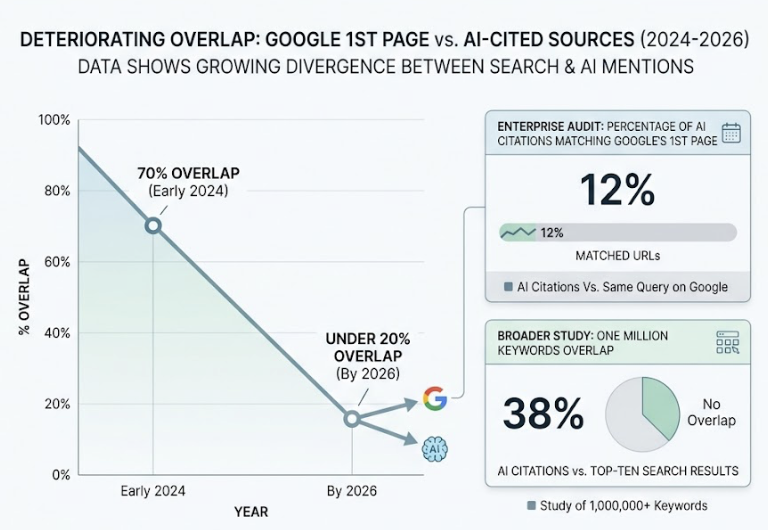
    The overlap between Google’s first page and AI-cited sources has deteriorated fast. By 2026, that correlation has dropped from roughly 70% in early 2024 to under 20%. A separate enterprise audit found that only 12% of AI citations matched URLs ranking on Google’s first page for the same query. A broader study of one million keywords showed just 38% overlap between AI citations and top-ten search results.

    The reason is architectural. Google ranks pages using domain authority and backlink velocity. Generative engines run Retrieval-Augmented Generation (RAG), decomposing queries into semantic vectors and extracting self-contained, high-density factual passages. The content that earns a top Google ranking and the content that earns an AI citation are selected by fundamentally different systems.

    Here’s the thing: because an AI response doesn’t expand to accommodate lower-tier results, every gain in a competitor’s visibility is a direct, zero-sum loss for everyone else. And with a projected 25% drop in traditional search volume by late 2026, the stakes are accelerating.

    What AI Search Visibility Actually Measures

    AI search visibility quantifies how frequently, accurately, and favorably large language models cite, mention, or recommend a brand when synthesizing answers to natural language prompts. It’s not a replacement for traditional search metrics. It’s a distinct, downstream layer.

    Legacy SEO acts as the initial filter, placing content within the indexable web pool. Generative engine optimization (GEO) then determines whether the model selects, extracts, and trusts that content during real-time synthesis. The two work in sequence, not in competition.

    The mechanism driving this selection is entity grounding. Generative engines don’t evaluate websites as isolated URL collections. They interpret the digital ecosystem as a web of interconnected entities: brands, products, individuals, and concepts. The model evaluates its “Entity Confidence,” the statistical certainty that a specific brand is the correct solution to recommend, by analyzing how consistently that brand is represented across independent surfaces. If your positioning is identical on your corporate blog, LinkedIn, third-party review directories, and industry forums, the model’s confidence increases.

    If it detects structural inconsistencies, your brand gets bypassed in favor of competitors with more corroborated footprints.

    This shift from link-based authority to entity-based consensus explains what analysts call the “Page 2 Anomaly.” In approximately 40% of analyzed conversational answers, platforms like ChatGPT bypass top-ten Google results to cite sources from pages two or three. The model prioritizes “information gain,” original research, proprietary statistics, or tightly structured comparison data, over raw backlink authority.

    The Five Metrics That Define AI Share of Voice

    Measuring brand representation inside probabilistic models requires a framework that distinguishes between simple presence and competitive ownership. Many legacy tools conflate presence rate (how often your brand appears) with actual Share of Voice. A presence rate ignores the other brands in those same responses.

    Open-Denominator vs. Closed-Denominator SOV

    A closed-denominator metric restricts the competitive pool to a preselected list of rivals. The problem: it’s gameable. Remove a dominant competitor from your tracking list and your reported SOV inflates instantly, even if the model’s real-world recommendations haven’t changed.

    The industry standard relies on an open-denominator framework. Here, the competitive pool is defined entirely by the model’s actual outputs. Every brand the AI names across all responses goes into the denominator. The formula:

    Open AI SOV = (Target Brand Mentions / Total Brand Mentions Across All Responses) x 100

    This must be calculated across multiple runs of a standardized prompt set. Single-prompt evaluations are too volatile to be useful.

    The Five Core Metrics

    The open-denominator SOV is evaluated alongside four secondary dimensions:

    Mention Rate. The percentage of priority prompts where your brand appears. If you’re named in 400 out of 1,000 tracked category prompts, your baseline mention rate is 40%. This is the initial gauge of whether the AI associates your brand with the category at all.

    Response Position Index. Conversational systems display a pronounced bias toward the first-named entity. Being placed as the primary recommendation is structurally distinct from an “also consider” mention at the end. The Position Index weighs mentions by placement order, assigning higher value to leading recommendations.

    Sentiment Score. A mention isn’t inherently valuable if it’s qualified negatively. If a model notes that your software is popular but “legacy, expensive, and difficult to integrate,” you’ve achieved high visibility with toxic sentiment. Advanced measurement uses NLP to score mentions on a polarity scale, turning sentiment into a multiplier that adjusts your absolute SOV score.

    Source Citation Coverage. This tracks the diversity of external domains the AI cites to validate its mention of your brand. If the model only cites your own website, that authority is shallow and prone to disruption. High-performing brands maintain citation coverage across industry publications, user forums like Reddit, and review directories like G2 and Capterra.

    Competitor Gap Analysis. This compares your performance across the previous four dimensions directly against your closest rivals. It reveals the “white space” in the AI’s consideration set: specific prompts where competitors are absent, giving you an opening to capture category real estate.

    How to Map These Metrics to a Tracking Dashboard

    Specialized platforms consolidate these five dimensions into unified diagnostic matrices. Topify, for example, maps them across a seven-metric system that adds two layers most frameworks miss.

    Abstract SOV MetricTopify IndicatorWhat It Measures
    Mention RateVisibility ScorePercentage of unbranded queries where the brand is named
    Response PositionPosition TrackingFirst-tier vs. trailing mention placement
    Sentiment ScoreSentiment (RankScale)NLP-driven rating from -100 to +100
    Source CoverageSource AnalysisDiversity of external domains cited to validate the brand
    Competitor GapShare of ModelCitation density compared against competitors on identical prompts
    Search DemandAI Volume AnalyticsEstimated search demand inside generative engines specifically
    Bottom-Line ImpactCVR (Conversion Visibility Rate)Revenue attribution from AI citations via GA4/Shopify integration

    The last two rows matter more than most teams realize. AI Volume Analytics reveals high-intent queries that traditional SEO tools miss entirely, because the queries are phrased as natural language sentences averaging 23 words in length and containing constraints around budget, company size, and integration requirements. CVR closes the attribution loop: it connects the upstream AI mention to a downstream conversion event.

    How to Track AI Share of Voice Across Platforms

    A major challenge is platform fragmentation. Brand representation varies dramatically across engines due to unique training datasets, indexing speeds, and citation architectures.

    ChatGPT dominates general discovery, processing over 2 billion queries daily across 800 million weekly active users. It embeds external links in roughly 31% of its responses, making citation tracking essential but incomplete.

    Perplexity serves research-intensive audiences with over 45 million monthly active users. It cites external sources in more than 77% of outputs, making it the primary driver of immediate referral traffic.

    Google Gemini and AI Overviews appear in approximately 18% of US desktop searches, with Gemini surpassing 750 million monthly active users and AI Overviews reaching over 2 billion users globally.

    Claude holds the highest average session value of $4.56 among conversational assistants, indicating a highly qualified audience of senior decision-makers.

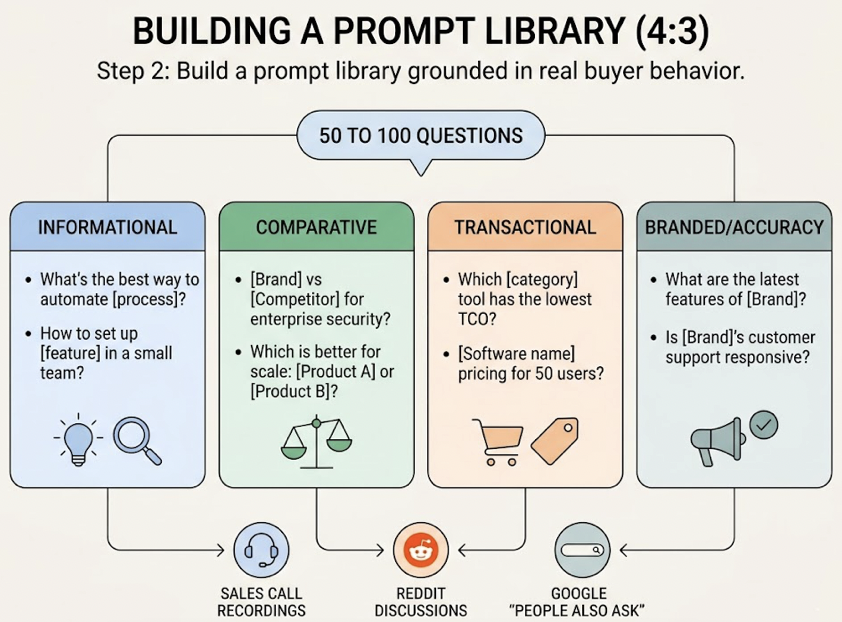
    Because these systems are probabilistic, manual tracking is functionally impossible at scale. A single prompt yields slightly different answers across different users, locations, and timeframes. Platforms like Topify automate this by executing browser-rendered simulations across multiple engines, capturing what real users see rather than sanitized API outputs. The workflow follows four steps: construct a prompt playbook from sales call data and community forums, measure a multi-model baseline across 7+ engines with 3-5 regenerations per prompt, diagnose citational gaps, then surgically optimize and re-evaluate.

    For teams tracking 100+ prompts across multiple platforms, this loop needs to run continuously. Topify’s Basic plancovers 100 prompts with roughly 9,000 AI answer analyses per month. The Pro plan expands to 250 prompts and 22,500 analyses for teams managing multiple brands or competitive categories.

    From Data to Action: Turning AI SOV Into Strategy

    Once you’ve mapped your Share of Voice, the remediation playbook differs fundamentally from traditional SEO. Three scenarios cover most situations.

    When Your Mention Rate Is Below 10%

    If you have strong Google rankings but remain invisible across AI engines, the issue is typically structural. JavaScript-heavy sites that rely on client-side rendering suffer a 60% reduction in AI citations because AI bots prioritize the initial server-side HTML return. Security configurations like Cloudflare may accidentally block crawlers like GPTBot.

    Once technical access is secured, content needs restructuring using the Bottom Line Up Front (BLUF) rule. Research shows that 44.2% of all AI citations are extracted from the first 30% of an article. Place direct, sentence-level answers within the first 100 words of every major heading section.

    Landmark research from Princeton University quantified the content transformations that drive AI citability: expert quotations lift visibility by 41%, factual statistics by 30%, inline citations by 30%, and technical terminology by 28%. Keyword stuffing, on the other hand, reduces visibility by 9%.

    When Your Position Is Low and Sources Are Thin

    If you’re mentioned but routinely buried at the bottom of recommendation lists, the model lacks sufficient third-party corroboration. The fix lives off your owned website.

    Average AI citation distributions trace to established sources: industry publications and news (34%), YouTube video transcripts (23.3%), Wikipedia (18.4%), and Google ecosystem domains (16.4%). User forums like Reddit and Quora carry heavy weight with models like ChatGPT. Maintaining an active, highly reviewed profile on directories like G2 or Capterra increases a brand’s probability of being cited in ChatGPT by 3x.

    When Sentiment Is Negative or Drifting

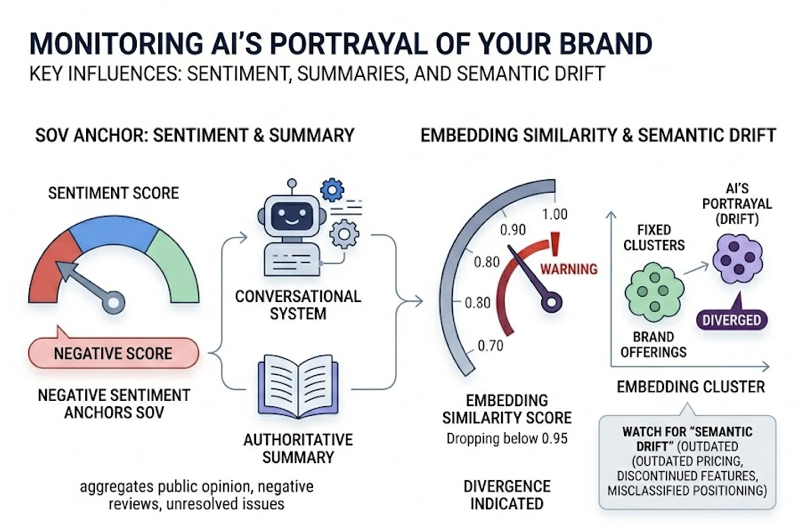
    A negative sentiment score anchors your SOV. Conversational systems synthesize public opinion, aggregating negative reviews and unresolved issues into authoritative summaries. Brands must also watch for “Semantic Drift,” where the AI’s internal representation diverges from reality: outdated pricing, discontinued features, or misclassified positioning. A drop in embedding similarity below 0.95 indicates the AI’s portrayal has diverged from your actual offerings.

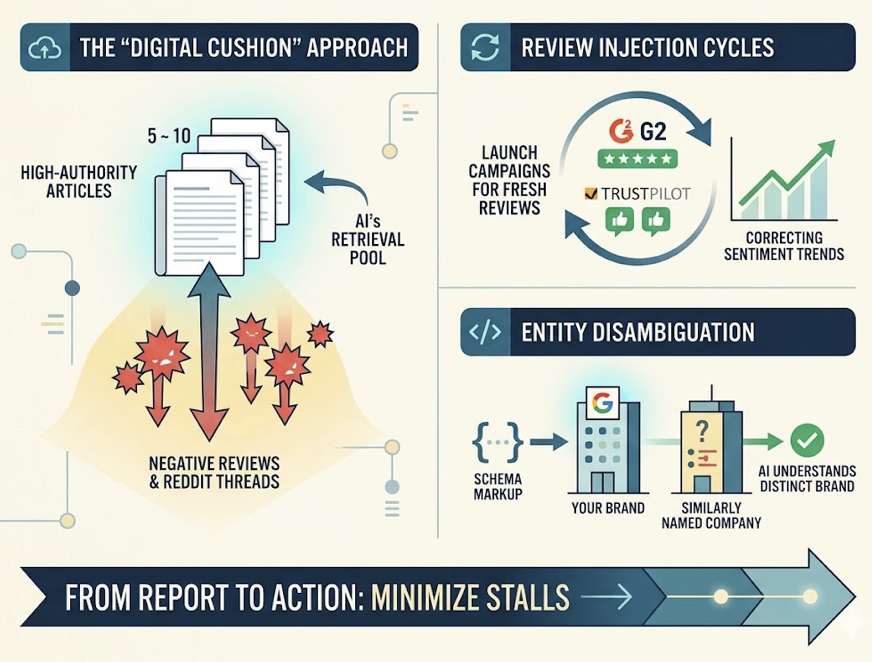
    The fix: audit the citations behind the negative summaries, refresh old product pages (content updated within the last 90 days increases selection likelihood by 2.3x), and launch targeted review generation on the cited platforms to dilute negative semantic signals.

    By deploying automated suites like Topify, teams can run this optimization loop continuously: monitoring mentions, diagnosing citational gaps, and using one-click execution to restructure pages before competitor-driven divergence erodes market share.

    Conclusion

    Traditional metrics like keyword rankings and organic impressions no longer capture the true path to revenue. Conversational search operates on a zero-sum, binary model: your brand is either integrated directly into the synthesized output as a trusted recommendation, or it’s invisible.

    Measuring AI Share of Voice isn’t a peripheral experiment. It’s a board-level indicator of future market share. By establishing an open-denominator measurement framework, tracking the five core metrics across multiple AI platforms, and connecting upstream visibility to downstream conversions, marketing teams can replace guesswork with precision. The brands that build this measurement layer now will be the ones AI systems recommend six months from now.

    FAQ

    Q: What is share of voice in AI search?

    A: Share of Voice in AI search represents the percentage of brand mentions and recommendations a company receives compared to all competitors across synthesized AI responses. Unlike traditional search metrics that track ad spend or link-based rankings, AI SOV measures how often a brand is included when conversational assistants like ChatGPT, Perplexity, and Gemini recommend solutions within a given category.

    Q: How is AI search visibility different from traditional SEO?

    A: Traditional SEO focuses on optimizing URLs to rank on search engine results pages through link building and keyword optimization. AI search visibility focuses on being cited, referenced, and recommended directly within AI-generated answers. While traditional SEO relies on domain-level backlink profiles, AI visibility is driven by semantic clarity, structural extractability (clean tables, data lists), factual corroboration across third-party sites, and overall entity authority.

    Q: Which AI platforms should I track for share of voice?

    A: A reliable strategy should cover at least three to four platforms: ChatGPT for general search behavior, Gemini for performance within Google’s ecosystem and AI Overviews, Perplexity for technical and research-oriented queries, and Microsoft Copilot for enterprise audiences. For global brands, adding engines like DeepSeek, Doubao, or Qwen provides critical visibility in non-English markets.

    Q: How often should I measure AI share of voice?

    A: Because LLMs update frequently and competitors continuously push fresh content, monthly or bi-weekly tracking is the baseline standard. Enterprises should use automated tracking systems for continuous monitoring, since citation drift rates of 40-60% per month mean manual audits are always looking at stale data.

    Read More

  • The GEO Playbook: How to Optimize Content for LLM Citations

    The GEO Playbook: How to Optimize Content for LLM Citations

    Your domain authority is 70. Your keyword rankings are solid. But when someone asks Perplexity for a recommendation in your category, the AI cites your competitor’s blog post instead of yours.

    That’s not a ranking problem. It’s a citation problem.

    Traditional SEO optimizes for link-based lists. Generative Engine Optimization (GEO) optimizes for something fundamentally different: whether AI models extract, trust, and cite your content when they synthesize answers. The two disciplines share surface-level similarities, but their underlying mechanics diverge in ways that catch most SEO teams off guard.

    Research from Princeton University, Georgia Tech, and the Allen Institute for AI (published at ACM KDD 2024) found that pages ranked fifth on Google saw their AI search visibility increase by up to 115.1% after applying GEO-specific content strategies. Meanwhile, first-place pages without those strategies often didn’t appear in AI answers at all.

    The takeaway isn’t that SEO is dead. It’s that ranking and being cited are now two separate outcomes, and they require two separate optimization approaches.

    Why High-Ranking Pages Go Missing in AI Answers

    The disconnect comes down to how generative engines process information versus how traditional search engines rank it.

    Google ranks pages. AI models extract passages.

    When a user submits a query to ChatGPT or Perplexity, the system doesn’t return a list of links sorted by authority. It runs a Retrieval-Augmented Generation (RAG) pipeline that pulls specific text chunks from indexed content, evaluates their factual density and structural clarity, and synthesizes them into a single coherent answer.

    That means your page’s overall authority score matters less than whether individual paragraphs contain extractable, verifiable claims. A well-structured blog post on a DA-30 site can outperform a DA-80 corporate page if its content is easier for the model to parse and cite.

    Here’s a side-by-side breakdown of where the two systems diverge:

    DimensionTraditional SEOGEO
    Core goalHigher SERP position for clicksCited and recommended in AI answers
    Visibility modelHierarchical (top 3 capture most traffic)Distributed (mid-tier sites can earn citations)
    Key signalsBacklinks, domain authority, keyword matchFact density, structured data, entity consistency
    User interactionClick-through to websiteZero-click consumption or citation-based verification
    Success metricsCTR, impressions, rank positionMention rate, citation frequency, sentiment, source weight

    With traditional search volume projected to decline 25% by 2026, the brands that don’t adapt their content for AI extraction will lose visibility in the channel that’s growing fastest.

    What LLMs Actually Look for When Citing Content

    AI models aren’t browsing your page the way a human reader does. They’re scanning for evidence.

    Specifically, LLMs prioritize three qualities when selecting which passages to cite: fact density, entity authority, and linguistic clarity.

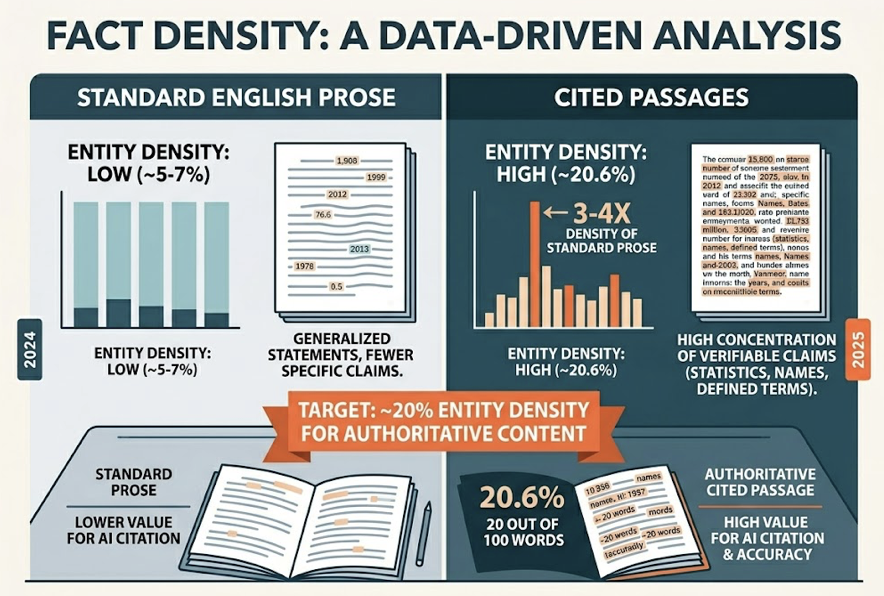
    Fact density is the ratio of verifiable claims (statistics, named entities, research conclusions) to total word count. Cited passages average an entity density of 20.6%, roughly three to four times the density of standard English prose. In practical terms, that means a 100-word paragraph needs to contain around 20 words that are specific names, numbers, dates, or defined terms.

    Entity authority refers to how consistently your brand, product names, and key claims appear across multiple sources on the web. AI models cross-reference your content with third-party mentions. Inconsistent descriptions across platforms create what researchers call a “Trust Gap” that reduces citation probability.

    Linguistic clarity matters more than you’d expect. Content written at a Flesch-Kincaid readability grade of 8 to 10 (roughly high school level) gets cited 20% more often than dense academic prose. AI models function as high-speed summarizers. If your sentence structure is complex or loaded with hedging language, the model moves to a cleaner source.

    The research quantifies how specific content improvements affect citation rates:

    OptimizationCitation liftWhy it works
    Adding authoritative citations+30% to +40%Strengthens the evidence chain
    Integrating statistics+37% to +40%Provides discrete, extractable fact points
    Embedding expert quotes+30%Adds third-party verification signals
    Improving readability+15% to +30%Reduces the model’s parsing cost
    Using declarative tone+10% to +20%Lowers uncertainty perception

    The pattern is clear: the more your content reads like a well-sourced briefing document, the more likely it is to be cited.

    5 Content Structures That Earn AI Search Visibility

    Content format directly determines extractability. Not all structures are equal in the eyes of a RAG pipeline. These five formats consistently outperform in citation frequency across ChatGPT, Perplexity, and Google AI Overviews.

    1. Definition-First Format

    AI models follow what researchers call a “ski slope” retrieval pattern: roughly 44.2% of citations come from the first 30% of a page’s content.

    That means the opening sentences under each H2 or H3 carry disproportionate weight. Place a 40-to-60-word direct definition or core claim immediately after each heading. Skip the background buildup. If the AI can extract your answer from the first paragraph under a heading, your chances of being cited multiply.

    2. Numbered Step-by-Step Guides

    For process-oriented queries (“how to set up,” “steps to implement”), ordered lists are the default extraction target. Each step should be a semantically complete chunk, meaning it makes sense on its own without needing context from surrounding steps.

    Use H2 or H3 tags for each step. AI models treat heading-tagged steps as standalone units they can pull into an answer individually.

    3. Comparison Tables with Clear Dimensions

    Narrative comparisons are hard for AI to parse. Tables are easy.

    One SaaS brand converted its narrative product comparison into a structured HTML table with explicit dimensions (pricing, features, target audience) and saw a 35% CTR lift within a week, plus inclusion in Google AI Overview snapshots. If you’re targeting any “X vs Y” or “best tools for Z” query, tables aren’t optional.

    4. FAQ Sections with Direct Answers

    LLMs handle complex queries by breaking them into sub-questions, a process called “query fan-out.” FAQ sections map directly to this behavior. Each question becomes a potential sub-query match, and each answer becomes a candidate citation.

    Pair your FAQ content with FAQPage Schema markup. It won’t guarantee citation, but it improves machine readability, which is the prerequisite.

    5. Data-Backed Claims with Source Attribution

    Every factual claim should follow a simple formula: claim + statistic + (source, year).

    Princeton’s research found that adding statistics alone can boost AI visibility by up to 40%. Perplexity, which operates as a real-time research engine, particularly favors passages with high fact density and clear source attribution. If your content makes a claim without a number or a source, it’s at a structural disadvantage.

    How to Reverse-Engineer What AI Platforms Already Cite

    GEO isn’t just about optimizing your own site. It’s about understanding the full ecosystem of sources that AI models trust in your category.

    Here’s the uncomfortable data point: between 82% and 85% of AI citations come from third-party sources like Reddit, G2, LinkedIn, Wikipedia, and industry publications. Your own website accounts for a small fraction of the citation landscape. That means “off-site authority” isn’t a nice-to-have. It’s the primary driver of AI visibility.

    The Manual Approach

    Start by building a “Money Prompt Set”: 20 to 30 long-tail questions that reflect real buyer intent in your category. Think “best [product type] for [specific use case]” or “[Brand A] vs [Brand B] for [industry].”

    Run each prompt across ChatGPT, Perplexity, and Gemini. Record which brands get mentioned, which sources get cited, and where your brand is absent. Keep in mind that citation overlap between models is only about 11%, which means each platform has its own trust graph. Testing on just one engine gives you an incomplete picture.

    The Systematic Approach

    Manual testing hits a wall quickly. LLM outputs are non-deterministic, meaning the same prompt can produce different citations on different runs. A single test gives you a snapshot, not a pattern.

    Topify‘s Source Analysis automates this at scale. It runs thousands of prompt variations across multiple AI platforms, maps the citation sources for each response, and identifies exactly which third-party domains your competitors are being cited from. That data tells you where to focus your earned media and content distribution efforts: the specific Reddit threads, review platforms, and industry publications where AI models are sourcing their recommendations.

    CapabilityTraditional SEO tools (e.g., Ahrefs)Topify GEO platform
    MonitorsKeyword rankings, backlink countsAI mention rate, citation position, brand sentiment
    Data sourceSearch index, clickstreamReal-time model outputs, RAG retrieval sources
    Analysis depthDomain-level, page-levelSentence-level fact attribution, semantic drift detection
    Optimization outputKeyword targeting, link buildingParagraph restructuring, Schema injection, third-party footprint expansion

    The GEO Content Audit Checklist

    Not every optimization carries equal weight. Here’s a priority framework based on ROI and implementation difficulty.

    Tier 1: Technical AI-Readiness (High ROI, Low Effort)

    Check your robots.txt. Make sure you haven’t blocked GPTBot, ClaudeBot, or PerplexityBot. CDN providers like Cloudflare sometimes block AI crawlers by default.

    Implement server-side rendering (SSR). AI crawlers typically can’t execute complex client-side JavaScript. If your content loads via JS, it’s invisible to AI.

    Create an llms.txt file. This machine-readable file in your root directory tells AI crawlers about your site’s structure and preferred citation format.

    Tier 2: Content Citation-Readiness (Medium ROI, Medium Effort)

    Optimize your first-paragraph summaries. The opening two to three sentences after each H1 should directly answer the topic. No throat-clearing.

    Insert evidence blocks. Every H2 section needs at least one statistic or expert quote. Without them, your content is assertion-heavy and evidence-light.

    Break long paragraphs into 50-to-150-word sections with clear headings. Add comparison tables where relevant.

    Tier 3: Entity Authority (High ROI, High Effort)

    Deploy comprehensive Schema markup: Organization, Person, and Product schemas with sameAs links to Wikipedia, LinkedIn, and other verification nodes.

    Build your external footprint. Contribute genuinely to Reddit discussions, Quora threads, and industry forums in your category. AI models assign significant weight to these “human consensus” signals.

    Audit dimensionExample checkWeight (1-10)ROI expectation
    Technical foundationAI crawler access, SSR10Baseline requirement
    Structure optimizationDefinition-first blocks, lists, tables9Significant extraction rate lift
    Evidence integrationAuthoritative citations, statistics, dates8Increased citation weight
    Semantic markupJSON-LD Schema depth7Improved entity recognition
    Off-site trustThird-party media mentions, reviews9Long-term citation moat

    Tracking Your AI Search Visibility After Optimization

    You’ve restructured your content. You’ve added Schema. You’ve planted evidence blocks in every section. Now what?

    Traditional analytics won’t tell you if it worked. AI search is largely zero-click, which means improvements in citation frequency don’t show up in Google Analytics as traffic increases. You need a different measurement system entirely.

    The Metrics That Matter

    AI Mention Rate: the percentage of relevant prompts where your brand appears in the AI’s response. The average brand sits at roughly 0.3%. Top-performing brands reach 12%.

    Citation Share: the proportion of all cited links in AI answers that point to your domain. This is your market share in the AI citation economy.

    Recommendation Position: when AI lists multiple brands, where do you rank? First position carries significantly more trust than third or fourth.

    Sentiment Score: how does the AI describe your brand? Positive, neutral, or subtly negative? “Semantic drift,” where AI’s characterization diverges from your actual positioning, is a real and measurable risk.

    Building a Continuous Monitoring Loop

    Single-point testing doesn’t work because LLM outputs are probabilistic. The same prompt can return different results on consecutive runs. Topify‘s Visibility Tracking solves this by running each prompt set 10 to 20 times across ChatGPT, Perplexity, Gemini, and AI Overviews, producing statistically stable visibility scores rather than anecdotal snapshots.

    The platform also functions as a competitive early-warning system. When a competitor earns a new citation in a high-value “best of” query, the system flags it and identifies what content change drove the shift. That’s the difference between discovering you’ve lost visibility three months later and responding within days.

    Conclusion

    Optimizing for LLM citations is a separate discipline from traditional SEO. It requires different content structures, different success metrics, and a different understanding of what “authority” means in an AI-driven search environment.

    The core loop is straightforward: audit your existing content for AI-readiness, identify which prompts matter to your buyers, reverse-engineer the citation sources AI already trusts, restructure your content for extraction, and track whether it’s working with AI-specific metrics.

    The brands that build this practice now are earning a structural advantage. AI models develop citation patterns over time, and early, frequently cited sources tend to maintain their position as the default recommendation. Waiting until AI search becomes the dominant discovery channel means competing against entrenched incumbents who started earlier.

    Start with your highest-converting pages. Run the audit. Measure your baseline. Then optimize from there.

    FAQ

    What is GEO, and how is it different from SEO?

    SEO focuses on ranking pages in search engine result lists to earn clicks. GEO focuses on getting your content cited and recommended inside AI-generated answers. SEO optimizes for page-level authority signals like backlinks. GEO optimizes for passage-level extractability: fact density, structured data, and entity consistency.

    How long does it take for optimized content to appear in AI answers?

    For AI engines with real-time browsing (Perplexity, ChatGPT Search, Google AI Overviews), optimized content can appear within 12 to 24 hours. For static model versions that rely on training data, updates may take months until the next model refresh.

    Should I optimize existing content or create new pages?

    Start with existing pages that already rank in Google’s top 20. They have retrieval baseline that GEO optimization can amplify. For high-intent long-tail questions that your site doesn’t cover yet, create new “GEO-native” pages designed specifically for AI extraction. Refreshing high-authority existing content typically delivers faster ROI than building from scratch.

    Which AI platforms should I prioritize?

    ChatGPT handles the largest share of AI search traffic and is the default starting point. Perplexity, despite smaller overall volume, has exceptionally high citation density and is particularly valuable for B2B and research-oriented brands. Google AI Overviews connects most directly to traditional SEO signals. The most effective approach is cross-platform optimization, because the strategies that improve Perplexity citations (data density, clear sourcing) tend to work across all platforms.

    Read More

  • How to Track Brand Mentions in ChatGPT, Perplexity, and Gemini

    How to Track Brand Mentions in ChatGPT, Perplexity, and Gemini

    Your team ran 200 prompts across ChatGPT, Gemini, and Perplexity last quarter. Not hypothetical prompts. Real questions your customers type every day: “best project management tool for remote teams,” “most reliable CRM for mid-market SaaS,” “top analytics platform with real-time dashboards.” You checked manually. Some days your brand showed up. Some days it didn’t. The results changed between Tuesday morning and Wednesday afternoon, even with the exact same wording.

    That inconsistency isn’t a bug in the AI. It’s the nature of how large language models generate responses. And it means the old approach of spot-checking your brand name in ChatGPT once a month tells you almost nothing about your actual AI search visibility.

    Why Manual Spot-Checks Fail at Measuring AI Search Visibility

    Traditional search visibility relied on a stable, periodically updated index. You could check your Google ranking, see the same result an hour later, and trust the data.

    Generative search doesn’t work that way. Every response is synthesized in real time through retrieval-augmented generation (RAG), and the output is shaped by token sampling strategies, temperature settings, and even the physical hardware running the inference. Small-to-medium-sized language models (2B to 8B parameters) demonstrate answer consistency rates in the range of 50% to 80% under standard inference conditions. That means the same prompt can produce a different brand list every time you run it.

    The technical reason is surprisingly fundamental: floating-point arithmetic isn’t perfectly associative in parallel computing environments. The order of operations in matrix multiplications can vary between runs. Those tiny rounding differences cascade across billions of calculations, and at a critical branch point, the model might include your brand in a recommendation list, or it might not.

    That’s why a marketing manager can see their brand recommended on a Tuesday, then fail to reproduce it during an executive presentation on Wednesday. It’s not anecdotal. It’s mathematical.

    Manual checks create three specific blind spots. First, they’re non-reproducible, which makes stakeholder reporting unreliable. Second, they can’t achieve cross-platform coverage. ChatGPT, Gemini, and Perplexity use distinct retrieval architectures, so monitoring just one platform gives a false sense of security. Third, manual checks provide zero historical trend data. Without a longitudinal database, you can’t tell whether a brand disappearance is a random fluctuation or a genuine decline in AI authority.

    What “Brand Mentions” Actually Mean Across AI Platforms

    Not all AI mentions carry the same weight. A brand mention in generative search is fundamentally different from a mention on social media or in a news article. The commercial value of each mention is directly tied to how close it sits to the user’s decision-making moment.

    Direct recommendations are the highest-value mentions. These happen when the AI explicitly names your brand as a solution: “The best CRM for small businesses is [Brand].” This implies a degree of algorithmic trust that’s difficult to earn and easy to lose.

    Comparative mentions appear when the AI lists your brand alongside competitors, often in a table or bulleted list. These reveal the “narrative neighborhood” your brand occupies in the AI’s training data. If you’re consistently grouped with budget tools when your positioning is enterprise-grade, that’s an insight manual checks would never surface at scale.

    Source citations occur when the AI provides a clickable link to justify its response. Perplexity does this systematically for nearly every claim. Gemini provides citations for factual statements. ChatGPT has historically leaned toward synthesized answers without direct attribution, though this is shifting with its search integrations.

    Each platform also has distinct retrieval biases that shape which brands get mentioned. Gemini demonstrates a strong preference for brand-owned content, with roughly 52.15% of its citations originating from brand-owned websites. It rewards structured, factual information and consistent schema markup. ChatGPT operates on the logic of consensus, with nearly 48.73% of its citations coming from third-party directories and aggregators like Yelp and TripAdvisor. Perplexity prioritizes niche expertise and factual density, often citing industry experts, real-time news, and customer reviews.

    The practical implication: your brand can be highly visible on one platform and completely absent on another. Tracking only one engine is like measuring your Google ranking and ignoring Bing, except the stakes are higher because AI answers don’t just list your site. They tell users whether to trust you.

    5 Metrics That Define Your AI Search Visibility

    Quantifying brand performance in a non-deterministic environment requires more than checking “are we mentioned or not.” Five metrics, tracked together, normalize the noise and reveal long-term trends.

    1. Visibility Score (Answer Share of Voice). This is the percentage of high-value prompts where your brand appears in the AI’s response. If you track 100 prompts across three platforms and appear in 34 responses, your Visibility Score is 34%. Think of it as market share for generative discovery.

    2. Sentiment and Narrative Framing. This goes beyond positive/negative. It evaluates the specific descriptors and tone the AI uses when positioning your brand. Tracking “Sentiment Velocity,” the direction of sentiment change over time, reveals whether the AI is becoming increasingly critical of your pricing, support, or product quality before it shows up in customer complaints.

    3. Recommendation Position. Just as position matters in SEO, the order in which your brand appears in an AI-generated list is critical. Users overwhelmingly trust the first recommendation. Whether you’re the primary pick or listed under “other options” is a clear indicator of relative authority.

    4. Source Citation Frequency and Gaps. This tracks which domains the AI relies on as “ground truth.” The most actionable insight here is the “Citation Gap”: prompts where competitors are cited from domains where your brand has no presence. Research indicates that third-party citations carry roughly 6.5 times the authority weight of self-published material in many AI retrieval systems. That makes earned media and expert quotes disproportionately valuable.

    5. Conversion Visibility Rate (CVR). CVR evaluates the context of a mention to project the likelihood of a downstream conversion. It distinguishes between a passive mention (a historical reference) and an active recommendation that aligns with the user’s specific constraints (“this tool fits your budget and feature requirements”). High CVR means the AI is sending high-intent signals. Low CVR means you’re visible but not driving action.

    MetricWhat It Tells YouHigh ScoreLow Score
    Visibility ScoreBroad brand awareness in AIDominant category presenceDiscovery gap
    Sentiment TrendBrand reputation healthAI promotes the brandAI warns against the brand
    PositionCompetitive authorityTrusted leaderSecondary alternative
    Source GapsContent coverage blind spotsStrong earned mediaMissing from key domains
    CVRPipeline impactHigh-intent leadsPassive discovery only

    How to Set Up Cross-Platform Brand Tracking, Step by Step

    Moving from manual checks to systematic AI search visibility tracking follows a four-step lifecycle. Each step builds on the previous one, and skipping ahead typically means the data you collect won’t be representative or actionable.

    Step 1: Build Your Prompt Universe

    Visibility tracking starts with identifying high-value conversational prompts, not short keywords. While traditional search queries average four words, conversational AI prompts often exceed 23 words and include specific user constraints. You need a “Prompt Matrix” organized by funnel stage:

    Problem/Solution prompts: “How do I automate payroll for a global team?” Product selection prompts: “What is the most secure cloud storage for healthcare?” Comparison prompts: “Notion vs. Obsidian for personal knowledge management.”

    Topify’s High-Value Prompt Discovery surfaces real-world AI search volume and response patterns to isolate “Dark Queries,” prompts where your brand should be present but is currently excluded. That’s the starting point: knowing which conversations matter before you start measuring.

    Step 2: Establish a Multi-Platform Baseline

    The baseline is your “before” snapshot across ChatGPT, Gemini, and Perplexity. To account for the non-determinism discussed earlier, each prompt needs to be sampled 15 to 20 times within a controlled period to achieve a statistically significant average for visibility and sentiment. This initial audit reveals where you stand relative to competitors and highlights the most immediate gaps.

    Doing this manually for even 50 prompts across three platforms means 2,250 to 3,000 individual checks. That’s where a tracking platform becomes non-negotiable. Topify’s Visibility Tracking runs this across ChatGPT, Gemini, Perplexity, DeepSeek, and other major AI platforms automatically, producing baseline scores for all five metrics in a single dashboard.

    Step 3: Turn on Continuous Monitoring

    AI recommendations shift as models get updated and new web content gets indexed. A competitor that wasn’t in the AI’s recommendation set last month can appear this month. Worse, the AI can start hallucinating incorrect information about your brand: claiming a product has been discontinued, misquoting your pricing, or confusing you with a similarly named company.

    Continuous monitoring catches these shifts in real time. Topify’s Competitor Monitoring automatically detects emerging rivals in your category and tracks position changes across platforms. Its hallucination alerting flags factual errors about your brand so PR teams can respond before the misinformation spreads.

    Step 4: Run Competitive Forensics on Citations

    The final layer is reverse-engineering the AI’s citations. When a competitor consistently outranks you on a specific prompt, the question isn’t just “why.” It’s “what sources is the AI trusting, and are we present on those sources?”

    Source Analysis shows you the exact domains and URLs that AI platforms cite for your category. If a competitor dominates because three industry journals reference them and none reference you, that’s a specific, actionable gap: earn coverage on those publications, and you change the AI’s input data.

    What Your First AI Visibility Report Should Include

    A visibility report that just shows numbers doesn’t drive action. The standard cadence for high-performing teams is a weekly report, produced every Monday, structured to translate data into decisions.

    Headline narrative. One paragraph that converts visibility movements into business context: “Visibility in Perplexity rose 12% following the TechCrunch feature, leading to a measurable increase in referred demo requests.”

    Model-specific visibility trends. A line graph comparing brand presence across ChatGPT, Gemini, and Perplexity. Large discrepancies between platforms point to platform-specific optimization needs. If Gemini visibility is low, schema markup and brand-owned content need attention. If ChatGPT visibility lags, third-party directory listings and aggregator presence are the lever.

    Sentiment velocity chart. A visualization of how the AI’s framing of your brand is changing over time. Downward trends in sentiment are leading indicators of future reputation problems, often surfacing weeks before they appear in customer feedback.

    The citation gap matrix. A table listing high-value prompts where your brand is absent, alongside the sources the AI currently cites for competitors. This is the direct “to-do” list for content and PR teams.

    The transition from report to action is where most teams stall. Common post-report strategies include the “Digital Cushion” approach: if the AI is citing negative reviews or Reddit threads, publishing 5 to 10 high-authority articles on the same topic dilutes the negative signal in the AI’s retrieval pool. Review injection cycles, launching campaigns for fresh reviews on G2 or Trustpilot, correct negative sentiment trends. Entity disambiguation through Schema Markup ensures the AI doesn’t confuse your brand with a similarly named company.

    3 Mistakes That Tank Your Brand Tracking Results

    Even teams that adopt AI visibility tracking make predictable errors in the first few months.

    Mistake 1: Only tracking brand-name prompts. If you’re only monitoring “Is [Brand] a good CRM?”, you’re missing the category prompts that drive discovery: “best CRM for mid-market SaaS.” Category prompts are where new customers first encounter your brand in AI search. Brand-name prompts tell you what the AI thinks about you. Category prompts tell you whether the AI thinks of you at all.

    Mistake 2: Monitoring a single AI platform. Given the retrieval biases outlined earlier (Gemini favors brand-owned content at 52.15%, ChatGPT favors third-party consensus at 48.73%, Perplexity favors niche expertise), single-platform tracking produces a fundamentally incomplete picture. Your audience uses multiple AI platforms, and your visibility profile is different on each one.

    Mistake 3: Running a one-time audit instead of continuous tracking. A single snapshot captures one moment in a highly volatile environment. AI recommendations change as models update, new content gets indexed, and competitor strategies shift. Without longitudinal data, you can’t distinguish a random fluctuation from a real trend. Weekly tracking is the minimum cadence for actionable insights.

    Conclusion

    The shift from index-based search to generative synthesis has changed what “brand visibility” means. You’re no longer competing for a position on a results page. You’re competing for a place in the AI’s narrative, across every platform your audience uses, on every prompt that matters to your business.

    Manual spot-checks can’t measure that. The non-determinism of large language models, with consistency rates as low as 50%, means that anything less than systematic, multi-platform, longitudinal tracking gives you unreliable data and false confidence. The brands that build this infrastructure now will know exactly where they stand. The ones that don’t will keep guessing. Get started with Topify and find out where your brand actually stands in AI search.

    FAQ

    How often should I check my brand’s AI search visibility?

    Weekly is the recommended minimum. AI recommendations shift as models update and new content gets indexed. Monthly audits miss too many changes, and daily tracking is overkill for most teams unless you’re in a fast-moving category with aggressive competitors.

    Can I track competitors’ brand mentions in AI search?

    Yes. Competitive benchmarking is one of the most actionable parts of AI visibility tracking. Tools like Topify automatically detect competitors in your category, compare visibility scores, sentiment, and position across platforms, and surface the specific sources the AI is citing for them but not for you.

    Which AI platforms should I prioritize for brand tracking?

    Start with ChatGPT, Gemini, and Perplexity. They represent the largest share of conversational AI usage and have distinct retrieval architectures, which means your visibility profile is different on each one. If your audience skews toward specific regions, platforms like DeepSeek or Doubao may also be relevant.

    Is AI search visibility different from traditional SEO rankings?

    Yes, fundamentally. Traditional SEO measures your position on a search results page. AI search visibility measures whether the AI mentions your brand in its synthesized response, how it frames you (sentiment), and what position you hold relative to competitors. A high domain authority and strong keyword rankings don’t guarantee that AI platforms will recommend your brand. They measure different signals entirely.

    Read More

  • How to Track AI Recommendations for Your Brand

    How to Track AI Recommendations for Your Brand

    You spent six months building domain authority, publishing content, and climbing Google rankings. Then a prospect typed “best tool for [your category]” into ChatGPT and got a list of five brands. Yours wasn’t on it. The worst part: you didn’t even know it was happening. The same prompt on Perplexity returned a completely different set of recommendations, and Gemini skipped your brand entirely while featuring two competitors you’d never heard of.

    This gap between what traditional SEO dashboards show and what AI engines actually recommend is where most brands are losing ground right now. And it’s growing wider every week.

    Why Manual Spot-Checks Don’t Work for AI Recommendation Tracking Monitoring

    The first thing most marketing teams do when they hear about AI search visibility is Google themselves on ChatGPT. It feels productive. It’s not.

    The core problem is that large language models are non-deterministic. The same prompt can produce different brand recommendations in 30% to 40% of instances, depending on when, where, and how the question is asked. That means a single manual check has roughly the same statistical value as flipping a coin.

    It gets worse. AI outputs are shaped by variables most teams never consider: geographical location, model version (GPT-4o vs. GPT-4o-mini), user account history, and even time of day. A brand might rank as the top recommendation in New York but disappear entirely for users in London. The citation rate in the United States sits at roughly 10.31%, nearly three times higher than many non-US markets.

    That’s not a rounding error. That’s a visibility blind spot.

    On top of that, hallucination rates across major models range from 15% to 52%. These aren’t random errors. They fall into four specific categories of brand risk: fabrication of features your product doesn’t have, omission of key differentiators, use of outdated pricing, and misclassification of your brand as a competitor. Without systematic AI recommendation tracking monitoring, teams end up making budget decisions based on anecdotal evidence, often realizing they’ve been displaced only after leads drop.

    What AI Recommendation Tracking Actually Measures

    AI recommendation tracking isn’t a new name for rank tracking. Traditional SEO measures where your page appears in a list of ten blue links. AI recommendation tracking measures whether the AI chose to mention your brand at all, where it placed you relative to competitors, and how it described you in a synthesized answer.

    The difference matters. In traditional search, users choose between ten results. In AI search, the model selects three to five brands and presents them as vetted recommendations. Your competition isn’t the SERP anymore. It’s the model’s internal reasoning.

    Professional monitoring systems built for this shift typically organize metrics around five core dimensions:

    MetricWhat It MeasuresWhy It Matters
    Visibility Score% of AI responses that mention the brand for target promptsTells you if the model “knows” your brand exists
    Position RankOrder in which the brand appears within a recommendation listPosition 1 carries a 33% citation probability; Position 10 drops to 13%
    Sentiment ScoreNLP-driven rating of the tone AI uses when mentioning the brandDistinguishes “industry leader” from “budget alternative”
    AI Search VolumeEstimated monthly demand for specific natural-language promptsShows which conversational queries are growing
    Citation SourcesURLs and domains the AI cites to support its recommendationReveals which third-party sites the AI trusts more than yours

    The interplay between these metrics is where the real insight lives. A high Visibility Score paired with a low Sentiment Score means the AI knows your brand but is actively steering users away. High Sentiment with low Position means the model respects you but finds competitors more relevant to the specific prompt. This nuance disappears entirely in traditional rank tracking.

    5 Steps to Set Up AI Recommendation Tracking in Practice

    Step 1: Build a Prompt Library, Not a Keyword List

    The foundation of AI recommendation tracking monitoring isn’t keywords. It’s prompts.

    Short-tail keywords like “CRM software” don’t reflect how people query AI assistants. Instead, users ask questions like “What’s the best enterprise CRM for a mid-market manufacturing firm with 50 employees?” These conversational, high-intent queries are what you need to monitor.

    The best sources for building your prompt library are already inside your organization. Sales call recordings from platforms like Gong or Chorus reveal the exact decision-making frameworks buyers use. Support tickets surface the feature gaps and bottlenecks users try to solve via AI. And Google Search Console, filtered with Regex for long-tail conversational queries, bridges the gap between traditional search behavior and AI prompts.

    Aim for 20 to 50 high-intent prompts grouped by semantic interest: use cases, comparisons, and buyer personas. Topify‘s High-Value Prompt Discovery feature automates this process, continuously surfacing new prompt opportunities as AI recommendations evolve.

    Step 2: Monitor Across Multiple AI Platforms

    Only tracking ChatGPT is like only tracking Google in 2010. You’d miss half the picture.

    Each AI platform has a fundamentally different recommendation logic. Perplexity operates as a research engine, citing an average of 21.87 sources per response, nearly three times more than ChatGPT’s 7.92. Perplexity is heavily biased toward recency: content updated within the last 30 days has an 82% citation rate. If you’re not refreshing content monthly, Perplexity probably isn’t citing you.

    ChatGPT, by contrast, is more selective. About 90% of its citations come from domains that already rank in Google’s Top 10, meaning traditional SEO still functions as a trust signal for ChatGPT. Google AI Overviews leans on the Knowledge Graph and E-E-A-T signals. DeepSeek and Qwen are emerging as significant players for technical queries, with Chinese LLMs mentioning brands at an 88.9% rate for English queries compared to 58.3% for international models.

    PlatformAvg. Citations/ResponseKey Recommendation Factor
    Perplexity21.87Recency and factual corroboration
    ChatGPT7.92Relevance overlap with Google Top 10
    Google AI8.34E-E-A-T and Knowledge Graph entities
    DeepSeekVariableTechnical accuracy and MoE reasoning

    Topify covers ChatGPT, Perplexity, Gemini, DeepSeek, Qwen, and other major platforms from a single dashboard. For teams using ai search engine optimization tools, this cross-platform view is the difference between a partial snapshot and a real baseline.

    Step 3: Benchmark Against Competitors

    Tracking your own data is only half the equation. The other half is understanding who the AI recommends instead of you, and why.

    Topify’s Dynamic Competitor Benchmarking automatically detects which brands appear alongside yours in AI responses. You can compare Visibility, Sentiment, and Position side by side, across every platform, for every prompt in your library. When a competitor suddenly climbs into Position 1 for a high-volume prompt, you’ll know within days, not quarters.

    Step 4: Reverse-Engineer Citations to Find Content Gaps

    Here’s the insight most teams miss: between 82% and 85% of AI citations come from third-party sources, not from the brand’s own website. Media coverage, Reddit threads, G2 reviews, and niche industry forums carry more weight with AI models than your homepage.

    If a competitor dominates AI recommendations in your category, it’s often because they’ve built a “citation moat” across these external platforms. The fix isn’t writing another blog post on your domain. It’s identifying the specific URLs the AI cites when recommending competitors and building your brand’s presence in those same contexts.

    Topify’s Source Analysis breaks down exactly which domains and URLs AI platforms reference. You can see whether the AI trusts your content or your competitor’s, and where the gaps are. That’s the foundation of any ai-powered search engine optimization strategy: know what the AI reads before you try to change what it says.

    AI-Based Search Engine Optimization Tools: What Separates Monitoring from Execution

    Most ai-based search engine optimization tools stop at dashboards. They show you the data, then leave you to figure out what to do with it.

    The gap between insight and action is where most tracking efforts stall. A team discovers their brand is invisible for 60% of high-intent prompts. The dashboard confirms it. Then what? Without a clear execution path, the data sits in a slide deck.

    This is where the market splits. Pure monitoring tools give you visibility metrics. End-to-end platforms connect those metrics to specific actions. When Topify identifies an “Invisibility Gap,” such as missing structured pricing data that causes an AI to skip your brand, its One-Click Execution feature can propose and deploy the fix: adding a comparison table, updating FAQ schema, or creating an llms.txt file to help AI crawlers prioritize your content.

    The ROI math supports this approach. AI-referred traffic converts at nearly 2x the rate of traditional organic search. In B2B SaaS specifically, the conversion rate for AI-referred clicks reaches 11.4%, compared to 5.8% for standard organic traffic. That “pre-vetting effect,” where the AI validates your brand before the user even clicks, makes every AI recommendation significantly more valuable than a traditional blue-link click.

    For teams evaluating ai tools for search engine optimization, the key question isn’t “does it track?” It’s “does it close the loop between tracking and doing?”

    CapabilityMonitoring-Only ToolsEnd-to-End Platforms like Topify
    Visibility metricsYesYes
    Cross-platform coverageVaries (often 1-2 engines)ChatGPT, Perplexity, Gemini, DeepSeek, Qwen+
    Competitor benchmarkingLimitedAutomatic detection and tracking
    Citation source analysisRareFull URL-level breakdown
    Execution from dashboardNoOne-Click Optimization

    Topify’s Basic plan starts at $99/month and includes tracking across ChatGPT, Perplexity, and AI Overviews with 100 prompts and 9,000 AI answer analyses. For teams that need broader coverage, the Pro plan at $199/month scales to 250 prompts across additional platforms. Check Topify’s pricing for full plan details.

    The Compounding Cost of Starting Late

    The brands winning in AI search aren’t optimizing harder. They’re monitoring earlier.

    AI platforms are recursive. Each time a model cites a brand and a user validates that recommendation through subsequent actions, the model’s confidence score for that brand increases. Over time, the brand that gets recommended first builds a self-reinforcing cycle: more citations lead to more trust, which leads to more citations.

    The flip side is equally powerful. Once a competitor captures more than 50% of category citations, they’ve built a level of topical authority that traditional SEO investment struggles to displace. The “citation moat” compounds. And the longer a brand waits to start tracking, the deeper that moat gets.

    In critical B2B sectors, AI-referred traffic now converts at up to 6x the rate of traditional channels. That’s not a future projection. That’s the current gap between brands that monitor AI recommendations and brands that don’t.

    The strategic roadmap is straightforward: establish a baseline across ChatGPT, Perplexity, and Gemini. Shift from keyword research to prompt research. Validate your technical setup (schema markup, llms.txt, bot access). Diversify your citation sources across third-party platforms. And build continuous monitoring into your weekly marketing operations, not your quarterly reviews.

    The brands that thrive in the AI era won’t be the ones that rank highest on Google. They’ll be the ones that AI chooses to recommend. And the only way to know if that’s happening is to track it.

    Get started with Topify to see where your brand stands across every major AI platform.

    Conclusion

    The shift from “getting found” to “getting recommended” is the defining change in digital marketing right now. Manual spot-checks can’t capture it. Traditional SEO dashboards can’t measure it. And waiting to see if it matters isn’t a strategy.

    AI recommendation tracking monitoring gives brands the visibility they need to act: which prompts matter, which platforms recommend you (or don’t), what competitors are doing differently, and where the citation gaps are. The brands building this infrastructure now are the ones AI will keep recommending tomorrow. The ones that delay are building their competitor’s moat for them.

    FAQ

    Q: What is AI recommendation tracking? 

    A: AI recommendation tracking is the process of systematically monitoring how AI platforms like ChatGPT, Perplexity, and Gemini mention, rank, and describe your brand in their generated responses. Unlike traditional SEO rank tracking, it measures conversational visibility, sentiment, position, and the specific sources AI models cite when recommending brands.

    Q: Which AI platforms should I monitor for brand recommendations? 

    A: At minimum, track ChatGPT, Perplexity, and Google AI Overviews, as they represent the largest share of AI-driven search behavior. For global or technical brands, add DeepSeek and Qwen. Each platform uses different retrieval mechanisms and citation logic, so cross-platform monitoring is essential for an accurate picture.

    Q: How often should I check my AI recommendation data? 

    A: Weekly monitoring is the practical baseline. AI models update their citation patterns frequently, and Perplexity in particular favors content updated within the last 30 days. Quarterly reviews are too slow to catch competitive shifts or model updates that could change your brand’s visibility overnight.

    Q: Can a generative AI search engine optimization agency handle AI recommendation tracking for me? 

    A: A generative ai search engine optimization agency can manage the tracking and optimization process, especially for brands without in-house GEO expertise. That said, platforms like Topify are designed for marketing teams to self-serve with minimal onboarding, starting at $99/month. Whether you use an agency or build the capability internally, the important thing is that someone is watching what AI says about your brand every week.

    Read More

  • AI Response Monitoring Tracker: How It Works

    AI Response Monitoring Tracker: How It Works

    Your team spent months building domain authority, earning backlinks, and climbing Google rankings. Then a prospective buyer asked ChatGPT, “What’s the best tool for [your category]?” and got a list of five recommendations. Your brand wasn’t on it.

    The frustrating part isn’t the omission. It’s that nothing in your analytics dashboard flagged it. Traditional SEO metrics still show green across the board, keyword positions look stable, and traffic from Google hasn’t changed much. But somewhere between 60% and 93% of informational queries now resolve inside an AI-generated answer, without a single click to any website. The buyers are still researching. They’re just not visiting your site to do it.

    That’s the gap an AI response monitoring tracker is built to close.

    What an AI Response Monitoring Tracker Actually Measures (and Why SEO Dashboards Can’t)

    An AI response monitoring tracker is a system that continuously monitors how large language models and AI search engines represent your brand when users ask natural-language questions. It’s not tracking keyword rankings or URL positions. It’s tracking whether the AI mentions you at all, how it describes you, where it places you relative to competitors, and which sources it cites to justify its answer.

    The core shift here is from “Keyword-to-URL” mapping to “Prompt-to-Entity” association. In traditional search, a keyword triggers a list of links ranked by relevance. In AI search, a prompt triggers a synthesis process where the model evaluates your brand’s presence across its training data and real-time retrieval window. You’re no longer competing for a spot on a page. You’re competing for space in the model’s recommendation logic.

    That distinction matters commercially. Click-through rates for informational queries dropped by 61% in 2025, even as search volume kept growing. Brands are still being searched for, but they’re being discovered inside the AI’s synthesized response. And the data shows that 92.36% of AI Overview citations pull from domains already ranking in the top 10 of traditional search, with cited brands seeing a 35% to 91% lift in CTR over non-cited brands appearing in the same result.

    Without a tracker, all of that influence stays invisible.

    How AI Response Monitoring Trackers Work Behind the Scenes

    The technical backbone of an AI response monitoring tracker is prompt-level simulation. The system programmatically sends real-world user queries to AI engines, captures the full response, and analyzes the content for brand mentions, sentiment, positioning, and citations.

    Most professional trackers use a hybrid approach. API-level tracking provides clean, structured data from the model’s backend, establishing what the model “knows” from core training. Browser-level scraping mimics an actual user session, capturing live elements like Google AI Overviews or Perplexity’s real-time web citations that shift based on geography, device, and user history.

    The complexity increases because each AI platform operates differently. ChatGPT combines pre-trained knowledge with SearchGPT for real-time retrieval. Perplexity functions primarily as an answer engine, pulling heavily from the most recently published authoritative content. Google AI Overviews integrate directly into the traditional search index, favoring domains with strong E-E-A-T signals. A single-platform tracker misses the full picture.

    One technical challenge worth noting: non-determinism. The same prompt can produce slightly different outputs depending on model temperature settings or updated training weights. Advanced trackers handle this through “Query Fan Out,” running the same prompt multiple times and flagging response drift or accuracy drops. If a third-party review site lists your price as $79 but your site says $99, the AI might hallucinate a figure in between. Detecting that inconsistency before your customers do is exactly what a monitoring tracker is for.

    The 7 Metrics That Separate Useful AI Monitoring from Vanity Dashboards

    Not all AI visibility data is created equal. The difference between a useful monitoring setup and a vanity dashboard comes down to which metrics you’re tracking and whether they connect to revenue.

    Here’s what a professional-grade system measures:

    Visibility Score. The percentage of responses where your brand appears across a set of high-intent prompts. A score of 40% means in 4 out of 10 relevant AI conversations, you’re named as a solution.

    Sentiment Score. An NLP-driven rating (0 to 100) that evaluates how the AI frames your brand. Being mentioned is one thing. Being described as “legacy” or “overpriced” is another.

    Position Weighting. In a conversational response, the first-named brand carries disproportionate influence. Being listed in an “also consider” section at the end of a long answer is not the same as being the opening recommendation.

    Mention Frequency. The raw count of brand occurrences across platforms. This measures your “Entity Density” in the model’s output.

    Share of Citation. How often the AI links to your domain compared to competitors. High citation share is the primary driver of referral traffic from AI platforms.

    Conversational Volume. The AI equivalent of search volume. Panel data estimates how many users are engaging with AI on specific topics, helping teams prioritize the prompts that represent the largest market opportunity.

    Conversion Efficiency (CVR). The bottom-line metric. By integrating with Google Analytics 4 or Shopify, trackers can attribute revenue directly to AI citations. This matters because visitors arriving from an AI recommendation convert at 4.4x the rate of traditional organic search visitors.

    Different roles need different slices of this data. A CMO focuses on Share of Model Voice and Sentiment for long-term competitive positioning. Brand managers prioritize mention accuracy and hallucination detection. SEO and content teams zero in on citation share and source attribution to figure out which content pieces are actually feeding the models.

    5 Mistakes That Tank Your AI Response Monitoring Strategy

    Implementing a tracker without understanding how LLMs actually behave leads to misleading data and wasted budget. These are the five most common failure modes.

    Tracking only one AI platform. Many teams default to ChatGPT because of its market share. But brand representation is highly fragmented across models. A brand can hold 24% Share of Model on Meta’s Llama while sitting below 1% on Google’s Gemini. Perplexity users skew toward senior enterprise leadership, while ChatGPT has broader general adoption. One platform gives you one slice, not the full picture.

    Filling your prompt library with branded searches. Queries like “What is [Brand]?” or “How do I use [Product]?” are useful for accuracy checks, but they don’t reflect how buyers discover new solutions. The high-value prompts are unbranded: “What’s the best project management tool for remote engineering teams?” If you’re only monitoring your own name, you’re missing the entire discovery phase.

    Counting mentions without checking framing. Traditional SEO treated any Page 1 result as a win. In AI search, visibility is binary but also qualitative. An AI might mention your brand and then add: “While [Brand] is a popular choice, users frequently report issues with integration speed.” Without sentiment and position tracking, you might think you’re winning while actively losing customers.

    No competitive benchmarking. AI visibility within a single response is zero-sum. If your visibility rises 10% but a competitor’s rises 50% across the same high-intent prompts, you’re losing recommendation share. Without a competitive framework, you can’t spot the “Entity Neighborhoods” where rivals are winning and you’re absent.

    Ignoring source attribution. This is the most consequential mistake. AI models rely on a narrow set of authoritative domains to verify answers. If you don’t know which third-party sites (Reddit, industry publications, review platforms) the AI is citing, you can’t optimize your PR, content, or outreach strategy to influence those sources.

    Strategic MistakeConsequenceCorrective Action
    Single-engine focusMissing up to 80% of buyer discovery pathsTrack ChatGPT, Gemini, Perplexity, and AI Overviews
    Branded-only promptsInvisible during the research phaseUse 75% unbranded, intent-based prompts
    Ignoring sentimentBrand damage at the point of recommendationImplement NLP-driven sentiment analysis
    No competitor frameworkCan’t measure relative market shareBaseline against 3 to 5 key rivals
    Ignoring citationsWasted content on untrusted sourcesReverse-engineer the AI’s trust neighborhood

    A Step-by-Step Strategy for Setting Up Your AI Response Monitoring Tracker

    Moving from traditional SEO reporting to AI-first monitoring doesn’t require scrapping everything you’ve built. It requires adding a new measurement layer. Here’s a five-step framework.

    Step 1: Define your AI platform scope. Your target audience determines which engines matter most. For B2B SaaS, ChatGPT and Perplexity are typically priorities since buyers use them for vendor shortlisting. For consumer brands, Google AI Overviews and Meta AI are more relevant due to their integration into search and social surfaces. Cover at least three engines for cross-model reliability.

    Step 2: Build a prompt library grounded in real buyer behavior. A “Golden Prompt” library typically starts with 50 to 100 questions across four tiers: informational (“What’s the best way to automate [process]?”), comparative (“[Brand] vs [Competitor] for enterprise security?”), transactional (“Which [category] tool has the lowest TCO?”), and branded/accuracy (“What are the latest features of [Brand]?”). Source these from sales call recordings, Reddit discussions, and Google’s “People Also Ask” sections.

    Step 3: Run a 30-day baseline measurement. Before optimizing anything, you need to know where you stand. This baseline reveals your current AI visibility score and surfaces “Dark Queries,” the prompts where your brand should appear based on SEO rankings but is currently missing from AI responses.

    Step 4: Map the competitive field. Configure your tracker to detect which brands are “Citation Leaders” (cited for links) and “Mention Leaders” (recommended by name). This reveals the Entity Association Gap. If the AI consistently pairs a competitor with “enterprise-grade” and pairs you with “small business,” you’ve uncovered a positioning problem that content alone can fix.

    Step 5: Set a reporting cadence and optimization loop. Weekly monitoring works for established brands. Daily tracking is better during active campaigns or product launches. The cycle looks like this: detect a drop in citation share on a key prompt, identify that the AI switched from citing your blog to a competitor’s new research report, produce a more comprehensive piece with proper Schema markup, then validate through the tracker that the AI updated its source within 14 days.

    That loop is where monitoring turns into growth.

    What the Best AI Visibility Solutions Available Look Like in Practice

    The market for AI response monitoring is split between legacy SEO platforms bolting on AI features and GEO-native platforms built specifically for this problem. The difference matters.

    Here’s what to evaluate when choosing a tool: multi-model coverage (does it track ChatGPT, Gemini, Perplexity, Claude, and regional engines like DeepSeek or Doubao?), an execution layer (does it tell you how to fix the gaps it finds?), attribution integration (can it connect AI citations to GA4 or Shopify revenue?), and enterprise compliance (SOC 2, HIPAA readiness).

    PlatformNotable FeatureStarting PriceBest For
    Topify7-dimension metrics + one-click agent execution$99/moTeams needing end-to-end optimization
    Profound“Prompt Volumes” panel data + shopping visibility$399/moLarge orgs focused on deep market research
    ZipTieOn-page crawlability audits for AI agents$69/moSEO teams focused on the Big Three engines
    Otterly AIBroadest engine coverage at low cost, daily tracking$29/moSolo marketers and small teams on a budget

    Topify stands out for teams that need more than a dashboard. Its platform covers ChatGPT, Gemini, Perplexity, DeepSeek, Doubao, Qwen, and other major AI engines, tracking seven core metrics (visibility, sentiment, position, volume, mentions, intent, and CVR) across all of them. But the real differentiator is the execution layer.

    Most monitoring tools stop at data. Topify’s AI agent identifies the prompts where competitors are winning, surfaces high-volume opportunities as AI recommendations evolve, and helps teams deploy optimized content with a single click. For e-commerce brands, that means identifying category prompts like “best eco-friendly running shoes” and optimizing product pages so AI agents can extract and recommend specific SKUs. For B2B SaaS teams, it means closing the gap between “being mentioned” and “being the first recommendation.”

    Pricing scales with usage: the Basic plan starts at $99/mo (100 prompts, 9,000 AI answer analyses, 4 projects), Pro at $199/mo (250 prompts, 22,500 analyses, 10 seats), and Enterprise from $499/mo with a dedicated account manager. You can check current pricing details on the Topify website.

    The team behind the platform includes a GEO strategy lead with 10+ years of Fortune 500 SEO experience, an LLM algorithm researcher from Stanford with publications at NeurIPS and AAAI, and a growth operator who’s scaled companies from zero to $20M in revenue.

    Ready to see where your brand stands? Get started with a baseline audit and find out which AI platforms are recommending your competitors instead of you.

    Conclusion

    The shift from “searchable” to “recommended” isn’t coming. It’s already here. Between 60% and 93% of informational queries now resolve inside AI-generated answers, and the brands that show up in those answers convert at 4.4x the rate of traditional organic traffic.

    An AI response monitoring tracker gives you the visibility your existing analytics can’t: which AI platforms mention you, how they frame you, where they rank you against competitors, and which sources they trust. The five-step framework outlined above, defining your platform scope, building a real prompt library, running a 30-day baseline, mapping competitors, and establishing an optimization loop, is where most successful teams start.

    The brands winning in AI search aren’t the ones with the highest domain authority. They’re the ones who know exactly what the models are saying about them and have a system to influence it.

    FAQ

    Q: What is an AI response monitoring tracker? A: An AI response monitoring tracker is a system that continuously monitors how AI platforms like ChatGPT, Perplexity, and Google AI Overviews mention, describe, and recommend your brand when users ask natural-language questions. It tracks metrics like visibility, sentiment, position, and citation sources across multiple AI engines.

    Q: How does an AI response monitoring tracker work? A: It uses prompt-level simulation, programmatically sending real user queries to AI engines and analyzing the full response. Professional trackers combine API-level tracking (for structured baseline data) with browser-level scraping (for real-time citations and live search results), running prompts multiple times to detect response drift and inconsistencies.

    Q: What’s the difference between AI response monitoring and traditional SEO tracking? A: Traditional SEO tracks keyword-to-URL rankings on search engine results pages. AI response monitoring tracks prompt-to-entity associations, measuring whether AI models mention your brand, how they frame it, and which sources they cite. The two systems measure fundamentally different discovery paths.

    Q: How much does an AI response monitoring tracker cost? A: Pricing varies by platform and scale. Entry-level tools start around $29/mo for basic tracking, mid-tier platforms like Topify start at $99/mo with full 7-dimension metrics and execution capabilities, and enterprise solutions range from $399/mo to $499/mo+ depending on prompt volume and custom requirements.

    Read More

  • AI Mention Tracking Analytics: How to Measure What AI Says About Your Brand

    AI Mention Tracking Analytics: How to Measure What AI Says About Your Brand

    Your team spent six months building SEO authority. Domain authority is up, keyword rankings are solid, and organic traffic looks healthy. Then someone on the leadership team asks ChatGPT for a product recommendation in your category, and your brand doesn’t appear anywhere in the response. Five competitors do. Your Google Analytics dashboard has no metric that explains why, because it was never designed to measure what AI chooses to say.

    That gap between what traditional SEO tracks and what actually drives AI recommendations is widening every quarter. And for brands that don’t close it, the cost isn’t hypothetical. It’s measurable in lost pipeline, missed conversions, and a shrinking share of the fastest-growing discovery channel in digital marketing.

    What AI Mention Tracking Analytics Actually Measures

    AI mention tracking analytics is the practice of systematically monitoring how often, where, and in what context a brand appears in AI-generated answers. It’s not the same as traditional brand monitoring, which tracks mentions on social media, news sites, and forums. Instead, it focuses on a fundamentally different layer: the synthesized responses produced by large language models like ChatGPT, Perplexity, Gemini, and DeepSeek.

    The distinction matters. Traditional monitoring tells you what people say about your brand. AI mention tracking tells you what machines say about your brand, and machines are increasingly the ones shaping purchase decisions.

    Here’s the scale: ChatGPT alone reached 800 million weekly active users by October 2025 and now processes over one billion queries per day. It accounts for roughly 77% of all AI-driven referral traffic to websites. Perplexity, with its citation-heavy answer format, drives another 15%. When a user asks one of these platforms “what’s the best project management tool for remote teams,” the answer isn’t a list of ten blue links. It’s a curated recommendation of two or three products, often with a brief explanation of why each one fits.

    If your brand isn’t in that answer, you’re not in the consideration set. AI mention tracking analytics exists to make sure you know where you stand.

    Why Your SEO Dashboard Can’t Track AI Mentions

    Google’s search market share dipped to 89.74% by March 2025. That’s the first time it dropped below 90% in nearly a decade. Meanwhile, AI-powered search tools captured between 12% and 15% of the global search market by year-end 2025, up from roughly 5% at the start of that year. Gartner’s 2024 prediction that traditional search volume would fall 25% by 2026 is tracking on schedule.

    But the more disruptive number is zero-click behavior. In the US, 58.5% of searches now end without a single click to an external website. When Google’s own AI Overviews appear, that rate jumps to 83%. The user gets the answer inside the search interface itself.

    This breaks the fundamental assumption of traditional SEO: that ranking high on a results page translates to traffic, which translates to conversions. In a zero-click environment, the AI’s synthesized answer is the final destination. If your brand isn’t named in that synthesis, your PageRank is irrelevant.

    That’s the gap most brands still can’t see.

    Traditional SEO tools measure keyword rankings, backlink profiles, and domain authority. None of these metrics tell you whether Perplexity is recommending your competitor instead of you, or whether ChatGPT describes your product as “budget-friendly” when your positioning is premium. AI mention tracking analytics fills that blind spot by directly querying AI platforms and analyzing the responses for brand presence, sentiment, and citation sources.

    The 5 Metrics That Define AI Mention Tracking Analytics

    Measuring AI mentions isn’t just about counting how many times your brand name appears. The context, position, sentiment, and source attribution of each mention determine its actual business impact. Here are the five metrics that matter most.

    1. Visibility Score

    This is the percentage of target prompts where your brand appears in the AI-generated response. If you’re tracking 100 high-value prompts across ChatGPT, Gemini, and Perplexity, and your brand shows up in 34 of those responses, your visibility score is 34%. It’s the top-of-funnel metric for AI discovery.

    2. Sentiment Score

    Not all mentions are equal. An AI response that describes your product as “the industry standard for enterprise teams” is fundamentally different from one that calls it “a decent option for small budgets.” Sentiment scoring evaluates whether AI platforms frame your brand positively, neutrally, or negatively, using a 0-to-100 scale rather than simple positive/negative buckets.

    3. Position Rank

    Research shows that the first brand mentioned in an AI recommendation list earns significantly more trust and click-through than the third or fourth. If ChatGPT lists five CRM tools and your competitor is consistently #1 while you’re #4, that ordering gap translates directly into lost conversions. Position tracking monitors where your brand falls in the recommendation hierarchy.

    4. Citation Source Analysis

    AI models don’t form opinions in a vacuum. They pull from specific web sources to construct their answers. Citation source analysis identifies which domains and URLs the AI is referencing when it mentions (or doesn’t mention) your brand. This is where strategy meets execution: if you discover that Perplexity cites a competitor’s blog post in 40% of relevant answers, you know exactly what content gap to close.

    5. Conversion Visibility Rate

    This advanced metric ties AI visibility directly to revenue impact. Platforms like Topify calculate CVR by estimating the conversion probability of a specific mention context. The underlying economics are compelling: AI search traffic converts at an average rate of 14.2%, compared to 2.8% for traditional organic search. That’s a 5.1x advantage. The average value of an AI-referred visit is $47, versus $9 from Google. For SaaS companies specifically, the conversion multiplier reaches 8.5x.

    Those numbers explain why AI mention tracking analytics isn’t a nice-to-have. It’s where the highest-converting traffic in digital marketing is being allocated.

    How the Best GEO Agencies Build an AI Mention Tracking Strategy

    A top GEO agency doesn’t start with tools. It starts with a framework. Here’s the four-step process that separates effective AI mention tracking from random spot-checking.

    Step 1: Define your prompt universe. Identify 50 to 200 prompts that your target audience is likely to type into ChatGPT, Perplexity, or Gemini. These aren’t traditional keywords. They’re full-sentence queries like “what’s the best invoicing software for freelancers in Europe” or “compare Notion vs Coda for product teams.” The best GEO agencies use tools like Topify’s High-Value Prompt Discovery to surface prompts with real AI search volume, not guesses.

    Step 2: Establish your baseline. Run those prompts across multiple AI platforms and record your brand’s visibility score, sentiment, position, and citation sources. This baseline is your “before” snapshot. Without it, you can’t measure improvement.

    Step 3: Monitor continuously, not once. AI recommendations shift. A brand that was #1 in ChatGPT’s answer last month might drop to #3 this month because a competitor published a well-cited research report. Continuous monitoring flags these changes in near-real-time so you can respond before the damage compounds.

    Step 4: Optimize the inputs. This is where GEO strategy diverges from traditional SEO. The most effective technique for improving AI visibility is including expert quotes in your content, which can increase AI citation rates by up to 41%. Structured data markup (JSON-LD for Article, FAQ, HowTo, Product schemas) drives a 67% improvement in AI coverage. And here’s a critical insight: citations from independent third-party sources carry roughly 6.5x more weight with LLMs than self-published brand content. That means your GEO strategy needs to extend beyond your own website into earned media, Reddit, Quora, and industry publications.

    A top geo agency understands that AI mention tracking analytics isn’t a one-time audit. It’s an ongoing operational discipline, like financial reporting or competitive intelligence.

    5 Mistakes That Tank Your AI Mention Tracking Results

    Most brands that attempt AI mention tracking make at least one of these errors. Each one silently degrades the accuracy and usefulness of the data.

    Tracking only one AI platform. ChatGPT, Perplexity, and Gemini use different retrieval architectures, different training data, and different citation patterns. A brand that’s visible on ChatGPT might be completely absent from Perplexity. Monitoring a single platform gives you a false sense of security.

    Counting mentions without reading sentiment. Being mentioned in an AI response where the model describes your product as “outdated” or “limited in functionality” is worse than not being mentioned at all. Volume without sentiment context is a vanity metric.

    Ignoring citation sources. If you don’t know which web pages the AI is pulling from when it recommends your competitor, you can’t reverse-engineer the strategy to overtake them. Citation source analysis is the actionable layer that transforms tracking into optimization.

    Relying on manual spot-checks. Typing your brand name into ChatGPT once a week and reading the response is not a tracking strategy. AI answers change based on model updates, retrieval augmentation shifts, and new content indexing. Manual checks miss 90%+ of the variation.

    Flooding the web with AI-generated filler content. Some brands try to game AI citation by mass-producing low-quality articles. Both search engines and AI models are increasingly penalizing this approach. The over-automation penalty is real, and it can push your brand further down the recommendation hierarchy instead of up.

    AI Mention Tracking Analytics Tools: What to Use in 2026

    The market for AI visibility platforms has expanded rapidly. Here’s how the major players compare across pricing, coverage, and core strengths.

    PlatformStarting PriceAI Models CoveredBest For
    Topify$99/moChatGPT, Gemini, Perplexity, DeepSeek, QwenCross-border SaaS, agencies managing multiple clients
    Profound$99/mo10+ engines incl. Claude, GrokEnterprise legal/finance with compliance needs
    ZipTie.dev$69/moChatGPT, Perplexity, Google AIOAccuracy-focused SEO teams (UI scraping approach)
    SE Ranking$119/moAIO, Gemini, ChatGPTSMBs needing integrated SEO/GEO workflow
    Cockpyt AI€59/moChatGPT, Perplexity, AIOFrench freelancers and VSEs
    Qwairy€59/mo10 AI enginesFrench marketing teams needing broad coverage

    For teams tracking brand visibility across multiple AI platforms and geographies, Topify stands out for three reasons. First, its seven-dimension metric system (visibility, sentiment, position, volume, mentions, intent, and CVR) covers the full spectrum of AI mention tracking analytics in a single dashboard. Second, it’s one of the few platforms with Mandarin LLM coverage (Qwen, DeepSeek, Doubao), which matters for any brand with Asia-Pacific exposure. Third, its one-click agent execution turns insight into action: define your optimization goal, review the proposed strategy, and deploy it without manual workflows.

    Pricing starts at $99/month for the Basic plan (100 prompts, 9,000 AI answer analyses, 4 projects). The Pro plan at $199/month scales to 250 prompts and 22,500 analyses. Enterprise plans start at $499/month with a dedicated account manager. Full details are on the Topify pricing page.

    A Note on the French GEO Agency Landscape

    The French market has developed its own specialized ecosystem for AI visibility. Domestic tools like Cockpyt AI, Qwairy, and Botrank.ai address regional needs, with Botrank.ai introducing “Bob,” an autonomous AI agent that structures action plans from visibility data.

    One insight specific to France: LinkedIn is the most cited domain across AI platforms for professional and tech queries, appearing in 11% of all analyzed AI answers. For any French geo agency or brand targeting the French market, LinkedIn content optimization is a disproportionately high-value GEO lever.

    Another regional finding: French websites that implement comprehensive JSON-LD schema see a 67% improvement in AI coverage. And because AI systems are heavily influenced by English-language training data, translating French content into English can boost citation rates even within French-language queries.

    Your AI Mention Tracking Checklist

    Before you invest in any platform, make sure you’ve covered these fundamentals:

    • Define 50+ target prompts that match how your audience queries AI platforms (full sentences, not two-word keywords)
    • Select at least 3 AI platforms to monitor (ChatGPT + Perplexity + one more relevant to your market)
    • Identify 3 to 5 direct competitors for benchmarking against your visibility and position data
    • Establish a baseline across all five core metrics: visibility, sentiment, position, citation sources, and CVR
    • Set a monitoring cadence: weekly for fast-moving categories, bi-weekly minimum for stable markets
    • Assign ownership: someone on your team needs to own the AI visibility number the way someone owns organic traffic
    • Connect tracking to action: every drop in visibility or sentiment shift should trigger a specific content or PR response

    Conclusion

    The brands that treated SEO as a growth channel ten years ago are the ones dominating organic traffic today. AI mention tracking analytics is the same inflection point, just earlier in the curve.

    AI search traffic already converts at 5.1x the rate of traditional organic. The average AI-referred visit is worth $47. And with zero-click behavior hitting 83% when AI Overviews are present, the window for brands to establish their position in AI recommendations is narrowing fast. Start with 10 high-value prompts, measure your baseline across ChatGPT and Perplexity, and build from there. The compounding advantage goes to whoever moves first. You can get started with Topify to set up your tracking in minutes.

    FAQ

    Q: What is AI mention tracking analytics? 

    A: AI mention tracking analytics is the process of monitoring and measuring how a brand appears in AI-generated responses across platforms like ChatGPT, Perplexity, and Gemini. It tracks metrics including visibility score, sentiment, position rank, citation sources, and conversion visibility rate to quantify a brand’s presence in the AI discovery layer.

    Q: How does AI mention tracking analytics work? 

    A: AI mention tracking tools query AI platforms with a defined set of prompts relevant to your brand and industry. They then analyze the responses to determine whether your brand is mentioned, how it’s described, where it ranks relative to competitors, and which web sources the AI cited. This data is collected continuously and displayed in dashboards for ongoing monitoring.

    Q: How can I improve my AI mention tracking analytics results? 

    A: Focus on three high-impact areas. First, include expert quotes in your content, which can increase AI visibility by up to 41%. Second, implement structured data markup (JSON-LD) across your site for a potential 67% improvement in AI coverage. Third, build citations from authoritative third-party sources like industry publications and community platforms, which carry 6.5x more weight with LLMs than self-published content.

    Q: How much does AI mention tracking analytics cost? 

    A: Pricing varies by platform and scale. Entry-level tools start around $59 to $69 per month. Mid-tier platforms like Topify start at $99/month for 100 prompts and 9,000 AI answer analyses. Enterprise plans with dedicated account management typically start at $499/month and up. The right investment depends on how many prompts, platforms, and competitors you need to track.

    Read More