Category: Article

  • 5 Things G2 Won’t Tell You About AEO Tools

    5 Things G2 Won’t Tell You About AEO Tools

    G2 ranks AEO tools by satisfaction and market presence. Neither score tells you whether the tool can handle what LLMs actually do.

    You opened G2. You filtered by “Answer Engine Optimization.” You sorted by highest rated.

    That’s a reasonable starting point. But here’s the thing: the two dimensions G2 uses to rank software — user satisfaction and market presence — were designed to evaluate CRMs and project management tools. They measure how easy the UI is, how responsive the support team is, and how big the company is. None of that tells you whether a tool can handle the one thing that makes AEO fundamentally different from every other software category: LLM non-determinism.
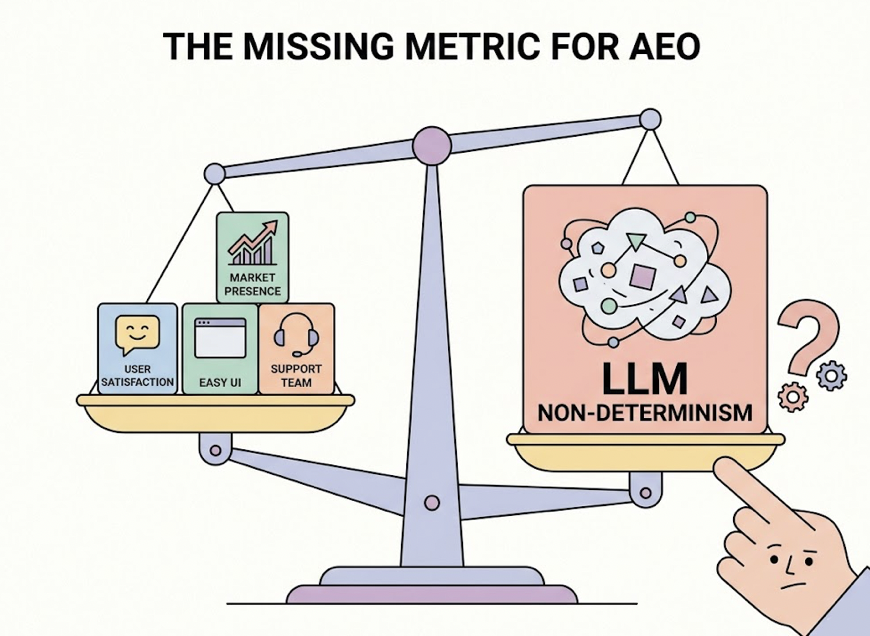
    Run the same query twice, 30 seconds apart. You may get different brand citations, different positions, different sentiment. Tools that rely on API caches or static snapshots will systematically undercount this variance. And they’ll do it in a way that looks fine on a dashboard.

    That’s the gap G2 scores can’t show you.

    Here’s a five-part framework that does.


    Why G2 Scores Are a Starting Point, Not a Verdict

    G2’s Satisfaction score is built on review breadth, recency, and net promoter ratings. Its Market Presence score factors in employee count, revenue, and social footprint. Both are legitimate signals for evaluating a project management tool or a CRM.

    For AEO tools, they miss the point.

    A tool with a polished UI and 24/7 live chat support can score in the top 10% on G2 while its underlying crawler fails to bypass LLM rate limits. A legacy SEO platform with 10,000 employees can dominate the Leaders quadrant after bolting a thin AI monitoring layer onto a five-year-old architecture.

    High satisfaction doesn’t mean accurate data.

    G2’s review cycle also updates quarterly. AI model weights can shift after any single API call. That speed gap — human review cadence vs. model inference updates — means G2 scores are always looking backward in a category that punishes lag.

    Use G2 to build your shortlist. Then run it through the five checks below.


    Check #1 — Does It Re-Run Queries Live, or Pull From a Cache?

    This is the most important question you can ask any AEO vendor.

    LLMs are non-deterministic by design. Even when Temperature is set to 0 — theoretically a deterministic greedy decoding mode — production API calls still produce variable outputs. The reasons are technical: floating-point rounding differences across parallel GPU threads, Mixture-of-Experts routing logic that shifts under continuous batching, and dynamic inference optimizations like prefix caching that change execution context from one call to the next.

    The practical consequence: accuracy rates for the same prompt can vary by up to 15% across runs. In extreme cases, the gap between best and worst performance reaches 70%.

    A tool that runs one query and caches the result for a week is showing you a single probability event, not your brand’s actual visibility distribution.

    Professional-grade platforms handle this with live re-runs: multiple independent queries across time windows and batching environments for the same prompt. The output isn’t a binary “mentioned / not mentioned.” It’s a probability distribution. That’s Visibility Tracking done correctly.
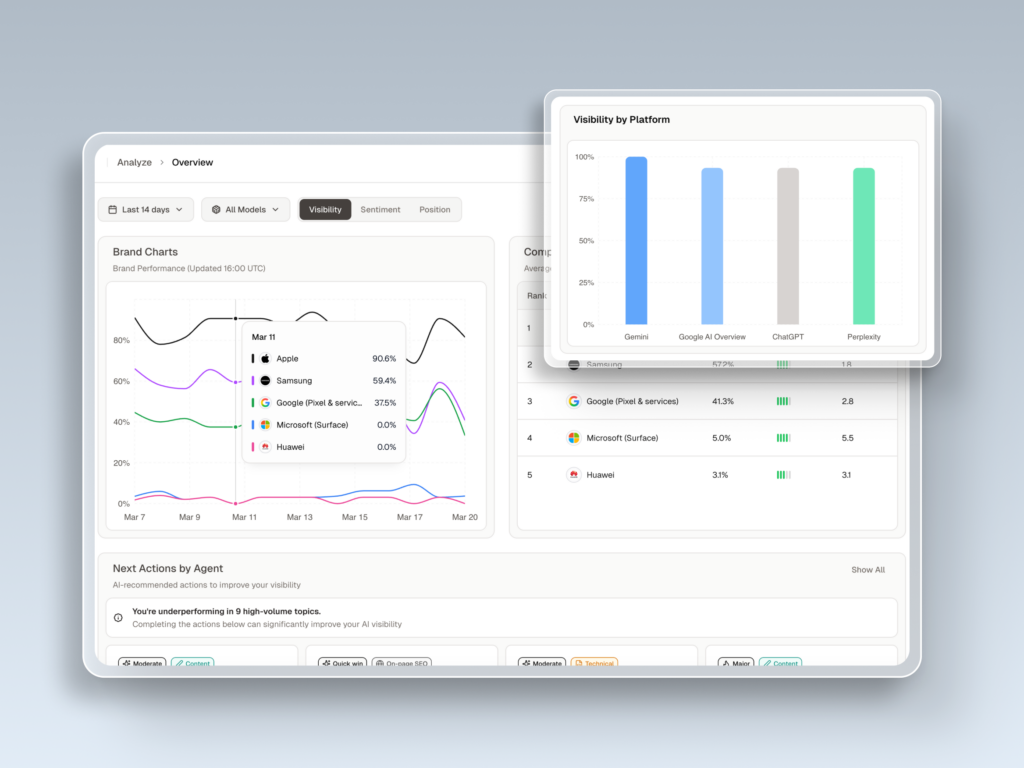
    When you’re in a vendor demo, ask one question: “For a single prompt, how many independent queries do you run? How do you model variance across runs?” If the answer is vague, the data quality probably is too.


    Check #2 — How Many AI Platforms Does It Actually Cover?

    Most tools that score well on G2 were built when “AI search” meant Google AI Overviews. That’s an understandable origin, but the market has fragmented significantly since then.

    As of early 2026, ChatGPT holds somewhere between 60% and 77% of AI-driven search and discovery traffic. Google Gemini sits at roughly 15%, Microsoft Copilot at 12.5%, and Perplexity at 5.4%. Claude AI is at 5.0% but growing faster than most — up 14% quarter over quarter.

    A tool that only monitors Google AIO leaves you blind to the conversations happening in ChatGPT. That’s three out of four AI interactions you’re not seeing.

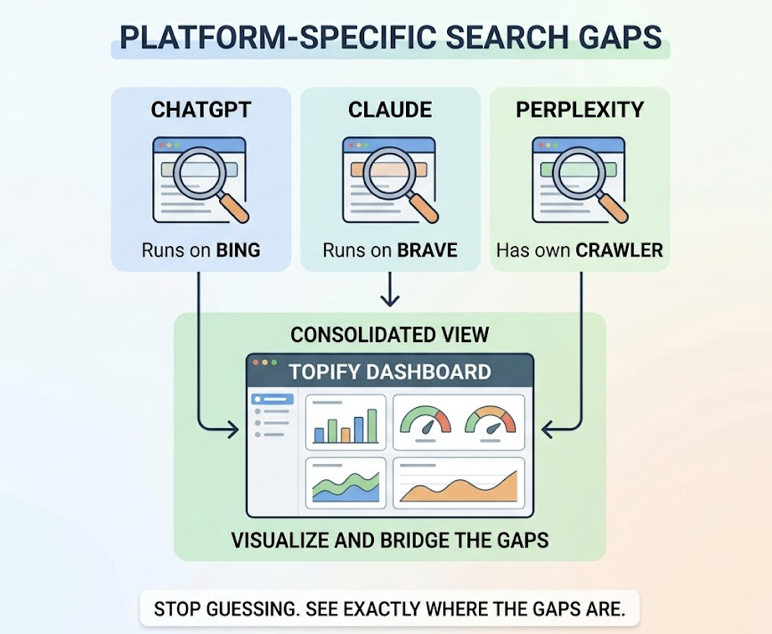
    Each platform also retrieves and cites information differently. Perplexity operates more like an AI-native search engine, relying on real-time web crawling and explicit inline citations — which is why tracking tools like Brandmentions have built dedicated Perplexity monitoring features. Google AIO correlates closely with traditional organic ranking signals. ChatGPT draws on training data, RAG retrieval, and browsing — a completely different influence model.

    You can’t optimize across platforms you can’t see.

    Topify tracks across 7+ AI platforms including ChatGPT, Gemini, Perplexity, Claude, DeepSeek, Grok, and others. For a brand with any international or multi-channel presence, that coverage isn’t a nice-to-have. It’s risk mitigation.


    Check #3 — Can It Measure Position, Not Just Presence?

    “Your brand appeared in 50% of AI answers this month.”

    That sounds positive. But if your brand appeared last in a five-item list every single time, that number is misleading you.

    Research into Answer Placement Scores (APS) shows that the first recommendation in an AI-generated list carries a weight of 1.0. The second position drops to roughly 0.6. By the third position and beyond, weight falls below 0.3 — which in a conversational context is functionally invisible. AI answers don’t come with a “see all results” button.

    Mention count without position is noise dressed up as data.

    There’s a second layer that matters equally: sentiment. AI doesn’t just list brands — it characterizes them. Being described as “a budget-friendly option with limited enterprise features” and being described as “the most reliable choice for compliance-heavy teams” are both citations. They produce opposite outcomes for your pipeline.

    Advanced platforms combine position tracking with sentiment polarity analysis, identifying not just where your brand appears but how it’s described — and whether those descriptions align with your positioning. Topify’s Competitor Monitoring surfaces both: where you rank relative to competitors on specific prompts, and when AI characterizations shift in tone.

    That’s the difference between brand monitoring and brand intelligence.


    Check #4 — Does the Data Update Daily, or Weekly?

    Google AI Overview trigger rates jumped from 25% to over 60% in 2025. For informational and educational queries, that shift drove a 61% decline in traditional organic click-through rates. The landscape isn’t just changing — it’s changing faster than most marketing teams can track.

    Three forces drive AI recommendation volatility: model provider weight updates (like OpenAI system prompt changes), real-time RAG retrieval pulling in newly published competitor content, and the compounding effect of third-party citation signals accumulating over time.

    A weekly report can’t catch any of that in time to act.

    Weekly-cadence tools are post-mortems. By the time the report lands, the ranking shift that pushed your brand out of the top position happened four days ago. A competitor published new structured content, AI picked it up within hours, and you’re already behind.

    Daily monitoring with meaningful analysis volume is what makes AEO actionable. Topify’s Basic plan supports up to 9,000 AI answer analyses per month — enough to run core prompts multiple times daily and build a visibility curve instead of a weekly snapshot. That curve is what lets a team catch a ranking drop within 24 hours of the triggering event, not after the next report cycle.

    Speed of insight is a structural advantage. Tools that can’t offer it cost you more than their subscription price.


    Check #5 — Does It Tell You What to Do Next?

    Most G2-ranked AEO tools are reporting tools. They surface data. Then they hand you a dashboard and leave the execution entirely to your team.

    Here’s what that actually looks like in practice: your team sees a visibility gap, manually re-analyzes keyword intent, rewrites content in an answer-first structure, updates the CMS, and then needs to build third-party citations on Reddit, LinkedIn, and Quora to generate the signal AI models actually prioritize. Each of those steps introduces lag. Each step is where strategies stall.

    Data without execution is just a more expensive form of anxiety.
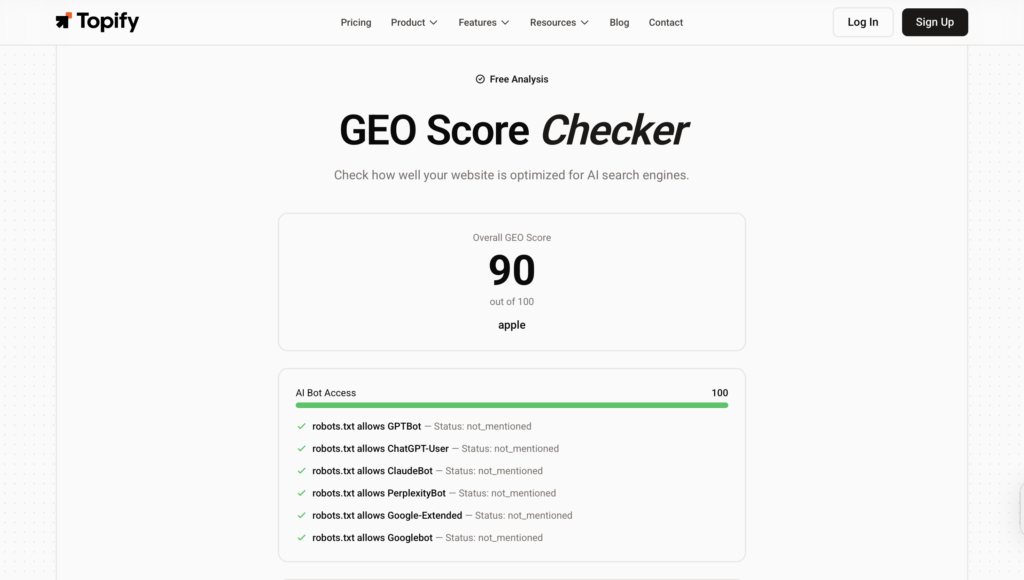
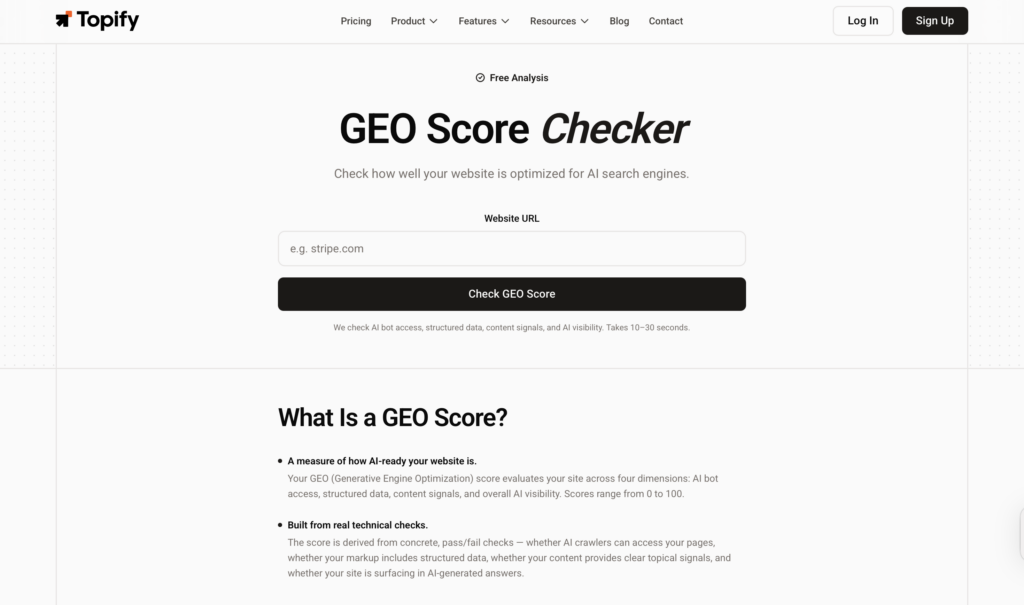
    The next category of AEO platforms closes that loop. Topify’s GEO Score Checker evaluates existing pages against specific AI platform retrieval preferences in real time. Its One-Click Execution takes those insights and deploys optimized content — structured answers, schema markup, entity signals — directly through CMS integrations, without a manual rebuild workflow.
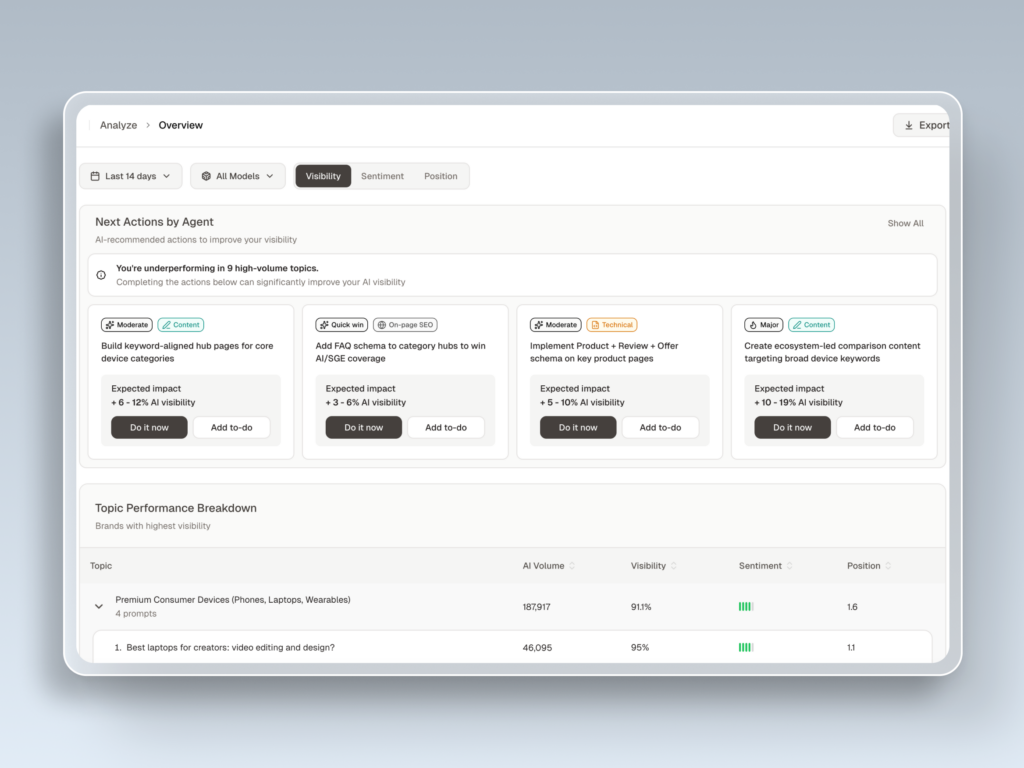
    Most tools stop at data. That’s where the real work begins.

    That gap between reporting and executing is the clearest product-generation difference in the AEO market right now. It’s also the one you’ll never spot on a G2 listing page.


    How to Use This Framework on G2 Right Now

    G2 is still a useful discovery funnel. The problem isn’t where you start — it’s where you stop.

    When you’re on a vendor’s G2 listing page, look past the star rating and check for these signals: does the feature list mention “LLM tracking,” “entity extraction,” or “generative AI optimization” specifically — not just generic “SEO”? Do their customer case studies reference AEO-specific KPIs like Citation Share or Answer Placement Score, or are they still talking about keyword rankings and backlinks? Search the review text for words like “accuracy,” “real-time,” and “caching” — user frustration about data lag often shows up there before it shows up in the aggregate score.
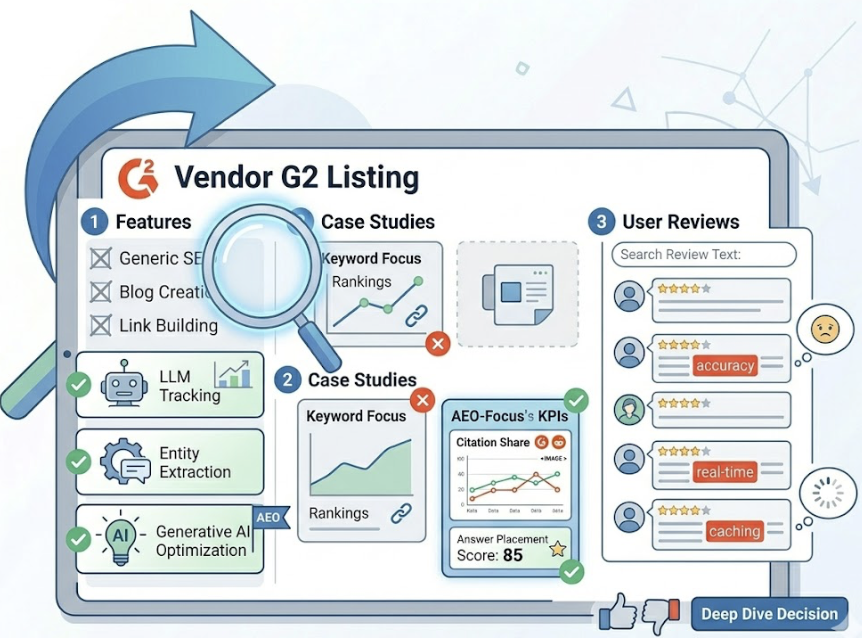
    In a demo or trial, three questions will tell you everything:

    Ask how they handle LLM non-determinism: do they run multiple queries per prompt, and what’s their variance modeling methodology? Ask whether they can distinguish between a positive brand mention with no link and a negative mention with a link in terms of sentiment scoring. Ask whether they have a direct path from insight to content deployment — not just a report, but an execution workflow.

    Here’s how the five dimensions stack up across tool types:

    Evaluation DimensionTopifyTypical G2 High-Scorer
    Data CollectionLive multi-run queries, variance modeledAPI cache or static snapshot
    Platform Coverage7+ platforms including DeepSeek, GrokUsually Google AIO or one other
    Measurement DepthAPS position + sentiment + entity associationBasic mention count
    Update FrequencyDaily monitoring, 9,000+ analyses/moWeekly or monthly reports
    Execution CapabilityGEO Score + one-click CMS deploymentReport only, manual follow-through

    Conclusion

    G2 is where you discover tools. It’s not where you evaluate them.

    AEO is a category where the underlying technology runs on probabilistic systems that change faster than human review cycles can track. The tools that look good on a satisfaction survey may be the same ones feeding you cached snapshots from a week ago and calling it a visibility score.

    The five checks above aren’t exhaustive. But they force the right conversations — about data collection methodology, platform coverage, position granularity, update cadence, and execution capability. Those are the questions that separate a dashboard from a platform that actually moves your brand in AI answers.

    See it work, then test it on your own brand. Explore how Topify handles these exact dimensions on the platform, or run your own brand through the GEO Score Checker for free before committing to anything.


    FAQ

    Q1: What does AEO mean on G2? 

    On G2, AEO (Answer Engine Optimization) typically sits within the SEO or AI marketing software categories. It refers to tools that help brands get cited directly by AI assistants like ChatGPT and Gemini, and AI search engines like Perplexity and Google AI Overviews, rather than just ranking in traditional blue-link results.

    Q2: How is AEO different from traditional SEO tools? 

    Traditional SEO optimizes for clicks on indexed links. AEO optimizes for citations and mentions in AI-generated answers. The signals that matter are different: entity authority, structured content readability, answer-first formatting, and third-party citation signals — not just keyword density or backlink count.

    Q3: What’s the most important feature to check in an AEO tool? 

    Data collection robustness. If a tool can’t demonstrate how it handles LLM output variance — ideally through live multi-run query execution — then the visibility numbers it produces aren’t reliable. After that, execution capability: a tool that only reports without offering an optimization workflow shifts the labor cost to your team without reducing it.

    Q4: Can I trust G2 ratings for AEO tools? 

    Partially. G2 is a useful discovery layer and reflects genuine user satisfaction around UI and support quality. What it doesn’t capture is algorithmic depth, real-time data accuracy, or the technical ability to handle non-deterministic AI outputs. Most reviewers on G2 are evaluating AEO tools through a traditional SEO lens, which means the ratings reflect a different set of priorities than what the category actually requires.
    Read More

  • Your GEO Score Is Useless Without This 5-Step Workflow

    Your GEO Score Is Useless Without This 5-Step Workflow

    Most brands run a GEO score check and stop there.

    They see a number, screenshot it, maybe share it in a Slack channel, and then… nothing. No action, no follow-through, no visible change in how often AI systems actually recommend them.

    That’s the gap most brands still can’t see. A GEO score isn’t a result. It’s a starting point. And without a structured workflow to act on it, the score is just a data point collecting dust.

    This guide walks through the five-step process that turns a GEO score into real AI citations — the kind that show up in ChatGPT, Gemini, and Perplexity responses when your ideal customers are making decisions.

    Step 1. Run Your GEO Score Check Before You Touch Anything Else

    The single most common mistake in GEO programs is optimizing without a baseline. Teams start producing content, updating schema, and chasing citations — all before they know where they actually stand.

    In a stochastic environment like large language models, that’s expensive guesswork.

    A GEO score check establishes the baseline your entire optimization strategy depends on. It measures how likely your brand is to be cited and recommended by platforms like ChatGPT, Gemini, and Perplexity — not as a single number, but as a weighted composite across six technical and qualitative dimensions:

    AI Bot Access is the binary foundation. If your robots.txt blocks crawlers like GPTBot, OAI-SearchBot, ClaudeBot, or PerplexityBot, you’re invisible to the retrieval-augmented generation (RAG) systems powering real-time AI search. Everything else in your GEO strategy becomes irrelevant.

    Structured Data measures your JSON-LD schema implementation. Schema acts as a machine-readable identity card — it helps AI engines resolve entities and understand relationships without relying on natural language interpretation.

    Visibility tracks how often your brand appears in responses for a set of high-intent industry prompts. This is your Share of Model: the percentage of relevant AI answers where your brand gets a mention.

    Sentiment evaluates how AI characterizes your brand when it does mention you. “Leading solution” and “budget alternative” are both citations — but one drives purchase intent and one doesn’t.

    Position measures where you appear in the generated answer. A first-position mention carries 32% higher purchase intent than a fourth-position mention, according to generative search research.

    Source Coverage tracks the diversity of third-party platforms citing you. AI models are 6.5 times more likely to recommend a brand when multiple independent sources — Reddit, Wikipedia, industry publications — corroborate its authority.

    Without this baseline, marketing teams can’t distinguish between a temporary model fluctuation and a systemic failure in their content strategy. The Topify GEO Score Checker runs this diagnostic across all six dimensions and surfaces exactly where the gap is.

    Step 2. Your GEO Score Masks More Than It Reveals — Find the Weak Dimension

    An aggregate score of 88/100 sounds like “excellent.” It’s often not.

    A brand can score well in technical SEO and AI bot access while remaining invisible for every high-intent buying prompt. The overall number smooths over the specific dimension that’s actually dragging performance. That’s where teams waste months optimizing the wrong things.

    The diagnostic work in Step 2 is about peeling back the aggregate to find the single weakest dimension. Each dimension has a different failure pattern:

    DimensionWhat It SignalsHow to Spot It
    SentimentAI describes your brand negatively or neutrallyHigh visibility, low conversion; AI frames you as “expensive” or “complex”
    PositionFrequent mentions, but always at the bottom of listsCitations exist, but competitors are named first every time
    Source CoverageAI only pulls from your own domainZero citations from Reddit, news media, or third-party review sites
    CVRPresent for informational queries, absent for decision-stage promptsMentioned in “what is X” answers, not in “best X for Y” answers

    The recommendation here is counterintuitive: don’t try to fix everything at once. In an LLM environment, shifting too many variables simultaneously makes it impossible to attribute improvements to specific actions. Pick the single most underperforming dimension and run a targeted remediation before touching anything else.

    Step 3. Don’t Optimize Blindly — Build a Prompt-Specific Action Plan

    GEO optimization is not about producing more content.

    It’s about producing content that satisfies the specific retrieval requirements of the engines. Once you’ve identified your weak dimension from Step 2, the response needs to be targeted — not generic.

    Different weaknesses require fundamentally different fixes:

    Source Coverage deficit: If AI engines only cite your own domain, you have a third-party validation problem. AI systems use something functionally similar to consensus scoring. The fix is earned media and digital PR — securing mentions on Reddit, industry publications, and third-party listicles. Off-site signals are often more effective than any on-page change.

    Sentiment deficit: If you’re described as “known for complex setup” or “better for enterprise,” the action plan involves publishing content that directly counters that narrative with evidence. Case studies with specific metrics. Review platform signals from G2 or Trustpilot. AI models synthesize these sources when forming their characterizations.

    Position deficit: Research shows that 44.2% of AI citations come from the first 30% of a page’s content. To move from trailing mention to top recommendation, content must lead with a 40-60 word direct answer to the prompt — not a long intro that buries the key information.

    The execution gap is where most teams stall. Identifying the fix is one thing. Deploying it across multiple content properties, updating schema, coordinating between writers and developers — that’s where timelines slip by weeks.

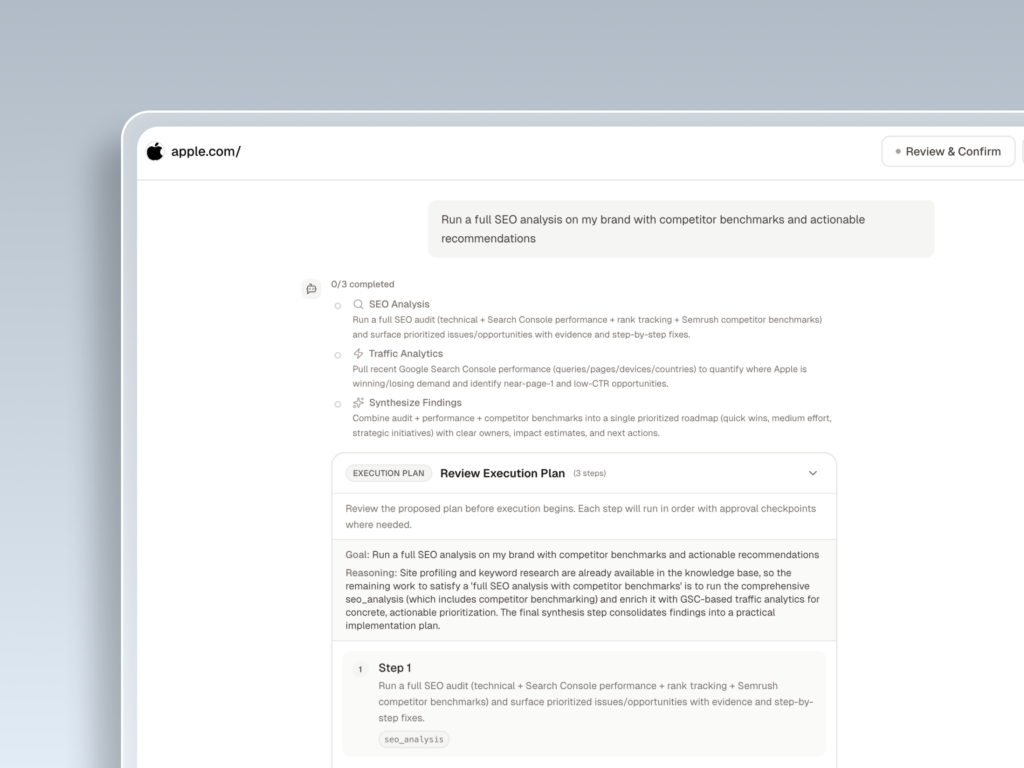
    Topify’s One-Click Agent addresses this directly. Define your goal in plain language, review the proposed strategy, and deploy with a single click. The agent handles monitoring, gap detection, content formulation, and direct publishing to your CMS — without requiring manual coordination across teams.

    Step 4. Track AI Citations — Not Just Rankings

    Here’s what traditional SEO metrics miss entirely: a page can rank #1 on Google and never get cited by ChatGPT.

    Ranking and citation are different signals. Generative engines don’t pull from the top of a search index — they pull from content that satisfies the structural requirements of retrieval-augmented generation. A page that ranks well but lacks factual depth, structured data, or third-party corroboration is invisible in AI answers.

    That’s why AI citation frequency is the North Star metric for the modern search marketer — not rankings, not impressions.

    Citations are the mechanism that preserves the revenue pathway in a zero-click world. While a mention builds awareness, a clickable citation is what drives high-converting referral traffic. Research shows that content incorporating authoritative citations, direct quotes, and relevant statistics achieves 30-40% higher visibility in generative engine responses.

    Different platforms also have different citation behaviors:

    PlatformCitation PatternWhat to Prioritize
    ChatGPT3-5 sources; favors high-authority editorial sitesEncyclopedic, factual depth
    Perplexity5-12 sources; heavy focus on recency and original dataMonthly updates and data-dense reports
    Google AIOFavors answer-first snippets from top rankingsTechnical SEO foundation + direct answers
    GeminiTrusts institutional sources (.gov, .edu) over UGCExpert authorship and credentials

    Tracking these citation patterns manually across four platforms is not realistic for any marketing team. Topify’s AI Visibility Tracker queries actual AI platforms and reads real-time responses to determine your Share of Voice. It identifies the specific trigger keywords that cause an AI to mention your brand — and detects the visibility gaps where you should be present but currently aren’t.

    That’s the data that informs every decision in the next step.

    Step 5. Iteration Is the Product — Set a 30-Day Feedback Cadence

    AI search is not a set-and-forget environment. LLMs update constantly. Search indices are dynamic. Content cited yesterday may be ignored by next week.

    Freshness is a primary citation signal. Pages updated within the last 14 days are cited 2.3 times more frequently than pages untouched for 60 or more days. After 90 days without updates, citation rates typically plateau at 40% of their initial peak.

    Update CadenceCitation Probability
    Continuous (Monthly)100% baseline maintained
    One-Time Optimization-60% decay within 3 months
    Biannual RefreshSignificant visibility gaps

    The implication is clear: GEO is an ongoing system, not a campaign. The brands winning AI citations aren’t the ones who ran the best one-time optimization. They’re the ones who built a repeatable monthly cadence.

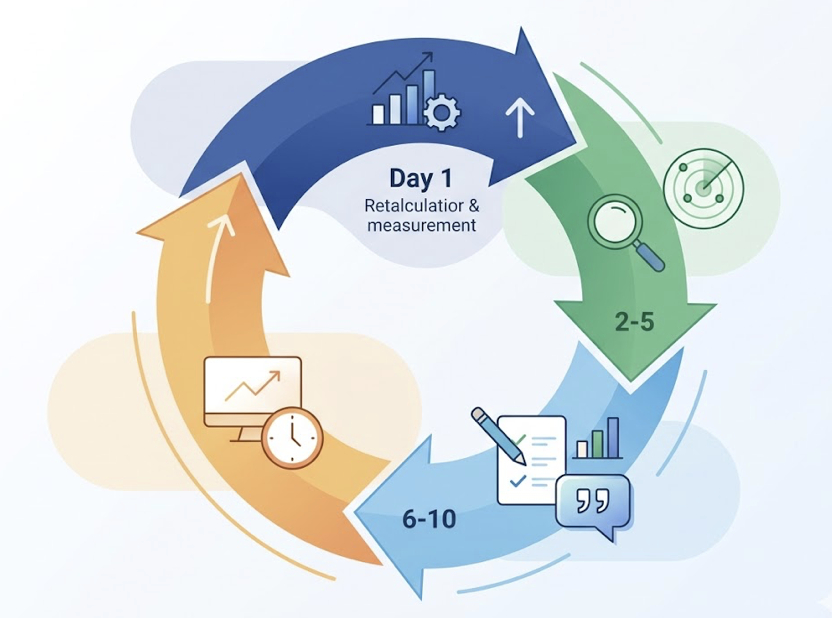
    A 30-day feedback loop looks like this: re-run your GEO score on Day 1 to capture any shifts. Spend Days 2-5 analyzing new weak dimensions or emerging competitor threats. Use Days 6-10 to execute — update content, add statistics, refresh expert quotes. Then monitor recovery metrics through the rest of the cycle and prepare for the next iteration.

    Topify’s AI Agent automates the execution layer of this loop. It continuously monitors your brand’s presence, identifies when citation rates drop, and proactively deploys fixes without requiring a manual trigger. You define the goals; the system handles the cadence.

    Why Most Teams Get Stuck After Step 1

    The gap between brands winning at GEO and those falling behind isn’t usually a matter of effort. It’s a matter of integration.

    Most marketing teams run three separate workflows: a tracking tool, a strategy planning process, and a content execution platform. These rarely talk to each other. When AI citation rates drop, the delay between identifying the problem and deploying a fix can stretch to weeks — and in an environment with a strong recency bias, that delay is expensive.

    That’s the structural problem Topify was built to solve.

    ApproachResultKey Weakness
    Score OnlyTemporary awareness of declineNo mechanism for fast recovery; manual work blocks progress
    Fragmented ExecutionInconsistent visibility across enginesHigh coordination costs; updates lag citation decay
    Topify Closed-LoopSustained citation leadershipRequires commitment to an automated, iterative workflow

    Topify is the only platform that unifies AI search tracking, GEO optimization strategy, and content execution in a single system. From running your first GEO score check to publishing optimized content and monitoring real-time citation changes, the entire workflow runs in one place — without coordination overhead.

    That closed-loop structure is what separates brands that maintain AI visibility from those who constantly play catch-up.

    Conclusion

    A GEO score tells you where you stand. It doesn’t tell you what to do next — and that’s the gap most brands don’t close.

    The five-step workflow here — baseline check, weak dimension diagnosis, targeted action plan, citation tracking, and continuous iteration — is what turns a number into a system. Each step feeds the next. And each cycle of the loop compounds on the one before it.

    In a world where 90% of B2B buyers use AI tools at some point in their purchasing journey, and AI-referred visitors convert at up to 4.4 times the rate of traditional organic visitors, the brands that build this system now are establishing a durable advantage. The ones that don’t will keep wondering why their score looks fine but no one’s citing them.

    FAQ

    What is a GEO score and how is it calculated? 

    A GEO score measures a website’s readiness for AI search engines. It’s calculated using a weighted methodology across six dimensions: AI Citability (25%), Brand Authority (20%), Content E-E-A-T (20%), Technical SEO (15%), Schema Markup (10%), and Platform Readiness (10%).

    How often should I check my GEO score? 

    Weekly for high-competition industries; monthly at a minimum for others. Citation frequency drops significantly after 30 days without updates, so a monthly check is the baseline for maintaining visibility.

    What is a good GEO score? 

    A score of 70 or above is considered good. Scores of 85 or above indicate that AI engines likely treat your brand as a primary source of authority for relevant prompts.

    Can I improve my AI citations without changing my website? 

    Yes. Off-site signals carry significant weight. Increasing your Source Coverage by securing mentions on Reddit, Wikipedia, and authoritative third-party media is often more effective than on-page changes alone.

    How long does it take to see results after GEO optimization? 

    Changes targeting real-time engines like Perplexity can appear within hours or days. For indexed engines like ChatGPT or Google AI Overviews, meaningful improvement typically takes 3 to 8 weeks.

    Read More

  • GEO Score Benchmarks 2026: How Does Your Site Stack Up?

    GEO Score Benchmarks 2026: How Does Your Site Stack Up?

    You ran the GEO Score check. Got a 54. Now what?

    A number without context isn’t a metric, it’s noise. The only way to know whether 54 means you’re ahead of the curve or quietly falling behind is to compare it against what’s actually happening in your industry. That’s what this benchmark report is for.

    What Your GEO Score Is Actually Measuring

    Before the numbers, a quick clarification: a GEO score measures your site’s content-level readiness to be ingested and cited by AI engines. It’s not a real-time tracker of whether ChatGPT mentioned you this morning. Think of it as an audit of your structural health, not a live performance report.

    The score pulls from four core dimensions:

    AI bot access checks whether crawlers like GPTBot, ClaudeBot, and PerplexityBot can actually reach your content. Many legacy sites unknowingly block these agents via outdated robots.txt files, or serve JavaScript-rendered pages that AI crawlers can’t parse.

    Content clarity measures how well your pages are broken into self-contained, fact-dense blocks. AI engines don’t consume full pages. They retrieve chunks. A page that reads as one long wall of text has low “extractability” regardless of how well-written it is.

    Authority signals track E-E-A-T indicators: verifiable statistics, original research, expert attribution. Princeton University research found that adding statistics can drive a 37% increase in AI visibility, while citing authoritative sources can lead to a 115% boost for lower-ranked pages.

    Citation-friendliness assesses structured data presence, specifically JSON-LD schema, FAQPage markup, and whether the site has deployed an llms.txt file to guide AI crawlers toward priority content.

    The 2026 GEO Score Scale

    Score RangeStatusWhat It Means
    0–39Foundational DeficiencyCritical technical gaps; AI crawlers blocked or content unparseable
    40–60Industry AverageMost sites land here; basic SEO present but not AI-optimized
    61–74Conscious OptimizationActive GEO attempts; inconsistent schema and structure
    75–84High AI ReadinessStrong E-E-A-T signals; frequent FAQ schema; RAG-friendly content
    85+EliteProactively designed for AI; dominant entity authority; systemic schema

    A score above 70 is considered good. Above 85 is where the leaders actually live.

    To get your baseline, the Topify GEO Score Checker runs a standardized technical audit across all four pillars and maps results to actionable recommendations.

    GEO Score Benchmarks by Industry in 2026

    Here’s where the data gets useful. Performance varies significantly by sector, and the gap between average and leading brands tells you exactly what’s winnable.

    B2B SaaS: Technical Depth, FAQ Gaps

    MetricBenchmark
    Average GEO Score52–58
    Leading Brand Score72–80+
    AI Referral Share2.80% (highest tracked)
    Primary GapsTechnical doc structure, FAQ coverage, schema completeness

    B2B SaaS companies start with an advantage: high-density informational content, which is exactly what AI engines prefer. The problem is that most of that content is written for humans scanning a features page, not for AI systems retrieving a specific answer chunk.

    The brands sitting at 72+ have restructured their help centers and technical documentation to mirror conversational prompts. One common pattern: using sameAs links in schema to anchor product entities to GitHub, G2, or LinkedIn, creating a “consensus signal” that AI engines use to verify brand claims.

    The most common gap at the average band (52–58)? FAQ content that answers generic questions instead of the specific, comparison-oriented questions your buyers are actually asking AI assistants.

    E-commerce: Thin Pages, Weak UGC Signals

    MetricBenchmark
    Average GEO Score44–52
    Leading Brand Score68–76
    AI Overview Presence6.80%
    Primary GapsThin product descriptions, no comparative data, weak UGC

    E-commerce has the steepest hill to climb. Most product pages are built for visual browsing. AI agents do attribute-based retrieval. Those aren’t the same task.

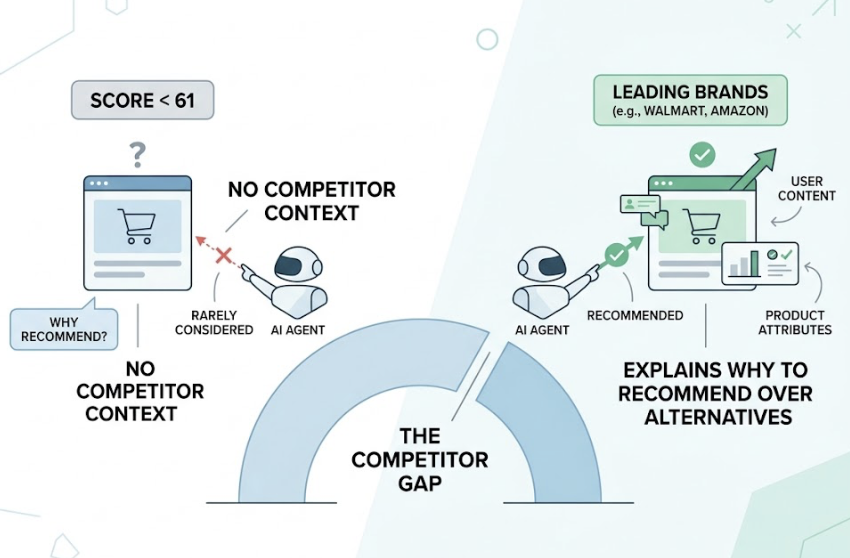
    Pages scoring below 61 are rarely considered by AI agents for purchase recommendations. Leading brands like Walmart and Amazon maintain high scores by combining massive user-generated content with detailed product attribute schemas. The gap for smaller retailers is specific: they don’t explain their product’s relationship to competitors. AI engines struggle to cite a product page that doesn’t tell them why to recommend it over alternatives.

    Comparison-oriented content, “X vs. Y” pages, detailed attribute breakdowns, verified review data, is what separates a 52 from a 72 in this sector.

    Media and Publishing: The Citation Architecture Problem

    MetricBenchmark
    Average GEO Score58–65
    Leading Brand Score80–88
    Primary GapsUnstructured citations, poor AI summary friendliness

    Publishers start with a natural advantage: content density. That’s why their average scores are higher than most other sectors. But they’re increasingly penalized for what might be called disorganized citation architecture.

    The primary differentiator for leading publishers is the “Bottom Line Up Front” (BLUF) writing structure. AI engines prioritize pages where the first 60 words directly answer the primary question. Many editorial teams write in the opposite direction: context, background, then the point.

    The other issue is a dual-optimization trap. Teams are trying to hold traditional SEO rankings while simultaneously improving AI citation probability, and without a unified framework, both suffer.

    Local Services: The Knowledge Graph Crisis

    MetricBenchmark
    Average GEO Score38–48
    Leading Brand Score60–70
    AI Overview Presence4.40% (lowest across sectors)
    Primary GapsNo structured data, thin content, missing Local Knowledge Graph signals

    Local services, legal, medical, home maintenance, consistently hold the lowest GEO scores in 2026. AI assistants frequently avoid citing local providers because their information (pricing, availability, specific expertise) isn’t provided in a verifiable, structured format.

    That’s a fixable problem. Leading local brands have built what you might call “Knowledge Hubs”: pages dedicated to answering specific, non-transactional questions rooted in their market. Think “Why does tap water taste different in [City]?” rather than “Hire us for water treatment.” These pages establish local authority in AI training data in a way that a service page never will.

    What Brands Scoring 85+ Are Actually Doing

    Getting above 85 isn’t a volume game. It’s a structure game. These brands have stopped thinking about “writing more content” and started thinking about their site as a data layer for the generative web.

    Systemic schema markup. Average sites use basic Article schema. Elite brands implement deeply nested JSON-LD across Organization, FAQPage, HowTo, and WebApplication schemas. The sameAs attribute links brand entities to Wikipedia, Wikidata, and Crunchbase, creating external verification that AI engines treat as a credibility signal.

    FAQ content designed for extraction. Pages with FAQPage schema see a 3.1x higher AI citation rate compared to equivalent pages without it. The format that works: a “Question-Answer-Evidence” (QAE) structure where every answer stays under 100 words, making it easy for an LLM to chunk and synthesize without losing the core claim.

    Proactive third-party authority building. Elite-scoring brands don’t rely only on their own domains. They know AI models weight earned media more heavily than owned content. Perplexity in particular draws heavily from Reddit. A substantive mention in a trusted community can serve as a 2.1x multiplier for AI citation probability. Publishing original data matters too: unique statistics can boost AI visibility by up to 40%.

    Your Score Is a Snapshot. Your Strategy Needs More.

    Here’s the part most GEO score reports skip: a high score doesn’t guarantee you’re actually getting cited.

    The GEO score measures citability, meaning the content is formatted correctly for retrieval. Actual citations in AI answers depend on external authority, recency, and how your “information gain” compares to competitors at that specific moment. A brand can have an 85+ score and still see low citation rates if a rival has higher information density on the same topic.

    AI engines are also non-deterministic. The same prompt can produce different citations at different times. That’s why the score serves as a baseline, but real-time citation tracking is the strategy.

    Tracking your GEO score in isolation can also create a blind spot: your score might climb from 50 to 70, but if the industry average moves to 75 in the same window, you’ve lost relative ground while feeling like you improved. That’s the case for placing your score inside a competitive context.

    Topify’s competitor benchmarking tracks Share of Voice across ChatGPT, Gemini, and Perplexity, so you can see not just your absolute score, but how your citation frequency compares to the top brands in your category. The score tells you if you’re ready. The competitive data tells you if you’re winning.

    How to Close the Gap: A 3-Step Framework

    Step 1: Detect your current baseline. Start with a full technical audit using the Topify GEO Score Checker. Map where you sit against the industry benchmarks above. The audit should also surface a “Citation Gap Analysis” showing which prompts are sending users to competitors instead of you.

    Step 2: Restructure for retrieval. This is less about adding keywords, more about increasing factual density. Rewrite the opening 60–100 words of key pages to lead with a direct answer (BLUF optimization). Deploy FAQPage and Organization schema with sameAs links. Use sequential H2-H3-H4 heading structures to help AI engines understand your semantic hierarchy.

    Step 3: Track and iterate. AI citation data decays. Research suggests it drops to roughly 40% of its initial level within 90 days. That means a one-time optimization isn’t a strategy. Weekly monitoring of how content updates influence visibility across platforms, combined with ongoing prompt research, keeps you from falling back below your industry benchmark after a single algorithm shift.

    Conclusion

    Most brands are scoring somewhere between 40 and 60. That’s not a failure, it’s where the industry currently sits. But the gap between 54 and 75+ is real, and it’s not bridged by writing more. It’s bridged by structuring differently: tighter schema, BLUF formatting, FAQ content designed for extraction, and third-party authority signals that give AI engines a reason to trust your content over a competitor’s.

    The score is the starting line. Use the Topify GEO Score Checker to find your baseline, then move from static readiness into active citation tracking with Topify’s competitive benchmarking to see where you actually stand in your industry’s AI search landscape.

    FAQ

    Q: What is a good GEO score in 2026? 

    A: A score above 70 is considered good, meaning your site is well-optimized and likely to be cited by AI engines. A score above 85 is excellent and characteristic of brands that have systematically designed their content for AI retrieval.

    Q: How often should I check my GEO score? 

    A: At minimum, run a full audit monthly. High-priority pages should be reviewed weekly, since AI model updates and competitor content changes can shift citation patterns quickly. Citation data tends to decay significantly within 90 days of any optimization.

    Q: Does a high GEO score guarantee AI citation? 

    A: No. A high score means your content is formatted correctly for retrieval. Actual citations depend on external authority, content recency, and how your information compares to competitors on a given topic. Real-time tracking is required to measure actual citation performance.

    Q: Which industry has the lowest average GEO score? 

    A: Local services currently holds the lowest average (38–48), largely due to widespread lack of structured data and thin content that doesn’t provide the localized, verifiable signals AI engines need to confidently recommend a provider.

    Read More

  • Your GEO Score Is Low. Here’s What to Fix First.

    Your GEO Score Is Low. Here’s What to Fix First.

    You ran the numbers. Your GEO score came back lower than expected, and now you’re looking at four dimensions wondering which one to actually fix first. Most teams pick the easiest one, or the one that sounds most familiar. That’s usually the wrong call.

    GEO score improvement isn’t about effort volume. It’s about fix order. The four dimensions interact, and optimizing Visibility before fixing Authority is roughly equivalent to running ads to a page that doesn’t load. The sequence matters. So does knowing which problems inside each dimension show up most often, and which ones move your score the most.

    Before anything else: if you haven’t run a baseline check yet, use the Topify GEO Score Checker to get your dimension-level breakdown. The fixes below are organized to match exactly what you’ll see in that report.

    The Fix Order That Actually Moves Your GEO Score

    Not all four dimensions carry equal weight. Research into AI citation patterns shows a clear hierarchy:

    DimensionRole in GEOFix Timeline
    AuthorityPrerequisite: AI won’t cite what it can’t verify3–6 months (compounds)
    Content RelevanceLever: fastest scoring gains once entity is established30–45 days
    SentimentFilter: blocks recommendations even with strong visibility60–90 days
    VisibilityOutcome: the measure, not the mechanismOngoing

    The logic is this: LLMs run an entity resolution check before they surface any content. If the model can’t confirm who you are through third-party corroboration, your on-site optimization goes to waste. That’s why Authority is the prerequisite. Content Relevance is where you gain fast ground once the model recognizes your entity. Sentiment is the last filter before a recommendation is made. Visibility is what you measure, not what you directly control.

    Work top to bottom. Here’s what breaks in each dimension, and how to fix it.

    Dimension #1 — GEO Authority: The Prerequisite You Can’t Skip

    Authority in GEO isn’t about domain rating or backlink count. It’s about what AI systems call “entity confidence”: how consistently and how broadly your brand is described across independent sources. Research shows that unlinked brand mentions are 3x more predictive of AI visibility than traditional backlinks, with a correlation coefficient of +0.664 compared to backlinks, which show roughly -70% predictive correlation with AI citation rates.

    This is the dimension most teams underestimate, because it looks nothing like traditional SEO.

    Problem 1: AI Platforms Can’t Find Credible Third-Party References About You

    When AI models lack external validation for a brand, they become “cautious” by design. The model defaults to recommending established competitors instead. The mechanism behind this is what researchers call the “Consensus Mechanism”: if multiple unrelated sites describe a brand in similar terms for the same use case, the AI treats this as established consensus and cites accordingly.

    Fix: Shift from link-building to entity seeding. Identify the trade publications, news outlets, and niche forums that AI platforms use as grounding sources, and secure genuine placements there. A single mention in a Tier 1 outlet carries more signal than dozens of low-authority blog links, because AI models apply “epistemic rigor” when evaluating source quality. Start with 5–10 unlinked mentions in industry-specific publications to establish a Trust Neighborhood.

    Problem 2: Your Brand Isn’t Present in High-Authority Training Sources

    Wikipedia accounts for roughly 16–48% of ChatGPT’s citation weight, depending on the query type. It isn’t just a search result for LLMs. It functions as the instruction manual that AI systems use to categorize and verify entities. Brands that are absent from Wikipedia and Wikidata carry structural ambiguity that suppresses citation rates.

    Fix: Build a proactive presence management strategy. This includes ensuring your brand or methodology has a Wikidata entry with proper “semantic triples” (Subject → Predicate → Object) that eliminate entity ambiguity. Podcast appearances also matter here. Transcripts are increasingly indexed for RAG retrieval, and a guest appearance on a recognized industry podcast creates a verifiable, structured mention that AI systems can extract and attribute.

    Problem 3: All Your Citations Point Back to Your Own Domain

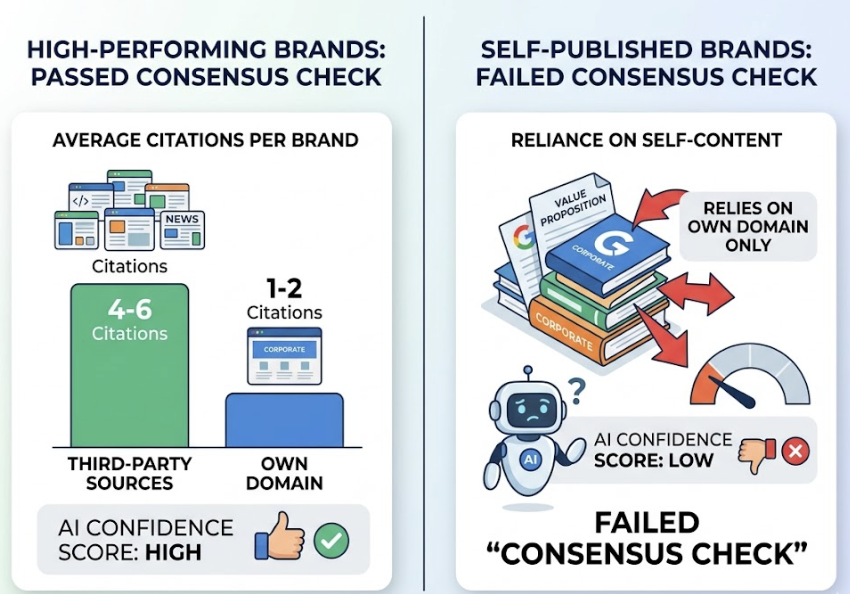
    Research from AirOps found that top-performing brands in ChatGPT average 4–6 citations from third-party sources versus only 1–2 from their own domain. Brands that rely primarily on self-published content to define their value proposition fail what’s called the “Consensus Check.” If you’re the only source making a claim about yourself, AI confidence scores stay low.

    Fix: Audit your current citation footprint. If the majority of your brand’s AI-visible content originates from your own domain, that’s the problem to solve first. Diversify through guest contributions, PR placements, co-authored reports, and genuine Reddit participation. Domain diversity is the strongest predictor of ChatGPT citation rate.

    Dimension #2 — GEO Content Relevance: The Fastest Win Available

    Once AI systems can resolve your entity, content relevance becomes the highest-leverage dimension for quick scoring gains. Structural changes here, such as reformatting existing pages and adding direct answer blocks, can show measurable improvement in 30–45 days. Authority compounds slowly. Content relevance moves fast.

    The core insight: AI systems don’t read pages the way humans do. They “chunk” content into discrete units and retrieve the chunk most likely to answer a specific sub-query. Long-form narrative with a delayed payoff fails at retrieval.

    Problem 1: Your Content Answers the Wrong Questions

    Most content teams still build around keyword volume. AI search is intent-driven, not keyword-driven. The conversational prompts being sent to AI systems today average 23–60 words, not the 3–4 word queries that defined traditional search strategy. That’s a fundamentally different type of question, and it requires different content to answer.

    Fix: Run a prompt mapping exercise against your category. Identify 500–1,000 natural-language questions that buyers ask at different funnel stages: problem discovery, solution comparison, and risk evaluation. Tools like Topify’s AI Volume Analytics can surface high-volume prompts specific to your brand and category, so you’re building content around questions AI is actually being asked, not keyword variants no one is typing anymore.

    Problem 2: Your Pages Use SEO Language, Not AI Answer Language

    Traditional SEO content is built for dwell time. The payoff often comes after several paragraphs of context-setting. In GEO, that’s a liability. AI engines favor what researchers call “Atomic Knowledge Blocks”: short, self-contained paragraphs of 40–60 words that deliver a complete idea in retrievable form.

    Research from Princeton and IIT Delhi found that adding a direct 1–2 sentence answer capsule at the top of a content section correlates with up to a 40% lift in citation frequency. Statistics embedded at roughly one data point per 150–200 words can add 31–37% visibility improvement. Expert quotes with clear attribution carry a 37–41% lift.

    Fix: Retrofit your highest-traffic pages first. Rewrite the opening 50 words of each major section as a direct “bottom-line-up-front” answer. Add a relevant statistic or expert citation. Use H2/H3 headers phrased as literal user questions. These are structural changes, not content rewrites. They can be executed at scale without a large content team.

    Problem 3: You Have Category Gaps That Competitors Are Filling

    Topical authority is the strongest predictor of AI citation, with a correlation coefficient of r=0.41, significantly outperforming domain authority (r²=0.032). Pages in positions 6–10 with strong topical coverage are cited 2.3x more than pages in position 1 with thin or scattered content. Ranking high doesn’t protect you if a competitor owns the semantic depth.

    Fix: Run a discrepancy audit. Identify high-intent prompts in your category where competitors are being cited and you’re absent. Priority targets are “Best [category] for [use case]” and “Compare X vs Y” style queries. Use Topify’s Source Analysis to see exactly which domains AI platforms are citing in your category, and map your content coverage against those gaps.

    Dimension #3 — GEO Sentiment: The Silent Score Killer

    Sentiment is where GEO diverges most sharply from traditional SEO. A search engine ranks a technically sound, high-backlinked page without reading it for tone. A language model does read it, and it makes a judgment about favorability before deciding whether to recommend.

    If your brand is associated with negative signals in training data or in actively crawled sources, the model may exclude you from “Best” recommendations entirely, or include you with cautionary framing. That’s not a ranking issue. It’s a sentiment issue, and it won’t respond to on-site optimization.

    Problem 1: Negative Third-Party Content Is Being Surfaced Repeatedly

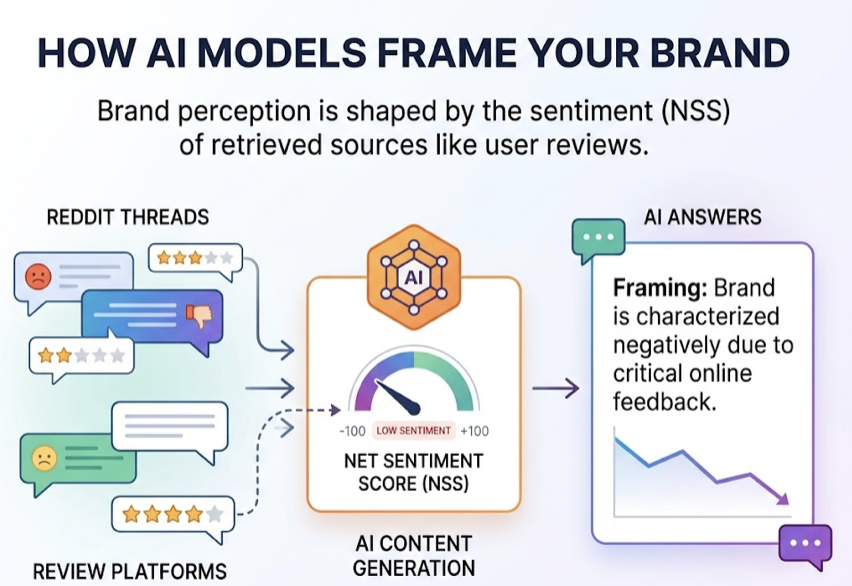
    Roughly 85% of AI brand narrative is constructed from third-party domains, not your own website. If critical forum threads, outdated crisis reports, or negative review patterns are being repeatedly surfaced by AI engines, you have an input problem. AI systems don’t fabricate sentiment. They resolve conflicting inputs, and if the majority of external sources frame your brand in negative terms, that becomes the stated consensus.

    Fix: Signal dilution, not suppression. You can’t optimize away negative sentiment. The fix is making meaningful, verifiable changes and then generating fresh, positive third-party coverage at volume to shift the overall signal. Reddit is worth specific attention here. It’s the most-cited UGC platform in most AI environments, and authentic participation in relevant subreddits can build authoritative, positive context that dilutes older negative threads.

    Problem 2: AI Describes Your Brand in Neutral or Vague Terms

    Neutral isn’t safe. If an AI describes you as “one option to consider” or uses vague generic framing, it means the model can’t confidently assign your brand to a specific audience or differentiated use case. This is called Brand Drift, and it typically results from inconsistent positioning across your digital touchpoints.

    Fix: Entity hygiene. Audit your brand’s name, category, and primary differentiator across your website, LinkedIn, Crunchbase, G2, social profiles, and any other indexed properties. These descriptors should be identical, not just similar. When multiple sources use the same language to describe your brand, the model’s confidence score rises and the framing becomes consistent and specific rather than vague.

    Use Topify’s Sentiment Analysis feature to monitor the exact adjectives and descriptors AI platforms are currently associating with your brand. You can’t fix drift you can’t measure.

    Dimension #4 — GEO Visibility: Present, But Not Prominent

    Visibility is the output dimension, not an input. It measures “Share of Model” (SoM): how often and how prominently your brand appears across a test set of high-intent prompts. Teams that try to optimize Visibility directly, without fixing the upstream dimensions, tend to see marginal gains at best.

    That said, once the foundation is in place, two problems account for most of the gap between brands that appear and brands that get recommended.

    Problem 1: You Show Up in AI Answers, But Not in First Position

    First-position mentions in AI responses aren’t just more visible. Research shows they capture up to 74% of user attention in Perplexity-style roundups, and they set the framing context for every other recommendation in the response. Being mentioned fifth in a list is functionally different from being mentioned first.

    Fix: Analyze the content characteristics of the brands holding first position in your category. AI models preferentially recommend brands they can describe with the highest density of verifiable data: specific pricing, documented outcomes, concrete comparison points. If a competitor owns a label like “best for enterprise teams,” displacing them requires a deliberate comparison matrix strategy that introduces specific, AI-verifiable attributes they don’t have.

    Topify’s Competitor Monitoring shows you exactly which brands are holding first-position recommendations in your target prompts, and what signals they’re carrying that you currently aren’t.

    Problem 2: You’re Strong on One Platform, Invisible on Others

    Only 11% of domains are cited by both ChatGPT and Perplexity, because the platforms rely on different underlying indices. ChatGPT Search favors Wikipedia and news sites through the Bing index. Perplexity leans toward Reddit and real-time content with a strong 30-day recency bias. Google AI Mode correlates most strongly with top-10 organic rankings. Claude applies a high bar for academic and research-grade sources.

    A brand can have strong Perplexity visibility through fresh, Reddit-corroborated content and near-zero ChatGPT visibility due to weak foundational authority signals.

    Fix: Cross-platform visibility testing. Run your core prompts across multiple AI platforms and map where you appear and where you don’t. That pattern tells you what’s missing: recency signals, foundational authority, or organic ranking health. Topify’s Visibility Tracking covers ChatGPT, Gemini, Perplexity, DeepSeek, and others, so you can see your cross-platform Share of Model in a single view instead of testing manually.

    Conclusion

    The dimension breakdown exists for a reason. Total GEO score is a lagging indicator. It tells you where you ended up, not where to push. The four dimensions tell you what to fix, and the sequence tells you what to fix first.

    Start with Authority. Build entity confidence through third-party corroboration before anything else. Once the model recognizes your brand as a verifiable entity, Content Relevance changes move fast: retrofit your pages with direct answer blocks, close your topical gaps, and embed data density. Sentiment runs in the background as a filter, and Neutral isn’t safe enough. Visibility is what you monitor as the upstream work compounds.

    Every one of these fixes is measurable. Use Topify to track your dimension scores as you move through the sequence, so you know when each lever has done its work and it’s time to move to the next.

    FAQ

    How long does it take to improve a GEO score after making changes?

    Structural content changes, like adding statistics, direct answer blocks, and schema markup, can show initial results within 30 to 45 days. Building entity authority through Wikipedia, Tier 1 media mentions, and Wikipedia/Wikidata entries is a longer-term effort that typically compounds over 6 to 12 months.

    Which GEO score dimension has the highest weight?

    Authority and Entity Clarity carry the highest weight because they’re the prerequisite for retrieval. Without a verified entity signal, content optimization has minimal impact. Research indicates that topical authority and unlinked brand mentions on high-authority sites are the strongest predictors of AI citation rate.

    Can I improve my GEO score without a large content team?

    Yes. GEO improvement is more about content structure and factual density than content volume. Small teams should focus on retrofitting existing high-traffic pages with atomic knowledge blocks, adding one statistic per 200 words, and ensuring schema and bot-accessibility signals are clean. Those changes don’t require new content, just structural editing of what already exists.

    Read More

  • Your GEO Score Has 4 Parts. Most Marketers Only Fix One.

    Your GEO Score Has 4 Parts. Most Marketers Only Fix One.

    A SaaS brand spent three months rewriting every product page. Sharper copy. More data. Better structure. Then someone asked ChatGPT to recommend tools in their category, and the brand wasn’t mentioned once.

    The problem wasn’t the content. It was that GPTBot, OpenAI’s retrieval crawler, had been blocked by a single line in their robots.txt file. The AI never saw the page.

    That’s what a GEO score is designed to catch. It’s not a single number measuring how “good” your content is. It’s a four-dimensional diagnostic that measures whether an AI can access your pages, understand them, trust them, and actually recommend you. Miss any one dimension and the others don’t matter.

    As traditional search volume is projected to decline by 25% by late 2026, and 93% of AI sessions already end without a click to any external site, your brand’s presence inside AI-generated answers is no longer optional. It’s the only impression you might get.

    What a GEO Score Actually Measures

    GEO stands for Generative Engine Optimization. A GEO score quantifies how well a brand is positioned to be cited by AI platforms like ChatGPT, Perplexity, and Gemini.

    Unlike an SEO score, which optimizes for “the click,” a GEO score optimizes for “the citation.” And the stakes are different: GEO-driven visitors convert at up to 12.9x higher rates than standard organic traffic. Each citation carries more weight than a standard impression ever did.

    The four dimensions of a GEO score follow a strict causal sequence:

    DimensionAnalogyWhat It Controls
    AI Crawler AccessThe GatekeeperCan AI find and fetch your pages?
    Structured DataThe TranslatorCan AI parse what your content means?
    Content SignalsThe RecommenderDoes AI consider your content worth citing?
    AI VisibilityThe Screen PresenceHow often does AI actually mention you?

    Each dimension is independent enough to diagnose separately. Together, they form a chain: a failure in Dimension 1 makes Dimensions 2, 3, and 4 irrelevant.

    Dimension 1 — AI Crawler Access: Can AI Even Find Your Pages?

    This is where most brands lose before they even start.

    Modern AI platforms use dedicated crawlers to index content in real time. OpenAI alone runs three: GPTBot for model training, OAI-SearchBot for search indexing, and ChatGPT-User for live retrieval during conversations. Perplexity uses PerplexityBot. Anthropic uses ClaudeBot.

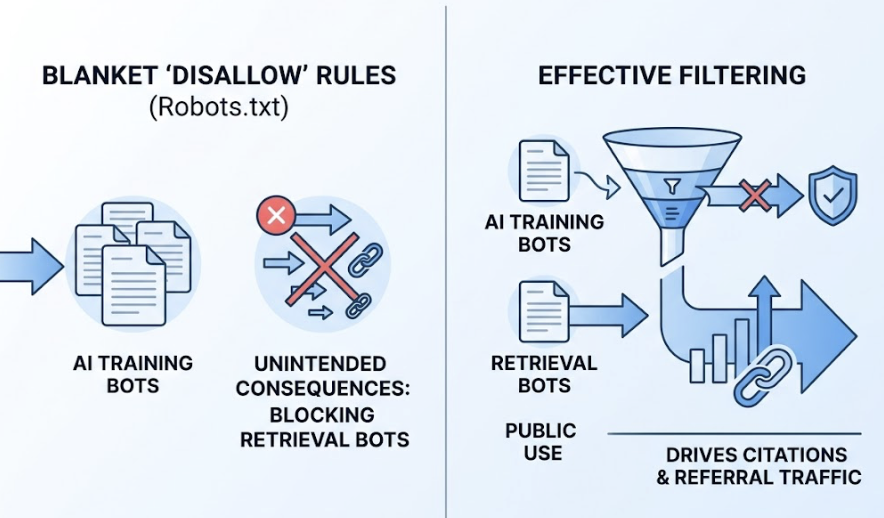
    The problem is that many websites, particularly publishers and enterprise sites, have deployed blanket “Disallow” rules in their robots.txt files. According to data from Cloudflare and Buzzstream, 79% of top news sites block at least one AI training bot. Many are also unknowingly blocking retrieval bots in the same sweep — the bots that would actually drive citations and referral traffic.

    The distinction matters enormously. Blocking GPTBot (training) might be a reasonable business decision. Blocking OAI-SearchBot or ChatGPT-User is effectively opting out of appearing in ChatGPT responses entirely.

    There’s a second technical layer: JavaScript rendering. Many AI retrieval pipelines cannot execute client-side JavaScript. They see a “ghost page” with none of the content that renders in a browser. Server-Side Rendering (SSR) or pre-rendering for bot traffic ensures that your actual content is visible during the initial fetch.

    A brand can rank on page one of Google and remain completely invisible to a user asking ChatGPT the same question. Crawler access is the prerequisite for everything else.

    Dimension 2 — Structured Data: Does AI Understand What You’re Saying?

    Getting crawled is the baseline. Getting understood is the next gate.

    AI systems don’t read pages the way humans do. They use Named Entity Recognition and relationship mapping to build an internal knowledge graph of a topic. Structured data, specifically Schema.org markup in JSON-LD format, acts as a translator that removes the ambiguity from that process.

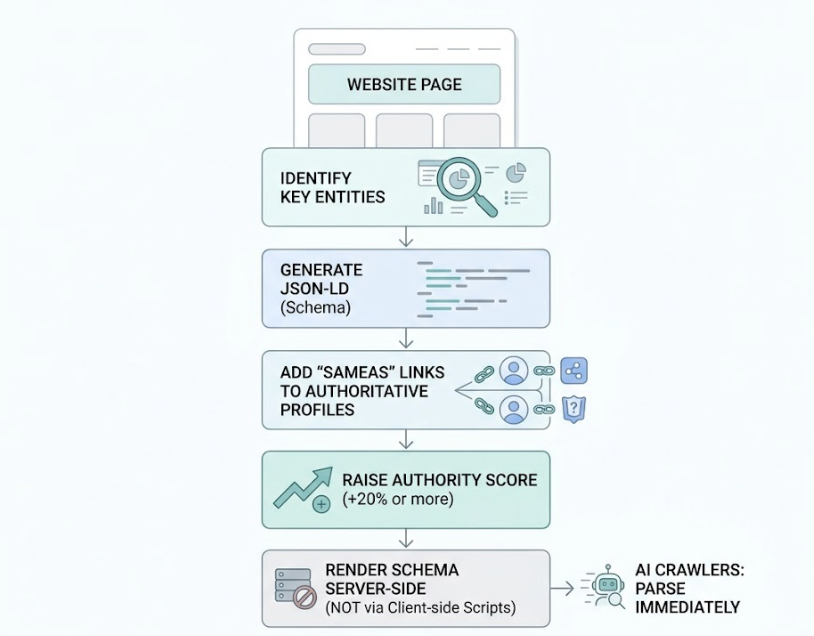
    The most direct application is entity disambiguation. An Organization schema, linked via the sameAs property to verified profiles on Wikipedia, Wikidata, or LinkedIn, tells an AI model exactly who created the content and whether they’re credible. Without this layer, the AI is guessing.

    Pages with well-implemented structured data are 36% more likely to appear in AI-generated summaries.

    Among all schema types, FAQPage markup has the highest leverage for GEO. Google pulled back FAQ rich results from traditional SERPs in 2023, but AI platforms have moved in the opposite direction — they treat FAQ schema as a preferred extraction format. Because the question-answer structure is already pre-packaged, the AI can cite the content with high confidence without needing to interpret narrative prose.

    The numbers bear this out: FAQ schema increases citation rates by 28% to 89%, and pages with FAQ schema are 3.2x more likely to appear in Google AI Overviews.

    One important ceiling to understand: schema doesn’t substitute for authority. Research into ChatGPT’s citation patterns shows an “Authority-to-Schema” ratio of roughly 3.5:1. Perfect schema implementation adds around 10% weight to the citation evaluation. It’s a last-mile optimizer — it ensures strong content gets extracted accurately rather than skipped due to parsing errors. It can’t rescue weak content.

    Dimension 3 — Content Signals: Is Your Content Worth Citing?

    Assuming a crawler can access the page and the AI can parse its structure, the third question is whether the content itself earns a citation.

    Generative engines are calibrated to provide accurate, specific answers. That shifts the content strategy away from keyword presence toward what researchers call “information gain” — data, claims, or findings that aren’t already present in the model’s training data.

    Content format matters significantly. Comprehensive guides with supporting data have a 67% citation rate. Comparison matrices and review content come in at 61%. Opinion pieces and general thought leadership without supporting data average only 18%. AI systems value objective, extractable facts over subjective narrative.

    The placement of information on the page is equally important. An analysis of 1.2 million ChatGPT responses found that 44.2% of citations originate from the first 30% of a webpage. Burying the answer in a long narrative introduction is one of the most common and costly GEO mistakes. Pages that place a concise 40-60 word direct answer immediately after an H2 tag are cited 2.4x more often than those that don’t.

    Quantitative specificity is also a consistent signal. AI systems show a 40% higher citation rate for content containing specific numbers and percentages compared to qualitative statements. The difference between “our software is fast” and “our software reduces latency by 40% according to the 2025 Benchmarking Report” is the difference between being invisible and being cited.

    Semantic HTML tables and structured lists push that advantage further: structured formats produce 2.5x to 2.8x higher citation rates than plain text equivalents covering the same information.

    Dimension 4 — AI Visibility: How Often Does AI Actually Mention You?

    The first three dimensions are inputs. AI Visibility is the output. It measures how frequently and how favorably your brand appears inside AI-generated responses.

    The key metric here is Share of Model (SoM), the GEO-era equivalent of Share of Voice. It’s calculated as the percentage of AI responses in a defined prompt set that mention your brand, relative to all brand mentions in that category.

    $$\text{Share of Model} = \frac{\text{Responses Mentioning Your Brand}}{\text{Total Responses Mentioning Any Brand in Category}}$$

    An AI mention rate of 10-15% across relevant prompts is considered healthy. Above 30% signals category leadership. But raw frequency isn’t the whole picture.

    Position within a response carries significant weight. Brands named first in a recommendation list signal “primary entity” status and receive disproportionate user attention. Position tracking uses a weighted formula where the first mention carries 5x more value than the fifth.

    Sentiment is the other variable that raw visibility hides. A brand with 25% visibility and an 80/100 sentiment score will consistently outperform a brand with 40% visibility and a 50/100 sentiment score in actual conversion outcomes. Being mentioned frequently as “expensive and complex” is worse than being mentioned less often in a favorable context.

    You can’t optimize what you can’t see.

    That’s why AI Visibility requires systematic, cross-platform monitoring across ChatGPT, Perplexity, Gemini, and others — not manual spot checks. The data changes fast: 40-60% of cited sources rotate monthly.

    Why Your GEO Score Won’t Move If You Only Fix One Dimension

    The most expensive GEO mistake is siloed optimization.

    A brand invests in high-quality, well-structured content (Dimension 3) while their robots.txt blocks the crawlers that would retrieve it (Dimension 1). Result: zero improvement in AI visibility despite significant content investment. Researchers call this the “Invisibility Paradox.”

    The four dimensions aren’t parallel tracks. They’re a sequence. Crawler access determines whether content can be ingested. Structured data determines whether ingested content can be understood. Content signals determine whether understood content is worth citing. AI visibility shows whether cited content is building brand presence.

    The correct optimization order is:

    1. Verify crawler access for GPTBot, OAI-SearchBot, and PerplexityBot
    2. Implement Organization, Product, and FAQ schema with sameAs entity anchoring
    3. Restructure key pages for Answer Capsule format and quantitative density
    4. Monitor Share of Model, sentiment, and position across platforms

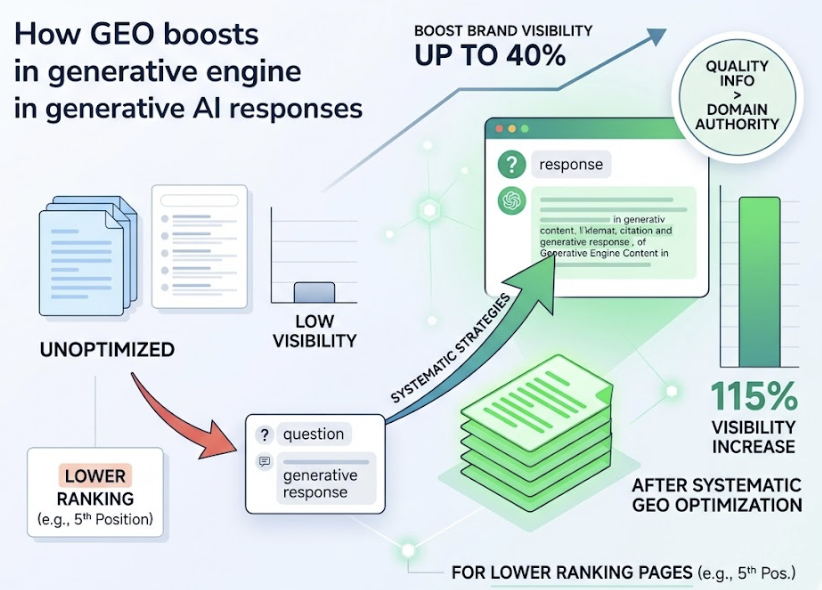
    Research from Princeton and IIT Delhi confirms that applying these strategies systematically can boost brand visibility in generative responses by up to 40%. Sites in lower positions see even larger gains: pages ranking fifth see a 115% visibility increase after systematic GEO optimization. Quality of information can override historical domain authority in this environment.

    Prioritizing Dimension 1 before Dimension 3 isn’t just logical. It’s the difference between content investment that compounds and content investment that disappears.

    Check Your 4-Dimension GEO Score Before You Optimize Anything

    Before rewriting a single page or adding schema markup, you need a baseline. Otherwise, you’re optimizing blind.

    Manually auditing all four dimensions requires technical crawl testing, cross-platform AI sampling, schema validation, and content analysis — running them together across multiple AI platforms takes significant time and specialized tooling most marketing teams don’t have in-house.

    The Topify GEO Score Checker automates that diagnostic. It queries AI platforms directly in real time and returns a four-dimensional scorecard showing exactly where your scores stand across Crawler Access, Structured Data, Content Signals, and AI Visibility. It’s free to run, and it takes minutes rather than days.

    One particularly useful output: the tool identifies “high-traffic, zero-citation” pages by correlating your existing traffic data with AI mention rates. These pages have the authority to rank but lack the formatting to be cited. They’re the highest-priority targets for structural optimization because the underlying authority is already there.

    Once you know where each dimension stands, the next step is watching how they move. Topify’s continuous tracking feature monitors changes across all four dimensions over time, surfacing shifts in AI citation patterns and competitor positioning as they happen. When 40-60% of cited sources rotate monthly, point-in-time scores aren’t enough. Trend data is where the real strategic signal lives.

    Conclusion

    A GEO score isn’t a vanity metric. It’s a diagnostic framework for a search environment where 83% of AI-influenced queries produce no referral traffic and the only impression you may get is a mention inside someone else’s answer.

    Each of the four dimensions does a specific job. Crawler access determines whether you exist in the AI’s retrieval window. Structured data determines whether the AI can accurately interpret what you’re saying. Content signals determine whether the AI considers your information worth recommending. AI visibility tells you whether all of that is actually working.

    Fix one without the others and the chain breaks. Fix all four in sequence and you build the kind of citable authority that compounds — the type where being recommended once makes the next recommendation more likely.

    The brands winning in AI search right now aren’t necessarily the biggest or the oldest. They’re the ones whose information is the most accessible, interpretable, and factually specific to the models making recommendations.


    FAQ

    What is a good GEO score? 

    A score above 85/100 is generally considered excellent, but aggregate scores can hide critical gaps. A brand might score 88/100 overall while scoring 9/100 on schema markup alone. That’s a fixable problem that aggregate visibility conceals.

    How often should I check my GEO score? 

    AI citation data is volatile: 40-60% of cited sources rotate monthly. For competitive categories, weekly re-sampling is recommended. Citation data for informational queries typically decays to 40% of its initial level within 90 days without content refreshes.

    Does a high GEO score affect Google rankings? 

    Indirectly, yes. 76% of AI Overview citations come from the top 10 organic results. Optimizing for entity clarity and structured data (Dimension 2) strengthens your representation in Google’s Knowledge Graph, which lifts organic rankings and increases AI Overview selection probability.

    Can I improve all 4 dimensions at the same time? 

    Technically yes, but it’s inefficient. Brands should fix Dimension 1 (Crawler Access) before investing in content rewrites. Without confirmed crawler access, content improvements produce zero ROI in the AI ecosystem.

    What’s the difference between an SEO score and a GEO score? 

    SEO scores optimize for the click — getting a user to visit your site. GEO scores optimize for the citation — getting an AI to recommend your brand inside its answer. GEO-driven visitors convert at up to 12.9x higher rates than traditional organic visitors, which changes the math on what a single citation is worth.


    Read More

  • How to Check Your GEO Score for Free

    How to Check Your GEO Score for Free

    Your domain authority is solid. Your keyword rankings look clean. But none of that tells you whether ChatGPT is recommending your competitor instead of you. Traditional analytics track clicks. They don’t track whether an AI engine ever considered citing your site in the first place.

    That gap is what a GEO score measures, and 60% of Google searches already end without a click. For AI-native queries, that number is higher. The brands showing up in AI answers didn’t get there by accident. They fixed four specific things. This guide shows you how to find out whether your site has fixed them too.

    Your Website Has an AI Readiness Problem You Can’t See in Analytics

    Search engine rankings are a poor proxy for AI visibility. The two systems use fundamentally different signals.

    Google rewards authority and relevance. AI engines like ChatGPT and Perplexity reward extractability: Can the crawler even access your site? Does the page structure make it easy to pull facts? Is the content dense enough with verifiable data to be worth citing? A top-ranking page that fails these checks gets ignored by AI retrieval pipelines, regardless of its domain authority.

    The conversion data makes this consequential. Visitors arriving via AI referrals convert at 1.2x to 5x higher rates than organic search visitors. Claude referrals, specifically, average a 16.8% conversion rate. That’s not a metric most teams are tracking yet, which is exactly why it’s an opportunity.

    What a GEO Score Actually Measures

    A GEO score is a composite metric, rated on a 0-100 scale, that evaluates four distinct dimensions of AI readiness. Each dimension corresponds to a specific stage in how AI systems retrieve and cite information.

    AI crawler access determines whether bots like OAI-SearchBot, PerplexityBot, and Claude-SearchBot can reach your pages at all. Many sites block these crawlers unintentionally via wildcard rules in robots.txt or through CDN-level settings in tools like Cloudflare.

    Structured data measures the presence and quality of Schema.org markup. AI engines are probabilistic systems. Schema reduces ambiguity, letting the model extract facts with higher confidence. Pages with FAQ schema are weighted 40% higher in ChatGPT’s source selection.

    Content signals evaluate factual density and modular readiness. Research from Princeton University found that adding statistics to a page lifts AI citation probability by up to 40%. Expert quotations add another 37%. The underlying reason: AI engines prefer verifiable specificity over qualitative claims.

    Overall AI visibility tracks your current “Share of Model”—how often AI engines are actually citing or mentioning your brand across relevant queries. This is the outcome dimension. The first three are inputs; this one measures results.

    Score ranges map to actionable tiers: 80-100 means you’re in the retrieval pool consistently; 50-79 signals competitive gaps; below 50 typically indicates a foundational block that’s keeping you out of AI answers entirely.

    AI Crawler Access: The Gate Most Sites Leave Locked

    The robots.txt file used to be simple. In 2026, it’s a governance document that controls access across a dozen distinct AI user agents.

    OpenAI alone operates separate bots for training (GPTBot) and retrieval (OAI-SearchBot). The same split applies to Anthropic and Perplexity. Many webmasters blocked all AI bots during the 2023-2024 period over data privacy concerns. The problem: retrieval bots are what put you in AI answers. Blocking them means your visibility is zero by default.

    The nuanced approach is selective access: allow retrieval-focused agents (OAI-SearchBot, Claude-SearchBot, PerplexityBot/1.0) while blocking training-focused ones (GPTBot, Claude-Searchbot training variants). This way your content appears in real-time AI search without contributing to model training without attribution.

    Structured Data: Why Schema Markup Is Now a GEO Signal

    Schema is no longer optional for AI visibility. Websites with author schema are 3x more likely to appear in AI answers than those without, because the model can trace the information to a credible entity.

    The highest-impact schema types for GEO are FAQPage (maps directly to conversational AI query patterns), Article and BlogPosting (provides freshness signals that Perplexity and others weigh heavily), and Organization/Person schema (establishes E-E-A-T that AI engines use for trust signals in sensitive topic areas).

    How to Check Your GEO Score in Under 2 Minutes

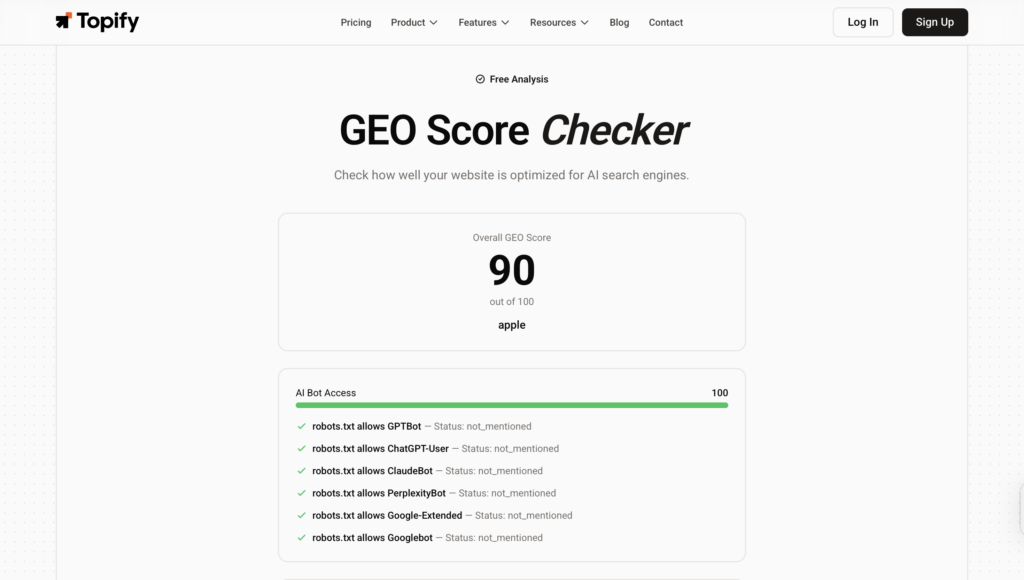
    The Topify GEO Score Checker runs a full four-dimension audit in 10-30 seconds. No login, no setup, no credit card. You enter a domain and get an instant report.

    Here’s what happens when you run it:

    Step 1: Enter your domain. Go to topify.ai/tools/geo-score-checker and type in any URL. You can audit your own site or a competitor’s.

    Step 2: The tool fetches your page using multiple AI user agents. It simulates requests from OAI-SearchBot, GPTBot, PerplexityBot, and others to identify any blocks at the robots.txt or CDN level.

    Step 3: Schema parsing runs in parallel. The checker audits for over 30 schema types, flagging missing or malformed markup that would reduce your citability.

    Step 4: Content analysis evaluates factual density. The tool assesses whether your page content is structured into extractable blocks, following the “modular readiness” criteria that AI retrieval systems favor.

    Step 5: A real-time visibility check pings leading LLMs to see whether your brand or domain is currently being cited for relevant keywords.

    The output is a scored report across all four dimensions, with specific flags on what’s blocking or reducing your AI visibility. The whole process takes under two minutes.

    One underused feature: run the same check on two or three competitors before you run it on yourself. Knowing where you sit relative to the field changes how you prioritize what to fix.

    Reading Your GEO Score Report: What the Numbers Mean

    The composite score tells you your overall AI readiness tier. The per-dimension scores tell you where to focus first.

    A score above 80 means you’re technically sound and content-ready. The gap between good and excellent at this level is usually in content signals—more proprietary data, more attributed expert quotes, more modular formatting. Content updated within the last 30 days is twice as likely to be cited by AI platforms, so freshness maintenance matters even when the fundamentals are solid.

    A score in the 50-79 range typically signals competitive gaps rather than outright blocks. You’re in the retrieval pool, but inconsistently. The most common culprits: partial schema coverage, a few AI crawlers blocked that others can access, or content that reads well but isn’t structured into extractable chunks.

    Below 50 usually means something binary is wrong. Either AI crawlers can’t reach your pages, or your site has essentially no structured data, or both. This is the fastest tier to improve because the interventions are specific and low-cost.

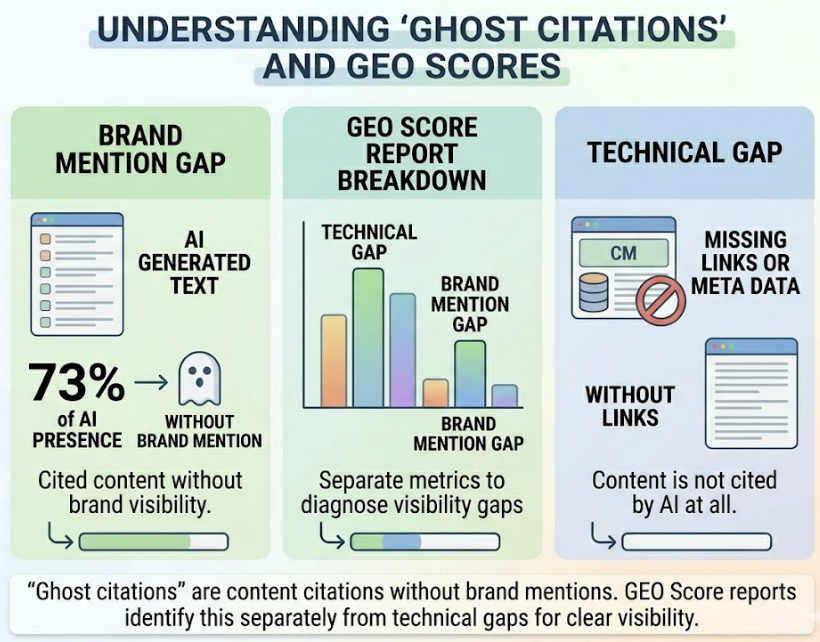
    One metric worth paying attention to beyond the score: the visibility dimension specifically. Research across multiple AI platforms found that 73% of AI presence for some brands consists of citations without brand mentions. A site can be cited extensively in AI answers while the brand name never appears in the generated text. The GEO Score report surfaces this “ghost citation” problem separately, so you know whether you have a technical gap or a brand mention gap.

    After Your GEO Score: 3 Actions That Actually Move the Needle

    The score is a diagnosis. These are the interventions with the strongest evidence behind them.

    Action 1: Fix crawler access first. This is binary. If key AI bots are blocked, your visibility is zero regardless of content quality. Update your robots.txt to explicitly allow OAI-SearchBot, Claude-SearchBot, and PerplexityBot/1.0. If you’re running Cloudflare, check whether the AI bot blocking feature was enabled during the 2023 wave of default settings—it often was. This fix costs nothing and the impact is immediate.

    Action 2: Implement FAQ schema on every informational page. Schema doesn’t require a developer for most CMS platforms. Given the 40% weighting boost for FAQ schema in ChatGPT source selection, it’s the highest-return structured data investment. Pair it with Person schema for author pages to establish the E-E-A-T signals that AI systems use for trust.

    Action 3: Enrich content with proprietary data. Generic content doesn’t win AI citations because AI systems already have generic knowledge in their training data. What they’re looking for in retrieval is “information gain”—data, benchmarks, or survey results they don’t already have. Embedding even one original statistic per article meaningfully shifts the citation probability. Content with 19 or more statistical data points earns nearly double the citations of content with minimal data.

    Once you’ve run these fixes, the next layer of intelligence is tracking how your GEO score changes over time—and how it compares against competitors. Topify’s AI Visibility Checker gives you ongoing Share of Model monitoring across ChatGPT, Perplexity, Gemini, and others, so you’re not just checking a one-time score but watching the trend. The competitor benchmarking feature shows you where rivals are pulling ahead in AI citations before you see it in traditional traffic data.

    Why Free GEO Score Tools Aren’t All the Same

    Not every tool that calls itself a GEO checker is measuring the same thing. The most common limitation: single-dimension audits. A tool that only checks schema, or only checks robots.txt access, gives you a partial picture. A site can have perfect schema and still have zero AI visibility because the crawlers are blocked at the CDN level.

    The ALM Corp overview of generative engine optimization notes that the GEO tool market is fragmenting into specialized niches, with significant variation in what each platform actually measures. The practical question for any free checker is: does it simulate actual AI crawler behavior, or does it check a static checklist? The former catches CDN-level blocks that the latter misses entirely.

    For quick diagnostics on individual URLs, no-login tools are the right starting point. The tradeoff is depth of ongoing monitoring. A free checker tells you where you stand today. A full platform like Topify tracks how that standing shifts week over week, which competitors are gaining ground in AI answers, and which content updates are driving citation improvements.

    The GEO market is projected to reach $33.7 billion by 2034. The tool landscape will consolidate around platforms that can close the loop from diagnosis to action to tracking. Knowing which layer you need—quick audit vs. continuous intelligence—is the main selection criterion.

    Conclusion

    A GEO score tells you something your current analytics stack can’t: whether AI systems can actually find, read, and cite your content. The Topify GEO Score Checker surfaces that information in under two minutes, with no setup required.

    Run the check on your primary revenue-driving URLs first. Then run it on the two or three competitors you most frequently lose deals to. The gaps between those reports are your roadmap. Crawler access, schema coverage, and content factual density are all fixable. The brands that fix them now accumulate an AI citation advantage that compounds as generative search volume continues to grow.

    Start with the free audit. Check your GEO score here.


    FAQ

    Q: What is a GEO score? 

    A: A GEO score is a 0-100 rating of how well your website is optimized for discovery and citation by generative AI engines like ChatGPT, Perplexity, and Google AI Overviews. It evaluates four dimensions: AI crawler access, structured data quality, content signals (factual density and modular structure), and current AI visibility (how often your brand is cited). Unlike an SEO score, it focuses on AI retrieval readiness rather than keyword rankings or backlink profiles.

    Q: How is a GEO score different from an SEO score? 

    A: An SEO score measures ranking signals like keyword relevance, backlink authority, and page speed—factors that affect where you appear in a list of blue links. A GEO score measures whether AI systems can access, extract, and cite your content in synthesized answers. A site can score well on SEO and poorly on GEO if it blocks AI crawlers, lacks structured data, or publishes content that isn’t structured for machine extraction.

    Q: Is the GEO Score Checker really free? 

    A: Yes. Topify’s GEO Score Checker is free to use with no registration required. You enter a domain, and the tool generates a scored report across all four AI readiness dimensions in 10-30 seconds. There’s no credit card, no trial period, and no account creation needed to see the full results.

    Q: How often should I check my GEO score? 

    A: Run a baseline check immediately, then recheck after implementing any changes to robots.txt, schema, or content. For ongoing monitoring, a monthly cadence catches drift from platform updates or competitor improvements. If you’re actively optimizing for AI citations, weekly checks during active campaigns help you correlate content changes to visibility shifts.


    Read More

  • Is Your Brand Getting AI Citations? Here’s How to Check

    Is Your Brand Getting AI Citations? Here’s How to Check

    Your SEO rankings look solid. Traffic is up. But when a potential customer opens ChatGPT and types “what’s the best [your category] tool for mid-sized companies,” your brand doesn’t come up. A competitor does. Three times.

    That gap, between where you rank on Google and where you land in AI answers, is where the new competitive battle is being fought. And most brands don’t even know they’re losing it.

    Most Brands Are Invisible to AI Search Without Knowing It

    Traditional search gives every brand multiple shots. A user clicks through three links, compares pages, and eventually finds you. AI search doesn’t work that way.

    When ChatGPT or Perplexity synthesizes an answer, it picks two or three sources and presents them as the definitive response. If your brand isn’t cited, it doesn’t exist in that conversation. The user doesn’t scroll down to find you.

    This is what researchers call an “AI visibility gap”: brands that dominate Google rankings but have zero presence in AI-generated answers. It’s not a penalty. It’s just that AI systems never learned to trust your content as a reliable source.

    That’s fixable. But first, you need to know where you actually stand.

    What AI Citation Actually Means (And Why It’s Not the Same as SEO)

    An AI citation isn’t a backlink. It’s not a ranking. It’s something more specific: when an AI system selects your content as evidence to support a claim it’s making.

    Traditional SEO is built on keyword matching and domain authority. AI citation runs on a different logic entirely, based on a process called Retrieval-Augmented Generation (RAG). The AI converts your content into a semantic vector, compares it against the user’s query, and decides whether your information is specific, accurate, and trustworthy enough to quote.

    The difference matters because a brand with a domain authority of 80 can still get zero AI citations if its content lacks what AI retrieval systems look for: factual density, clear entity definitions, and external corroboration. The research report from this field puts it plainly: AI citation is about being a source of evidence, not a source of traffic.

    The table below shows where the two systems diverge:

    DimensionTraditional SEOAI Citation (GEO)
    Core unitWeb pages (URLs)Semantic passages / chunks
    Key signalsBacklinks, keyword densityFactual density, entity clarity
    User experienceClick-through to your siteZero-click, answer delivered directly
    Citation purposePromotion and visibilityFact verification and evidence
    How you measure itRankingsCitation frequency, Share of Voice

    How to Manually Check Your AI Citations Right Now

    Before setting up any monitoring system, run a manual audit. It takes about 15 minutes across three platforms and tells you whether you have a citation problem worth solving.

    The goal isn’t to search your brand name. It’s to simulate how real buyers actually ask questions, then see whether your brand appears in the response.

    ChatGPT

    ChatGPT’s search mode (available in GPT-4o with browsing enabled) pulls from Bing’s index, semantically reranks the top results, and synthesizes an answer. It tends to weight recency and source specificity.

    Use prompts like: “What are the most recommended [your product category] tools for mid-sized companies in 2026? Give me the top three with reasons.”

    What to look for: Is your brand listed as a primary recommendation, or just mentioned in passing? More importantly, check the footnotes. If ChatGPT cites a competitor’s website in the sources but only mentions your brand in the text, your content is losing the “information gain” competition. The AI found a competitor’s page more useful as evidence.

    Perplexity

    Perplexity is a citation-first engine. Every sentence it generates needs a source. It pulls from Google, Bing, and its own crawl index, and it weights recency heavily.

    Try: “Compare [your brand] and [competitor] on [specific capability]. Include recent user reviews and technical documentation.”

    What to look for: If the sources cited are from two years ago, your newer content hasn’t passed Perplexity’s time decay filter. Perplexity discounts older material systematically. Being cited from a 2023 blog post in 2026 is almost worse than not being cited, because it signals to users that your thinking hasn’t evolved.

    Claude

    Claude uses Brave Search as its primary retrieval infrastructure. Research shows that Brave’s search results correlate with Claude’s citations at a rate of 86.7%, which means your Brave Search presence is a strong proxy for your Claude visibility.

    Try: “From an expert perspective, what is [your brand]’s core methodology for solving [specific customer problem]? How does it differ from industry standards?”

    What to look for: Can Claude describe your product accurately and specifically? If it gives a vague or generic description, it means your brand hasn’t been clearly defined in the external sources Claude trusts. Wikipedia, industry white papers, and analyst coverage are the “trust anchors” Claude relies on most.

    5 Signs Your Brand Has an AI Citation Problem

    After running those checks, you’ll have raw observations. Here’s how to turn them into a diagnosis.

    Low citation frequency. In 10 queries about core problems you solve, your brand appears in fewer than 3. The research benchmark is clear: brands cited fewer than 30% of the time on their core topic have a content extractability problem. AI systems can’t pull clean facts from your pages.

    Competitor displacement. The AI describes a competitor’s features in detail and only mentions you in passing. This signals that in AI semantic space, your competitor has established a stronger association with your category. They’ve achieved what researchers call “semantic monopoly.”

    Outdated or negative sentiment. The AI pulls a two-year-old review or a discontinued product mention. Old negative signals haven’t been overwritten by newer positive content. AI systems don’t automatically forget bad data; you have to bury it with volume and authority.

    Source mismatch. The AI cites a Reddit thread or third-party review to explain your pricing, rather than your own pricing page. This means your official content has poor machine readability. The Reddit thread was more extractable than your website.

    Entity ambiguity. When asked about your brand, the AI gives the wrong industry classification or confuses you with another company. This is the most serious signal. Your brand’s entity identity hasn’t been established in the knowledge graph that AI systems draw from.

    Why Running Manual Checks Every Week Doesn’t Scale

    Here’s the core problem with the manual approach: LLMs are stochastic. The same query, run twice, can return different sources. A single test gives you one data point from one moment in one model’s probabilistic output.

    To get statistically meaningful visibility data, you’d need to run hundreds of prompt variations, across multiple AI platforms, on a consistent schedule, and then aggregate the results. Manually. Every week.

    That’s not realistic for any team.

    This is where a platform like Topify changes the equation. Instead of running 10 manual checks, Topify executes thousands of simulated queries daily, covering long-tail prompt variations your team would never think to test. The result isn’t a snapshot; it’s an AI Visibility Score (AVS) with statistical weight behind it. Scores below 10 indicate near-invisibility. Above 70 means you’re functioning as a category authority in AI answers.

    The difference between a manual check and Topify’s tracking is the difference between checking the weather once and running a climate model.

    How to Set Up Ongoing AI Citation Monitoring

    If you’re moving from manual checks to systematic monitoring, the setup process follows three steps.

    Build a prompt library first. Don’t just monitor your brand name. Structure your prompt matrix around three types of queries: buyer intent (“which [category] tool is best for [specific use case]”), entity clarity (“what is [your brand]’s approach to [core methodology]”), and competitive comparison (“[your brand] vs [competitor] for [specific need]”). This covers the full range of ways a real buyer might encounter or look for you.

    Track the right metrics. Topify surfaces seven core dimensions: visibility, sentiment, position, volume, mentions, intent, and CVR (Conversion Visibility Rate). For most teams starting out, three matter most. Your AI Visibility Score tells you whether you’re present. Sentiment Velocity tells you whether the AI’s description of your brand is improving or declining over time. Source Forensics identifies which specific URLs are being cited, so you know which content is actually working.

    Monitor across platforms, not just one. A brand can have strong ChatGPT visibility and near-zero Claude visibility. These gaps aren’t random; they reflect the different retrieval infrastructure each platform uses. ChatGPT runs on Bing. Claude runs on Brave. Perplexity has its own crawler. Topify’s dashboard consolidates these into a single view, so you can see exactly where the gaps are rather than guessing.

    What to Do When Your Brand Isn’t Being Cited

    Knowing you have a citation gap is step one. Closing it requires a different kind of thinking than traditional SEO.

    Restructure content for AI extractability. AI retrieval systems favor high information density. Every H2 section on your site should open with a 40-60 word factual summary: a concise, self-contained statement that can stand alone as a cited passage. Think of it as writing for an AI that’s going to quote one sentence from your entire page. Which sentence would you want it to pick?

    Fix your machine readability. Deploy JSON-LD Schema markup, especially Organization, FAQPage, and HowTo types. The sameAs attribute is particularly valuable: it connects your official site to Wikipedia, LinkedIn, and Crunchbase entries, which signals entity uniqueness to AI knowledge graphs. Also consider implementing an /llms.txt file in your root directory, a Markdown-formatted index that tells AI systems which pages are your authoritative source of truth.

    Build external trust signals. AI systems cite sources they already trust. Getting accurate coverage in industry directories like G2 and Capterra, in authoritative media, and in high-activity communities like Reddit increases the probability that AI retrieval systems will include you in their trusted source pool. These are the “trust seeds” that influence which brands get cited consistently.

    Don’t try to fix hallucinations by deletion. If an AI is generating inaccurate descriptions of your brand, you can’t remove the bad data. The strategy is volume: publish enough accurate, high-authority content that the correct signal overwhelms the incorrect one. Researchers call this a “digital cushion strategy.”

    Conclusion

    Your brand’s visibility in AI search isn’t determined by your SEO rankings. It’s determined by whether AI systems have been given enough clean, credible, and extractable information about you to include you as a trusted source.

    The manual checks in this guide take 15 minutes and give you a starting baseline. But if you’re serious about closing the gap, the next step is moving from one-off audits to continuous monitoring. Start with the three prompt types above, run them across ChatGPT, Perplexity, and Claude this week, and use what you find to prioritize which signals to fix first. Then set up a tracking system that removes the guesswork.

    AI citation isn’t a trend you can wait out. It’s the infrastructure of how buyers discover brands now.


    FAQ

    Q: How often should I check my brand’s AI citations? A: For brands in fast-moving industries, weekly monitoring across all major platforms is the right cadence. Monthly checks are likely too slow to catch negative sentiment trends or citation drops before they affect pipeline. AI models update their retrieval indexes frequently, and what was true last month may not reflect your current visibility.

    Q: Does being cited by AI actually drive traffic? A: Yes, though the traffic profile is different from organic search. Traffic arriving from an AI citation typically converts at a significantly higher rate because the AI has already done the initial trust-building. The research on this topic suggests that citation-referred visitors arrive with higher purchase intent than visitors from traditional search results.

    Q: Can I request that AI platforms cite my brand directly? A: There’s no official appeal process or submission channel at any major AI platform. Citations are determined algorithmically through RAG logic. The only reliable path is building what researchers call “overwhelming consensus”: ensuring that accurate, structured information about your brand is consistently available across the sources AI systems are trained on and retrieve from.

    Q: What’s the difference between an AI citation and an AI mention? A: A mention means the AI said your brand name in a response. A citation means the AI linked to or explicitly sourced your content as evidence. Mentions build mindshare. Citations build authority and provide a conversion path back to your site. In Topify’s scoring system, citations carry significantly more weight than plain mentions because they reflect the AI’s judgment that your content is credible enough to stake a claim on.


    Read More

  • How to Get Cited by AI: A 5-Step Checklist for 2026

    How to Get Cited by AI: A 5-Step Checklist for 2026

    Your content ranks on page one. Your DA is solid. But a potential customer asks ChatGPT, “What’s the best [tool in your category]?” and gets five recommendations. You’re not on the list.

    Traditional SEO metrics can’t explain this. They weren’t built to measure what AI chooses to say. And in 2026, the gap between Google visibility and AI citation is where most brands are quietly losing ground.

    AI Citation Isn’t Random. It Follows a Pattern.

    Most marketers assume AI just summarizes whatever ranks well on Google. That’s not how it works.

    Generative AI engines use a process called Retrieval-Augmented Generation (RAG). When a user submits a prompt, the AI retrieves relevant text fragments from the web, then synthesizes them into a response. It doesn’t pick the highest-ranked page. It picks the most extractable, fact-dense, and structurally clear content it can find.

    Research from Princeton, Georgia Tech, and other institutions confirms that AI citation visibility can improve by 30% to 40% through targeted GEO strategies. That improvement doesn’t come from gaming algorithms. It comes from strengthening what AI researchers call “authority signals”: precise data, verifiable claims, expert attribution, and semantic clarity.

    The difference between a cited brand and an invisible one isn’t always content quality. It’s usually content structure. AI needs content it can extract cleanly. If yours buries key facts in marketing copy or behind heavy JavaScript, AI moves on.

    That’s the pattern. And it’s fully optimizable.

    Step 1: Know Which Prompts You Need to Appear In

    AI citation starts with prompts, not keywords.

    A user on Perplexity doesn’t type “best CRM.” They type, “What’s the best CRM for a 15-person remote team that needs Salesforce integration and a free trial?” That specificity completely changes the competitive landscape. Brands that built their SEO around short-tail keywords are often invisible in this context.

    The first step is building a prompt library: 50 to 100 real user prompts that map to your product category, use cases, and decision stages. Importantly, about 20% of ChatGPT conversations carry clear commercial intent. If your brand enters those “intent windows,” conversion potential is substantially higher than traditional search.

    The challenge is that different AI platforms attract different user behaviors. Perplexity users skew toward factual queries and recent data. ChatGPT users tend toward complex, multi-step reasoning. Google AI Overviews blend both. Your prompt library needs to reflect where your actual audience is asking questions, not just where you’ve historically built SEO authority.

    Topify‘s AI Volume Analytics addresses this gap directly. Unlike traditional keyword tools, it estimates monthly prompt demand across ChatGPT, Gemini, Perplexity, and other platforms. You can see which prompts have high AI search volume in your category, where competitors are already getting cited, and which platform differences matter for your audience.

    This isn’t keyword research with a new name. It’s a fundamentally different data layer.

    Step 2: Structure Content So AI Can Extract It

    AI doesn’t read your page the way a human does. It uses vector embeddings to scan for semantically relevant text chunks. If your content is buried in promotional copy, nested inside accordions, or rendered client-side via JavaScript, AI often retrieves nothing.

    The fix is a production model called semantic chunking: every section of your content should be an independent, self-contained unit of meaning. That means it should make sense even if lifted out of context.

    The Formats AI Prefers to Cite

    Some content structures are consistently over-represented in AI citations:

    Comparison tables are the highest-value format. Structured data in Markdown tables is trivial for LLMs to parse and compare. If you’re making category claims, put them in a table.

    Numbered step lists map cleanly to how-to queries, which are among the most common AI search prompt types. A well-formatted 5-step process is almost purpose-built for RAG retrieval.

    Definition blocks let AI extract your answer in a single chunk. If you’re defining a concept, lead with the definition, not the backstory. Put the answer first, every time.

    FAQ sections are consistently cited. Domains with structured FAQs are cited roughly 40% to 100% more often than those without. The questions should mirror real user language, not sanitized marketing phrasing.

    Data points with explicit sourcing are the highest-trust signal. “According to [Institution] 2025 research” gives AI a clear attribution chain. Unsourced statistics get deprioritized.

    What Makes a Page “Uncitable” to AI

    Heavy client-side rendering is the most common problem. If your page requires JavaScript execution to surface your content, many AI crawlers (including GPTBot and ClaudeBot) see a blank page or a loading state.

    Hiding key facts in collapsible UI elements, using non-semantic HTML, or writing in long, dense paragraphs without clear topic sentences all reduce what researchers sometimes call “extraction score.” Pages that take more than 2 seconds to load risk timing out AI retrieval systems entirely.

    The structural principle is straightforward: write for humans, but render for machines.

    Step 3: Build Source Authority That AI Trusts

    In 2026, traditional Domain Authority is being supplemented by something more nuanced: entity authority and consensus signals.

    AI models don’t just evaluate your site in isolation. They evaluate your brand across the entire web. Is the information about you consistent across LinkedIn, Wikipedia, G2, your press coverage, and your own site? Inconsistencies, even minor ones like differing founding dates or mismatched product descriptions, create what AI systems treat as a reliability flag.

    Three dimensions drive AI source trust:

    Cross-web consistency. Your brand’s factual footprint needs to be uniform. This is table stakes, but most brands haven’t audited it.

    Associative authority. AI tracks which other sources cite you. A mention in a .gov report, an .edu case study, or a Forbes feature carries substantial weight. This is where digital PR starts to directly feed AI citation rates.

    Community consensus. This is the most underestimated factor. Research shows Reddit accounts for 21% to 46.7% of AI citations across major platforms. Perplexity, in particular, draws heavily from forum discussions. If your brand is genuinely referenced and discussed in relevant communities, AI picks up those signals.

    Topify’s Source Analysis tool maps exactly this: which domains are citing your competitors, in what context, and what the citation-to-authority pattern looks like. You can identify the specific media outlets or community platforms that function as AI citation hubs in your category, then prioritize outreach accordingly.

    Link-building in this context isn’t about PageRank. It’s about being cited by sources that AI already trusts.

    Step 4: Track Whether AI Is Actually Citing You

    “You can’t optimize what you can’t measure” applies here more than in almost any other channel.

    Manually prompting ChatGPT to see if you appear is both inefficient and misleading. Large language models introduce randomness into every response. A single test tells you almost nothing. You need volume, consistency, and cross-platform coverage to establish a real baseline.

    The metrics that matter in 2026 are different from traditional SEO KPIs:

    Share of Model (SoM): The percentage of target-prompt responses that include your brand. This is the AI-era equivalent of share of voice.

    Citation sentiment: Whether AI describes your brand positively, neutrally, or negatively. A brand cited as “affordable but limited” has a very different conversion trajectory than one cited as “the go-to platform for enterprise teams.”

    Citation provenance: Which specific URLs on your site, or which third-party pages, are generating AI citations. This tells you which assets are pulling weight and which aren’t.

    Position in response: When multiple brands are listed, where do you appear? First-position citations generate meaningfully more trust and traffic than fifth-position.

    Tracking MethodLimitationTopify Advantage
    Manual testing10-20 prompts/day max, high varianceThousands of simulated prompts, multi-platform
    Platform-native analyticsOnly covers one AI engineUnified view across ChatGPT, Gemini, Perplexity, and more
    Standard SEO toolsNo AI citation layerNative GEO metrics: SoM, Sentiment, Position, CVR

    Topify’s Visibility Tracking runs automated prompt simulations at scale, surfaces sentiment scoring through an NLP engine, and tracks how your citation rate changes over time. The optimization cycle typically shows measurable visibility improvement within 8 to 12 weeks of implementing structural changes.

    Set a baseline before you change anything. Otherwise, you’re optimizing blind.

    Step 5: Close the Gap Between You and the Brands AI Prefers

    AI citation in most categories follows a concentrated pattern. AI typically cites 3 to 7 sources per response. If you’re not in that set, the traffic and trust go entirely to whoever is.

    The question isn’t whether to compete for citations. It’s why AI is currently choosing your competitors and not you.

    Three Gaps Worth Diagnosing

    Information gain gap. Does your competitor have original research, proprietary data, or exclusive case studies that you don’t? AI is drawn to information that can’t be generated from existing training data. Publishing an annual industry survey or a dataset no one else has is one of the most durable citation assets you can build. Generic “skyscraper content” no longer works here.

    Schema gap. Are competitors using structured data markup (FAQPage, ProductDetail, ShippingDetails) that makes their commercial information machine-readable at lower cost? Schema markup reduces the work AI has to do to extract your data. Less extraction friction equals more citations.

    Third-party validation gap. Is your competitor consistently referenced on Reddit, mentioned in Wikipedia, and listed in authoritative industry reports while your brand is absent? That external consensus is what AI uses to break ties between similar-quality sources.

    Topify’s Competitor Monitoring gives you a live view of this: where competitors are being cited, by what sources, in what prompt contexts, and at what sentiment levels. The output isn’t just a report. It’s a gap analysis you can act on.

    Once you’ve identified the gaps, the action sequence is clear. For information gain: publish original data. For schema: audit your highest-value pages and add missing markup. For third-party validation: invest in community presence in the forums and platforms your category actually uses.

    The 5-Step AI Citation Checklist at a Glance

    StepCore ActionSupporting Tool
    1. Identify high-value promptsBuild a prompt library of 50-100 commercial-intent queriesTopify AI Volume Analytics
    2. Restructure content for extractionImplement semantic chunking, FAQ sections, comparison tablesTopify One-Click GEO Execution
    3. Build cross-web authorityAudit brand consistency, pursue digital PR in high-citation channelsTopify Source Analysis
    4. Track citation performanceEstablish SoM baseline, monitor sentiment and positionTopify Visibility Tracking
    5. Close the competitor gapRun gap analysis on information, schema, and third-party validationTopify Competitor Monitoring

    Conclusion

    AI citation isn’t luck. It’s what happens when a brand consistently provides clear, structured, verifiable information across the right channels.

    The brands winning in AI search right now didn’t stumble into citations. They built the content architecture, the authority footprint, and the measurement system that makes citation predictable. That’s achievable for any brand willing to treat GEO as a structured channel, not an afterthought.

    Get started with Topify to see exactly which of your pages are generating AI citations, which prompts you’re missing, and where your competitors are pulling ahead.

    FAQ

    Q: How long does it take for AI to start citing my content after I optimize it?

    A: It depends on the platform. AI engines with live web search (like Perplexity and SearchGPT) can pick up newly indexed content within days. For models that rely on training data snapshots, the lag can be several months. In practice, GEO optimization on real-time AI platforms typically shows measurable citation improvement within 8 to 12 weeks.

    Q: Does my Google ranking affect whether AI cites me?

    A: There’s a correlation, but not a direct causal link. Roughly 38% of AI citations come from pages in Google’s top 10, but that figure is declining as AI engines develop more independent evaluation logic. A page ranking #12 with a clean structure, strong schema markup, and clear factual content often outperforms a #3 page that’s dense, slow-loading, or marketing-heavy.

    Q: Which AI platforms should I prioritize?

    A: Prioritize based on where your audience actually asks questions. If your category involves frequent factual queries or product research, Perplexity is high-priority. If your audience uses AI for complex decision-making, ChatGPT should be central. Google AI Overviews is non-negotiable for most brands given Google’s search volume. Ideally, you’re tracking all three simultaneously.

    Q: Can a smaller brand realistically compete with large incumbents for AI citations?

    A: Yes, and in some ways GEO is more democratic than traditional SEO. AI evaluates content quality and structural clarity more than raw domain authority or budget. A smaller brand that publishes original data, maintains consistent schema markup, and builds genuine community presence can capture citation share from much larger competitors in a specific niche. The information gain advantage is not something money can simply buy.

    Read More

  • AI Citations: 5 Metrics That Actually Matter

    AI Citations: 5 Metrics That Actually Matter

    Someone searches “best project management tool for remote teams” on ChatGPT. The response names three products. Yours isn’t one of them.

    You don’t know this happened. Your competitor does.

    That’s the gap most brands are operating in right now. Traditional tools — GA4, Google Search Console — only track what happens after someone arrives at your site. They can’t see the thousands of moments where AI shapes a buyer’s perception before any click occurs. Brand mentions in AI answers correlate three times more strongly with AI visibility than traditional backlink profiles. Yet most teams have no system to track them.

    This guide breaks down the five metrics that tell you whether your brand is actually winning in AI search — and what to do when you’re not.

    Why AI Citations Are a Different Beast Than Backlinks

    Getting a backlink is simple enough to understand: another site links to yours, and that signals authority to Google. AI citations work differently, and the difference matters.

    AI models don’t evaluate “who links to you.” They evaluate factual density, structural parsability, and cross-platform corroboration. A citation in a ChatGPT response might appear as a footnote, a passing mention, or a direct recommendation — and those are not the same thing commercially.

    Here’s the thing: being cited doesn’t mean being recommended. Being recommended doesn’t mean being named first. And being named first on one platform tells you nothing about your position on another.

    GA4 and Search Console track destination traffic. They don’t track the “share of model” — the instances where AI shaped purchase intent without generating a click. That’s where brands are bleeding visibility without realizing it.

    FeatureTraditional BacklinksAI Citations
    Primary SignalLink Equity / PageRankEntity Relevance / Factual Density
    Control MechanismSite editors / WebmastersLLM Retrieval Algorithms (RAG)
    Visibility FormatAnchor text on a web pageFootnotes, summaries, direct mentions
    User IntentNavigation / ExplorationInformation satisfaction / Recommendation
    Success MetricClick-Through Rate (CTR)Visibility Rate / Share of Voice
    Data TrackingGA4 / Search ConsoleAI-specific monitoring (e.g., Topify)

    Metric 1: Visibility Rate — Are You Even in the Room?

    Visibility Rate answers the most basic question: for the prompts your potential customers are typing into ChatGPT or Perplexity right now, how often does your brand appear?

    The calculation is straightforward. If you test 100 prompts relevant to your category and your brand is mentioned in 30 of them, your Visibility Rate is 30%. But the number alone isn’t the insight — the benchmark is.

    Performance TierVisibility RateWhat It Means
    Pre-Visibility0% – 15%Invisible to AI search; high displacement risk
    Developing15% – 30%Cited occasionally; early traction
    Category Presence30% – 50%Regularly in the consideration set
    Category Leadership50% – 75%Recognized as top-tier in the niche
    Category Dominance75% – 100%The consensus answer for relevant queries

    Most mid-market brands fall in the 15–30% range. Most don’t know it.

    What makes this metric harder to manage than search rankings is platform fragmentation. ChatGPT, Gemini, and Perplexity use different retrieval architectures — and the overlap of domains they cite for the same query can be as low as 11%. Your brand can rank well in ChatGPT and be essentially absent from Perplexity for identical queries.

    Topify Visibility Tracking monitors brand presence across these ecosystems simultaneously, providing a normalized score that shows where you’re strong and where the gaps are. Without cross-platform tracking, you’re making strategy decisions based on a fraction of the picture.

    Metric 2: Citation Source — Who’s Vouching for You?

    Here’s the number that surprises most brand teams: 85% of brand mentions in AI answers come from third-party domains. Only 15% come from a brand’s own website.

    Your content strategy alone can’t carry your AI visibility. What matters is whether the right external sources are talking about you.

    AI models seek corroboration. The more a brand appears across trusted external sources, the more likely it is to be retrieved and recommended. The hierarchy looks roughly like this:

    • Public forums: Reddit drives nearly 50% of top sources for Perplexity and features prominently in Gemini results
    • Industry review platforms: G2, Capterra, and Yelp provide the social proof models use to validate recommendations
    • Encyclopedia and news: Wikipedia and major publishers anchor ChatGPT’s general knowledge layer

    The top cited domains for each platform in 2025 look like this:

    RankChatGPTGeminiPerplexity
    1Wikipedia (7.8%)Reddit (2.2%)Reddit (6.6%)
    2Reddit (1.8%)YouTube (1.9%)YouTube (2.0%)
    3Forbes (1.1%)Quora (1.5%)Gartner (1.0%)
    4G2 (1.1%)LinkedIn (1.3%)LinkedIn (0.8%)
    5TechRadar (0.9%)Gartner (0.7%)Yelp (0.8%)

    The strategic question isn’t just “are we on these platforms.” It’s “which specific URLs are carrying our competitors’ visibility, and are we absent from those exact locations?”

    Topify Source Analysis reverse-engineers which domains are fueling competitor citations. That data becomes a PR and content roadmap — target the sources AI trusts, earn the mentions, and eventually those mentions surface in the retrieval layer.

    Metric 3: Position in Answer — First Mention or Footnote?

    Visibility Rate tells you how often you show up. Position tells you whether showing up is actually working.

    In a conversational AI response, the first recommendation carries something researchers call “recommendation bias.” Up to 74% of users choose the AI’s first mentioned option. The difference between being named first and being listed third isn’t just aesthetic — it has a direct impact on whether anyone goes looking for your brand after that interaction.

    A useful scoring framework for quantifying this:

    Placement QualityPointsDescription
    Primary Citation with Link5Named first; includes a direct URL
    Primary Citation (No Link)4Named first; no link
    Secondary Mention with Link3Listed as an option; linked
    Secondary Mention (No Link)2Listed as an option; not linked
    Passing Mention1Brief mention, no recommendation
    Absent0Brand doesn’t appear

    A brand could have a 40% Visibility Rate but score an average of 1.5 on this scale — meaning it’s consistently being listed as “others also include” rather than the lead recommendation. That’s a very different strategic problem than low visibility, and it requires a different fix.

    Topify Position Tracking surfaces this distribution by brand, by competitor, and by prompt type — so you can see not just whether you’re being mentioned, but what kind of role the AI is casting you in.

    Metric 4: Sentiment Score — What Is AI Actually Saying About You?

    Being visible isn’t always a win. If the AI is consistently describing your brand as “an older option worth considering for smaller teams,” that’s visibility working against you.

    AI models characterize brands based on the sentiment of the sources they retrieve. If Reddit threads and review platforms are critical of your product, those attitudes tend to show up in how AI answers frame you. The Net Sentiment Score (NSS) captures this on a scale from -100 to +100.

    The thresholds matter:

    NSS RangePerception StatusStrategic Action
    +60 to +100Brand AdvocacyLeverage for high-intent marketing
    +20 to +60Healthy ReputationMaintain trajectory; optimize for intent
    0 to +20Vulnerable / NeutralFocus on earning “enthusiastic” mentions
    Below 0Crisis ZoneIdentify and correct negative source material

    The hallucination category deserves specific attention. AI occasionally generates factually incorrect claims about brands — invented pricing, wrong founding dates, fabricated product limitations. These aren’t just reputation problems; they’re retrieval problems. The fix requires identifying which source material is feeding the error and correcting it upstream.

    Topify Sentiment Analysis uses NLP to detect shifts in AI’s attitudinal tone toward your brand across platforms. A sudden NSS drop is often a leading indicator of a narrative forming on Reddit or review platforms — before it reaches traditional media.

    Metric 5: CVR — Does Being Cited Actually Drive Action?

    The prior four metrics measure what’s happening inside the AI response. CVR (Conversion Visibility Rate) asks whether any of it is translating to commercial outcomes.

    AI-referred traffic is a different animal than traditional search traffic. A user who arrives at your site after reading a ChatGPT recommendation has already been through the research and comparison phase. The AI handled it. That changes the conversion math significantly:

    • B2B SaaS: AI-referred visitors convert at 12–15%, vs. 2.5–4% for traditional organic search — roughly a 4x lift
    • E-commerce: AI traffic converts 42% better than traditional paid search, with users spending 48% more time on-site
    • Lead generation: AI-referred sign-up conversions have been measured at 1.66% vs. 0.15% for traditional organic — an 11x difference

    Not all prompts carry the same conversion potential, though. Prompt intent changes everything:

    Prompt IntentConversion PotentialWhat It Drives
    Informational (“What is…”)LowBrand imprinting / Awareness
    Comparison (“Brand X vs Y”)MediumConsideration / Validation
    Transactional (“Best tool for…”)HighDirect conversion / Purchase

    The challenge is that most of these interactions are “zero-click” — users don’t always visit your site after seeing you mentioned. Topify CVR correlates these invisible influence moments with Branded Search Lift, the measurable increase in users searching for your brand by name in the days following AI exposure.

    That’s the closest proxy to attribution that currently exists for this channel.

    These 5 Metrics Don’t Work in Isolation

    Tracking each number separately misses the point. The value is in reading them together as a diagnostic system.

    A high Visibility Rate with a low Sentiment Score means you’re visible, but the AI is saying something unfavorable. Fix the source material, not the visibility strategy. A strong Position Score on informational prompts with weak CVR suggests you’re winning awareness but not conversion-stage queries — the prompt library needs rebalancing toward transactional intent.

    Here’s a practical operating framework:

    MetricCheck FrequencyWarning ThresholdResponse
    Visibility RateWeeklyBelow 20%Audit content for parsability and entity clarity
    Citation SourceMonthlyCompetitor share 2x yoursTarget high-citation 3rd-party domains via PR
    Position (APS)WeeklyAvg score below 0.5Improve unique data points and information gain
    Sentiment (NSS)DailyScore below 0Identify and correct negative source material
    CVR / Branded SearchMonthlyDeclining trendRealign prompt library toward commercial intent

    The operational problem is that these signals live in different places — AI responses, review platforms, search trend data, traffic analytics. Topify consolidates them into a single dashboard, identifying specific “Citation Gaps” where your brand should appear but doesn’t, and providing a prioritized action list for content and PR teams.

    Without that consolidation, most teams end up checking metrics inconsistently and reacting to problems weeks after they develop.

    Conclusion

    The three recommendation slots in a ChatGPT or Perplexity response are the new prime real estate of the internet. Most brands don’t know whether they’re in those slots or not — and for the ones that don’t know, the answer is usually “not often enough.”

    Visibility Rate, Citation Source, Position, Sentiment, and CVR are the five numbers that tell you the truth. Track them together, act on the gaps, and you move from being indexed to being recommended.

    The brands doing this now will be significantly harder to displace in six months. The ones waiting will be catching up.

    FAQ

    How often should I check my AI citation metrics?

    Weekly for Visibility Rate and Position — AI models update frequently, and citation patterns can shift overnight after a model update. Sentiment should be monitored daily for enterprise brands, specifically to catch hallucinations or emerging negative narratives before they scale. Citation Source analysis is typically most useful on a monthly cadence, since the domain-level signals move more slowly.

    Can I track AI citations without a paid tool?

    You can do a rough version manually — run 20–50 prompts across ChatGPT, Gemini, and Perplexity once a week and log what you find. The problem is accuracy. AI responses are probabilistic; a single run of a prompt doesn’t represent what your audience is actually seeing. Paid tools like Topify iterate each prompt dozens of times across different models and IP locations to produce a statistically significant normalized score. Manual tracking is better than nothing, but it tends to give teams false confidence in incomplete data.

    How is AI citation tracking different from traditional brand monitoring?

    Social listening tracks what humans say to other humans — reviews, posts, comments. AI citation tracking measures what the machine says to potential buyers during the decision phase. A brand could be mentioned 10,000 times on social media; if those mentions aren’t being retrieved by AI models, the brand is invisible in the AI search funnel. The fix is also structurally different: improving AI visibility requires content optimization for parsability and earning corroborating mentions on high-weight domains — not community management.

    Read More

  • Improve Your GEO Score: 5 Changes That Actually Work

    Improve Your GEO Score: 5 Changes That Actually Work

    You ran a GEO score check. The number came back somewhere in the 40s or 50s. Now you’re staring at a dashboard and wondering what, exactly, you’re supposed to do with that information.

    That’s the gap most optimization content doesn’t fill. Knowing your score is step one. Knowing which specific changes will actually move it — and in what order — is where most teams get stuck. Research has a clear answer on this. Pages that hit a GEO score of 0.70 or above, covering at least 12 signal dimensions, achieve a 78% cross-platform AI citation rate. The three factors that drive the most of that outcome aren’t content volume or keyword density. They’re metadata freshness, semantic HTML structure, and structured data.

    Here’s what to fix, and why it works.

    Your GEO Score Isn’t One Metric — It’s a Weighted System

    Most teams treat GEO score like a single number to push upward. It’s not. It’s a composite of 12 signal dimensions that reflect how ready a page is for AI retrieval and citation.

    According to Geoptie’s framework, these dimensions span technical infrastructure, content architecture, authority signals, and monitoring practices. The weighting matters here: “AI interpretability” and “semantic richness” together account for more than 55% of the total score. That’s why brands can have strong content but still score in the 40–60 range — they’ve invested in the wrong dimensions.

    The practical implication is that improving your GEO score isn’t about doing everything at once. It’s about identifying which of the 12 dimensions are dragging your weighted average down. In most cases, three categories explain the majority of the gap.

    The 3 Factors Behind 78% of AI Citation Rate

    Research by Arlen Kumar and Leanid Palkhouski, conducted at UC Berkeley and the Wrodium Research Center, audited 1,702 citations across Brave Summary, Google AI Overviews, and Perplexity. The finding that stands out isn’t just the 78% citation rate at G ≥ 0.70 — it’s the threshold effect. Citation probability doesn’t increase linearly with quality. It jumps once a page crosses the 0.70 line.

    The three factors with the highest correlation coefficients in the logistic regression were:

    FactorCorrelation (r)Primary Mechanism
    Metadata Freshness0.68Addresses RAG time-decay bias
    Semantic HTML Structure0.65Reduces extraction noise
    Structured Data (Schema)0.63Accelerates entity recognition

    These aren’t arbitrary rankings. Each one directly resolves a specific obstacle in the Retrieval-Augmented Generation (RAG) pipeline that AI engines use to pull and synthesize content. A page that scores well on all three gives an AI model cleaner data, clearer context, and more confidence that the content is current.

    High-scoring pages are 4.2 times more likely to be cited than low-scoring pages. That’s the odds ratio from the same study. The asymmetry is significant enough that fixing these three factors should come before anything else.

    Change #1: Refresh Your Metadata Before You Touch Anything Else

    Metadata freshness has a correlation coefficient of 0.68 with AI citation rate — the highest of the three. The reason is straightforward: AI engines with real-time retrieval capability, like Perplexity, are trained to prioritize current, accurate information. Stale metadata acts as a binary filter. A page whose timestamp still reads 2023 can get excluded from the candidate pool before an AI even evaluates its content.

    The data on this is concrete. Content updated within the past 60 days is cited 1.9 times more often than older content. That’s not a marginal improvement — it’s nearly double the citation rate for pages that simply signal recency.

    The operational fix is more specific than just “updating content.” Three fields matter most:

    Last-Modified header: This needs to appear in both the HTTP response header and the HTML source. It should be a machine-readable timestamp, not a visible date string.

    Meta description: AI-optimized meta descriptions should be 50–100 words and state the page’s core conclusion directly. The traditional click-bait format doesn’t serve AI retrieval — a concise, factual summary does.

    OG tags: These are often overlooked. If your Open Graph tags reference an old version of a headline or image, AI systems pulling cached data will work with outdated information.

    For fast-moving industries, a monthly metadata audit is worth building into the content calendar. For evergreen content, quarterly is sufficient.

    Change #2: Rebuild Your Page Structure with Semantic HTML

    The correlation between semantic HTML structure and AI citation rate is 0.65. That’s because AI retrieval systems don’t read pages the way humans do — they parse them. A page built with generic <div> containers creates extraction noise. A page with proper semantic markup gives the retrieval model a clear map.

    Research shows that clear H1–H3 heading hierarchies allow AI models to achieve 85% chunking accuracy during text parsing. Without semantic structure, content gets fragmented or loses context during extraction — meaning even good content can get cited incorrectly or not at all.

    Five structural changes with the highest GEO impact:

    <article> and <section> tags: These define content boundaries. When a retrieval system encounters these tags, it treats the content inside as a discrete information block — which is exactly how you want your content to be indexed and vectorized.

    <header> and <main> tags: These help crawlers separate navigation and sidebar content from the page’s actual substance. Without them, irrelevant sidebar text can get weighted alongside your core argument.

    Strict H1–H3 hierarchy: H2 for primary sections, H3 for supporting points. This creates a natural summary-to-detail relationship that AI can use to generate accurate, structured answers.

    <table> with <thead>: Tabular data gets cited at 2.5 times the rate of plain-text equivalents. If you’re making comparisons or presenting data, a table isn’t just visually cleaner — it’s structurally superior for AI extraction.

    <cite> and <blockquote>: When your content references expert sources, these tags explicitly signal attribution. That transparency raises the page’s authority score in AI evaluation.

    The underlying principle: a “clean” HTML architecture is the physical prerequisite for G ≥ 0.70. You can’t compensate for structural chaos with better content.

    Change #3: Add Structured Data — and the Right Kind

    If semantic HTML is about making content extractable, JSON-LD structured data is about making it understandable. It converts natural language into machine-readable fact sheets that AI engines can use to verify, categorize, and confidently cite information.

    Pages with structured data show 43–44% higher visibility in AI responses. The mechanism is direct: when a RAG pipeline matches a query to a page with Schema markup, the AI’s confidence in generating an accurate answer increases. That confidence translates into citation.

    Four Schema types that move the needle most:

    FAQPage: This is the highest-leverage Schema type for GEO. Since generative search is fundamentally a question-answering system, FAQ structure allows AI to directly extract a question and its verified answer. Even pages that have lost Google SERP visibility can gain AI citation volume through FAQPage markup.

    Article: Defines content type, author identity, and publication date. This is the primary input for E-E-A-T evaluation — the set of signals AI uses to assess whether an author and publisher are credible.

    Organization: Establishes your brand as a distinct entity. This is what allows AI systems to aggregate information about your brand from multiple sources and attribute it correctly.

    HowTo: For procedural queries, structured step data gets extracted more reliably than long-form prose. If your content explains a process, HowTo Schema turns it into a format AI can use directly.

    The fastest path to implementation: identify the key entities on each page, generate JSON-LD using a Schema generator, and add SameAs properties that link your entities to authoritative third-party profiles. That linkage alone has been shown to raise authority scores by 20% or more. One non-negotiable: render Schema server-side, not via client-side scripts. AI crawlers need to parse it immediately.

    Changes #4 and #5: The Last Mile to 0.70

    Once the technical foundation is in place, two more factors determine whether a page can reach and hold a score above 0.70. These are less about infrastructure and more about content depth.

    Change #4: Strengthen Authority Signals

    In the 12-dimension GEO scoring model, authority signals carry high weight. Research from Princeton (Aggarwal et al., 2023) confirmed that specific authority-building interventions produce measurable citation gains.

    Adding concrete statistics to a page improves AI visibility by 40%. Not approximate ranges — specific numbers. AI engines treat quantitative data as a verification anchor. If your content can make a claim and back it with a precise figure, it becomes more citable than a page making the same claim without evidence.

    Including expert quotations lifts visibility by 30% or more. AI interprets direct attribution as a signal of industry consensus and depth of sourcing.

    The counterintuitive one: citing high-authority external sources within your content. This doesn’t dilute your page’s value — it positions the page as a knowledge hub. Pages that actively cite credible external references have shown visibility gains of 115% in AI responses for Tier 5 sites. The logic is that AI models view outbound links to authoritative sources as a sign that the content is well-researched and contextually accurate.

    Change #5: Optimize for Answer Density

    AI models have a finite context window. They’re looking for pages that deliver the highest information-to-token ratio. A page that answers a question directly, with minimal setup and no filler, is more likely to be selected as a source.

    Content written at a Flesch-Kincaid grade level of 6–8 gets cited 31% more often than content at higher complexity levels. That’s not about dumbing down — it’s about removing friction from the extraction process. Short sentences and direct statements are faster for AI to parse and verify.

    Each paragraph should orbit one central fact. Transitional throat-clearing (“As we’ve seen so far…”) consumes token space without adding information. Cut it.

    There’s also a credibility angle: content that explicitly acknowledges trade-offs or presents multiple perspectives is 1.7 times more likely to be cited than single-viewpoint content. AI models appear to weight intellectual honesty — admitting what a recommendation doesn’t cover — as a quality signal.

    You’ve Optimized. Now Track Whether AI Actually Notices.

    These five changes will move your GEO score. But here’s what most teams discover next: they don’t know if it worked.

    AI citation is probabilistic. The same prompt can produce different results across ChatGPT, Perplexity, Gemini, and Claude — and can shift week to week as models update. A one-time score check tells you where you started. It doesn’t tell you whether your brand is being cited now, what language AI is using to describe you, or which competitors just moved ahead of you in AI recommendations.

    That’s the problem Topify is built to solve. The GEO Score Checker gives you a baseline — and ongoing monitoring across major AI platforms shows you what happens after you’ve made the changes. You can track visibility by prompt, monitor sentiment in AI-generated descriptions, and analyze which source URLs AI platforms are actually citing when they answer questions in your category.

    Top brands in competitive categories reach 12% AI visibility on relevant prompts. The average is 0.3%. The gap between those two numbers isn’t just about content quality — it’s about whether a brand is iterating on real citation data or guessing.

    Optimization without measurement is a one-time event. Measurement turns it into a system.

    Conclusion

    A GEO score below 0.70 typically means a page has structural gaps, not content gaps. The three highest-leverage changes — metadata freshness, semantic HTML architecture, and structured data — address the retrieval and comprehension bottlenecks that prevent AI from citing even well-written content.

    Changes #4 and #5 close the gap for pages already near the threshold. Authority signals and answer density are what separate a page that sometimes gets cited from one that consistently does.

    Start with a GEO score check to know which dimensions are pulling your score down. Fix the technical layer first — metadata, HTML, Schema. Then add the content-level authority signals. And build a monitoring system that tells you whether the citations are actually coming in.

    The research is clear on what the threshold is. Whether you’ve hit it is a measurement question, not a guessing one.


    FAQ

    Q: What is a good GEO score for AI citations?

    A: A score of 70 or above is generally considered the baseline for entering the AI citation pool. Pages at this level have sufficient semantic structure and metadata to be included in multi-engine retrieval. To hit the 78% cross-platform citation rate identified in the Kumar et al. research, you’d want to push toward 85+. Most current websites score in the 40–60 range, so exceeding 70 already represents a significant competitive advantage.

    Q: How long does it take to see GEO score improvements after optimization?

    A: Technical changes — Schema markup, metadata updates, HTML restructuring — typically register within 1–2 weeks, once AI crawlers re-index the page. Longer-term authority signals like E-E-A-T improvements can take 3–6 months to shift how AI models represent your brand in non-RAG contexts, where the underlying knowledge base needs time to update.

    Q: Does improving my GEO score also help traditional SEO rankings?

    A: Yes, and the correlation is strong. Around 80% of AI citations already come from pages that rank in Google’s top 10. The technical requirements for GEO — structured data, fast load times, semantic markup, quality external links — are the same signals Google’s ranking algorithm rewards. Improving your GEO score is, in practice, a reinforcement of the same content quality and technical health that drives traditional SEO.

    Q: Which Schema type has the biggest impact on GEO score?

    A: FAQPage Schema tends to have the highest GEO impact because generative search is fundamentally a question-answering system. AI engines can directly extract the question and its answer from FAQPage markup, which is cleaner and more reliable than parsing a long-form paragraph for the same information. Article and Organization Schema are also high-priority additions, particularly for establishing entity identity and E-E-A-T signals.


    Read More