Category: Article

  • 5 Claude Token Mistakes Killing Your AI Budget

    5 Claude Token Mistakes Killing Your AI Budget

    You’re spending more on AI than ever. But your brand is still missing from ChatGPT’s answers.

    That’s not a budget problem. That’s a usage problem.

    Most teams treating Claude token usage as a throughput metric — more tokens spent, more content generated, more progress made. The math looks clean until you realize none of those outputs are earning citations in AI-generated answers. You’re not buying visibility. You’re buying noise.

    Here are the five token mistakes that are quietly draining your AI budget, and what to actually do about them.

    Mistake #1: Prompting for Output, Not for Position

    The most expensive habit in AI marketing is using Claude as a content factory.

    Teams prompt Claude to “write a blog post” or “draft a product page,” consume the tokens, and call it done. But generating output is not the same as earning position. In the GEO era, what matters isn’t how much content you publish — it’s whether AI engines cite your brand when users ask relevant questions.

    Research confirms the gap is real. Brands ranking in the top three organic Google results often have zero visibility in AI-generated summaries for the same queries. AI models don’t “search” — they retrieve and synthesize based on what they call Fact Units: structured, verifiable information that reduces hallucination risk.

    When a Claude prompt produces purely promotional copy (“We are the best CRM for teams”), the AI treats that source as high-risk and omits it. When the same prompt produces a technical specification or a verifiable comparison stat, the model has grounding material it can cite.

    Every token budget decision should start with one question: does this output earn a position, or just fill a page?

    Mistake #2: Running Broad Prompts When Specific Ones Cost Less

    Broad prompts are a budget multiplier — and not in a good way.

    A prompt like “Analyze the CRM market for small businesses” triggers what’s known as Prompt Bloat: irrelevant context gets processed, input costs spike, and the output is too generic to drive AI citations. You’ve spent more tokens to get less value.

    According to research on prompt engineering economics, specific intent-driven prompts — those that define persona, comparison target, and constraint — consume roughly 500 to 800 tokens while achieving an AI recommendation rate of 79%. Broad prompts consume 5,000-plus tokens and hit less than 15%.

    The fix is Prompt Research, not keyword research. Instead of brainstorming topics, identify the specific conversational paths real users take when researching your category on ChatGPT or Perplexity.

    Topify‘s High-Value Prompt Discovery is built for exactly this. It identifies Intent Clusters — the specific buying prompts where users compare vendors and seek recommendations — and estimates AI search volume across platforms. More importantly, it surfaces Invisibility Gaps: high-intent prompts where your brand ranks well on Google but is absent from the AI’s synthesized answer. That’s where your Claude token usage should be concentrated, not spread thin across generic topics.

    The 80/20 rule applies here. Focus token spend on the 20% of prompts that drive 80% of AI recommendations. Everything else is overhead.

    Mistake #3: Tracking Token Count Instead of Visibility Impact

    This one is a governance failure, not a content failure.

    Most organizations track token consumption the same way they track bandwidth: as an infrastructure cost to minimize. Cost-per-token goes down, the spreadsheet looks better, leadership signs off. But if those tokens aren’t producing AI citations, the ROI is effectively zero.

    A team might consume 100 million tokens to generate 1,000 blog posts. If none of those posts earn a mention in ChatGPT or Perplexity when a user asks a relevant question, the budget was spent on a content library that the primary discovery channel of the next decade will never touch.

    The KPI shift that actually matters:

    Legacy MetricModern GEO MetricWhat It Measures
    Token UsageAI Visibility ScorePresence, not cost
    Cost per 1M TokensIntelligence Efficiency RatioValue per dollar
    Page Views / CTRCitation RateAuthority and trust
    Message VolumeConversion Visibility Rate (CVR)AI-to-revenue pipeline

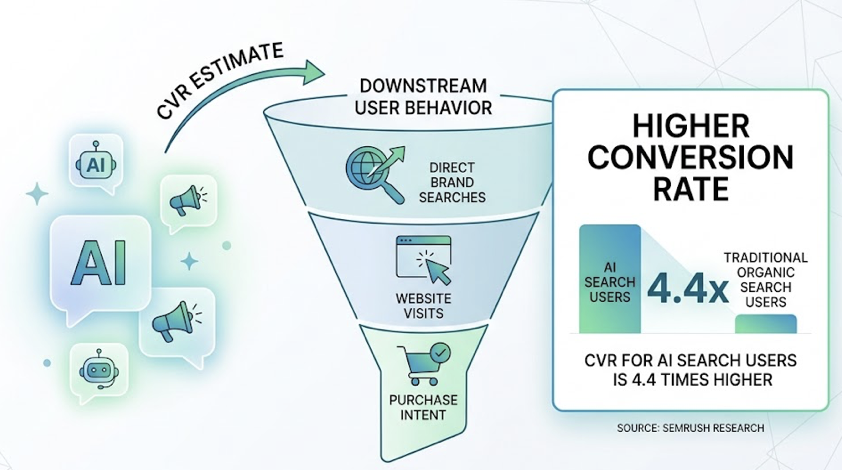
    Topify’s Visibility Tracking measures the frequency with which a brand appears in primary synthesized answers across multiple LLMs for a defined set of high-value prompts. Its CVR metric connects AI recommendations to downstream signals: branded search lift, site visits from ChatGPT-User agents, and lead flow.
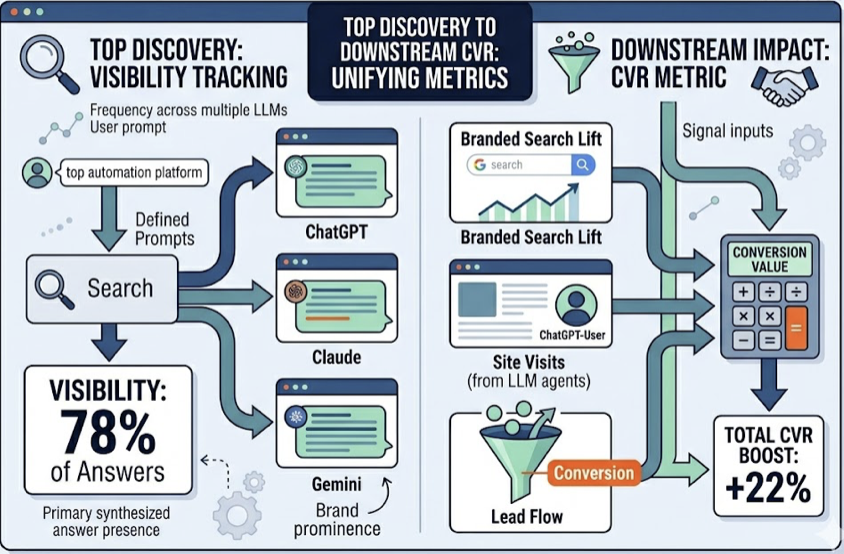
    Organizations that make this shift can see 320% growth in citation rates within 90 days — not by spending more tokens, but by reallocating existing spend toward high-visibility Fact Units. That’s not a marketing claim. That’s what happens when you stop measuring consumption and start measuring position.

    Mistake #4: Ignoring Which AI Platforms Actually Recommend You

    Platform Monoculture is one of the most expensive blind spots in AI marketing.

    Most teams optimize for one model — usually Claude or ChatGPT — and assume the visibility carries across platforms. It doesn’t. Research shows the overlap between citations in ChatGPT and Perplexity for identical queries can be as low as 11%.

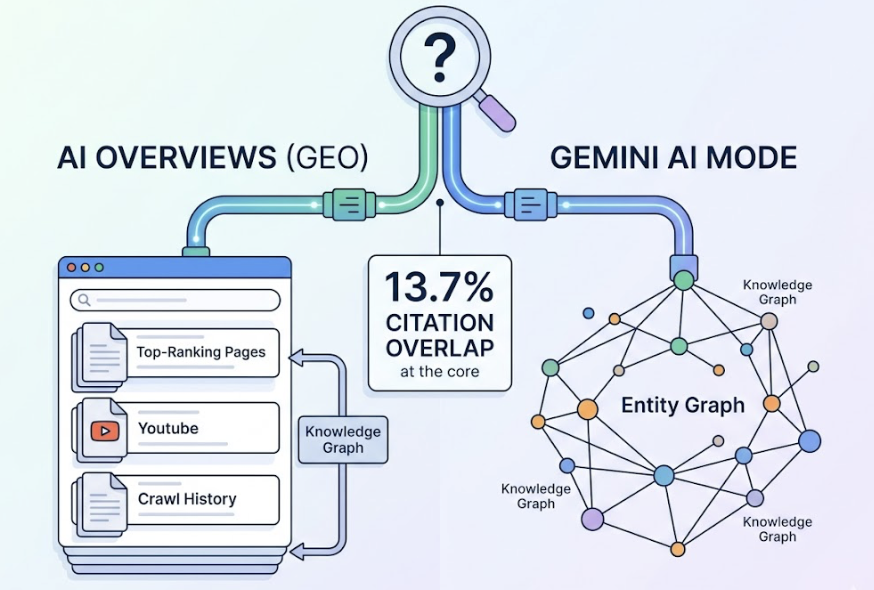
    Each AI engine has its own retrieval philosophy. Claude prioritizes long-form technical documents and structured content. Perplexity leans heavily on Reddit threads, niche blogs, and real-time sources, with Reddit accounting for nearly 47% of its citations. Gemini oscillates between its Knowledge Graph and traditional organic signals. DeepSeek pulls from documentation, code repositories, and academic papers.

    A brand optimized only for Claude’s retrieval logic — white papers, technical FAQs, structured data — might be invisible on Perplexity because it has zero Reddit presence. A competitor with 20 community-sourced threads discussing their product will dominate there, regardless of how polished your corporate blog is.

    Here’s the platform breakdown:

    PlatformCitation RateSource Preference
    ChatGPT~60%Bing Index, high-authority blogs
    Perplexity13%Reddit (46.7%), real-time web
    Gemini6-76%Wikipedia, YouTube, Google Graph
    ClaudeHighPDFs, technical whitepapers
    DeepSeekVariableDocumentation, code repos

    Without cross-platform intelligence, you can’t see that gap. Topify’s multi-model Visibility Tracking monitors brand presence simultaneously across ChatGPT, Gemini, Perplexity, and emerging players like DeepSeek and Doubao. When it reveals a competitor is dominating Perplexity via community threads while you’re only cited on ChatGPT via your corporate blog, you can reallocate budget before that visibility gap compounds.

    Diversify your token strategy across platforms. One retrieval logic doesn’t fit all.

    Mistake #5: No Feedback Loop from AI Citations Back to Content

    This is the silent budget killer most teams never diagnose.

    You use Claude tokens to produce content. You publish it. You check traffic analytics. You don’t check which of that content is actually being cited by AI engines — and which of it is being silently ignored.

    Without Source Forensics, you’re optimizing blind.

    Here’s the technical reality: AI retrieval systems don’t ingest entire pages. They extract Fraggles — small text fragments typically 50 to 150 words long — and evaluate them for Information Density. A 2,000-word blog post with only one extractable Fact Unit wastes the tokens spent on the other 1,850 words from a GEO perspective. You’re paying Claude to write content that AI engines mostly skip.

    Topify Source Analysis reverses this. It extracts every URL cited in an AI response and classifies it as Owned, Competitor, or Third-Party Reference. When it finds that a competitor is being cited because they have a cleaner machine-readable pricing table or a more fact-dense technical FAQ, you get a direct content brief — not a vague recommendation to “improve quality.”

    The execution workflow matters too. Topify’s one-click GEO execution converts that intelligence into content action: stripping superlatives and replacing them with verifiable specifications, restructuring content to increase Information Density, and syncing brand data across authoritative grounding layers like Wikipedia, LinkedIn, and G2 that AI engines use for cross-referencing.
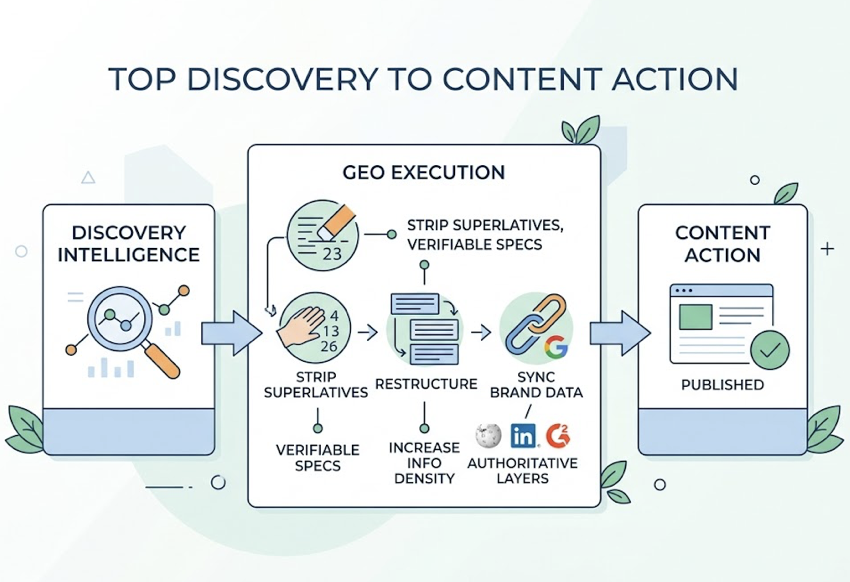
    The feedback loop is what separates brands that grow AI visibility from brands that keep guessing. Without it, you’re spending tokens and hoping.

    What Good Claude Token ROI Actually Looks Like

    Tokens are inputs. Visibility is the output that matters.

    The shift from output-centric to position-centric token strategy changes everything. It’s less about generating more content, more about ensuring each piece earns a position in the AI’s recommendation logic.

    Three questions every marketing leader should ask before approving Claude token spend:

    Visibility: Did this spend increase our AI Visibility Score or Share of Voice for a high-value prompt?

    Authority: Did it move us from being mentioned to being cited with a verified source link?

    Conversion: Did the AI recommendation result in a branded search lift or a trackable session from a ChatGPT-User agent?

    The results when teams apply this framework are documented. Popl.co achieved a 1,561% ROI with an 18-day payback period after restructuring content for AI comprehension. Grüns grew Share of Voice from 2.0% to 12.6% in 60 days using a prompt-led cluster strategy.

    MetricUnmanaged SpendManaged GEO Spend
    Token ROILess than 1:13.7:1 to 15:1
    Conversion Rate2.8% (standard organic)14.2% (AI-referred)
    Visibility GainStagnant / unmeasured320%-1,000% citation growth
    Content StrategyHigh volume / low signalLow volume / high signal density

    The difference isn’t budget. It’s how the budget is directed.

    Topify turns Claude token usage into a structured, measurable growth channel — tracking visibility across seven key metrics: visibility, sentiment, position, volume, mentions, intent, and CVR — so every dollar spent has a clear line to brand authority.

    Conclusion

    The enterprise AI budget isn’t being killed by the price of tokens. It’s being killed by how they’re used.

    Tokens are the fundamental currency of AI work. Their value is realized only when they secure a brand’s position in the synthesized answers of generative engines. Prompting for output in a world that rewards position is a recipe for strategic invisibility.

    Avoid these five mistakes — output-centrism, broad prompting, KPI misalignment, platform siloing, and missing feedback loops — and your token budget becomes a competitive asset. Keep making them, and a competitor with a smarter allocation strategy will own the AI answer instead of you.

    Stop measuring what you spend on Claude. Start measuring what you own in the AI’s knowledge graph.

    Start tracking your AI visibility with Topify before a competitor already has.


    FAQ

    How many tokens does it take to rank in AI answers?

    Ranking in an AI answer isn’t a function of token volume. It’s about Information Density and Semantic Proximity. A 500-token prompt that injects high-quality Fact Units into the AI’s grounding layer is more effective than 10,000 tokens of generic copy. Brands appearing across four or more authoritative platforms — Reddit, G2, news sites, and niche blogs — are 2.8x more likely to be cited.

    Is Claude better than other models for AI visibility content?

    Claude (the 3.5 and 4.6 series) is well-suited for generating deeply structured content that provides the Technical Justification AI engines look for when citing sources. That said, for broad consumer discovery, ChatGPT’s market share makes it the primary visibility target. Perplexity is most accessible for niche sites due to its consistent citation behavior — and its reliance on Reddit means community presence matters as much as content quality.

    What’s the difference between token optimization and GEO optimization?

    Token optimization is a financial and technical discipline: reducing cost-per-request through model selection (Claude Haiku instead of Opus, for example) and context management. GEO optimization is a strategic marketing discipline: increasing how frequently and prominently your brand appears in AI-generated answers. Token optimization manages the spend. GEO optimization manages the impact. You need both — but most teams only do the first.

    Can I track AI visibility across platforms like DeepSeek or Doubao?

    Yes. Topify’s surveillance covers global and open-source models including DeepSeek and Doubao, in addition to the major Western platforms. As the AI ecosystem moves toward Machine-to-Machine communication — where autonomous agents query multiple models to complete tasks — multi-model visibility tracking becomes a baseline requirement, not a premium add-on.
    Read More

  • DeepSeek V4 Is Out. Is Your Brand Visible on It?

    DeepSeek V4 Is Out. Is Your Brand Visible on It?

    The biggest open-source AI drop of 2026 just changed where your audience searches. Here’s what it means for your brand visibility strategy.

    Most marketers heard about DeepSeek V4’s release and filed it under “model news.” That’s a mistake. DeepSeek V4 isn’t just a smarter chatbot. It’s a new discovery channel, and by March 2026, it was pulling 350.8 million monthly web visits with no signs of slowing down.

    If you’re not tracking your brand on it, you’re not just missing data. You’re missing recommendations.


    DeepSeek V4 in Plain English: What Actually Changed for Brand Visibility

    Forget the parameter counts. What matters for marketers is behavioral change, and DeepSeek V4 changed a lot.

    V3 was reactive. A user asked, and the model answered by pulling from what it had seen. V4 operates differently. It runs what researchers call a “Deliberative Search Model,” a cycle of Planning → Query Generation → Search → Reflection before it ever surfaces a recommendation. In practice, this means the model is no longer summarizing the internet. It’s auditing it.

    When a user asks DeepSeek V4 to recommend an enterprise CRM, the model doesn’t just pull a list. It decomposes the query into verification points, including scalability benchmarks, security certifications, and verified user reviews, then cross-validates claims across sources before assigning confidence scores.

    How DeepSeek V4 Differs from V3 in the Way It Recommends Brands

    The table below captures what’s actually shifted for brand teams:

    Behavioral DimensionDeepSeek V3DeepSeek V4
    ReasoningSingle-pass inferenceMulti-stage “Thinking” mode
    Citation styleBroad summariesFootnote-level verifiable sources
    Task behaviorReactive responsesAgentic workflow execution
    Context window128K tokens1 million tokens (“Interleaved” history)

    The context window expansion isn’t a technical footnote. A 1-million-token window means V4 can process a full decade of brand financial reports or an entire enterprise documentation site in one pass. It’s no longer skimming. It’s reading.


    Why Marketers Are Paying Attention to DeepSeek V4 Now

    DeepSeek V4’s global reach grew from 33.7 million monthly active users in January 2025 to 181.6 million by February 2026, a roughly 430% increase year over year.

    That growth isn’t evenly distributed. Over 51% of DeepSeek’s monthly active users come from China, India, and Indonesia. If your brand targets any of those markets, or the broader Asia-Pacific region, DeepSeek V4 is no longer optional to monitor. It’s table stakes.

    The economic efficiency of V4 is the other driver. DeepSeek V4 Flash is priced at roughly $0.14 per million input tokens, approximately 1/100th the cost of comparable closed-source models. That price point means thousands of third-party applications are integrating DeepSeek as their intelligence layer, from customer support bots to competitive analysis tools.

    More AI surfaces. More places your brand can either show up or go missing.


    Your Brand Is Already on DeepSeek V4. Just Not How You Think.

    Here’s what most marketing teams don’t realize: AI answers are not search results. They’re active recommendations. Your brand is likely already appearing in DeepSeek’s reasoning pool. Whether it’s being represented accurately is a different question entirely.

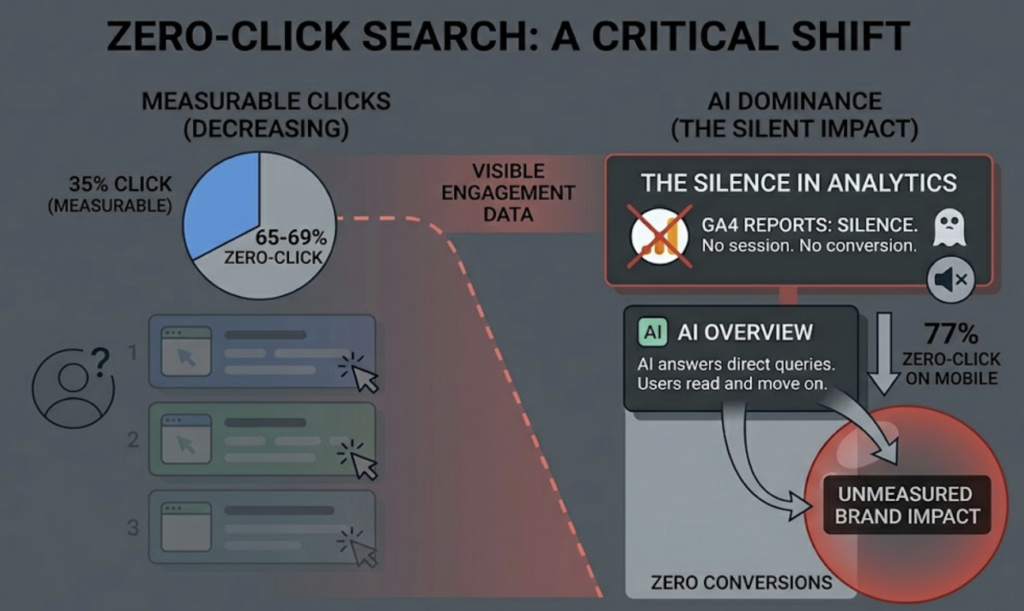
    Traditional SEO metrics don’t exist in a zero-click AI environment. There are no impressions. There are no clicks. There’s only whether the model selects your brand as evidence, or filters it out.

    Research from the report above identifies three specific gaps driving brand invisibility on DeepSeek V4:

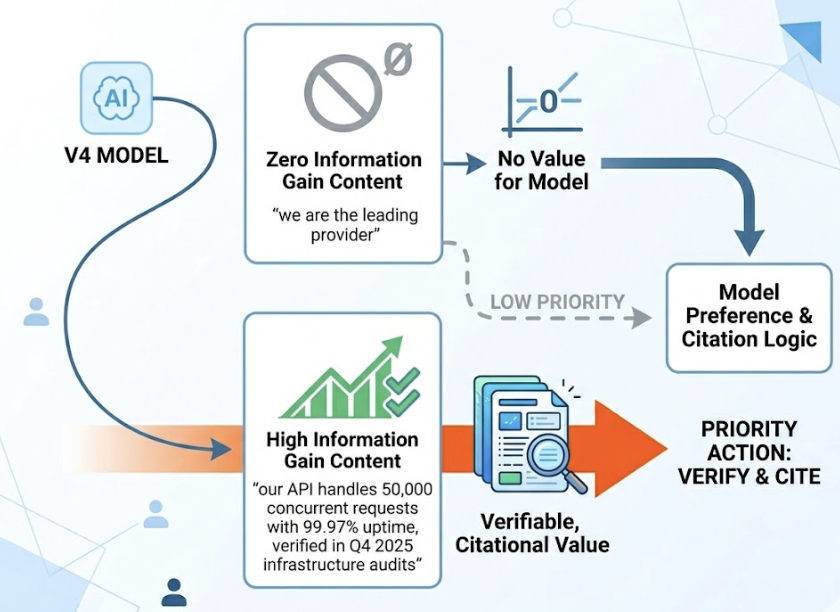
    The Information Gain Gap. V4 is trained to prioritize content that provides unique, structured, factual data. If your content replicates information available elsewhere, the model’s reasoning agent treats it as redundant and skips it in favor of the original source. “Me-too” content doesn’t survive V4’s audit.

    The Extraction Gap. Content locked in PDFs or behind non-semantic code is difficult for DeepSeek’s Retrieval-Augmented Generation systems to parse into structured verification points. The model can’t extract what it can’t read cleanly.

    The Persistence Problem. Only 30% of brands maintain consistent visibility across multiple regenerations of the same prompt. A brand that appears in one session may vanish entirely in the next, because V4’s “Thinking” mode can produce different reasoning paths through the same query.

    The median enterprise brand is cited in only 3% of the relevant AI answers where it should logically appear. That’s not a ranking problem. That’s a content architecture problem.


    What DeepSeek V4’s Reasoning Upgrade Means for Your Content Strategy

    DeepSeek V4’s multi-step reasoning changes what “good content” means. Writing for emotion won’t get you cited. Writing for keyword density won’t either.

    V4’s recommendation logic is built around “Information Gain.” The model favors sources that provide raw data, technical documentation, and structured specifications, the kind of content that gives it something new to extract, not something it already knows. A paragraph that says “we are the leading provider” offers zero information gain. A paragraph that says “our API handles 50,000 concurrent requests with 99.97% uptime, verified in Q4 2025 infrastructure audits” gives the model something it can verify and cite.

    The strategic shift looks like this:

    Optimization LayerOld GoalDeepSeek V4 Goal
    Content goalClicks and impressionsInclusion in reasoning chains
    Writing focusKeyword densityVerifiable ground truth
    Page structureEngaging narrativeData-rich specifications
    Success metricHigh rankingSelection as primary evidence

    The “Atomic Answer” strategy is worth implementing now. This means placing a 30-to-60-word direct factual summary at the top of every high-value page, a format that directly supports V4’s “Extract Agent” in converting natural language into independent verification points.

    Also worth noting: 82% to 85% of AI citations come from third-party sources like Reddit, industry forums, and academic publications. If your content strategy is focused solely on your owned domain, you’re working with roughly 15% of the available citation surface. The rest of the authority signals DeepSeek uses to validate brand recommendations live off-site.

    Topify’s Source Analysis feature reverse-engineers the exact URLs and third-party threads DeepSeek cites in your category. That gives you a map of where the model’s authority signals are actually coming from, and where your brand can realistically be planted into that citation network.


    How to Track Your Brand’s Presence on DeepSeek V4

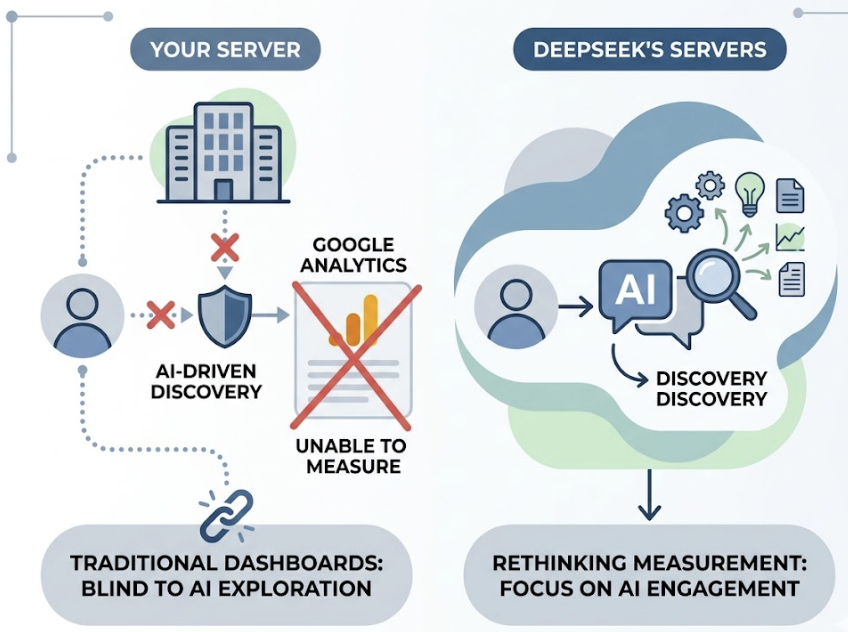
    Google Analytics won’t measure this. The interaction happens on DeepSeek’s servers, not yours. Traditional analytics tools are structurally blind to AI-driven discovery, which means if you’re relying on existing dashboards, you’re measuring the wrong channel entirely.

    Tracking brand presence on DeepSeek V4 requires a framework built around seven core metrics:

    1. AI Visibility Score (AVS): The percentage of relevant, high-intent prompts where your brand appears.
    2. Mention Frequency: How often DeepSeek names your brand without necessarily linking to it.
    3. Sentiment Polarity: A 0-100 score tracking how favorably the AI characterizes your brand.
    4. Brand Position Index: Whether your brand is named first in a comparison or buried in a footnote.
    5. Information Gain Gap: How much unique data your content provides compared to category baseline.
    6. Citation Rate: How often DeepSeek provides a specific URL back to your brand as a source.
    7. CVR (Conversion Visibility Rate): Connecting AI mentions to downstream branded search lift or revenue signals.

    Topify already covers DeepSeek as a tracked platform alongside ChatGPT, Gemini, Perplexity, and others. All seven metrics above are available in a single dashboard, which matters because cross-platform visibility gaps are often where the most actionable insights live.

    Three steps to get started:

    Step 1: Prompt-Level Audit. Identify the top 50 high-intent prompts your buyers use during discovery and evaluation, for example, “How does [your product] compare to [Competitor] for [Use Case]?”

    Step 2: Source Analysis. Use Topify to reverse-engineer which external domains DeepSeek V4 is citing to validate claims in your category. That list tells you exactly where to build authority.

    Step 3: Continuous GEO Monitoring. Set up automated scanning to track Persistence and Sentiment Drift over time. V4 retrains on new data, so what’s true this month may shift by next quarter.


    DeepSeek V4 vs. ChatGPT: Where Should You Focus First?

    This is no longer an either/or question. But it is a sequencing question.

    FeatureDeepSeek V4ChatGPT (GPT-5.x)
    Primary audienceAsia, developers, researchersUS/EU, generalists, creatives
    Cost efficiencyExtremely high (1/10 to 1/100)Premium pricing
    Reasoning behaviorTransparent, logical, citation-heavyFluid, nuanced, conversational
    MultimodalityMainly text and imagesAdvanced voice, video, vision
    Best use caseTechnical B2B, fact-checking queriesBrand storytelling, broad awareness

    Bottom line: if your brand is in a technical category (SaaS, FinTech, engineering) or targets Asia-Pacific markets, DeepSeek V4 should be your primary optimization target in 2026. Its reasoning traces pick up on structured technical documentation more aggressively than ChatGPT’s conversational model.

    That said, both platforms are now active discovery channels, and treating them as separate silos leads to blind spots. A cross-platform tracking approach, monitoring visibility scores across ChatGPT, DeepSeek, Perplexity, and Gemini simultaneously, is the only way to see the full picture.


    Conclusion

    DeepSeek V4 is not just a model update. It’s a signal that the Agentic Era has arrived, where brands are no longer found via keywords but selected through multi-step reasoning chains.

    The shift from “search results” to “active recommendations” means brand visibility is now a probability. That probability is shaped by verifiable evidence, information gain, and third-party authority signals. None of those are traditional SEO metrics.

    Marketers who aren’t monitoring their DeepSeek presence are flying blind in a discovery channel that now reaches 350 million users and powers thousands of third-party applications. The mandate for 2026 is clear: integrate DeepSeek into your AI visibility monitoring, or risk being filtered out of the reasoning chains that drive tomorrow’s buying decisions.

    Topify tracks brand visibility across DeepSeek, ChatGPT, Gemini, Perplexity, and more, with all seven core GEO metrics in one place.


    FAQ

    What is DeepSeek V4 and why does it matter for marketing?

    DeepSeek V4 is an open-source AI model released in early 2026 with advanced multi-step reasoning capabilities and a 1-million-token context window. It matters for marketing because it functions as an active recommendation engine, not just a search tool, and it reached 350.8 million monthly web visits by March 2026. Brands that aren’t tracking their presence on it are missing a significant and growing discovery channel.

    Does DeepSeek V4 affect my brand’s SEO?

    Not directly in the traditional sense, but it does affect brand discovery. DeepSeek V4 operates in a zero-click environment where there are no impressions or click-through rates to measure. Instead, the relevant metric is whether the model cites your brand as a trusted source in its reasoning chain. This falls under Generative Engine Optimization (GEO), which is distinct from traditional SEO but increasingly critical for brands targeting technical audiences or Asia-Pacific markets.

    How do I know if my brand appears in DeepSeek answers?

    Google Analytics and traditional SEO tools can’t tell you. You need a dedicated AI visibility platform. Topify tracks brand mentions, sentiment, citation rates, and position across DeepSeek and other major AI platforms in real time. The fastest starting point is a prompt-level audit: identify the top 50 queries your buyers use during discovery, then run them through a tracking tool to see where and how your brand currently appears.


    Read More

  • Claude Haiku Token Usage: A Marketer’s Cost Guide

    Claude Haiku Token Usage: A Marketer’s Cost Guide

    You built the campaign brief, wrote the system prompt, and pushed 10,000 customer reviews through your new AI pipeline. The results looked good. Then the invoice came, and the number was three times what you budgeted. The model wasn’t expensive. The prompts were.

    That’s the pattern most marketing teams hit with Claude Haiku token usage: the model is priced right, but the billing logic is invisible until it isn’t. Once you understand how tokens actually work, the gap between “expected cost” and “actual cost” closes fast.

    Haiku 4.5 Isn’t the “Cheap Claude” — It’s the Right Claude for High-Volume Work

    Most teams pick Claude Haiku 4.5 for the price and stick around for the speed. That’s the wrong mental model.

    Haiku 4.5 performs at near-frontier levels for structured, repeatable tasks. Benchmark data shows it matches the coding and reasoning capabilities of the original Claude Sonnet 4, which was state-of-the-art just months before Haiku 4.5 launched. For a marketing team processing thousands of tasks daily, that’s not a budget model. That’s the right model.

    The real distinction across the Claude 4.5 family isn’t quality. It’s task type.

    ModelBest ForLatency
    Claude Haiku 4.5Batch processing, ticket triage, real-time chatSub-second
    Claude Sonnet 4.6Content generation, personalization, deep analysis1–3 seconds
    Claude Opus 4.7Strategic planning, complex multi-agent workflows3–10 seconds

    Think of Haiku 4.5 as the worker, not the consultant. Where Opus handles high-level strategy, Haiku executes the thousands of discrete tasks, like generating social copy variations, categorizing support tickets, or tagging catalog items at scale.

    The Token Math Most Marketers Get Wrong

    A token isn’t a word. That’s the first thing to fix.

    The Claude tokenizer runs on Byte-Pair Encoding, which means 1 token is roughly 4 characters or 0.75 words for standard English prose. But the rate shifts depending on content type, and those shifts have direct cost consequences.

    Content TypeTokens per 1,000 WordsCost Impact
    Standard English prose1,300–1,500Baseline
    Technical marketing copy1,500–1,800~20% higher
    JSON / structured data3,000–4,0002–3x higher
    Chinese or Japanese text2,000+Significant premium
    HTML / JavaScript code2,000–3,000High overhead

    If your team runs multilingual campaigns or works with structured data outputs, the token count per task isn’t what you’d estimate from word count alone.

    The bigger issue is the output premium. Input tokens on Haiku 4.5 cost $1 per million. Output tokens cost $5 per million. That’s a 5x multiplier. Every time a prompt asks the model to “explain in detail” or “write a comprehensive draft,” you’re pulling on the expensive side of that ratio.

    Real Numbers: What 100 Customer Reviews Actually Costs

    Here’s a concrete breakdown that illustrates how Claude Haiku token usage adds up in practice.

    Task: Analyze 100 customer comments for sentiment and feature requests.

    Input breakdown: a system prompt with brand guidelines runs about 800 tokens, and 100 comments averaging 150 words each add roughly 20,000 tokens. Total input: 20,800 tokens.

    Output breakdown: 50-token analysis per comment plus a 1,000-token summary report. Total output: 6,000 tokens.

    Total cost per run: approximately $0.05.

    That seems trivial. Scale it to 10,000 comments per day and it becomes roughly $1,524 per month, assuming clean, single-pass calls. Add multi-turn conversation history that gets re-sent on every message, and that monthly number can increase by an order of magnitude.

    The math doesn’t lie. The drift comes from not running the math at all.

    5 Habits That Silently Inflate Your Claude Haiku Token Bill

    Analysis of enterprise AI spend in 2026 shows the same five patterns appearing across marketing teams. None of them are obvious. All of them are fixable.

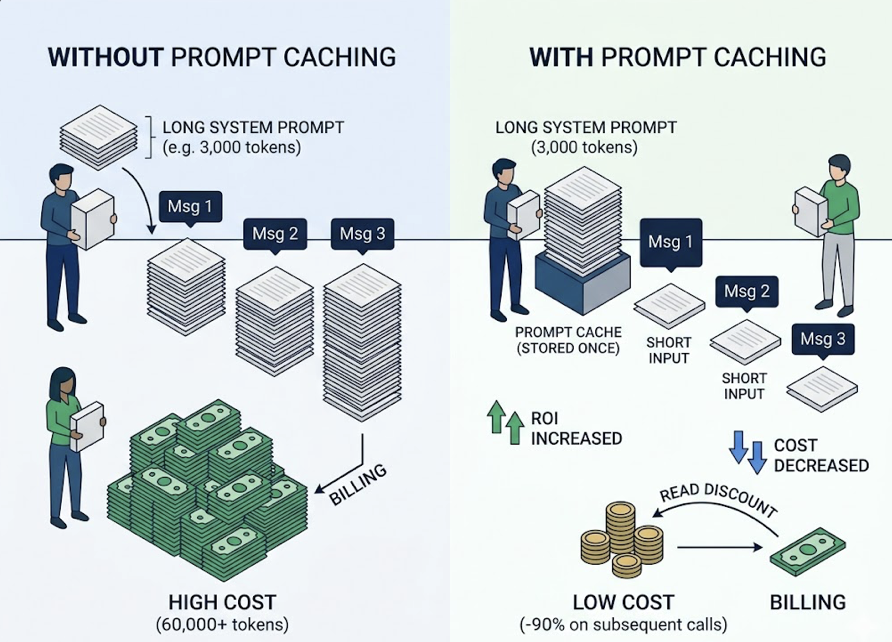
    1. System prompt bloat. Marketing teams often load system prompts like contracts: every brand rule, negative constraint, and few-shot example in one block. A 3,000-token prompt in a 20-message chat generates 60,000 tokens of redundant input billing. Prompt Caching stores these prefixes at a 90% read discount on subsequent calls. It’s the highest-ROI optimization available.

    2. Linear history persistence. Many internal tools append the full chat history to every new message. By message 15, the model is re-reading message 1 for the 14th time. The fix: after 15–20 turns, ask the model to summarize key decisions, then start fresh with only that summary as context.

    3. Verbosity over-requesting. Phrases like “explain your reasoning in detail” or “give me a comprehensive analysis” are output token magnets. Since output costs 5x more than input on Haiku 4.5, these phrases should stay in testing only. In production, add constraints: “no commentary” or “provide only the final JSON.”

    4. Modality inefficiency. Uploading a high-resolution screenshot to extract a headline can consume over 1,300 tokens. The extracted text might be fewer than 50. Use surgical image cropping or prefer text-based markdown uploads over raw PDFs when vision isn’t actually needed.

    5. Skipping batch processing. Teams run bulk tasks through the synchronous API, paying full real-time pricing for work that doesn’t require instant results. The Anthropic Message Batches API provides a 50% discount for workloads that can run within 24 hours. Nightly social sentiment analysis and catalog tagging are natural fits.

    How to Estimate Your Monthly Token Budget Before You Commit

    Budgeting AI spend requires a formula that accounts for variability. A reliable model:

    Monthly cost = (tasks × avg tokens per task × rate) × variability multiplier

    Use a variability multiplier of 1.7x to 2.0x to account for usage spikes, developer testing, and conversation drift. Here’s how that plays out across team sizes:

    Team SizeTask TypeMonthly VolumeAvg Tokens/TaskEst. Monthly Spend
    Small teamContent & email500 tasks2,500~$2–$5
    Mid-marketMixed docs & RAG5,000 tasks10,000~$60–$100
    EnterpriseAutomation & triage50,000 tasks8,000~$450–$600
    High-volumeBatch data analysis500,000 tasks5,000~$2,500*

    *Assumes heavy use of the Batch API for a 50% discount.

    One setting teams consistently skip: max_tokens. Setting a ceiling on every API call acts as a financial safety valve. A malformed prompt or a model loop can burn through thousands of dollars in output tokens before anyone notices. Set max_tokens on every call.

    When Haiku 4.5 Isn’t Enough: The Signals to Watch

    Haiku 4.5 handles 80–90% of daily marketing workloads. But there are real signals that a task has exceeded its capacity.

    Instruction drift is the clearest. If the model starts ignoring constraints like “do not use the word ‘innovative’” after several turns, it’s likely hitting context saturation or reasoning limits. The 200,000-token context window is large enough to ingest an entire product documentation set or a 300-page research PDF in one pass, but the middle of long prompts can lose fidelity.

    Architectural hallucination shows up in agentic workflows. If the model generates logically impossible sub-tasks that look valid on the surface, it’s lacking the global-state reasoning that Sonnet 4.6 or Opus 4.7 provide.

    High-stakes nuance is a harder call. If a campaign involves sensitive cultural translations, legal compliance checks, or anything where getting the tone wrong costs real money, escalate to Sonnet or Opus.

    The most cost-efficient 2026 architecture is a tiered system: Opus 4.7 plans, Haiku 4.5 executes at scale, Sonnet 4.6 reviews for quality and consistency. Teams using this barbell approach typically reduce total AI spend by around 60% compared to uniform Opus deployments, without sacrificing quality on high-stakes outputs.

    The Part Token Optimization Alone Can’t Solve

    You can run perfect token hygiene and still get near-zero ROI if you’re optimizing content for questions nobody asks.

    That’s the gap that sits outside most token management frameworks. Marketing teams spend budget generating content around prompts that have no AI search volume, or prompts where their brand has 0% visibility regardless of content quality. Getting the economics right on the execution side doesn’t fix a strategy built on the wrong inputs.

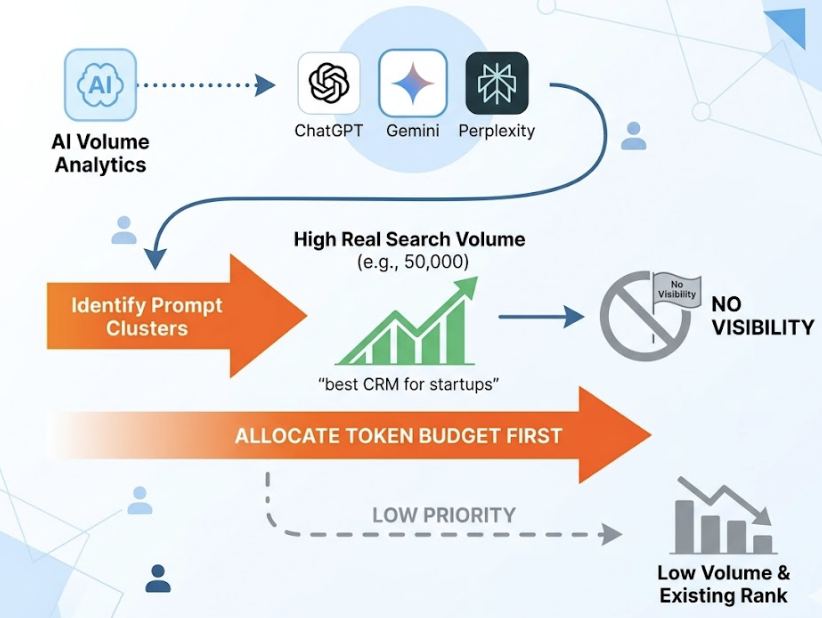
    Topify addresses this from the other direction. Its AI Volume Analytics maps actual user demand across ChatGPT, Gemini, Perplexity, and other major AI platforms, showing which prompt clusters have real search volume and where your brand currently appears or doesn’t. If “best CRM for startups” has 50,000 AI searches per month and your brand has no visibility, that’s where the token budget should go first, not into low-volume queries where you already rank.

    Topify also surfaces what it calls “conversion-killing hallucinations”: cases where an AI engine consistently pairs a brand with outdated pricing or wrong positioning. Catching those patterns early lets content teams fix the upstream sources before they compound. Combined with Haiku’s low-cost, high-throughput execution, the result is a closed loop: know which prompts matter, generate content for those prompts efficiently, and track whether the brand moves.

    The six Topify metrics that define this loop are Visibility Rate, AI Search Volume, Sentiment Score, Position Score, Intent Coverage, and Source Citation Frequency. Together, they convert AI search from an untracked variable into a measurable channel.

    Conclusion

    Token optimization and content strategy are both necessary. Neither one works without the other. A team with perfect token hygiene but no visibility data is spending efficiently on the wrong things. A team with strong GEO strategy but no cost discipline will burn budget faster than the visibility gains justify.

    The practical path: treat Claude Haiku token usage as a managed resource with real budget rules, use the Batch API and prompt caching as defaults rather than optional features, and use a tool like Topify to make sure the token spend is pointing at prompts that actually move the needle. That’s how AI stops being a cost center and starts producing measurable brand outcomes.

    FAQ

    Q: Does Claude Haiku 4.5 support vision and image input?

    A: Yes, Haiku 4.5 supports image inputs. That said, images consume significantly more tokens than equivalent text, often over 1,300 tokens for a single screenshot. For tasks where only the text content matters, extracting or cropping the image before sending it will reduce both cost and latency.

    Q: What’s the context window size for Claude Haiku 4.5?

    A: Claude Haiku 4.5 has a 200,000-token context window for input, which is large enough to process around 150,000 words in a single request. Max synchronous output is 64,000 tokens. For batch workloads, the same 64,000-token output limit applies.

    Q: Can prompt caching actually reduce Claude Haiku token costs significantly?

    A: Yes, significantly. Cached input tokens are re-read at a 90% discount compared to uncached input. For any workflow that reuses a long system prompt across multiple calls (brand guidelines, instructions, few-shot examples), prompt caching is the single highest-ROI optimization available. It’s most impactful when system prompts exceed 1,000–2,000 tokens.

    Q: Is Claude Haiku 4.5 suitable for long-form content generation?

    A: It depends on the task. Haiku 4.5 handles structured long-form output well, such as templated reports, structured summaries, and catalog descriptions at scale. For open-ended editorial content where tone, nuance, and creative judgment matter, Sonnet 4.6 typically produces better results. The hybrid approach, using Haiku for a first draft and Sonnet for review and refinement, often delivers the best cost-to-quality ratio.

    Read More

  • 5 Ways Agentic AI Is Reshaping Brand Visibility in 2026

    5 Ways Agentic AI Is Reshaping Brand Visibility in 2026

    Your content team has been publishing consistently. Your domain authority is solid. Your backlink profile looks healthy. But when a potential buyer asks ChatGPT, “What’s the best tool in [your category]?”, your brand isn’t in the answer. Traditional SEO can’t tell you why, because it was never built to measure what happens inside a synthesized response.

    That gap is widening fast. And agentic AI is now the layer where brand visibility is actually won or lost.

    1. AI Platforms Are Being Monitored Automatically, Across Every Prompt Variation

    Manual spot-checks on ChatGPT or Perplexity used to be the norm. A marketer would run a few queries, see whether the brand appeared, and call it done. That approach misses most of what’s actually happening.

    The core problem is that AI responses are non-deterministic. Run the same prompt twice and you’ll often get different brand mentions, different positions, different framing. A single check gives you one data point. What you need is a probability.

    That’s where agentic AI comes in. Platforms like Topify run high volumes of prompts, often 100 or more per query variation, to calculate a statistically reliable visibility score. The output isn’t “your brand appeared” or “it didn’t.” It’s a confidence interval. You learn that your brand shows up in 34% of relevant prompts on ChatGPT, versus 61% on Perplexity. Those are numbers you can actually act on.

    The other variable is scale. Agentic systems track across ChatGPT, Gemini, Perplexity, and other platforms simultaneously, running continuously rather than on demand. That kind of coverage makes it possible to catch shifts as they happen, not two weeks later when a competitor has already pulled ahead.

    2. Competitor Positions in AI Recommendations Are Being Tracked in Real Time

    In traditional search, rank tracking is straightforward. Your keyword, their keyword, ten blue links, a number from 1 to 10. Generative engine rankings don’t work that way.

    AI responses are narrative. Your brand might be mentioned first, third, or not at all, depending on how the question was framed, which AI platform answered, and what day it is. Research from Princeton University has established that brands mentioned earlier in a synthesized answer carry significantly more weight, leading to what researchers call the Position-Adjusted Word Count (PAWC) metric: a brand mentioned in the first sentence with ten words is mathematically more visible than one appearing fourth with twenty.

    That means position isn’t just a vanity metric. It predicts discovery.

    Agentic AI handles this by running continuous competitor probes. Not “did Brand X appear?” but “where did Brand X appear relative to us, across which prompt types, on which platforms, and is that changing?” The output is a dynamic competitive map, not a static leaderboard.

    What makes this useful in practice: teams can see when a competitor gains first-mention advantage in a specific category and correlate that shift with what changed in their content or PR coverage. The insight is actionable, not just observational.

    3. The Sources AI Trusts Most Are Being Reverse-Engineered

    Most brand teams don’t know which third-party domains AI engines are actually pulling from when they generate answers in their category. That’s a problem, because the source layer is where AI recommendations are built.

    The research here is clear. Third-party coverage gets cited between 72% and 92% of the time in AI responses, while brand-owned content accounts for only 18% to 27%. Wikipedia, Reddit, industry blogs, and review platforms like G2 carry far more weight than your own website. That’s the “Earned Media Gap,” and it means your PR and community strategy is effectively your GEO strategy.

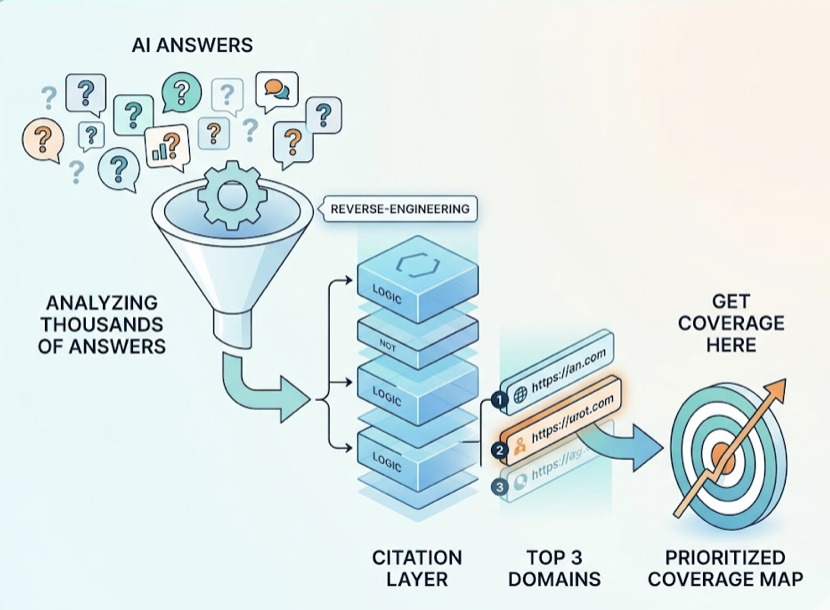
    Agentic AI platforms can now reverse-engineer the citation layer at scale. By analyzing which domains and specific URLs are being retrieved across thousands of AI answers in your category, you get a prioritized map of where your brand needs coverage. Not “write more content,” but “get coverage on these three domains, because those are what ChatGPT is pulling from when users ask about your product type.”

    Topify’s Source Analysis feature does exactly this, identifying the specific third-party URLs that AI platforms cite most frequently. For content teams, that data reshapes the editorial calendar. For PR teams, it replaces guesswork with a ranked target list.

    It also works the other way. If AI platforms are citing outdated pages about your brand, or pulling from a forum thread that misrepresents your pricing, you’ll see it here first.

    4. Sentiment Shifts Are Being Caught Before They Spread

    AI responses aren’t neutral. They carry framing. Your brand might be cited as the leading option, the budget alternative, the one that “works well but has a learning curve,” or the one “not recommended for enterprise use.” Each of those framings affects buyer behavior differently.

    The mechanism behind this is what researchers call AI bias. Confirmation bias in LLMs tends to reinforce existing patterns repeatedly: if the training data associated your brand with a particular limitation, that characterization persists in AI responses even after you’ve fixed the underlying issue. It doesn’t correct itself automatically.

    This is why real-time sentiment monitoring now matters more than a quarterly brand audit. Agentic AI systems score the qualitative framing of brand mentions on a scale, tracking whether your brand is being positioned as a primary recommendation, a secondary alternative, or a cautionary mention. Topify’s sentiment engine runs this continuously, outputting a score from -100 to +100 across platforms.

    The strategic value is in early detection. If Gemini starts describing your product with a “good but expensive” qualifier, you have a window to act before that framing becomes entrenched. The intervention: identify which source documents are feeding that characterization, displace them with current, authoritative content, and monitor whether the sentiment score shifts over the following weeks.

    That’s the difference between narrative control and narrative cleanup.

    5. High-Value Prompts That Drive Competitor Discovery Are Being Surfaced

    Most brands optimize for keywords. Short queries, 4 words on average, designed for a traditional search box. AI search doesn’t work that way.

    The average AI prompt is 23 words long, conversational, and often includes specific constraints: budget ranges, team sizes, technical integrations, use cases. “Best project management tool for a 10-person remote agency that uses Slack and needs a Kanban board under $30 a month.” That single prompt surfaces completely different recommendations than “best project management tool.”

    Most brands have no visibility into which prompts their competitors are being discovered through. That’s the gap agentic AI fills. By continuously mining what researchers call a “Prompt Matrix,” platforms like Topify identify the high-intent questions users are asking AI engines in your category, map them to brand performance data, and surface the specific prompt patterns where competitors have an advantage.

    The practical output: a prioritized list of prompt types where your brand should be appearing but isn’t. Each one becomes a content brief. Not based on keyword volume, but on actual AI discovery behavior.

    One concrete starting point for teams building this capability manually: filter Google Search Console queries using a regex pattern for 10+ word queries. Those long-form questions approximate the prompts users are taking to AI engines, and they reveal the intent structure that generative optimization should be targeting.

    What These Five Use Cases Share

    Each of these applications requires the same underlying capability: continuous, automated, cross-platform execution at a volume that no human team can replicate manually.

    AI citations turn over at a rate of 40 to 60% per month. A competitor that was absent from ChatGPT recommendations last month might dominate them this month. A source that AI trusted six weeks ago might have dropped off entirely. The volatility makes periodic audits nearly useless.

    That’s the core argument for agentic AI in brand visibility: not that it produces better insights than a smart analyst, but that it produces them continuously, across every platform, at a cadence that matches how fast the underlying system is changing.

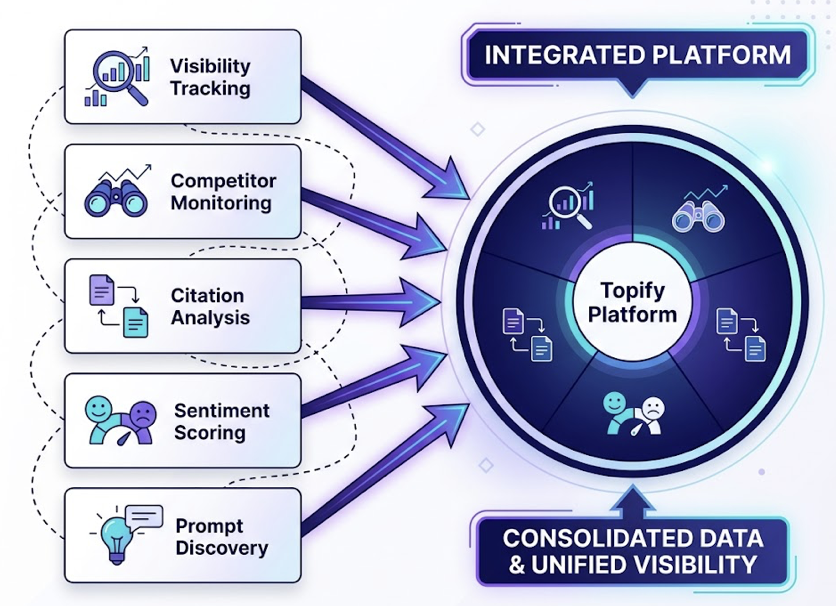
    Topify integrates all five of these workflows into a single platform, covering visibility tracking, competitor monitoring, citation analysis, sentiment scoring, and prompt discovery. For teams moving from manual GEO checks to a structured, measurable program, that consolidation matters. The alternative is stitching together five separate tools, each with its own data model and update frequency, and trying to find the signal across all of them.

    The brands that will be recommended by AI in 2026 are the ones that started treating AI visibility as a measurement problem, not a content problem, early enough to build the feedback loop. The data infrastructure is the strategy. Get started with Topify to see where your brand stands today.

    Conclusion

    Agentic AI didn’t just make brand visibility tracking faster. It made it possible at the scale the problem actually requires. The five use cases covered here, from automated platform monitoring to high-value prompt discovery, each address a different layer of how generative engines decide what to recommend.

    The underlying principle is the same in each case: you can’t optimize what you can’t measure continuously. Traditional SEO tools measure a static ranking system. Agentic AI tools measure a probabilistic, constantly shifting one. Getting that right, consistently, at scale, is the foundation of brand authority in the synthesis economy.


    FAQ

    Q: What is agentic AI in the context of brand visibility?

    A: Agentic AI refers to autonomous AI systems that can plan, execute, and iterate on tasks without constant human input. In brand visibility, this means running thousands of prompts across multiple AI platforms, analyzing citation sources, tracking sentiment shifts, and surfacing high-intent prompts continuously, rather than in one-off manual audits.

    Q: How is agentic AI different from traditional SEO tools?

    A: Traditional SEO tools measure a relatively stable system: keyword rankings, backlink counts, page authority. Generative engine responses are non-deterministic, meaning the same query produces different outputs across sessions. Agentic AI tools are built for this volatility, using probabilistic scoring across large sample sizes rather than static rank positions.

    Q: Can smaller brands benefit from agentic AI visibility tools?

    A: Yes, often more than larger ones. Smaller brands typically have narrower category footprints and fewer resources for manual monitoring. Agentic AI tools surface the specific prompt types and citation sources where they can gain ground efficiently, rather than requiring broad content coverage across the entire category.

    Q: How often should brands run AI visibility audits?

    A: Given that AI citation patterns turn over at 40 to 60% per month, periodic audits are generally insufficient. Continuous monitoring is the baseline expectation for brands treating AI search as a real acquisition channel. Weekly reporting on key prompt clusters is a practical starting point for teams new to GEO.


    Read More

  • Agentic AI Picks Winners. Is Your Brand on the List?

    Agentic AI Picks Winners. Is Your Brand on the List?

    Your SEO rankings are solid. Your domain authority is climbing. Then a potential customer opens ChatGPT and types, “What’s the best tool for [your category]?” The agent returns three names. Yours isn’t one of them.

    That’s not a search ranking problem. It’s a selection problem — and traditional SEO metrics can’t detect it, because they were never designed to measure what an agentic AI decides to recommend.

    Agentic AI Doesn’t Search. It Decides.

    Most brands still think of AI as a smarter search engine. It isn’t.

    Traditional AI answers questions. Agentic AI completes tasks. When a user asks ChatGPT or Perplexity to “find the best project management tool for a remote engineering team,” the agent doesn’t return a list of links and walk away. It evaluates options, applies criteria, and delivers a final recommendation — often without the user ever seeing a search results page.

    That’s the core distinction. A search engine finds the best document. A decision engine solves a problem.

    The implications for brand visibility are significant. In the search era, the goal was to rank. In the agentic era, the goal is to be chosen. Those are two different games, and most brands are still playing the first one.

    From Answer Engine to Decision Engine

    The shift has happened in three distinct phases. First came keyword indexing: rank a page, earn a click. Then answer engines like the early versions of ChatGPT and Perplexity synthesized information and delivered direct responses — the goal shifted from ranking a URL to earning a citation.

    Now comes the decision engine era. A user doesn’t ask “What is the best CRM?” anymore. They ask an agent to set one up. The agent evaluates brands not just on content quality, but on whether the brand has enough consistent, trustworthy data in the AI’s knowledge base to justify a recommendation. Brands that lack that foundation are excluded before the decision process even begins.

    The Shortlist Problem Most Brands Don’t Know They Have

    Here’s what makes this particularly difficult to detect: agentic AI doesn’t consider every brand on the open web. It operates from an internal candidate pool — a shortlist generated through retrieval mechanisms that prioritize authority, semantic clarity, and cross-platform consistency.

    If your brand isn’t in that pool, it will never appear in a recommendation. Not because the AI evaluated you and passed, but because it never considered you at all.

    Organic search traffic is predicted to decrease by 50% or more as consumers shift to generative AI. Yet most brands won’t notice this in their traditional analytics, because the failure happens silently. You’ll still see your Google rankings. You won’t see the AI conversations where your competitors are being recommended and you’re absent.

    This is what makes the shortlist problem so dangerous. It’s invisible until it isn’t — and by then, competitors have already built a substantial head start in AI recommendation share.

    What Agentic AI Looks for Before It Picks a Brand

    To get into the shortlist, it helps to understand what signals the agent is actually using. They’re not what most marketers expect.

    Citations Over Clicks

    In the search era, backlinks were the primary trust signal. In the agentic era, the equivalent is citations — how often your brand appears in AI-generated responses and what sources are being used to justify those mentions.

    Research from Princeton and Georgia Tech found that specific content optimizations can increase AI visibility by 30–40%. Adding statistics boosted citation probability by roughly 40%. Including references to authoritative external sources added another 30–40%. Expert quotations contributed 20–30%.

    The mechanism matters here. Agentic AI systems use RAG (Retrieval-Augmented Generation) to ground their recommendations. They look for content that can be extracted cleanly, stated declaratively, and verified against other sources. Dense, promotional marketing copy fails this test. Factual, specific, high-information content passes it.

    Sentiment Isn’t Soft Data Anymore

    This is the part most brand teams underestimate. LLMs don’t just track whether your brand is mentioned — they evaluate how it’s described across every platform they have access to: G2, Trustpilot, Reddit, industry publications, news sites.

    That sentiment analysis produces a score, typically on a 0–100 scale, and that score directly influences recommendation probability. A brand with a high visibility score but a poor sentiment score for “customer support” won’t appear in queries like “best tool with responsive support.” The agent filters it out.

    More important is sentiment velocity — the direction sentiment is moving over time. A downward trend, even a gradual one, is a leading indicator of declining AI recommendations. A product bug discussed across Reddit in one week can suppress AI mentions several weeks later. By the time traditional brand monitoring picks it up, the damage in AI recommendation share may already be done.

    Entity Consistency Across the Digital Ecosystem

    Agentic AI builds its understanding of a brand entity by synthesizing information across dozens of sources. When those sources contradict each other — conflicting pricing, outdated feature descriptions, varying company names — the agent treats that as uncertainty. And uncertain data typically means exclusion from the shortlist.

    Maintaining what researchers call “Entity Hygiene” means ensuring your brand’s factual record is consistent and accurate across Google Knowledge Panels, Wikipedia, LinkedIn, G2, Trustpilot, and the third-party publications your category relies on. The AI trusts neutral, encyclopedia-style information more than promotional copy. Shifting from a marketing tone to a factual, informative tone isn’t a stylistic choice in the agentic era. It’s a technical requirement.

    Why Your SEO Score Won’t Save You Here

    This is worth stating plainly: the technical logic that drove SEO success for the past 20 years is not the same logic that governs agentic AI recommendations. They’re different systems solving different problems.

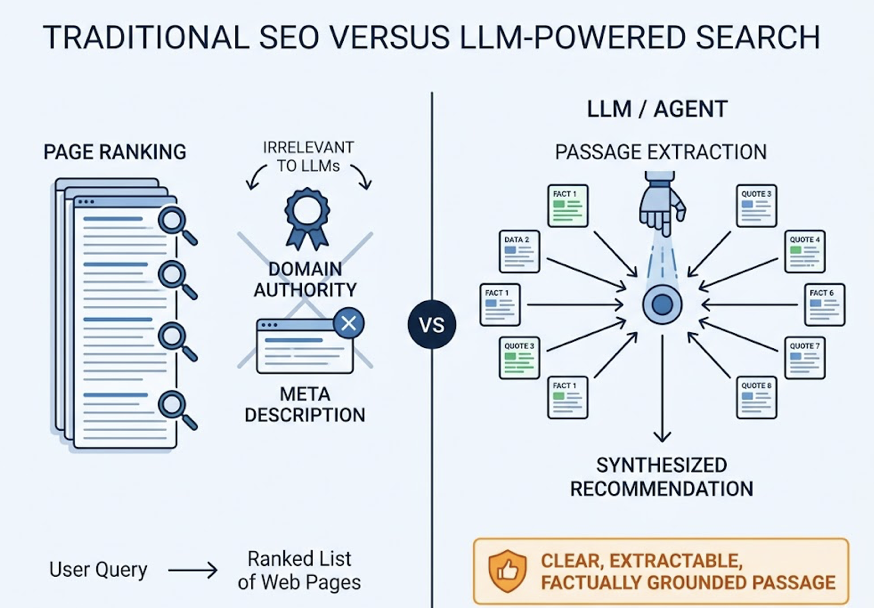
    Traditional SEO ranks pages. LLMs extract and synthesize passages. An agent might pull 10 content chunks from 10 different websites and combine them into a single recommendation. Your page’s domain authority and meta description are irrelevant to that process. What matters is whether your content contains a clear, extractable, factually grounded passage that the agent can use to justify including your brand.

    SignalTraditional SEOAgentic AI
    Primary goalRank a URLBe cited in a recommendation
    Success metricClick-through rateRecommendation probability
    Trust signalDomain authorityEntity confidence + co-citation
    Content unitFull pageIndividual passages/chunks
    Relevance mechanismKeyword matchSemantic similarity (embeddings)

    Content optimized for human conversion — emotional hooks, benefit-focused headlines, CTAs — often performs poorly in AI retrieval environments because it lacks the structural clarity required for machine inference. Agents reward semantic depth, structured data (FAQPage and Organization schema), and declarative language that states the core claim in the opening paragraphs.

    A brand might rank #1 on Google and still be completely absent from ChatGPT or Perplexity recommendations — not because of a content quality issue, but because the content isn’t structured for AI extraction.

    How to Check If You’re on Agentic AI’s Radar

    The most direct starting point is a manual prompt audit. Test your brand across ChatGPT, Gemini, Perplexity, and Claude using three types of prompts.

    Direct-brand prompts: “What does [Brand] do?” / “Is [Brand] reliable?” / “How does [Brand] compare to [Competitor]?” These check whether the AI has accurate, current knowledge of your brand entity.

    Category-level prompts: “What’s the best [category] tool for [use case]?” / “Top 5 [category] platforms for enterprise teams.” These measure your organic recommendation frequency when no brand is specified.

    Scenario-based prompts: “I need to [goal], which tool should I use?” These test how the AI translates complex user objectives into specific brand recommendations.

    For each response, document four things: whether your brand was mentioned at all, where it appeared in the response, what tone the AI used, and which sources were cited to justify the mention.

    That last point is where most manual audits stop short. Knowing that you were or weren’t recommended is useful. Knowing which third-party domains the AI relied on to make that decision is actionable.

    This is where Topify closes a significant gap. Manual audits don’t scale across geographies, languages, or time — and AI platforms update their citation patterns frequently, often weekly. Topify’s Source Forensics feature identifies the specific domains and URLs that AI platforms cite when mentioning your brand (or your competitors), surfacing citation blind spots that you can then target with content or PR strategy. Its Visibility Tracking monitors recommendation frequency across ChatGPT, Gemini, Perplexity, and other major platforms, giving teams a unified score rather than a collection of disconnected snapshots.

    The 30-prompt audit tells you where you stand today. Systematic tracking tells you whether you’re moving in the right direction.

    Getting Into the Shortlist: What Actually Works

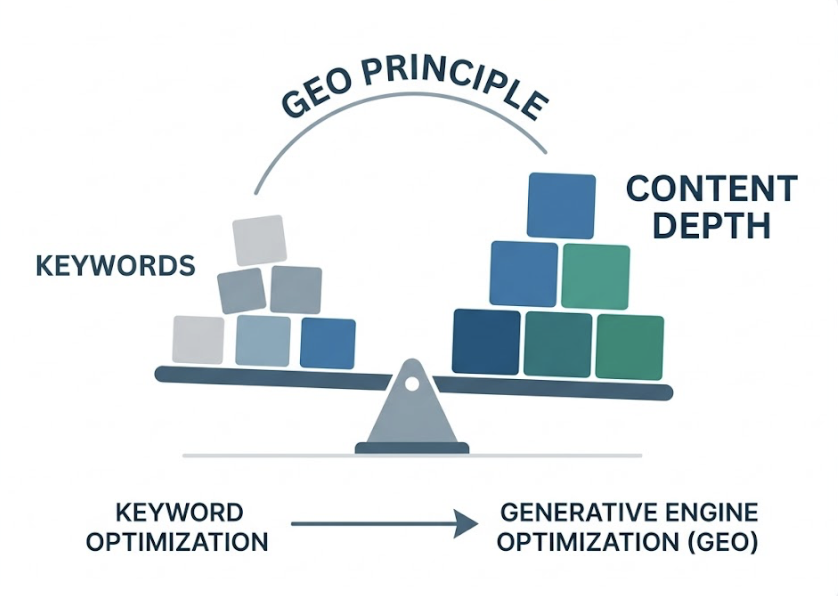
    There’s a term for the practice of optimizing content for AI recommendation systems: Generative Engine Optimization, or GEO. The Princeton research that quantified citation impacts established one core principle: content depth matters more than keyword optimization for GEO success.

    In practice, that means four things.

    Factual specificity over promotional language. Replace benefit statements with verifiable claims. Instead of “industry-leading performance,” use a specific benchmark with a source. LLMs prioritize what researchers call “high-entropy” content — dense with facts, light on filler.

    Authority amplification through earned media. AI agents weight third-party editorial mentions more heavily than brand-owned content. Getting your brand discussed alongside category leaders in independent industry publications builds the co-citation signals that move you into the agent’s candidate pool.

    Proactive sentiment correction. If the AI is citing an outdated negative review or a 2022 article that no longer reflects your product, that source is actively suppressing your recommendation probability. Reaching out to the publisher to update the record, or building a body of newer, accurate coverage, is a direct GEO intervention.

    Structured data implementation. FAQPage, Organization, and Product schema give AI crawlers a deterministic data layer — a clean, machine-readable version of your brand’s key facts that doesn’t require the agent to infer anything.

    The challenge for most marketing teams is the gap between detecting a visibility problem and fixing it. Topify’s One-Click Execution addresses this directly. Its AI agent continuously monitors recommendation data across platforms and generates a prioritized list of GEO actions — content updates, citation opportunities, sentiment corrections — that teams can deploy without building custom workflows. When AI platforms update their citation patterns, the system detects the shift and surfaces new actions automatically, creating a closed loop between visibility monitoring and strategy execution.

    That’s a meaningful operational difference. Weekly SEO audits are too slow for a system where citation data can shift within days.

    Conclusion

    The transition from search engine to decision engine is already in progress. Agentic AI is making brand recommendations today, in real conversations, for real purchase decisions — and most brands have no visibility into whether they’re winning or losing those moments.

    The brands that move first to build entity authority, citation density, and consistent sentiment signals will establish a structural advantage that compounds over time. The ones that wait until their traffic data shows the impact will be correcting a deficit instead of building a lead.

    Get started with Topify to see where your brand currently stands in AI recommendations — and what’s actually driving (or blocking) the result.


    FAQ

    Q: What is agentic AI and how is it different from regular AI search?

    A: Regular AI search (like early ChatGPT) synthesizes information and gives you an answer. Agentic AI goes further — it can plan, reason across multiple steps, use external tools, and complete tasks autonomously on behalf of the user. Instead of telling you which CRM options exist, an agentic AI might evaluate your team’s needs and recommend a specific one. For brands, this distinction matters because agentic AI doesn’t just present options; it selects a winner.

    Q: Does agentic AI use Google search results to make recommendations?

    A: Not directly. Agentic AI systems typically rely on their own RAG (Retrieval-Augmented Generation) pipelines, which pull from a curated mix of indexed web content, structured databases, and internal knowledge bases. A high Google ranking can increase the chance that your content gets indexed by these systems, but it doesn’t guarantee inclusion. The selection criteria — factual grounding, entity consistency, sentiment scores, citation patterns — are different from Google’s ranking signals.

    Q: How can I tell if my brand is being recommended by agentic AI?

    A: Start with a manual audit: test 20–30 prompts across ChatGPT, Gemini, Perplexity, and Claude using direct-brand, category-level, and scenario-based queries. Track whether your brand appears, where it ranks in the response, and which sources are cited. For ongoing monitoring at scale, platforms like Topify automate this tracking across platforms and geographies, and can identify exactly which third-party domains are influencing your AI recommendation rate.

    Q: What’s the fastest way to improve my brand’s visibility to AI agents?

    A: The highest-impact starting point is usually source correction — identifying which third-party domains AI platforms are currently citing about your brand or category, and ensuring your brand has accurate, current coverage on those specific sites. This is more direct than creating new content from scratch. From there, implementing structured data (Organization and FAQPage schema) and securing mentions in category-level editorial pieces are consistently strong GEO moves, backed by the Princeton/Georgia Tech citation research.


    Read More

  • AI Citations Are the New Backlinks. Here’s How to Track Them.

    AI Citations Are the New Backlinks. Here’s How to Track Them.

    Your domain authority is 70. Your keyword rankings are solid. But none of that tells you whether Perplexity is recommending your competitor instead of you. Google’s organic results and AI-generated answers are pulling from increasingly different sources, and the gap between “ranking well” and “being cited by AI” is widening every quarter. A high backlink count got you to the top of a results page. It won’t get you into a ChatGPT answer.

    The unit of authority has changed. And most teams are still measuring the old one.

    Your Backlink Profile Doesn’t Predict Your AI Citation Rate

    This is the central paradox of modern search. Brands with strong SEO foundations are discovering their AI visibility is near zero, while newer sites with modest domain authority are getting cited consistently across ChatGPT, Perplexity, and Google AI Overviews.

    The data makes this uncomfortable to ignore. While established domains with DA 60+ are cited 4x more frequently than new sites overall, the correlation between raw link quantity and LLM citations sits at roughly r = 0.10. That’s not a weak signal. That’s almost no signal at all.

    The reason is structural. A traditional search engine asks: “What is the most popular page for this query?” A generative engine asks something different: “What is the safest, most verifiable thing I can repeat without being wrong?”

    Those are not the same question. And they don’t produce the same results.

    Approximately 31% of AI-cited pages rank outside the top 100 in traditional organic search. AI engines are surfacing “hidden gems” of structured, data-dense content that Google’s algorithm overlooks due to a lack of traditional backlinks. Your competitor with the clean FAQ structure and original research report may be getting cited constantly, while your 5,000-word pillar page sits invisible.

    What AI Citations Actually Are (and Why Mentions Don’t Count)

    Before tracking anything, it helps to be precise about what you’re tracking.

    An AI citation is not the same as a brand mention. A mention is when an AI names your brand in its response — a recommendation, a comparison, a reference. Mentions drive brand awareness and share of voice, which matter. But they don’t drive traffic.

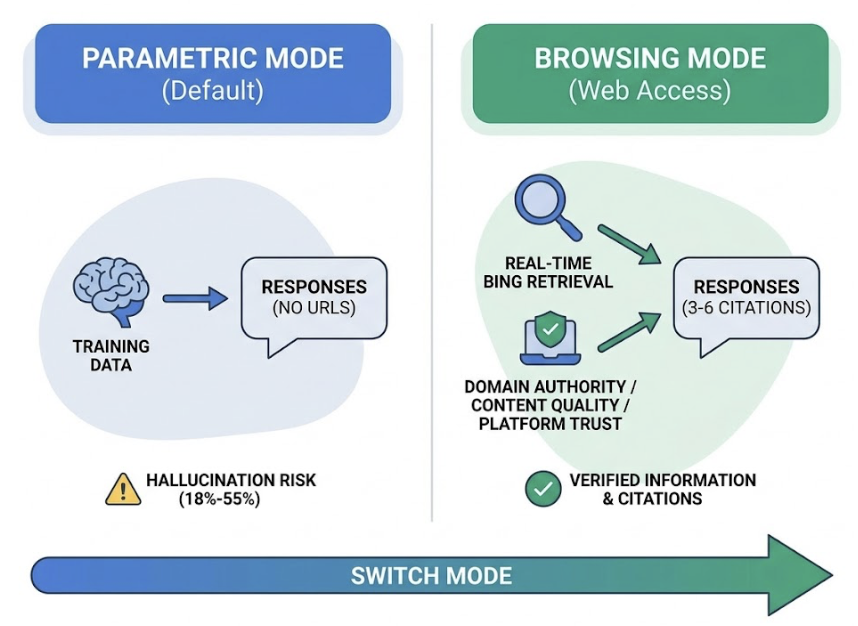
    A citation is formal attribution. It’s the structured link embedded in an AI response that identifies the specific URL used as evidence for a claim. It’s the mechanism behind Retrieval-Augmented Generation (RAG), where the AI grounds its answer in a source it can point to.

    FeatureBrand MentionAI Citation
    Visual formPlain text in response bodyClickable link or footnote
    Primary mechanismEntity recognition and training biasRAG retrieval
    Primary valueBrand awarenessHigh-intent referral traffic
    Key metricShare of VoiceCitation Rate and CVR
    Optimization focusMulti-source PR/socialContent structure and factual density

    There’s a pattern worth knowing called the “Mention-Source Divide”: an AI platform uses your brand’s data but names a competitor, or cites a third-party aggregator like Reddit or a review site instead of your original source. Brand mentions are 3x more predictive of overall AI visibility than backlinks, yet citations are the only mechanism that preserves the direct revenue pathway from the AI interface to your website.

    The 3 Factors AI Engines Actually Weigh When Selecting a Source

    AI visibility is less about link authority, more about what makes content safe for a machine to repeat. Three factors dominate the selection logic.

    Format and extractability. AI platforms don’t read 3,000-word articles. They retrieve chunks of text, typically 75–300 words per section. Content must be modular. Leading each section with a direct, declarative statement — the core answer first — increases citation probability by 40%. Structured data (Schema.org markup) acts as a direct line to the AI, reducing ambiguity during extraction.

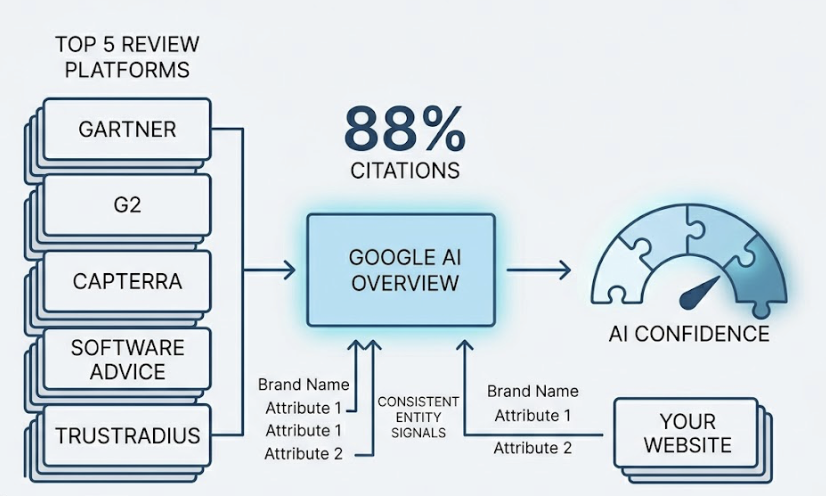
    Source type and corroboration. For category-level queries, 88% of citations in Google AI Overviews go to just five major review platforms: Gartner, G2, Capterra, Software Advice, and TrustRadius. For many brands, the path to being cited doesn’t run through your own website first. It runs through the third-party platforms the AI already trusts. Consistent entity signals — your name, core attributes, and positioning — across multiple authoritative sources builds the AI’s “confidence” to cite your own content later.

    Factual density and original research. Statistics are the primary currency of AI trust. Adding statistics to a piece of content improves AI visibility by 41%, making it the single most effective optimization technique tested in peer-reviewed research from Princeton and Georgia Tech. Websites hosting original research generate 4.31x more citation occurrences per URL than those that rehash existing information.

    Original research, surveys, and benchmark reports are citation magnets precisely because they offer unique data points the AI cannot find elsewhere.

    Most Brands Don’t Know If They’re Being Cited — or Ignored

    This is where the problem gets operationally difficult.

    Traditional web analytics weren’t built for AI search. Google Analytics 4 doesn’t have a native “AI referral” channel. A substantial portion of AI-referred traffic lands as “Direct” with no referrer — because when a user clicks a link inside the ChatGPT or Claude mobile app, referrer headers are frequently stripped. Users who read your AI citation, trust the reference, and type your URL into a browser hours later look like direct traffic. They’re not.

    There’s also a decoupling between impressions and clicks that makes this harder to see. Organic CTR can drop by as much as 61% for informational queries when an AI Overview is present. But the visitors who do click through from an AI citation convert at 9x the rate of standard search traffic and bounce 23% less. They arrive pre-qualified by the AI, ready to act rather than browse.

    The visibility is real. The standard measurement framework just can’t see it.

    5 Things an AI Citation Tracker Should Actually Show You

    Knowing you’re missing from AI answers is only the starting point. The tools that matter for this kind of tracking need to do more than confirm absence. Here’s what to look for when evaluating an ai citation tracker:

    1. Cross-platform coverage. A tracker monitoring only ChatGPT sees less than 15% of the total citation landscape. Only 11% of domains are cited by both ChatGPT and Perplexity for the same set of queries. Professional tracking requires visibility across ChatGPT, Perplexity, Gemini, Google AI Overviews, Bing Copilot, and regional models. Each platform has its own retrieval logic and source preferences.

    2. Statistical sampling at scale. AI responses are non-deterministic. There’s less than a 1-in-100 chance that an AI will produce the same list of brand recommendations twice in a row if asked 100 times. A single manual check is a snapshot, not a signal. Effective trackers run prompt matrices of 50 to 150 queries, each executed dozens of times across locations and timeframes to produce a statistically meaningful AI Visibility Score.

    3. Source granularity and citation gap mapping. Knowing who got cited instead of you is more actionable than knowing you were absent. A tracker should map the exact third-party domains driving citations in your category. If the AI consistently cites a specific Reddit thread or a competitor’s comparison table, that’s your next content target.

    4. Contextual and sentiment analysis. Being cited isn’t always a win. If an AI cites your brand alongside caveats about pricing or support, you’re accumulating reputation damage with every mention. Position rank matters too: being the first brand listed in an AI response carries significantly more authority than being fifth.

    5. Source decay monitoring over time. The half-life of an AI citation for a non-network domain is roughly 4.5 weeks. Content that isn’t refreshed falls out of the retrieval pool on a rolling basis. A tracker needs to surface when a high-performing page has decayed and needs updating to regain its citation status.

    How to Start Tracking AI Citations Without Starting From Scratch

    Manual checks — typing prompts into ChatGPT or Perplexity yourself — are free and useful for initial exploration. They’re also easy to misread. Confirmation bias is a real problem: one positive citation creates the assumption of high visibility, while one negative result triggers an unnecessary content overhaul. Manual checks also can’t capture the “fan-out queries” — the 3 to 5 secondary searches an AI engine runs in the background to build a comprehensive answer.

    The shift to automated monitoring is where real signal emerges.

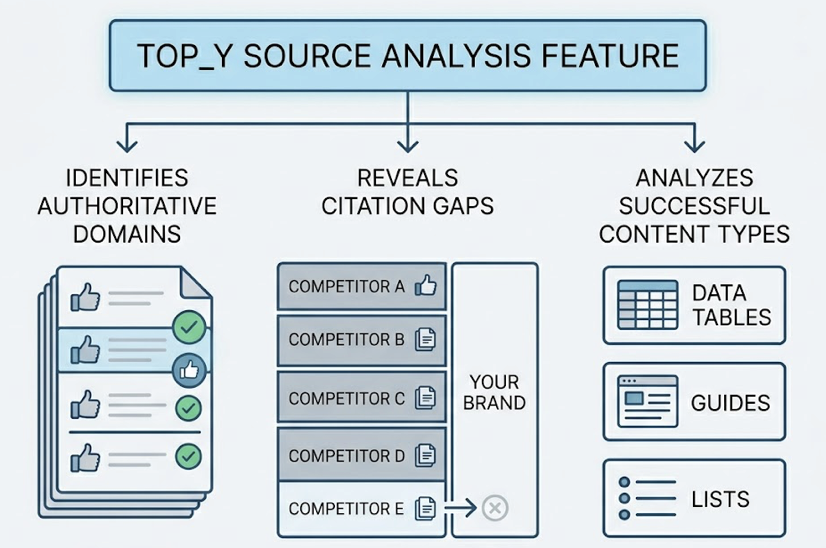
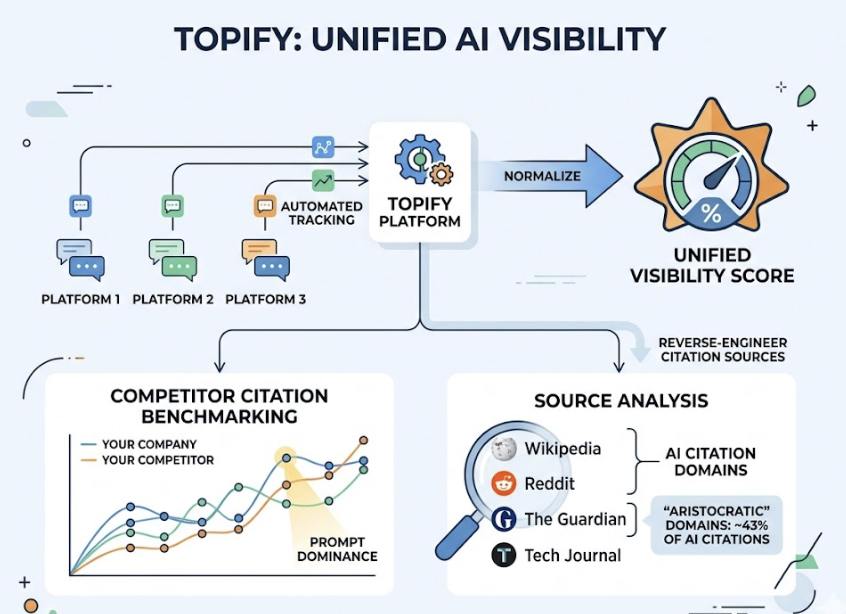
    Topify addresses this through its Source Analysis feature, which reverse-engineers the retrieval logic behind AI citations at scale. Rather than telling you whether your brand appeared, it identifies which domains the AI is treating as authoritative for your category, which queries produce citation gaps where competitors appear and you don’t, and what content types are driving successful citations in your space.

    The practical output: a prioritized list of third-party domains where your brand needs coverage. Not “what keyword should we target,” but “which authoritative site does the AI trust that doesn’t mention us yet?” That’s a fundamentally different — and more actionable — question.

    Topify tracks performance across ChatGPT, Gemini, Perplexity, and other major AI platforms, covering seven key metrics: visibility, sentiment, position, volume, mentions, intent, and Conversion Visibility Rate (CVR). The CVR metric is particularly relevant here — it estimates the probability that an AI response will lead a user to meaningful brand interaction, which is the revenue signal that standard analytics can’t capture.

    Turning Citation Data Into a Content Strategy That Compounds

    The goal isn’t just to track citations. It’s to build a system where being cited more often creates the conditions for being cited even more.

    The feedback loop works like this: consistent AI citations increase branded search volume, which search engines read as an authority signal, which increases the AI’s confidence in citing your content, which drives more branded searches. First-mover advantage is real here, and it compounds.

    A few structural moves make a measurable difference:

    Map the revenue visibility gap. Find the high-intent queries where your brand ranks #1 on Google but is absent from the AI response. That intersection is the highest-ROI target for optimization. You already have the domain authority. You need the content format.

    Restructure for modular extraction. Rewrite H2 and H3 headers as specific questions. Lead each section with a direct answer. Keep sections focused — 75 to 300 words per idea. This is the content architecture that facilitates the chunking process RAG systems rely on.

    Target the gatekeeper domains. Use citation gap data to identify the review sites, Reddit threads, and industry publications the AI treats as primary sources in your category. Building presence on those domains — through contributed content, product listings, or coverage — is often faster than outranking them.

    Implement a 90-day refresh cycle. AI-cited content is, on average, 25.7% newer than traditional search results. High-value pages that go 90+ days without updates fall out of the active retrieval pool. A regular refresh cadence — updating statistics, adding new data points, expanding FAQ sections — is a core GEO tactic, not an optional hygiene step.

    Unmask AI referrals in GA4. Implement custom channel groups using Regex to move “Direct” sessions with AI-platform referrer patterns into a distinct “AI Referrals” bucket. This is how you start calculating true CVR and attributing revenue to citation activity.

    Conclusion

    Backlinks built authority on the human web. AI citations are building authority on the machine-synthesized one. The selection logic is different, the content requirements are different, and the measurement infrastructure is different. What hasn’t changed is the first-mover advantage: the brands that start measuring now are building a gap that compounds.

    The analytics infrastructure most teams rely on was built for a world where impressions and clicks moved together. In AI search, they’ve decoupled. Visibility often happens without a click. Influence precedes the session by hours or days. The brands winning in this environment aren’t just publishing more content. They’re measuring what the machine chooses to repeat — and optimizing for that signal specifically.

    An ai citation tracker doesn’t replace your SEO stack. It fills the measurement gap your current tools can’t see.


    FAQ

    What is an AI citation tracker?

    An AI citation tracker is a monitoring tool that simulates user prompts at scale to measure how often, where, and in what context a brand is referenced within AI-generated answers. Unlike traditional rank trackers, it analyzes the specific URLs used as evidence in an AI response and identifies citation gaps where competitors appear and you don’t.

    How is an AI citation different from a backlink?

    A backlink is a static hyperlink placed by a human editor to signal popularity or relevance. An AI citation is a dynamic, probabilistic attribution generated by an LLM during synthesis to ground a response in verifiable facts. The selection logic is fundamentally different: backlinks signal popularity, citations signal extractability and factual legitimacy.

    Can I track AI citations for free?

    Manual tracking — typing prompts into ChatGPT or Perplexity — costs nothing but produces unreliable signal. Because AI outputs are non-deterministic, a single check has less than a 1-in-100 chance of matching what the AI would say on the next prompt. Statistically meaningful tracking requires automated sampling across dozens or hundreds of prompt executions.

    Does being cited by AI improve traditional SEO?

    AI citations don’t pass link equity in the traditional sense. But they create an authority feedback loop: more citations drive more branded search volume, which Google reads as a topical authority signal, which improves organic rankings. The two systems are increasingly interconnected, even if the direct mechanism differs from classic link equity.

    What content format gets cited most by AI?

    Modular content with a clear inverted pyramid structure — direct answer first, supporting detail after — performs best. Original research with verifiable statistics generates 4.31x more citation occurrences per URL than derivative content. FAQ sections with specific, conversational questions also see high citation rates because they directly match how users phrase AI queries.


    Read More

  • How to Set Up an AI Citation Tracker Dashboard

    How to Set Up an AI Citation Tracker Dashboard

    Your competitor was cited 14 times by ChatGPT last week in response to high-intent buyer queries. Your brand? Zero mentions. And you had no idea it was happening.

    That’s not a hypothetical. It’s the default state for most marketing teams right now. Your Google Analytics is blind to AI-mediated discovery because most of these interactions happen inside the AI interface — no referral link, no session data, no trace.

    Setting up an AI citation tracker dashboard is how you fix that. Here’s exactly how to do it.

    What AI Citation Tracking Actually Measures

    Most brand monitoring tools track mentions: your brand name showing up in a news article, a tweet, or a review site. AI citation tracking is different.

    It measures the internal logic of LLM responses — specifically, which domains the AI uses to construct its answers and whether your brand is named as a recommendation in the response body.

    There’s a meaningful gap between the two. Research shows only 28% of brands achieve both a citation (the AI linking to your domain as a source) and a mention (the AI recommending your brand by name) in the same response. That “Mention-Source Divide” matters: brands that earn both signals are 40% more likely to reappear in consecutive AI responses, creating a compounding visibility advantage.

    Google Analytics can’t see any of this. You need a dedicated system.

    The 5 Metrics Your Dashboard Needs Before Anything Else

    Before you touch any tool, get clear on what you’re actually measuring. A dashboard built around the wrong metrics is worse than no dashboard at all.

    Visibility Rate (Share of Answer). The percentage of AI responses to your target prompt set that include your brand. If your brand appears in 31 out of 100 ChatGPT responses for a specific query, your visibility rate is 31%. Because LLMs are non-deterministic, this number needs to be averaged across 60-100 prompt iterations — not pulled from a single test.

    Citation Source Share. How often your domain appears in the citation or footnote section of an AI response, relative to competitors. AI interfaces like Perplexity typically limit citations to 3-10 links per answer. That’s an intensely competitive slot.

    Sentiment Score. A high visibility rate with negative sentiment is actively harmful. If the AI describes your brand as “an outdated solution” or positions you unfavorably against a competitor, that visibility is working against you. Track the quality of mentions, not just the count.

    Platform Breakdown. ChatGPT and Perplexity share only 11% of the domains they cite. A single “AI score” hides these divergences. You need per-platform data.

    Trend Line. Static snapshots are useless. AI citation patterns shift constantly as models update and web indexes are recrawled. You need weekly trend data to separate signal from noise.

    Step 1: Define the Prompts That Drive Citations in Your Category

    Your citation tracker is only as good as the prompts you’re monitoring. And this is where most teams underinvest.

    Traditional keyword research doesn’t translate. The average ChatGPT prompt runs around 60 words. You’re not optimizing for “best CRM” — you’re optimizing for “what’s the best CRM for a 10-person SaaS team that needs Salesforce integration and doesn’t want to pay enterprise pricing.”

    Start with two prompt categories that consistently drive citations. Evaluative prompts (“What’s the best [product] for [use case]?” / “Compare X vs Y”) push the AI to recommend a shortlist — these are your highest-value slots. Research prompts (“How does [process] work?”) often trigger citations of authoritative reports even when they don’t name brands.

    Aim for 20-30 prompts that cover discovery, comparison, and evaluation stages. Manual prompt creation is a significant bottleneck — Topify’s High-Value Prompt Discovery automates this by surfacing the exact questions users are already asking AI engines in your category, including visibility gaps where competitors appear but you don’t.

    Step 2: Map Your Competitive Entity Landscape

    AI systems don’t see brands as isolated entries. They understand them as entities within a knowledge graph, clustered by association and context.

    This has a practical implication: your “AI-perceived competitors” are often not the same as your marketing plan’s competitor set.

    During initial dashboard setup, it’s common to discover that the AI is grouping your brand alongside a G2 aggregator page, a Reddit thread, or a niche analyst report — not the direct competitors you were tracking. That aggregator might be capturing citation share you didn’t know you were competing for.

    Topify’s Competitor Monitoring automates this detection, showing how AI engines cluster your brand and flagging new rivals as they emerge. Don’t configure your competitor set manually based on gut instinct. Let the AI tell you who it thinks your competitors are.

    Also track co-citation signals: when your brand is mentioned in the same context as trusted industry leaders across independent sources, the statistical probability of the AI recommending you alongside those leaders increases. Co-citation is an authority signal you can actively engineer.

    Step 3: Set Up Source-Level Citation Tracking

    This is the part most teams skip. It’s also where the most actionable intelligence lives.

    AI models don’t just pull from brand-owned content. According to a 2026 citation distribution analysis, blogs and industry content account for 53.46% of all AI citations. News publishers contribute 14.09%. Reddit and community forums drive 8.71% — spiking significantly in evaluative queries where users are trying to gauge real-world trust.

    Official brand pages are often deprioritized unless the query is brand-specific.

    That distribution has a direct strategic implication: writing more content on your own domain isn’t always the highest-leverage move.

    Using Topify’s Source Analysis, you can identify exactly which domains the AI is citing to construct answers in your category. When you look at a competitor who consistently appears in Perplexity responses, the source might not be their blog — it might be a specific Reddit thread, an analyst report, or a niche review on a trade publication you hadn’t considered.

    That’s your action item. Not a new blog post. A targeted engagement in the channel the AI already trusts.

    Sort your high-citation domains into two buckets: sources you can influence (community forums, industry publications that accept contributed content, analyst relationships) and sources you can’t (Wikipedia, major news archives). Allocate effort accordingly.

    Step 4: Build Your Weekly Monitoring Routine

    Here’s where most teams drop the ball: they build the dashboard and then check it once a month.

    That’s not enough. Perplexity shows an 82% citation rate for content updated within the last 30 days, compared to 37% for content older than six months. AI citation patterns shift fast. A monthly review cycle means you’re responding to changes that happened weeks ago.

    The manual alternative is unsustainable. Monitoring AI citations by hand requires roughly 3 hours per week — and human data entry carries a 1-7% error rate. With an automated platform, that drops to 15 minutes with significantly higher data density.

    Here’s the weekly structure that works:

    Metric audit (5 min). Check Visibility Rate and Sentiment trend lines across ChatGPT, Perplexity, and Gemini. You’re looking for direction changes, not absolute numbers.

    Competitor pulse (5 min). Did any unexpected rivals appear? Did a competitor’s Citation Share spike? A sudden shift usually points to a content or PR move you should investigate.

    Source opportunity (5 min). Identify one high-citation domain where your brand is currently absent. Assign it as an action item for the week — a Reddit comment, a media outreach, a data contribution to an industry report.

    Topify generates these reports automatically. You show up, read the summary, make the call.

    The Setup Mistakes That Tank Your Dashboard Before It Starts

    Platform myopia. Most teams start with ChatGPT because of market share. But Perplexity skews toward niche expertise and community content, while Gemini prioritizes brand-owned pages and YouTube. Optimizing for one engine leaves you invisible on the others. Your dashboard needs cross-platform coverage from day one.

    Tracking volume, ignoring sentiment. AI models are fine-tuned through RLHF to avoid recommending brands with poor user experience signals or controversy associations. A high citation count with negative sentiment is not a win — it’s a risk that compounds over time.

    Only tracking your brand name. Category-level prompts (“what should I use for X”) often drive more purchasing decisions than brand-specific queries. If you’re not monitoring those, you’re missing the prompts where competitor share is being built.

    Blocking AI crawlers. If GPTBot, ClaudeBot, or PerplexityBot are blocked in your robots.txt, your domain never enters the retrieval pipeline. The AI falls back on third-party sources — which may be less accurate or actively unfavorable. An AI robots checker should be part of your initial technical audit.

    Monthly cadence on a weekly problem. Citation drift is real. By the time your monthly report lands, the shift you needed to respond to happened three weeks ago.

    One Technical Detail Most Guides Don’t Cover

    Content structure affects citability in ways most teams underestimate.

    Placing a 40-80 word direct answer at the top of a page — before any supporting context — increases citation rates by 40%, based on research from the Princeton GEO study and industry testing. AI models running RAG retrieval are looking for machine-extractable answers, not prose that buries the key point in paragraph four.

    Structured data (Schema.org Organization and Product markup) gives the AI a “cheat sheet” to extract brand facts accurately. Information gain — unique data points not found in the AI’s base training data — is weighted heavily as a sourcing signal. If your content says the same thing as ten other pages, it’s not a citation candidate.

    This is worth auditing during setup, not after you’ve been tracking for six months.

    Conclusion

    The business case for this work is straightforward. AI search visitors convert at 23x the rate of traditional organic search visitors because they arrive pre-qualified. AI-driven retail referrals grew 4,700% year-over-year by mid-2025. The cost of invisibility is no longer theoretical.

    Setting up an AI citation tracker dashboard isn’t a one-time project. It’s a visibility infrastructure — a system that tells you where you stand in the AI’s reasoning, what your competitors are doing that you’re not, and where to put resources next week.

    Start with 20-30 prompts. Map your actual competitor set. Set up source-level tracking. Build the 15-minute weekly habit. The teams that treat this as operational infrastructure — not a reporting experiment — are the ones building defensible positions in AI search right now.

    FAQ

    What’s the difference between AI citation tracking and brand mention monitoring?

    Traditional monitoring indexes public URLs to track social and news mentions. AI citation tracking analyzes the internal synthesis of LLMs, measuring how often a brand is mentioned, cited as a source, and recommended within AI-generated responses — data that standard analytics tools can’t capture.

    How many prompts should I track when starting out?

    Start with 20-30 high-value prompts covering discovery, comparison, and evaluation stages of the buyer journey. Prioritize evaluative and comparative prompts — these drive the AI to recommend shortlists and are the highest-value slots to compete for.

    Can I track citations across ChatGPT, Perplexity, and Gemini in one dashboard?

    Yes. Platforms like Topify provide unified multi-platform tracking so you can compare inter-engine performance and catch divergences that a single-platform view would miss.

    How often does AI citation data change?

    Frequently. Perplexity prioritizes content updated within 30 days, showing an 82% citation rate for fresh content vs. 37% for content older than six months. Weekly monitoring is the minimum cadence to distinguish sustained trend changes from temporary algorithmic noise.

    Read More

  • How to Track AI Citations Across 3 Platforms

    How to Track AI Citations Across 3 Platforms

    Your content might be getting cited by ChatGPT, Perplexity, or Google AI Overviews right now. You’d have no idea.

    That’s not a hypothetical. Zero-click searches already account for 69% of all queries, up from 56% just a year ago. When Google triggers an AI Overview, the click-through rate for the top organic result drops by 58% to 61%. The traffic didn’t disappear. It got redirected to whoever AI decided to cite.

    The brands winning in this shift aren’t the ones with the highest rankings. They’re the ones who know exactly when and where they’re being cited, and why.

    Here’s how to build that visibility across all three major AI platforms.


    AI Citations Are Now a Traffic Source. Most Brands Still Don’t Track Them.

    Being cited by an AI platform isn’t just a credibility signal. It’s a revenue driver.

    Sources cited in Google AI Overviews earn 35% more organic clicks and 91% more paid clicks than non-cited competitors on the same query. And users arriving from AI platforms aren’t casual browsers: they generate 23x more signups relative to their traffic share compared to traditional organic visitors.

    Legacy SEO tools can’t see any of this. Rank trackers check where a URL sits in a list. They can’t detect when AI uses your content to build a synthesized answer without linking to you, or when a competitor is getting cited for every prompt in your core category.

    That’s the gap. And it’s widening.


    What “AI Citation” Actually Means on Each Platform

    The phrase “AI citation” covers three distinct architectures. Getting them confused leads to the wrong tracking approach.

    FeatureChatGPT (Browsing)Perplexity AIGoogle AI Overviews
    Retrieval TypeBing Search APIHybrid (Bing + Cache)Google Search Index
    Citation StyleFootnotes / IconsNumbered Inline LinksCarousel / Source Links
    Sources Per Answer3 to 63 to 46.8 to 13.3
    Update SpeedReal-timeReal-timeModerate (indexed)
    Selection FocusAuthority & readabilityEntity clarity & BLUFE-E-A-T & extractability

    ChatGPT operates in two modes. Its default “parametric” mode draws from training data and doesn’t cite real URLs, with hallucination rates between 18% and 55%. Switch to Browsing Mode and the architecture changes entirely: real-time retrieval from Bing, 3 to 6 clickable citations per response, and a selection process weighted toward domain authority (40%), content quality (35%), and platform trust (25%).

    Perplexity is RAG-native. Every answer requires citations. That makes it structurally more transparent than standard LLMs, but also more selective: while a single query might retrieve 60+ sources, only 3 to 4 make the final answer.

    Google AI Overviews sits inside the search index itself, using Gemini to synthesize multiple sources simultaneously. It cites more sources per answer than either ChatGPT or Perplexity, but the selection logic is built around extractability, not just rank.


    How to Check If ChatGPT Is Citing Your Content

    The manual approach is straightforward: open a ChatGPT session with Browsing enabled, run a prompt your target customer would ask, and check the Sources panel. If your domain appears, you’re cited.

    The problem isn’t the method. It’s the math.

    ChatGPT’s responses are non-deterministic. The same prompt generates different sources across different sessions. A single check is a snapshot of one instance, not a reliable indicator of your actual inclusion probability across hundreds of regenerations.

    Content updated within the past 30 days gets 3.2x more citations in Browsing Mode. Which means stale content that showed up last month might already be gone.

    This is where Topify’s Source Analysis changes the math. Instead of running one test prompt, Topify runs thousands of relevant prompts across ChatGPT automatically, logs every citation event, and surfaces your domain’s inclusion probability over time. It’s the difference between checking the weather once vs. reading a 30-day forecast.


    Tracking Citations in Perplexity: What the Numbers Actually Tell You

    Perplexity’s user base is smaller than ChatGPT’s (roughly 780 million monthly queries vs. 2.5 billion daily prompts), but its audience skews heavily toward research-oriented, high-intent buyers. Being cited there carries real commercial weight.

    The platform uses an L3 XGBoost reranker to decide which sources earn a spot in the final answer. Two signals matter most:

    BLUF rule: 90% of top citations come from content that answers the query directly within the first 100 words. Perplexity’s model doesn’t have patience for slow-building articles.

    Schema markup: Pages with FAQ or Article JSON-LD schema see a 47% top-3 citation rate, compared to 28% for pages without it. That’s not a marginal difference.

    The difference between being cited #1 vs. #5 in Perplexity

    Perplexity doesn’t display citations as a ranked list, but position still matters. “Primary Sources” appear in the opening paragraph of the synthesized answer. “Supporting Citations” appear later and attract significantly less attention. Moving from a supporting slot to a primary slot is the difference between being a reference and being the answer.

    Topify’s Visibility Tracking shows where your citations appear within Perplexity responses, not just whether they appear. That position data is what turns tracking into optimization.


    Google AI Overviews Citations Are Different. Here’s Why That Matters.

    Google AI Overviews now appear on 13.14% of all U.S. desktop searches, and for informational queries that number reaches 80% to 88%. When an AIO triggers, the average zero-click rate for that query hits 83%.

    Here’s what most brands get wrong about AIO: they assume it favors top-ranked pages.

    It doesn’t.

    Analysis of over 4 million AIO citations shows that only 38% of cited pages come from the top 10 search results for that query. More than 60% come from pages ranking at position 40 or lower. This happens because of “Query Fan-Out”: Google’s AI expands your original question into multiple related sub-queries, pulling from a much wider pool of content than standard ranking would reach.

    For AIO, the winning factor is extractability. Content needs to be structured as standalone blocks of 40 to 60 words that lead with a direct answer, include a concrete data point, and can be parsed without context from the surrounding page. Pages that combine text with original images and video see a 156% higher selection rate in AIO.

    Topify’s Visibility Tracking monitors your brand’s appearance in AI Overview responses across the queries that matter to your category, including prompts where you’re not showing up but competitors are.


    Stop Tracking 3 Platforms Separately. Use One AI Citation Tracker.

    Managing citations manually across ChatGPT, Perplexity, and Google AIO creates three separate data silos and burns team hours that don’t compound into results.

    The efficiency gap is hard to ignore:

    MetricManual TrackingTopify Automation
    Audit Speed5 to 10 minutes per promptUnder 1 second per prompt
    Error RateHigh (human error)Under 1%
    Update CadenceMonthly (at best)Daily or hourly
    Statistical PowerSingle result snapshotInclusion probability across sessions
    ActionabilityQualitative notesOne-click optimization

    Citation sources churn at 40% to 60% monthly. A brand cited reliably in October might be completely displaced by November. Monthly manual audits can’t catch drift at that speed.

    Topify runs automated prompt tracking across all three platforms, normalizes the results into a unified Visibility Score, and surfaces Competitor Citation Benchmarking so you can see exactly which prompts a competitor dominates and what’s driving their edge. The Source Analysis feature reverse-engineers the specific third-party domains driving competitor citations, including the “aristocratic” domains like Wikipedia, Reddit, and industry journals that account for 43% of all AI citations.

    That’s not a report you read once. It’s a live signal you act on weekly.


    What to Do With Citation Data After You Have It

    Citation data is only useful if it changes what your team produces. Three actions to take immediately after your first audit.

    Identify which content types are getting cited, then double down. If your pricing pages are getting cited but your blog posts aren’t, that’s not a content quality problem. It’s a format signal. AI models are 6.5x more likely to cite a brand through external authoritative sources than through its own website, which means investing in third-party placements on Reddit, review sites, and industry publications often outperforms publishing more owned content.

    Close the gaps where competitors win and you don’t. Use Citation Gap Analysis to find prompts where competitors show up and you don’t. If competitors are winning because they have original research or proprietary statistics, that’s the content gap to close. Content that contains 32% more explicit concepts than average is significantly more likely to earn a citation.

    Restructure high-performing pages into extractable chunks. The BLUF rule applies across all three platforms: answer the question directly in the first 100 words, include a specific data point, and wrap the block in schema markup. That format change alone can move a page from a supporting citation to a primary one.

    3 actions to take after your first citation audit

    1. Pull your top 10 cited pages and identify their shared format (length, structure, data density)
    2. Run a Competitor Citation report for your top 5 category prompts and map the gap
    3. Pick your 3 most-visited pages and restructure the opening 150 words to answer the primary query directly

    Conclusion

    AI citations are no longer a bonus visibility play. They’re a core traffic and conversion channel, one where the gap between tracked brands and untracked ones is widening every month.

    The mechanics differ across ChatGPT, Perplexity, and Google AI Overviews, but the underlying principle is the same: the brands that understand where they appear, where they don’t, and why are the ones building compounding authority. The brands that find out six months later are the ones trying to catch up.

    Start with an audit. Know your inclusion probability. Then build from there.

    FAQ

    Can I track AI citations for free?

    Manual tracking is technically free, but it’s not reliable. Running tests manually across three platforms costs 5 to 10 minutes per prompt, and without statistical sampling across multiple sessions, a single result tells you little about actual inclusion probability. Paid platforms like Topify start at $99/month and automate what would otherwise take hundreds of hours monthly.

    How often should I audit my AI citations?

    Citation sources churn at 40% to 60% per month, and the primary narrative inside Google AI Overviews shifts roughly every 90 days. Monthly audits can’t catch that rate of change. High-performing brands have moved to weekly or daily monitoring to catch competitive displacements before they compound.

    Does getting cited by AI improve my website traffic?

    The impact is non-linear. Overall click volume may drop due to zero-click results, but the traffic that does come through AI citations is substantially higher quality. AI-referred users generate 23x more signups relative to their traffic share, view 50% more pages per session, and have lower bounce rates than traditional organic visitors.

    What’s the difference between AI visibility and AI citations?

    AI visibility includes both Brand Mentions (your name appears in the AI’s text) and Website Citations (the AI links directly to your URL). Mentions build awareness. Citations drive referral traffic and validate authority. Only 28% of brands achieve both in AI-generated answers.


    Read More

  • AI Citation Tracker: How to Know If AI Mentions You

    AI Citation Tracker: How to Know If AI Mentions You

    Your Google Analytics dashboard looks fine. Traffic is stable. Rankings haven’t moved.

    But somewhere right now, a potential customer is asking ChatGPT which tool to use in your category — and your brand isn’t in the answer.

    That’s the gap most marketing teams still can’t see.

    As AI search becomes the default way people discover products, the metric that matters is no longer “Did they click?” It’s “Did the AI mention us at all?” This guide breaks down what AI citation tracking is, how it works across ChatGPT, Perplexity, and Gemini, and what you can do about it starting this week.


    You Can’t See AI Traffic in Google Analytics. That’s the Problem.

    Between 65% and 69% of all Google searches end without a click to an external website. On mobile, that number climbs to nearly 77%.

    This isn’t a traffic problem. It’s a measurement problem.

    When an AI engine answers a query, it does the browsing on the user’s behalf. It visits your site, extracts relevant facts, and synthesizes an answer — all without generating a session in your analytics. You provided the data. You got zero credit in GA4.

    The dangerous part: a brand can be the most-cited authority in ChatGPT responses and still see a declining traffic report internally. Marketing teams perceive a failure that isn’t actually there.

    What makes this worth tracking anyway? Visitors who do click through from AI citations browse 12% more pages per visit and bounce 23% less than traditional search traffic. AI referrals convert at rates up to 9 times higher than the Google organic baseline. The volume is smaller. The intent is sharper.


    What an AI Citation Actually Is (Hint: It’s Not a Backlink)

    A backlink is a static hyperlink added by a human editor. An AI citation is a probabilistic outcome — the model decided, during synthesis, that your content was the most accurate and contextually relevant source for the answer.

    The difference matters because the signals are completely different. Backlinks demonstrate popularity and social proof. AI citations demonstrate factual legitimacy. You can have thousands of backlinks and zero AI citations.

    There are three ways a brand actually appears in a generative answer:

    Direct Citations are clickable links in a “Sources” box or as footnotes. This is the only modality that shows up in GA4 as referral traffic.

    Brand Mentions name the brand in the body of the answer without a link. This builds Share of Voice and entity authority but stays completely invisible to click-based analytics.

    Recommended Rankings are the comparative lists AI produces — “Top 3 CRM tools for startups.” Where you land in that list drives user perception, even if your name isn’t linked.

    Traditional tools like Ahrefs and Semrush can’t see any of this. They index crawlable URLs and backlinks. They can’t read the non-deterministic text an LLM generates inside a private chat session.


    3 Questions an AI Citation Tracker Should Answer

    Not all tracking tools are built the same. Before choosing one, make sure it’s designed to answer these three questions — in order.

    Is your brand being mentioned at all?

    Start here. Research indicates that 98.8% of local businesses and 26% of major brands are currently invisible in AI-generated recommendations for their primary categories. Being absent from an AI answer is functionally equivalent to being removed from the consideration set.

    This first question measures entity clarity: does the model recognize your brand as a distinct, authoritative entity with defined attributes? If the answer is no, no amount of content optimization will fix it until you build multi-source corroboration through PR, third-party coverage, and structured data.

    What sources is AI citing when it talks about your category?

    Here’s where it gets counterintuitive. AI models often don’t cite your own website. Instead, they rely on a narrow set of domains they’ve determined to be authoritative.

    For example, 88% of review-platform citations in AI Overviews go to just five sites: Gartner, G2, Capterra, Software Advice, and TrustRadius. That means if your brand isn’t covered on those platforms, you’re structurally absent from a huge portion of category queries — regardless of how good your own site is.

    Understanding these retrieval patterns lets you reverse-engineer visibility by targeting the domains AI actually trusts.

    How do you rank against competitors in AI answers?

    The final layer is competitive. If AI mentions a competitor 80% of the time for purchase-intent queries and mentions you 20% of the time, you have a visibility deficit that no traditional dashboard will surface.

    A solid tracker calculates Share of Voice across platforms and identifies Citation Gaps — specific prompts where competitors are recommended and you’re absent.


    How AI Citation Tracking Works Under the Hood

    The technical challenge here is real. Unlike a search engine that returns a stable list of links, an LLM can produce different answers to the same prompt minutes apart.

    AI citation trackers handle this by simulating human interactions at scale. They run large libraries of prompts — conversational questions that mirror real user behavior — across multiple platforms. Because of model volatility, they use high-frequency sampling: each prompt gets run dozens or hundreds of times across different locations and settings to produce a statistically significant visibility score.

    Most serious tools follow the logic of the RAG (Retrieval-Augmented Generation) pipeline. They monitor which URLs the AI is pulling in real-time, track which specific passages from those URLs were extracted for synthesis, and record which sources were ultimately credited in the final response. This breakdown pinpoints exactly where the failure happens — a retrieval issue (the site isn’t being crawled) versus a synthesis issue (the content isn’t structured clearly enough to be used).

    Continuous monitoring matters more here than in traditional SEO. A model update can shift a brand from primary source to completely omitted overnight. And source decay is real: the median citation half-life for non-network domains is roughly 4.5 weeks. Content that isn’t refreshed falls out of the citation pool on a rolling basis.


    ChatGPT vs. Perplexity vs. Gemini: Do They Cite the Same Sources?

    They don’t. There’s only an 11% domain overlap between sources cited by ChatGPT and those cited by Perplexity for identical queries. That’s the number that kills single-platform monitoring strategies.

    PlatformAvg Citations / ResponseFreshness SensitivityKey Bias
    ChatGPT7.92Moderate (60-day window)High-authority domains, Wikipedia, major news
    Perplexity21.87Extreme (30-day window)Reddit, YouTube, niche technical docs
    Gemini / AI Mode8.34Moderate (90-day window)E-E-A-T signals, Google Knowledge Graph

    ChatGPT’s citation behavior

    ChatGPT relies on the Bing index and Microsoft’s crawler. It favors a small set of high-authority sources: major publications, Wikipedia, established industry journals. It’s 3.5 times more likely to cite an established industry journal than a niche blog. For B2B brands, it functions as a curator of established reputations, not a discovery engine for emerging players.

    Perplexity’s citation behavior

    Perplexity is built for recency. It cites nearly three times more sources per response than ChatGPT and actively surfaces secondary sources — Reddit threads, YouTube videos, specialized documentation. 82% of its cited content was updated within the last 30 days. If your content publishing cadence is slow, Perplexity will quietly deprioritize you.

    Gemini’s citation behavior

    Google’s AI systems draw from two decades of crawl history and a proprietary Knowledge Graph. They weight E-E-A-T signals heavily. There’s also a meaningful internal divergence: Google AI Overviews and the Gemini-powered AI Mode only cite the same URLs 13.7% of the time. AI Overviews lean toward top-ranking pages and YouTube. AI Mode behaves more like a conversational assistant pulling from a broader entity graph.

    One-platform monitoring misses almost everything that matters.


    How to Start Tracking Your AI Citations in 30 Days

    The transition from keyword tracking to citation tracking follows a four-week rhythm.

    Week 1: Build your Core Prompt Set. Stop tracking keywords. Start tracking prompts — the conversational questions your target customers actually ask. Compile 30 to 50 prompts covering brand-specific questions, category comparisons, and problem-aware queries. Run them through an AI visibility checker to establish a baseline score across all three platforms.

    Week 2: Run cross-platform capture and source analysis. Extract every cited URL and brand mention from the AI responses across ChatGPT, Perplexity, and Gemini. Topify’s Source Analysis feature is built for exactly this step: it reverse-engineers which third-party domains are driving competitor citations and outputs a prioritized PR target list — the external sites that need your content to appear before AI will trust you.

    Week 3: Identify Citation Gaps. With the data captured, map the prompts where competitors appear and you don’t. Analyze the authority weight of your mentions. Are you being recommended as a primary solution or buried as a footnote in the third sentence?

    Week 4: Optimize and monitor. Increase fact density in your core content (concrete statistics, named sources). Improve structural clarity (H1/H2 hierarchy, FAQ schema). Implement Organization and Product schema markup. Then monitor whether your Visibility Score and Share of Voice respond. Brands using systematic GEO approaches have reported significant increases in AI mentions within two weeks of targeted optimization.


    5 Signs Your Brand Is Losing Ground in AI Citations Right Now

    These are diagnostic signals, not vanity metrics. If you’re seeing two or more of these, the problem is already compounding.

    1. Your rankings are stable but your AI Visibility Score is declining. This is the clearest sign of low extractability. Your content exists but isn’t structured clearly enough for a model to pull facts from it with confidence. Verbose content without structured data fails the synthesis test even when it ranks.

    2. Competitors dominate transactional prompts. If Topify’s Source Share data shows competitors cited in 70%+ of purchase-intent queries (“What is the best [product] for [use case]?”) while you’re under 10%, you have a multi-source corroboration problem. AI sees competitors discussed across many authoritative domains. It sees you only on your own site.

    3. Sentiment is shifting toward neutral. When AI citation tracking reveals that mentions of your brand are accumulating caveats or becoming factually hedged, the model is likely retrieving outdated or negative content from Reddit or Quora. Your reputation moat is leaking.

    4. You’re disappearing from niche, long-tail queries. Research shows that citation changes are overwhelmingly binary — domains go from cited to not cited, not gradually down. Disappearing from fringe queries first is the early warning signal that your content freshness is falling below the model’s threshold.

    5. High impressions, falling CTR in Search Console. If your brand appears in AI Overviews but your click-through rate on those queries has dropped, and you’re not the primary cited source in the answer, you’re effectively supplying data that helps a competitor win the customer’s decision.

    Conclusion

    AI citations are the new first impression. A potential customer who never visits your website can still form a complete opinion about your brand based on how — or whether — an AI describes you.

    The measurement tools most marketing teams rely on were built for a different era. Zero-click search and generative synthesis have made a significant portion of brand discovery invisible to traditional analytics. That gap is only widening.

    The path forward isn’t complicated, but it requires a different set of metrics. Identify your Core Prompt Set. Run cross-platform capture. Find your Citation Gaps. Optimize for fact density and entity clarity. Then monitor whether the model’s behavior actually changes.

    Brands that build this workflow now will have a significant data advantage over those that start when the shift is already complete.


    FAQ

    Is an AI citation tracker the same as a rank tracker? 

    No. A rank tracker measures where a URL sits in an ordered list of links. An AI citation tracker measures how frequently your brand is mentioned, how prominently it’s positioned, and what sentiment surrounds it inside a synthesized narrative answer. Rank trackers measure where you are. Citation trackers measure whether you’re recommended at all.

    How often does AI change what it cites? 

    High-authority sources are relatively stable — 96.8% of citations remain consistent week-to-week. But when changes happen, they’re usually binary. Content either stays in the citation pool or drops out entirely. Pages updated within the last 14 days are cited 2.3 times more often than older content.

    Do I need separate tools for ChatGPT and Perplexity? 

    With only 11% overlap in cited sources between the two platforms, single-platform monitoring gives you a severely incomplete picture. A reliable tracker needs to cover ChatGPT, Perplexity, and Gemini at minimum to reflect how your target audience actually searches.

    Can I track competitor citations too? 

    Yes, and you should. Running identical prompts for competitor brands lets you calculate relative Share of Voice and map the specific Citation Gaps where competitors are winning discovery opportunities you’re currently missing.


    Read More

  • Your SEO KPIs Are Lying to You. Measure This

    Your SEO KPIs Are Lying to You. Measure This

    Your brand ranks #1 on Google. Traffic looks stable. The dashboard is green.

    And somewhere right now, a high-intent buyer just asked ChatGPT which tool to use in your category. Your competitor got recommended. You weren’t mentioned.

    Your KPIs didn’t catch it.

    That’s not a data gap. That’s a measurement system built for a world that no longer exists.

    Ranking #1 on Google Doesn’t Mean You Exist in AI Search

    Google’s dominance is cracking. Its global search market share has dropped below 90% for the first time since 2015, sitting at 89.56% as of early 2025. Meanwhile, ChatGPT now handles roughly 2.5 billion prompts per day, with about a third of those being direct information queries.

    The shift isn’t just about volume. It’s about how answers get built.

    AI platforms like ChatGPT, Perplexity, and Gemini use Retrieval-Augmented Generation (RAG) to synthesize answers from crawled sources. They don’t serve a list of links. They make a judgment call about which brands to name, which to skip, and what to say about each one.

    Research shows that only 12% of AI-cited sources overlap with Google’s top 10 organic results.

    That’s the gap most SEO teams still can’t see.

    Why Traditional SEO KPIs Break Down for AEO

    The entire logic of SEO measurement rests on a single assumption: users click links, and clicks are trackable.

    AI search breaks that assumption completely.

    Zero-click search now accounts for 65–69% of all Google queries, and 77% on mobile. When AI Overviews answer a question directly, users read the summary and move on. No click. No session. No conversion event in GA4. Your analytics report shows silence while your brand’s narrative is actively being shaped in AI-generated text.

    There are three specific failure modes worth understanding.

    The invisible mention. A user asks an AI which software to use for your exact use case. Your brand gets described positively. They internalize the recommendation. GA4 shows zero traffic from the interaction.

    The competitor blind spot. AI platforms often present competitors in a synthesized narrative, not as a list of domain names. Without dedicated monitoring, you have no way to know your share of voice in AI answers is eroding week by week.

    The sentiment drift. AI pulls from third-party sources like Reddit, G2, and Wikipedia when forming its descriptions of brands. If your reputation is slipping in those channels, AI starts adding qualifiers. “While [Brand] is well-known, recent user feedback suggests…” That kind of framing does damage that never shows up in a keyword ranking report.

    Gartner projects that traditional search engine traffic to websites will fall 25% by the end of 2026. The measurement gap isn’t theoretical. It’s already costing brands visibility they can’t currently quantify.

    The 5 KPIs That Actually Measure AEO Performance

    These aren’t replacements for your existing SEO stack. They’re the metrics your current stack was never designed to capture.

    1. AI Visibility Rate

    This is the foundational AEO metric, and the closest equivalent to keyword ranking in traditional SEO.

    It measures the percentage of prompts in a defined test set where your brand gets mentioned or cited by an AI model. If you run 100 industry-relevant queries and your brand appears in 18 of them, your AI Visibility Rate is 18%.

    For market leaders, this number typically needs to exceed 30% to reflect genuine category authority. Most brands tracking this for the first time discover they’re well below that threshold, even when their Google rankings look healthy.

    2. Brand Mention Frequency by Platform

    Not all AI platforms recommend the same brands. ChatGPT leans on Bing-indexed content and high-authority encyclopedia-style sources. Perplexity is a pure RAG engine that heavily weights Reddit discussions and real-time news. Gemini integrates Google’s Knowledge Graph and YouTube signals.

    A brand that dominates on Perplexity can be nearly invisible on ChatGPT, and vice versa.

    Tracking mention frequency across platforms separately gives you an accurate picture of where your AI presence is strong and where the gaps are. Averaging across platforms produces a number that’s accurate nowhere.

    3. AI Sentiment Score

    Visibility without sentiment context is incomplete data.

    This metric tracks the attitudinal tone AI uses when mentioning your brand, expressed as a score (typically on a 0–100 or -100 to +100 scale). The calculation looks at positive recommendations and neutral mentions against negative descriptions and factual errors generated about your brand.

    Being mentioned with the wrong framing compounds over time. AI systems aren’t static. They update their descriptions of brands as new content gets crawled. A negative sentiment score is a leading indicator that needs to be addressed at the source: the third-party content AI is pulling from.

    High visibility with a low sentiment score isn’t a win.

    4. Source Citation Share

    Roughly 85% of AI citations come from third-party sources, not brand-owned domains. That means the content shaping how AI describes your brand is largely outside your direct control.

    Source Citation Share measures what percentage of AI-referenced domains in your category belong to you versus competitors and third parties. It’s the most direct signal of how much your content ecosystem is influencing AI output.

    If a competitor consistently shows up in AI answers because three key industry blogs cite them heavily, that’s actionable intelligence. It points directly to where your PR and content partnerships strategy needs to go.

    5. Conversion Visibility Rate (CVR)

    This is the AEO metric that ties most directly to business outcomes.

    CVR estimates the likelihood that AI-generated mentions of your brand lead to downstream user behavior: direct brand searches, website visits, or purchase intent. Research from Semrush indicates that users arriving from AI search convert at 4.4 times the rate of traditional organic search users.

    The practical measurement approach is correlation analysis: track how changes in your AI Visibility Rate correlate with movement in branded search volume. The relationship is real, but it’s not immediate. AI visibility improvements typically take 60–90 days to surface in branded search data.

    Position in AI Answers Isn’t One Number

    In traditional SEO, Position 1 is straightforwardly better than Position 3.

    AI answers don’t work that way.

    An AI response might mention your brand as the first recommendation in a long-form answer, or as a brief comparison point near the end, or as a cited source in the footnotes without naming you in the main text. Each of these carries a fundamentally different weight.

    The industry has started standardizing this through a Citation Placement Index (CPI) that assigns weighted scores to different mention types: a primary recommendation scores 10 points, a top-3 placement scores 7, a lower-list appearance scores 4, and a passing mention scores 2.

    That scoring structure matters because a passing mention in 8 prompts is not equivalent to a single primary recommendation, even though the raw mention count looks similar.

    The other thing to stop tracking: average ranking across platforms. If ChatGPT puts you third and Perplexity puts you first, the average (Position 2) tells you nothing useful. The right question is why your authority signals are stronger in Perplexity’s crawl path than in ChatGPT’s. That answer points to a specific content and distribution strategy.

    How to Build an AEO KPI Dashboard That Works

    Start with 30–50 core prompts that cover your target user’s decision journey: awareness-stage questions (“What is [category]?”), consideration-stage questions (“What are the top options for [use case]?”), and comparison-stage questions (“[Brand A] vs. [Brand B]?”).

    Track those prompts weekly, not monthly. AI models, particularly RAG-based systems, update their recommended sources continuously. Studies suggest 40–60% of citation sources change within any given month. Monthly reporting lags too far behind to be useful for optimization decisions.

    This is where a platform like Topify changes what’s operationally possible. Topify tracks brand performance across ChatGPT, Gemini, Perplexity, DeepSeek, and other major AI platforms against seven core metrics: visibility, sentiment, position, volume, mentions, intent, and CVR. The Source Analysis module reverse-engineers the exact domains AI platforms are citing, so if a competitor is dominating AI recommendations because of three specific industry publications, you can see that directly and adjust your content and PR strategy accordingly.

    The visibility radar view makes cross-platform gaps immediately obvious. A significant drop in one platform’s coverage usually indicates a technical issue in that platform’s crawl path, not a content quality problem.

    One integration note for teams running both AEO and traditional SEO metrics: in GA4, AI-referred traffic frequently gets miscategorized as Direct or Referral. Set up a custom channel grouping to isolate traffic from AI sources like perplexity.ai. Then run correlation analysis between your AEO Visibility Rate and branded search trends over 90-day windows. That’s the most reliable way to demonstrate AEO’s contribution to business outcomes in terms your leadership team already understands.

    AEO isn’t a replacement for your existing SEO stack. It’s the layer your current stack was built without.

    Conclusion

    Rankings and organic traffic aren’t going to zero. But they’re no longer telling you the full story of where your brand stands in the minds of high-intent buyers.

    The search session that doesn’t generate a click, the AI recommendation that shapes a purchasing decision before a user ever visits your site, the competitor quietly accumulating authority in AI answer systems while your dashboard stays green: none of that is visible in a traditional KPI report.

    AI Visibility Rate, Brand Mention Frequency, Sentiment Score, Source Citation Share, and CVR aren’t abstract metrics for an abstract future. They’re the signals that reflect what’s already happening to your brand in AI search, whether you’re measuring it or not.

    Start measuring it.

    FAQ

    What’s the difference between SEO KPIs and AEO KPIs? SEO KPIs track user pathways: how did someone get to your site? AEO KPIs track cognitive influence: what did AI tell someone about your brand before they made a decision? SEO pushes traffic. AEO shapes authority.

    How often should I check my AEO metrics? Weekly is the minimum. AI citation sources change at a rate of 40–60% per month, so monthly reporting is too slow to catch meaningful shifts before they compound.

    Can I track AEO KPIs without a dedicated tool? At small scale, yes. You can manually submit prompts to each AI platform and log mention frequency, sentiment, and cited domains in a spreadsheet. It’s not scalable and it won’t give you competitive benchmarks, but it’s a reasonable starting point for understanding your baseline.

    Which AI platform should I prioritize? It depends on your audience. B2B brands should prioritize Perplexity (more precise academic and real-time sourcing) and ChatGPT (largest user base). E-commerce and local service brands should prioritize Google AI Overviews, which integrates directly with Shopping and Maps data.

    How do I benchmark my AEO performance against competitors? Build an AEO Readiness Score for each competitor across three dimensions: content structure and schema markup, third-party entity authority (number and quality of external sources citing them), and raw citation frequency in your core prompt set. Score each on a 1–5 scale. Any competitor scoring above 10 total has already established algorithmic trust that you’ll need a deliberate strategy to close.

    Read More