Blog

  • 5 Ways AI Agents Find Brands

    5 Ways AI Agents Find Brands

    Agentic SEO isn’t about ranking pages. It’s about being discoverable before a user types a single query.

    Most marketers still think brand discovery starts with a search box. It doesn’t anymore. AI agents don’t wait for a query. They crawl, reason, and synthesize across dozens of sources before a user even realizes they have a question.

    That changes everything about how brands need to show up.

    The shift from search engine to decision engine is already here. An AI agent evaluating “the best project management tool for a remote-first SaaS team” won’t just return a list of links. It’ll pull structured product data, cross-reference third-party reviews, check Reddit for consensus, and consult what it already knows from training. If your brand isn’t present across all five of these discovery layers, it doesn’t exist in that decision.
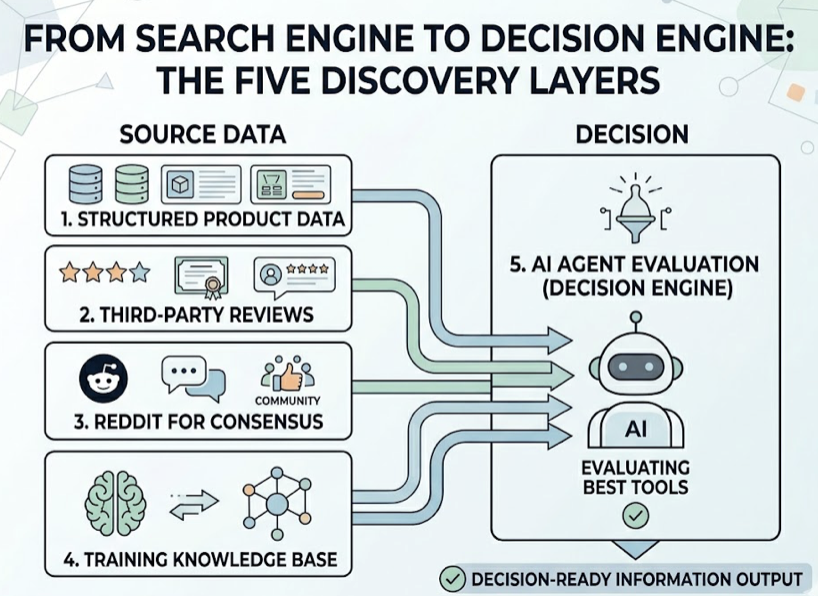
    Miss one channel, and you’re invisible to a system that never asks twice.

    AI Agents Don’t Search. They Decide.

    Traditional search engines rank pages. AI agents make recommendations. That’s not a subtle difference — it’s a complete restructuring of how brand visibility works.

    A search engine responds to a query with a list. An AI agent responds to a goal with a synthesized answer and, increasingly, a direct action. The path from “user intent” to “brand selected” has collapsed from five steps to one.

    DimensionSearch EnginesAI Decision Engines
    Starting pointUser types keywordUser states a goal or ongoing task
    OutputRanked list of linksSynthesized recommendation or direct execution
    Core logicIndex + keyword match + link authorityFetch + reasoning + multi-source synthesis
    Brand visibilityRanking on page oneBeing cited or directly recommended in the answer
    User pathSearch → Browse → Compare → ChooseAsk → Shortlist → Verify → Done

    This is the core insight behind agentic SEO. You’re not optimizing for a position on a results page. You’re optimizing for inclusion in a reasoning chain. And that reasoning chain pulls from five distinct discovery channels — each with its own logic, its own signals, and its own playbook.

    Way 1: Real-Time Web Crawling

    The first way AI agents discover brands is the most direct: they fetch your pages live.

    Agents like those powering Perplexity and ChatGPT Search use dedicated crawlers (PerplexityBot, GPTBot) to pull real-time content during a query. Unlike traditional SEO crawlers that build indexes over weeks, agent crawlers often act in the moment — triggered by a specific task, not a scheduled index run.

    That means your page has milliseconds to prove its value.

    Schema markup has moved from optional to essential. Data shows that pages using three or more Schema.org types are cited in AI answers roughly 13% more often than pages with no structured data. The reason is straightforward: structured data tells agents exactly what a piece of content means, not just what words it contains.

    Schema TypeValue for AI AgentsKey Fields
    OrganizationDefines your brand entity and official identityName, logo, social profiles, contact info
    ProductEnables precise product matching for specific queriesPrice, SKU, material, features, availability
    FAQFeeds directly into conversational answer patternsQuestion text, answer text
    HowToSupports procedural queries step-by-stepSteps, tools required, expected output
    ReviewAdds third-party validation signalsRating, review content, date, reviewer

    Freshness matters here too. Content updated in the past 30 days is cited far more often than older material, particularly in fast-moving industries like tech, finance, and SaaS. If your product pages haven’t been touched in six months, an agent treating freshness as a trust signal will deprioritize them.

    One often-overlooked issue: many AI crawlers can’t execute JavaScript. If your site relies on client-side rendering, agents may be fetching empty pages. Server-side rendering isn’t just a performance optimization — in agentic SEO, it’s a baseline requirement.

    Way 2: LLM Training Data (The Slow Channel Nobody Talks About)

    Real-time crawling gets the attention. But there’s a slower, deeper channel that shapes how agents perceive your brand before a query even runs.

    Large language models are trained on massive datasets — Common Crawl, Wikipedia, academic publications, industry media. That training data forms the model’s background assumptions. When an agent is asked which CRM has the strongest enterprise integration, its initial reasoning draws on patterns baked into its weights, not just live search results.

    If your brand doesn’t appear in that training data, or appears in the wrong context, you’re fighting an uphill battle every time.

    Wikipedia is the clearest example. Research indicates that roughly 47.9% of top citations in ChatGPT’s general knowledge queries originate from Wikipedia. A brand without a Wikipedia entry — or with an outdated one — risks being classified as an obscure or unverified entity by the model.

    The same dynamic applies to industry reports, analyst coverage, and media mentions. Gartner Magic Quadrant placements, deep-dive features in trade publications, and citations in academic research all contribute to what models “know” about your brand at a foundational level. These signals build slowly, but they compound. A brand consistently mentioned in authoritative sources trains future models to treat it as a default reference point.
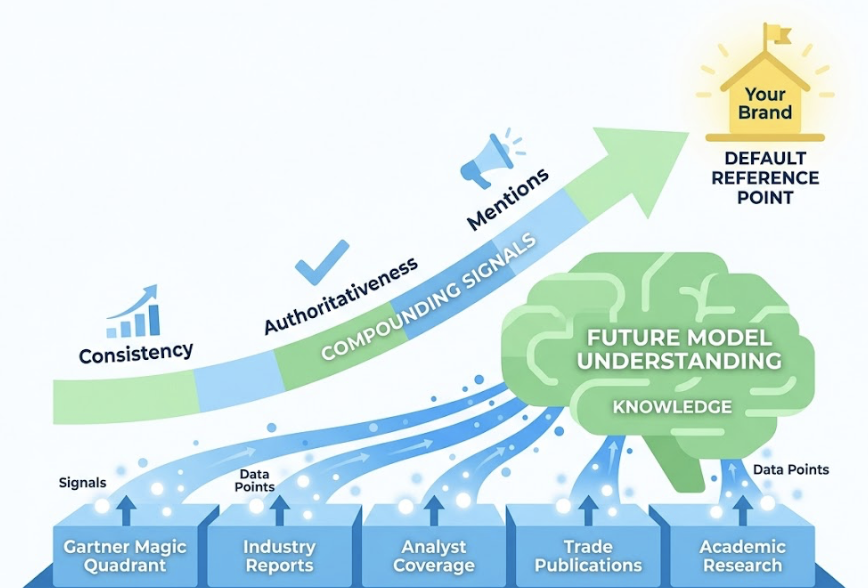
    Narrative drift is the hidden risk here. If your brand was heavily associated with a specific use case three years ago, models trained on that data will reproduce that framing — even if your product has evolved. The only fix is sustained presence in authoritative, updated sources. That means maintaining Wikipedia accuracy, publishing original research that gets cited, and using Organization Schema to establish clear entity relationships that prevent models from generating hallucinated attributes.

    This is the long game. And most brands aren’t playing it.

    Way 3: RAG and AI-Native Search (The Fast Channel)

    Retrieval-Augmented Generation is the engine behind ChatGPT Search, Perplexity, and Google AI Overviews. It’s what makes these platforms feel current: instead of relying solely on trained weights, they retrieve live content and generate answers grounded in real sources.

    This is where content strategy and agentic SEO converge directly.

    In a RAG pipeline, a user’s query gets converted into a numerical vector. The system finds content chunks with the closest semantic match. The model then synthesizes an answer from those chunks. If your content isn’t structured to match the way queries are phrased — not just in keywords, but in intent — it won’t surface.

    The practical implication: content that leads with a clear, direct answer performs significantly better in RAG retrieval than content that buries the point. Think BLUF (Bottom Line Up Front) — a 50-word summary at the top of your article that directly answers the core question, followed by supporting evidence. Agents don’t read linearly. They extract.

    Each AI platform weighs sources differently:

    PlatformSource PreferenceKey Data
    ChatGPT SearchBing-indexed content, Wikipedia, local authority mediaWikipedia accounts for ~47.9% of top citations
    PerplexityHighly recency-weighted, heavy social consensus signalsReddit citations account for ~46.7% of references
    ClaudeTechnical precision, official docs, academic sourcesStrong preference for structured specs and formal citations
    Google AIODeep Google ecosystem integration, EEAT signalsFavors traditionally authoritative domains with strong backlinks

    The gap between these preferences is significant. A brand that dominates in ChatGPT’s citation pool might barely appear in Perplexity’s answers. You can’t optimize for “AI” as a category. You need to understand platform-specific logic.

    Topify’s Source Analysis lets you see exactly which domains are being cited in AI answers for the prompts that matter to your brand. That data reveals not just where you appear, but which sources your competitors are leveraging — and what content gaps you need to close.

    Way 4: Third-Party Databases and Tool Integrations

    This channel is growing fastest, and most brands aren’t paying attention to it yet.

    AI agents don’t just browse the web. Increasingly, they call external APIs and databases directly through protocols like MCP (Model Context Protocol). A purchasing agent evaluating B2B software might query G2’s API for intent scores and competitive data, check Crunchbase for funding stage, or pull Yelp ratings for local service providers — all without loading a single web page.

    In this context, your G2 profile isn’t just a review platform. It’s your brand’s identity card in the agent ecosystem.

    If that profile has incomplete integration listings, outdated feature descriptions, or no recent customer case studies, an agent reasoning through a vendor shortlist will encounter what the research calls a “data void.” Incomplete data doesn’t get a benefit of the doubt. It gets deprioritized or excluded.

    The social layer matters here too. Agents consistently use Reddit, industry forums, and community platforms to source “authentic, non-promotional” signals. Perplexity’s 46.7% Reddit citation rate isn’t accidental — it reflects a deliberate preference for peer consensus over brand-controlled content.

    Data consistency across platforms is non-negotiable. Agents perform cross-source verification. If your Crunchbase lists 50 employees, your LinkedIn shows 200, and your own site claims “global team,” the inconsistency triggers a reliability penalty in the agent’s reasoning. It treats conflicting signals the same way a diligent analyst would: with skepticism.

    The practical checklist for this channel:

    • Maintain an accurate, complete G2/Capterra profile with recent reviews and current feature parity.
    • Keep Crunchbase data updated, especially funding stage and headcount.
    • Build genuine Reddit presence in relevant communities — not promotional posts, but actual participation in category discussions.
    • Ensure all third-party data sources agree on the same core facts about your company.

    Way 5: Agent Memory and Personalization Layers

    The fifth channel is the one that creates the most durable competitive advantage — and the hardest to recover from if you’re not in it.

    Modern AI agents, including ChatGPT’s Memory feature, store interaction history across sessions. They build a layered understanding of user preferences that informs future recommendations. A brand that earns a positive first mention in an agent’s memory doesn’t just win one recommendation. It enters a compounding feedback loop.

    Agent memory operates across three cognitive layers:

    Episodic memory stores specific interactions: “User was frustrated with Brand X’s delivery speed last month.” Semantic memory accumulates preference patterns: “User consistently prioritizes sustainable materials and mid-range pricing.” Procedural memory learns interaction rules: “User always wants local suppliers considered first.”

    When an agent draws on these layers to make a recommendation, recency matters — but established positive associations carry disproportionate weight. The agent is trying to minimize the risk of a bad recommendation. A brand it already “knows” is positive is safer than a new entrant, even one with a better objective profile.

    First impression compounds.

    This is why agentic SEO front-loads so heavily on the other four channels. You need to ensure your brand is present and accurate across crawling, training data, RAG, and third-party databases — so that when an agent encounters your brand for the first time in a zero-state query, the signals are strong enough to earn memory placement.

    Brands that miss the first wave of agent recommendations don’t just fall behind. They face an exponentially higher barrier to entry as agent memories become more established.

    You Can’t Optimize What You Can’t See — Track All 5 Channels

    Here’s the practical problem: manually testing these five channels isn’t feasible. You can’t query thousands of prompts daily across ChatGPT, Perplexity, Gemini, and Google AIO to check where your brand appears, how it’s framed, and whether competitors are outpacing you.

    That’s where purpose-built agentic SEO platforms change the calculation.

    Topify provides a unified GEO (Generative Engine Optimization) dashboard that converts these five discovery channels into trackable, actionable metrics. It monitors not just whether your brand name appears, but the context and sentiment of those appearances across major AI platforms.

    Topify FeatureProblem It SolvesApplication
    Visibility TrackingEliminates the blind spot of “am I being recommended?”Daily Share of Model monitoring across ChatGPT, Perplexity, Gemini
    Source AnalysisReveals which third-party domains are speaking for your brandIdentifies which media or Reddit threads competitors are leveraging for AI citations
    Sentiment AnalysisTracks shifts in how AI frames your brandIssues early warnings when AI begins generating negative framing before it hits sales
    Competitor MonitoringMaps competitor positions across AI platformsCompares AI-generated strength/weakness analysis across your competitive set

    The platform’s Source Analysis feature is particularly relevant to channels 3 and 4. When Topify detects that an AI platform is consistently citing a specific domain or URL when recommending your competitors, you can identify the exact content gap and act on it — whether that’s a piece of research, a review profile update, or a Reddit engagement strategy.

    Topify’s one-click execution layer closes the loop. When the platform surfaces a specific optimization opportunity — an outdated citation, a missing Schema type, a competitor dominating a key prompt — it doesn’t just show you the data. It proposes and deploys a targeted response.

    That’s the difference between monitoring visibility and actually moving it.

    Conclusion

    Agentic SEO isn’t an upgrade to traditional SEO. It’s a different game with different rules.

    In the search engine era, you optimized for the probability of being selected. In the agent era, you’re optimizing for the inevitability of being recommended. That means building entity clarity, not just keyword density. Cross-channel signal consistency, not just page rankings. Content structures that agents can parse at extraction speed, not just text that reads well to humans.

    The five channels — real-time crawling, training data, RAG, third-party databases, and agent memory — aren’t independent levers. They’re interconnected layers of a single discovery architecture. Strength in one amplifies the others. A gap in one creates drag across all of them.

    The brands showing up everywhere in AI recommendations aren’t lucky. They’re structured for it.

    FAQ

    What is Agentic SEO?

    Agentic SEO is the practice of optimizing brand presence across the discovery channels that AI agents use to find, evaluate, and recommend brands. It goes beyond traditional SEO (ranking on search results pages) and GEO (appearing in generative AI answers) to address the full decision-making logic of autonomous AI systems. This includes structured data, training data presence, RAG-optimized content, third-party database accuracy, and agent memory signals.

    How is Agentic SEO different from GEO?

    GEO (Generative Engine Optimization) focuses on getting your content cited in AI-generated answers. Agentic SEO is broader: it treats AI agents as autonomous decision-makers with tool access, memory, and reasoning capabilities — and optimizes for every layer those agents use. GEO is one component of agentic SEO, specifically addressing the RAG and training data channels.

    Which AI platforms should I prioritize for brand visibility?

    Start with ChatGPT Search, Perplexity, Google AI Overviews, and Gemini — these four cover the majority of AI-driven discovery today. For B2B brands, prioritize platforms with MCP integrations, as agents in enterprise workflows increasingly query G2, Crunchbase, and similar databases directly. Monitor Perplexity for social consensus signals and ChatGPT for entity authority. Visibility data across all platforms varies significantly by brand category, so tracking at the prompt level — rather than assuming platform-wide presence — gives you an accurate picture.
    Read More

  • Agentic SEO vs GEO vs Traditional SEO: What’s Different

    Agentic SEO vs GEO vs Traditional SEO: What’s Different

    Your domain authority is solid. Your keyword rankings are holding. But none of that tells you whether Perplexity is recommending your competitor instead of you right now.

    That gap isn’t a data problem. It’s a structural one. Search has quietly split into three parallel systems, each with its own logic, its own signals, and its own definition of “visible.” Running one playbook across all three doesn’t work anymore. And in 2026, the cost of that mistake is compounding fast.

    Traditional SEO Still Works — Just Not for Everyone Searching

    Traditional SEO is built on three pillars: crawling, indexing, and ranking. Backlink authority, keyword relevance, page speed, and mobile-friendliness are the signals that tell Google’s algorithm a page deserves to rank. That logic hasn’t changed in 20 years.

    What has changed is the scope of what it covers.

    Traditional SEO only captures users who go to a search engine, type a query, and click a result. That’s a shrinking slice of how people actually find information today. In 2024, 60% of US searches ended without a single click — up from just 26% in 2022. AI Overviews, featured snippets, and direct answer boxes are absorbing the query before the user ever reaches the blue links.

    That said, traditional SEO isn’t dying. It’s shifting roles.

    Most AI engines use traditional search indexes as their retrieval layer. ChatGPT pulls from Bing, Google AI Overviews rely on Google’s native index, and Claude uses Brave’s search infrastructure. A brand that’s technically invisible to crawlers — slow pages, broken schema, thin content — stays invisible in AI answers too. Traditional SEO is now less about rankings and more about making sure AI can find you in the first place.

    The floor is still the floor. The ceiling has moved.

    GEO Is About Getting Cited — Not Getting Clicked

    Generative Engine Optimization (GEO) is the second layer. Its goal isn’t a ranked position. It’s getting included in the AI-generated answer itself, as a cited source, a named brand, or a referenced data point.

    The mechanism is different from PageRank. When a user sends a prompt, the LLM retrieves “knowledge chunks” from across the web and synthesizes them into a response. AI systems favor content with high semantic density — specific statistics, clear structure, direct answers. A sentence like “our software is fast” has near-zero retrieval value. A sentence like “average processing time is 12ms, 40% faster than the industry baseline” is exactly what gets pulled.

    Citation patterns in 2025 make this concrete. Reddit accounts for 46.5% of Perplexity’s citations and 21% of Google AI Overviews references. Wikipedia holds 47.9% of ChatGPT’s citations. YouTube drives roughly 23% of citations across all major AI platforms. The pattern is clear: AI systems trust third-party voices over brand-owned content.

    Here’s the counterintuitive upside. GEO traffic converts at a different rate. Visitors arriving from AI citations convert 23x higher than traditional organic traffic. By the time a user clicks through from an AI answer, they’ve already done the research, made the comparison, and largely made the decision. You’re not at the top of the funnel. You’re at the bottom.

    That changes how you should value GEO mentions. A brand cited twice in a Perplexity answer may be worth more than ranking third on Google.

    Agentic SEO Is a Different Game Entirely

    Agentic SEO is where the model breaks from everything familiar. It’s not about ranking. It’s not about being cited. It’s about being selected by an AI agent that’s executing a task without a human in the loop.

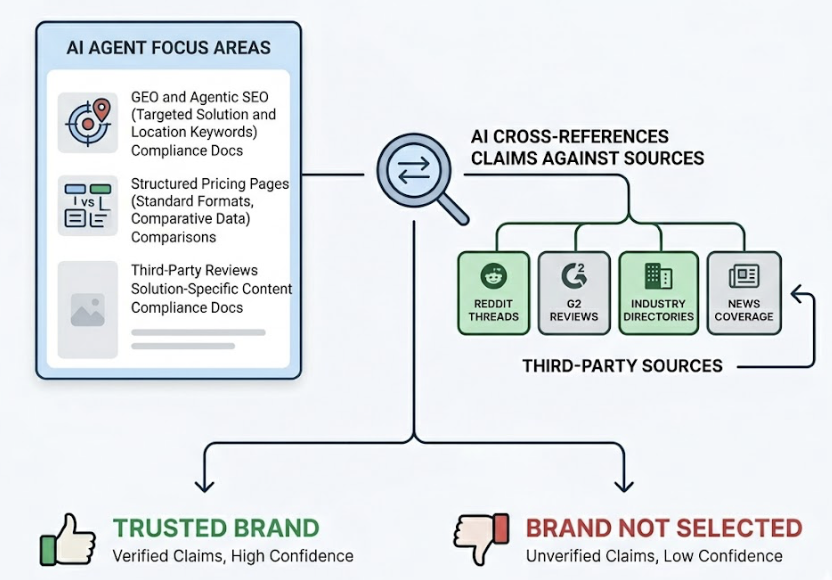
    When someone asks an AI agent to “find the best CRM for a 50-person B2B team under $200/month with SOC 2 compliance,” the agent doesn’t browse websites. It makes API calls, reads structured data, cross-references entity records across LinkedIn, G2, government registrations, and review platforms, then builds a shortlist. There’s no search results page. There’s no article to click. There’s a decision brief — and your brand is either on it or not.

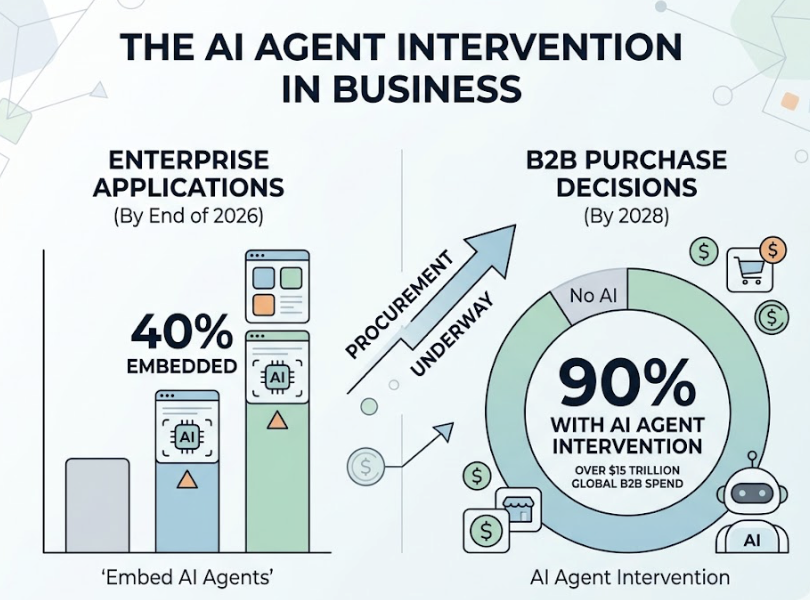
    Gartner projects that 40% of enterprise applications will embed AI agents by end of 2026. In B2B specifically, 90% of purchase decisions are expected to involve AI agent intervention by 2028, covering more than $15 trillion in global B2B spend. That’s not a future scenario. That’s a procurement shift already underway.

    Winning in agentic SEO requires three things most brands haven’t built yet.

    First, entity consistency. Every data point about your brand across your website, G2, LinkedIn, and third-party databases needs to match exactly. Conflicting information — different founding years, different headcounts, different pricing — lowers an agent’s confidence score in your brand.

    Second, API accessibility. Agents prefer structured data they can query directly over HTML they have to parse. Pricing pages, spec sheets, and compliance documentation that’s machine-readable give agents a reason to include your brand without extra effort.

    Third, schema depth. Using Schema.org @id as a global identifier connects your discrete web pages into a knowledge graph an agent can navigate logically, not just crawl.

    This is less about content and more about infrastructure.

    The Three Models, Side by Side

    DimensionTraditional SEOGEOAgentic SEO
    TriggerKeyword searchConversational promptAutonomous goal execution
    Core goalRank and earn clicksGet cited in AI answersEnter the agent’s decision brief
    Key signalsBacklinks, keyword relevance, authoritySemantic density, structured content, third-party citationsAPI compatibility, schema completeness, entity consistency
    MetricsRankings, CTR, organic trafficCitation frequency, Share of Voice, sentimentSelection rate, decision-chain participation
    Typical toolsSemrush, Ahrefs, GSCPerplexity, Topify, FraseAPI managers, LangChain, MCP
    How you winBuild authority, own the first pageBecome the source AI can’t skipBe machine-readable and directly transactable

    The three aren’t competing. They’re sequential. Without traditional SEO, AI can’t find you. Without GEO, AI agents can’t verify your authority. Without agentic SEO, you can’t complete the transaction when no human is watching.

    Which One Should You Prioritize in 2026?

    The honest answer: it depends on who’s buying from you and how they search.

    For SaaS brands, GEO and agentic SEO should take the lead. Pricing pages and solution-specific content get 4 to 9 times more AI traffic than other site sections. Buyers are already asking AI to compare tools before they book a demo. Optimizing for that moment — through third-party reviews, structured pricing, and compliance documentation — matters more than chasing one more ranking.

    For e-commerce brands, GEO is the most immediate lever. AI-driven retail recommendations grew 693% during the 2025 holiday season. Consumers are asking ChatGPT for product recommendations the same way they used to ask Google. YouTube and Reddit, which together drive close to half of retail AI citations, are your new distribution channels.

    For professional services and content-driven brands — legal, financial, medical — traditional SEO and GEO carry equal weight. These are YMYL categories where AI systems heavily reference indexed, authoritative sources. The play is structuring content for AI extractability: lead with a 40-60 word direct answer at the top of each piece, then build out the detail below.

    One thing is true across all categories: GEO is the highest-ROI opportunity most teams haven’t acted on yet. Agentic SEO is the most important thing most teams aren’t ready for.

    Start with GEO. Build toward agentic.

    You Can’t Optimize What You Can’t See

    Here’s the problem none of this solves on its own. Traditional SEO has Google Search Console. GEO and agentic SEO have almost nothing built for measurement.

    AI answers are a black box. A brand might be getting cited in Perplexity 40 times a day without knowing it. A competitor might have quietly overtaken them in ChatGPT responses while their Google rankings held steady. Without visibility into what AI is actually saying, any optimization effort is essentially guesswork.

    That’s the gap Topify was built to close.

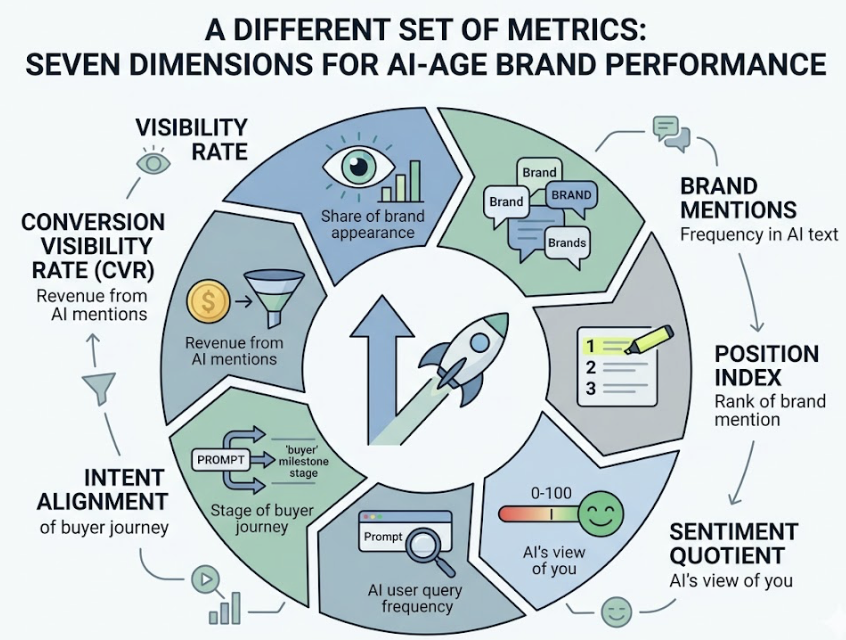
    Topify tracks brand visibility across ChatGPT, Gemini, Perplexity, and Google AI Overviews, measuring seven metrics per platform: visibility, sentiment, position, volume, mentions, intent, and CVR. In practice, this means a team can see not just whether they’re being mentioned, but whether the sentiment is positive, where they rank relative to competitors, and which types of prompts are driving those mentions.

    The Source Analysis feature is particularly useful for GEO strategy. It reverse-engineers AI citations: which third-party domains are being referenced when a competitor gets recommended? That tells you exactly where to publish, pitch, or place content next — not based on assumption, but on the actual retrieval patterns of the AI systems.

    A common scenario: a brand’s official site ranks higher than a competitor’s domain in Google. But in Perplexity, the competitor keeps appearing because a third-party review site with highly structured comparison tables is getting cited instead. Topify surfaces that gap. Without it, the brand keeps optimizing the wrong asset.

    AI Volume Analytics adds another layer. It identifies which prompt categories are growing in your space — so a content team can build for queries that are gaining traction before competitors do. It’s less about reacting to existing rankings and more about positioning for where AI search volume is heading.

    Conclusion

    Traditional SEO, GEO, and agentic SEO aren’t three versions of the same thing. They’re three separate games running simultaneously, each with different rules, different signals, and different definitions of winning.

    Traditional SEO is still the foundation — skip it and AI can’t find you at all. GEO is the highest-leverage opportunity in 2026 for most brands, with citation-driven traffic converting far beyond what organic ever did. Agentic SEO is the long game: the infrastructure decisions made now will determine whether your brand appears in automated purchasing decisions two years from now.

    The starting point for all three is knowing where you actually stand. Before you restructure content, build schema, or pitch review sites, check what AI systems are saying about your brand today. That answer tends to be more surprising than most teams expect.

    Get started with Topify to see where your brand stands across AI platforms before optimizing for any of the three models.


    FAQ

    Q: What’s the difference between GEO and Agentic SEO?

    A: GEO focuses on getting your brand cited in AI-generated answers to human prompts — someone types a question and the AI pulls your content as a source. Agentic SEO is about being selected by AI agents operating without human prompts at all. The agent has a goal, executes a multi-step research process, and makes a recommendation or decision. GEO is about citation. Agentic SEO is about selection.

    Q: Does traditional SEO still matter in 2026?

    A: Yes, but its role has shifted. Google still holds 89.6% of the global search market and handles billions of queries daily. More importantly, most AI engines — ChatGPT, Claude, Google AIO — rely on traditional search indexes to retrieve real-time content. A brand that’s technically broken or invisible to crawlers won’t appear in AI answers either. Traditional SEO is now the prerequisite layer, not the end goal.

    Q: How do AI agents discover brands?

    A: Agents don’t browse websites the way humans do. They make API calls, pull structured data, and cross-reference entity records across multiple platforms — your website, G2, LinkedIn, government registries, review databases. Brands with consistent entity data, accessible APIs, and clean schema markup are far more likely to make it into an agent’s shortlist. Inconsistent information across platforms lowers an agent’s confidence score in your brand.

    Q: What metrics should I track for Agentic SEO?

    A: Traditional metrics like rankings and CTR don’t apply. The relevant signals are entity consistency scores across platforms, API response quality, schema coverage depth, and — where trackable — selection rate in agent-driven tasks. On the monitoring side, tracking AI citation frequency, Share of Voice across AI platforms, and sentiment trends gives you a proxy for how agents are likely to perceive your brand when they do their own research.


    Read More

  • Agentic SEO: How AI Agents Are Changing Brand Discovery

    Agentic SEO: How AI Agents Are Changing Brand Discovery

    Traditional SEO gets you ranked. Agentic SEO gets you chosen, by AI agents acting on users’ behalf before they ever open a search box.

    Here’s a scenario that’s playing out more often than most marketers realize. A user types into ChatGPT: “Find me reliable cloud storage for a 50-person agency, under $20 per seat.” The agent calls a search tool, crawls a dozen sites, cross-references G2 reviews, checks Reddit threads, and outputs one recommendation with a clear explanation of why. The user says “sounds good” and signs up.

    Your brand’s Google ranking? Never entered the picture.

    This is what Agentic SEO is actually about. Not rankings, not even AI citations. The question is whether autonomous agents, the ones making decisions on your users’ behalf, include you in their final answer.

    The Search Box Is No Longer the Front Door

    For two decades, the path was predictable. User types a query, a ranked list of links appears, user clicks through to a brand website. That website was the decision environment. Every conversion test, every landing page, every headline variant was designed for that moment.

    AI agents break that path entirely.

    Systems like OpenAI’s Operator, Microsoft Copilot, and Google’s Gemini don’t return a list of links. They take an instruction, execute a multi-step research process, and deliver a singular recommendation. They browse on the user’s behalf, synthesize across dozens of sources, and often complete the entire task, including purchase, without the user ever visiting a brand website.

    The brand website is no longer the decision environment. The agent’s reasoning engine is.

    For commercial brands, the stakes compound quickly. With the Universal Commerce Protocol (UCP), developed by Google and Shopify, agents can now complete transactions directly inside conversational interfaces. A user asks for a weekender bag under $250 and checks out without ever landing on a storefront. If your brand isn’t in the agent’s selection set, you don’t just lose a click. You lose the sale entirely.

    Agentic SEO, Defined (Without the Jargon)

    The industry uses a lot of terms loosely. AEO, GEO, Agentic SEO. They’re not interchangeable.

    Optimization TypeWhat You’re Optimizing ForTypical Platforms
    Traditional SEOSearch engine rankings, human clicksGoogle, Bing
    GEOCitation in AI-generated answersChatGPT, Perplexity, AI Overviews
    Agentic SEOSelection by autonomous agents acting on users’ behalfAI Operator, Copilot, agent workflows

    GEO gets you mentioned. Agentic SEO gets you chosen.

    The difference matters because an agent’s goal isn’t to summarize information. It’s to complete a task. When an agent is booking, comparing, or purchasing, it’s making a judgment call about which brand to act on. That judgment runs on a different set of signals than keyword relevance or backlink authority.

    Agentic SEO is the practice of ensuring your brand is structured, verified, and consistent enough to be selected at the end of that judgment process.

    How AI Agents Actually Decide What to Recommend

    This is the part most SEO guides skip over. The mechanics matter.

    An agent doesn’t search. It executes. When a user hands it a task, it breaks that task into sub-tasks, calls tools (web search APIs, the Model Context Protocol), crawls pages that offer structured and machine-readable information, then verifies.

    That last step is where most brands get filtered out.

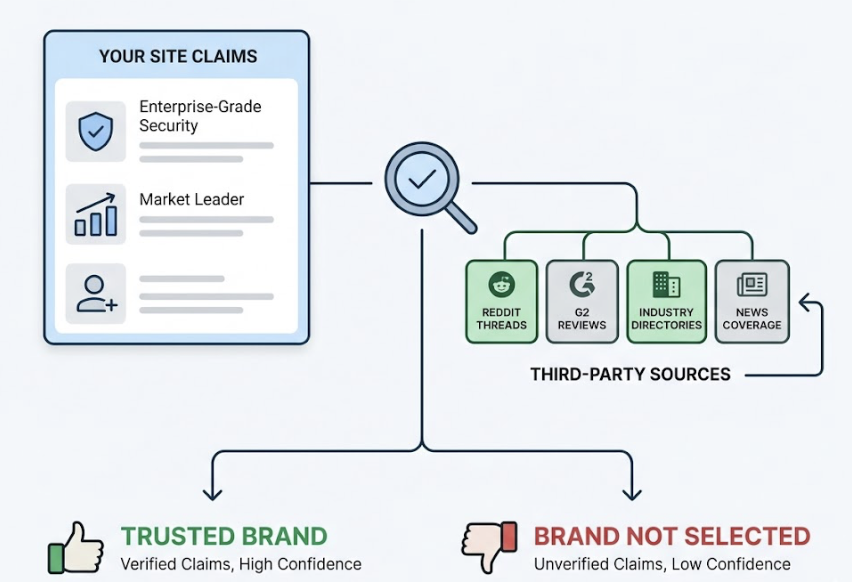
    The agent cross-references what your site claims against what third-party sources say. It checks Reddit threads, G2 reviews, industry directories, and news coverage. If your site says “enterprise-grade security” but no credible third-party source corroborates that claim, the agent’s confidence in your brand drops. You don’t get selected because the agent can’t verify you.

    Three dimensions drive agentic selection:

    Brand Clarity: Can the agent build a coherent picture of what you offer? If your website says “premium” but Yelp says “budget,” the mixed signal creates ambiguity the agent won’t resolve in your favor.

    Brand Authority: Do independent sources validate your claims? Third-party sources are cited 6.5 times more often by AI engines than a brand’s own owned media. That’s not a minor factor.

    Brand Trust: Is your brand credible enough for an agent to build a plan around? For high-stakes actions like booking or purchasing, trust is the decisive threshold, and it’s earned externally, not declared internally.

    You Can Rank #1 on Google and Still Be Invisible to Agents

    Traditional SEO tools track the ten-blue-links world. Ahrefs and Semrush tell you where you rank on SERPs, how many backlinks you have, what keywords you’re targeting. Useful data, built for a model that agents are increasingly bypassing.

    The gap is structural. An agent may ignore the top organic result entirely if it detects a contradiction on a high-authority third-party site, or if the top result sits behind a login wall. No traditional SEO tool tracks that. None of them measure Share of Model, how often a brand appears and gets recommended across LLMs relative to its competitors.

    There’s also a decay problem that most teams aren’t accounting for. A Google ranking can hold for years. AI citations in platforms like ChatGPT Search or Perplexity decay in roughly 13 weeks if the content isn’t updated to reflect new data or industry shifts. The cadence required for agentic visibility is fundamentally different from what most SEO workflows are built for.

    Most content strategies compound this gap by optimizing for human readers. Persuasive copy, emotional hooks, conversion-focused layout. Agents are bot-readers. They prioritize neutral, fact-dense, structurally clear content. If your site is heavy on narrative and light on machine-readable structure, an agent will pass you over for a competitor that’s easier to process.

    3 Signals That Determine Whether Agents Select Your Brand

    Signal 1: Third-Party Consensus

    Agents verify before they recommend. That means earned media, review platform presence, and forum mentions aren’t just brand awareness plays anymore. They’re the grounding data agents use to calibrate trust.

    Strategic digital PR, getting your brand referenced on Reddit, G2, or in credible industry publications, now directly influences whether agents include you in their recommendation set. If the consensus says you’re credible, the agent treats you as credible. It’s that direct.

    Signal 2: Cross-Platform Narrative Consistency

    Inconsistency is a red flag for AI reasoning systems. If your core value proposition reads differently on your website, your LinkedIn profile, and your G2 listing, the agent’s confidence in your brand drops. Standardize descriptions, pricing context, and positioning across your entire digital footprint.

    Category leaders typically hold 35–40% Share of Model on high-intent prompts. That level of presence doesn’t happen by accident. It’s built on consistent, reinforced brand signals across multiple platforms over time.

    Signal 3: Machine-Readable Infrastructure

    This is the technical layer most marketing teams overlook. Agents favor content that’s structured for machine consumption: FAQPage schema, Product schema, pricing tables, feature comparison tables, and clear instructional guides. Content buried in complex JavaScript or locked behind paywalls is effectively invisible to most research agents.

    For e-commerce brands, UCP compliance is becoming non-negotiable. It lets agents see real-time pricing, inventory, and discounts, and complete transactions without human navigation. For SaaS and data-heavy products, exposing data through APIs or the Model Context Protocol allows agents to answer highly specific user questions with live data, a meaningful trust signal that pushes you ahead of competitors who don’t offer it.

    How to Start Measuring Your Agentic Visibility

    You can’t optimize what you can’t see.

    The first step is establishing a baseline for your brand’s current presence across AI systems. How often does your brand appear when a relevant prompt is submitted to ChatGPT, Perplexity, or Gemini? When it appears, is it being recommended or just listed as a footnote? How does that compare to your direct competitors?

    This is where Topify becomes practically useful. Topify tracks brand visibility across major AI platforms, monitoring seven key metrics: visibility rate, sentiment, position, volume, mentions, intent, and conversion visibility rate (CVR). It surfaces which sources AI engines are pulling from, which competitors are being recommended over you, and where gaps in your content strategy are creating blind spots.

    Brands with a visibility rate below 10% are effectively invisible to AI systems. The benchmark for market leaders runs at 80% or higher. Knowing where you sit is the starting point for knowing what to fix.

    Because LLMs generate probabilistic outputs (the same prompt can return different results), measuring agentic visibility requires sampling across prompt variations: “best CRM,” “top CRM for startups,” “CRM with the best security.” Topify handles this probabilistic sampling automatically, giving you a statistically grounded picture of your Share of Model rather than a single-point snapshot that might not reflect typical agent behavior.

    Conclusion

    The shift to agentic discovery isn’t coming. It’s already running in the background of how users make decisions about products, services, and brands.

    The brands that’ll have an advantage aren’t necessarily the ones with the biggest content budget. They’re the ones with the cleanest data, the most consistent narrative, and the strongest third-party validation. The ones that have made it easy for an agent to read, verify, and trust them.

    Establishing your baseline AI visibility now, before agentic traffic becomes the majority, is the highest-leverage move most marketing teams can make. The window for early positioning is open. It won’t stay that way.

    FAQ

    Q: Is Agentic SEO the same as GEO?

    No. GEO focuses on being cited in AI-generated answers. Agentic SEO covers the full autonomous workflow: research, verification, decision, and action. GEO is one component of an agentic strategy, but the latter also requires technical infrastructure like UCP and MCP that GEO doesn’t necessarily address.

    Q: What types of content do AI agents actually prioritize for crawling?

    Agents favor content that’s machine-readable and fact-dense: schema markup, pricing tables, feature comparisons, and clear How-To guides. They tend to skip content that’s conversational without supporting facts, hidden behind login walls, or rendered in complex JavaScript that’s difficult to parse.

    Q: Should I focus on GEO first or Agentic SEO?

    For most brands, starting with GEO builds visibility in current AI summary systems like Google AI Overviews. If you’re in e-commerce, travel, or software, layer in Agentic SEO primitives (UCP, MCP, structured data) in parallel. The technical investments overlap significantly, so there’s no reason to treat them as sequential.

    Q: Does Agentic SEO require a dedicated technical team?

    Not to get started. Adding schema markup, improving cross-platform consistency, and monitoring AI visibility don’t require engineering resources. A full-scale implementation with live API connections and MCP integrations does benefit from technical involvement. But the strategic groundwork is accessible to most marketing teams today.

    Read More

  • Agentic SEO: How to Track Your Brand Across AI Agents

    Agentic SEO: How to Track Your Brand Across AI Agents

    The first thing most brands do when they hear about agentic SEO is type their own name into ChatGPT. That’s the wrong starting point.

    Searching your brand name tells you almost nothing about how you’re actually performing. The real question is: when a buyer prompts an AI agent with “what’s the best tool for [your category],” does your brand appear? And if it does, where does it rank, and how does the AI describe you?

    Most brands have no idea. This guide walks through a repeatable, step-by-step process for building real visibility tracking across AI agents, so you stop guessing and start seeing the full picture.


    Your Brand Might Already Be Invisible to AI Agents

    Traditional SEO tells you how you rank in a list of blue links. Agentic SEO asks a different question entirely.

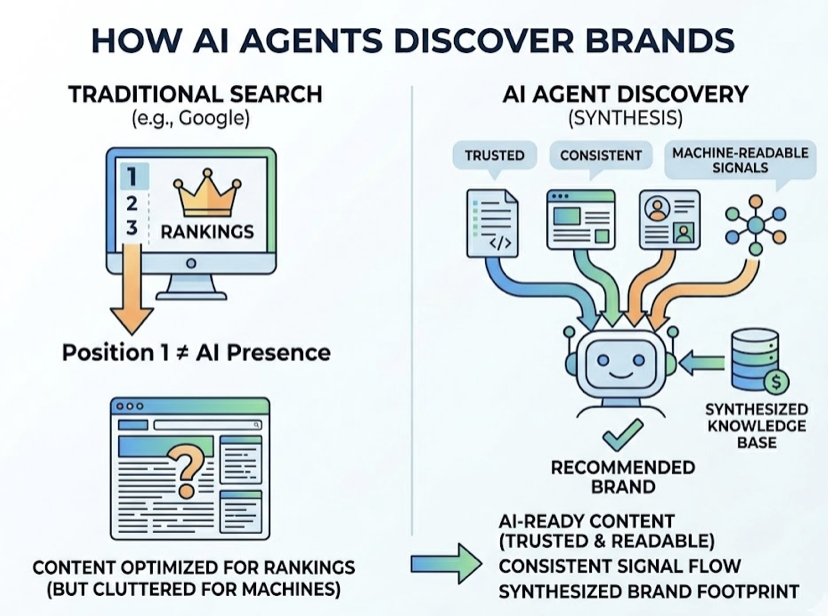
    AI agents don’t pull from search rankings. They synthesize from trusted, consistent, machine-readable signals across a brand’s entire digital footprint. A brand can sit at position one in Google and still be absent from every AI-generated recommendation because the two systems operate on fundamentally different logic.

    The gap is larger than most teams expect. Research shows AI models currently misrepresent 60% of brands, stating incorrect prices, discontinued features, or fabricated claims. Meanwhile, 93% of AI search sessions end without a website click, meaning the AI’s recommendation is the decision point, not a gateway to one.

    That’s the problem agentic SEO tracking is built to close.


    What “Tracking Visibility” Actually Means in Agentic SEO

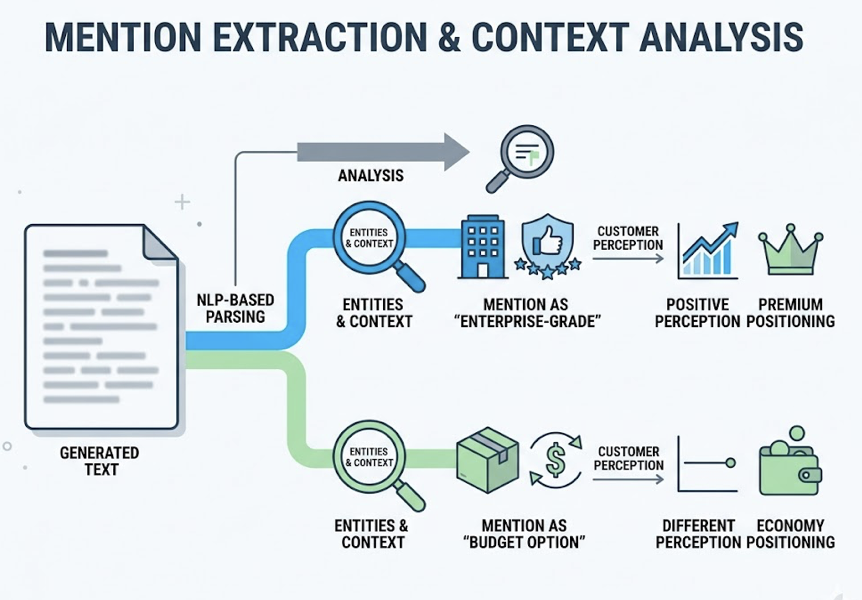
    Brand tracking in agentic SEO isn’t a single metric. It’s a combination of three signals that need to be measured together: Visibility (whether you’re mentioned at all), Position (where you appear relative to competitors in the AI’s response), and Sentiment (how the AI characterizes your brand).

    Tracking any one of these in isolation will mislead you. A brand mentioned frequently but always framed as “a budget option” has a sentiment problem that raw mention counts won’t reveal. A brand that ranks first for one prompt type and disappears for another has a coverage gap.

    Here’s how agentic SEO metrics compare to what most marketing teams currently track:

    DimensionTraditional SEOAgentic SEO
    Visibility signalKeyword ranking positionBrand mention rate in AI responses
    Quality signalClick-through rateSentiment score + position in AI answer
    CoverageSearch query rankingsPrompt type coverage across platforms
    Competitive dataSERP shareCitation share vs. competitors

    The stakes are real: 73% of B2B buyers now report trusting AI product recommendations over traditional advertisements. If a competitor is cited in 80% of AI responses and your brand appears in 20%, that’s not a ranking problem. That’s an eligibility gap.


    Step 1: Map the AI Agents Your Audience Actually Uses

    Not every AI platform serves the same audience. Start with platform-audience fit before building a tracking system.

    ChatGPT currently holds between 60% and 78% of the global generative AI market and drives 87.4% of all AI-related referral traffic, making it the default priority for most brands. But the picture is more nuanced by buyer type.

    Perplexity AI skews toward research-intensive and technical queries, holding a stable 6-7% market share by focusing on high-accuracy citation. Google’s AI Overviews reach 2 billion monthly users, making it essential for any brand dependent on Google’s ecosystem. Microsoft Copilot has strong penetration in the 18-29 demographic through Office 365 integration.

    Match platforms to your buyer profile before you track anything:

    Audience TypePriority Platforms
    B2B / Enterprise buyersChatGPT, Perplexity, Copilot
    Consumer / General marketChatGPT, Google AI Overviews
    Research / Technical usersPerplexity, Claude
    Global / Emerging marketsChatGPT, Gemini

    Don’t try to track everywhere at once. Pick two or three platforms where your buyers are actually making decisions. Go deep on those before expanding.


    Step 2: Build a Prompt Library That Mirrors Real Buyer Queries

    AI agents respond to prompts, not keywords. The quality of your visibility tracking depends entirely on the quality of the prompts you’re testing against.

    Your prompt library needs to cover three types of queries: category queries (“what’s the best tool for X”), comparison queries (“X vs. Y, which should I use”), and recommendation queries (“I need help with Z, what do you suggest”). Each type reveals a different dimension of how AI agents perceive your brand.

    Here’s the thing: response variability makes low-volume tracking unreliable. Research by SparkToro found there’s less than a 1-in-100 chance that ChatGPT or Google’s AI will surface the same brand list in two consecutive responses to the same prompt. Every run produces slightly different outputs. You need enough data points to identify patterns, not noise.

    The recommended minimum is 20-50 conversational queries, run across dozens of sessions, to identify what researchers call a “stable consideration set”: the brands that appear frequently enough to be treated as reliable options by the model. Below that threshold, you’re tracking randomness.

    Topify‘s High-Value Prompt Discovery feature automates this step, continuously surfacing the prompts most likely to drive buyer decisions in your category, rather than relying on manual guesswork.


    Step 3: Run Systematic Tracking Across Platforms

    Once your prompt library is in place, tracking cadence becomes the next critical variable. AI model re-training cycles cause brands to be re-evaluated against fresh data, which means a brand that appeared consistently last month can drop out of recommendations this month without any change on your end.

    Minimum tracking frequency: weekly. Monthly snapshots are already stale.

    For each tracking run, record four dimensions per prompt: Was the brand mentioned? At what position relative to competitors? What was the sentiment framing (positive, neutral, cautious, or negative)? What sources did the AI cite to support its recommendation?

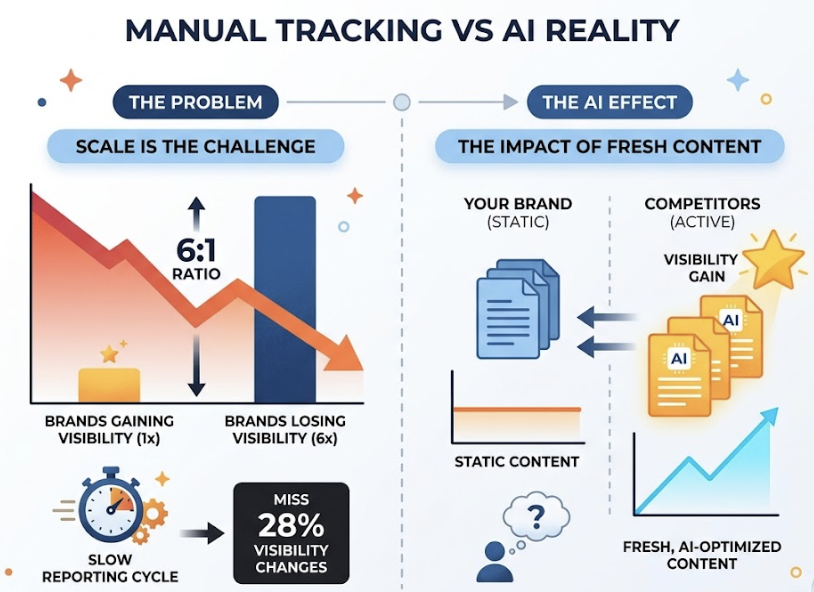
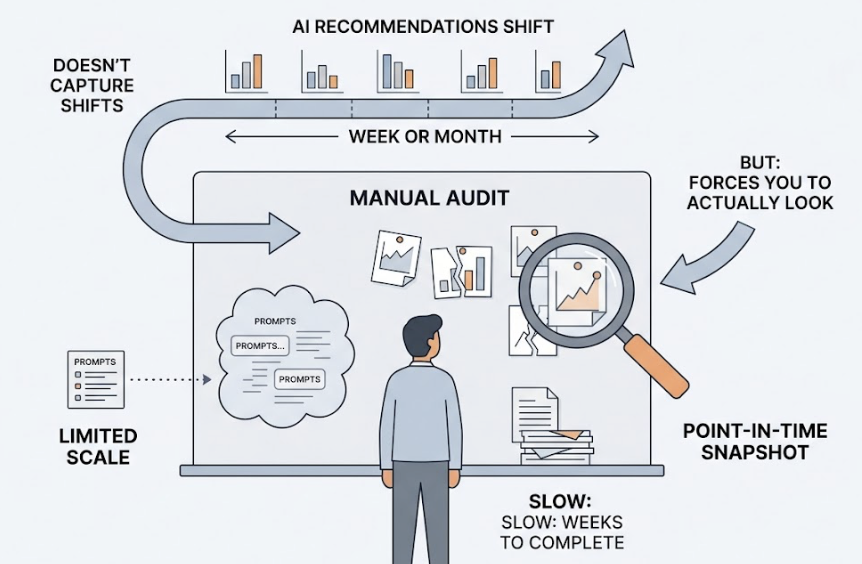
    Manual tracking at this scale isn’t feasible. For every brand that gains AI visibility in a given week, six lose it: a 6:1 negative-to-positive ratio driven by competitors publishing fresh, AI-optimized content while a brand’s representation stays static. Businesses relying on manual methods miss an estimated 28% of visibility changes simply because the reporting cycle is too slow.

    Topify‘s platform handles this automatically, tracking brand performance across ChatGPT, Gemini, Perplexity, DeepSeek, and other major platforms simultaneously, then generating seven standardized metrics per run: visibility, sentiment, position, volume, mentions, intent, and CVR. The Basic plan covers 100 prompts and 9,000 AI answer analyses per month, which is enough for most in-house teams to start building a reliable baseline.


    Step 4: Read the Data, Then Act on It

    Raw tracking data has no value without a clear framework for interpreting it. The most structurally useful framework here is the Net Sentiment Score (NSS), which classifies AI mentions across five categories: Endorsement, Neutral, Cautious, Negative, and Hallucination.

    The formula:

    NSS = [(Endorsement + Neutral Mentions) − (Negative + Hallucination Mentions)] / Total Mentions × 100

    NSS RangeWhat It MeansWhat to Do
    +60 to +100Strong positive positioningMaintain signals; expand to adjacent categories
    +20 to +59Net positive with gapsStrengthen third-party credibility sources
    −19 to +19Neutral or mixedAddress cautious or negative drivers immediately
    −20 to −100Net negativeRemap your digital entity across authoritative sources

    Each metric category points to a specific action. Low visibility means you’re absent from the AI’s consideration set — build topical coverage on the prompts where you’re missing. Low position means you’re mentioned but outranked — analyze which domains AI platforms are citing for higher-ranked competitors and close those content gaps. Negative or cautious sentiment typically signals inconsistent entity data across your website, directories, and third-party platforms.

    Hallucinations are the most urgent issue. When AI models state incorrect facts about your brand — wrong pricing, discontinued features, fabricated capabilities — the fix requires proactive “entity remapping”: publishing clear, authoritative, machine-readable corrections across your entire digital footprint. Forty-seven percent of B2B purchase decisions now involve an AI research phase; a hallucinated fact at that stage costs you the deal before you ever knew you were competing for it.

    Topify‘s Source Analysis feature shows exactly which domains AI platforms are citing when they respond to prompts in your category. Competitor Monitoring reveals the specific prompt types sending buyers to competitors instead of you, giving your team a clear list of gaps to close.

    Data without action is just a dashboard.


    3 Mistakes That Make Agentic SEO Tracking Useless

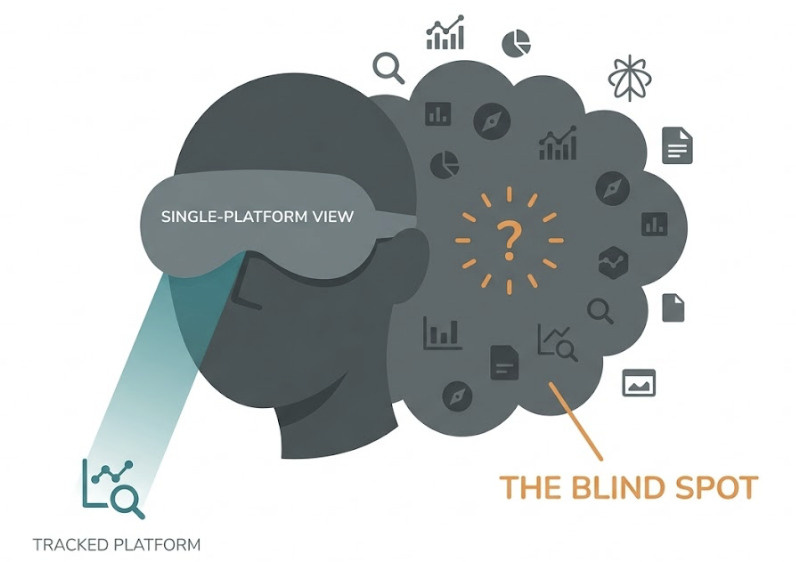
    Tracking only one platform. ChatGPT dominates with 810 million daily users, but your buyers may be using Perplexity for technical research or encountering Google AI Overviews during category discovery. Single-platform tracking creates blind spots in exactly the prompt types where you’re most vulnerable.

    Tracking too infrequently. Quarterly or monthly snapshot audits are already outdated by the time they’re reviewed. AI model updates re-evaluate every brand in the training corpus. The 6:1 ratio of brands losing visibility versus gaining it compounds quickly when tracking gaps let competitors pull ahead undetected.

    Measuring mentions without context. Being mentioned fifth out of five with a “cautious” framing is worse than not being mentioned at all. It signals to the model that your brand exists in the consideration set but isn’t the safe choice. Visibility data without position and sentiment makes your tracking misleadingly positive and leads to the wrong optimization decisions.

    Conclusion

    Tracking your brand across AI agents follows a clear sequence: map the platforms your buyers use, build a prompt library that mirrors real purchase queries, run systematic weekly tracking, and act on what the NSS and citation data reveal.

    The brands building this infrastructure now, before AI-driven discovery becomes the primary buyer research channel, will hold a compounding advantage over those still optimizing for traditional search rankings. Visibility in agentic SEO comes before optimization. And in the agentic era, being eligible is the new ranking factor.

    Topify is built specifically for this workflow, tracking brand visibility, sentiment, position, and citation sources across the major AI platforms with automated reporting and one-click optimization execution. The Basic plan at $99/month covers 100 prompts and 9,000 AI answer analyses across ChatGPT, Perplexity, and AI Overviews.


    FAQ

    What’s the difference between Agentic SEO and GEO? 

    GEO (Generative Engine Optimization) refers to optimizing content to appear in AI-generated responses. Agentic SEO is broader: it covers the full continuous workflow of AI agents that sense, plan, and act, including tracking, optimization, execution, and performance monitoring. GEO is one component of an agentic SEO strategy.

    How many prompts do I need for reliable visibility data? 

    Research points to 20-50 conversational queries as the minimum for a stable dataset. Below that threshold, response variability makes it difficult to distinguish real patterns from noise in the AI’s outputs.

    Can small brands compete with large brands in AI agent recommendations? 

    Yes, and often more effectively. AI models prioritize entity consistency and topical depth over media budgets. A brand with clear, consistent, machine-readable information across its website, directories, and third-party sources will outperform a large brand with fragmented or contradictory messaging.

    How often do AI agents change which brands they recommend? 

    Frequently. For every brand gaining AI visibility in a given week, six are losing ground. Model updates, competitive content, and query sensitivity all drive this volatility. Weekly tracking is the minimum cadence for catching changes before they compound.

    What’s the fastest way to improve brand visibility in AI agents? 

    Fix entity consistency first. Ensure your brand name, description, pricing, and key claims match exactly across your website, Google Business Profile, industry directories, and review platforms. Cross-source consensus is how AI models determine which brands are “safe” to recommend. Inconsistency signals risk, and AI agents are trained to avoid risk.


    Read More

  • Agentic SEO for SaaS: Get Into the Agent Workflow

    Agentic SEO for SaaS: Get Into the Agent Workflow

    A SaaS buyer asks ChatGPT to recommend a project management tool. ChatGPT responds with three names. Yours isn’t one of them.

    Not because your product is worse. Because the agent couldn’t find enough consistent, authoritative signals to include you.

    That’s the Agentic SEO problem. And most SaaS teams don’t know they have it.

    AI Agents Don’t Search Like Humans. Your SEO Strategy Doesn’t Know That Yet.

    Traditional SEO optimizes for ranking on a results page. GEO (Generative Engine Optimization) optimizes for being cited in an AI-generated answer. Agentic SEO is the layer above both: getting your product into the workflow of an AI agent that’s executing a task on a buyer’s behalf.

    These aren’t interchangeable. They’re a stack. And most SaaS teams are still working on layer one.

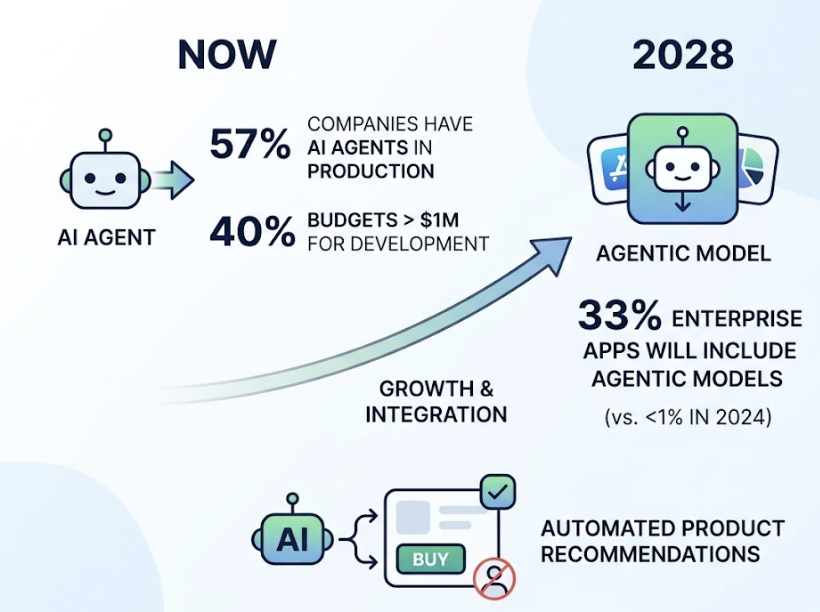
    As of 2026, 57% of companies already have AI agents in production, with 40% allocating budgets exceeding $1 million specifically for agentic AI development. Gartner projects that by 2028, 33% of enterprise applications will include agentic models, up from less than 1% in 2024. The agent isn’t coming. It’s already making product recommendations right now, often without a human in the loop.

    If your brand isn’t optimized for how agents discover and evaluate SaaS products, you’re not in the conversation.

    The Agentic SEO Gap Most SaaS Brands Haven’t Found Yet

    Most SaaS content is written for human readers.

    That’s increasingly a liability. When an AI agent evaluates which analytics platform, CRM, or security tool to recommend, it doesn’t read your homepage the way a prospect does. It parses signals across multiple sources, scores your brand’s authority and consistency, and synthesizes a recommendation in seconds.

    The sourcing logic varies by platform, and the differences are significant. Google Gemini draws 52.15% of its citations from brand-owned content, which means your structured, schema-optimized website carries real weight. ChatGPT relies more heavily on third-party consensus, with 48.73% of citations pulling from directories and review platforms like G2, Capterra, and Reddit. Perplexity favors niche experts and mid-tier industry publications.

    One product. Three platforms. Three completely different discovery paths.

    If you’re only optimizing one of them, you’re leaving most of your AI visibility on the table.

    How AI Agents Actually Decide What to Recommend

    Forget keyword ranking. Agents work through a four-stage reasoning cycle: perception, reasoning, action, and learning.

    In the perception phase, the agent gathers available signals about your product category. In the reasoning phase, it evaluates which brands have consistent, cross-platform presence. It then acts by surfacing the most credible options, and refines its outputs as it processes feedback from tool calls and user interactions.

    What this means practically: the agent isn’t looking for the product with the most features. It’s looking for the brand it can confidently recommend.

    That confidence is built through what researchers call the “Consensus Pattern”: AI models cross-reference claims across vendor sites, third-party editorial, review platforms, and community discussions before including a brand in a recommendation. If your homepage says one thing, G2 describes something slightly different, and Reddit users share a third experience, the agent’s confidence drops. Inconsistency is a visibility killer.

    Reddit, specifically, has become a high-trust signal for LLMs, accounting for over 40% of AI citations in some product categories. That’s not noise. That’s a distribution channel most SaaS marketing teams still don’t treat seriously enough.

    3 Signals That Determine Your Agentic SEO Visibility

    Signal 1: Source Authority

    Agents prioritize brands that appear consistently across the platforms they pull from. Pages with attribute-rich schema markup earn citation rates above 60%, while pages with missing or generic schema are often skipped entirely. That means your product listing, structured data, and third-party coverage on G2, Capterra, and relevant subreddits aren’t optional extras. They’re your agent-facing distribution layer.

    FAQPage schema alone increases citation rates by up to 2.7 times, because it directly maps to how LLMs answer questions. If you haven’t implemented it across your key product and category pages, that’s a gap worth closing today.

    Signal 2: Semantic Precision

    Can an agent accurately describe what your product does after reading your content?

    If your positioning relies on vague language like “powerful,” “intuitive,” or “next-generation,” an agent has nothing concrete to extract. Semantic precision means writing in direct, exact terms: “a pipeline analytics tool that tracks deal velocity by rep and segment” is machine-readable. “An innovative sales intelligence platform” is not.

    There’s also a freshness factor. AI-cited content is, on average, 25.7% fresher than traditional search results. RAG systems filter by recency. A product page or comparison article that hasn’t been updated in 18 months is being actively deprioritized across agentic workflows.

    Signal 3: Prompt-to-Brand Alignment

    This is the gap most SaaS teams don’t see until it’s pointed out.

    When a buyer asks an agent “what’s the best tool for tracking AI search visibility across platforms,” the agent retrieves content that maps to that exact question pattern. If your content covers the concept but uses different terminology, the alignment score drops, and your brand doesn’t surface.

    Discovering which prompts agents actually use in your product category, and making sure your content maps to them directly, is foundational Agentic SEO work.

    How to Build an Agentic SEO Strategy for Your SaaS Product

    Step 1: Audit your current AI visibility

    Before optimizing, you need to know where you stand. Build a set of 100-200 category-level prompts and run them across ChatGPT, Gemini, Perplexity, and other platforms. Track how often your brand appears. That’s your mention rate baseline.

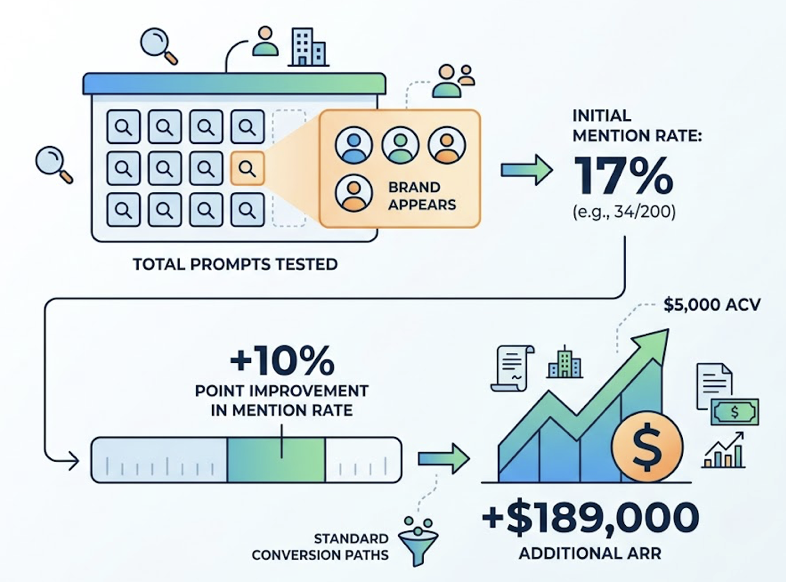
    To put it in concrete terms: if you test 200 prompts and your brand appears in 34 of them, you have a 17% mention rate. That number is your starting point. A 10-percentage-point improvement in mention rate, for a SaaS product with a $5,000 average contract value, can translate to roughly $189,000 in additional ARR, assuming standard referral-to-paid conversion paths.

    Step 2: Map the prompts agents use in your category

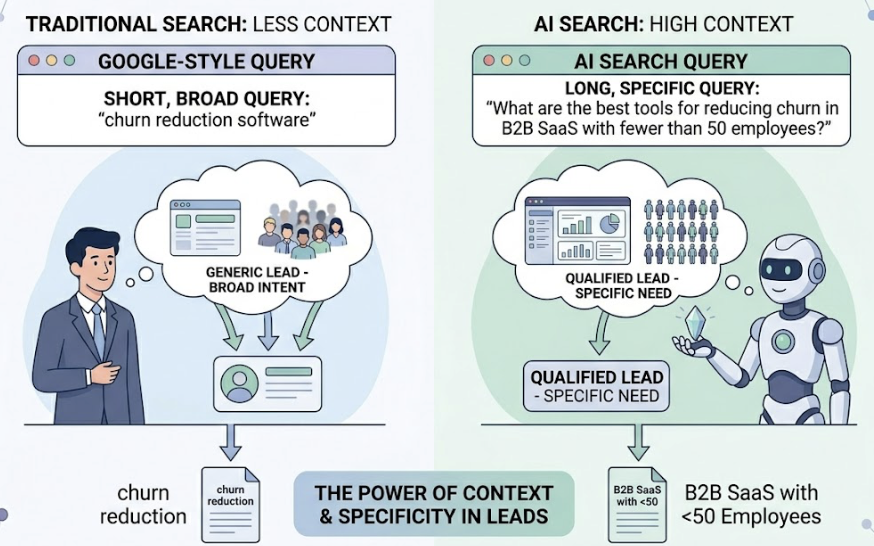
    These aren’t keyword searches. They’re conversational, task-framed, and often comparative: “which tool should I use to monitor my brand in AI responses” or “compare options for GEO tracking for a mid-size B2B team.” Your content needs to answer those questions, using that language, in a format agents can parse and cite.

    Step 3: Build distributed source coverage

    No single piece of content gives you visibility across all agents. You need consistent presence across the platforms each agent trusts: accurate G2 and Capterra listings, brand mentions in relevant subreddits, citations in industry publications, and schema-optimized pages on your own domain.

    For SaaS teams building this out, Topify provides the infrastructure to track exactly where you’re visible and where you’re not, across ChatGPT, Gemini, Perplexity, DeepSeek, and other major AI platforms. Its Source Analysis feature reverse-engineers which domains AI engines are actually citing in your product category, so you know where to invest instead of guessing.

    Topify’s Visibility Tracking maps your brand’s performance across seven metrics: visibility, sentiment, position, volume, mentions, intent, and CVR (Conversion Visibility Rate). CVR estimates the likelihood that an AI recommendation leads to actual brand engagement, which is increasingly the metric SaaS marketing teams need to justify Agentic SEO investment to leadership.

    Measuring Agentic SEO: What the Right Metrics Actually Look Like

    Traditional SEO KPIs won’t tell you whether an AI agent is recommending your product or silently leaving you off the shortlist.

    Mention Rate measures the percentage of relevant prompts that result in your brand being named. Share of Voice compares your mention volume to competitors’. Citation Rate tracks how often a mention includes a source link back to your content, and linked citations increase reappearance likelihood by 40%. Position tracks where in the response your brand appears: first mention, buried in a list, or absent entirely.

    Sentiment monitoring isn’t optional. Mentions with inaccurate or negative framing are often worse than no mention at all. If an AI model describes your product as discontinued, or mischaracterizes what it does, that incorrect signal can get reinforced across the agent ecosystem. It’s damage control infrastructure, not a nice-to-have.

    A practical tracking rhythm for most SaaS teams: review mention rate and position monthly, audit source coverage and schema quarterly, and run a full competitive Share of Voice analysis every six months.

    Conclusion

    Most SaaS brands are optimizing for page-one rankings while AI agents are making product recommendations with zero clicks involved.

    Agentic SEO isn’t a rebrand of GEO. It’s the optimization layer for autonomous AI workflows, the ones that run when a buyer says “help me find the right tool” and an agent goes off to figure it out. Those workflows have their own sourcing logic, their own trust signals, and their own citation patterns.

    You either show up in them or you don’t.

    The window to build early agent visibility is open right now. Most competitors haven’t started. That won’t be true in 12 months.

    If you want to see where your SaaS brand currently stands across AI agent workflows, Topify’s Visibility Tracking gives you the cross-platform data to find out, and the Source Analysis to act on it.

    FAQ

    What’s the difference between Agentic SEO, GEO, and traditional SEO?

    Traditional SEO optimizes for keyword rankings on search engine results pages. GEO optimizes for being cited in AI-generated answers. Agentic SEO goes a step further, optimizing for visibility in the workflows of autonomous AI agents completing tasks on a user’s behalf. Each layer builds on the previous one.

    Which AI platforms matter most for SaaS brand visibility?

    ChatGPT, Google Gemini, and Perplexity are the highest-priority platforms for most SaaS brands right now. Each has different sourcing preferences: Gemini favors brand-owned structured content, ChatGPT relies more on third-party directories and consensus, and Perplexity pulls from niche experts and mid-tier industry sources. Tracking all three gives you the complete picture.

    How long does it take to see Agentic SEO results?

    It depends on your starting point. AI RAG systems filter by content recency, which means fresh, well-structured content can gain visibility within weeks of publishing. Building source authority across third-party platforms takes longer, typically 2-4 months of consistent presence before citation patterns shift meaningfully.

    Do I need to change my entire content strategy?

    Not entirely, but significantly. The core shift is from writing for human readers only to writing for machine extractability as well. That means direct language, structured formatting, schema markup, and content organized around the exact question patterns AI agents use in your category.

    How do I know if my product is being recommended by AI agents?

    The most reliable method is systematic testing. Build a set of 100-200 category-level prompts and run them across major platforms, tracking where your brand appears and where it doesn’t. Topify automates this monitoring at scale, flagging visibility gaps and tracking mention rate, sentiment, and competitive position over time.

    Read More

  • AEO Visibility Metrics: What to Track and Why It Matters

    AEO Visibility Metrics: What to Track and Why It Matters

    You’ve been tracking keyword rankings for years. You know your position, your impressions, your CTR. But here’s what those numbers don’t tell you: whether ChatGPT mentioned your brand this week, what it said, and whether it recommended you first or last.

    That’s the measurement gap AEO creates. And it’s growing fast.

    Gartner projects that traditional search volume will drop 25% by 2026 as users shift to AI-generated answers. In environments where AI Overviews are active, zero-click searches already reach 83%. When an AI engine summarizes the answer for the user, there’s no SERP to rank on. There’s only the response.

    Three metrics have emerged as the AEO equivalent of rank, impressions, and CTR: Share of Voice, Position, and Sentiment. Each one measures something the others can’t. Miss any of them, and you’re making decisions on incomplete data.

    Why Your Current SEO Dashboard Misses AEO Visibility

    Traditional SEO operates on a simple assumption: surface a URL, earn a click. The metrics built around that assumption, such as organic sessions, keyword position, and domain authority, are designed to measure how well you compete for those clicks.

    AEO breaks that assumption entirely.

    Research shows that only 12% of ChatGPT citations overlap with Google’s top 10 organic results. A brand holding the #1 organic position for a query can be completely absent from the AI answer for the exact same query. The ranking signals that got you to page one don’t predict whether an LLM will include you in its response.

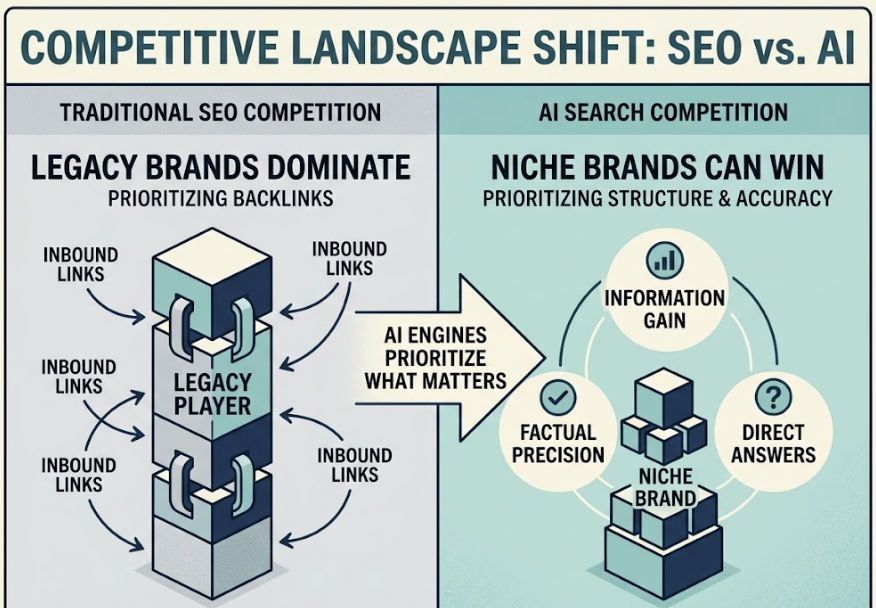
    The divergence goes deeper than just different platforms. AI engines don’t prioritize backlink profiles. They prioritize what researchers call “Information Gain,” factual precision, and whether your content answers the question directly. The result is a fundamentally different competitive landscape, one where a niche brand with structured, accurate content can outperform a legacy player with thousands of inbound links.

    That’s why measurement & monitoring for AEO requires its own metric framework.

    Share of Voice: Are You Even in the Conversation?

    AI Share of Voice (AI SoV) measures what percentage of AI-generated responses mention or recommend your brand, relative to all tracked competitors across a defined set of prompts.

    Unlike traditional SoV, which counts media spend or ad impressions, AI SoV is built on prompt-based analysis. You define a “Master Prompt List” of 50-100 queries that reflect how your target audience actually searches using AI. Discovery questions, comparison queries, and purchase-intent prompts all belong in that list. For each prompt, you track whether your brand appears, and divide your total mentions by the combined mentions of all tracked brands.

    The baseline formula is clean:

    AI SoV = (Your Brand Mentions / Total Mentions Across All Tracked Brands) × 100

    But raw mention rate only tells you part of the story. A more useful variant is Prompt Coverage Rate, which measures the percentage of total prompts where your brand appears at all:

    Prompt Coverage Rate = (Prompts Including Your Brand / Total Prompts Tested) × 100

    This metric surfaces “blind spots,” entire query clusters where your brand is completely invisible. If your Prompt Coverage Rate is 60%, you’re absent from 40% of the conversations your potential customers are having with AI.

    Prompt Set Design Determines What SoV Actually Measures

    The prompts you choose define the market you’re measuring. A set built entirely on awareness-stage questions will show different SoV than one built on “best [category] for [use case]” queries.

    In practice, you want prompts across three intent layers: discovery (“what is [category]”), evaluation (“what’s the best [product type]”), and comparison (“[your brand] vs [competitor]”). Each layer reveals a different dimension of your AI presence. A brand that dominates awareness queries but disappears at the comparison stage has a different problem than one that’s invisible at the top of the funnel but shows up at the point of decision.

    Position: Mentioned Isn’t the Same as Recommended

    Being in the conversation is the floor. Being the first name the AI says is the ceiling. The gap between those two points determines how much commercial value your AI visibility actually generates.

    Research on LLM behavior confirms a consistent primacy bias: items mentioned first in a response are more likely to be selected or remembered by the user. More directly, studies show that positively framed LLM summaries increase purchase likelihood by 32% compared to the original review text. When the AI introduces your brand as a “widely recommended option” in the opening line, that framing follows the reader into their evaluation process.

    The Citation Placement Index (CPI) formalizes what this means for measurement & monitoring:

    Mention DepthScoreStrategic Meaning
    Primary Recommendation10The AI treats your brand as the default choice
    Top 3 Placement7You’re in the consideration set
    Lower List Placement4Recognized, not prioritized
    Passing Mention2You exist, but lack topical authority

    A brand averaging 4.2 on this scale has a meaningfully different market position than one averaging 8.1, even if both appear in 65% of responses.

    First Mention vs. Top Recommendation: A Real Distinction

    Here’s a scenario worth sitting with. Brand A appears in 70% of AI responses but 80% of those mentions come after a competitor is introduced. Brand B appears in only 45% of responses but holds the first-mention position in 75% of those cases.

    Brand B’s Position score is stronger. And depending on the query intent, Brand B is likely generating more qualified consideration from that smaller slice of visibility.

    That’s the core insight: Position-Weighted SoV, where each appearance is scored by where in the response it occurs, is a more reliable predictor of downstream conversion than raw mention rate. Standard measurement & monitoring setups that only track presence miss this entirely.

    Sentiment: What AI Actually Says About Your Brand

    High Share of Voice with weak Sentiment is worse than low visibility. If an AI engine consistently describes your product as “a budget option with known reliability issues,” every mention is doing negative work.

    AI Brand Sentiment tracks the qualitative framing of how your brand is characterized in AI responses. It’s distinct from social listening, which tracks human-generated opinion. AI sentiment reflects the “view” the model has constructed from its training data, which includes reviews, forum posts, news coverage, structured data on your site, and third-party citations.

    That characterization typically falls into five categories:

    Endorsement: The AI actively recommends the brand. “Widely recommended,” “top choice for.” High entity authority required.

    Neutral Mention: Factual description without comparative framing. You’re known, not differentiated.

    Cautious Mention: Inclusion with hedging. “Worth considering, but…” Often caused by conflicting data in the training corpus.

    Negative Mention: Unfavorable framing or warnings. Requires active remediation of source content.

    Hallucination: Incorrect facts, fabricated features, wrong pricing. Highest reputational risk because users treat AI output as objective.

    The Net Sentiment Score (NSS) converts these qualitative signals into a trackable number:

    NSS = [(Endorsements + Neutrals) – (Negatives + Hallucinations)] / Total Mentions × 100

    An NSS above +60 indicates strong competitive positioning. Below -20 means your digital footprint is actively working against your sales process.

    Sentiment Drifts. That’s the Part Most Teams Miss.

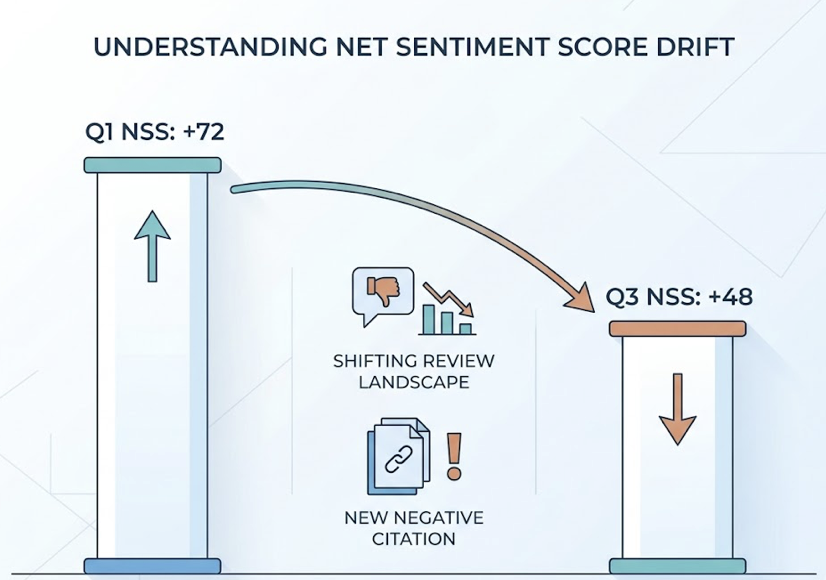
    AI models don’t form a fixed opinion and hold it. Citation Drift, the rate at which the sources AI platforms cite for the same prompt change over time, currently runs between 40% and 60% per month. That means the content shaping your Sentiment Score is rotating at a high rate.

    A brand that earns an NSS of +72 in Q1 can drift to +48 by Q3 without any intentional action, simply because the review landscape shifted or a new piece of negative content got picked up as a citation source.

    This is why Sentiment can’t be a quarterly audit. It requires ongoing monitoring as part of your measurement & monitoring stack, not a one-time health check.

    Reading All Three Together: The AEO Diagnostic Framework

    Each metric isolates one dimension of AI visibility. The real diagnostic power comes from how they interact.

    A brand with high SoV, low Position, and neutral Sentiment is visible but not preferred. The fix isn’t content volume; it’s building the kind of cross-domain consensus (consistent mentions across authoritative sources, Wikipedia, major publications, niche industry blogs) that signals to the model which brand to surface first.

    A brand with high Position and Endorsement-level Sentiment but low SoV is a niche authority. It’s winning specific query clusters hard, but hasn’t expanded its prompt coverage to adjacent topics where buyers are also searching.

    ScenarioSoVPositionSentimentDiagnosisNext Move
    Visible But Not TrustedHighLowNegativeHigh exposure, poor framingRemediate source content driving negative signal
    Category LeaderHighHighPositiveStrong across all dimensionsExpand into adjacent topic clusters
    Reputation CrisisHighMidNegativeMentions are doing damageIdentify and correct citation sources
    Niche AuthorityLowHighPositiveWinning specific clustersIncrease Brand Signal Density via PR
    New EntrantLowLowNeutralStarting positionBuild entity authority through structured data and FAQs

    The diagnostic matrix lets you skip the generic “improve AI visibility” advice and go directly to the specific lever that changes your situation.

    How to Start Tracking Without Building from Scratch

    Most teams don’t need a six-figure enterprise setup to get started. The implementation follows a natural progression from manual audit to automated monitoring.

    Days 0-30: Manual baseline. Query a set of 25-50 prompts weekly across ChatGPT, Gemini, and Perplexity. For each response, record whether your brand appears (SoV), where it appears (Position), and what the framing says (Sentiment). This establishes your baseline before you optimize anything.

    Days 31-60: Technical signals. Deploy schema markup using Product, Organization, FAQ, and Author schema. Restructure key content pages so the direct answer appears in the first 150 words. Research shows this answer-first formatting increases citation rates by 40%.

    Days 61-90: Automated monitoring. Manual tracking at 25 prompts is manageable. At 100+ prompts across five AI platforms, it breaks down fast.

    Topify tracks all three AEO visibility metrics, Share of Voice, Position, and Sentiment, in a single dashboard, across ChatGPT, Gemini, Perplexity, DeepSeek, and other major platforms. The Basic plan ($99/mo) covers 100 prompts and 9,000 AI answer analyses per month across 4 projects. The Pro plan ($199/mo) expands to 250 prompts and 22,500 analyses for teams managing multiple brands or competitive categories.

    The measurement value isn’t just in the data. It’s in the speed of detection. When Citation Drift is running at 40-60% monthly, a team doing manual audits every two weeks is always looking at stale data. Automated monitoring catches Sentiment shifts and Position changes in near-real time, which is when they’re still correctable.

    Conclusion

    The three AEO visibility metrics each solve a different blind spot. Share of Voice tells you whether you’re in the conversation at all. Position tells you where you land when you are. Sentiment tells you what the AI says about you when it gets there.

    None of them are sufficient on their own. A brand can have strong SoV but weak Position and lose the recommendation to a less visible competitor. A brand can hold first-mention Position but carry negative Sentiment that cancels out the advantage. The diagnostic value only appears when you read all three together.

    AI referral traffic currently accounts for roughly 1% of total web visits. But it converts at 4.4x to 23x the rate of traditional organic traffic, because users arrive having already been “recommended” by the model. That conversion premium is the business case for taking measurement & monitoring seriously, and for building the baseline now before the channel grows more competitive.

    Start with 25 prompts. Track all three dimensions. Then build from there.


    FAQ

    How often should I check AEO visibility metrics? 

    Weekly is the practical minimum given Citation Drift rates of 40-60% per month. For brands in fast-moving categories or those actively running remediation campaigns, bi-weekly monitoring gives you faster feedback loops.

    Can I track AEO metrics without a paid tool? 

    Yes, at small scale. A manual audit of 25-50 prompts across two or three AI platforms is viable for establishing a baseline. The limitation is volume and frequency: manual tracking doesn’t scale past ~50 prompts without significant time cost, and it can’t catch rapid Sentiment shifts between audit cycles.

    What’s a realistic Share of Voice benchmark for AEO? 

    Benchmarks vary significantly by industry. Healthcare and Financial Services see AI Overviews in nearly half of queries, making those categories highly competitive for AI SoV. Less transactional categories like Real Estate see much lower AI answer rates. In most B2B categories, a Prompt Coverage Rate above 40% with consistent top-3 Position represents a strong starting position.


    Read More

  • GEO vs AEO vs SEO: How to Measure Each in 2026

    GEO vs AEO vs SEO: How to Measure Each in 2026

    Your keyword rankings are holding steady. Organic traffic is down for the third quarter in a row. And the most common explanation you’ve heard is “AI Overviews.” The problem is, that’s only part of the picture. Google’s AI snippets are one thing. ChatGPT recommending a competitor instead of you is something else entirely. These are two separate measurement problems, and most teams are still treating them as one.

    Three channels. Three different scorecards. Here’s how they actually work.

    Three Disciplines, Three Different Scorecards

    Search has moved through three distinct phases: keyword matching, featured snippet extraction, and now synthetic AI recommendation. In 2026, each phase has its own measurement logic, and they don’t overlap as much as marketers assume.

    SEO answers the question: where do I rank? Its domain is Google and Bing, and its metrics are positions, organic traffic, and backlink authority. It’s the most mature measurement system of the three.

    AEO asks: am I being extracted? It focuses on whether Google AI Overviews or Bing Copilot pulls your content into a generated answer block, regardless of where your page ranks. You could be #4 and still get cited in an AI Overview. You could be #1 and get ignored.

    GEO asks a different question entirely: does AI recommend me? Its targets are ChatGPT, Perplexity, Gemini, and DeepSeek. These platforms don’t index your page the way Google does. There’s no SERP. There’s no rank. There’s only whether the model includes you in a synthesized response, in what context, and ahead of or behind your competitors.

    DimensionSEOAEOGEO
    Target PlatformGoogle, BingGoogle AIO, Voice AssistantsChatGPT, Perplexity, DeepSeek
    Core QuestionWhere do I rank?Am I being cited?Does AI recommend me?
    Key MetricsRank, Organic TrafficSnippet rate, AIO trigger rateVisibility Rate, Mention Rate, Sentiment
    Primary ToolsAhrefs, SEMrushSearch Console, SERP monitorsTopify

    These three don’t replace each other. But they measure fundamentally different things, and conflating them is how brands end up with reporting gaps they can’t explain.

    What SEO Measurement Actually Looks Like

    SEO tracking is well understood: keyword rankings, organic traffic, CTR, domain authority, and backlink growth. Most teams have this covered.

    What’s less understood is the ceiling SEO measurement has hit. Over 60% of Google searches now end without a click. When an AI Overview appears in the SERP, the #1 organic result sees its CTR drop from roughly 10.67% to below 7%. In some informational queries, the drop exceeds 60%.

    The impact is uneven across categories. Consumer electronics brands saw organic click share fall from 23% to 11% year-over-year. Online gaming dropped from 88% to 75%. Retail apparel, which still drives comparison and transactional searches, barely moved. The pattern is consistent: the more informational the query, the worse the click erosion.

    That said, SEO still matters. It’s the technical foundation that determines whether AI systems can crawl and understand your content in the first place. You don’t abandon it. You just stop expecting it to tell you the full story.

    AEO: Tracking the Answers AI Overviews Steal from You

    AEO measurement centers on Google AI Overviews and Bing Copilot. The question isn’t your page position. It’s whether AI selects your content as a source.

    Google now deploys AI-generated answers in 20% to 50% of searches, rising to over 60% in information-dense categories like health and science. Being included in those answers carries brand value even without a direct click, since only about 1% of users actually click the source links inside AIO results.

    The core AEO metrics to track:

    • AIO trigger rate: How often does your target query surface an AI Overview at all?
    • AIO citation overlap: How frequently does your content get pulled into those answers? Research puts this rate between 14% and 38% for pages that already rank in the traditional top 10.
    • Featured snippet hold rate: Are you maintaining your answer position as AI rewrites the SERP?
    • Structured data validation rate: Can AI crawlers parse your entities cleanly? A target above 80% is the benchmark.

    AEO success is better understood as brand asset accumulation than traffic generation. A citation in an AI Overview often leads to downstream branded search growth, even when the user never clicks through. You’re building recognition inside a zero-click environment.

    GEO Measurement Is a Different Animal Entirely

    GEO doesn’t map to any existing analytics framework. ChatGPT, Perplexity, Gemini, and DeepSeek don’t expose public APIs for rank tracking. Their answers are probabilistic, not deterministic. Ask the same question twice and you may get different results.

    That’s why GEO tracking requires what researchers call synthetic probing: running large volumes of carefully designed prompts across AI platforms, then analyzing the output to calculate how often your brand appears, in what position, and with what sentiment. This can’t be done manually at any meaningful scale.

    DeepSeek alone now draws close to 300 million monthly visits, with daily active users exceeding 22 million. Its user base skews young, with 40% in the 18-24 age bracket. If your brand isn’t in GEO monitoring across DeepSeek alongside ChatGPT and Gemini, you’re operating with blind spots in a fast-growing segment of AI traffic.

    Topify uses a seven-dimensional framework to make GEO results reportable:

    • Visibility: What percentage of relevant AI responses mention your brand? If you appear in 30 out of 100 probed prompts, your Visibility Rate is 30%.
    • Sentiment: How does AI describe your brand? High visibility paired with phrases like “expensive and difficult to set up” is a visibility problem with a sentiment coat of paint on top.
    • Position: Where do you appear in an AI recommendation list relative to competitors? First position in an AI recommendation carries the same strategic weight as a #1 Google ranking.
    • Volume: How many prompt analyses back the data? GEO results are probabilistic, so statistical confidence requires thousands of samples, not dozens.
    • Mentions: Total brand references across responses, including text-only mentions without linked citations.
    • Intent: Are you being recommended at the right funnel stage? Appearing in “what is” queries when your goal is “best option for” queries is a misalignment.
    • CVR (Conversion Visibility Rate): What’s the predicted downstream impact of your AI citations on traffic or leads?

    This framework is now standard in CMO reporting at brands that take GEO seriously. It’s not a nice-to-have dashboard. It’s the only structured way to treat AI recommendation as a measurable channel.

    Why Your Current Reporting Mix Doesn’t Add Up

    The most common setup in 2026: a detailed SEO dashboard showing keyword rankings trending up, paired with a few screenshots of manual ChatGPT searches someone ran last quarter.

    That’s not a measurement system. It’s a gap with a thin layer of data on top.

    User behavior is now distributed across three distinct discovery channels: traditional search still accounts for roughly 40-50% of search activity, AI answer layers (AEO) capture 25-35%, and generative AI platforms (GEO) handle 20-30%. If your reporting only covers SEO, you’re measuring less than half the market.

    You can’t optimize what you don’t measure.

    The practical consequence is that brands with solid SEO scores are losing recommendation share to competitors who’ve been building GEO authority quietly. By the time it shows up in revenue data, the gap is already six to twelve months wide.

    A Unified Tracking Framework for SEO, AEO, and GEO

    The goal isn’t to run three separate reporting systems. It’s to build one framework with three layers, each feeding into the next.

    Layer 1: SEO Foundation

    Use Ahrefs or SEMrush for weekly rank tracking and traffic reporting. In 2026, the priority shift here is toward transactional keywords, the queries that still drive clicks despite AI interference. Informational head terms are increasingly AEO and GEO territory.

    Core metrics: target keyword rankings, organic traffic by intent segment, domain authority trends, and conversion rates from organic.

    Layer 2: AEO Synthesis

    Combine Google Search Console data with a third-party SERP monitor to track AI Overview trigger rates across your target query set. Tools like Authoritas can map AIO coverage at scale.

    Core metrics: AIO trigger rate per query cluster, featured snippet hold rate, People Also Ask coverage, structured data health score.

    Layer 3: GEO Influence

    This is where Topify fills a gap that no traditional SEO tool can. Topify runs prompt matrix analysis simultaneously across ChatGPT, Perplexity, Gemini, and DeepSeek, returning real-time competitive comparisons across all seven GEO dimensions.

    The practical setup: establish a 30-day baseline using 200 or more core prompts mapped to your product category. Track brand position relative to two or three key competitors. Topify’s Basic plan supports 100 prompts per cycle at $99/month; the Pro plan covers 250 at $199/month, which is closer to the minimum for statistically reliable GEO reporting in competitive categories.

    These three layers compound. SEO health determines whether AI crawlers can access and parse your content. AEO structure improves the probability that AI selects your content as a source. GEO authority, built through high-quality citations, industry publications, and entity recognition, determines whether a large language model treats your brand as a trusted recommendation. Each layer reinforces the next.

    Conclusion

    SEO, AEO, and GEO aren’t competing priorities. They’re sequential layers of a single visibility stack.

    SEO answers whether you exist in the digital record. AEO answers whether you get extracted from it. GEO answers whether AI recommends you over everyone else.

    The biggest risk in 2026 isn’t choosing the wrong tool. It’s tracking only one layer and assuming you have the full picture. A brand with strong SEO but no GEO monitoring is flying with two instruments covered. They’ll be the last to know that a competitor has been the first recommendation in ChatGPT for the past six months.

    Start with the three-layer framework. Fill in Layer 3 with a dedicated GEO monitoring tool. Then run a 30-day baseline before drawing any conclusions. The data will do the rest.

    FAQ

    What’s the difference between AEO and GEO?

    AEO targets Google’s AI Overviews and Bing Copilot, both of which operate within a traditional search engine’s retrieval system. GEO targets standalone LLM platforms like ChatGPT and Perplexity, where answers are generated from model weights and retrieval-augmented sources rather than a standard index. Different systems, different optimization strategies, different metrics.

    Can I use SEO tools to track GEO performance?

    No. SEO tools work by scraping static HTML from search engine results pages. GEO responses are generated probabilistically in real time and vary by prompt, context, and platform. Tracking GEO requires synthetic probing across AI platforms at scale, which tools like Topify are built specifically to do.

    How do I know if my brand appears in ChatGPT answers?

    The most reliable method is using an AI visibility monitoring platform. Topify runs thousands of industry-relevant prompts on your behalf and scans the generated outputs for brand mentions, citation links, and description tone. Manual searches give you anecdotal data. Systematic prompt matrix analysis gives you a statistically valid Visibility Rate.

    What GEO metrics should I report to my CMO?

    Prioritize three: Visibility Rate (how often you appear in relevant AI responses), Sentiment Score (how AI describes your brand), and Competitive Share of Voice (your recommended position relative to competitors). These three give executives a clear picture of AI market standing without requiring them to understand the technical methodology.

    How often should I run GEO measurement?

    A weekly light pass combined with a monthly deep audit is the standard cadence. In competitive verticals, real-time monitoring is worth the investment, particularly when AI models update their citation behavior or start surfacing inaccurate brand descriptions that need content-level correction.

    Read More

  • AI Overview Tracking: What Your SEO Tool Misses

    AI Overview Tracking: What Your SEO Tool Misses

    Your brand holds the #1 ranking. Your rank tracker shows green. But your organic traffic is down 40%.

    That’s the gap most SEO teams don’t see coming. It’s called “The Great Decoupling”: the moment when cardinal position and actual visibility stopped moving together. AI Overviews triggered it. And most tracking tools still haven’t caught up.

    Your Rank Tracker Is Lying to You

    Traditional rank trackers do one thing: they check where your URL sits in a list of blue links. That methodology worked for 20 years. It doesn’t anymore.

    When an AI Overview appears, it occupies more than 75% of the initial screen on mobile and exceeds 1,200 pixels on desktop. The result? Your #1 organic result gets pushed below the fold before a user ever scrolls.

    The CTR data confirms it. For informational searches with an AI Overview, organic click-through rate has dropped 61%, from a pre-rollout average of 1.76% down to 0.61%. For brands holding positions 2 or 3, the situation is worse: those placements are now effectively zero-value assets for any informational query.

    Here’s the uncomfortable truth: rank and visibility are no longer the same thing.

    A brand can sit at #8 organically and still be the primary cited source in an AI Overview, generating 35% more clicks than a non-cited competitor holding #1. A brand can hold #1 and be completely absent from the AI summary, absorbing the full weight of the traffic collapse.

    Cardinal position has become a table-stakes metric. It matters, but it no longer defines whether users actually encounter your brand.

    What “Ranking” Even Means in AI Overviews

    AI Overviews don’t have a position 1, 2, or 3. There’s no ranked list of URLs. The system generates a synthesized narrative, and your brand either appears in it or it doesn’t.

    This is a fundamentally different success model. The underlying mechanism is Retrieval-Augmented Generation (RAG): Google expands a single query into dozens of sub-queries, pulls fragments from authoritative sources, and synthesizes a final answer. More than 60% of AI Overview citations come from URLs that rank outside the top 20 of traditional search results. A page at position #40 for a specific sub-query can end up providing the primary evidence for an AI summary on a related head term.

    That breaks every assumption traditional rank tracking is built on.

    Measuring performance in this environment requires a different set of metrics. The most useful framework tracks seven dimensions: Visibility Rate (the share of relevant prompts where your brand appears), Brand Mentions (raw frequency in AI-generated text), Position Index (where in the response your brand is mentioned), Sentiment Quotient (how the AI characterizes you, on a 0-100 scale), AI Search Volume (prompt frequency within AI interfaces), Intent Alignment (whether you appear at the right buyer journey stage), and Conversion Visibility Rate (CVR), which connects AI mentions to actual revenue.

    Of those seven, the three that matter most for day-to-day monitoring are Visibility Rate, Sentiment, and Position Index. Together, they answer the question your rank tracker can’t: are you actually in the conversation?

    The 3 Signals That Actually Tell You Where You Stand

    Move beyond cardinal position. These are the three signals that determine generative performance.

    Signal 1: Trigger Rate

    Trigger rate is the percentage of your target prompts where an AI Overview appears at all. Between early 2024 and mid-2025, overall AI Overview prevalence jumped from 6.49% to more than 50% of all search results. But the distribution is uneven by intent: informational and educational queries trigger AI Overviews 80-88% of the time. Transactional queries still trigger at only 1-13%.

    Monitoring trigger rate tells you which segments of your prompt library are most exposed to zero-click displacement. If 85% of your TOFU keywords now trigger AI Overviews, your content strategy needs to shift from “ranking for clicks” to “engineering for citations.”

    Signal 2: Inclusion Rate

    Inclusion rate measures how often your brand appears in the AI summaries that do trigger. This is the new position #1.

    Because LLMs are probabilistic, a single manual check is a snapshot, not a signal. You need to run dozens of prompt variations to calculate a reliable inclusion probability. If a competitor’s inclusion rate is rising while yours is flat, you’re losing Entity Salience, which is the model’s confidence in your brand as a leading solution for that topic.

    Signal 3: Source Attribution

    Source attribution identifies which specific domains and URLs AI Overviews pull from when building responses about your category. Analysis of 46 million citations shows that a small group of “aristocratic” domains (Wikipedia, YouTube, Reddit, and Google’s own properties) account for roughly 43% of all AI citations.

    That’s the signal that tells you where to invest. If AI Overviews for your category are citing G2 reviews and Reddit threads instead of your owned content, you don’t have a content problem. You have an authority distribution problem. Topify’s Source Analysis tracks the exact domains and URLs that AI Retrievers ingest for a given prompt, across both your brand and your competitors.

    Step-by-Step: Building a Monitoring Workflow

    Here’s how to build a monitoring system that actually reflects generative performance.

    Step 1: Build a Prompt Matrix

    Replace keyword lists with a prompt matrix: a library of 25 to 100 context-rich, conversational queries that simulate real buyer journeys. A keyword like “email marketing” tells you little. A prompt like “which email marketing tool is best for a 50-person SaaS team with a $500 budget?” reflects how buyers actually use AI.

    Over 80% of AI prompts are phrased differently than Google searches on the same topic. Your tracking input needs to match the actual input, not a legacy keyword format.

    Step 2: Run a Baseline Audit

    With your prompt matrix in place, run an initial audit across ChatGPT, Gemini, Perplexity, and AI Overviews. Record your Visibility Rate, Position Index, and Sentiment scores for each prompt. Include the top 3-5 competitors. The output is a “Visibility Gap” map: every query where a competitor is recommended and you’re not.

    Step 3: Identify Source Gaps

    For every gap, analyze what the AI is citing. Is a competitor dominating because they have a more comprehensive pricing table? A data-rich case study? A Reddit thread with high engagement? The answer dictates whether your response is a content update, a PR play, or a structured data implementation.

    Step 4: Act and Re-Audit on a Weekly Cadence

    AI citations are not stable. Cited sources churn at 40-60% monthly, and 70% of AI Overviews shift their primary narrative within a 90-day window. A monthly review cycle isn’t enough. You need to be watching for shifts on a weekly basis so you can respond before a competitor’s rising inclusion rate compounds into a structural visibility gap.

    Manually auditing 500 prompts across four platforms takes hundreds of labor hours per month. Topify automates the entire pipeline, running audits in minutes with an error rate below 1%, while surfacing new high-value prompts as AI recommendations evolve.

    The Tools That Can (and Can’t) Track AI Overviews

    Not all monitoring tools operate at the same layer of the stack.

    Legacy platforms like Ahrefs and Semrush remain strong for foundational SEO work: backlinks, technical audits, and cardinal rank. Their AI Overview coverage typically goes as far as trigger rate detection. You can see that an AI Overview appeared for a keyword. You can’t see whether your brand was in it, how it was characterized, or how you stack up against competitors inside the summary.

    Specialized platforms are built specifically for the synthesis layer. They probe AI responses statistically, track brand presence across multiple LLMs simultaneously, and reverse-engineer citation trails.

    PlatformCore AdvantagePlatform CoverageStarting Price
    Topify7-Metric Analytics + One-Click ExecutionChatGPT, Gemini, Perplexity, AIO$99/mo
    ProfoundEnterprise Intelligence & SKU Tracking10+ Engines (Claude, Grok, etc.)$499/mo
    QuattrGEO-SEO Bridge + Content OpsChatGPT, Perplexity, AIOCustom
    AhrefsBacklinks & Brand RadarChatGPT, Perplexity, Gemini, AIO$129/mo
    Otterly.aiLight Visibility & Prompt Discovery6 Platforms (incl. Copilot)$29/mo

    For teams that need to act on data, not just collect it, the key differentiator is whether the platform includes an execution layer. Topify’s Action Center connects monitoring insights to one-click content deployment, closing the loop between what the AI says and what your team does about it.

    Measurement & Monitoring Mistakes That Skew Your Data

    Getting the tracking set up is one thing. Getting it right is another.

    Tracking short-tail keywords instead of prompts. Monitoring “CRM software” produces generic, concept-level AI answers that rarely mention specific brands. You need context-rich, long-tail prompts that match real buyer intent to get inclusion data that’s actually actionable.

    Using rank as a traffic proxy. Stable organic rankings can mask a 40-60% traffic collapse caused by AI Overview displacement. If you’re only monitoring rank, you’ll be the last to know your pipeline is drying up.

    Tracking only one platform. Research shows only a 13.7% citation overlap between different AI search surfaces. What you see in ChatGPT tells you almost nothing about your visibility in Google AI Overviews or Perplexity. Brands that monitor a single engine are operating with a massive blind spot.

    Siloing AI visibility from your existing reports. AI visibility isn’t a replacement for organic search metrics. It’s a parallel channel. Without connecting citation frequency to branded search lift and assisted conversions, you can’t prove ROI, and you can’t defend the investment to stakeholders.

    Counting mentions, ignoring sentiment. If an AI characterizes your enterprise platform as a “budget option” or a “basic tool,” raw mention counts are irrelevant. The AI is filtering out your best prospects before they ever click. Sentiment tracking is not optional.

    That last one shows up in more than half of the AI visibility reports we’ve reviewed.

    What to Do With the Data Once You Have It

    Data without a decision framework is just storage cost.

    When your inclusion rate is low on specific prompts, start by analyzing what the AI is citing for those queries. AI systems don’t “read” content the way humans do. They extract facts and semantic relationships from fragment-level patterns. The fix is usually structural: restructure high-value pages into “Information Islands,” sections that lead with a clear, factual answer in the first 2-4 sentences, with structured data markup and a fact-dense HTML structure. Avoid client-side JavaScript rendering on any page you want AI crawlers to reach.

    When source attribution shows that AI Overviews in your category prefer third-party sources over your owned content, the priority isn’t more blog posts. It’s earned media. One press mention generating 15 unlinked brand references on an authoritative domain may drive more AI visibility than 15 high-DA backlinks. Target the aristocratic domains: Reddit threads, YouTube reviews, G2 listings, and industry publications.

    When it’s time to report up the chain, stop using rank screenshots. Use “AI Answer Inclusion Rate” and “Share of Model Presence” instead. These metrics reflect your brand’s actual role in the information ecosystem that drives discovery. And when you need the business case for continued investment in GEO, the “Citation Paradox” is your anchor: brands cited in AI Overviews recover roughly 35% of the traffic other brands lose to zero-click displacement. That’s the delta between a brand that’s invisible to AI and one that’s part of the answer.

    Conclusion

    Cardinal rank is not disappearing, but it’s no longer the scoreboard. In 2026, the brands that win search are the ones that show up in the answer, not just below it. That requires a different measurement system, a different prompt strategy, and a different relationship between your tracking data and your content decisions.

    The monitoring shift isn’t complex. It’s a matter of replacing a single metric (rank) with a more accurate one (inclusion rate), and making sure your tools can actually see what’s happening inside AI-generated responses.

    The traffic is still out there. It’s just flowing through a different layer.

    FAQ

    Do I need a separate tool to track AI Overviews?

    General-purpose SEO tools can identify which keywords trigger an AI Overview, but they lack the statistical multi-model probing needed to measure actual brand inclusion, sentiment, and competitive position inside the summary. For benchmarking and execution, a specialized visibility platform is necessary.

    How often does AI Overview content change?

    Frequently. Cited sources rotate at 40-60% monthly, and 70% of AI Overviews shift their primary narrative within a 90-day window. Weekly monitoring is the minimum cadence to catch shifts before they compound into sustained visibility loss.

    Can I track AI Overview performance for multiple competitors at once?

    Yes. Platforms with parallel competitor tracking surface “Share of Model” data, showing which brands are preferred by specific LLMs and which third-party domains are fueling their authority. Topify’s Competitor Monitoring tracks position, sentiment, and citation sources across your full competitor set simultaneously.

    What’s the difference between SGE and AI Overviews?

    Search Generative Experience (SGE) was Google’s experimental phase for generative search features. AI Overviews is the production version, powered by the Gemini 3 model architecture since early 2026, and now active across the majority of search results.

    How do I know if my content is being cited in AI Overviews?

    URL-level source analysis in specialized tools tracks every domain and page that Google’s AI Retrievers pull for a given prompt. Topify’s Source Analysis distinguishes between your owned site, competitor pages, and third-party authority sources, so you can see exactly where the gap is.

    Read More

  • Are AI Engines Citing You? Here’s How to Find Out

    Are AI Engines Citing You? Here’s How to Find Out

    The first thing most brands do when they hear about AI citation monitoring is Google themselves on ChatGPT. They type in their brand name, see it appear, and assume everything’s fine.

    That’s the wrong test. The right question isn’t “does AI know I exist?” It’s “when a potential customer asks ChatGPT to recommend a solution in my category, does my brand show up?” Those are very different prompts. And for most brands, the second one returns a list of competitors.

    Here’s how to build a measurement and monitoring system that answers the right question, across the platforms that actually matter.


    Your Google Rankings Don’t Tell You What AI Is Saying

    Most teams assume strong SEO performance carries over into AI search. The data says otherwise.

    An analysis of 1.9 million AI citations found that only 12% of AI-cited content also appears in Google’s top 10 results. More striking: roughly 80% of AI citations come from pages that don’t rank on Google’s first page at all.

    That’s not a minor gap. That’s a completely separate system operating by different rules.

    The decoupling goes deeper when you factor in zero-click behavior. When Google AI Overviews appear at the top of a results page, the click-through rate for the #1 organic result drops by 58%. In high-traffic informational queries, that number reaches 64%.

    So brands are simultaneously losing traffic to AI summaries and being excluded from those summaries. Measurement and monitoring only begins to matter once you accept that these two systems require separate tracking.


    Citations vs. Mentions: What You’re Actually Tracking

    Before setting up any monitoring workflow, it’s worth being precise about what you’re measuring. The two metrics serve different purposes and diagnose different problems.

    Citations are when an AI engine explicitly attributes information to your website, usually through a footnote, source link, or sidebar card. They’re the only mechanism that drives actual referral traffic from AI. When AI systems decide whether to cite a source, they assess “hallucination risk”: content with structured technical details, original research data, or expert testimony gets treated as a “source of truth” and cited more often.

    Mentions are when an AI says your brand name in the generated text without necessarily linking to you. A mention signals that your brand has strong entity association in the model’s knowledge base. If AI answers “What’s the best CRM for enterprise?” with your brand name unprompted, that means you’ve built real category authority in the training data or retrieval pool, even without a citation link.

    Both matter. Citations drive traffic. Mentions build category positioning. A brand that gets mentioned but not cited is building awareness without capturing revenue. A brand that gets cited but rarely mentioned may be winning tactical queries while losing category-level authority.


    Step 1: Build a Prompt Matrix Before You Run a Single Query

    Most monitoring setups fail because they start with the wrong inputs. Running queries using your brand name as the prompt tells you almost nothing useful.

    What you actually need is a Prompt Matrix: a structured library of the questions your target customers are asking AI before they’ve even thought of your brand.

    AI search queries average 23 words in length, compared to Google’s 4. That length carries context. Someone asking “What are the best tools for reducing churn in B2B SaaS with fewer than 50 employees?” is a very different lead from someone who types “churn reduction software.” Your prompt library needs to reflect that specificity.

    Build prompts across three stages of the customer journey:

    • Problem Unaware: “Why is our customer retention rate dropping even after product improvements?”
    • Problem Aware: “How do enterprise SaaS companies usually reduce involuntary churn?”
    • Solution Aware: “What’s the difference between [Your Brand] and [Competitor] for enterprise churn prevention?”

    Industry benchmarks suggest a minimum of 20-30 core prompts per category for baseline monitoring. For larger brands managing multiple product lines or markets, that number typically runs between 100 and 300, with dynamic adjustments as AI recommendation patterns shift.

    Don’t skip contextual modifiers. Adding conditions like “for a team of 20,” “under $500/month,” or “compatible with Salesforce” changes AI recommendation outputs significantly. A brand can dominate unmodified queries and disappear completely once a budget or tech stack constraint is added.

    Topify‘s AI Volume Analytics surface high-value prompts continuously as AI recommendation behavior evolves, which removes the manual guesswork of figuring out which queries are worth tracking in the first place.


    Step 2: Run Queries Across Multiple AI Platforms

    Monitoring only ChatGPT is a common shortcut that produces misleading data.

    Each major AI platform uses different retrieval logic and citation preferences. Tracking brand performance on one while ignoring the others means you’re measuring a fraction of where your customers are actually finding recommendations.

    Here’s how the major platforms differ:

    PlatformCitation LogicMarket Position
    ChatGPTTraining data + Bing real-time search layer. Favors structured, long-form content78.16% AI search share
    Google Gemini / AI OverviewsDeeply integrated with Google index. Prioritizes E-E-A-T signals8.65% share, highest impact on traditional search traffic
    PerplexityPure RAG architecture. Strong recency bias, heavy Reddit and news weighting7.07% share, high-value professional users
    Microsoft CopilotBing-indexed. Sensitive to LinkedIn and professional social signals3.19% share, strong enterprise penetration

    The math behind manual monitoring is its own argument for automation. If you’re tracking 200 prompts across 4 platforms, that’s 800 queries per month, each requiring manual reading, citation extraction, and sentiment assessment. There’s no practical way to maintain historical trend data at that volume without tooling.

    Topify’s Visibility Tracking handles cross-platform coverage automatically and flags competitor changes in real time. In practice, that efficiency gap tends to be the difference between brands that have current data and brands that are working from impressions.


    Step 3: Separate Citations from Mentions in the Data

    Raw query results need to be processed before they’re useful. The goal in this step is to split what you’ve collected into two distinct data types: traffic-driving citations and brand-positioning mentions.

    For citation identification: Parse the HTML or footnote links that AI platforms attach to their answers. Each source link points to a specific domain and URL. That data tells you not just whether you’re being cited, but which type of content AI treats as credible enough to reference.

    Topify’s Source Analysis feature reverse-engineers the third-party domains that drive competitor citations, which turns a general awareness of “we’re not being cited enough” into a specific list of target publications for your PR and content strategy.

    For mention extraction: Use NLP-based parsing to pull brand entity references from the generated text. Focus especially on the context around each mention. Being mentioned as “an enterprise-grade solution” vs. “a budget option” produces very different downstream effects on customer perception, even if both appear in the same query results.

    Once the data is separated, layer it across three dimensions:

    • By prompt type: Are you getting cited in informational queries but disappearing in transactional ones?
    • By platform: Which AI engine is citing you most, and why?
    • By competitive position: Of all brand mentions in your category, what share is yours?

    That last metric, Share of Voice in AI answers, is often more actionable than raw visibility numbers. A brand can have 40% visibility and still be losing to a competitor who appears first in 80% of the queries that matter.


    The 4 Metrics That Tell You If Your Measurement & Monitoring Is Working

    Once the data pipeline is established, these are the numbers worth tracking consistently:

    Citation Rate is the percentage of relevant prompts where AI provides a link to your website. This is the direct measurement of AI-driven referral traffic potential. Low citation rate with high mention frequency means AI knows you exist but doesn’t trust your content enough to send users there.

    Mention Frequency tracks how often your brand name appears in AI answers across your prompt library. This reflects category-level authority and is a leading indicator of future citation performance.

    Position in Answer measures where your brand appears within a multi-brand recommendation. Research suggests that first-position mentions drive 1.5 to 2 times more clicks and trust than third-position mentions. Being in the answer isn’t enough: position within the answer matters.

    Sentiment Score quantifies how AI describes your brand. Topify’s NLP-based scoring translates qualitative brand descriptions into a 0-100 score. A brand appearing consistently in AI answers as “a solid mid-market option” when their actual positioning is enterprise-grade has a data problem, not just a perception problem. High visibility with low sentiment is a net negative.


    What Low Citation Rates Are Actually Telling You

    When citation rates underperform across a prompt category, it usually points to one of two structural issues.

    Content that isn’t machine-readable: AI retrieval systems, especially RAG-based architectures like Perplexity, favor content that puts conclusions first. A long-form article that buries its key finding in paragraph eight is technically correct but practically uncitable. The fix is restructuring key pages so the first 1-3 sentences under each heading deliver a complete, extractable answer. JSON-LD structured data that explicitly labels entity relationships also increases citation probability meaningfully.

    Missing third-party validation: AI systems treat cross-source validation as a signal of factual reliability. If the only place AI can find information about your brand is your own website, it tends to avoid citing you, not because your content is wrong, but because it can’t verify the claim from an independent source.

    The platform distribution data makes this concrete. Brand official websites typically account for less than 10% of AI citations. The rest come from community platforms like Reddit and Quora, professional review sites like G2 and Capterra, and mainstream media. Reddit’s influence has grown particularly sharp since its data licensing agreements with major AI providers: a well-ranked Reddit thread in your product category can generate more AI citation weight than a dozen brand blog posts.

    Princeton University GEO research found that content with statistical evidence, technical explanations, and expert citations gets cited 30-40% more often than content without those features. The implication for content strategy is straightforward: every claim on a high-priority page should be backed with a number, a study, or a named authority.

    There’s also a recency dimension. AI models carry a strong near-term bias. Updating a cornerstone page and explicitly marking it “Updated 2026” improves retrieval probability in most platforms. Content that looks stale gets deprioritized regardless of its quality.


    Conclusion

    Measurement and monitoring in AI search is a fundamentally different exercise than SEO reporting. The metrics are different, the data sources are different, and the strategic implications are different.

    The brands that are building durable AI visibility aren’t doing it by checking ChatGPT once a month. They’ve defined the prompts their customers use, built cross-platform tracking across ChatGPT, Gemini, and Perplexity, and structured their measurement system around citations, mentions, position, and sentiment, not just keyword rankings.

    That infrastructure takes time to build manually. If you want to skip the setup and start with a working baseline, get started with Topify and run your first cross-platform visibility report.


    FAQ

    Q: What’s the difference between an AI citation and a brand mention?

    A: A citation includes a direct link or footnote pointing to your website and drives referral traffic. A mention is when AI says your brand name in the answer text without necessarily linking to you. Citations have higher direct commercial value. Mentions reflect category-level authority. Both require separate tracking strategies.

    Q: How often should I run AI citation monitoring?

    A: At minimum, weekly. Research shows that 40-60% of AI Overview citation sources rotate on a monthly basis, meaning last month’s baseline is often already outdated. For brands in competitive categories, real-time or daily monitoring tends to surface competitor changes before they compound.

    Q: Which AI platforms should I prioritize?

    A: Start with ChatGPT (highest market share), Google AI Overviews (largest impact on traditional search traffic), and Perplexity (concentrated professional user base with high purchase intent). Once that baseline is stable, expand to Copilot and emerging platforms based on where your audience concentrates.

    Q: Can I track competitor citations using the same method?

    A: Yes. Adding competitor brand names to your Prompt Matrix alongside category-level queries gives you a direct comparison of AI Share of Voice. Topify’s Source Analysis also identifies which third-party domains are driving competitor citations, which is often more actionable than the raw Share of Voice number alone.


    Read More

  • How to Track Brand Visibility in ChatGPT and Perplexity

    How to Track Brand Visibility in ChatGPT and Perplexity

    You searched your brand name on ChatGPT. It mentioned you — buried in the third paragraph, after two competitors, with a description pulled from a press release that’s two years old.

    That’s not a win. That’s a measurement problem.

    Most marketing teams have no systematic way to track how often AI platforms recommend their brand, what they say when they do, or how that compares to competitors. They run one or two manual checks, screenshot the result, and move on. That’s not monitoring. That’s guessing.

    This guide walks you through a practical framework for tracking brand visibility in ChatGPT and Perplexity — from building your first prompt set to the metrics that actually tell you whether your brand is winning in AI search.


    Most Brands Don’t Know They’re Invisible to ChatGPT

    The scale of AI search adoption in 2026 makes this a measurement gap you can’t afford.

    ChatGPT now has 900 million weekly active users — more than double the 400 million reported just a year earlier. Perplexity processes approximately 780 million monthly queries and grew its user base 300% within a single year to reach 45 million monthly active users by late 2025. These platforms are no longer novelties. They’re where buyers are going to discover, compare, and shortlist brands.

    Here’s the thing: being visible in AI search isn’t binary. It’s not just “mentioned” vs. “not mentioned.” It’s about how often, in what context, in what position, with what sentiment — and how that changes over time. A one-time manual check tells you nothing about any of that.

    You need a repeatable measurement and monitoring system. This guide builds one from scratch.


    ChatGPT vs. Perplexity: Why They Surface Brands Differently

    Before you track, you need to understand what you’re tracking — because ChatGPT and Perplexity don’t work the same way, and they don’t recommend the same brands.

    ChatGPT relies primarily on pre-trained knowledge, occasionally triggering real-time browsing through SearchGPT. Perplexity is built on a retrieval-first architecture — it searches the live web for every query and cites its sources inline. That structural difference produces strikingly different results.

    Empirical studies involving over 200 high-intent product discovery prompts found only a 25% overlap between brands recommended by ChatGPT and Perplexity. Even among “consensus picks” — brands recommended consistently across multiple sessions — the overlap only rises to about 33%. What this means in practice: a brand’s AI visibility is not a single number. It’s platform-specific.

    ChatGPTPerplexity
    Search mechanismHybrid (pre-trained + selective browsing)Retrieval-first (real-time web search)
    Citation styleAvailable but less centralPersistent, numbered, inline
    Brand preferenceFavors established, high-traffic brandsFavors newer, content-active brands
    Data recencyTraining cutoff unless browsing is triggeredReal-time dynamic retrieval

    The practical implication: brands recommended exclusively on ChatGPT tend to be 3 to 10 times larger in web traffic than those surfaced on Perplexity. Perplexity actually favors smaller, more agile brands that are actively creating content and gaining recent traction — its recommended brands have, on average, 32% fewer monthly visitors than ChatGPT’s picks.

    If you’re an early-stage brand, Perplexity is your immediate opportunity. ChatGPT is the longer-term authority benchmark.


    Step 1 — Build the Prompt Set That Reveals Your AI Footprint

    The foundation of any measurement framework is the right set of prompts. Most teams make the same mistake: they search their brand name and call it a day.

    That’s not visibility monitoring. That’s vanity monitoring.

    Real brand visibility tracking requires three categories of prompts — and you need all three.

    Category 1: Brand-direct queries These test what AI says about you specifically.

    • “[Your brand] vs. [Competitor]”
    • “Is [Your brand] good for [use case]?”
    • “What are the pros and cons of [Your brand]?”

    Category 2: Category-level queries These test whether you appear when buyers are still exploring the market.

    • “Best tools for [category]”
    • “How to solve [problem your product addresses]”
    • “Top [category] platforms in 2026”

    Category 3: Scenario and intent queries These test the highest-value moments in the buyer journey.

    • “What do most [target companies] use for [workflow]?”
    • “Which [category] platform is best for [specific use case]?”
    • “What should I look for in a [category] tool?”

    You need at least 20 to 30 prompts to form a meaningful baseline. Below that, you’re just sampling noise. Tools like Topify support up to 100 prompts on the Basic plan and 250 on Pro — giving you a dataset large enough to draw actual conclusions.


    Step 2 — Run Your First AI Visibility Audit

    With your prompt set ready, run your first audit. The goal is a snapshot: where does your brand currently stand?

    Here’s a simple manual process to start:

    1. Run each prompt in both ChatGPT and Perplexity
    2. Record whether your brand appears in the response
    3. Note your position (first, second, third mention, or absent)
    4. Copy the exact language used to describe you
    5. Flag any competitor that appears in your place

    Use a spreadsheet. Rows for prompts, columns for platform, visibility (yes/no), position, sentiment (positive/neutral/negative), and any notable quotes.

    The limitations of this approach are real. A manual audit is a point-in-time snapshot — it doesn’t capture how AI recommendations shift over a week or month. It also can’t scale to the full set of prompts you need. And it’s slow: a comprehensive manual audit of a moderately sized website can take weeks. McKinsey research from 2024 found that firms using AI for monitoring see up to a 50% reduction in manual data processing time. But the manual process gets you started — and it forces you to actually look at what the AI says about your brand, which most teams have never done seriously.


    Step 3 — The 4 Metrics That Actually Measure Brand Visibility

    Once you have data, you need to know what to do with it. These are the four metrics that form the core of a professional measurement framework.

    1. AI Visibility Score The percentage of tracked prompts where your brand appears in the AI response. This is your foundational benchmark — the simplest measure of whether AI platforms know you exist. A Visibility Score of 20% means you appeared in 1 out of every 5 prompts you tested. The goal isn’t 100%; it’s tracking the trend over time and comparing it to competitors.

    2. Sentiment Score AI platforms don’t just mention brands — they describe them. Sentiment scoring uses natural language analysis to determine whether that description is positive, neutral, or negative. If ChatGPT consistently pairs your brand name with phrases like “steep learning curve” or “limited integrations,” that’s a signal worth acting on — even if your Visibility Score looks healthy.

    3. Position Not all mentions are equal. A brand named first in an AI response has significantly higher influence than one buried in a third-paragraph list. Position tracking measures where you appear relative to competitors within the same response, and GEO techniques like Technical Justification and Statistics Addition can elevate citation rates by over 40% when factoring in position weight.

    4. Citation Source This metric is especially important for Perplexity. When a platform cites a source to support a claim about your brand, that source becomes part of your AI reputation infrastructure. Are the citations pointing to your own site? A G2 review? A Reddit thread? A competitor’s comparison page? Knowing which sources AI platforms use to describe you tells you exactly where to invest in content and digital PR.

    Platforms like Topify track all four of these — plus three additional metrics (volume, intent, and CVR) — across ChatGPT, Perplexity, Gemini, and other major AI engines simultaneously, eliminating the need to manually reconcile data across platforms.


    What Your Visibility Data Actually Tells You

    The data patterns you’ll encounter typically fall into one of three buckets — and each points to a different optimization path.

    Pattern 1: You don’t appear at all. This usually means one of two things: AI platforms don’t have enough high-authority, structured content to confidently cite your brand, or your brand presence exists primarily behind paywalls, JavaScript-heavy pages, or formats AI crawlers can’t parse. Nearly 91% of top-cited sites use HTTPS, and pages with LCP over 4 seconds are 72% less likely to be cited. Fix the technical foundation first.

    Pattern 2: You appear, but your position is consistently behind competitors. Your brand is on AI’s radar, but it’s not the consensus pick. This is a Share of Voice problem. In three out of five major industries, the top-ranked entity in AI recommendations captures an average of 62% of total AI Share of Voice. You need to build more citation sources — structured content, third-party mentions, Reddit threads, review platforms — to shift the weight.

    Pattern 3: You appear, but sentiment is mixed or outdated. AI platforms synthesize millions of sources. If outdated information about your pricing, features, or team is circulating in high-authority sources, that’s what the model reflects. The fix involves updating Wikipedia entries, LinkedIn profiles, and high-authority industry publications, and ensuring your own site has a clearly structured “about” or “company facts” section that AI crawlers can extract cleanly.

    The stakes aren’t abstract. ChatGPT referral traffic converts at 15.9% — versus 1.76% for Google organic. Perplexity referral traffic converts at 10.5%. Being cited as a “source of truth” in a high-accuracy AI response carries a 4.4x higher conversion probability compared to traditional organic search. The measurement matters because the outcomes matter.


    When Manual Tracking Breaks Down (and How to Automate It)

    Manual audits can get you started. They can’t scale with you.

    Three structural problems eventually make manual monitoring unworkable. First, time lag: AI recommendation patterns shift as models update and new content enters the web. A monthly manual check misses weeks of drift. Second, coverage: to track 30+ prompts across two platforms, for your brand and three competitors, consistently, is a significant operational burden. Third, consistency: human reviewers classify sentiment differently. The data degrades over time.

    This is where automated monitoring earns its place.

    Topify tracks brand visibility across ChatGPT, Perplexity, Gemini, DeepSeek, and other major AI platforms — automatically running your full prompt set, analyzing 9,000 AI answers per month on the Basic plan, and returning structured data across all four core metrics (plus three additional ones). You get a live comparison against competitors without manually querying a single prompt.

    For teams managing multiple clients, Topify’s agency-oriented workflow supports up to 10 seats and 8 projects on the Pro plan, making it practical to run measurement frameworks at scale rather than as a one-off exercise.

    The market for AI visibility tracking tools was valued at $848 million in 2025 and is projected to reach $33.7 billion by 2034. That growth reflects how quickly “GEO monitoring” is shifting from nice-to-have to operational requirement — especially as Gartner projects traditional search volume will drop 25% by the end of 2026 alone.

    Topify’s Basic plan starts at $99/month and includes a 30-day trial. For most in-house marketing teams and agencies, that’s the practical entry point for systematic measurement.


    Conclusion

    Tracking brand visibility in ChatGPT and Perplexity isn’t complicated. But it does require a system.

    Start by building a prompt set across three categories: brand-direct, category-level, and scenario queries. Run your first manual audit to get a baseline. Then focus on four metrics that actually tell you something: Visibility Score, Sentiment Score, Position, and Citation Source. Use the data to diagnose which of the three patterns you’re in — invisible, underranked, or misrepresented — and act accordingly.

    You can’t optimize what you don’t measure.

    Once manual tracking hits its limits, automated platforms like Topify make it possible to run this as a continuous, scalable process rather than a one-time project.

    AI search is already influencing buyer decisions at a conversion rate that dwarfs traditional organic search. The brands that build measurement & monitoring frameworks now will have the data advantage that compounds as the channel grows.


    FAQ

    How often should I run a brand visibility audit in ChatGPT? 

    For manual audits, monthly is a reasonable starting cadence. The risk is that model updates and new content can shift recommendations in a matter of weeks. Automated platforms typically run continuous monitoring, giving you data that reflects current AI behavior rather than a point-in-time snapshot.

    Does Perplexity show different brand visibility results than ChatGPT? 

    Yes, significantly. Studies show only a 25% overlap in brand recommendations between the two platforms. Perplexity favors brands with recent, content-active presence; ChatGPT tends toward established players with deep historical data. Both should be tracked separately, not treated as equivalent.

    What’s a good AI Visibility Score benchmark? 

    There’s no universal benchmark, since it varies by category size and competitive density. What matters more is the trend over time and your position relative to competitors. In most competitive categories, the leading brand captures around 62% of total AI Share of Voice — giving you a realistic ceiling to measure against.

    Can I track competitor visibility at the same time as my own? 

    Yes, and you should. Monitoring your competitors’ Visibility Score, position, and citation sources helps you understand why they’re recommended over you in specific prompt contexts. This is where competitive intelligence in GEO tracking becomes most actionable.

    How is AI brand visibility different from traditional SEO ranking? 

    Traditional SEO ranks individual pages by keyword. AI visibility measures how often your brand is synthesized into a generative response — factoring in mention frequency, position within the response, sentiment, and source attribution. A page can rank #1 on Google and never be cited by ChatGPT, if it lacks the structural clarity and “extractability” that AI retrieval systems prioritize.


    Read More