Category: Article

  • How to Build a Prompt Set Your GEO Rank Tracker Can Trust

    How to Build a Prompt Set Your GEO Rank Tracker Can Trust

    Your visibility number dropped from 34% to 21% last week, and your manager wants an explanation. You pull the answers. Same competitors, same citations, nothing obvious changed. So you check the prompt list, and it turns out 40 of your 60 prompts came from a keyword export somebody ran in March. Most of them nobody has ever typed into ChatGPT.

    Your GEO rank tracker didn’t fail. It measured exactly what you told it to measure. The problem is that what you told it to measure isn’t your market.

    Your Prompt Set Is a Sample, Not a Checklist

    Every number a tracker reports is an estimate about a population you can’t enumerate: all the ways real buyers phrase questions in your category, across every engine, every week.

    You can’t run that population. You run a sample of it. Which means the prompt set isn’t a to-do list of terms you want to win. It’s a sampling frame, and it determines the accuracy ceiling of every metric downstream.

    That distinction has teeth right now, because the population looks nothing like a keyword list. Across Semrush’s ChatGPT prompt dataset, between 65% and 85% of prompts couldn’t be matched to any traditional search keyword. Seer Interactive found that 95% of Gemini’s fan-out queries carry zero monthly search volume by conventional metrics.

    No amount of dashboard polish fixes a bad sample.

    Three Sampling Biases a GEO Rank Tracker Can’t Correct for You

    A tracker reports what it observes. It has no way of knowing that what it observed came from a skewed frame. Three biases account for most of the damage.

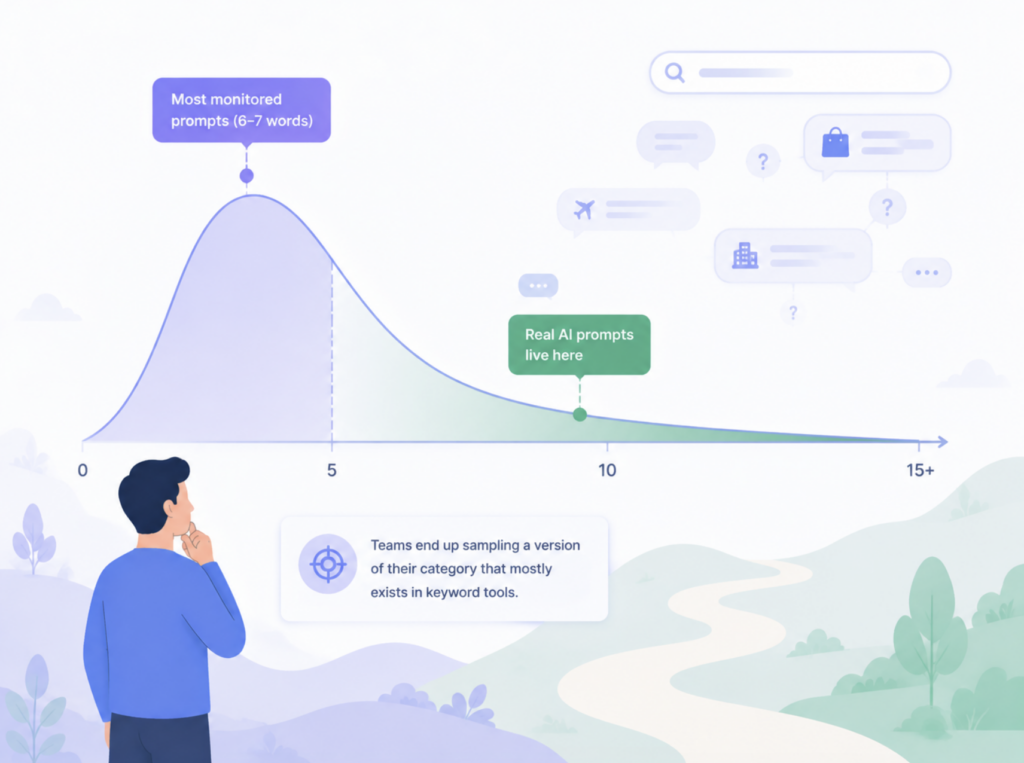
    Coverage bias toward the head. AirOps analyzed 245,000-plus prompts that brands were actively monitoring and found they peaked around 6 to 7 words, with almost nothing past 10. Real AI prompts sit much further out on the tail. Teams end up sampling a version of their category that mostly exists in keyword tools.
    Branded self-selection. Most brands perform well on their own name, so a set heavy in branded prompts reports a visibility rate that’s structurally inflated. Conductor’s guidance is to keep branded prompts at 25% or less of the total. Anything above that and you’re measuring your own recall, not your category position.

    Format skew. How a prompt is shaped changes how many brands appear at all. An analysis of 37,804 AI responses found that ranking-style prompts surfaced roughly 20% more brand mentions than open-ended ones, and concise keyword-style prompts added up to 25%. Load your set with “best X” formats and your visibility looks great. Load it with open questions and the same brand looks weak. Neither number is wrong. Both are unrepresentative.

    Stratify First: Five Layers a Representative Prompt Set Needs

    Random sampling doesn’t work here, because the strata behave differently and you need to read them separately. Stratified sampling does.

    LayerWhy it moves the numberSuggested share
    Intent stageTOFU category questions are stable; MOFU commercial queries swing hard on small wording changes25% TOFU / 45% MOFU / 30% BOFU
    Prompt formatRanking, comparison, and open-question formats return different brand counts40% question / 35% comparison or ranking / 25% keyword-style
    Persona and context“Best CRM” and “best CRM for a 12-person remote team” resolve to different brand sets3+ personas, none below 15%
    Language and marketA crossed-effects study found brand-by-language accounted for 8.6% of total variance, a measurable bilingual penaltyProportional to revenue mix, minimum 20 prompts per market
    Branded vs unbrandedBranded prompts test entity recognition; unbranded prompts test category positionBranded capped at 25%

    The point of stratifying isn’t tidiness. It’s that a stratum you didn’t define is a stratum you can’t diagnose. When visibility drops, you want to be able to say “it fell in MOFU comparison prompts in German” rather than “it fell.”

    How Many Prompts Is Enough? Run the Math Before You Run the Tracker

    Brand visibility on a single answer is a Bernoulli trial: you’re either mentioned or you’re not. That makes the sample size question answerable with a formula rather than a gut check.

    Margin of error on a proportion is z multiplied by the square root of p(1-p)/n. Assuming a realistic visibility rate around 30%, here’s what different precision targets actually cost:

    Target margin of errorConfidenceIndependent prompts needed
    ±10 pp90%~57
    ±5 pp90%~230
    ±5 pp95%~325
    ±3 pp95%~900

    Two things fall out of that table. Halving your margin of error costs four times the sample, not twice. And a 90% confidence interval is usually the right call for a marketing metric, since you’re deciding whether a topic is trending up or down, not approving a drug.

    Here’s the part most teams miss. Those numbers apply per stratum you want to read on its own. Split 100 prompts across five intent-and-format strata and each one lands at 20 prompts, which carries a margin of error near ±17 pp at 90% confidence. At that width, 25% and 40% are the same number.

    Decide your reporting granularity first. Then size the set to support it.

    Not Every Prompt Deserves an Equal Vote

    An unweighted average treats a prompt asked twice a month and a prompt asked four thousand times a month as equally important. That’s a modeling choice, and it’s almost always the wrong one.

    Weighting by demand fixes the distortion. It also introduces a new one, because prompt volume estimates are reconstructions. No vendor has access to AI platform query logs. Conductor’s critique is blunt on this: with long, context-laden prompts, exact-match volume approaches one, so keyword-level aggregation breaks down and panel-based estimates carry their own coverage gaps.

    The workable middle: use volume data to sort prompts into three demand tiers rather than to assign precise multipliers. Weight them 3, 2, and 1. Then report both the weighted and unweighted visibility rate every cycle. When those two numbers diverge sharply, you’ve learned something real about where your visibility is concentrated.

    One Query, Five Answers: Runs Are Not Prompts

    Ask the same question twice and the answer moves. The SparkToro and Gumshoe study ran 12 prompts roughly 3,000 times across ChatGPT, Claude, and Google’s AI features, and found the odds of getting the same brand list twice were under 1 in 100. Getting the same list in the same order was closer to 1 in 1,000.

    The standard response is to repeat each prompt and average. That’s correct, and it has a sharp ceiling. A 2026 variance-components decomposition found that a repeat past the fifth reduced relative-error variance by only 0.0003, while adding models and languages reduced it far more per unit of query budget. A separate study recommends at least 7 runs per prompt per day for brand monitoring.
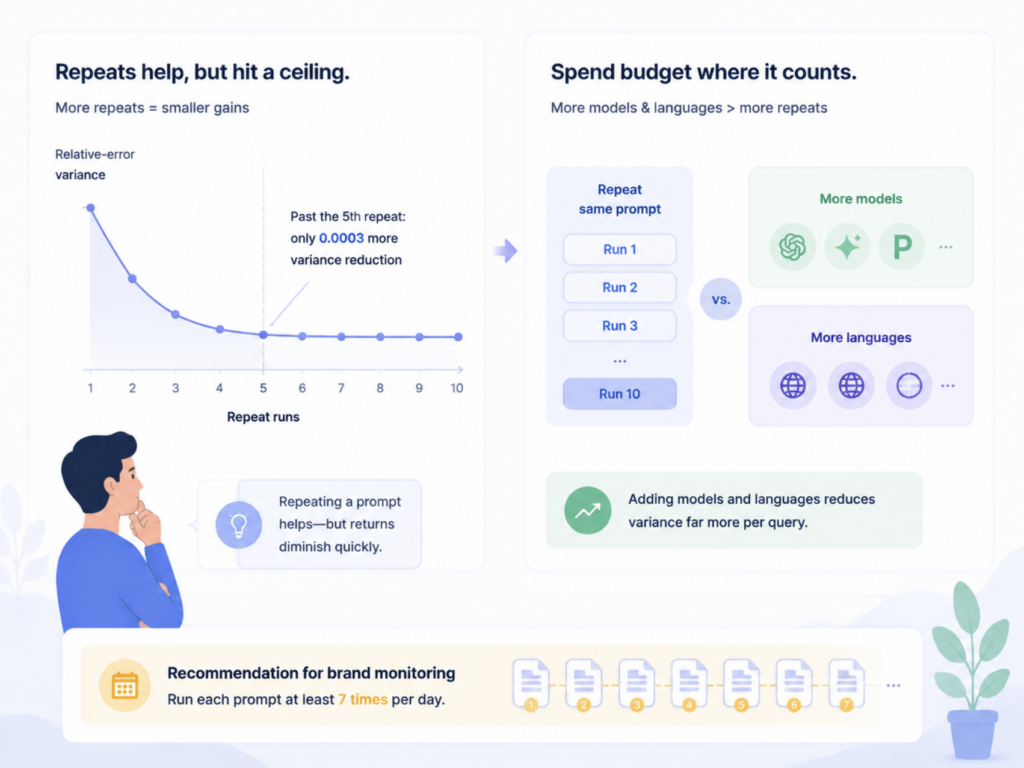
    So the practical allocation is: 5 to 7 runs per prompt per engine, then spend everything left on more prompts and more engines.

    The reason matters. Repeated runs shrink noise within a prompt. They do nothing for coverage. Thirty prompts run ten times produces 300 answers but still only 30 independent draws from the population of buyer questions, and your confidence interval on category visibility is governed by the 30, not the 300. Teams that report the larger number are quoting a precision they don’t have.

    One practical rule falls out of this: never call a week-over-week change real unless it clears the confidence interval you calculated in the previous section.

    Building and Validating the Set Inside a GEO Rank Tracker

    All of this assumes your tracker can do three things: find the prompts you missed, tell you which ones carry weight, and let you read strata separately.

    Coverage is the hardest of the three, because you can’t audit a blind spot from the inside. Topify approaches it through High-Value Prompt Discovery, which surfaces prompts your buyers are actually using rather than the ones your keyword export suggested, and keeps surfacing new ones as recommendation patterns shift. In practice, that’s the difference between a set you wrote from memory and a set drawn from observed demand.

    Weighting runs off AI Volume analytics, which gives you the demand tiers described above without hand-waving. Position Tracking and Competitor Benchmarking then let you read those strata as separate series, so a drop in MOFU comparison prompts shows up as a distinct signal instead of getting averaged into a flat category number. Coverage spans ChatGPT, Gemini, Perplexity, DeepSeek, Doubao, Qwen, and others, which is what makes the language and market layer measurable rather than theoretical.

    Budget math is worth checking before you commit. The Basic plan covers 100 prompts and 9,000 AI answer analyses per month, and the Pro plan covers 250 prompts and 22,500 analyses. Run 100 prompts at 5 runs across 3 engines and you spend 1,500 analyses per cycle, which leaves room for weekly cadence inside the Basic tier. At 250 prompts you can support ±5 pp overall with enough left to read three or four strata independently.

    If you’re rebuilding a set from scratch, the fastest validation is to get started with your existing prompts loaded, then compare them against discovered prompts. The gap between the two is your coverage bias, quantified.

    Prompt Sets Decay. Here’s the Refresh Cadence

    Sets go stale faster than most reporting calendars assume. The same study that recommended 7 runs per prompt also measured roughly 65% day-to-day turnover in cited sources, and found the standard error of a per-brand detection rate only dropped below 0.05 at around 24 days. A week is not an observation window. A month is the floor.

    Rebuild quarterly, not continuously. Replace 20% to 30% of the set each quarter and lock the remaining 70% as your time-series baseline. Swap everything at once and you’ve broken comparability with every prior cycle, which is a more expensive mistake than tracking a few stale prompts.

    Then keep three triggers for off-cycle refreshes: a major model release, a new competitor appearing in your answers, and any product or market launch on your side. Those change the population you’re sampling, which means the frame has to change with it. Everything else can wait for the quarter.

    Conclusion

    The prompt set is the one part of a GEO measurement system that no software can repair after the fact. Size it against a stated margin of error, stratify it so you can diagnose what moves, cap branded prompts, weight by demand tiers rather than false precision, and spend surplus budget on more prompts rather than more repeats.

    Start by auditing what you already track. Count the branded share, count the words per prompt, and calculate the margin of error on your current sample. If that last number is wider than the changes you’ve been reporting to leadership, fix the frame before you fix the strategy.

    FAQ

    Q: How many prompts should I track in a GEO rank tracker? 

    A: For an overall visibility rate at ±5 percentage points and 90% confidence, plan on roughly 230 independent prompts. If you want to read intent stages or markets as separate series, size each stratum to that target on its own. Fewer than 60 prompts gives you a pilot, not a reportable number.

    Q: What share of my prompt set should include my brand name? 

    A: 25% or less. Branded prompts test whether AI engines recognize and describe you correctly, which is worth monitoring, but they inflate overall visibility because most brands perform well on their own name.

    Q: Is it better to run more prompts or repeat the same prompts more often? 

    A: More prompts, past about 5 runs each. Repeats reduce noise within a single prompt and stop paying off quickly. Coverage across prompts, engines, and languages is what tightens your estimate of category visibility.

    Q: How often should I rebuild my prompt set? 

    A: Quarterly, replacing 20% to 30% while keeping the rest locked as a baseline. Refresh off-cycle when a major model ships, a new competitor enters your answers, or you launch into a new market.
    Read More

  • Your GEO Rank Dropped. Here’s the GEO Rank Tracker Decision Tree

    Your GEO Rank Dropped. Here’s the GEO Rank Tracker Decision Tree

    Monday morning. Your GEO rank tracker shows your brand sliding from position two to position seven in ChatGPT answers across your three highest-intent prompts. Nobody shipped anything last week. No pages were deprecated. No redirects broke.

    The default reaction is to rewrite the pages that stopped getting cited. That reaction is wrong most of the time, because a position drop in AI answers has at least four separate causes and only one of them is fixed by touching your content. Picking the wrong branch costs you a sprint, and by the time you find out, the number has moved again.

    A GEO Rank Drop Is Never Just One Problem

    Traditional rank tracking trained a reflex: position falls, so audit the page. That reflex assumes a stable index behind the result. AI answers don’t have one.

    The measurement layer itself keeps shifting. As Search Engine Journal pointed out in a breakdown of why prompt tracking needs a different approach, when OpenAI shipped a new default model, most AI citation trackers registered a collective drop. Optimization quality hadn’t changed. The number of citation links exposed in the response had.

    So the first question after a drop isn’t “what did we do wrong.” It’s “which layer moved.”

    Most teams can’t answer that, and they know it. Semrush’s 2026 AI Visibility Index, built on 126 million US AI search prompts from January through April 2026, found that 45% of marketing leaders can’t accurately measure brand visibility in AI-generated answers, and only 9% have tools covering every metric they need.

    That gap is exactly where wasted sprints come from.

    Step Zero: Prove the Drop Is Real Before You Diagnose It

    Most reported GEO rank drops aren’t drops. They’re single samples pulled from a distribution that was always noisy.

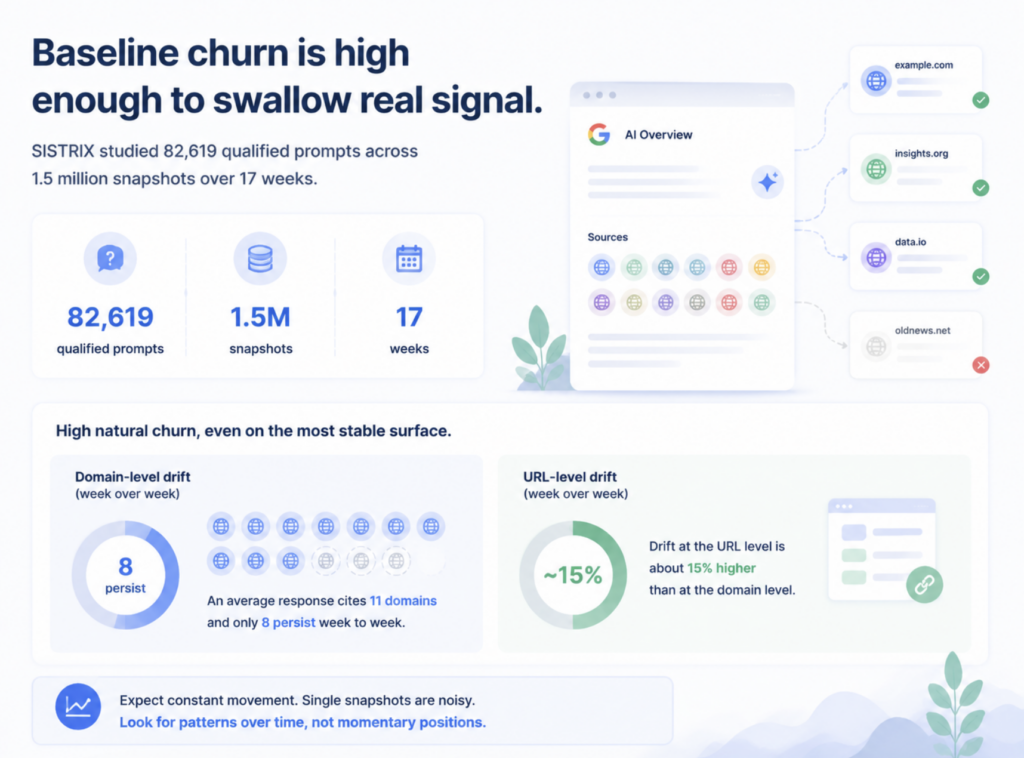
    The baseline churn is high enough to swallow real signal. SISTRIX studied 82,619 qualified prompts across 1.5 million snapshots over 17 weeks and found that even on Google AI Overviews, the most stable surface tested, an average response cites 11 domains and only 8 of those persist week to week. At the URL level, drift runs about 15% higher than at the domain level.

    Zoom out to a month and the picture gets rougher. Digital Authority Partners tracked citation persistence across five engines and measured an average 28-day citation retention rate of 33%, meaning roughly two-thirds of cited URLs get replaced inside four weeks without anyone doing anything.

    Against that baseline, a single check proves nothing.

    Three gates before you open an investigation:

    • Sampling gate. The prompt has been run enough times in the window to separate rate from roll of the dice. One run is a screenshot, not a measurement.
    • Persistence gate. The lower position holds across consecutive sampling windows, not just one refresh.
    • Scope gate. You know whether the drop is confined to one prompt, one prompt cluster, or your whole tracked set. This single distinction eliminates two of the four branches below.

    Run those gates first and a good share of your alerts close themselves.

    The GEO Rank Tracker Decision Tree: Four Branches From One Drop

    Once the drop clears the gates, it belongs to exactly one of four branches. They’re ordered by diagnostic cost, cheapest first.

    BranchWhat the data looks likeLayer you need to checkFirst move
    1. Citation lossYour position falls, the domains that used to cite you are gone from the answerCited source domains and URLs, before and afterRecover or replace the lost source
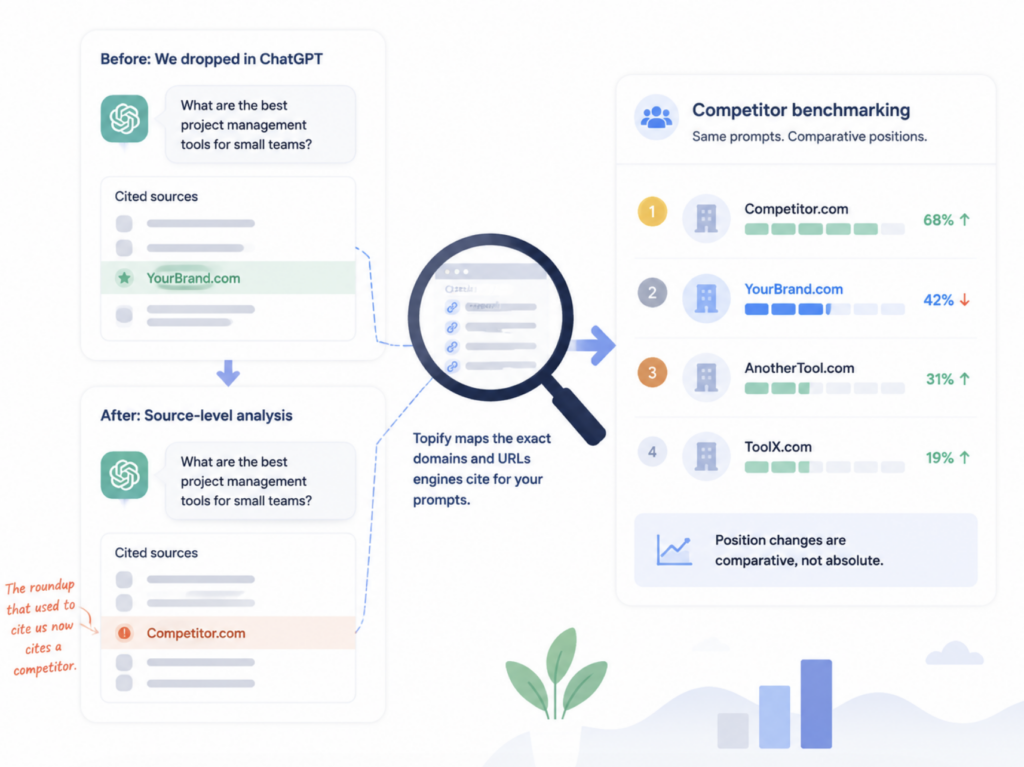
    2. Competitor gainYour citations are intact, but a rival now sits above youCompetitor position history on the same promptsAnalyze what got them cited
    3. Platform changeMany unrelated prompts move on the same day, one engine onlyCross-engine comparison on the same dateRebaseline, change nothing
    4. Framing driftYou’re still mentioned as often, but described differently and ranked lowerSentiment and descriptor tracking over timeFix the third-party narrative

    Branch 1: You Lost the Citation

    Start here because it’s the only branch with a direct, controllable fix.

    Compare the cited domain set from before and after the drop. If a review site, a forum thread, or a comparison page that used to appear in the answer is missing now, your position didn’t fall because your content weakened. Your evidence base did.

    Common causes: a listicle got updated and dropped you, a directory listing expired, a media placement fell behind a paywall, or a page you own got restructured and lost the specific passage the engine was pulling.

    The fix is source-level, not site-level. Restore that citation or earn a replacement of similar authority.

    Branch 2: A Competitor Took the Slot

    If your citations are unchanged and your position still fell, someone else moved up. AI answers rank on relative authority within a topic, so you can lose ground without losing anything.

    This branch is more common in unsettled categories than most teams expect. Semrush and Kevin Indig’s study of 1,094 US categories and more than 50,000 brands found that clear category owners held first place in 90.4% of month-over-month comparisons, while in emerging and unsettled categories the top brand switched in 1,950 out of 5,470 comparisons.

    Translation: if you own your category, a drop is probably noise. If you’re an emerging leader, a drop is probably a competitor.

    The same research also found that real topic ownership means appearing in at least four of five related prompts with a five-point lead over the runner-up. Winning one prompt isn’t ownership, and losing one prompt isn’t a crisis.

    Branch 3: The Model Changed, Not Your Content

    This is the branch that burns the most budget, because the drop looks exactly like a content failure and responds to none of the usual fixes.

    When ChatGPT switched its default model in early March 2026, Search Engine Land tracked 400 daily prompts over 14 weeks and found the average number of unique domains cited per response fell from 19 to 15, with unique URLs sliding from 24 to 19. Roughly a fifth of the citation surface vanished across the board, and it didn’t come back.

    Every brand tracking that engine registered a decline that week. None of them had done anything.

    The tell is scope plus timing: a large share of unrelated prompts move together, on one engine, on one date, while the same prompts on other engines hold steady. That pattern is only visible if you’re tracking more than one platform, which is why single-engine monitoring produces so many false diagnoses.

    The correct response is to reset the baseline and hold the strategy. Chasing a platform-level change with a content sprint is how teams spend a quarter recovering ground that was never lost.

    Branch 4: Your Framing Drifted

    The subtlest branch. Mention frequency holds, but the answer now calls you the budget option, or the legacy option, or the tool for small teams, and the ordering shifts to match.

    Position in an AI answer follows the descriptors the model has absorbed about you. When third-party coverage starts framing you differently, ranking moves before mentions do. This is a public relations problem wearing a GEO costume, and no amount of on-page work will fix it.

    Mentions and Position Don’t Move Together

    Here’s the structural point most dashboards miss: how often AI names your brand and where it places you are governed by different inputs. They can move in opposite directions in the same week.

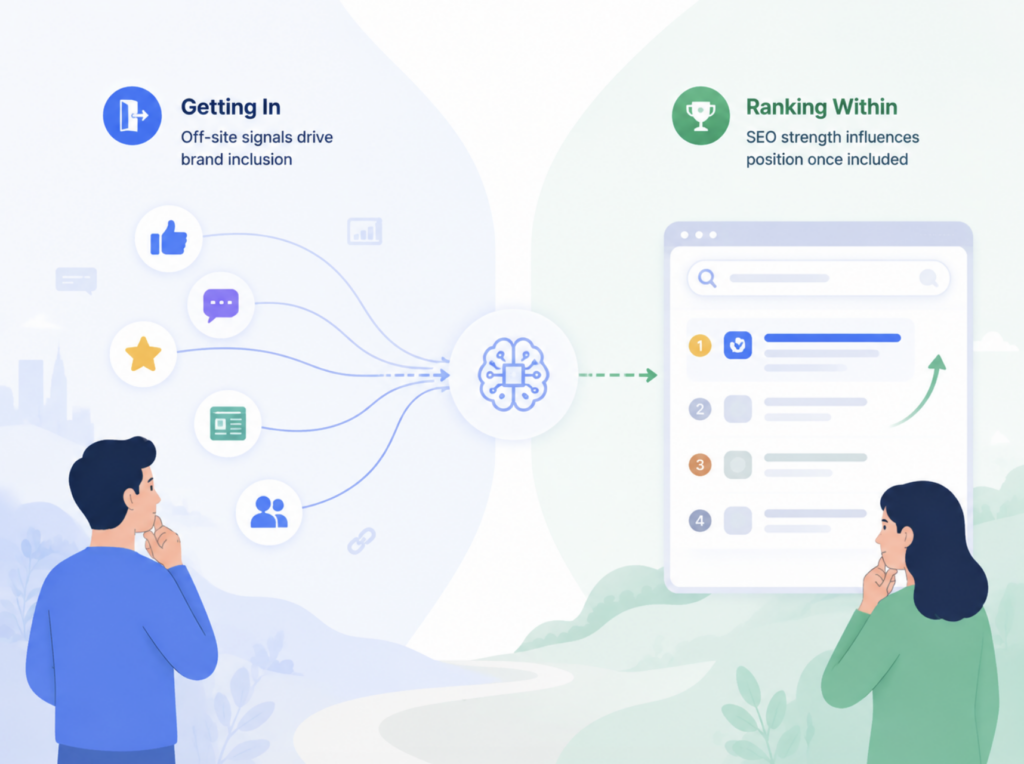
    Research on the shift from SEO to generative search keeps landing on the same separation. Conventional SEO strength tends to predict where a brand lands once it’s inside an answer, but it’s a weak predictor of whether the brand gets named at all. Off-site signals carry that part.

    Ahrefs’ analysis of 75,000 brands put numbers on it. Branded web mentions correlated with AI Overview visibility at 0.664, branded anchors at 0.527, and brand search volume at 0.392, while referring domains, the classic backlink metric, came in at 0.218. Brands in the top quartile of web mentions earned up to 10 times more AI Overview mentions than the next quartile.

    Which means a rank tracker that collapses everything into one visibility score is measuring two different systems and reporting one number.

    That’s the number that tells you something dropped and nothing about what.

    What Your GEO Rank Tracker Needs to Finish the Diagnosis

    Walking this decision tree requires five data layers. Most tools ship two or three.

    1. Prompt-level position history, not just an aggregate score, so you can separate one bad prompt from a systemic slide.
    2. Cited source domains and URLs, tracked over time, so Branch 1 becomes a lookup instead of a guess.
    3. Competitor position on the same prompts, so Branch 2 is answerable without manual re-runs.
    4. Multi-engine coverage on a shared timeline, so Branch 3 is provable by cross-reference.
    5. Sentiment and descriptor tracking, so Branch 4 shows up before it becomes a positioning problem.

    Topify was built around that structure rather than around a single score. It monitors brand performance across major AI platforms through seven metrics covering visibility, sentiment, position, volume, mentions, intent, and CVR, and its citation analysis reverse-engineers the exact domains and URLs each platform pulls from.

    In practice, that turns a Monday morning alert into a ten-minute triage. You see the position drop, open the source view, and find that a comparison page which had been citing you for months now cites two competitors instead. That’s Branch 1 with a named target, not a hypothesis.

    Engine coverage matters as much as depth, since Branch 3 can’t be ruled out from inside a single platform. Tracking spans ChatGPT, Gemini, Perplexity, DeepSeek, Doubao, Qwen, and others, so a platform-level shift is distinguishable from a brand-level one on the same chart.

    The Repair Order After a GEO Rank Drop

    Branch determines both the fix and the realistic timeline.

    BranchWhat to doWhat not to do
    Citation lossRebuild the specific lost source, or earn an equivalent third-party placementRewrite unrelated pages
    Competitor gainStudy what got the competitor cited, then contest that source setPublish more of what already isn’t working
    Platform changeReset the baseline, document the date, keep executingLaunch an emergency content sprint
    Framing driftCorrect the narrative at the source level through reviews, comparisons, and earned coverageAdd schema and hope

    Two rules worth holding across all four. Don’t optimize for one engine when your audience uses several, and don’t treat a week of data as a trend when the baseline churn is this high. If you want a working setup, start with a tracked prompt setof 30 to 50 real buyer questions, sample them on a fixed cadence, and let a full month accumulate before you call anything a drop.

    Conclusion

    A falling number in your GEO rank tracker isn’t a content problem. It’s an attribution problem, and it stays unsolvable as long as your tooling reports a single score instead of the layers underneath it.

    Run the gates first. Confirm the drop survives sampling, persistence, and scope. Then walk the four branches in order, cheapest diagnosis first, and fix only what the data points at. Teams that do this spend their sprints on the one branch that’s actually broken. Teams that don’t spend them rewriting pages that were never the reason.

    FAQ

    Q: Why did my GEO rank drop overnight when nothing changed on my site? 

    A: Overnight movement across many unrelated prompts on a single engine usually points to a platform change rather than anything on your end. Default model swaps have measurably reduced how many sources get cited per response, which lowers everyone’s numbers at once. Check whether your other tracked engines held steady on the same date before you touch anything.

    Q: How often should I check a GEO rank tracker? 

    A: Continuously for data collection, but weekly or biweekly for decisions. With roughly two-thirds of cited URLs rotating within a 28-day window, daily readings mostly capture noise. Set an alert threshold that requires the change to persist across consecutive sampling windows.

    Q: Is a GEO rank tracker different from an SEO rank tracker? 

    A: The output looks similar and the mechanics aren’t. SEO rank tracking reads a stable index where the same URLs hold the same positions for weeks. GEO rank tracking samples a probabilistic system, so position has to be measured as a rate across repeated runs, and it has to be paired with citation-source data to be diagnosable.

    Q: Can I recover a lost AI citation? 

    A: Sometimes directly, more often by substitution. If the source that cited you still exists and simply updated its content, an outreach or refresh path may work. If it’s gone, the practical route is earning a comparable third-party mention, since off-site brand mentions correlate far more strongly with AI visibility than backlinks do.

    Read More

  • Building Your Own GEO Rank Tracker: The Real Cost Breakdown

    Building Your Own GEO Rank Tracker: The Real Cost Breakdown

    You priced it out already. A hundred prompts, four AI engines, a scheduled job, and a Postgres table. The token bill came back under $150 a month, which is less than one seat on most analytics platforms, and the whole GEO rank tracker looked like a two-week sprint you could slot in between roadmap items.

    That estimate isn’t wrong. It’s just measuring the cheapest part of the system.

    The expensive parts are statistical validity, entity resolution, and the fact that what you’re measuring shifts underneath you every few weeks. Here’s the full bill, line by line, including the items that never appear on a credit card statement.

    The Napkin Math That Makes a DIY GEO Rank Tracker Look Cheap

    The estimate almost always looks the same. Take your prompt list, multiply by the number of engines, multiply by how often you want to check, then multiply by a per-call token price.

    At current rates that math genuinely is small. OpenAI’s mid-tier model runs $2 per million input tokens and $12 per million output, and a typical brand-recommendation answer is maybe 700 output tokens. That’s less than a cent per call.

    So the spreadsheet says $60 a month and the meeting ends.

    The problem isn’t the arithmetic. It’s that the arithmetic prices one question asked once, and a tracker that anyone will act on has to do something considerably harder than that.

    What a GEO Rank Tracker Has to Do Before Anyone Trusts Its Output

    Asking an AI engine a question is one function call. Turning thousands of those answers into a number a marketing lead can defend in a QBR takes six separate systems.

    Prompt set design. Which questions represent real buyer intent in your category, and how many paraphrases of each do you need? This is a research problem, not an engineering one.

    Multi-engine querying. ChatGPT and Claude have clean APIs. Google’s AI Overviews and AI Mode don’t, so you’re routing through a third-party SERP provider with its own failure modes.

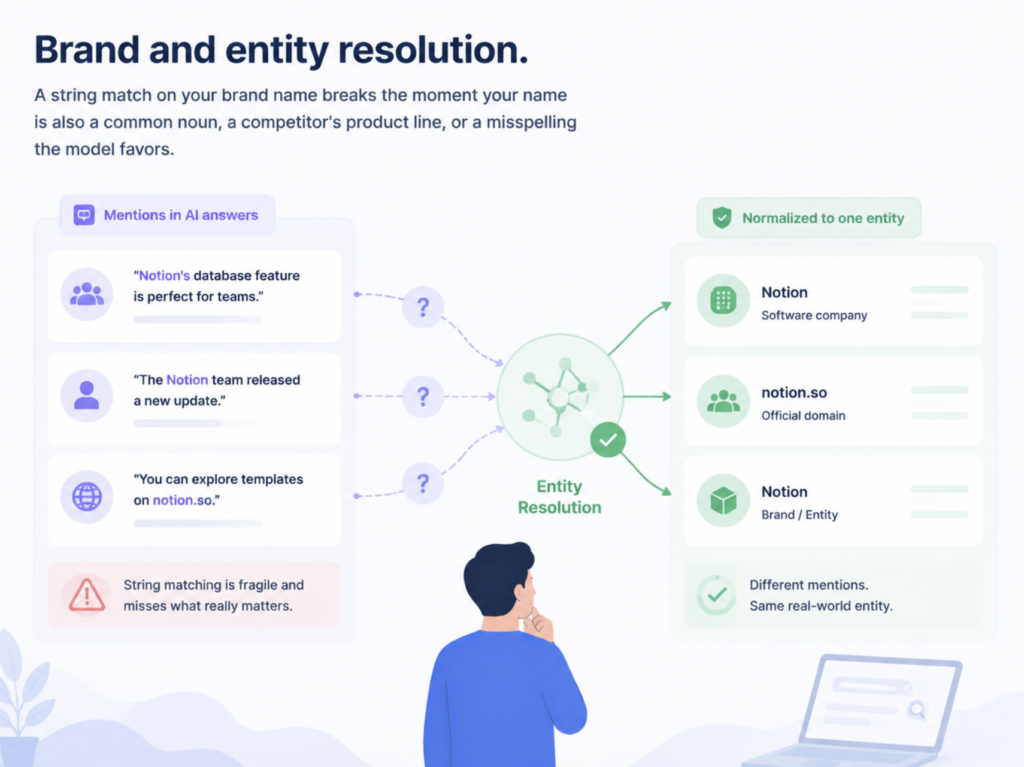
    Brand and entity resolution. A string match on your brand name breaks the moment your name is also a common noun, a competitor’s product line, or a misspelling the model favors. Mentions arrive as “Notion’s database feature,” “the Notion team,” and “notion.so” in the same answer set.

    Position and sentiment scoring. Was your brand first, third, or a footnote qualified with “though it’s pricier than alternatives”? Both need a second LLM pass, which means a second token bill and a second source of variance.

    Citation parsing. Which domains did the engine actually cite, and did any of them belong to you? This is where most homegrown trackers stop, because it requires normalizing wildly inconsistent source formats.

    Longitudinal storage. Every one of the above has to stay comparable to itself across months, or the trend line means nothing.

    Each of those is a module. Not an if-statement.

    API Costs Are the Smallest Line on the Bill

    Run the numbers at a realistic configuration and the API layer still comes in modest, but it’s meaningfully higher than the napkin version because of the surfaces you can’t reach with an LLM API alone.

    Perplexity’s Sonar bills $1 per million tokens each way plus a per-request search fee of $5 to $14 per 1,000 requests, and its standalone Search API sits at $5.00 per 1,000 requests. Google AI Overviews require a SERP vendor, where prices run from about $0.30 to $25 per 1,000 searches depending on how much structured parsing you want. The same benchmark found DataForSEO’s AI Overview endpoint around $1.20 per 1,000.

    Pick your vendor carefully, though. One head-to-head test found that three major scraping providers returned zero AI Overview data despite selling Google SERP access, which means a pipeline built on them has to be rebuilt later.

    A realistic monthly total for 100 prompts across four engines, checked weekly, lands somewhere between $55 and $125. Call it $1,000 a year.

    The Sampling Multiplier Nobody Puts in the Estimate

    Here’s where the napkin math quietly breaks. One call per prompt per engine tells you almost nothing, because AI answers aren’t stable.

    SparkToro and Gumshoe.ai ran 2,961 prompts across ChatGPT, Claude, and Google’s AI with 600 volunteers, repeating each prompt 60 to 100 times per platform. The odds of getting the same brand list twice came in under 1 in 100. The odds of getting it in the same order were closer to 1 in 1,000.

    What did hold up was frequency. The top brands in each category appeared in 55% to 77% of responses regardless of phrasing, which is why visibility percentage survives scrutiny and single-run “rank” doesn’t.

    That finding rewrites your cost model. If a defensible number needs dozens of runs rather than one, every API figure above multiplies accordingly.

    And repetition alone won’t save you. A variance-components study of non-determinism in LLM brand answers found that a sixth repeat of the same prompt reduces relative-error variance by only 0.0003, while brand-ranking reliability sits near 0.01 for a single answer and reaches only about 0.36 across a full crossed design of eight languages, three models, and fifteen paraphrases. Reliability comes from spreading across models, languages, and phrasings, not from hammering one prompt.

    Separate research on paraphrase brittleness puts a sharper edge on it: two natural paraphrases of the same buyer intent produced recommendation sets overlapping just 14% to 29%, against 50% to 61% for reruns of the identical prompt. The phrasing your tracker happens to issue becomes the dominant variable in your own metric.

    So the honest API estimate isn’t 100 prompts. It’s 100 intents times several paraphrases times several runs times four engines. That’s a 15x to 30x multiplier on the number your spreadsheet started with.

    The Line Item You Can’t Put on a Credit Card

    Even at 30x, the API bill stays under $2,000 a year. Engineering time is where the money actually goes.

    Industry cost modeling puts a blended loaded cost across engineers, PM, and UX at around $230,000 per FTE per year. A single developer typically runs $120,000 to $180,000 fully loaded once benefits and overhead are counted. A production-grade internal tool with auth, logging, error handling, and a usable interface generally takes three to six months and $150,000 to $400,000 before anyone logs in.

    A GEO tracker is narrower than that, so scale it down. Six to twelve weeks of one competent engineer, plus review time, lands in the $25,000 to $60,000 range for a v1 that produces charts you’d show a client.

    Then it never stops. The same modeling puts ongoing maintenance at 20% to 30% of the original build cost annually, and broader research finds that maintenance consumes more than half of a system’s lifecycle cost, with some platform engineering estimates putting it at 70% to 80% of lifetime cost.

    Your real recurring bill isn’t tokens. It’s an engineer, every month, forever.

    Why a Self-Built GEO Rank Tracker Drifts Out of Sync Within a Quarter

    This is the failure mode that turns a working tracker into a decorative one, and it has nothing to do with code quality.

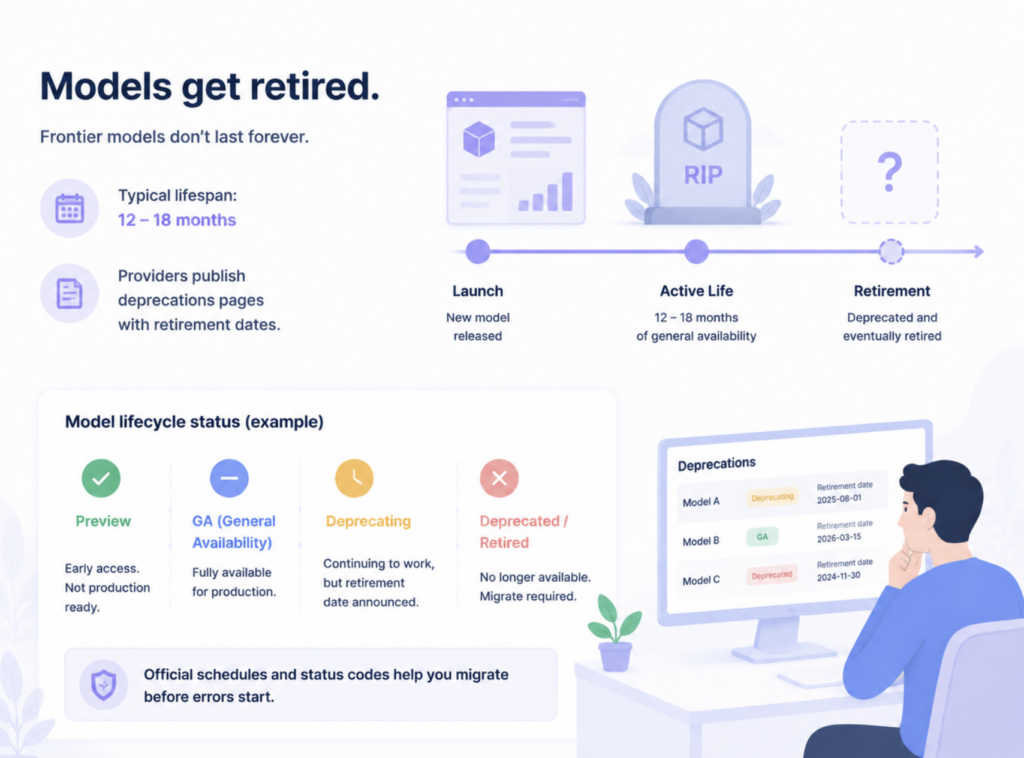
    Models get retired. Providers typically give a frontier model a lifespan of roughly 12 to 18 months before deprecating it, and every provider maintains a running deprecations page with retirement dates attached. Microsoft’s Foundry documentation goes further, publishing a formal model retirement schedule and lifecycle status codes so integrations can be migrated before they start returning errors.

    When the model under your tracker changes, your baseline changes with it. The visibility drop you see in month five might be a real competitive loss, or it might be the new model version. You have no way to tell them apart, because the only control you had was the model itself.

    Answers are also conditioned on who’s asking. A cross-provider audit of persona conditioning sampled 2,000 runs across ten personas and found that the same prompt produces materially different recommendation sets depending on the buyer context the model infers, with the effect concentrated in mid-market. If your tracker issues every query as a context-free string, it’s measuring one narrow slice of reality and reporting it as the whole picture.

    The compounding problem is that once your time series breaks, every dollar you already spent producing it loses its analytical value. You don’t get to compare Q1 to Q3.

    DIY GEO Rank Tracker vs. Managed Platform: The 12-Month Numbers

    Put the two paths side by side over a first year, using conservative figures on the build side.

    Cost lineBuild it yourselfManaged platform
    Initial engineering$25,000 to $60,000$0
    LLM and SERP API spend$700 to $2,000/yearIncluded
    Maintenance and rework20% to 30% of build cost annuallyIncluded
    Model migration workRecurring, unpredictableHandled upstream
    Engine coverageWhatever you wire up and maintainMulti-engine by default
    Metrics producedMention counts, maybe positionVisibility, sentiment, position, volume, mentions, intent, CVR
    Citation-level source dataUsually skippedBuilt in
    Historical continuityBreaks on model or vendor changeMaintained across versions
    Year-one totalRoughly $32,000 to $95,000$1,188 to $2,388

    For reference on the right-hand column, Topify prices its Basic plan at $99 a month with 100 tracked prompts and 9,000 AI answer analyses, and Pro at $199 a month with 250 prompts and 22,500 analyses. Full pricing sits on the Topify pricing page.

    The gap isn’t close. It’s roughly 15x to 40x, and the DIY column buys you fewer metrics.

    When Building Your Own GEO Rank Tracker Actually Makes Sense

    Buying isn’t automatically correct, and pretending otherwise would be dishonest. Three situations justify the build.

    You’re doing research, not marketing. If the output is a paper or an internal study rather than a monthly report, you need methodological control that no vendor will expose. Custom sampling designs, specific model versions, controlled persona variables.

    You already have the infrastructure. If your team runs data pipelines with scheduling, storage, and observability already solved, the marginal cost of one more pipeline is much lower than the numbers above suggest.

    Your entities aren’t standard. Tracking internal product codenames, regulated terminology, or a private corpus alongside public AI answers is genuinely outside what a general platform handles.

    Three signals point the other way. If nobody on the team owns the tracker as a named responsibility, it will rot. If the output has to be client-facing within a quarter, you’ll ship a prototype and present it as data. And if you can’t articulate your sampling design in one sentence, you’re not building a measurement system. You’re building a screenshot generator.

    What You’re Buying When You Skip the Build

    The thing worth paying for isn’t the dashboard. Dashboards are the easy part, and an engineer can produce a passable one in a week.

    What’s hard is consistent measurement methodology maintained across model changes, plus the historical continuity that makes any of it comparable over time. That’s the part a self-built tracker loses first and notices last.

    For teams tracking visibility across multiple engines, Topify covers the seven-metric picture in one place: visibility, sentiment, position, volume, mentions, intent, and CVR across ChatGPT, Gemini, Perplexity, DeepSeek, and other major engines. In practice, that means you can spot a mention drop in one engine and trace it to a specific source domain that stopped citing you, without joining three tables by hand.

    Two capabilities in particular tend to be the ones DIY builds never reach. Competitor benchmarking runs the same prompt set against rivals automatically, so position is measured relative to a live set rather than against your own history. And citation analysis reverse-engineers which exact domains and URLs the engines are pulling from, which is the difference between knowing your visibility fell and knowing which publication to pitch next.

    There’s also a prompt discovery layer that surfaces high-volume queries in your category as recommendations shift, which is the research problem from section two, handled as a feature rather than a quarterly manual exercise.

    You can start with Topify on a single project and validate the data against whatever spot checks you’d run manually.

    Conclusion

    Go back to that first spreadsheet. The token math was right, and it was also measuring maybe 3% of the total cost of a working GEO rank tracker. The other 97% is engineering time you can’t invoice, sampling design that determines whether your numbers mean anything, and continuity that breaks the first time a model gets deprecated.

    If you’re a research team with infrastructure and a methodology to defend, build it. If you need a number your CMO can act on next month, the honest comparison isn’t $150 a month versus $199 a month. It’s $32,000 versus $2,400, with fewer metrics on the expensive side.

    Run the 12-month table with your own loaded engineering cost before the next planning cycle. The answer usually stops being ambiguous once the FTE line is in the sheet.

    FAQ

    Q: What’s the realistic minimum monthly API cost for a DIY GEO rank tracker? 

    A: For 100 prompts across four engines checked weekly at a single run each, roughly $55 to $125 a month. Once you add the paraphrase and repetition sampling that makes the data statistically meaningful, expect that figure to multiply 15x to 30x, landing between $1,000 and $2,000 a year.

    Q: How many runs per prompt do I need before the data is reliable? 

    A: Research points to 60 to 100 runs per prompt per platform for stable visibility percentages. But repetition alone hits diminishing returns fast, and reliability improves more from varying paraphrases and models than from repeating a single prompt.

    Q: Can I just track ChatGPT and skip the rest? 

    A: You can, and it’s the cheapest path since it needs only one clean API. The tradeoff is that brand recommendation sets differ meaningfully across engines, so a single-engine tracker reports one slice of your visibility as though it were the whole number.

    Q: Can I migrate data from a self-built tracker into a platform later? 

    A: Partially. Raw answer logs usually import fine as historical reference, but computed metrics rarely reconcile, because your scoring logic and the platform’s won’t share definitions. Most teams treat the switchover as a new baseline rather than a continuous series.

    Read More

  • Most GEO Rank Trackers Are Measuring the Wrong Thing

    Most GEO Rank Trackers Are Measuring the Wrong Thing

    Two GEO rank trackers, same brand, same week. One says you’re second in your category. The other says fourth. Neither number matches what happens when you open ChatGPT and ask the question yourself five times, where your brand shows up twice and gets skipped three times.

    The dashboards aren’t broken. They’re reporting a metric borrowed from SERP tracking and applied to a system that doesn’t behave like a SERP. Before you argue about which tool is more accurate, it’s worth asking what “rank” is supposed to mean here in the first place.

    What Your GEO Rank Tracker Means When It Says “Rank 3”

    Open three GEO rank tracking products and you’ll find at least three definitions of the same word.

    Some tools count the order your brand appears in the answer text. Others average your position across a prompt set and report a weighted score. A third group ranks the citation panel, meaning your “rank” is really the position of a URL in a source list that most readers never open.

    These produce different numbers from the same underlying answer. That’s not a rounding problem. It’s a definitional one, and it means cross-tool comparison is meaningless until you know which layer each vendor is counting.

    Here’s the thing: none of those three definitions tells you the number your CMO actually asked for, which is how often the brand appears at all.

    The Ranking and Mention Gap Most GEO Rank Trackers Never Show

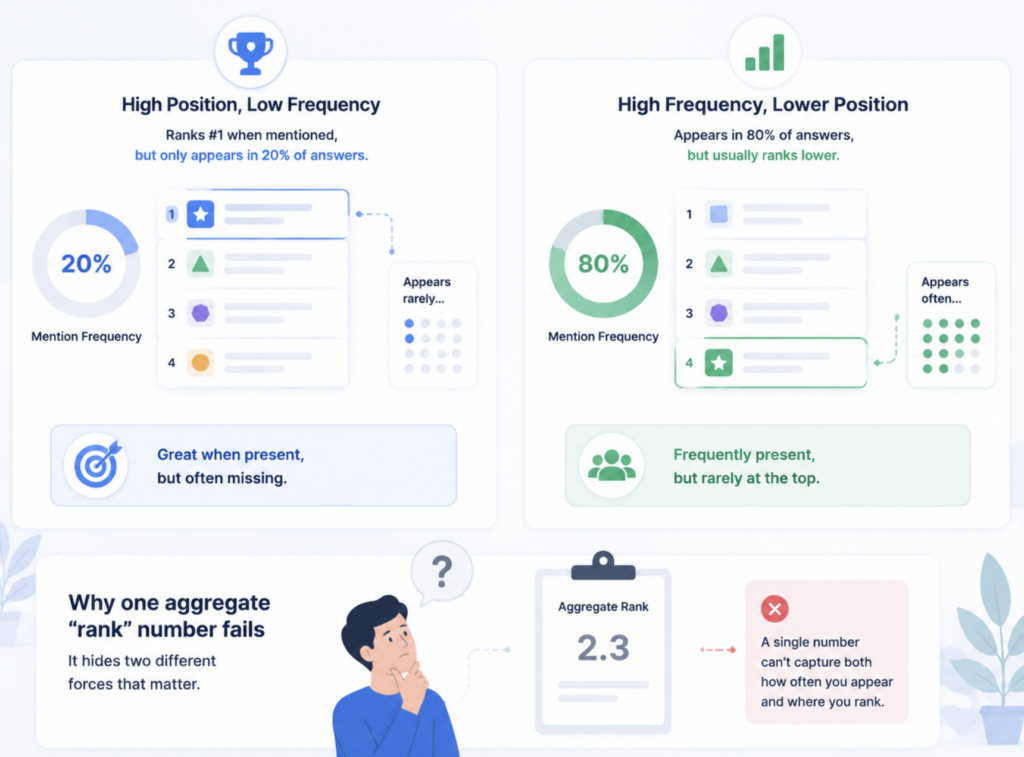
    Position and mention frequency are separate phenomena. A brand can rank first every time it appears and still appear in only a fifth of relevant answers. Another can appear in most answers and land consistently in fourth place. One aggregate “rank” number flattens both into something that describes neither.

    Onely documented a law firm holding the top Google position for a competitive local query while receiving zero ChatGPT mentions. Traditional ranking authority was intact. Presence in the answer was zero.

    The retrieval data explains why. Ahrefs ran 15,000 long-tail queries through Google and Bing, then asked the same questions to four AI assistants, and found that on average only 12% of links cited by ChatGPT, Gemini, and Copilot appear in Google’s top 10 for the same prompt. Perplexity was the outlier at roughly one in three.

    Short-tail queries don’t close the gap either. In a separate Ahrefs study of about 3,000 short-tail terms, ChatGPT’s URL overlap with Google’s top 10 sat at 10%, while Perplexity hit 65%.

    Rank tells you how you’re described once you’re in the answer. Mention rate tells you whether you’re in the room.

    Both matter, and they move independently. Conflating them is the single most common measurement error in AI search rank tracking today.

    AI Answers Don’t Have a Position One. They Have a Sentence Order.

    A SERP position is discrete, stable, and reproducible. Ask Google the same thing twice and you get the same ten results. Ask an AI assistant the same thing twice and the brand order can change without anything about your brand changing.

    This isn’t a minor caveat. A 2026 variance-components study of non-determinism in LLM brand answers found that brand-ranking reliability sits near 0.01 for a single answer, rising to only about 0.36 across a fully crossed design spanning repeats, paraphrases, models, and languages.

    Read that again. A single-sample rank number carries almost no signal.

    The same paper found that pure within-prompt resampling accounts for 34.8% of total variance, and that adding a sixth repeat of the same prompt reduces relative-error variance by roughly 0.0003. Sampling more languages and more models buys reliability. Hammering the same prompt does not.

    Most GEO rank trackers don’t disclose their sampling design at all. No repeat count, no paraphrase set, no model coverage. You’re handed a decimal point with no confidence interval attached, and then asked to make budget decisions with it.

    There’s a related credibility problem worth naming. A practitioner discussion cited in Onely’s analysis argues that a large share of GEO trackers run on scraper plus API pipelines rather than the consumer product itself, producing results that diverge meaningfully from what real users see. Whether that estimate holds across every vendor, the underlying question stands: ask your provider what exactly they’re querying.

    Four Blind Spots in Most GEO Rank Tracking Setups

    Blind Spot 1: Single-Platform Coverage

    Plenty of tools still report a rank that means “your position in ChatGPT.” As of May 2026, ChatGPT held 53.9% of worldwide AI assistant web visits, with Gemini at 27.9% and Claude at 9.2%. Roughly half your audience is being asked about by engines your tracker never touches.

    Blind Spot 2: Keyword Input Instead of Prompt Input

    A keyword is a lookup. A prompt is a request with intent, constraints, and phrasing baked in. Tools that convert keywords into synthetic prompts are measuring a query nobody typed.

    Blind Spot 3: No Sentiment Layer on the Position

    Appearing third with a strong recommendation beats appearing first as a hedged alternative. Gartner projects that 30% of brand perception will be shaped by generative AI, which makes the framing of a mention a reputation metric, not a nice-to-have.

    Blind Spot 4: No Citation Attribution Behind the Rank

    A rank change without a source explanation isn’t actionable. Citation concentration is severe: an analysis of 1,000 AI Overviews found the top 1% of cited domains capture 47% of all citations. When your position drops, the cause usually lives in that source layer.

    What the tracker showsWhat’s actually happeningDecision risk
    “Rank 2 in ChatGPT”One engine, one sample, unknown repeat countOptimizing for a number with near-zero reliability
    “Visibility score 68”Composite of mention rate and position, undisclosed weightsCan’t tell whether to fix presence or framing
    “Rank improved 3 spots”Sentence order shifted, mention rate flatReporting a win that didn’t change reach
    “Cited in 12 answers”No sentiment attachedMissing negative or hedged framing entirely

    What a GEO Rank Tracker Should Measure Instead

    Five layers, aligned to the same prompt set, sampled on a disclosed schedule. Anything less and you’re guessing.

    LayerThe question it answersWhat breaks without it
    Mention rateDo we appear at all, and in what share of runs?Position looks fine while reach collapses
    PositionWhen we appear, where in the answer?Can’t tell a recommendation from a footnote
    SentimentHow are we framed relative to competitors?High visibility, low persuasion, no explanation
    Citation sourceWhich domains fed this answer?Every change is unattributable
    Prompt volumeHow many people actually ask this?Optimizing for prompts nobody uses

    The alignment matters as much as the metrics. Five numbers pulled from five different prompt sets can’t be cross-referenced, which is exactly why so many teams end up with a full dashboard and no diagnosis.

    One more design point from the variance research: reliability comes from spreading samples across models and languages, not from repeating one prompt. Any GEO rank tracker that scales cost by repeat count instead of coverage has its incentives pointed the wrong way.

    Reading a GEO Rank Tracker That Reports Both Layers

    The practical requirement is simple to state and harder to buy. You need mention rate and position reported side by side, on the same prompts, across the engines your buyers actually use, with the citation trail attached.

    Topify was built around that separation. Its analytics layer tracks seven metrics in parallel, including visibility, position, mentions, sentiment, volume, intent, and CVR, so a drop in one is legible against the others rather than averaged into a single score.

    In practice that changes the workflow. You notice mention rate falling in Gemini while position holds steady in ChatGPT, open the citation view to see which domains stopped referencing your brand, and check whether a competitor picked up those same sources. Presence problem, framing problem, and source problem are three different fixes, and the platform is structured so you can tell which one you have. Coverage spans ChatGPT, Gemini, Perplexity, DeepSeek, Doubao, Qwen, and others, which matters for teams whose audience isn’t concentrated in a single English-language engine.

    Sampling depth is a budget line, not a feature toggle. The entry plan runs $99 per month with 100 tracked prompts and 9,000 AI answer analyses, which is roughly what a statistically meaningful design costs once you stop taking single samples seriously.

    Audit Your Current GEO Rank Tracker in One Afternoon

    You don’t need a new vendor to find out whether your current numbers hold up.

    Step one. Pick 10 prompts that reflect real buying questions in your category. Category prompts, comparison prompts, and alternative prompts, not keywords.

    Step two. Run each one three times in the consumer app, not the API, across at least two engines. Log two things per run: did your brand appear, and in what order.

    Step three. Calculate mention rate as appearances divided by total runs. Calculate mean position using appearances only. You now have the two numbers separated.

    Step four. Compare against your tracker’s reported figure for the same week. A gap under 10 percentage points on mention rate is tolerable. Anything past 20 means the tool is modeling a version of the answer your customers don’t see.

    Step five. Ask your vendor three questions: how many samples per prompt, which engines and interfaces, and whether the reported rank counts answer text or the citation panel. Vendors who can’t answer plainly are telling you something.

    If you’d rather run the comparison against a platform that separates the layers by default, you can start a project in Topifyand point it at the same 10 prompts.

    Conclusion

    The disagreement between your two dashboards isn’t a data quality issue. It’s a category error. Rank was designed for a medium with fixed positions, and AI answers don’t have those. Until your GEO rank tracker reports mention rate and position as separate lines, on disclosed sampling, across the engines your buyers use, you’re optimizing against a number that can move for reasons that have nothing to do with your brand.

    Start by splitting the two metrics in your own reporting this month. The diagnosis usually becomes obvious once they stop being averaged together.

    FAQ

    Q: What’s the difference between a GEO rank tracker and a traditional SEO rank tracker? 

    A: An SEO rank tracker reports a fixed, reproducible position in a result list. A GEO rank tracker samples probabilistic answers, so its output is a statistical estimate rather than a lookup. The methodological consequence is that sampling design determines accuracy, which is why disclosed repeat counts and engine coverage matter more than dashboard polish.

    Q: How often do AI search rankings actually change? 

    A: Frequently enough that a single sample is unreliable. Variance research places brand-ranking reliability near 0.01 for one answer, meaning order can shift between two runs of the identical prompt with no change to your brand. Weekly sampling captures volatility; monthly aggregation gives a more stable directional read.

    Q: How many prompts do I need before the numbers mean something? 

    A: Most practical setups start at 15 to 30 prompts covering category, comparison, alternative, and use-case intents, sampled multiple times across at least two engines. Coverage across engines and phrasings buys more reliability per dollar than repeating a single prompt.

    Q: My brand ranks first but gets mentioned rarely. What should I fix? 

    A: That’s a presence problem, not a positioning one, and it usually traces to the source layer. Off-site coverage drives the majority of early-stage brand mentions, so the fix tends to be earning references in the listicles, comparison pages, and review roundups that AI engines retrieve from, rather than editing your own product pages.

    Read More

  • We Ran One Prompt 500 Times. Here’s What a GEO Rank Tracker Sees

    We Ran One Prompt 500 Times. Here’s What a GEO Rank Tracker Sees

    You checked ChatGPT three times last week to see whether your brand came up in your category. First run, you were there. Second run, gone. Third run, you were back but listed fourth instead of second.

    So which number goes in the monthly report? That question is the entire problem with treating AI search like a ranking board, and it’s the reason a GEO rank tracker has to work differently from anything in your SEO stack.

    The Setup: One Prompt, 500 Runs, Five Engines

    We took a single high-intent commercial prompt, the kind a real buyer types when they’re two weeks from a purchase decision, and ran it 100 times each across ChatGPT, Gemini, Perplexity, Claude, and Google AI Overviews. Same wording. Same day. No personalization, no session history.

    For every response we logged three things: whether the target brand appeared at all, where it sat in the ordering when it did appear, and which domains got cited underneath.

    The point wasn’t to measure one brand. It was to answer a more basic question: does “rank” survive contact with a system that generates a fresh answer every time?

    The short version is that it survives, but not in the shape most teams assume.

    A Single Check Isn’t a Rank. It’s an Anecdote

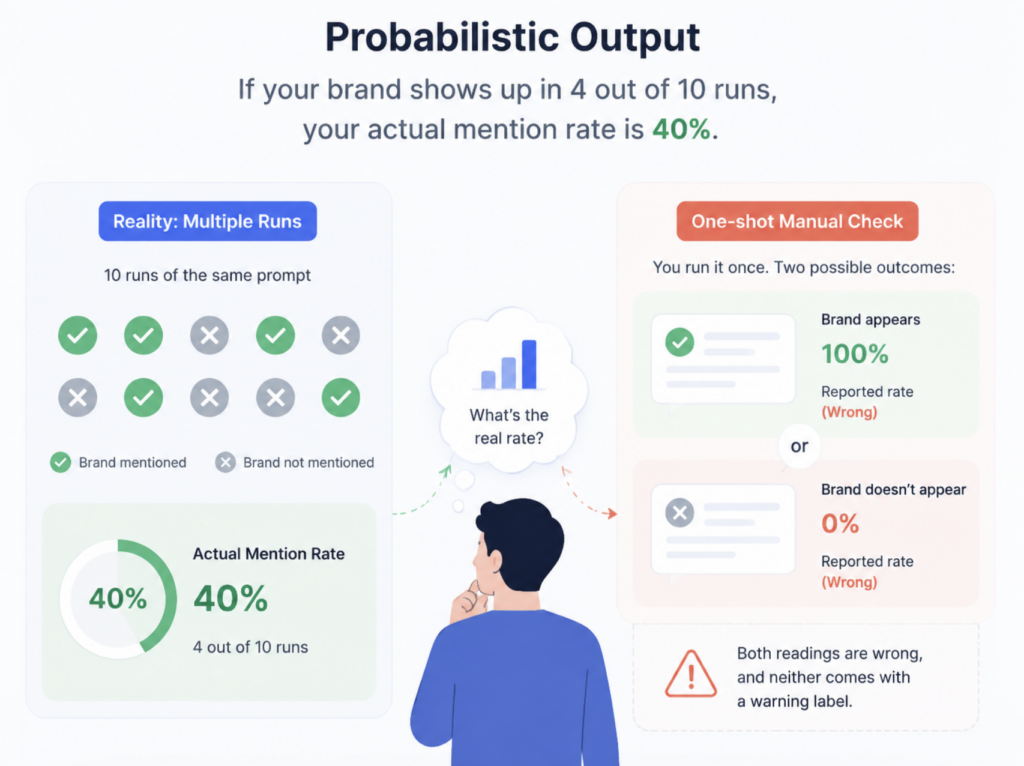
    Here’s the thing about probabilistic output. If your brand shows up in 4 out of 10 runs, your actual mention rate is 40%. A one-shot manual check reports either 0% or 100% depending on which run you happened to catch. Both readings are wrong, and neither comes with a warning label.

    This isn’t a quirk you can configure away. Even at temperature zero, the same prompt can produce different outputs across runs because of floating-point non-associativity combined with dynamic batching on the inference side. Variance is baked into the infrastructure.

    The measurement layer inherits that. As iPullRank puts it in their AI search manual, share of voice in generative search is a statistical distribution of presence over many trials, not a static percentage of positions held.

    One check is not a data point. It’s a coin flip you wrote down.

    The instability compounds over time, too. Independent analyses suggest 40 to 60% of AI citations rotate every month for mid-sized B2B brands, and that 73.4% of specific URLs get cited exactly once before vanishing from AI answers entirely.

    Mention Rate Moved a Lot. Position Barely Did.

    This was the finding that changed how we read the data.

    Across the 500 runs, whether the brand appeared swung far more than where it appeared. On three of the five engines, mention rate moved by double digits between the first 50 runs and the second 50. But in the runs where the brand did appear, its ordinal position clustered tightly, usually within a single slot of its median.

    Two different signals. Two different failure modes. Most dashboards collapse them into one number called “rank” and lose both.

    There’s academic backing for the split. Research on the structural gap between search engine and generative AI brand visibility found that traditional SEO strength predicts a brand’s ranking position inside an AI answer reasonably well, but predicts its mention frequency poorly. Being strong enough to get listed and being retrieved often enough to get listed are governed by different mechanics.

    Semrush’s study of 1,094 subject areas in ChatGPT points the same direction from another angle. Only 21% of the most-cited domains in a category were also the most-mentioned brand, and the two signals correlate slightly negatively at -0.229.

    That matters operationally. If your mention rate is falling but your position holds, you have a retrieval problem and you need more citable surface area. If your mention rate is stable but your position slides, you have a framing problem and competitors are being described as the better fit.

    Same “rank drop.” Opposite fixes.

    Five Engines, Five Different Answers to the Same Question

    Run-to-run variance was real. Cross-engine variance was bigger.

    The gap between what ChatGPT said and what Perplexity said, given identical input, exceeded the gap between any single engine’s best and worst run. That tracks with the published research. One analysis of 50 buyer-intent prompts found that ChatGPT, Perplexity, and Gemini named the same brand only 21% of the time, with over half of all brand mentions coming from just one engine.

    The citation layer diverges even harder. Across 680 million AI citations analyzed in early 2026, only 11% of domains were cited by both ChatGPT and Perplexity. Yext’s look at 6.8 million citations found very little overlap in what each model cites, with each engine weighting source types on its own logic.

    So tracking one engine isn’t partial coverage. It’s a systematic bias, and it points in a direction you can’t predict from the engine you did measure.

    The corollary is worse for reporting: a blended cross-engine average hides exactly the thing you’d act on. A brand at 60% on Gemini and 5% on ChatGPT averages to a perfectly unremarkable 32%.

    What This Means for Your GEO Rank Tracker

    Work backward from the variance and the tool requirements write themselves.

    RequirementSingle-check approachSampling-based GEO rank tracker
    Sample size1 run per promptDozens of runs per prompt, reported as a rate
    Metric structureOne blended “rank” scoreMention rate and position tracked separately
    Engine coverageOne engine, extrapolatedEach engine reported independently
    CadenceMonthly or ad hocWeekly minimum, daily for volatile categories
    Competitor contextAbsentSame prompt set, same sampling, side by side

    Search Engine Land’s overview of the category makes the same point about methodology: variable outputs mean tracking requires consistent monitoring and statistical sampling rather than spot checks.

    Cadence deserves its own note. Monthly monitoring is effectively no monitoring when citation sets turn over at 40 to 60% in that same window. By the time you see the change, you can’t attribute it to anything.

    And frequency without competitor context still leaves you blind. If your citation rate holds flat at 15% while a rival climbs from 10% to 40%, your number didn’t move but your share collapsed.

    Where Topify Fits

    The reason we ran this test at all is that it maps directly onto how measurement should be built.

    Topify reports seven metrics separately rather than folding them into a single score: visibility, sentiment, position, volume, mentions, intent, and CVR. Visibility answers how often you appear across a defined prompt set. Position answers where you land when you do. Keeping them apart is what makes the mention-versus-position diagnosis possible in the first place, and it’s the difference between knowing your number dropped and knowing why.

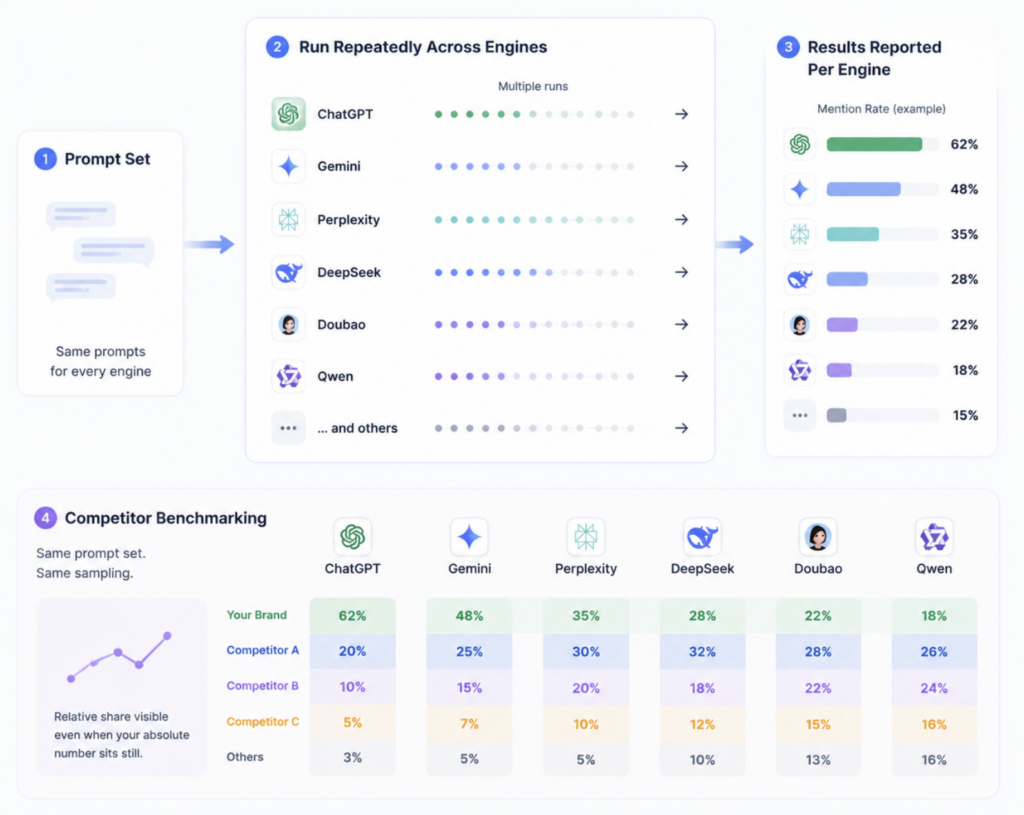
    Each prompt runs repeatedly across ChatGPT, Gemini, Perplexity, DeepSeek, Doubao, Qwen, and others, with results reported per engine instead of averaged into a single figure. Competitor benchmarking runs on the same prompt set and the same sampling, so relative share is visible even when your absolute number sits still.

    The citation reverse-engineering layer closes the loop. Seeing which exact domains and URLs each engine pulls from tells you where the retrieval gap lives, which is the actionable half of a falling mention rate. Our earlier breakdown of how a GEO rank tracker measures AI search position covers the metric definitions in more depth.

    Plans start at $99/month with 100 tracked prompts and 9,000 AI answer analyses, which is roughly the sampling volume this kind of question requires. You can get started with Topify on a 30-day trial.

    How to Read Your Own Rank Data Without Fooling Yourself

    Four habits separate teams who act on AI search data from teams who argue about it.

    Track prompt sets, not keywords. Buyers ask several related questions on the way to a decision, and winning one of them isn’t the same as owning the topic. Visibility that looks strong on a single prompt often thins out across the cluster.

    Read trend bands, not points. A 5-point week-over-week move on a sampled rate is usually noise. A 5-point move sustained across four weeks is a trend. Set that threshold before you look at the data, not after.

    Plot competitors on the same axis. Absolute visibility without relative share tells you almost nothing about whether you’re winning.

    Separate “absent” from “present but ranked low.” They look identical on a summary dashboard and they need completely different responses.

    Sample enough. Split the metrics. Check every engine.

    Conclusion

    Rank didn’t disappear when search became generative. It changed units. It stopped being a position you hold and became a probability you occupy, which means the number is only meaningful attached to a sample size.

    The three checks you ran in ChatGPT last week weren’t wrong. They were just three draws from a distribution you hadn’t measured yet. A GEO rank tracker built on repeated sampling, separated metrics, and per-engine reporting turns those draws into something you can put in a report and defend.

    Start by defining the ten prompts your buyers actually ask. Everything else follows from having a stable set to sample against.

    FAQ

    Q: How many times does a prompt need to run before the result is trustworthy? 

    A: Dozens, not a handful. The practical floor is enough runs that a single outlier can’t move the rate by more than a point or two. Most sampling-based platforms run each prompt many times per cycle for exactly this reason, and any tool reporting a rank off one query is reporting an anecdote.

    Q: Which matters more, mention rate or position? 

    A: Mention rate, in most cases. A brand that never appears can’t benefit from good placement. Once you’re appearing consistently, position becomes the lever that affects which option the buyer actually picks.

    Q: Can I just track ChatGPT and assume the rest follow? 

    A: No. Cross-engine agreement on brand recommendations runs around 21%, and domain-level citation overlap between major engines sits near 11%. Single-engine tracking produces a biased read in an unpredictable direction.

    Q: How often do AI rankings actually change? 

    A: Faster than SEO rankings. With a large share of citations rotating monthly, weekly tracking is the minimum viable cadence, and competitive categories often warrant daily sampling.

    Read More

  • Prompt Search for E-Commerce: How Shoppers Use AI to Find Products

    Prompt Search for E-Commerce: How Shoppers Use AI to Find Products

    Your product page ranks third for its main category term. The feed is clean, reviews are strong, and paid shopping sends steady traffic every week. Then someone opens ChatGPT and types “durable carry-on under $200 that actually fits budget airline sizers,” and gets five specific recommendations. Yours isn’t one of them.

    Nothing broke. The shopper just asked a question your keyword strategy was never built to answer. That’s prompt search, and in a growing number of categories it’s where product discovery now starts.

    Prompt Search Isn’t Keyword Search With More Words

    Keyword search asks the shopper to translate a need into terms a machine already indexes. “Running shoes men.” “Carry-on luggage.” The engine returns a list, and the shopper does the filtering.

    Prompt search flips who does the work. The shopper states a goal with constraints attached, and the system does the sorting before anything reaches the screen.

    Google’s own framing is that people now interact using conversational language, not keywords, and expect the system to read intent rather than match strings. Google’s search leadership has described seeing two, three, or four-sentence querieswhere people explain a problem instead of naming a product.

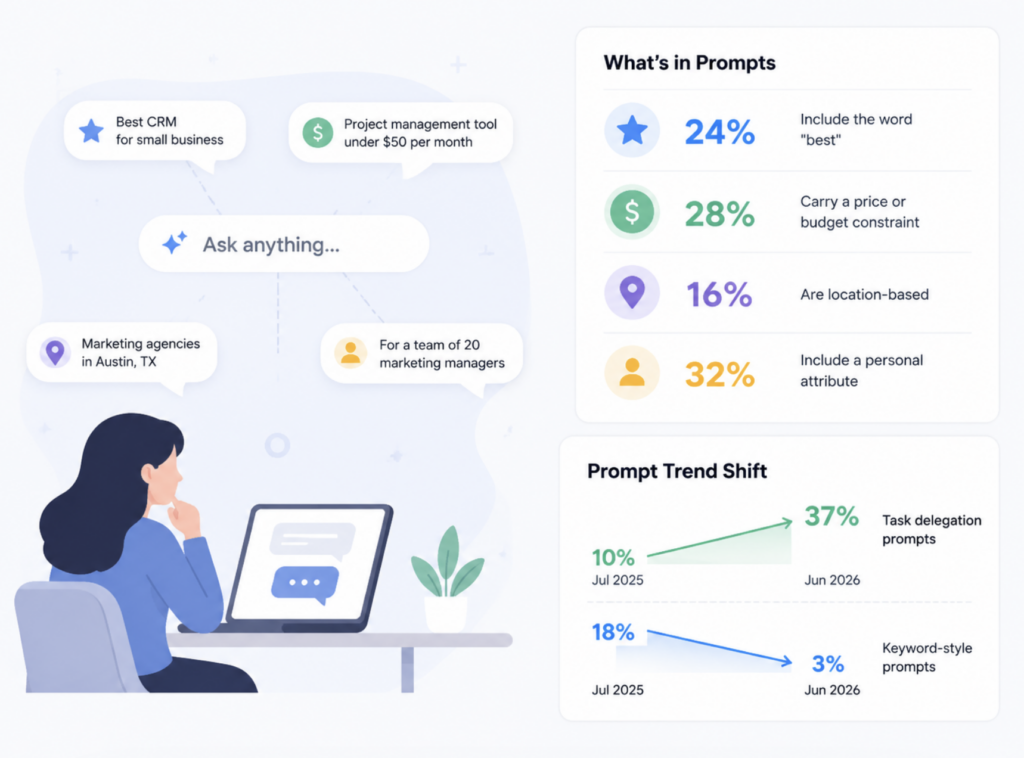
    The gap this creates is measurable. Semrush found that 65% to 85% of ChatGPT prompts have no matching keyword in its keyword database at all.

    That’s not a long-tail problem. It’s a coverage problem, and most keyword tools can’t see it.

    DimensionKeyword searchPrompt search
    Input2 to 4 termsGoal plus constraints, often a full sentence
    Who filtersThe shopperThe model
    Output10 links plus ads3 to 8 products, one synthesized recommendation
    What winsRanking positionBeing selected as evidence
    Measurable byRank trackersPrompt-level monitoring

    Shoppers Bring Constraints and Feelings, Not Keywords

    Here’s the thing about how people actually write shopping prompts: they’re shorter than most marketers assume, and more personal.

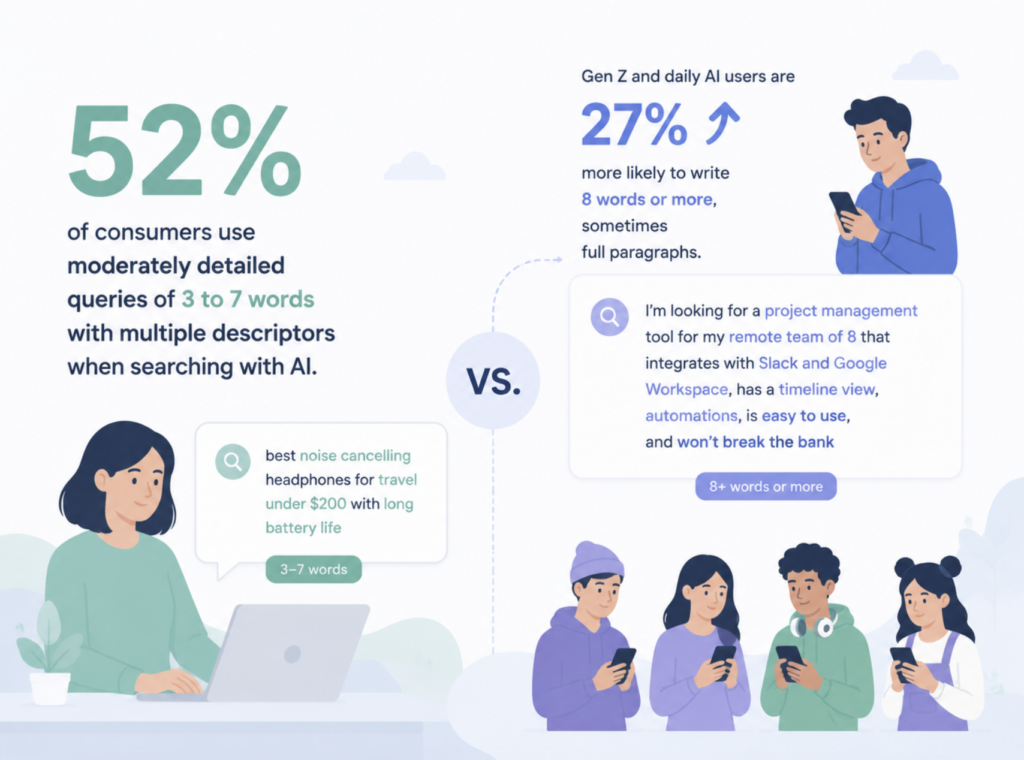
    Klaviyo’s consumer research found that 52% of consumers use moderately detailed queries of 3 to 7 words with multiple descriptors when searching with AI. Gen Z and daily AI users are 27% more likely to write 8 words or more, sometimes full paragraphs.

    The bigger shift is context. Klaviyo found 78% of people include emotional or personal context at least some of the time, asking for “something to cheer me up” or “a gift that feels thoughtful” rather than naming a product category.

    That’s goal-based shopping. The shopper describes the outcome and lets the model reverse-engineer the product.

    There’s a counterintuitive wrinkle worth knowing. A 2026 study covered by Search Engine Journal found that concise, keyword-style prompts produced more brand mentions than persona-heavy conversational ones, and that adding budget or feature constraints reduced the number of brands shown in ChatGPT and Perplexity while increasing it in Gemini and AI Overviews. Filler words changed nothing.

    So the constraint is the moment of truth. “Under $200” and “fits budget airline sizers” are exactly where products get screened out, and they’re the attributes most product pages state vaguely or not at all.

    One Prompt, a Dozen Hidden Searches

    A shopping prompt rarely triggers one retrieval. It triggers query fan-out: the model decomposes the request into sub-queries, retrieves separately for each, then synthesizes.

    The carry-on prompt above probably becomes something like: budget airline sizer dimensions by carrier, best carry-on under $200, spinner wheel durability complaints, warranty comparison across luggage brands, plus a few review-aggregation queries.

    Your brand isn’t competing for the prompt. It’s competing for the sub-queries.

    This is why single-page thinking fails in AI product discovery. Most ecommerce teams have one PDP built to win the parent phrase, and nothing that answers the definitional sub-query or the objection sub-query. The model needed four answers and found yours useful for zero of them.

    Fan-out also explains why results feel unstable. Run the same prompt twice and citations shift, because retrieval is sampled rather than fixed. Checking your brand in ChatGPT once and feeling relieved is an anecdote, not a measurement.

    AI Sends Less Traffic. It Sends Much Better Traffic.

    The volume argument against prompt search is getting weaker every quarter.

    Adobe Analytics, working from more than a trillion visits to U.S. retail sites, found AI-referred traffic to retail grew 138% year over year in May 2026 and 1,324% since October 2024, when it started tracking the category. Retail led every vertical in AI visit share growth in Q1 2026.

    The quality signal is stronger than the volume signal. Adobe reported shoppers arriving from AI referrals spend 53% more time on site and browse 23% more pages per visit. By March 2026, AI traffic converted 42% better than non-AI traffic, with revenue per visit running 37% above other sources. A year earlier, that comparison ran the other way.

    Scale is already there on the query side. Roughly 2% of ChatGPT queries involve shopping, which works out to about 50 million shopping queries per day against a base of 900 million weekly users. A Semrush survey found half of U.S. shoppers have bought something after researching it with AI.

    Bottom line: prompt search is a small channel producing pre-qualified buyers, which is the profile every acquisition team says it wants.

    Why AI Picks Three Products Out of Three Hundred

    Where a Google results page gives ten links and a wall of shopping ads, an AI assistant returns three to eight products. Selection is the whole game.

    Products surface based on structured merchant feeds, crawled web content, and third-party trust signals rather than paid placement. OpenAI’s shopping research model was trained to read trusted sites and cite reliable sources, synthesizing across many of them and refining as the shopper adds constraints.

    The industry settled into a clear division of labor in 2026. OpenAI stepped back from running checkout and refocused on product discovery, with merchants keeping their own checkout under the Agentic Commerce Protocol. Google moved the same direction, letting shoppers refine a query through conversation in AI Mode with agentic checkout handled on the merchant side.

    Discovery is the layer that got automated. That’s the layer to optimize.

    Three things tend to decide selection. First, machine readability: Adobe’s content visibility scoring flags pages where a large share of the content simply can’t be parsed by a model, and a page scoring 50% has half its content invisible. Second, attribute coverage, meaning the specific constraints shoppers name are stated explicitly in your product data rather than implied by a photo. Third, corroboration, since models weight independent reviews, editorial roundups, and community discussion more heavily than your own copy.

    Turning Prompt Search Into a Channel You Can Measure

    Most ecommerce teams find out they’re invisible in AI answers by accident, usually when a founder types the category into ChatGPT and sees three competitors. The problem with that discovery method is obvious: it’s one prompt, one run, one platform, no baseline.

    Measuring prompt search properly means treating prompts the way you once treated keywords. You need a defined set, repeated sampling over time, competitor comparison in the same runs, and visibility into which sources fed the answer.

    Topify is built around that workflow. Its High-Value Prompt Discovery surfaces the prompts that actually carry volume in your category and keeps surfacing new ones as recommendations shift, which matters more in retail than in most verticals because seasonality rewrites the prompt set every quarter. Comprehensive GEO Analytics then tracks seven metrics across ChatGPT, Gemini, Perplexity, and other major engines: visibility, sentiment, position, volume, mentions, intent, and CVR.

    The citation layer is where merchandising decisions come from. Topify reverse-engineers the exact domains and URLs AI platforms cite for your tracked prompts, so when a competitor takes over a “best under $200” prompt, you can see whether it won on its own PDP, a retailer listing, or a review site you’ve never pitched.

    Dynamic Competitor Benchmarking runs alongside it, flagging emerging rivals in real time rather than at quarter end.

    Pricing starts at $99 per month on the Basic plan with 100 tracked prompts, which is roughly the size of a serious starting prompt set for a single-category store. You can get started without rebuilding anything on your side.

    Where to Start If You Sell Products Online

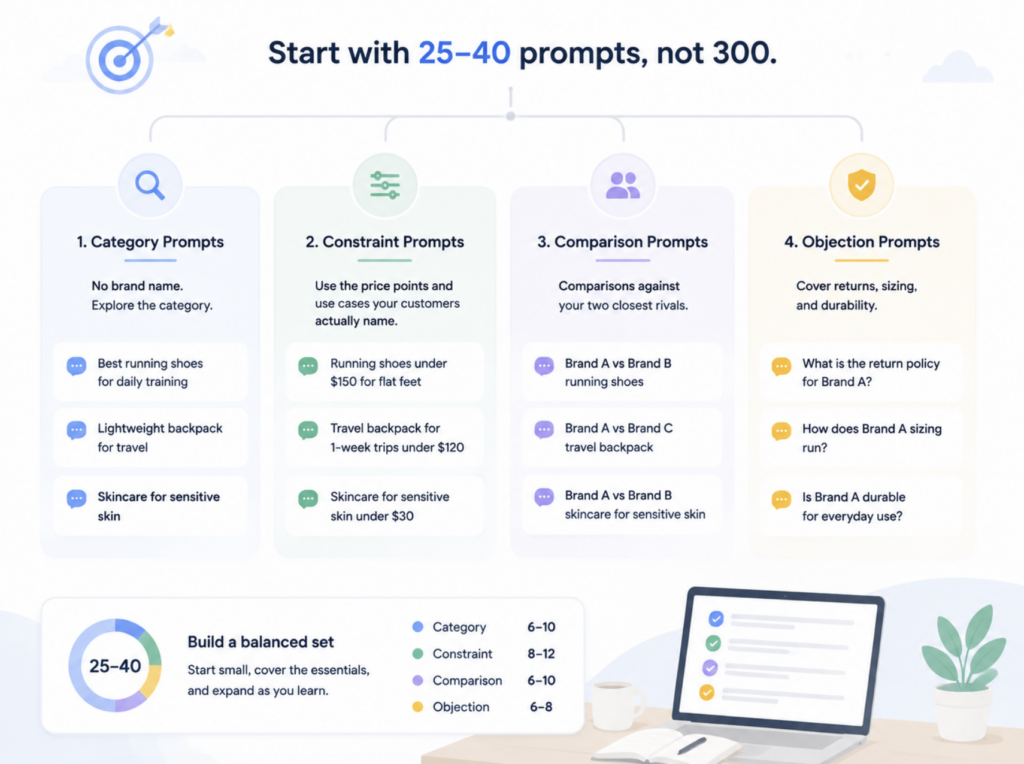
    Start with 25 to 40 prompts, not 300. Split them into category prompts with no brand name, constraint prompts using the price points and use cases your customers actually name, comparison prompts against your two closest rivals, and objection prompts covering returns, sizing, and durability.

    Run them weekly and record which brands appear, in what order, and which sources get cited.

    Then fix the readability gaps the citation data exposes. Put constraint answers in text on the page, not in images. Make sure your feed carries the attributes that show up in prompts. Get corroboration where the model already looks.

    Only 16% of brands currently track their AI search performance in any systematic way, which means the competitive bar in most categories is still low. That won’t hold for long.

    Conclusion

    The shopper who couldn’t find your carry-on didn’t reject your product. Your product never entered the consideration set, because the constraints in the prompt never matched anything readable in your data.

    Prompt search rewards a different kind of work than keyword search did. Less about ranking for terms, more about being the clearest, best-corroborated answer to a specific goal with specific limits attached. The channel is still small enough that a focused prompt set and a few weeks of citation data can move you from invisible to recommended.

    Pick 25 prompts your customers would actually type. Run them. See who’s there instead of you.

    FAQ

    Q: What is prompt search? 

    A: Prompt search is product discovery through conversational prompts in AI assistants like ChatGPT, Gemini, and Perplexity, where a shopper describes a goal with constraints and the system returns a short recommendation set instead of a page of links.

    Q: How is prompt search different from keyword search for e-commerce? 

    A: Keyword search matches terms and leaves filtering to the shopper. Prompt search interprets intent, expands the request into sub-queries through query fan-out, and returns three to eight products. Visibility depends on selection, not ranking position.

    Q: Which prompts should an ecommerce brand track? 

    A: Track four types: unbranded category prompts, constraint prompts built around real price points and use cases, comparison prompts naming your closest competitors, and objection prompts about returns, sizing, or durability. Keep branded prompts in a separate group so they don’t inflate your overall visibility numbers.

    Q: Does AI search traffic actually convert for retail? 

    A: Adobe’s 2026 data shows AI-referred retail traffic converting 42% better than non-AI traffic, with 37% higher revenue per visit and 53% more time on site. Volume stays modest relative to paid search and email, but intent runs higher.

    Read More

  • How to Track Your Brand Visibility Across Prompt Searches

    How to Track Your Brand Visibility Across Prompt Searches

    There’s a spreadsheet on your team’s shared drive with about a dozen prompts in it. Someone runs them through ChatGPT every Monday, screenshots the answers, and fills in a column marked “mentioned: yes/no.” Last week your brand showed up in four out of twelve. This week it’s two. Nobody can say whether something actually changed or whether the model just answered differently that morning. That gap is where most prompt search reporting collapses, usually right after someone in the meeting asks a follow-up question.

    Ten Prompts in a Spreadsheet Isn’t Tracking. It’s Sampling Noise.

    Manual spot-checking fails for a reason that has nothing to do with effort. AI answers are probabilistic, so the same question produces a different brand list nearly every time you ask it.

    SparkToro and Gumshoe.ai tested this directly. Running 2,961 prompts across ChatGPT, Claude, and Google’s AI surfaces, they found less than a 1-in-100 chance that the same prompt would return the same list of brands across repeated runs. Search Engine Journal

    Read that number again before you plan your next report.

    If a single run has roughly a 1% chance of reproducing itself, then a screenshot proves nothing about your position. It proves the model said something once. A company can’t credibly claim it “ranks number one in ChatGPT” based on an isolated response, which is what most internal AI visibility decks are quietly built on. Web Logix Group

    The fix isn’t more careful screenshotting. It’s changing the unit of measurement from a binary yes/no to a frequency: out of N runs of this prompt, on what percentage did the brand appear, and in what position.

    Prompt Search Isn’t Keyword Search Wearing a New Name

    A prompt search is a full natural-language question submitted to an AI system that returns a synthesized answer instead of a ranked list. That difference in output format changes what you can measure.

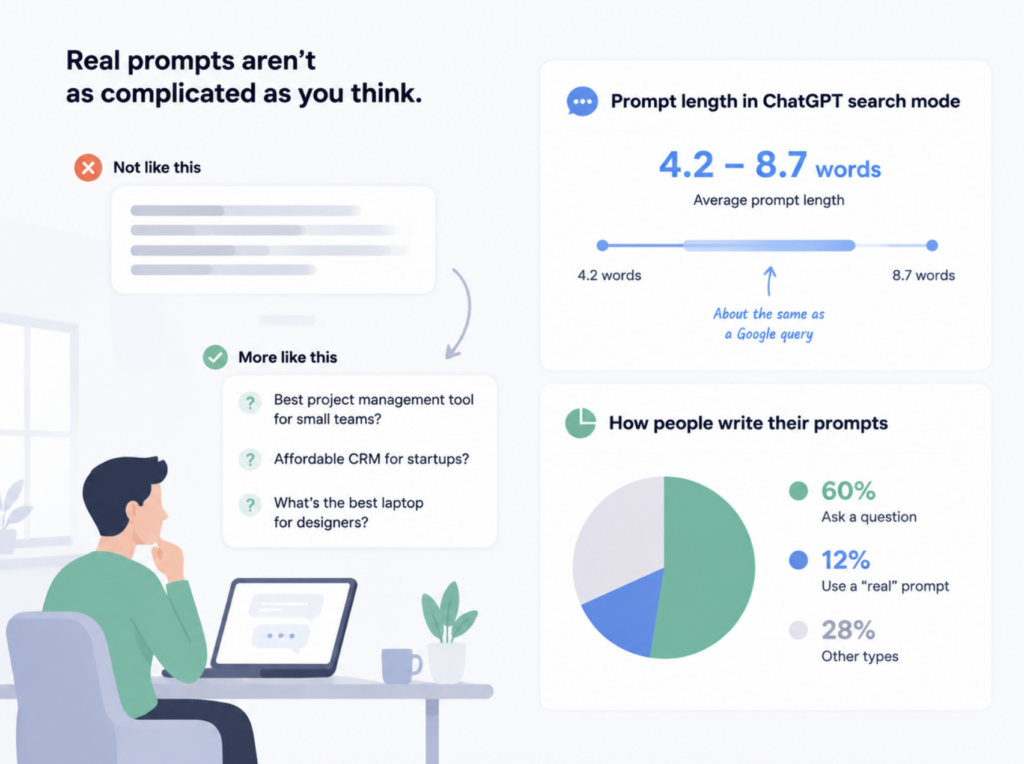
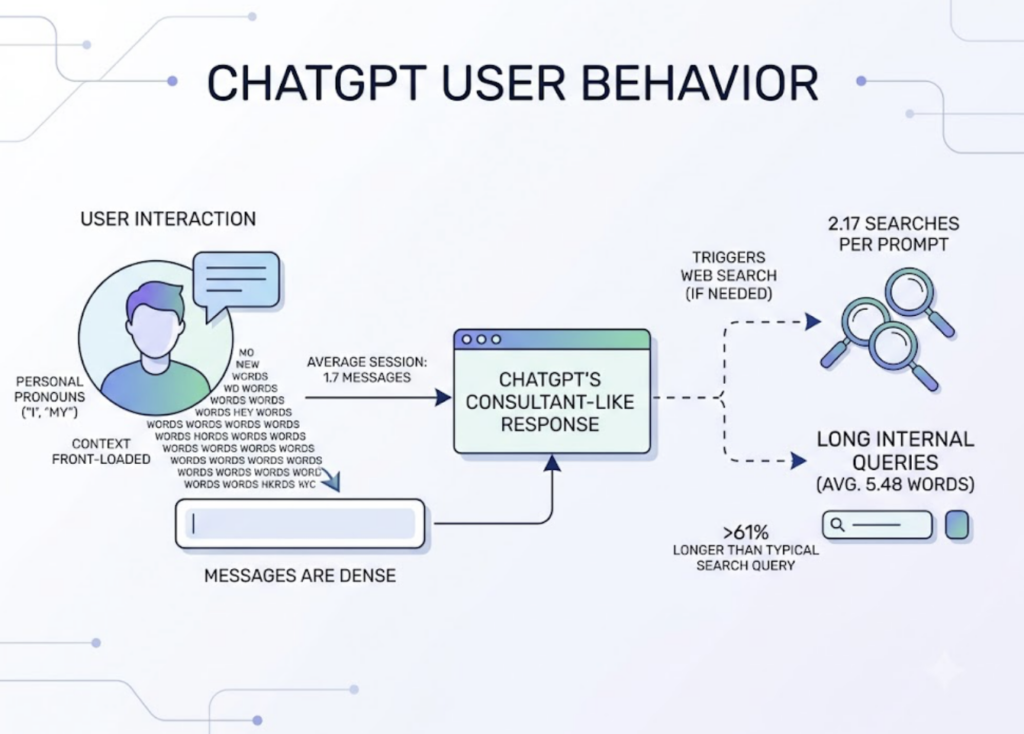
    Here’s the part most teams get backwards. Real prompts aren’t the elaborate templates you see in AI marketing threads. Semrush clickstream data puts the average prompt length in ChatGPT’s search mode at 4.2 to 8.7 words, roughly the same as a Google query. Survey work from Stella Rising found that only 12% of respondents wrote anything resembling a “real” prompt, while about 60% phrased their query as a question.

    So the prompts your buyers actually type look closer to keywords than you’d expect. The divergence happens after they hit enter.

    AI engines don’t retrieve against the string you typed. They expand it. Google’s query fan-out technique breaks one prompt into related searches across subtopics before synthesizing an answer. Research on AI Mode shows 59% of prompts trigger between five and eleven simultaneous sub-queries, with complex B2B queries averaging nine to eleven, while ChatGPT runs 2.3 to 2.8 sub-queries per prompt. Pepper

    Bottom line: one prompt search is not one query. It’s a bundle of them, and your brand has to survive the whole bundle to show up in the answer.

    Step 1: Build a Prompt Set That Matches How Buyers Actually Ask

    Start with coverage, not volume. A tracked prompt set should map to the decisions your buyers make, not to the questions that flatter your product.

    Four categories cover most of the ground:

    Prompt typeExample shapeWhat it tells you
    Category discovery“best [category] tools for [use case]”Whether you’re in the consideration set at all
    Comparison“[competitor] vs alternatives”Where you sit when a rival is the anchor
    Problem-led“how do I fix [problem]”Whether your content gets pulled into solution answers
    Brand-direct“is [your brand] any good”How AI describes you when you’re named

    Skip the brand-direct prompts as your starting point. They’re the easiest to win and the least informative, since a user who already knows your name isn’t the acquisition problem.

    The best source material is your own sales calls and support tickets. Pull the actual phrasing people use when they don’t know your category vocabulary yet. That phrasing is what feeds the fan-out.

    For scale, a set of 100 prompts tends to be enough to cover a single product line across four engines. Multi-product or multi-market brands generally need 250 or more before the coverage stops feeling arbitrary.

    Step 2: Define What Counts as Brand Visibility Before You Measure It

    Most teams measure mentions and stop. That’s the single biggest reason prompt search dashboards look impressive and change nothing.

    Visibility has three layers, and they answer different questions:

    • Mention rate. Out of N runs, how often does your brand appear at all?
    • Position. When you appear, are you first in the list or fourth? Users read AI answers top-down.
    • Citation. Which of your URLs did the engine actually pull from, if any?

    A brand can have a healthy mention rate and zero citations, which means AI knows your name but isn’t reading your content. That’s a very different problem from being absent, and it needs a different fix.

    Platform baselines matter here too. One 2026 analysis of 34,234 AI responses found ChatGPT cited brands 0.59% of the time while Perplexity sat at 13.05%. Comparing your ChatGPT mention rate against your Perplexity mention rate without adjusting for that gap will make ChatGPT look like a failure when it’s behaving normally. Leapd

    Sentiment belongs in the definition as well. Appearing in an answer that calls you “a budget option” isn’t the same win as appearing as “the enterprise standard,” even though both count as a mention.

    Step 3: Run Prompt Searches on a Schedule, Across Every Engine That Matters

    Frequency solves the variance problem. Nothing else does.

    Since a single run is close to meaningless, you need repeated sampling to turn noise into a rate. Weekly cadence works for most brands. Anything slower and you’ll miss the shifts that follow model updates or a competitor’s content push.

    Coverage solves the second problem. Engines don’t share source pools, and the overlap is far smaller than most teams assume. Analysis across hundreds of millions of citations found that only 11% of domains are cited by both ChatGPT and Perplexity, and Google AI Overviews and AI Mode cite the same URLs just 13.7% of the time. Leapd

    That means single-engine tracking isn’t a partial view. It’s a view of a different ecosystem than the one your buyer might be using.

    If you collapse everything into one blended “AI visibility score,” you lose the ability to act on it. As one analysis of citation reporting put it, collapsing all AI visibility into one number removes your ability to see where you’re winning, where you’re absent, and where competitors are taking share.

    Track per engine, per prompt, per week. Then blend for the executive summary, never for the diagnosis.

    Step 4: Trace Each Mention Back to the Source That Produced It

    A visibility number without attribution is a mood ring. It tells you how things feel this week and nothing about what to do next.

    The actionable layer is the source. When your mention rate drops on a comparison prompt, the useful question is which domain the engine cited instead, and whether that domain mentions you at all.

    This matters more now that AI citations have decoupled from rankings. In mid-2025, 76% of AI Overview citations came from top-10 organic results. By early 2026, that had fallen to 38% in Ahrefs data. Your rank report is no longer a proxy for your citation footprint. Leapd

    Practically, source tracing gives you a content backlog. If three of your competitors show up through the same industry roundup and you don’t, that roundup is a placement target. If Reddit threads are feeding an entire prompt cluster, that’s a community presence problem, not a blog problem.

    Track it. Trace it. Fix the source.

    Four Mistakes That Make Prompt Search Data Useless

    Tracking only brand-name prompts. You’ll see great numbers and learn nothing, because the people asking those prompts already found you.

    Running one engine. With roughly 11% domain overlap between major platforms, one-engine tracking leaves most of your citation landscape unmeasured. Cross-platform work has documented citation volume differences of up to 615 times for the same brand between platforms.

    Sampling once and calling it data. One run per prompt per month produces a chart that moves for reasons you can’t explain. Repeat runs are what convert a yes/no into a defensible rate.

    Stopping at the mention. A mention count tells you the score. It doesn’t tell you which play to run. Without source attribution, every optimization decision is a guess.

    What Prompt-Level Tracking Looks Like When It’s Not Manual

    Everything above is doable by hand. The math is what kills it. One hundred prompts, four engines, five repeat runs, weekly, is 2,000 answers a week to capture, parse, and classify. That’s a full-time job before anyone looks at a single insight.

    This is where a purpose-built platform earns its cost. Topify handles the sampling layer, running prompt sets across ChatGPT, Gemini, Perplexity, AI Overviews, and regional engines including DeepSeek, Doubao, and Qwen, then reporting results as rates rather than snapshots.

    The part worth paying attention to is what happens after the data lands. Topify’s analytics cover seven metrics in one view: visibility, sentiment, position, volume, mentions, intent, and CVR. So when your mention rate on a comparison prompt drops, you can check whether position slipped, whether sentiment shifted, and which cited domains changed, without exporting anything. Its prompt discovery keeps surfacing new high-volume questions in your category as buyer language moves, which is the piece a static spreadsheet can never do. Competitor benchmarking runs on the same prompt set, so you’re comparing like for like instead of guessing at rival performance.

    Pricing starts at $99/month for 100 prompts across three engines, and $199/month for 250 prompts, with details on the Topify pricing page. You can get started with a single project before committing a whole team to the workflow.

    Conclusion

    The spreadsheet isn’t wrong. It’s just built on a unit of measurement that doesn’t hold up: a single answer treated as a fact, when the underlying system produces a different answer nearly every time it’s asked.

    Fixing this takes two decisions and one habit. Decide which prompts represent real buying questions, decide whether you’re measuring mentions, position, or citations, then commit to running the set on a schedule across more than one engine. Do that for 30 days and you’ll have something you can defend in a meeting.

    Start with 20 prompts you can name a business reason for. Expand once the pattern is visible.

    FAQ

    Q: How many prompts should I track to get reliable data?
    A: Around 100 prompts covers a single product line across the four main prompt types. What matters more than the count is repeat sampling. Ten prompts run five times weekly produces better data than 50 prompts run once a month, because AI answers vary run to run.

    Q: What’s the difference between prompt search tracking and keyword research?
    A: Keyword research measures search volume for phrases that return ranked links. Prompt search tracking measures how often your brand appears inside a synthesized answer, and in what position. The two overlap in phrasing, since real prompts average under nine words in search mode, but diverge in what happens after retrieval.

    Q: How often should I run prompt searches?
    A: Weekly is the practical default. AI engines update models and refresh their retrieval indexes frequently enough that monthly data misses the changes you’d want to react to. Give any new tracking set at least 30 days before drawing conclusions.

    Q: Why does the same prompt return different brands each time?
    A: Generative systems are probabilistic, and personalization adds session context, location, and history on top. Research on repeated brand recommendation prompts found the same list reappears less than 1% of the time. This is why prompt-level visibility should be reported as a percentage across runs, not as a single result.

    Read More

  • Prompt Search Optimization: How to Get Your Brand Cited in AI Answers

    Prompt Search Optimization: How to Get Your Brand Cited in AI Answers

    Most teams start prompt search work the same way. Someone exports the keyword list, pastes the top 20 terms into ChatGPT one at a time, screenshots the answers where the brand shows up, and calls it a baseline. Two weeks later the same 20 prompts return different answers, different competitors, different sources, and nothing in the report explains what moved.

    The data isn’t broken. The method is. A keyword list was never a prompt list, and one run was never a measurement.

    Your Keyword List Isn’t a Prompt Search List

    The first gap is linguistic. The average prompt runs about five times longer than a classic search keyword, which means the odds of two people typing the exact same thing are close to zero.

    Real user data shows how fast that gap is widening. In an August 2025 panel, roughly half of free-text prompts were still short and keyword-shaped. By January 2026 that share had dropped closer to 30%, with the rest growing longer and more contextual.

    What replaced them is more specific than any keyword tool records. Nearly a quarter of prompts include the word “best,” 28% carry a price or budget constraint, 16% are location-based, and 32% include a personal attribute like profession, team size, or health condition. Separate panel research found task delegation prompts jumped from 10% to 37% between July 2025 and June 2026, while keyword-style prompts fell from 18% to 3%.

    The prompts deciding your category are the ones your keyword tool never recorded.

    One Prompt Search Turns Into a Dozen Hidden Queries

    Here’s the thing about prompt search that trips up most SEO teams: the prompt you track is almost never the query the model actually runs.

    AI search engines decompose a single question into parallel sub-queries before retrieving anything. Published measurements put the range at roughly 9 to 11 sub-queries per prompt, with software and B2B buying questions fanning out hardest. One analysis of 60,000+ fan-out queries found software prompts averaged 11.7 sub-queries on Google, compared with 3.79 for local intent.

    Those sub-queries are invisible and mostly unsearchable. A study of 72,000+ AI-generated queries found that 95% of fan-out phrases show zero monthly search volume, yet they gatekeep which sources make the final answer.

    Which explains the ranking disconnect. Analysis of 173,902 URLs found 68% of pages cited in AI Overviews were not in the top 10 organic results. In SaaS specifically, 81% of brand appearances in ChatGPT answers came from brands outside Google’s top 10 for that keyword.

    You’re not competing for the prompt. You’re competing for a dozen queries nobody showed you.

    Being Mentioned and Being Cited Are Two Different Scoreboards

    Prompt search optimization gets muddy when teams treat “our brand appeared” and “our page was cited” as the same outcome. They behave differently on every platform.

    A 2026 study of 34,234 AI responses found ChatGPT cited brands 0.59% of the time while Perplexity sat at 13.05%, a 46x spread. The same analysis found only 11% of domains are cited by both engines. ChatGPT will happily name your brand in prose and link somewhere else entirely.

    Citation volume differs too. ChatGPT averages around 15 sources per response while Gemini cites 3, and on Gemini the overlap between brands mentioned and domains cited can fall to 30%.

    SignalWhat it tells youWhat it doesn’t
    Brand mentionWhether the model considers you part of the categoryWhether any page of yours influenced the answer
    Source citationWhich URL earned retrieval and attributionWhether the brand was recommended favorably
    Answer positionWhether you’re framed as first choice or footnoteWhether the framing is stable across runs
    SentimentHow the model characterizes youWhich source shaped that characterization

    Track one signal and you’ll optimize for the wrong thing. Track a mention rate that climbs while your citation rate flatlines, and someone else’s content is doing the work of describing you.

    How to Build a Prompt Search Set Your Buyers Would Recognize

    Prompt selection is where most programs quietly fail. A short, well-filtered set outperforms a long, unfocused one, so the goal is coverage of decisions, not coverage of keywords.

    Start from the buying journey, not the keyword export. Semrush’s study of 50,000 brands structured each category as five representative prompts: definition, comparison, alternatives, use case, and buying question. That shape is a workable default for any category you own.

    Seed from paid keywords. Competitor bids on three-word-plus commercial terms are already validated by someone’s budget. “CRM for construction companies” converts into “What’s the best CRM for construction companies?” without guessing.

    Borrow the phrasing from community threads. Reddit sits among the most-cited domains across engines, and its question style is closer to how people actually prompt than any template.

    Add the constraint layer. Budget, location, industry, and role appear in a large share of real prompts, and constraints change results in ways that vary by platform. On ChatGPT and Perplexity they tend to narrow the brand set. On Gemini and AI Overviews they can widen it by triggering more fan-out.

    Keep the wording plain. Controlled testing published in June 2026 found concise keyword-style prompts produce up to 25% more brand mentions than persona-heavy prompts, which tend to push answers toward education instead of recommendation.

    On volume: start with 20 to 40 prompts across 2 or 3 models and hold for at least 30 days. That’s enough to detect absence. To detect movement of a few percentage points, you need far more surface area, which is why mature programs monitor 200 to 500 prompts grouped into intent clusters rather than read individually.

    Measure Prompt Search Visibility as a Distribution, Not a Screenshot

    Every prompt is n = 1. Run it once and you’ve captured one sample from a probabilistic system, which is why last week’s screenshot keeps contradicting this week’s.

    The volatility is measurable. Citation patterns for the same prompts shift 40% to 60% month to month as models update and competitors publish. A 2026 paper argued that AI search visibility should be characterized as a distribution rather than a single-point outcome, because answers vary across runs, wording, and time.

    In practice that means three things. Repeat each prompt several times per platform per cycle instead of once. Fix your sampling conditions, including location and account state, so run-to-run differences reflect the model and not your setup. Report ranges and trend lines, not a number your CMO will treat as precise.

    Semrush’s category data shows why patience matters: across 1,094 tracked categories, only 15% had a clear brand winner. In the other 85%, no single brand showed up consistently across a topic’s related prompts. Category leadership in AI answers is still unclaimed in most markets.

    Where AI Answers Actually Pull Their Sources

    Once you can see which prompts you’re losing, the next question is what to change. The citation data is unusually blunt about this.

    An analysis of 25 million cited links across ChatGPT, Claude, and Gemini found 84% of AI citations trace back to earned media, with paid and advertorial content accounting for about 0.3%. Consolidated ranking of 680 million citations found Reddit is the top source across every major engine at roughly 40% frequency, Wikipedia accounts for 26% to 48% of ChatGPT’s top-10 citation share, and the top 15 domains capture 68% of all citation share.

    Three moves follow from that, in order.

    First, check whether machines can read you at all. A 2026 analysis of over a million citations reported that roughly 73% of sites carry technical barriers blocking AI crawler access, which makes every content decision downstream irrelevant.

    Second, work the sources your prompts already surface. If a comparison roundup or a subreddit thread is being cited for your category prompt, presence in that thread moves your visibility faster than a new landing page will.

    Third, make your own pages quotable. The GEO study from Princeton, Georgia Tech, and IIT Delhi found that adding statistics lifted visibility by 41%, while keyword stuffing lowered it. Models extract passages, so write passages worth extracting.

    Turning Prompt Search Data Into Weekly Decisions

    The operational problem is scale. Repeating 200 prompts across four engines with several runs each, then attributing every change to a source, isn’t manual work anyone sustains past month two.

    That’s the gap platforms like Topify are built for. It tracks brand performance across ChatGPT, Gemini, Perplexity, and other major engines using seven metrics: visibility, sentiment, position, volume, mentions, intent, and CVR. Prompt discovery surfaces high-volume prompts in your category as they emerge, so your tracked set expands with the market instead of freezing at whatever you brainstormed in the kickoff meeting.

    The part that matters most for citation work is source-level analysis. Topify maps the exact domains and URLs engines cite for your prompts, which turns “we dropped in ChatGPT” into “the roundup that used to cite us now cites a competitor.” Competitor benchmarking runs on the same prompt set, so position changes are comparative rather than absolute.

    Pricing starts at $99/month for 100 tracked prompts and 9,000 answer analyses, with the Pro tier at $199/month for 250 prompts. If you want a baseline before committing to a program, running a first prompt set takes less setup than most keyword audits.

    Conclusion

    Prompt search optimization isn’t SEO with a new vocabulary. Prompts are longer and more contextual than keywords, each one fans out into sub-queries you can’t see, and the answer changes between runs, which makes single-shot screenshots worse than useless.

    Build a prompt set around buying decisions instead of search volume. Track mentions and citations as separate signals. Measure across repeated runs and report ranges. Then spend your effort where 84% of citations actually come from: third-party sources that already show up in your category’s answers.

    With 85% of categories still lacking a consistent AI answer winner, the position is open. It goes to whoever measures the prompts first.

    FAQ

    Q: What is prompt search optimization? 

    A: It’s the practice of tracking the natural-language prompts buyers use in AI assistants, measuring whether your brand is mentioned and cited in the resulting answers, and optimizing the sources that feed those answers. The unit of measurement is a prompt and its variants, not a keyword and its ranking position.

    Q: How many prompts should I track to get a reliable read? 

    A: 20 to 40 prompts across two or three engines is enough to confirm whether your brand appears at all. Proving that visibility moved from 18% to 23% takes a much larger, stratified set, typically 150 or more prompts repeated on a fixed schedule.

    Q: If I rank #1 on Google, will AI engines cite me? 

    A: Often not. Analysis of 173,902 URLs found 68% of pages cited in AI Overviews weren’t in the organic top 10, and in SaaS, 81% of ChatGPT brand appearances came from brands outside Google’s top 10 for that keyword. Ranking and citation are separate selection mechanisms.

    Q: Why do my AI answers change every time I run the same prompt? 

    A: Because generative engines are probabilistic and their retrieval layer refreshes constantly. Citation patterns shift 40% to 60% month to month for identical prompts, so a defensible measurement needs repeated runs and confidence ranges rather than a single answer.

    Read More

  • Prompt Search in 2026: How Users Query AI Differently

    Prompt Search in 2026: How Users Query AI Differently

    Your keyword research says “best CRM” gets 40,000 searches a month. Clean data. Clear intent. But when a prospect actually opens ChatGPT, they type something closer to “I run a 12-person B2B agency and we need a CRM that integrates with HubSpot, handles deal tracking, and costs under $50 per seat.” That’s 27 words, loaded with constraints your keyword tool never saw. The gap between what traditional search data captures and what users actually type into AI platforms is widening every quarter. And that gap is where brand visibility gets won or lost.

    What Separates a Prompt Search from a Keyword Search

    The difference isn’t just length. It’s structure.

    A Google search is a signal. You type “running shoes flat feet” and the engine infers the rest. An AI prompt is a briefing. You explain your situation, set constraints, and expect a tailored answer. The input changes from a fragment to a paragraph, and the output changes from a list of links to a synthesized recommendation.

    The data backs this up. A Semrush study of ChatGPT usage found that the average ChatGPT prompt runs about 23 wordswhen web search isn’t activated. Google’s average query length, by comparison, sits at roughly 3.4 words according to Semrush data. That’s nearly a 7x difference. And when users do activate ChatGPT’s search feature, their prompts drop to about 4.2 words, closer to Google’s norm, but the conversational framing stays.

    An analysis of 13,252 publicly shared ChatGPT conversations found that opening messages average 103 words. Users aren’t just asking questions. They’re describing scenarios, listing preferences, and setting context before the first response even loads.

    That matters for brands because prompt search isn’t about matching a keyword. It’s about matching a situation.

    Three Platforms, Three Prompt Patterns: ChatGPT vs. Perplexity vs. Google AI Mode

    Not all prompt search behavior looks the same. Each platform trains users into different querying habits, and those habits shape which brands get surfaced.

    ChatGPT leans conversational and personal. Users treat it like a consultant. Over half of real ChatGPT prompts use personal pronouns like “I,” “my,” or “me.” Sessions average just 1.7 messages, but those messages are dense. The typical user front-loads context rather than asking follow-ups. When ChatGPT does trigger a web search, it averages 2.17 searches per prompt, with internal queries running 5.48 words on average, 61% longer than a typical Google query.

    Perplexity attracts a different behavior: iterative research. Users report replacing Google for 70% to 99% of their research and knowledge queries while still defaulting to Google for navigation and shopping. Perplexity’s interface encourages progressive refinement. You start broad, then scope down with follow-ups. The platform transparently shows its sub-searches and cited sources, which trains users to write more structured, research-spec-style prompts.

    Google AI Mode is the most revealing shift. After launching in May 2025, it hit 1 billion monthly active users within a year. The average AI Mode query is three times longer than a traditional Google search. Follow-up queries have risen over 40% per month, and planning queries are growing 80% faster than AI Mode usage overall. Similarweb data shows that even in traditional Google Search, average query length has climbed from 3.33 words to 3.51 words since AI Mode launched.

    Here’s a side-by-side breakdown:

    DimensionChatGPTPerplexityGoogle AI Mode
    Avg. prompt length~23 words (without search)Structured research queries3x traditional Google search
    Primary behaviorSingle-turn, context-denseIterative refinementConversational follow-ups
    Search trigger rate31% of promptsEvery query triggers retrievalBuilt into every interaction
    User framing stylePersonal (“I need…”)Analytical (“Compare X vs. Y…”)Natural language, often voice
    Follow-up patternLow (1.7 msgs avg.)High (progressive scoping)Growing 40%+ per month

    The takeaway: a brand that shows up in ChatGPT’s single-turn answers may be invisible in Perplexity’s iterative chains or Google AI Mode’s follow-up conversations. Prompt search visibility is platform-specific.

    Why Keyword Research Tools Can’t Track Prompt Search Patterns

    Traditional keyword tools were built to index Google’s search bar. They capture short phrases, estimate monthly volumes, and cluster by head terms. That model breaks down when prompts become paragraphs.

    The core issue is structural. When someone types “best CRM for small teams” into Google, the engine matches it against its index and returns ranked pages. When the same person types a version of that query into ChatGPT, the model doesn’t just match. It decomposes. This is called query fan-out: the AI breaks one prompt into multiple sub-queries, runs them in parallel, retrieves sources for each, and synthesizes a single answer.

    Google described this behavior explicitly when it launched AI Mode, calling it a “query fan-out technique” that issues multiple related searches at once across subtopics and data sources. In practice, one user prompt can generate 8 to 16 sub-queries behind the scenes. ChatGPT averages 2.17 fan-out searches per prompt, with some triggering up to four.

    That means the unit of optimization has shifted. It’s no longer one keyword per page. It’s one topic cluster per prompt.

    And it gets more complex. SparkToro’s January 2026 research, conducted with Gumshoe.ai across 2,961 prompt runs, found that AI tools produce a different brand recommendation list more than 99% of the time. Even when 142 participants wrote their own prompts for the same underlying intent, the average semantic similarity was only 0.081. In other words, people with identical needs phrase their prompts in vastly different ways, and each variation can surface a different set of brands.

    No keyword tool captures that.

    What Prompt Search Behavior Means for Brand Visibility

    The SparkToro finding sounds alarming at first. If AI recommendations change with every query, what’s the point of tracking them?

    Here’s the thing. The brand lists vary, but the brand clusters don’t. SparkToro’s own follow-up analysis noted that despite massive prompt variation, AI tools often returned similar clusters of brands across different phrasings. The wording and order shifted, but the pool of recommended brands overlapped significantly. The question for marketers isn’t “which exact prompt should I optimize for?” It’s “am I showing up reliably across the full semantic neighborhood of this intent?”

    That reframes the visibility challenge. Brands need to understand which prompt patterns, not which exact keywords, drive their inclusion in AI answers. A prompt like “recommend a project management tool for remote teams” and “what’s the best PM software for distributed startups under 20 people” may look different to a keyword tool. To an AI platform, they overlap heavily, but not entirely. The second prompt’s constraints (startup, under 20 people) may pull in a different subset of brands.

    This is where prompt-level visibility tracking becomes non-negotiable. Topify‘s High-Value Prompt Discovery surfaces the actual prompts driving AI recommendations in your category, across ChatGPT, Perplexity, Google AI Mode, and other platforms. Instead of guessing which keywords matter, you see which prompt patterns your brand appears in and which ones you’re missing.

    In practice, that means a SaaS brand can discover that it’s consistently recommended when users ask about “CRM with email automation” but disappears when the prompt adds “for agencies” or “under $30 per seat.” That’s the kind of prompt-level gap that traditional keyword tools can’t reveal, but that directly impacts pipeline.

    How to Track and Adapt to Prompt Search Trends

    Knowing that prompt behavior matters is step one. Acting on it requires a system.

    Start by mapping your prompt terrain. Use Topify’s Prompt Discovery to identify which AI prompts mention your brand, your competitors, or your product category. This surfaces the actual language users type, not the cleaned-up keyword variants from traditional tools. You’ll often find prompt patterns you never anticipated, like industry-specific use cases or constraint combinations that don’t show up in Google Search Console.

    Monitor cross-platform visibility at the prompt level. A brand that ranks well in ChatGPT’s recommendations may be absent from Perplexity or Google AI Mode. Topify’s Comprehensive GEO Analytics tracks seven metrics (visibility, sentiment, position, volume, mentions, intent, and CVR) across major AI platforms. The platform-specific view matters because each engine’s fan-out logic, citation preferences, and retrieval patterns differ.

    Analyze what AI cites, not just what it recommends. Topify’s Source Analysis shows which domains and URLs AI platforms reference when generating answers. If a competitor’s blog post is the cited source behind your category’s top prompts, that’s a content gap you can close. If your own product page gets cited for the wrong prompts, that’s a positioning issue to fix.

    Iterate based on prompt clusters, not individual keywords. Group the prompts where your brand appears (and where it doesn’t) by intent and constraint patterns. Then map your content to those clusters. The brands that win in prompt search aren’t the ones optimizing for one keyword. They’re the ones that cover the full fan-out surface of their category’s most common prompts.

    Conclusion

    Prompt search is the new first touchpoint for brand discovery. In 2026, AI Mode alone has a billion monthly users asking queries three times longer than traditional searches, and ChatGPT processes billions of prompts daily with conversational inputs that no keyword tool was designed to capture. The brands that adapt aren’t just optimizing for AI. They’re tracking the actual language their audience uses across platforms, identifying the prompt patterns where they’re visible or invisible, and closing the gaps before competitors do. The shift from keywords to prompts isn’t coming. It’s already here, and it’s measurable.

    FAQ

    Q: What is prompt search? 

    A: Prompt search refers to the behavior of querying AI platforms like ChatGPT, Perplexity, and Google AI Mode using natural language prompts instead of short keyword strings. These prompts tend to be longer, more context-rich, and more personal than traditional search queries, often including constraints, preferences, and situational details.

    Q: How do prompt search patterns differ between ChatGPT and Google AI Mode? 

    A: ChatGPT prompts tend to be single-turn and context-dense, averaging 23 words without web search activated. Users often describe personal scenarios upfront. Google AI Mode prompts are three times longer than traditional Google searches, with follow-up queries growing over 40% per month. AI Mode encourages multi-turn conversations, while ChatGPT users typically front-load their context in one message.

    Q: Can traditional SEO tools track prompt search behavior? 

    A: Not effectively. Traditional keyword research tools capture short-phrase queries from Google’s index and estimate search volume. They don’t cover the longer, conversational prompts users type into AI platforms, the query fan-out behavior where one prompt becomes multiple sub-queries, or the cross-platform variation in how AI engines surface brands for similar intents.

    Q: How can brands optimize for prompt-based AI search? 

    A: Focus on three areas. First, discover the actual prompts driving recommendations in your category using prompt-level tracking tools like Topify. Second, build content that covers full topic clusters rather than single keywords, since AI platforms decompose prompts into sub-queries. Third, monitor your visibility across multiple AI platforms, because prompt behavior and citation patterns vary significantly between ChatGPT, Perplexity, and Google AI Mode.

    Read More

  • The Rise of Prompt Search: How AI Is Replacing the Search Bar

    The Rise of Prompt Search: How AI Is Replacing the Search Bar

    Your keyword rankings are stable. Your domain authority is climbing. Your content calendar is running on schedule. Then a prospect types a 23-word question into ChatGPT, gets a direct recommendation for your competitor, and never visits Google at all. Nothing in your SEO dashboard flagged it. Nothing in your analytics even registered the lost opportunity.

    That’s the gap prompt search has opened. And for most marketing teams, it’s completely invisible.

    From Keywords to Prompts: What Actually Changed in Search

    For two decades, search worked on a simple contract: users compressed their intent into short keyword phrases, and search engines matched those fragments against indexed pages. Type “best CRM small business,” get a ranked list of links. The system rewarded brevity because the algorithm needed it.

    Prompt search flips that contract. Instead of trimming context to fit a search box, users now write full questions with constraints, preferences, and background information baked in. A Semrush study found that the average ChatGPT prompt runs about 23 words, compared to roughly 4 words for a typical Google query. Some analyses put the ChatGPT average even higher, around 60 words, once you include detailed research and multi-step requests.

    The difference isn’t just length. It’s structure. A keyword query like “project management tool” carries almost no context. A prompt like “What project management tool should I use for a remote team of 15 people with a tight budget and Slack integration?” tells the AI who’s asking, what they need, and what constraints matter. The AI doesn’t match keywords to pages. It interprets intent, weighs context, and synthesizes an answer from multiple sources.

    That shift has a direct consequence for brands: if your content was built to match keyword fragments, it may not surface when an AI system processes a context-rich prompt.

    Why Prompt Search Breaks Traditional Keyword Research

    The mechanical reason is a process called query fan-out. When a user submits a prompt to ChatGPT, Perplexity, or Google’s AI Mode, the system doesn’t search for the exact phrase. It breaks the prompt into multiple sub-queries, runs them in parallel, retrieves pages for each, and synthesizes the results into a single answer.

    A Nectiv study analyzing 8,500+ ChatGPT prompts found that 31% triggered at least one web search, with an average of 2.17 searches per prompt. NoGood’s testing showed that a single prompt can generate 8 to 15 sub-queries behind the scenes, each pulling from different sources.

    Here’s what that looks like in practice. A user asks: “How do I reduce customer acquisition costs?” ChatGPT might fan out into sub-queries like “CAC reduction strategies for SaaS,” “customer acquisition cost benchmarks by industry,” and “CAC vs LTV optimization.” The final answer combines passages from six different websites, none of which necessarily ranked first for the original query.

    Traditional keyword research can’t capture this. Your keyword tool shows volume for “reduce customer acquisition costs.” It doesn’t show you the five hidden sub-queries that actually determine which brands get cited. And those sub-queries change depending on the phrasing, context, and constraints the user includes in their prompt.

    That’s the core problem. Keyword research tells you what humans type into Google. Query fan-out tells you what the AI types into Google after it reads what the human asked. Different layer, different leverage.

    The Numbers Behind the Shift to Prompt Search

    The scale of this shift is no longer speculative. It’s measurable across every major platform.

    ChatGPT reached over 1 billion monthly active users in early 2026, processing roughly 2.5 billion prompts per day. Perplexity scaled to 1.2 to 1.5 billion monthly queries. Google’s AI Overviews now appear on roughly 15% of all Google searches, with higher rates for informational and research queries.

    The behavioral data is equally clear. Bain & Company’s 2025 research found that 80% of consumers rely on AI-written results for at least 40% of their searches, reducing organic web traffic by 15% to 25%. Gartner predicted that traditional search volume would drop 25% by 2026 as users shifted to AI chatbots. About 37% of consumers now start searches with AI tools, and that figure is higher among younger demographics.

    The commercial impact is where it gets interesting. The Opollo AI Search Benchmark Report, analyzing 312 B2B technology companies, found that AI-referred traffic converts at 14.2%, compared to Google organic’s 2.8%. That’s a 5x gap. Fewer visitors, but dramatically more valuable ones.

    Yet only 23% of marketers currently invest in measuring AI visibility, even though 54% plan to implement GEO within the next 3 to 6 months. The gap between awareness and action is wide.

    What Prompt Search Means for Your Content Strategy

    The strategic shift is straightforward, even if the execution isn’t. Content built for keyword matching needs to evolve into content built for intent coverage.

    Here’s what that looks like in practice:

    DimensionKeyword-Optimized ContentPrompt-Ready Content
    Query it targetsShort phrase (“best CRM”)Full question with context and constraints
    Optimization goalRank for one keywordCover multiple sub-queries an AI might generate
    Content structureSingle topic, keyword densityMulti-angle coverage with clear, extractable answers
    Success metricGoogle ranking positionWhether AI cites the content in generated answers
    Update cadenceQuarterly refreshContinuous, since AI favors pages updated within 30 days

    The practical starting point is prompt mapping. Rather than building a keyword list, you build a prompt set that mirrors how real users ask questions in AI search. SurfacedBy’s research breaks this into four categories:

    Discovery prompts: Broad category questions where no brand is named. (“What’s the best way to track my brand’s visibility in AI search?”)

    Constraint prompts: Questions that add budget, company size, use case, or technical requirements. (“What AI visibility tool works for a 10-person marketing team under $200/month?”)

    Comparison prompts: Questions that force tradeoffs between named options. (“How does X compare to Y for AI search monitoring?”)

    Follow-up prompts: Second and third questions in a conversation that narrow the recommendation. (“Does it also track Perplexity and Google AI Overviews?”)

    Your content needs to address all four types, not just the head term. That means structuring articles so that each sub-section answers a distinct question an AI might fan out into. If your page answers the most relevant sub-queries with clear, direct passages at the top of each section, you’re more likely to get cited.

    How to Track Prompt Search Visibility Before Competitors Do

    Here’s the thing: you can’t optimize what you can’t measure. And traditional SEO tools weren’t built to measure prompt-level visibility. They’ll tell you where you rank on Google for “best CRM.” They won’t tell you whether ChatGPT mentions your brand when a user asks, “Which CRM should a 15-person remote team use if we need Slack integration and spend under $50/seat?”

    That’s a fundamentally different measurement problem. It requires tracking real prompts across multiple AI platforms, monitoring which brands get cited, and understanding the sentiment and position of those citations.

    Topify was built for exactly this shift. Its High-Value Prompt Discovery feature surfaces the specific prompts your audience is asking across ChatGPT, Perplexity, and Google AI Overviews, so you’re optimizing for the questions that actually drive AI recommendations, not just the keywords that drive Google rankings.

    The platform’s Visibility Tracking monitors whether your brand appears in AI-generated answers at the prompt level. You can see which prompts trigger a mention, which don’t, and how your citation rate compares to competitors. Source Analysis then shows which domains and URLs the AI platforms are actually citing, so you can identify exactly where your content gaps are.

    In practice, this means a marketing team can go from “we think we’re doing well in AI search” to “we know we’re cited in 34% of high-intent prompts in our category, up from 18% last quarter, and competitor X just passed us on Perplexity.” That’s the difference between guessing and operating.

    For teams just getting started, the first step is simple: take your top 10 keywords and rewrite them as the prompts your buyers would actually type into ChatGPT. Then check whether you show up. If the answer is no, or you don’t know, that’s where Topify’s prompt-level tracking fills the gap.

    Conclusion

    Search didn’t die. It evolved. The search bar trained users to think in fragments. AI search is training them to think in full sentences, with context, constraints, and follow-ups. That’s prompt search, and it’s already reshaping which brands get discovered, recommended, and chosen.

    The marketers who’ll win this transition aren’t the ones with the best keyword rankings. They’re the ones who understand which prompts matter, track their visibility at the prompt level, and build content that answers the sub-queries AI actually runs behind the scenes. The data is clear, the shift is measurable, and the tools to act on it exist today.

    FAQ

    Q: What is prompt search? 

    A: Prompt search refers to the way users interact with AI platforms like ChatGPT, Perplexity, and Google AI Mode by typing full, natural-language questions instead of short keyword fragments. These prompts typically include context, constraints, and specific intent, and the AI interprets them to generate synthesized answers rather than a list of links.

    Q: Does prompt search mean keywords are dead? 

    A: No. Keywords still indicate where demand exists. But keywords alone no longer capture how AI search engines process and respond to user queries. The shift is from optimizing for a keyword to covering the full set of sub-queries an AI might generate from a single prompt. The two approaches work together, not as replacements.

    Q: How does query fan-out work in AI search? 

    A: When you submit a prompt to an AI search platform, the system breaks it into multiple narrower sub-queries, searches the web for each one in parallel, and then synthesizes the results into a single answer. This process, called query fan-out, means that the pages cited in an AI answer often weren’t optimized for the original prompt at all. They were pulled in because they answered one of the hidden sub-queries.

    Q: How can I track my brand’s visibility in prompt search results? 

    A: You need a platform that monitors AI-generated answers at the prompt level across multiple AI engines. Topify, for example, tracks which prompts mention your brand in ChatGPT, Perplexity, and Google AI Overviews, and shows how your visibility compares to competitors. The key is moving beyond keyword rankings to prompt-level citation tracking.

    Read More