Category: Knowledge

  • Why Your Products Aren’t Showing Up When ChatGPT Shops for Customers

    Why Your Products Aren’t Showing Up When ChatGPT Shops for Customers

    ChatGPT now handles roughly 50 million shopping related queries every day. Searches for “AI shopping” alone have grown 1,767% over the last two years.

    If your products aren’t turning up in those conversations, you’re not losing a future channel. You’re losing a present one.

    The ChatGPT Shopping Moment Nobody Priced In

    Most brands still treat ChatGPT shopping as a side project. That’s a mistake.

    More than six in ten consumers have already used ChatGPT to shop, and one in four say it gives better recommendations than Google. Bain & Company found that 80% of consumers now rely on AI generated results for at least 40% of their searches.

    The dollars are catching up too. McKinsey projects agentic commerce could drive $3 to $5 trillion in global transactions by 2030. That’s not a niche. That’s a new front door for retail.

    Instant Checkout Died, but Agentic Commerce Didn’t

    Here’s a twist that changes the strategy for a lot of teams. OpenAI’s Instant Checkout, the buy-without-leaving-chat feature launched in September 2025, has been quietly shelved as of March 2026. Fewer than 30 Shopify merchants ever went live, against the over a million once promised.
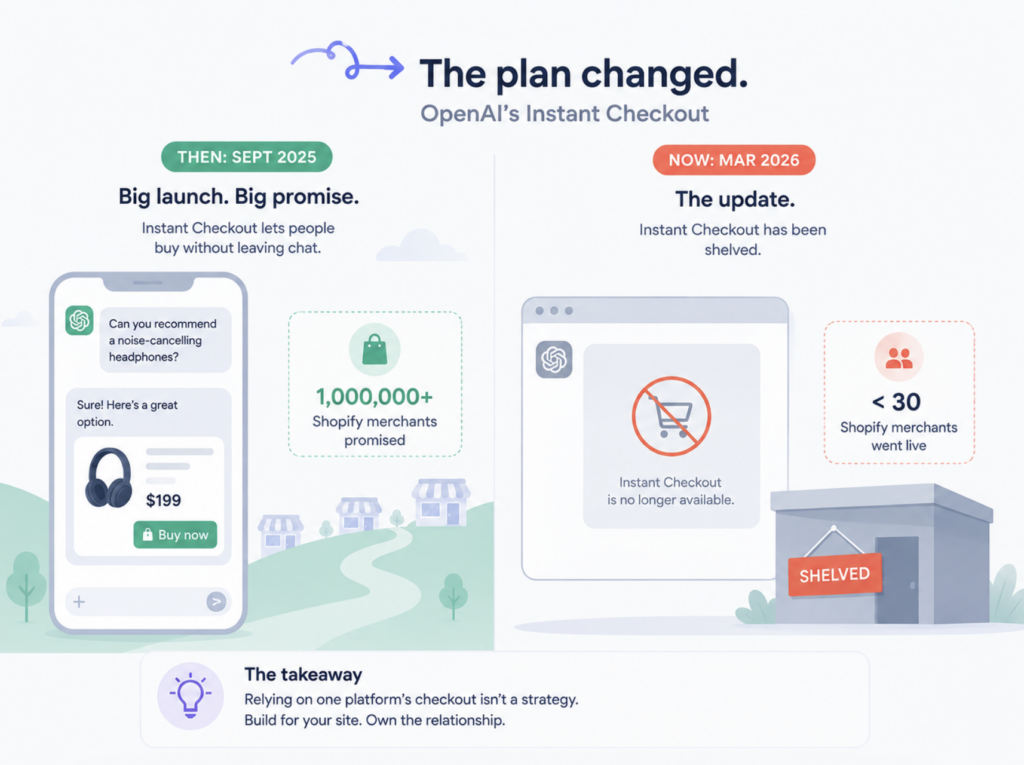
    The reason wasn’t philosophical. It was conversion math.

    Walmart found that checkout inside ChatGPT converted roughly 3 times worse than a click through to walmart.com, even though ChatGPT drove about twice the new customer rate that Walmart sees from search. In practice, ChatGPT is turning out to be a discovery engine, not a checkout counter.

    The underlying Agentic Commerce Protocol, open sourced by OpenAI and Stripe, is still very much alive. It just plays a different role now: get discovered in the chat, close the sale on your own site. That’s the model worth building for.

    That’s the gap most brands still haven’t priced in.

    The Real Gatekeeper Is Google Shopping, Not ChatGPT

    Here’s the part that surprises most marketing teams. ChatGPT doesn’t build its own product index. It reads someone else’s.

    Peec AI analyzed over 43,000 ChatGPT carousel products and found that 83% were strong matches to Google Shopping’s organic top 40 results for the same query. A separate study found the number closer to 100%, with Bing Shopping explaining only about 11% of what showed up. ChatGPT also pulls roughly 75% of its raw product data straight from Google Shopping.

    Rank matters more than most teams assume. Peec AI’s data shows 60% of carousel matches come from Google Shopping’s top 10 results, climbing to 84% by the top 20. Products sitting at rank 21 to 40 account for only about 16% of matches.

    Google Shopping RankShare of ChatGPT Carousel Matches
    Top 10~60%
    Top 20~84%
    Rank 21 to 40~16%
    Outside top 40Effectively 0%

    If you’re not in Google Merchant Center with a clean feed, you’re not in ChatGPT’s candidate pool at all. No amount of great copywriting on your product page fixes that. Feed quality is the gate. Everything else decides what happens once you’re through it.

    Why Your Titles Fail a Model That Talks Like a Shopper

    Getting into the pool is step one. Getting picked is a different problem, and it’s where most feeds quietly fail.

    Shopping fan out queries inside ChatGPT average about seven words and read like something a person would actually say, not a keyword string. “Red Dress Cotton” doesn’t match how anyone talks to an AI. “Women’s A-Line Cotton Midi Dress in Cherry Red” does.

    Structured attributes carry the same weight. Google Shopping needs brand, product type, material, color, size, gender, condition, and a GTIN or manufacturer ID to place your product correctly. Skip a field and you either drop out of relevant queries or get miscategorized entirely.

    Freshness compounds this. ChatGPT’s own merchant feed spec supports updates every 15 minutes, compared to Google Shopping’s standard 24 hour cycle. Stale pricing or a phantom “in stock” tag is often the quiet reason a product that used to appear stops showing up.

    The Trust Signals That Decide Whether You Get Recommended

    Once ChatGPT has a shortlist, it starts reasoning about which product to actually suggest. That’s where trust signals take over from feed mechanics.

    Reviews matter more than most teams realize, because ChatGPT performs sentiment synthesis on the actual text of reviews to answer detailed shopper questions. If your review content isn’t wired into your feed, ChatGPT pulls social proof from Reddit or third party blogs instead, and you lose control of your own narrative.

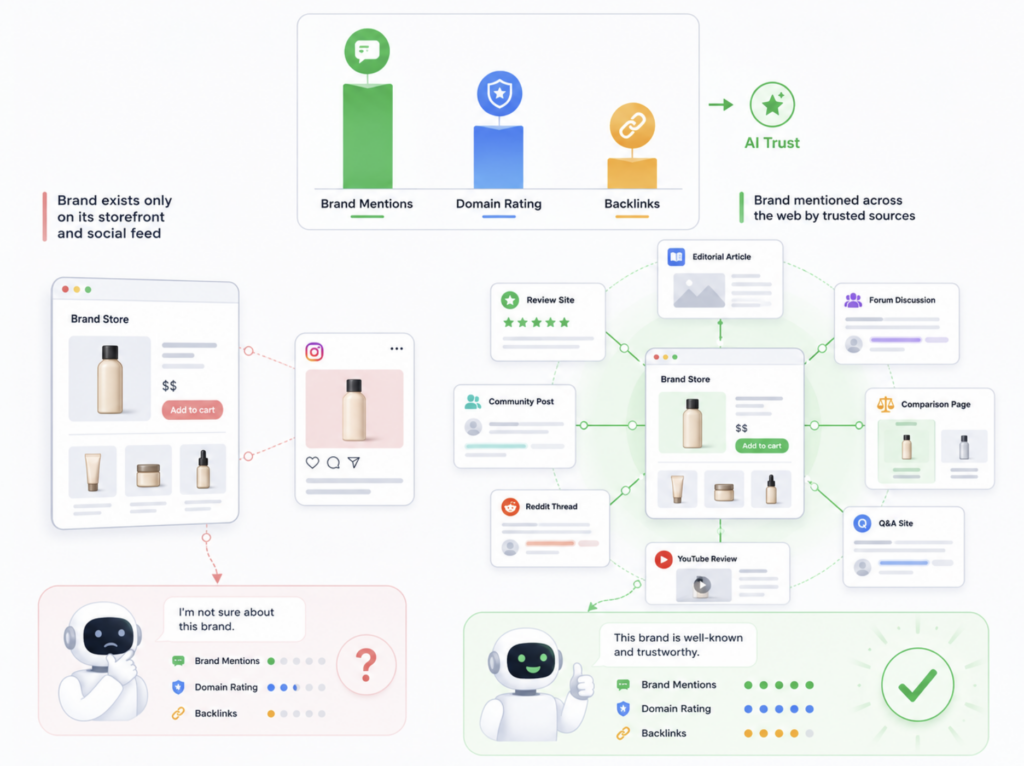
    Brand mentions carry surprising weight too. Ahrefs found that branded mentions across the web correlate with AI visibility at 0.664, well above backlinks at 0.218 or domain rating at 0.326. A brand that only exists on its own storefront and its own feed is structurally harder for an AI agent to trust.
    Content depth adds another layer. Academic GEO research from Princeton and Georgia Tech found that content backed by statistics, citations, and structured evidence can lift AI visibility by up to 40%.

    None of these signals live in your product feed. They live in how your brand shows up everywhere else AI models look.

    How to Check If You’re Even in the Running

    Before fixing anything, you need to know where you actually stand.

    Run a handful of shopping style prompts through ChatGPT the way a real customer would phrase them. Not “best waterproof boots” but “what’s a good waterproof hiking boot for wide feet under $200.” Check whether your brand appears, where it lands in the carousel, and which competitors keep showing up instead.

    This works fine as a spot check. It falls apart at scale. Prompts drift, models get updated, and a brand that shows up today can quietly disappear next week without anyone noticing until sales already dipped.

    Turning Product Visibility Into Something You Can Track

    Manual prompt testing tells you what’s happening right now, once. What most teams actually need is a way to see the pattern over time, and to know which lever to pull when visibility drops.

    Topify‘s Visibility Tracking follows how often your products and brand actually surface across ChatGPT, Perplexity, and Google AI Overviews, so a drop shows up as a chart instead of a support ticket. Paired with Source Analysis, it shows exactly which domains and review sources AI models are citing when they explain a recommendation, which is often the fastest way to spot a content gap before a competitor fills it.

    Competitor Monitoring rounds it out by showing who’s winning the same carousel you’re trying to get into, and where their feed or content is simply stronger than yours right now. That turns “why aren’t we showing up” from a guess into a diagnosis.

    What to Fix This Week

    • Confirm your Google Merchant Center feed is complete: brand, GTIN, material, color, size, and condition, with no missing fields
    • Rewrite your top 20 product titles the way a customer would actually ask for them, not the way your internal catalog names them
    • Sync your product page schema markup with your feed data so the two never contradict each other
    • Wire your genuine review content into your feed instead of leaving AI models to source sentiment from third party sites
    • Start tracking your AI shopping visibility on a recurring basis instead of spot checking it once and moving on

    Conclusion

    Your products aren’t invisible to ChatGPT because AI shopping is some kind of black box. They’re invisible because Google Shopping’s organic index decides who even gets considered, and most feeds still aren’t clean enough to clear that bar. Fix the feed first. Build the trust signals second. Track what happens next, because a visibility gap you can’t see is one you can’t fix.

    FAQ

    Does ChatGPT rank paid ads in its shopping results? 

    No. Both Peec AI and OpenAI confirm that ChatGPT’s product carousel pulls from organic Google Shopping results only. There’s currently no way to pay for placement.

    Do I need to be on Shopify to appear in ChatGPT shopping? 

    No. Appearing depends on having a well optimized Google Merchant Center feed, not on which ecommerce platform you run. Etsy and independent merchants show up the same way Shopify stores do.

    Is Instant Checkout still worth building for? 

    Not as a priority. OpenAI shelved Instant Checkout for most merchants in March 2026 after adoption stalled. The Agentic Commerce Protocol behind it is still active, but the practical model right now is getting discovered inside ChatGPT and closing the sale on your own site.

    How is agentic commerce different from regular ecommerce SEO? 

    Regular SEO optimizes pages for crawlers and keywords. Agentic commerce optimizes structured data, primarily your Google Shopping feed, for an AI agent that reasons over attributes, reviews, and trust signals before recommending a product on a customer’s behalf.
    Read More

  • What Is Agentic Commerce, and Why Your Brand May Be Invisible

    What Is Agentic Commerce, and Why Your Brand May Be Invisible

    Someone opens ChatGPT and types “find me running shoes under $150 in size 10.” The agent searches, compares, and either checks out on the spot or hands the shopper straight to a merchant. No browser tabs. No scrolling through search results. No side-by-side comparison of ten websites.

    That’s agentic commerce. And it’s already live.

    What “Agentic Commerce” Actually Means

    Agentic commerce is when autonomous AI agents research, compare, and purchase products on behalf of a human buyer. It’s a step beyond conversational commerce, where a chatbot just assists a human shopper. Here, the AI system takes over decision-making and, in a growing number of cases, the transaction itself.

    The shopper states intent. The agent handles discovery, comparison, and either checkout or a seamless handoff to the merchant. That’s the entire shift in one sentence.

    This isn’t a future scenario. McKinsey projects the global agentic commerce opportunity will hit $3 trillion to $5 trillion by 2030, and Morgan Stanley estimates $190 billion to $385 billion of U.S. e-commerce spending will run through agentic shoppers by that same year. Bain puts the U.S. market even higher, at $300 billion to $500 billion, or 15% to 25% of e-commerce.

    Why This Is Different From Ranking on Google or Being Cited by ChatGPT

    Traditional SEO solves for “being found.” GEO solves for “being mentioned.” Agentic commerce solves for something harder: being selected and paid for, without a human ever seeing the alternatives you lost to.

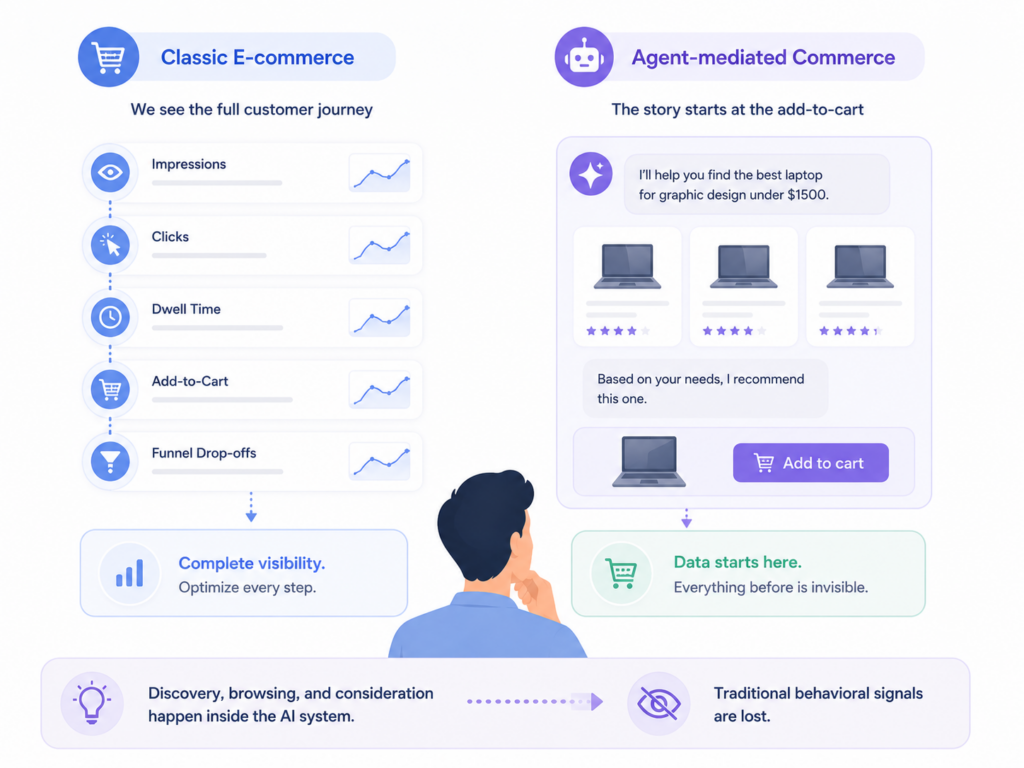
    In classic e-commerce, retailers see impressions, clicks, dwell time, add-to-cart events, and funnel drop-offs. In agent-mediated commerce, that entire story disappears. The behavioral data stream starts at the add-to-cart moment, while the discovery, browsing, and consideration all happen inside the AI system.

    That’s not a small detail. It means a brand can lose a customer during the comparison stage and never know it happened.

    The scale backs this up. Shopify reported AI-driven traffic to its stores grew 8x year over year in Q1 2026, with orders from AI-powered search up nearly 13x. Those orders also carried 14% higher average order values compared to organic search. Brands catching this wave aren’t seeing marginal gains. They’re seeing a new channel outperform the old one.

    Where Brands Are Already Going Invisible

    Here’s the part most marketing teams miss. AI agents don’t crawl your website the way Google does. They read a feed.

    The OpenAI Product Feed acts as the single source of truth for a merchant’s product data, including titles, prices, stock, and media, and powers search, discovery, and checkout inside ChatGPT. Critically, this data isn’t crawled. Merchants push a structured file directly to OpenAI’s endpoint. No feed, no listing, no matter how well your site ranks on Google.

    If you’re not in the feed, you don’t exist to the agent.

    The numbers on structured data make the stakes concrete. Pages with structured data are cited 3.1x more frequently than pages without it. And the honest state of most catalogs isn’t good. Google’s Universal Commerce Protocol launched in January 2026 with Shopify, Wayfair, Target, Etsy, and Walmart as founding partners, and OpenAI’s Agentic Commerce Protocol already powers ChatGPT’s Instant Checkout. The infrastructure exists. The real question is whether a given merchant’s product data is in a format agents can read, trust, and act on, and for most stores today the honest answer is no.

    What Determines Whether an AI Agent Picks Your Brand

    Agents don’t judge a brand by tone of voice or homepage design. They judge it by data completeness.

    The minimum bar is low but strict. Every product record needs an ID, title, description, price, availability, URL, and image, with 25 or more additional structured attributes recommended for discovery quality. Fields like GTIN coverage per SKU are called out as the single highest-leverage fix for Perplexity and ChatGPT discoverability. Marketing copy actually hurts you here. ChatGPT rejects feeds that use promotional language in the description field, and mismatched pricing between the feed and the live product page is one of the leading reasons feeds get rejected outright.

    Consumer behavior adds another layer. 73% of consumers already use AI somewhere in their shopping journey, mostly for getting product ideas, summarizing reviews, and comparing prices. But trust hasn’t caught up to comfort. 70% say they’re at least somewhat comfortable with an AI agent making a purchase on their behalf, yet only 4% trust an AI to buy without a final human review. That gap is exactly why the brands that show up clearly, with clean data and credible signals, win the moment a shopper does let the agent decide.

    That’s the practical difference between traditional visibility and agentic visibility.

    Traditional SEO / GEOAgentic Commerce
    What’s trackedRankings, citations, mentionsSelection and transaction completion
    Data source for AICrawled web pagesMerchant-pushed structured feed
    Update frequencyDays to weeksAs often as every 15 minutes
    Failure modeLower ranking, fewer clicksTotal absence from the agent’s candidate set

    How to Check If Your Brand Is Visible to Shopping Agents

    The fastest test costs nothing. Open ChatGPT, Perplexity, or Gemini and run the exact prompts your customers would use to shop your category. Note whether your brand shows up, in what position, and against which competitors. Do this across a handful of real purchase-intent prompts, not just your brand name.

    That manual check tells you where you stand today. It won’t tell you where you’re losing ground next month, or which competitor just improved their feed and jumped ahead of you.

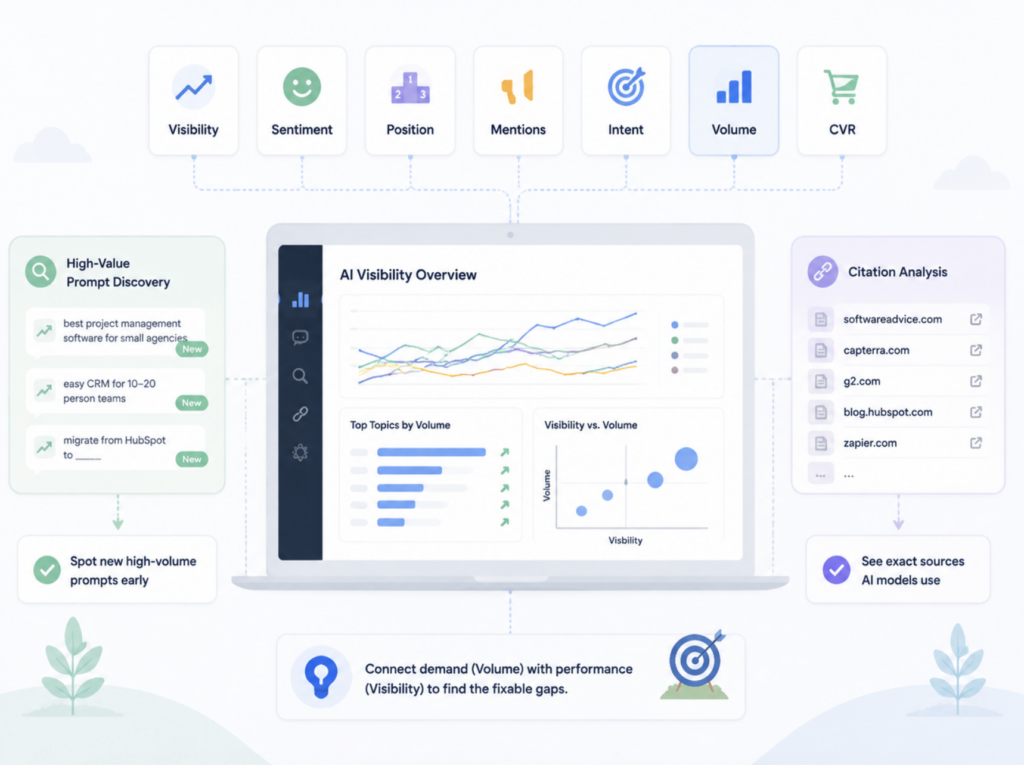
    This is where Topify’s Comprehensive GEO Analytics becomes useful. It tracks brand performance across major AI platforms through seven metrics: visibility, sentiment, position, volume, mentions, intent, and CVR, the last of which estimates how likely an AI answer is to actually drive a real interaction or purchase rather than just a mention. For agentic commerce specifically, CVR matters more than any single citation count, because being named by an agent means nothing if the agent never routes the shopper toward you. Topify’s Dynamic Competitor Benchmarking layers on top of that, showing who the agent recommends instead of you and how that ranking shifts as your feed and content change.

    Checking once tells you your current score. Checking continuously tells you whether you’re gaining or losing ground as protocols like ACP and UCP keep expanding what agents can do.

    What Brands Can Do Before Agentic Commerce Scales Further

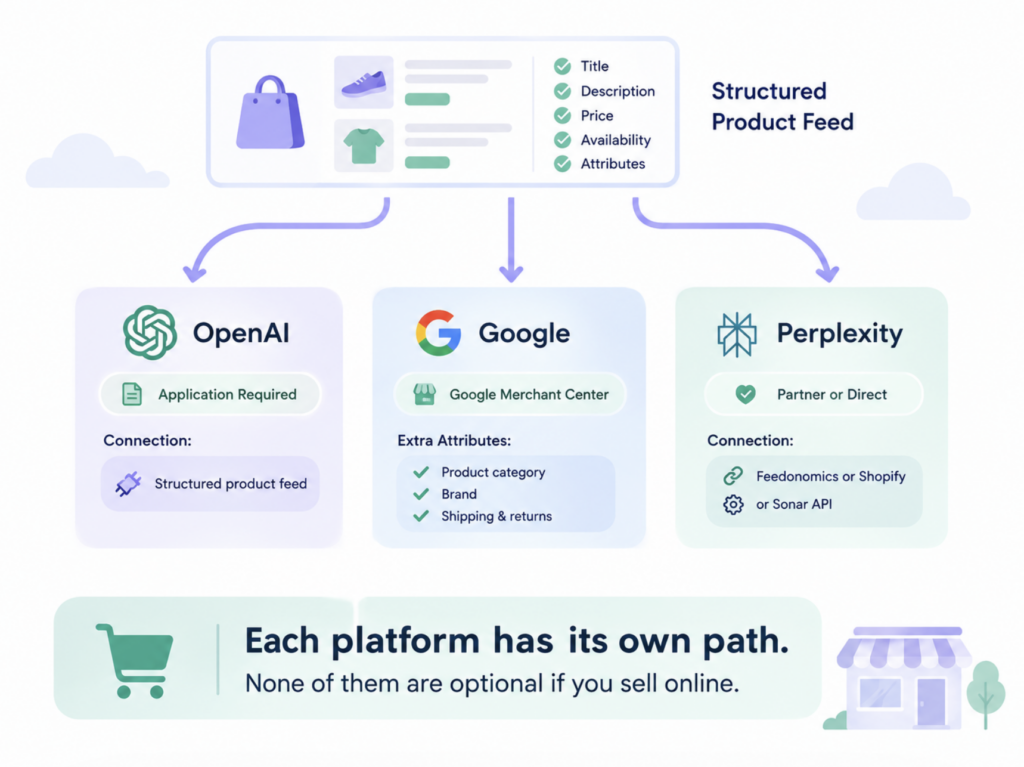
    Start with the feed, not the marketing copy. OpenAI requires an application and a structured product feed, Google runs through Google Merchant Center with extra attributes, and Perplexity connects through partners like Feedonomics or Shopify, or directly via its Sonar API. Each platform has its own path, and none of them are optional if you sell online.

    Audit before you rebuild. If your Google Merchant Center feed is already clean and your images meet a 1,500×1,500 resolution standard, you’re roughly 60% of the way to being ready across surfaces. That’s a lower lift than most teams assume.

    Fraud and trust infrastructure is catching up too. 78% of financial institutions expect fraud to spike specifically from AI shopping agents, which means authentication standards for distinguishing real agents from bots will keep tightening this year. Brands that get their structured data and merchant verification in order now won’t be scrambling when those standards become gatekeepers.

    Being invisible to an agent isn’t a ranking problem. It’s a data completeness problem, and it’s fixable in weeks, not quarters.

    Conclusion

    Agentic commerce isn’t a distant trend to plan for next year. It’s a live channel already redirecting traffic, orders, and average order value away from brands that haven’t structured their data for it. The brands showing up in agent-driven results aren’t necessarily the ones with the best product. They’re the ones an agent can actually read.

    Check where your brand stands with an AI agent today, before a competitor’s cleaner feed makes that decision for you.

    FAQ

    What is agentic commerce? 

    It’s AI-agent-driven shopping, where an autonomous system researches, compares, and completes a purchase for a human buyer instead of the human clicking through search results themselves.

    How is agentic commerce different from traditional e-commerce?

     Traditional e-commerce puts the human through every step: search, compare, click, buy. Agentic commerce delegates discovery and comparison, and increasingly checkout itself, to the AI system.

    How do I know if AI shopping agents can see my brand? 

    Run real purchase-intent prompts through ChatGPT, Perplexity, and Gemini for your product category, or track it continuously with a tool built for AI visibility monitoring.

    Do I need a product feed to appear in ChatGPT Shopping? 

    Yes. ChatGPT indexes a structured feed pushed directly by the merchant rather than crawling your website, so without a feed submission your products generally won’t surface in shopping results.

    Read More

  • We Analyzed 200 AI Prompts to See How Brands Stack Up

    We Analyzed 200 AI Prompts to See How Brands Stack Up

    A SaaS brand we looked at sat at position two on Google for its main category keyword. Solid rankings, solid backlink profile, years of SEO work behind it. When we ran the same query set through ChatGPT, that brand didn’t show up once. Its closest competitor, ranked seven spots lower on Google, got mentioned in nearly a third of the AI responses.

    That’s the kind of gap you only find by actually testing it. So we did, using Topify’s competitor analysis tool to track how a set of brands performed across roughly 200 AI prompts, and the results didn’t match what most SEO playbooks would predict.

    Why We Ran This Analysis

    Competitor analysis used to be simple. Check rankings, check backlinks, check who shows up on page one. That framework worked when search meant a list of blue links.

    It doesn’t work the same way anymore. AI engines don’t return ten ranked results. They synthesize an answer and decide, on their own logic, which two or three brands are worth naming. That’s a different kind of competition, and most brands are still analyzing it with the wrong toolkit.

    We wanted to know: if you actually run an AI visibility competitor analysis instead of a traditional SEO audit, what shows up that a Google-first view would completely miss?

    How We Set Up the Test

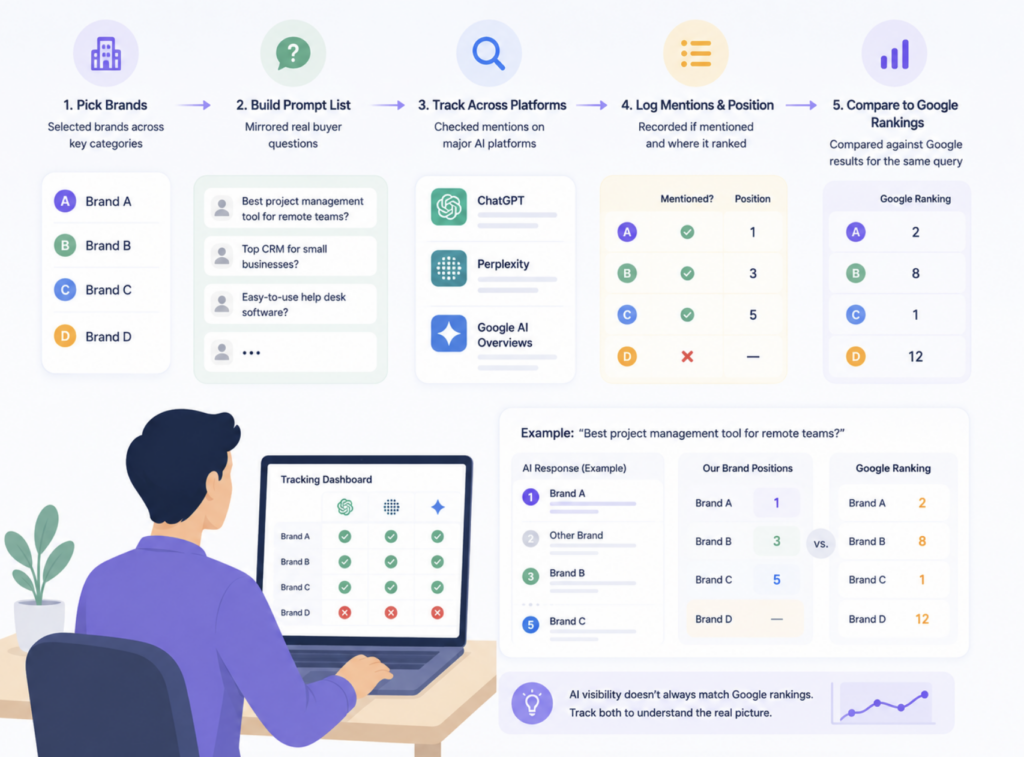
    We picked a set of brands across a few categories, built a prompt list that mirrored real buyer questions, and tracked mentions across ChatGPT, Perplexity, and Google AI Overviews. For each brand, we logged whether it got mentioned, where it landed in the response, and how that compared to its Google ranking for the same query.

    This is close to what Topify’s Dynamic Competitor Benchmarking does automatically. Instead of a one-time snapshot, it keeps running the comparison so you catch shifts as AI engines update their answers, not months after the fact.

    The goal wasn’t to prove a point. It was to see what the data actually showed.

    Finding #1: Ranking #1 on Google Buys You Less Than You’d Think

    This is the finding that should worry anyone treating SEO rank as a proxy for AI visibility. A large-scale study of 150 SaaS companies across 120 keywords found that <cite index=”3-1″>ChatGPT cited study brands 686 times across all keywords, and only 128 of those mentions overlapped with a brand’s Google top-10 ranking</cite>. Put differently, roughly 44% of the brands with strong Google positions were nowhere to be found in ChatGPT’s answers.

    Separate research looking at the reverse angle found something just as stark. Among brands that ChatGPT actively recommended, <cite index=”1-1″>81% didn’t rank in Google’s top 10 for the matching query</cite>.

    That’s not a small discrepancy. It’s two different visibility systems running in parallel, and most brands are only measuring one of them.

    Finding #2: The Gap Isn’t Even Across Categories

    Here’s where it gets more useful. The size of that citation gap depends heavily on the category you’re in.

    CategoryGoogle-to-ChatGPT Citation GapLikely Driver
    Marketing Automation53%Heavy reliance on paid placement and brand SEO over third-party discussion
    Dev Tools18%Strong documentation and community content, exactly what AI models train on
    SaaS (overall average)44%Mixed content ecosystems, inconsistent third-party coverage

    The pattern researchers pointed to lines up with what we saw in our own sample. <cite index=”3-1″>Categories with better documentation and more community discussion tend to have narrower citation gaps</cite>, because that’s the type of content generative engines actually pull from.

    If your category leans on brand-controlled marketing content rather than independent reviews, forums, and comparison articles, expect your gap to run wider than average.

    Finding #3: Bing Might Matter More Than Your SEO Team Realizes

    This is the finding that surprised us the most. A separate case study tracking hotel brand mentions across ChatGPT responses found that <cite index=”4-1″>Bing rank strongly predicts ChatGPT citations, with 87% alignment to Bing’s top results</cite>.

    Not Google. Bing.

    The same case study illustrated how sharp this effect can get. One boutique hotel appeared in <cite index=”4-1″>just 1.5% of trials</cite>, while a similarly positioned competitor showed up far more often and got cited in a meaningfully higher share of responses.

    That’s a hard thing to catch with a traditional SEO audit. Nobody’s checking their Bing rankings in 2026. But if ChatGPT is quietly leaning on Bing’s index to decide who gets named, ignoring it means missing a real lever.

    What Correlates and What Doesn’t

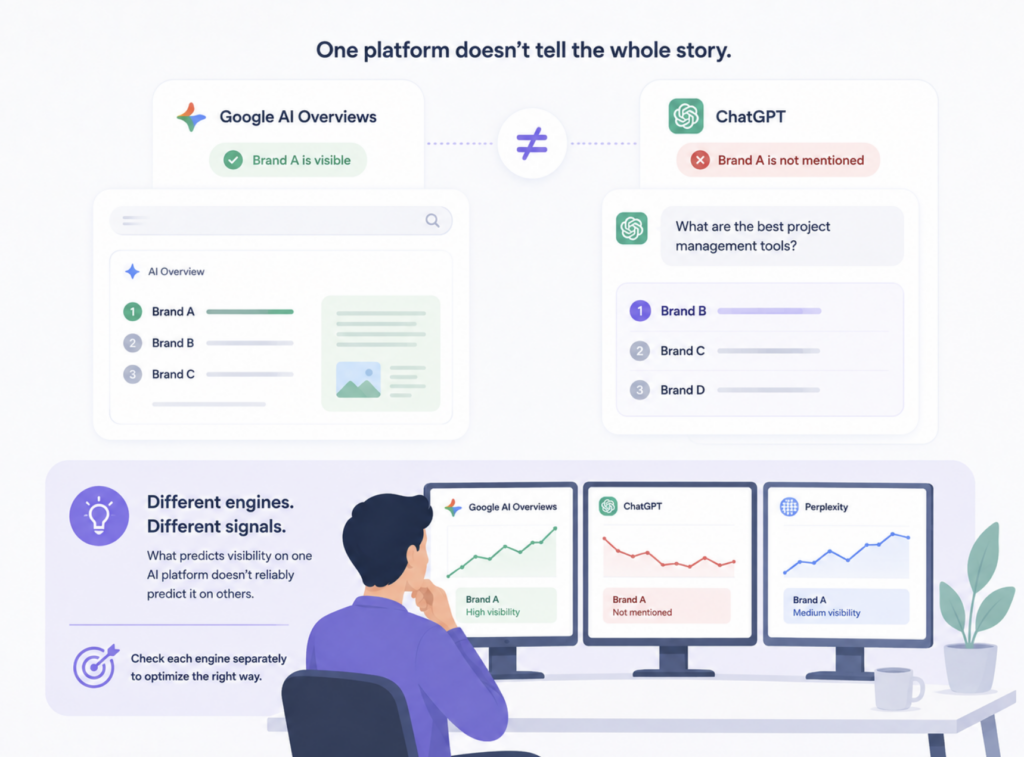
    Not every AI platform plays by the same rules, which is part of why a single-platform check gives you an incomplete picture. Analysis of branded web mentions across roughly 75,000 websites found a clear pattern: <cite index=”6-1″>branded web mentions were the strongest correlating factor for Google AI Overview visibility</cite>. But that same signal barely moved the needle elsewhere. <cite index=”6-1″>Perplexity showed a weak correlation with branded mentions, and ChatGPT an even weaker one</cite>.

    That’s the core problem with running a competitor analysis on just one AI platform. What predicts visibility on Google AI Overviews doesn’t reliably predict visibility on ChatGPT. You need to check each engine separately, or you’re optimizing for the wrong signal.

    What This Means If You’re Running Your Own Competitor Analysis

    A few things worth acting on if you’re setting this up for your own brand:

    Don’t stop at Google rankings. They tell you almost nothing about whether ChatGPT or Perplexity will mention you. Pull actual AI responses and check for yourself.

    Segment by category before you panic. A 50% citation gap in marketing automation isn’t the same red flag as a 50% gap in dev tools. Know your category’s baseline first.

    Check Bing, even if you’ve ignored it for years. It’s quietly become a bigger input into ChatGPT’s answers than most teams assume.

    Track this continuously, not once. AI answers shift as models update and as competitors publish new content. A one-time competitor snapshot goes stale fast. This is exactly what Topify’s Competitor Monitoring is built for: it keeps checking your position against competitors across platforms so you’re not rerunning a manual audit every quarter.

    The trade-off is time. Manually running 200 prompts across three AI platforms, logging every mention, and cross-referencing Google rank takes days if you’re doing it by hand. Automating that comparison is less about convenience and more about being able to catch a shift before a competitor quietly takes your spot in AI answers.

    Conclusion

    The brand we mentioned at the start wasn’t losing to a competitor with better content or a bigger budget. It was losing to a competitor that happened to align better with the signals AI engines actually weigh, consensus across sources, Bing visibility, and category-specific content patterns that have nothing to do with traditional rank.

    Running an AI visibility competitor analysis isn’t about replacing your SEO process. It’s about seeing the part of the competitive landscape that SEO tools were never built to measure.

    FAQ

    What is a competitor analysis for AI visibility? 

    It’s the process of tracking how your brand and your competitors show up across AI platforms like ChatGPT, Perplexity, and Google AI Overviews, measuring mention rate, position, and sentiment rather than traditional search rank.

    How many prompts do you need for a reliable analysis? 

    It depends on your category, but most reliable studies use somewhere between 100 and 250 prompts spread across a range of buyer intents. Fewer than that and you risk drawing conclusions from noise.

    Do I need to check every AI platform, or is one enough? 

    Check more than one. Correlation between traditional SEO signals and AI visibility varies significantly by platform, so a competitor analysis limited to one engine will miss how you’re performing elsewhere.

    Does ranking well on Google still matter for AI visibility? 

    It helps, but it’s not sufficient on its own. It’s the foundation, not the ceiling.

    Read More

  • The AI Visibility Battle: Why Your Competitor Analysis Falls Short

    The AI Visibility Battle: Why Your Competitor Analysis Falls Short

    Your quarterly competitive review probably has a slide for search rankings, one for backlink growth, and one for social share of voice. None of them show what ChatGPT told a prospect who asked for a recommendation in your category last week. That gap doesn’t show up in a rank tracker, and it won’t show up until someone on your team happens to ask the same question a customer already asked an AI. By then, the answer that mattered already happened, and it probably favored someone else.

    Your Competitor Analysis Probably Stops Before It Gets to AI Search

    Most competitive intelligence stacks were built for a world with ten blue links. They track keyword rankings, backlink velocity, paid search spend, and social mentions. None of those dimensions tell you whether an AI platform is recommending you or your competitor when a buyer asks for options.

    That blind spot is common. Only 14% of marketers currently track how their brand shows up in AI-generated answers at all. Everyone else is running competitor analysis on a channel that’s shrinking in influence while ignoring the one that’s growing.

    The disconnect gets worse the closer you look. Pages that rank well on Google used to be a reliable predictor of AI citation. Not anymore. The overlap between top-10 Google rankings and the sources AI Overviews actually cite has dropped from roughly 76% to 38% in under a year. Your rank tracker and your AI visibility are answering two different questions now.

    What AI Visibility Competitor Analysis Actually Means

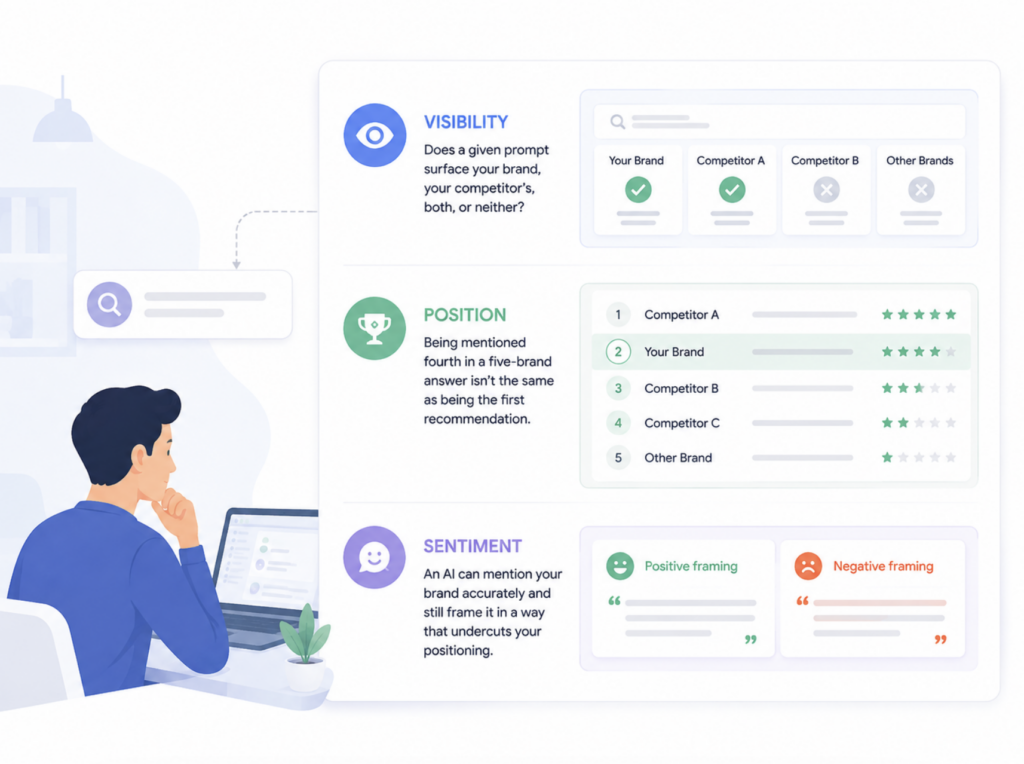
    AI visibility competitor analysis isn’t “check if we rank higher than them.” It’s a comparison across three separate layers: whether you’re mentioned at all, where you land relative to competitors when you are, and how the AI describes you when it does.

    Visibility is the baseline. Does a given prompt surface your brand, your competitor’s, both, or neither? Position matters once you clear that bar. Being mentioned fourth in a five-brand answer isn’t the same as being the first recommendation. Sentiment is the layer most teams skip entirely. An AI can mention your brand accurately and still frame it in a way that undercuts your positioning.

    Run all three side by side against your top two or three competitors, across the prompts your buyers actually use, and you get a real picture of where you stand. Run just one, and you’re guessing.

    The Gap Most Brands Never See

    Here’s the part that doesn’t show up in a monthly report: the brands winning AI visibility aren’t necessarily the ones winning search.

    Top-performing SaaS brands earn 8.4x more AI citations than the median brand in their category, and the gap is widening. Part of the reason is that AI platforms pull the vast majority of what they say about you from somewhere other than your own website. Roughly 79% of AI citations come from third-party domains rather than vendor pages.

    That means your competitor could be losing the SEO fight on paper and still be winning the narrative in ChatGPT, simply because a review site, a comparison article, or a forum thread is doing the talking for them. Your existing competitor analysis has no way to catch that.

    Think about how this plays out in practice. Your team ranks on page one for your category’s main keyword. Your top competitor ranks on page two. On paper, you’re ahead. But a G2 comparison page and a handful of Reddit threads happen to favor your competitor’s positioning, and those are exactly the kinds of pages AI platforms lean on for third-party validation. Ask ChatGPT for a recommendation, and your competitor shows up first. Your rank tracker never flags this, because it isn’t measuring the same thing anymore.

    This is also why B2B discovery is shifting faster than most teams have adjusted for. AI-driven answers now account for 17% of B2B SaaS discovery, up from just 4% a year earlier. A channel growing that quickly deserves its own line in a competitive review, not a footnote under “emerging trends.”

    How to Run a Real AI Visibility Competitor Analysis

    Start with the prompts, not the platforms. Build a list of 15 to 30 real buyer questions: category questions (“best tools for X”), comparison questions (“X vs Y”), and problem-based questions (“how do I solve Z”). These are the moments where AI answers actually shape a purchase decision.

    Run that prompt set across ChatGPT, Perplexity, and Gemini at minimum. Citation behavior and sentiment can shift dramatically depending on the platform, and relying on a single one gives you an incomplete, sometimes misleading picture. Then compare your brand against the same competitors on each of the three layers: visibility, position, and sentiment.

    The last step is tracing citations back to source. If a competitor consistently outranks you in AI answers, find out which domains AI is pulling that recommendation from. That tells you exactly where to focus outreach or content work, instead of guessing.

    Keep a simple scorecard while you do this. For each prompt, log which brands appeared, in what order, and whether the framing was positive, neutral, or negative. After a few rounds, patterns show up fast. Maybe a competitor dominates “best for beginners” prompts but disappears entirely from “enterprise” ones. Maybe your brand shows up consistently but always described with a qualifier that undersells you, like “budget option” when your positioning is premium. Those patterns are the actual output of an AI visibility competitor analysis, and they’re specific enough to act on immediately.

    Don’t skip the sentiment column to save time. A brand that’s mentioned often but described unfavorably isn’t actually winning, even though a visibility-only view would suggest otherwise.

    Where Competitor Monitoring Tools Fit In

    Doing this manually, prompt by prompt, platform by platform, works for a one-time snapshot. It doesn’t scale to weekly or monthly tracking, and AI answers change often enough that a snapshot goes stale fast.

    Topify built Dynamic Competitor Benchmarking specifically for this gap. It automatically detects who’s competing with you across AI platforms, even competitors you haven’t manually added, and tracks Visibility, Sentiment, and Position for all of them side by side. Pair that with Reverse-Engineer AI Citations, which surfaces the exact domains and URLs feeding your competitors’ AI mentions, and you get the source-level detail that a manual prompt audit can’t easily produce at scale.

    If you want to see where you stand against a specific competitor right now, Topify’s AI visibility competitor analysis tool runs that comparison directly, without needing to set up prompt tracking from scratch first.

    Reading the Results Without Overreacting

    One important caveat before you act on any of this: AI answers move.

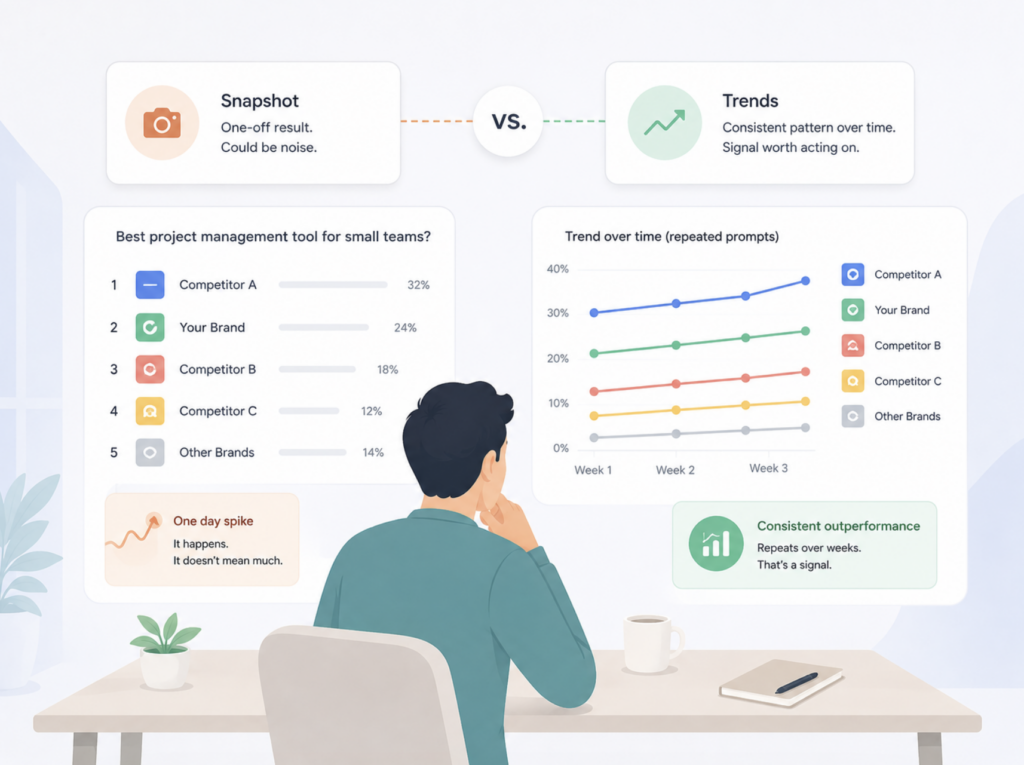
    Citation rates and sentiment can vary by up to 615x depending on the platform, and only about 30% of brands stay visible across back-to-back runs of the exact same query. A single check where a competitor outranks you isn’t proof of a permanent gap. It might just be that day’s answer.

    That’s the real reason to track trends instead of snapshots. If a competitor consistently outperforms you across two or three weeks of repeated prompts, that’s a signal worth acting on. If it’s a one-off, it’s noise.

    Brands that show up both mentioned and cited by name tend to hold their position better over time than brands that only get cited without a direct mention. That’s a useful marker to watch as you build out your own tracking, since it points to which competitors have durable AI visibility and which are just having a good week.

    Conclusion

    The traditional competitor analysis playbook, rankings, backlinks, and social mentions, was never built to answer the question buyers are now asking an AI directly. Closing that gap starts with treating AI visibility as its own dimension of competitive intelligence, tracked across visibility, position, and sentiment, not folded into an SEO report where it doesn’t fit. Start with a handful of real buyer prompts this week, check where you and your top two competitors land, and build the habit of repeating it before the next quarterly review catches you off guard again.

    FAQ

    Q: How is AI visibility competitor analysis different from a traditional competitor analysis? 

    A: Traditional competitor analysis compares rankings, backlinks, and traffic. AI visibility competitor analysis compares whether, where, and how favorably each brand is mentioned inside AI-generated answers, which increasingly draws on a different set of sources than classic search rankings.

    Q: How often should I run this kind of analysis? 

    A: Weekly or biweekly, if possible. AI answers can shift noticeably from one run to the next, so a single check tells you less than a repeated pattern over two or three weeks.

    Q: Which AI platforms should I actually track? 

    A: At minimum, ChatGPT, Perplexity, and Gemini. Citation behavior and sentiment differ enough between platforms that tracking only one can give you a misleading sense of where you actually stand.

    Q: Can a small team without a dedicated SEO person do this? 

    A: Yes. A manual version works fine for an initial check: pick 15 to 20 real buyer prompts, run them across the major AI platforms, and note who gets mentioned and how. Scaling that into ongoing tracking is where a monitoring tool becomes worth the time saved.

    Read More

  • 12 Months of AI Search Volume: What’s Growing, What’s Collapsing

    12 Months of AI Search Volume: What’s Growing, What’s Collapsing

    Your top keywords held position. Your domain authority didn’t move. Then the quarterly report came back with informational pages down double digits, and no core update to point at. The gap isn’t in your rankings. It’s in the layer above them, where an answer gets written before anyone scrolls to a blue link. AI search volume didn’t just grow over the past 12 months. It reallocated, fast enough that a year-old measurement setup is now reporting on a search experience that no longer exists.

    Your Rankings Held. The Clicks Didn’t.

    Start with what collapsed, because it’s the part most dashboards still can’t show you.

    The share of Google searches producing at least one click fell 9.51 percentage points between 2024 and 2026, a relative decline of 22.9%, according to SparkToro data. That figure includes paid clicks and clicks to Google-owned properties, so the drop reaching independent sites is steeper than the headline suggests.

    Position one absorbed most of the damage. When an AI Overview appears, the top organic result’s CTR falls from 31.7% to 19.8%, a 37.5% relative decline, while positions two through five lose about 12%. Ranking first stopped meaning what it meant two years ago.

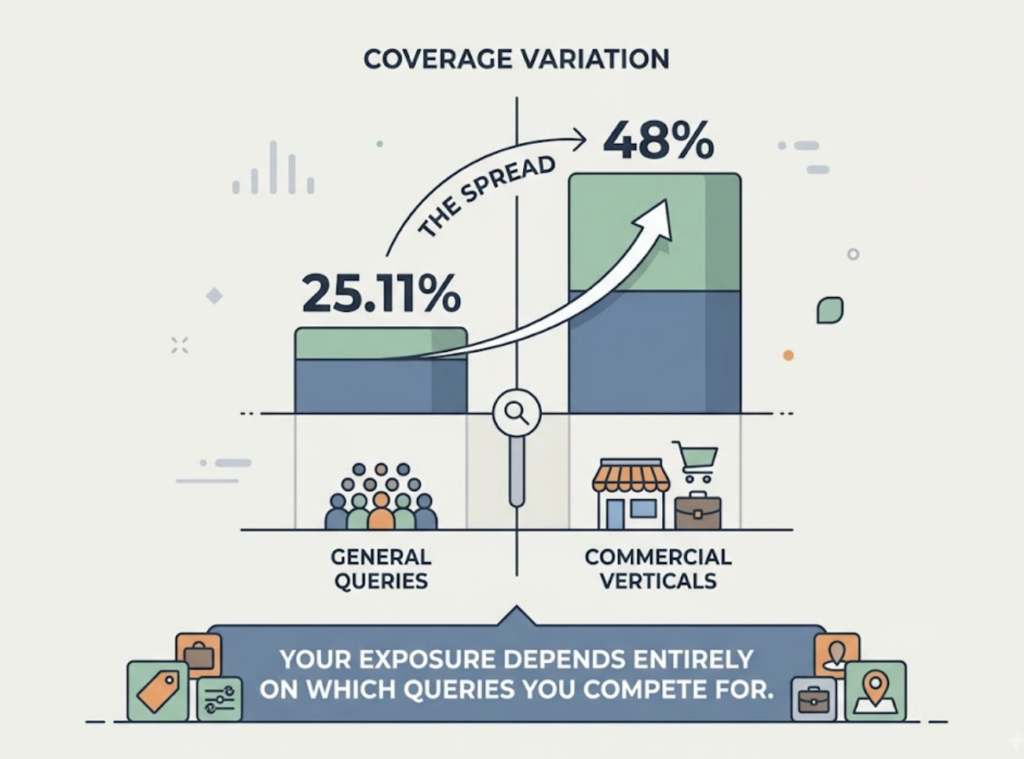
    Coverage kept expanding through the year. Conductor’s Q1 2026 benchmark across 21.9 million queries put AI Overview prevalence at 25.11%, while trackers focused on commercial verticals recorded roughly 48% by March 2026. The spread between those two numbers is itself useful: your exposure depends almost entirely on which queries you compete for.

    Behavioral data confirms the pattern rather than modeling it. Pew Research tracked real browsing sessions and found users clicked a traditional result 8% of the time when an AI Overview was present, against 15% when it wasn’t.

    That’s the collapse. Now the harder question: where did the demand go?

    What Grew in AI Search Volume Was Citation Frequency, Not Traffic

    The instinct is to measure AI search volume the way we measured Google, by counting sessions. That undercounts the shift by an order of magnitude, because most AI answers never produce a session at all.

    The number that actually moved is how often AI systems cite anything. Citation presence in US ChatGPT prompts rose from about 1.6% in June 2025 to roughly 6.8% by May 2026, and the rate splits hard by vertical: around 23% in Travel and Hospitality, around 20% in Automotive, under 4% in Professional Services. If you sell professional services, a citation-only strategy is competing for a very thin slice. If you sell travel, the slice quadrupled while most teams weren’t watching.

    Referral volume grew too, from a small base. One panel of 166 GA4 properties measured 6.77 million LLM-driven sessions and 12.8x growth over 19 months, from 47,606 sessions in November 2024 to 610,910 by May 2026.

    Here’s the part that changes how you value it. LLM-referred visitors convert at roughly 4.4x the rate of organic search visitors, because they arrive with intent already validated by the AI’s recommendation. A channel at 2% of your traffic doing 4x the conversion rate isn’t a rounding error in your reporting. It’s a line item you don’t have.

    Three Reports, Three Different Numbers for the Same Year

    This is where a lot of GEO strategy quietly goes wrong.

    Ask three credible sources what happened to ChatGPT’s share of AI referrals over the last 12 months and you get three incompatible answers. Similarweb’s traffic data shows ChatGPT sliding from roughly 76% of worldwide generative AI web traffic a year ago to around 53%, with Gemini past a quarter and Claude the fastest-growing platform in the category. The GA4 panel above reports 92.4% of AI referral traffic still coming from ChatGPT. A third study of B2B brand sites landed near 62.6%.

    None of them is wrong. They’re measuring different things: total platform web traffic, referral clicks landing on a specific panel of sites, and B2B-weighted brand referrals. Panel composition decides the answer.

    The takeaway isn’t that the industry data is unreliable. It’s that industry averages can’t tell you your number.

    Your category’s platform mix, citation rate, and answer position are properties of your queries, not of the market. That’s the gap a GEO rank tracker fills, and it’s why the tooling question stopped being optional sometime around the middle of last year.

    Why AI Search Volume Doesn’t Show Up in a Keyword Rank Tracker

    Two structural differences make the old instrument unusable here.

    The first is instability. A citation isn’t a ranking that decays over months. SISTRIX’s April 2026 citation drift study across six countries found 54 to 59% of cited domains shift week over week, with ChatGPT replacing roughly 74% of its cited domains each week. Monthly snapshots of something that turns over weekly produce noise, not trend lines.

    The second is that the query you optimize for isn’t the query the engine runs. ChatGPT produced 91% unique queries with only 13% word overlap with what the user typed, while Perplexity stayed close to the original phrasing at 88% overlap. Your keyword list and the engine’s internal fan-out are two different vocabularies, which is why keyword volume alone can’t stand in for AI search volume.

    DimensionKeyword rank trackerGEO rank tracker
    Unit of measurementPosition on a results pageFrequency of appearance inside an answer
    Query inputFixed keyword listPrompt sets, expanded to match engine fan-out
    Update cadence that makes senseWeekly to monthlyDaily to weekly, given citation drift
    Competitive readWho outranks you on one pageWho gets named alongside you, and in what order
    Failure mode it catchesRanking dropSilent removal from the answer with rankings intact

    That last row is the one worth sitting with. A brand can hold every ranking it had in 2025 and be absent from every AI answer in its category, and no traditional report will flag it.

    The Query Types Gaining Volume and the Ones Being Absorbed

    Aggregate volume hides the actual reallocation. Break it down by intent and the picture gets far more actionable.

    AI Overviews started as an informational feature and didn’t stay one. In January 2025, 91.3% of queries triggering an AI Overview were informational. By October 2025 that share had dropped to 57.1%, while navigational triggers went from 0.74% to 10.33%. Commercial intent moved into the overview layer during the same window.

    Comparison queries are now almost fully absorbed. Seer Interactive’s analysis of 49,353 queries found X vs Y comparison formats trigger AI Overviews 95.4% of the time, question formats 85.9%, and review queries 86.3%. If your content strategy leans on comparison and review pages, that traffic is being answered upstream of your page.

    The AI-native platforms tilt the other way. Informational and research queries make up about 58% of ChatGPT Search volume, while purely transactional queries account for roughly 3%. Publishers and top-of-funnel content took the hit first. Ecommerce and transactional pages have been slower to feel it.

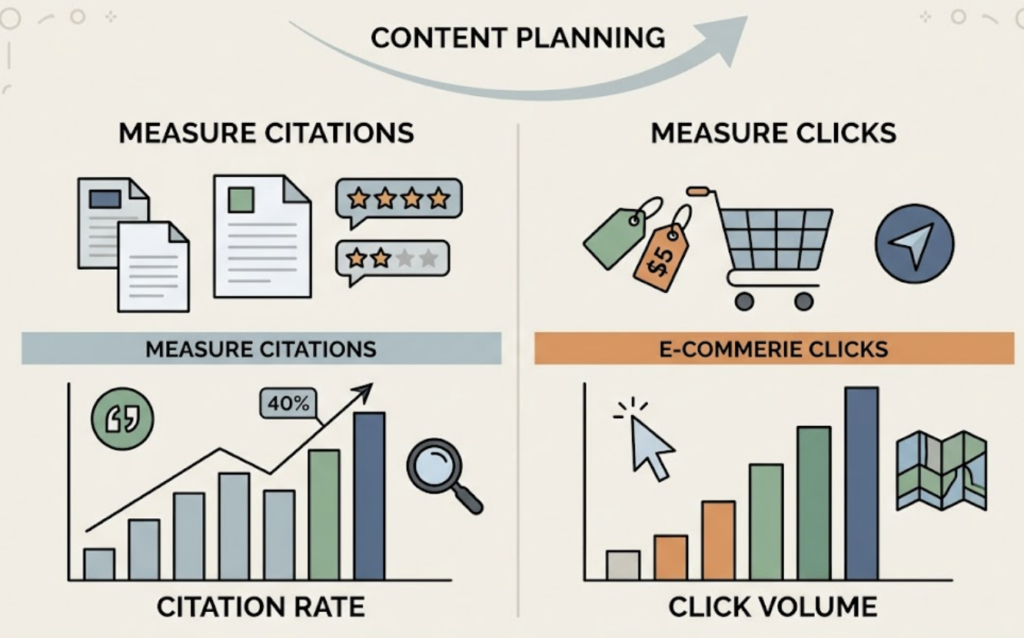
    Read those three datasets together and the planning implication is clear. Comparison, review, and definitional content should be measured on citation rate, not click volume. Transactional and navigational pages should still be measured on clicks, for now.

    Being cited still pays, even on the click side. Per million impressions on informational queries, cited brands take roughly 20,743 clicks against 9,445 for uncited brands on the same AI Overview query. Citation is worth more than double the residual traffic of non-citation.

    What Belongs on Your GEO Rank Tracker for the Next 12 Months

    Given the drift rates and the intent reshuffling above, four things need continuous measurement rather than quarterly audits.

    Cross-platform visibility, weighted to your audience. Platform share disagreements in the public data mean you need your own read on which engines actually send and influence your buyers.

    Prompt-level volume, not keyword volume. Prompt demand and keyword demand are related but not interchangeable, and brand-direct prompts behave differently from open-ended ones: they trigger a site-specific query against the named brand’s domain 40% of the time versus 16% for open-ended prompts. Those are two separate markets inside one category.

    Position relative to competitors, not just presence. Being named third in a five-brand answer is a different outcome from being named first, and presence-only tracking flattens that distinction.

    The source domains behind each answer. With most cited domains rotating weekly, knowing which third-party pages carry your mentions is what makes a visibility drop diagnosable instead of mysterious.

    Topify is built around that combination. It monitors brand performance across ChatGPT, Gemini, Perplexity, and other major engines on seven metrics: visibility, sentiment, position, volume, mentions, intent, and CVR. In practice, that means a drop in ChatGPT mentions can be traced back to a specific source domain that stopped citing you, inside the same view where you spotted the drop. High-value prompt discovery keeps surfacing new prompts as recommendation patterns shift, and competitor benchmarking shows who the engines are naming instead of you. Plans start at $99 per month for 100 tracked prompts, which is roughly the size of a first serious prompt set for a single category.

    Whatever tool you use, the cadence matters more than the vendor. Weekly, at minimum, on a fixed prompt set.

    Conclusion

    The last 12 months didn’t reduce search demand. They relocated it, from a ranked list you could measure with one tool into a synthesized answer that changes composition every week. Clicks fell hardest on the query types that used to feed top-of-funnel content. AI search volume grew fastest in categories most brands weren’t tracking at all.

    Start with your 30 highest-intent prompts, not your keyword list. Measure how often you appear, in what position, and which domains carry the mention. Run it weekly for a quarter. That baseline is worth more than any industry benchmark, because it’s the only number that describes your brand. You can get started with Topify on a single project to see where the gaps sit before committing to a full prompt set.

    FAQ

    Q: What is AI search volume, and how is it different from keyword volume? 

    A: Keyword volume counts how many times a phrase is typed into a search engine. AI search volume describes how much demand flows through prompts on platforms like ChatGPT, Gemini, and Perplexity. The two overlap but don’t map cleanly, since a single keyword can fan out into hundreds of distinct prompts phrased in natural language.

    Q: How do I get AI search volume or prompt volume data? 

    A: There’s no public equivalent of Keyword Planner for AI prompts. Most teams use two proxies: existing keyword volume as a demand signal, and prompt-level tracking of a fixed prompt set to measure how often the brand surfaces. Segment brand-direct prompts from open-ended ones, since they behave differently.

    Q: How is a GEO rank tracker different from a traditional rank tracker? 

    A: A keyword rank tracker answers “where does this page sit on a results page.” A GEO rank tracker answers “does the answer mention us at all, and why.” The difference matters because rankings can stay flat while AI mentions disappear, and no SERP-based report will surface that.

    Q: How often should I track AI citations? 

    A: Weekly at minimum. With more than half of cited domains rotating week over week on major platforms, monthly checks smooth over the exact movements you’d want to act on.

    Read More

  • GEO Rank Tracker: Reverse-Engineer Why Competitors Get Cited

    GEO Rank Tracker: Reverse-Engineer Why Competitors Get Cited

    Your competitor shows up in ChatGPT’s answer for your highest-intent category prompt. You don’t. So you open their page next to yours and look for the difference. Their content is thinner. Their domain authority is lower. Their page loads slower.

    Nothing on that page explains the gap, because the answer wasn’t assembled from that page. It was assembled from a set of third-party sources that mention them and skip you, and that never surfaces in a two-tab comparison. It only surfaces in citation-level data, which is exactly what a GEO rank tracker exists to capture.

    Your Competitor Isn’t Winning on Content. They’re Winning on Sources.

    The default assumption is that AI engines reward better pages. The citation data says otherwise.

    Muck Rack’s 2026 analysis of 25 million cited links across ChatGPT, Claude, and Gemini found that 84% of AI citations trace back to earned media rather than owned content, paid placements, or SEO pages. CiteMetrix, tracking 680 million citations, put the performance gap between earned and owned placements at 325%. AirOps research landed in the same place from a different angle: brands are 6.5x more likely to be discovered through third-party sources than through their own domains.

    The source pool is also narrower than most teams expect. A synthesis of six citation studies covering more than 680 million citations found that the top 15 domains absorb roughly 68% of everything ChatGPT, Claude, Gemini, Perplexity, and Google AI Overviews produce, with Reddit alone cited at around 40% frequency across engines.

    So when a competitor gets recommended and you don’t, the useful question isn’t “what’s better about their page.” It’s “which sources did the model read, and why does your brand not appear inside them.”

    That’s a different investigation, and it needs different data.

    What a GEO Rank Tracker Records the Moment a Competitor Gets Cited

    Most tools marketed as AI rank trackers record a position and stop. Position tells you the outcome. It doesn’t tell you the mechanism.

    A tracker built for attribution captures five layers on every run: the prompt that triggered the answer, which brands were mentioned, the order they appeared in, the specific URLs cited, and the domains those URLs belong to. The last two layers are where reverse-engineering actually happens. Everything above them is a scoreboard.

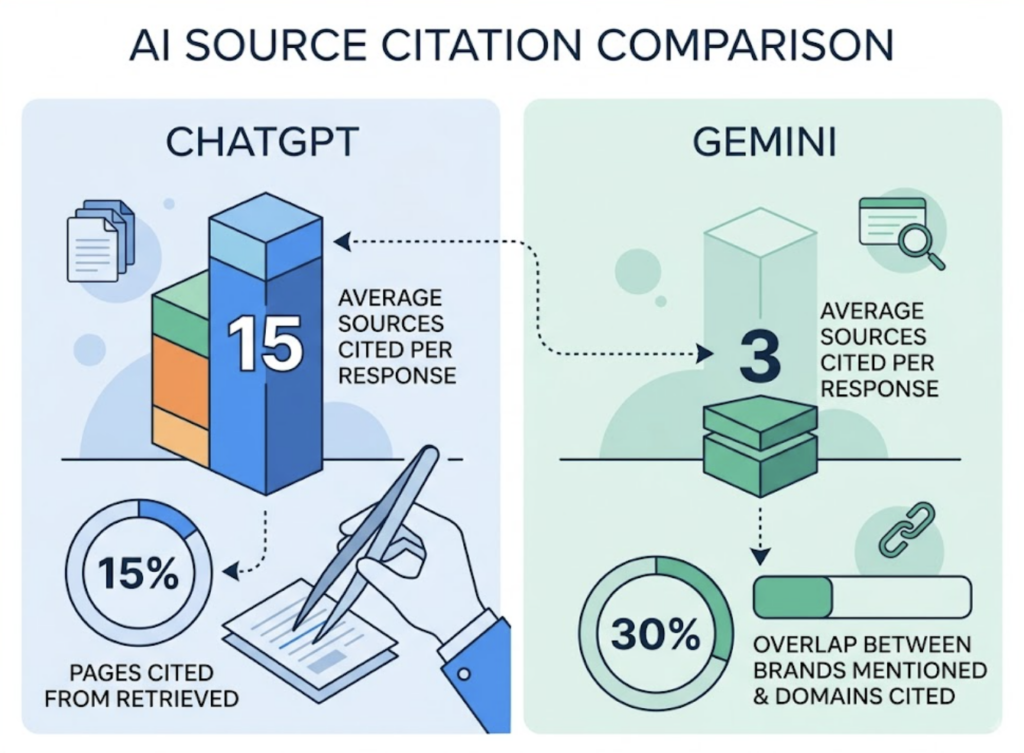
    The gap between layers is measurable. ChatGPT cites an average of 15 sources per response while Gemini cites 3, and on Gemini the overlap between brands mentioned in the text and domains cited underneath can fall to 30%. ChatGPT is also selective about what makes the cut, citing only about 15% of the pages it retrieves for a given query.

    Read those two numbers together and the implication is uncomfortable. A competitor can be named in an answer built almost entirely from sources they don’t own, and your absence can be decided at a retrieval step you never see.

    The Four Citation Gaps Behind Every “Why Them and Not Us”

    Once you have prompt-level citation logs for both brands, the gaps sort into four types. Each one produces a distinct signature in the data, and each one needs a different response.

    Gap typeWhat the tracker showsWhat it actually meansFirst action
    Owned-content gapCompetitor’s own pages cited, yours absentThey have a comparison, pricing, or use-case page that answers the prompt directlyBuild the specific page the prompt asks for, not a broader guide
    Third-party citation gapCited domains are review sites, forums, or editorial, none mentioning youThe sources the model trusts have no record of your brandTarget placement in the exact domains already cited for that prompt cluster
    Narrative gapYour brand appears, but framed as niche, cheap, or secondaryThe model has signal about you, and the signal is off-positionCorrect the description at its source, then re-measure sentiment and position
    Technical gapYour pages are indexed but never retrievedStructure, access, or clarity is blocking the retrieval stepAudit crawler access and answer formatting for the failing prompts only

    A caution on the technical bucket, because it collects a lot of wasted effort. Zyppy’s citation factor analysis scored LLMs.txt at 2.0 out of 10 for influence on AI citations, with no credible evidence it moves the number. Fixing files nobody reads is a comfortable way to avoid the harder source-placement work.

    Mentioned but Never Cited Is a Different Problem Than Never Mentioned

    This distinction decides your entire remediation plan, and most dashboards blur it.

    Being mentioned means the model names your brand. Being cited means the model treats your domain as the source behind the claim. A brand can be recommended by name while the model cites a review site or a competitor’s pageinstead. That gap is diagnostic: absent from the answer entirely points to an awareness problem, while present but never sourced points to a trust problem.

    Academic work supports the split. A 2026 study analyzing 602 controlled prompts across ChatGPT, Google AI Overviews, and Perplexity treated citation and absorption as two discrete stages, not one metric.

    Benchmarks give you a rough read on severity. Category leaders rarely clear 60% AI share of voice because engines diversify sources by design, so treat anything under 15% as a structural citation gap rather than a bad month.

    Five Steps to Reverse-Engineer a Competitor’s Citation Advantage

    Here’s the workflow that turns citation logs into a queue of fixes.

    1. Define the prompt cluster, not the keyword. Pick 30 to 50 prompts a real buyer would type at the comparison stage. Commercial phrasing matters for retrieval: prompts carrying words like reviews, comparison, or a year trigger live web search in ChatGPT 53.5% of the time versus 18.7% for informational queries.

    2. Lock a competitor set of three to five. Include the brands buyers compare you against, plus any name that keeps appearing in answers even though it never showed up in your SEO reports. Those are the ones winning on sources.

    3. Log every cited URL, then classify it. Own domain, review platform, community thread, editorial, directory. The distribution is the finding. If 70% of a competitor’s citations come from community and editorial sources, no amount of on-site optimization closes that.

    4. Map your absence inside their winning sources. Not “do we have a page on this,” but “does the cited page mention us at all.” This is the step teams skip, and it’s the one that produces an actionable target list.

    5. Rank fixes by leverage, not effort. Off-site signals carry the most weight. Ahrefs’ data put branded web mentions at a 0.664 correlation with AI Overview visibility, with YouTube mentions at 0.737, the strongest single factor measured. SE Ranking’s 129,000-domain study found citation rates nearly doubling once a site crossed roughly 32,000 referring domains.

    Bottom line: earn mentions on the pages the engine already cites, before you write anything new.

    Where the Data Lies to You: Volatility, Platform Split, and Sample Size

    One run proves nothing. AI answers regenerate a different brand set on repeat queries, so a single screenshot of a competitor beating you is noise until it repeats.

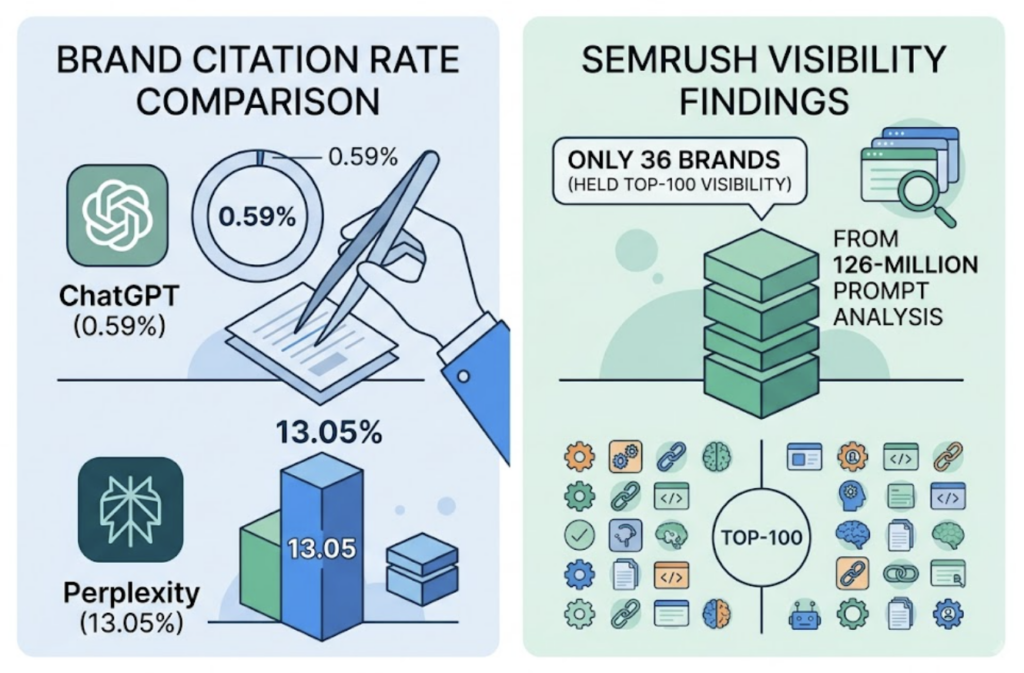
    Platform differences are larger than most teams budget for. A 2026 study of 34,234 AI responses found a 46-times spread in brand citation rates, with ChatGPT citing brands 0.59% of the time and Perplexity at 13.05%. Semrush’s 126-million-prompt analysis found only 36 brands held top-100 visibility across all four major AI platforms.

    A finding on one engine is not a finding on the others. Wikipedia strategy is a clean example: it carries meaningful citation weight inside ChatGPT and close to none inside Claude or Perplexity.

    The practical guardrail is boring. Same prompt set, same competitor set, weekly cadence, raw answers preserved so a change can be audited later. Trend lines survive volatility. Screenshots don’t.

    Turning Citation Intelligence Into an Action Plan

    Most platforms stop at reporting the gap. The work that matters starts one layer down, at the domain and URL level, and it needs to run continuously because citation patterns shift in weeks.

    Topify is built around that layer. Its Reverse-Engineer AI Citations function analyzes the exact domains and URLs AI platforms cite for your prompt set, then shows whether you or your competitors dominate those references at scale. Paired with Dynamic Competitor Benchmarking, you can see which rival is gaining position on a specific prompt cluster and trace the movement back to the sources driving it.

    The seven-metric view matters here more than the feature count. Visibility, sentiment, position, volume, mentions, intent, and CVR sit in one place, which is what lets you separate the mention problem from the citation problem without exporting three dashboards into a spreadsheet.

    Coverage spans ChatGPT, Gemini, Perplexity, DeepSeek, Doubao, Qwen, and other major engines, which matters given how little findings transfer between platforms. High-Value Prompt Discovery keeps surfacing new prompts as recommendation patterns shift, so the tracked set doesn’t go stale while you’re working the current backlog.

    Plans start at $99 per month for 100 prompts and 9,000 AI answer analyses, with a 30-day trial. You can get started on a single prompt cluster before expanding the tracked set.

    Conclusion

    The side-by-side page comparison fails because it’s the wrong unit of analysis. Your competitor’s advantage is usually sitting in a Reddit thread, a review roundup, or an editorial piece that a model trusts and that doesn’t mention you.

    Start narrow. Take the ten prompts closest to purchase in your category, log every cited URL for you and three competitors over four weeks, and classify the sources. The pattern will point at one of the four gaps, and the fix follows from the classification rather than from guesswork.

    Track it. Classify it. Then go earn the mention.

    FAQ

    Why does AI cite my competitor instead of me when my content is better? 

    Because page quality is not the primary input. With 84% of AI citations tracing to earned media, the deciding factor is usually whether the third-party sources an engine trusts mention your brand at all. A competitor with weaker content and stronger source presence will win that prompt.

    What’s the difference between mention share and citation share? 

    Mention share counts how often your brand name appears in AI answers. Citation share counts how often your domain is credited as the source. Being mentioned without being cited signals a trust gap in your content, while being absent from both signals an awareness gap. The two require different fixes.

    How many competitors should a GEO rank tracker cover? 

    Three to five direct competitors is the practical starting point for core category prompts. Add any brand that appears frequently in AI answers even if it never ranked against you in traditional search, since those are often the brands winning on third-party citations.

    How often should I run competitor citation gap analysis? 

    Weekly for measurement, monthly for action. Answers vary between runs, so single-run comparisons are unreliable. Consistent cadence on a fixed prompt set is what makes a genuine competitive shift distinguishable from normal output variance.

    Read More

  • What a GEO Rank Tracker Can’t Tell You About AI Visibility

    What a GEO Rank Tracker Can’t Tell You About AI Visibility

    Your GEO rank tracker says you moved from position 4 to position 2 in ChatGPT last week. Nobody on your team can explain why. Nobody can explain how to hold it, either.

    Run the same prompt again tomorrow and the number may move again, with nothing on your site having changed. Most teams treat that number as a scoreboard. The research on how AI answers actually get assembled suggests it’s closer to a single frame pulled from a film that never plays the same way twice.

    What a GEO Rank Tracker Actually Measures, and What It Leaves Out

    A GEO rank tracker does one specific thing well. It sends a prompt to an AI engine, parses the brands in the response, and records where yours landed in the sequence.

    That’s a snapshot of one generation, from one prompt, on one platform, at one moment.

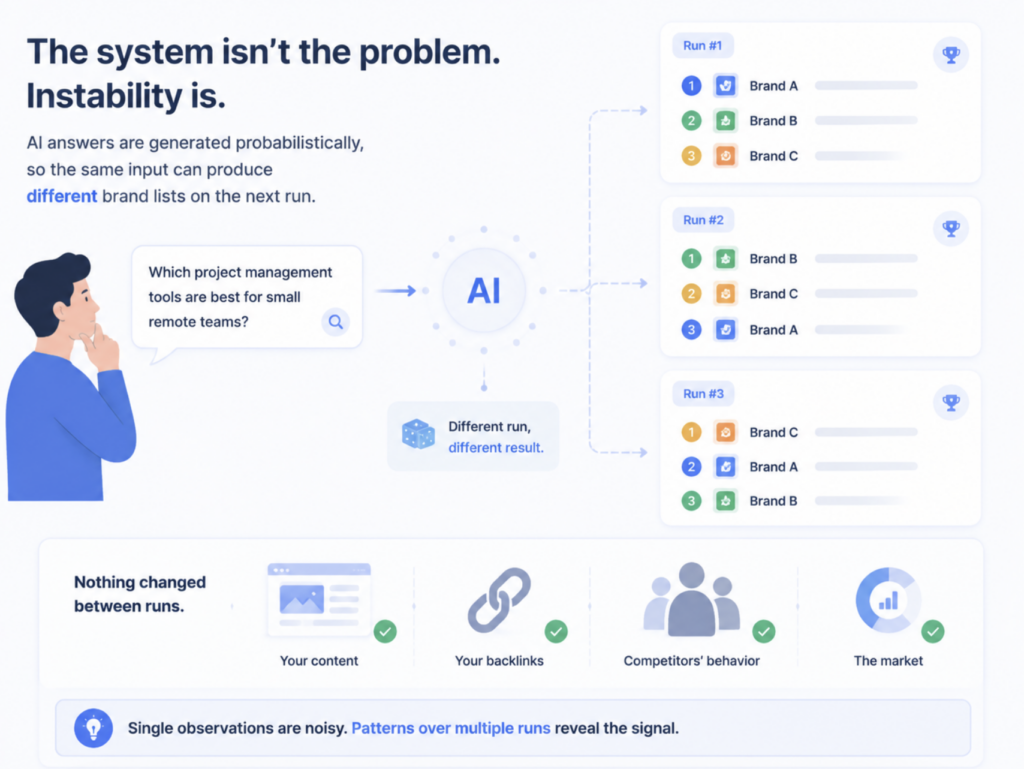
    The problem isn’t that the measurement is wrong. It’s that the underlying system isn’t stable enough for a single observation to mean much. AI answers are generated probabilistically, which means the same input can produce a different brand list on the next run without any change in your content, your backlinks, or your competitors’ behavior.

    Traditional SEO trained everyone to read a position number as a state. In AI search, position is closer to a draw from a distribution. Rank tracking still has a job to do, but the job is narrower than most dashboards imply.

    Ranking First in an AI Answer Isn’t the Same as Being Mentioned Often

    This is the gap that costs teams the most, and it’s now well documented.

    SparkToro ran what remains the largest public test of this question. Working with 600 volunteers, the team ran 12 prompts across ChatGPT, Claude, and Google AI a combined 2,961 times over two months. The result: fewer than 1 in 100 runsreturned the same list of brands for the same prompt, and roughly 1 in 1,000 returned that list in the same order.

    Rand Fishkin’s conclusion was blunt: a tool that reports your “ranking position in AI” is reporting noise.

    But the same dataset contains a second finding that gets quoted far less often. Aggregate appearance rates were considerably more stable. Across categories, the leading brands showed up in a consistent majority of runs even as their order shuffled every time.

    Position and mention frequency are two different variables, and they don’t move together.

    That separation has practical consequences. A brand can hold an average position of 2.1 while appearing in only a third of responses, and a competitor can average position 4 while appearing in 80% of them. The second brand wins almost every real buying conversation. A GEO rank tracker that averages positions across the runs where you appeared will never surface that, because it only measures the runs you were already in.

    The metric that predicts commercial outcomes is how often you’re in the room, not where you sit once you’re there.

    Your GEO Rank Tracker Can’t Tell You Which Sources Built the Answer

    Position is an output. Citations are the input that produced it. Most AI search rank tracking stops at the output.

    Ahrefs compared AI Mode and AI Overviews on the same queries and found they cited the same URLs only 13.7% of the time, while still reaching semantically similar conclusions 86% of the time. Two surfaces from the same company, agreeing on the answer and disagreeing almost completely on where they found it.

    The connection between rankings and citations has also weakened fast. Only 38% of pages cited in AI Overviews still rank in Google’s top 10 for the same query, down from 76% eight months earlier.

    Then there’s where the source material lives. Research from AirOps found that 85% of brand mentions in AI responses originate from third-party pages rather than owned domains, and that brands are roughly 6.5 times more likely to be cited through external sources than through their own site.

    Read those three findings together and the implication is uncomfortable. Your position moved because a Reddit thread, a review roundup, or a comparison article entered or exited the citation pool. Your rank tracker recorded the effect. It has no visibility into the cause, which means it can’t tell you what to go fix.

    A Position Number Says Nothing About How AI Describes You

    Being cited first while being framed as the budget option is not a win. It’s a positioning failure that shows up as a green number on your dashboard.

    Sentiment and position are structurally independent. An engine can lead its answer with your brand and then attach a qualifier that removes you from consideration for the exact buyer you’re targeting. Phrases like “popular but expensive” or “powerful but complex” do more damage than an absent mention, because the reader has already accepted the framing before they reach your site.

    The durability is what makes this different from traditional reputation risk. A social post decays in days. A characterization baked into how a model describes your category can persist across millions of queries until the underlying sources change.

    A GEO rank tracker has no field for any of this. It counts the mention and moves on.

    One Prompt Isn’t a Market, and Sampled Rank Tracking Undercounts

    Every tracking tool works from a prompt list. Real users don’t.

    Semrush’s expanded 2026 AI Visibility Index analyzed 126 million U.S. AI search prompts, a jump from the 2,500 prompts in its original version. That scale gap is the whole issue in one number. A tracker sampling a few dozen prompts per day is estimating your presence across a query space several orders of magnitude larger.

    The undercount runs in one direction. If your brand happens to be strong on a long tail of conversational queries nobody put on the tracked list, the dashboard reports weakness that doesn’t exist. If your tracked prompts happen to be the ones you win, it reports strength that doesn’t generalize.

    Prompt coverage is a measurement decision that most teams make by accident, usually in the first week of setup, and then never revisit.

    Volume context matters just as much. Ranking first on a prompt nobody sends is worth nothing, and the prompts that matter shift as AI-referred traffic grows. AI referral traffic converted 42% better than non-AI traffic in Adobe’s March 2026 analysis, a reversal from converting 38% worse a year earlier. The channel is small and getting more valuable per visit, which raises the cost of pointing your tracking at the wrong queries.

    The Gap Between Knowing Your Rank and Knowing What to Change

    Here’s the practical test for any GEO rank tracker. Your position drops three spots. What does the tool tell you to do?

    For most, the honest answer is nothing. You get a number, a timestamp, and a line on a chart. The diagnosis, the source-level investigation, and the content decision all happen somewhere else, usually in a spreadsheet, usually a week later.

    That gap explains why AI visibility programs stall after the first month. The data arrives, the meeting happens, and no one can point to a specific action with a defensible expected outcome. Only a small fraction of marketing teams currently track AI search performance at all, and among those that do, the bottleneck tends to be interpretation rather than collection.

    Measurement without a causal chain isn’t analytics. It’s weather reporting.

    What Belongs Around a GEO Rank Tracker in a Complete Setup

    None of this means position should be discarded. It means position needs company.

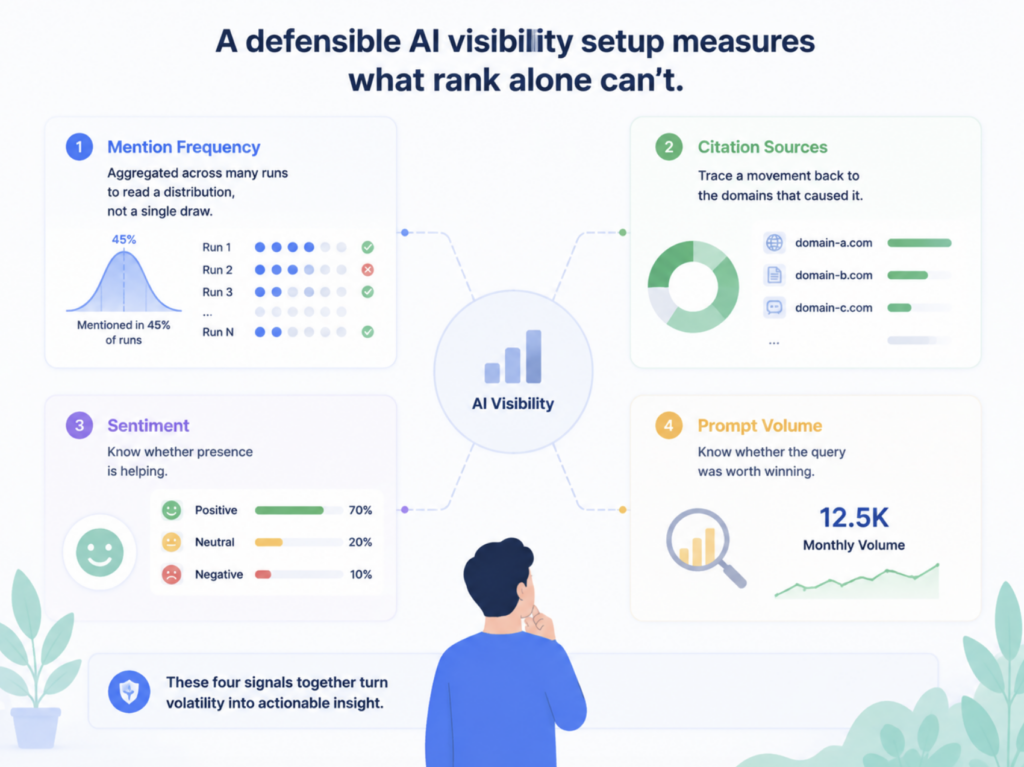
    A defensible AI visibility setup measures four things a rank tracker alone can’t reach. Mention frequency aggregated across many runs, so you’re reading a distribution rather than a draw. Citation sources, so you can trace a movement back to the domains that caused it. Sentiment, so you know whether presence is helping. And prompt volume, so you know whether the query was worth winning.

    geo rank tracker

    Topify was built around that layering. Its GEO analytics run across seven metrics, visibility, sentiment, position, volume, mentions, intent, and CVR, tracked together across ChatGPT, Gemini, Perplexity, DeepSeek, and other engines rather than reported as isolated scores.

    The part that matters operationally is the link between them. When visibility on a prompt cluster drops, the citation analysis shows which domains stopped feeding those answers and which competitor domains took the slot. Competitor benchmarking runs on the same data, so you can see whether a new entrant is pulling from sources you’ve never published on. Prompt discovery keeps the tracked list current as query patterns shift, which is where sampled rank tracking quietly goes stale.

    The output is a diagnosis rather than a score. You can start with a free visibility check before committing to a tracked prompt set, which is usually the fastest way to find out how far your current numbers are from the aggregate picture.

    Conclusion

    A GEO rank tracker answers one question: where did my brand land in this response. That question mattered enormously in an ordered-list era. In generative search, where fewer than 1 in 100 identical prompts return an identical brand list, single-run position is the least stable thing you can measure.

    The metrics that survive the noise are the aggregate ones. How often you appear across many runs. Which sources put you there. How you’re described when you arrive. Whether anyone is asking the question at all.

    If your current reporting can’t answer those four, the position number isn’t telling you much, no matter which direction it’s moving. Start by auditing your prompt list against how your buyers actually phrase things, then add the citation layer underneath it.

    FAQ

    Q: What does a GEO rank tracker actually measure? 

    A: It sends a prompt to an AI engine, identifies the brands in the response, and records the order they appear in. That gives you a position for one generation of one prompt on one platform. It doesn’t measure how often you appear across repeated runs, which sources produced the answer, or how the engine characterized you.

    Q: Is AI search rank tracking useless then? 

    A: Not useless, but narrower than it looks. Single-run position is noisy enough that it shouldn’t drive decisions on its own. Position tracked across many runs and read alongside mention frequency is still useful for spotting directional change. The failure mode is treating one snapshot as a trend line.

    Q: How is a GEO rank tracker different from an SEO rank tracker? 

    A: An SEO rank tracker measures a deterministic system. Query the same keyword twice and you’ll get close to the same result. AI engines generate answers probabilistically, so identical prompts return different brand lists and different orderings. The measurement method carried over from SEO, but the underlying stability didn’t.

    Q: How do I track brand mentions in ChatGPT answers reliably? 

    A: Run each tracked prompt many times rather than once, aggregate the appearance rate across those runs, and treat that percentage as your primary metric instead of average position. Then pair it with citation data so you can trace changes back to specific source domains. Platforms that handle repeated sampling and citation attribution together will get you there faster than manual spot checks.

    Read More

  • What a GEO Rank Tracker Shows When the Model Updates

    What a GEO Rank Tracker Shows When the Model Updates

    Your brand held position two in ChatGPT’s answer for six weeks straight. Then on a Monday it showed up at position six. Nothing on your side had changed: no content edits, no lost backlinks, no competitor campaign. The obvious next move is to start fixing something.

    That’s usually the wrong move. The thing that changed probably wasn’t your site. It was the model underneath the answer. And most GEO rank tracker setups can’t tell those two cases apart, because they report where you stand today instead of what happened across the last sixty days.

    Your GEO Rank Didn’t Drop. The Model Changed Its Mind.

    Three forces move a brand’s position inside an AI answer: your content, your competitors’ content, and the model’s own retrieval and ranking behavior. The first two move slowly. The third moves overnight.

    And “overnight” is now the normal case. Major labs ship a flagship model every 6 to 12 months with point upgrades every few weeks in between, and public trackers log a notable release every few days once open-weight models are counted. OpenAI alone replaced GPT-5.2 with GPT-5.4 on March 5, 2026, then shipped GPT-5.5 seven weeks later.

    Each swap can rewrite how the model retrieves.

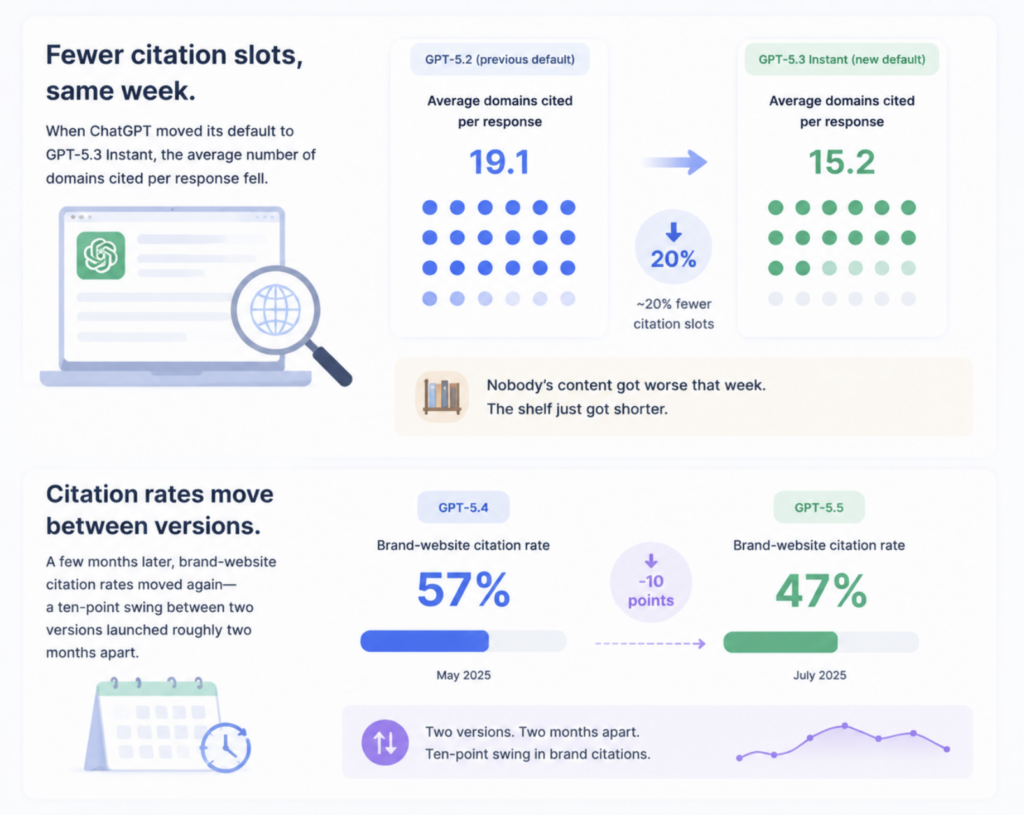
    When ChatGPT moved its default to GPT-5.3 Instant, the average number of domains cited per response fell from 19.1 to 15.2, roughly a 20% cut in citation slots. Nobody’s content got worse that week. The shelf just got shorter. A few months later, brand-website citation rates moved again, from about 57% on GPT-5.4 to about 47% on GPT-5.5, a ten-point swing between two versions launched roughly two months apart.

    Here’s the part that costs teams money. If you reallocated budget toward brand-domain optimization after the first shift, the second shift partially walked it back. A model change is a measurement change before it’s a performance change, and teams that miss that distinction spend a quarter fixing a problem that never existed.

    What a GEO Rank Tracker Measures That a Single Check Can’t

    Most people treat “GEO rank” as one number. It’s at least three, and they don’t move together during a model transition.

    LayerWhat it answersTypical behavior during a model update
    PositionWhere does your brand sit in the recommendation order?Moves first and moves loudest. Highest noise, lowest signal in isolation.
    Mention rateHow often does your brand appear at all across a prompt set?Moves slower. A real drop here is the one worth acting on.
    Citation sourceWhich domains does the model pull from to justify the answer?Often moves before the other two. The best early indicator.

    Position is the metric everyone screenshots and the one least worth reading alone. AI answers are non-deterministic by design: roughly 70% of content changes between repeated runs of the same query, and only about 30% of brands stay visible in back-to-back responses. Against that baseline, a two-place move on a single check tells you almost nothing.

    The citation layer is where model updates show their hand earliest. If the mix of domains behind your category’s answers shifts from vendor sites toward community and editorial sources, the retrieval policy changed. Your rank is downstream of that, and no amount of on-page work will reverse it.

    The 60-Day Curve: How Long Model Update Volatility Actually Lasts

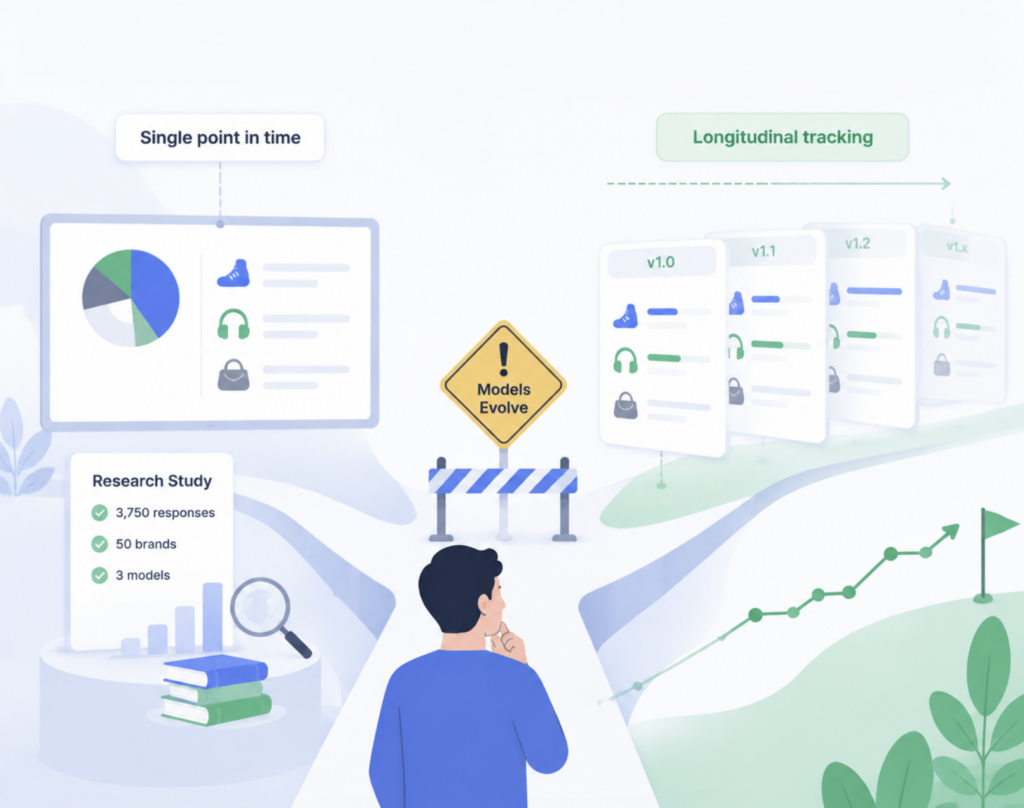
    A useful longitudinal window has three parts: 14 days of pre-update baseline, the transition itself, and 30 to 60 days of post-update observation.

    The pre-update baseline is the part teams skip, and it’s the part that makes everything else interpretable. Without it you have no noise floor, which means you have no way to say whether a six-point move is a real event or a normal Tuesday.

    After a transition, the pattern usually looks like a spike in variance followed by a new plateau. Where the plateau lands is the actual finding. Some brands return close to their old position within a few weeks, and practitioners tracking through transitions generally report partial recovery in the 4 to 8 week range when the cause is model behavior rather than competitive displacement.

    Some brands don’t come back. That’s the case worth catching early, because it means the new retrieval policy structurally deprioritized the kind of source your visibility was built on. Waiting for it to “settle” wastes the window when a content correction still compounds.

    The distinction between those two outcomes only exists in time-series data. A snapshot shows you the same number in both scenarios.

    Rank Moves, Mentions Don’t. Most Dashboards Only Watch One.

    This is the finding most GEO rank tracking misses, and it holds at scale.

    Semrush’s 2026 AI Visibility Index analyzed 126 million U.S. AI search prompts from January through April 2026 and found that being mentioned and being cited are separate outcomes. On Gemini, the overlap between mentioned brands and cited domains can run as low as 30%. You can be the brand the model names and not the source it trusts, or the source it trusts and not the brand it names.

    Recent academic work on the SEO-to-GEO transition points the same direction: traditional search metrics tend to predict where a brand lands within an AI answer, but they’re weak predictors of how often the brand gets mentioned at all. Ranking and mention frequency behave like two independent curves.

    Which means a dashboard that only plots position can show a clean recovery while your mention rate keeps sliding.

    It also explains why measurement gaps are so common. The same Semrush research found 45% of marketing leaders can’t accurately measure their brand’s presence in AI answers, and only 9% have tooling that covers the full metric set across platforms.

    Three Signals That Tell You It’s the Model, Not Your Content

    Before you change a single page, run these three checks. They take an afternoon and they’ll save you a quarter.

    Signal 1: Your competitors moved too. Pull position data for the top five brands in your category over the same window. If four of five shifted in the same direction on the same date, you’re looking at a category-wide re-ranking, not a brand-specific problem. Nothing you publish will unwind it.

    Signal 2: The source mix changed shape. Compare the domain types cited before and after. A swing from first-party vendor pages toward community platforms, review sites, or news is a retrieval policy change. Your fix is third-party presence, not more on-domain content.

    Signal 3: Sentiment held while position fell. If the model still describes your brand in the same terms but ranks it lower, its evaluation of you didn’t change. Its ordering logic did. That’s a model event, and the response is patience plus source diversification, not a rewrite.

    If all three point the same way, log the date as a model event and hold your content roadmap. If none of them do, the problem is yours and it’s fixable.

    How to Run Your Own Longitudinal GEO Rank Study

    Five steps. The discipline matters more than the tooling.

    1. Lock a prompt set of 30 to 60 buyer-intent queries. Fewer than 25 and single-prompt noise dominates the trend. Cover definitions, comparisons, alternatives, and purchase-decision phrasings, not just your brand name.

    2. Prioritize repeated runs over a bigger list. Because variance lives at the run level, a 50-prompt set run 10 times tells you more about stability than a 500-prompt set run once. Weekly cadence at minimum. Daily during a known transition.

    3. Freeze the set for the full cycle. Adding or dropping prompts mid-comparison changes what you’re measuring and quietly invalidates the trend. Version the library and date every change.

    4. Annotate model release dates on the timeline. This is the step that turns a chart into an explanation. Without event markers you have a squiggle. With them you have attribution.

    5. Refuse to act on a delta that doesn’t clear the noise floor. Most week-over-week movement in AI visibility reporting is variance being narrated as strategy. Set a threshold before you look at the data, not after.

    One caveat worth stating plainly. Even published research runs into this: a 2026 multi-industry study of brand ownership in AI recommendations covering 3,750 responses across 50 brands and 3 models flagged its own single-point-in-time design as the main limitation, noting that only longitudinal tracking would show how recommendation patterns evolve as models update. If a research team with 250 controlled queries hits that wall, a monthly dashboard check definitely does.

    Where a GEO Rank Tracker Earns Its Keep

    Everything above is doable by hand. It just doesn’t survive contact with a real workload, because the three things that make it work are continuous sampling, cross-platform synchronization, and event annotation. Miss any one and the attribution breaks.

    That’s the gap Topify was built to close. Its GEO analytics layer tracks seven metrics on the same timeline, including visibility, position, mentions, sentiment, and CVR, so you can see whether a position drop came with a mention drop or without one. That single comparison resolves most model-update false alarms in about a minute.

    Two other pieces matter during transitions. Competitor benchmarking runs against the same prompt set on the same schedule, which gives you Signal 1 without assembling it manually. And citation analysis reverse-engineers the exact domains and URLs the platforms are pulling from, which is where a retrieval policy change becomes visible before your rank reacts.

    Coverage spans ChatGPT, Gemini, Perplexity, DeepSeek, Doubao, Qwen, and others. That breadth is what keeps a single platform’s release schedule from being mistaken for a global trend. Plans start at $99/mo, and you can set up a tracked prompt set and start building baseline data in an afternoon.

    Build the baseline before the next release, not after it.

    Conclusion

    Model updates aren’t an edge case in GEO. They’re the background condition, arriving faster than most reporting cycles can absorb. A brand that reads every position change as a content problem will spend its budget chasing phantoms, and a brand that dismisses every change as noise will miss the one drop that was structural.

    The difference between those two failures isn’t a better metric. It’s a longer window. Set a 14-day baseline, freeze your prompt set, mark the release dates, and separate mention rate from position before you touch anything. Do that once, and the next model swap becomes an event you can explain instead of a fire you have to fight.

    FAQ

    Q: Does a model update reset my GEO rank? 

    A: Not usually a full reset, but it can reorder recommendations within days. What actually changes is retrieval behavior: which sources the model trusts and how many it cites. Position follows from that, which is why the citation layer is the better early indicator.

    Q: How often should a GEO rank tracker re-measure? 

    A: Weekly is the floor for stable trend data. Move to daily for the two weeks surrounding a known model release, since that’s when variance peaks and when the recovery curve is actually readable.

    Q: My rank dropped after a model update. Should I change my content now? 

    A: Run the three signals first. If competitors moved with you and the source mix shifted, hold your roadmap and wait 4 to 8 weeks. If your mention rate dropped while competitors held steady, that’s a content and authority problem worth acting on immediately.

    Q: Can free tools handle longitudinal GEO rank tracking? 

    A: Free checkers give you a useful snapshot of where you stand today. Longitudinal work needs a frozen prompt set, repeated runs, and stored history across platforms, which is where a dedicated tracker becomes the practical option.

    Read More

  • 90 Days of GEO Rank Tracker Data: What Actually Moved the Needle

    90 Days of GEO Rank Tracker Data: What Actually Moved the Needle

    Your GEO rank tracker showed your brand at an average position of 4.1 in March and 3.6 in May. Your VP asks what you did to earn that. You scroll back through the changelog: a pricing page rewrite, two comparison posts, a schema fix, one podcast appearance. Any of them could explain it. None of them explains it alone.

    The uncomfortable part is that a chunk of that movement probably wasn’t yours. On the platforms most buyers use, recommendation lists reshuffle on their own every few days, which means a lot of what shows up in a rank chart is the platform breathing, not your work landing.

    Rank Movement in a GEO Rank Tracker Is Mostly the Platform Breathing

    The largest public 90-day panel on this question ran 1,247 buyer-intent prompts every single day across eight AI platforms, producing 897,840 answers between March and May 2026. Across that set, 17% of prompts returned a different set of recommended brands than they had the day before, and the median brand list survived unchanged for just five days.

    Over the full 90 days, the top-recommended brand flipped at least once for 65% of prompts.

    Stability varies by almost 3x depending on which platform your GEO rank tracker is pointed at.

    PlatformDaily brand-set churnMedian unchanged streak#1 brand flipped in 90 days
    Perplexity27%3 days84%
    Google AI Mode23%4 days78%
    ChatGPT18%5 days69%
    Google AI Overviews13%7 days58%
    Gemini11%9 days49%
    Claude9%11 days41%

    Not all of that is real movement. When the same prompts were re-run ten times inside a single hour, ChatGPT came back with a different brand set in only 7% of pairs. Roughly a third of the day-over-day churn is sampling noise. The rest is the platform genuinely changing its mind.

    Academic work points the same direction. A daily tracking study across four AI engines and four verticals found that visibility has to be treated as a probability across repeated runs rather than a fixed value, with brand sets overlapping only 45% to 59% between runs of an identical prompt.

    Two caveats before you build a quarterly plan on these numbers. The panel skews US, English-language, and B2B software, and it runs clean sessions with no personalization or chat history. Your buyers carry both, which adds variance on top.

    Three Signals That Moved GEO Rank, and Two That Didn’t

    Once you strip out the noise, the levers that correlate with real position gains look nothing like a traditional SEO checklist.

    Third-party review presence moved the most. A study of over 800,000 AI responses across ChatGPT, Gemini, Perplexity, and Google AI Mode sorted brands into four tiers by review profile depth. Brands with no profile had a median AI citation rate of 1%. Brands with even a minimal profile, as few as 1 to 13 reviews, jumped to 53.5%. That’s a 52-point swing from a setup task.

    geo rank tracker

    The effect concentrates where it matters commercially. Review and trust sites are a small slice of citations at the awareness stage and grow 10 to 20 times by the decision stage.

    Earned brand mentions moved second. Analysis of 75,000 brands found that YouTube mentions correlate with AI visibility at 0.737 and branded web mentions at 0.664, both measured on the Spearman scale.

    Source freshness moved third. Cited content runs meaningfully newer than organic top-10 results, and on retrieval-heavy platforms the pages behind your position rotate weekly. Keeping the sources that mention you current is closer to maintenance than to campaign work.

    Now the two that didn’t.

    Backlinks correlate at 0.218 in the same 75,000-brand dataset, and domain rating at roughly 0.18. Both are positive. Neither explains much. Publishing volume performs worse still, with content volume landing near 0.194, meaning the number of pages on your site has almost no bearing on whether AI systems name your brand.

    One honest conflict is worth flagging. One analysis of AI Overview results reports that multi-modal content shows 156% higher selection rates than text-only pages, while a separate agency study found multi-modal content moved results far less than expected. The evidence here isn’t settled, so treat image and video additions as a hypothesis to test rather than a rule to adopt.

    Why Your Citation Sources Move Rank Faster Than Your Page Edits

    Here’s the thing most teams get backwards. You don’t optimize a page into an AI answer slot. You influence which sources get pulled when the answer is assembled.

    The gap between those two ideas is now measurable. The overlap between Google’s top-10 rankings and the sources cited in AI answers collapsed from around 75% in mid-2025 to between 17% and 38% by early 2026. Winning the old surface stopped guaranteeing the new one.

    Citation slots also rotate hard. In Google AI Overviews, the same URL holds its citation for an average of 3.87 consecutive days, and 91% of tracked URLs were dropped at some point during the study window.

    That’s why a rewrite of your own page often produces nothing in the GEO ranking data while a single new third-party comparison article moves three prompts at once.

    Prompt specificity matters here too. A test across 5,000 local queries found URL overlap between identical runs as low as 18% to 20% on vaguely phrased prompts, with specificity nearly doubling stability. If your tracked prompt set is full of “best CRM” rather than “HIPAA-compliant CRM for small clinics,” you’re measuring a noisier signal than you need to.

    The Lag Between Doing the Work and Seeing It in GEO Ranking Data

    Most GEO experiments get killed before they resolve.

    Edit-to-citation lag varies by an order of magnitude across engines, from a median of about two days on Perplexity to roughly a month on Gemini, with a meaningful share of edits never reflected at all. Broader timeline estimates converge on first signals at 4 to 8 weeks and meaningful citation patterns at 3 to 6 months, with one 2026 breakdown putting consistent citation at 8 to 12 weeks of active work.

    Platform updates add a second trap. On days when a model refresh shipped, brand-set churn spiked to 2.7 times baseline and took four to six days to settle. A team that reads that spike as a strategy failure and rolls back its changes has just destroyed its own trend line.

    Two operating rules follow. Don’t evaluate a GEO change on a window shorter than six weeks. And when churn spikes across every category at once rather than in the one you touched, wait a week before concluding anything.

    Ranking Higher and Getting Mentioned More Are Not the Same Win

    This is the part a position-only dashboard hides.

    Analysis of 541,213 LLM responses across 20 brands and six platforms found a brand’s citation rate was 53.1% when the brand was named in the response and 10.6% when it wasn’t. The proposed mechanism is that the model chooses which brands to name from trained memory first, then retrieves sources to support those choices. Citations behave like a bibliography, not a brainstorm.

    If that’s directionally right, then climbing from position 4 to position 2 inside answers you already appear in is a different achievement from getting named in answers where you’re currently absent. The first is an ordering problem. The second is a memory problem.

    Research from Topify’s own team, currently under academic review, points the same way: traditional SEO metrics predict where a brand lands inside an AI answer but not how often the brand gets named at all. Ranking and mention frequency separate.

    That’s the gap most rank trackers still can’t show you.

    What a GEO Rank Tracker Has to Show You Besides Position

    Everything above adds up to a fairly specific tool requirement. Position alone is a noisy, partial, single-platform metric. To act on GEO ranking data you need the mention layer, the citation layer, and the competitive axis in the same view, sampled often enough to see through the churn.

    Topify is built around that combination. It tracks seven metrics in parallel, visibility, sentiment, position, volume, mentions, intent, and CVR, so a position drop can be checked against whether your mention rate fell with it or held steady. Those are two different problems with two different fixes, and a position-only chart can’t distinguish them.

    The citation layer is where attribution usually gets settled. Topify’s citation analysis surfaces the exact domains and URLs the platforms pulled for a given prompt, which turns “our rank moved” into “a review aggregator that used to list us dropped us in week six.” Pair that with competitor benchmarking on the same prompt set and you can tell whether you slipped or a rival simply landed three new placements. Coverage spans ChatGPT, Gemini, Perplexity, DeepSeek, Doubao, and Qwen, which matters if any part of your audience searches outside the US.

    Entry pricing starts at $99 per month for 100 tracked prompts and 9,000 AI answer analyses, which is roughly the sampling density the volatility data suggests you need.

    How to Run a 90-Day GEO Rank Test That Survives Scrutiny

    The method matters more than the tool. Five decisions do most of the work.

    Freeze your prompt set. Pick 50 to 200 prompts that mirror real buyer questions and don’t change them mid-quarter. Swapping prompts destroys the trend line you’re trying to read.

    Sample repeatedly, then report frequency. Run each prompt several times per platform per window and report the share of runs your brand appeared in, not a yes or no from a single check. Practitioners generally land on 5 to 10 runs per prompt per engine.

    Hold conditions constant. Same time of day, clean sessions, fixed geography. Otherwise you’re measuring your own setup drift.

    Change one variable at a time. The single most common reason teams can’t explain their own GEO ranking data is that they shipped four things in the same sprint.

    Wait out the lag before you judge. Six weeks minimum, longer on model-led platforms.

    Run that for a quarter and you’ll have something defensible: a baseline, a noise floor, and a short list of changes with dates attached. You can set up a tracked prompt set in Topify and let the first 30 days establish the baseline before you change anything.

    Conclusion

    Ninety days of data doesn’t make AI search predictable. It makes it legible. The honest read is that recommendation lists turn over every three to eleven days depending on platform, roughly a third of what a GEO rank tracker shows on a given day is sampling noise, and the changes that reliably move real position are off-site: review presence, earned mentions, and fresh third-party sources.

    Start by measuring properly. Freeze a prompt set, sample it repeatedly for 30 days without touching anything, and find out what your brand’s natural variance actually looks like. Only then will a rank change mean something when you report it.

    FAQ

    Q: What’s the difference between a GEO rank tracker and a traditional SEO rank tracker? 

    A: An SEO rank tracker measures where a page appears in a results list. A GEO rank tracker measures whether a brand appears inside a generated answer, in what order relative to competitors, which sources the engine cited, and how the brand was described. The output is probabilistic, so it has to be sampled repeatedly rather than checked once.

    Q: How often should I check my GEO rankings? 

    A: Daily or near-daily on the platforms your buyers use, with weekly review of the aggregate trend. Median brand-list persistence runs three to seven days on the most-used platforms, so weekly manual checks miss entire appearance windows.

    Q: My position improved but my mention rate didn’t. What does that mean? 

    A: You got better ordering inside answers you were already appearing in, without expanding into new prompts. Position work responds to on-page and comparative content. Mention rate responds to off-site brand presence. They need different fixes.

    Q: How many prompts do I need to track for the data to be meaningful? 

    A: Fifty is a workable floor for a single category, and 100 to 200 covers a mid-sized product line with room for competitor prompts. What matters more than raw count is repeated sampling per prompt and keeping the set frozen across the measurement window.

    Read More

  • Why Prompt Search Volume Is the Metric Marketers Are Missing

    Why Prompt Search Volume Is the Metric Marketers Are Missing

    Your keyword report says the category term you own gets 8,000 searches a month, and you’re sitting at position three. Then a buyer opens ChatGPT and types twenty-three words about their team size, their budget, and the tool they already run. Not one of those words appears in your keyword tool. The answer names three vendors. Yours isn’t among them.

    Nothing in your reporting stack explains what happened, because that stack counts strings typed into a search box, not questions asked of a model. Prompt search volume is the number built to close that gap, and most dashboards still don’t have a row for it.

    Keyword Volume Stops Working When Nobody Types Keywords

    The shape of demand changed before the measurement did.

    Google’s average US query has held steady at 3.33 to 3.36 words for most of a year, then climbed past 3.51 words by May 2026 after AI Mode rolled out. That’s a modest move. Inside AI assistants, the move isn’t modest at all: SOCi’s 2026 Visibility Index found LLM queries average 23 words, roughly six times a traditional search query.

    Semrush’s database of over 239 million prompts shows the same pattern at scale. Prompts routinely run fifteen to twenty-five words and carry context, constraints, and qualifications that never survive the trip into a keyword field.

    Volume didn’t disappear. It changed shape.

    And the scale is no longer a rounding error. ChatGPT alone handles more than 2.5 billion prompts per day across roughly 900 million weekly active users. Every one of those prompts is demand your keyword tool has no way to see.

    What Prompt Search Volume Actually Measures

    Prompt search volume is the estimated number of times a given prompt, or a cluster of similar prompts, gets submitted to AI platforms in a month. Think of it as the AI-era counterpart to keyword search volume, with one difference that matters: no AI platform publishes this data.

    That means every number you see is modeled. Vendors build estimates from panel data, systematic prompt sampling, extrapolation from related keyword demand, and observed answer behavior. Methodologies differ, so two tools can disagree on the same topic.

    What the data does reveal is composition, and composition is where the strategy lives. A Search Engine Land survey of how people actually prompt found that 24.5% of prompts include the word “best”, 28% mention price or budget, 16% are explicitly location-based, and 32% include personal attributes such as profession, life stage, or health condition.

    Those aren’t keywords. They’re qualifying conditions, and they decide which brands make the shortlist.

    The Long Tail Didn’t Get Longer. It Got Personal.

    Here’s the shift that breaks the old model. In an August 2025 survey, roughly half of free-text prompts were still SEO-keyword-shaped: short, ambiguous, brand-and-attribute driven. By January 2026, that share had fallen to about 30%.

    The other 70% grew longer and more contextualized.

    You can’t win those prompts by matching phrasing, because the phrasing is close to one-of-a-kind. You win them by covering the constraint. A page that says “CRM software for small teams” competes weakly against a page that specifies seat counts, pricing tiers, migration paths from named incumbents, and what happens when a ten-person team doubles.

    That’s the practical difference between a keyword strategy and a prompt search strategy. One targets a phrase. The other targets a decision.

    Prompt Search Volume Tells You Where Demand Is Moving

    Keyword volume describes a channel that’s mature and measurable. Prompt search volume describes one that’s growing and partially blind. Running only the first is comfortable. Running only the second is reckless.

    DimensionKeyword search volumePrompt search volume
    Data sourceEngine-reported query and click logsModeled from panels, sampling, extrapolation
    Typical query shape3 to 4 words15 to 25 words with context
    RepeatabilityStable month over monthHigh share of one-off phrasings, clustered by topic
    What it predictsRanking opportunity on a results pageWhether your brand enters the answer at all
    How to read itAbsolute numbers are usableTrends beat absolute numbers

    The useful move is watching the ratio per topic. When a topic’s AI demand starts outrunning its Google demand, answer-first content moves up the queue for that topic and only that topic.

    Two more numbers make the case for paying attention. ChatGPT performs a live web search on roughly 31% of prompts, with the model’s own behind-the-scenes queries averaging 5.48 words. And according to Ahrefs data cited by Search Engine Land, AI search visitors convert at 23 times the rate of traditional organic visitors, even though the raw session count is far smaller.

    Fewer sessions, much higher intent. That’s a channel worth measuring properly.

    Where Prompt Search Data Gets Oversold

    Now the honest part, because vendors tend to skip it.

    Prompt volume estimates are directional. Treat a specific number the way you’d treat an analyst forecast: useful for ranking priorities, unreliable as a headline figure in a board deck.

    The bigger issue is answer variance. Growth Memo’s analysis of prompt tracking methodology found that only 2.3% of citations survive three runs of the same prompt. Run a prompt once and you’ve flipped a coin with the result hidden from you.

    So single-prompt testing tells you almost nothing. Repeated runs across a stable prompt set, tracked over weeks, tell you a lot.

    Three practical guardrails. Track trends inside one tool rather than comparing absolute numbers across vendors. Run each prompt multiple times before you record a result. Refresh monthly for stable categories and weekly for fast-moving ones like AI tooling, finance, and tech.

    How to Put Prompt Search Volume to Work in 30 Days

    Start by building a controlled prompt set instead of chasing a leaderboard. Pick five to ten topics you want AI systems to associate with your brand, then write prompts across the funnel for each: category discovery, comparison, objection, and purchase.

    Layer in the constraint patterns the data already surfaced. Budget, team size, location, and personal context show up in a large share of real prompts, so your set should reflect that instead of testing clean category terms nobody actually types.

    Then run the set consistently and record four things: whether you appear, which competitors appear, which sources get cited, and how your brand gets described.

    This is where tooling stops being optional, because doing it by hand across four platforms and fifty prompts is a full-time job. Topify tracks volume as one of seven metrics alongside visibility, sentiment, position, mentions, intent, and CVR, so a spike in prompt demand for a topic sits next to whether you’re actually showing up for it. Its High-Value Prompt Discovery surfaces new high-volume prompts as AI recommendation patterns shift, and its citation analysis maps the exact domains and URLs the models pull from, which is usually where the fixable gap turns out to be.

    Coverage matters here too. Prompt demand splits across ChatGPT, Gemini, Perplexity, and regional engines including DeepSeek, Doubao, and Qwen, and a tool that only reads one platform will miss most of the picture. Plans start at $99 a month for 100 tracked prompts, and you can get started with a trial before committing budget.

    Bottom line on sequencing: map intent, cluster into topics, prioritize by prompt search volume, validate with repeated manual testing, then track visibility over time. Prompt volume is the prioritization input, not the whole program.

    Conclusion

    The buyer who skipped your brand in that ChatGPT answer didn’t type a keyword. They described a situation, and the model matched that situation to whichever sources covered it best. Prompt search volume is the first metric that puts a number on how often those situations come up in your category.

    It’s modeled data, it varies between vendors, and it deserves skepticism on any single figure. It’s also the only demand signal that maps to how a growing share of your market now asks questions. Run it alongside keyword volume, watch the ratio per topic, and move answer-first content to the front of the queue when AI demand starts winning.

    The teams that build this measurement habit now will be reading trend lines while everyone else is still guessing.

    FAQ

    Q: What is prompt search volume?
    A: It’s the estimated number of times a specific prompt, or a cluster of closely related prompts, is submitted to AI platforms like ChatGPT, Gemini, Perplexity, and Google AI Mode in a given month. It plays the same prioritization role that keyword search volume plays in traditional SEO.

    Q: Is prompt search volume data accurate?
    A: It’s directional rather than exact. AI platforms don’t publish prompt-level data, so every estimate is modeled from panels, sampling, and extrapolation. Use it to rank priorities and read trends over time, not to report precise monthly figures.

    Q: Does prompt search volume replace keyword research?
    A: Not yet, and probably not entirely. Google still handles the majority of global queries, and many AI prompts mirror underlying keyword demand. The workable approach in 2026 is running both side by side: keyword volume for SEO, prompt search volume for GEO and AEO.

    Q: How often should you track prompt search volume?
    A: Monthly works for most categories. Fast-moving verticals such as AI tools, finance, and tech benefit from weekly checks, while stable categories can be reviewed quarterly. Consistency inside one tool matters more than frequency.

    Read More