Blog

  • 90 Days of GEO Rank Tracker Data: What Actually Moved the Needle

    90 Days of GEO Rank Tracker Data: What Actually Moved the Needle

    Your GEO rank tracker showed your brand at an average position of 4.1 in March and 3.6 in May. Your VP asks what you did to earn that. You scroll back through the changelog: a pricing page rewrite, two comparison posts, a schema fix, one podcast appearance. Any of them could explain it. None of them explains it alone.

    The uncomfortable part is that a chunk of that movement probably wasn’t yours. On the platforms most buyers use, recommendation lists reshuffle on their own every few days, which means a lot of what shows up in a rank chart is the platform breathing, not your work landing.

    Rank Movement in a GEO Rank Tracker Is Mostly the Platform Breathing

    The largest public 90-day panel on this question ran 1,247 buyer-intent prompts every single day across eight AI platforms, producing 897,840 answers between March and May 2026. Across that set, 17% of prompts returned a different set of recommended brands than they had the day before, and the median brand list survived unchanged for just five days.

    Over the full 90 days, the top-recommended brand flipped at least once for 65% of prompts.

    Stability varies by almost 3x depending on which platform your GEO rank tracker is pointed at.

    PlatformDaily brand-set churnMedian unchanged streak#1 brand flipped in 90 days
    Perplexity27%3 days84%
    Google AI Mode23%4 days78%
    ChatGPT18%5 days69%
    Google AI Overviews13%7 days58%
    Gemini11%9 days49%
    Claude9%11 days41%

    Not all of that is real movement. When the same prompts were re-run ten times inside a single hour, ChatGPT came back with a different brand set in only 7% of pairs. Roughly a third of the day-over-day churn is sampling noise. The rest is the platform genuinely changing its mind.

    Academic work points the same direction. A daily tracking study across four AI engines and four verticals found that visibility has to be treated as a probability across repeated runs rather than a fixed value, with brand sets overlapping only 45% to 59% between runs of an identical prompt.

    Two caveats before you build a quarterly plan on these numbers. The panel skews US, English-language, and B2B software, and it runs clean sessions with no personalization or chat history. Your buyers carry both, which adds variance on top.

    Three Signals That Moved GEO Rank, and Two That Didn’t

    Once you strip out the noise, the levers that correlate with real position gains look nothing like a traditional SEO checklist.

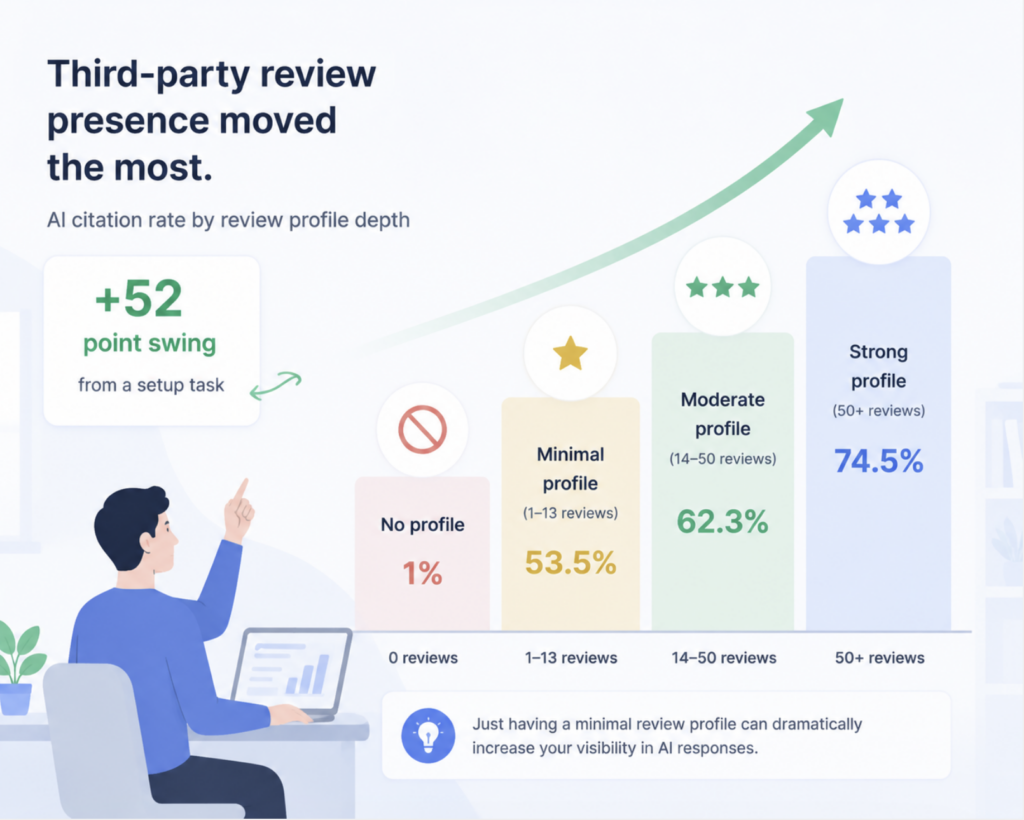
    Third-party review presence moved the most. A study of over 800,000 AI responses across ChatGPT, Gemini, Perplexity, and Google AI Mode sorted brands into four tiers by review profile depth. Brands with no profile had a median AI citation rate of 1%. Brands with even a minimal profile, as few as 1 to 13 reviews, jumped to 53.5%. That’s a 52-point swing from a setup task.
    geo rank tracker

    The effect concentrates where it matters commercially. Review and trust sites are a small slice of citations at the awareness stage and grow 10 to 20 times by the decision stage.

    Earned brand mentions moved second. Analysis of 75,000 brands found that YouTube mentions correlate with AI visibility at 0.737 and branded web mentions at 0.664, both measured on the Spearman scale.

    Source freshness moved third. Cited content runs meaningfully newer than organic top-10 results, and on retrieval-heavy platforms the pages behind your position rotate weekly. Keeping the sources that mention you current is closer to maintenance than to campaign work.

    Now the two that didn’t.

    Backlinks correlate at 0.218 in the same 75,000-brand dataset, and domain rating at roughly 0.18. Both are positive. Neither explains much. Publishing volume performs worse still, with content volume landing near 0.194, meaning the number of pages on your site has almost no bearing on whether AI systems name your brand.

    One honest conflict is worth flagging. One analysis of AI Overview results reports that multi-modal content shows 156% higher selection rates than text-only pages, while a separate agency study found multi-modal content moved results far less than expected. The evidence here isn’t settled, so treat image and video additions as a hypothesis to test rather than a rule to adopt.

    Why Your Citation Sources Move Rank Faster Than Your Page Edits

    Here’s the thing most teams get backwards. You don’t optimize a page into an AI answer slot. You influence which sources get pulled when the answer is assembled.

    The gap between those two ideas is now measurable. The overlap between Google’s top-10 rankings and the sources cited in AI answers collapsed from around 75% in mid-2025 to between 17% and 38% by early 2026. Winning the old surface stopped guaranteeing the new one.

    Citation slots also rotate hard. In Google AI Overviews, the same URL holds its citation for an average of 3.87 consecutive days, and 91% of tracked URLs were dropped at some point during the study window.

    That’s why a rewrite of your own page often produces nothing in the GEO ranking data while a single new third-party comparison article moves three prompts at once.

    Prompt specificity matters here too. A test across 5,000 local queries found URL overlap between identical runs as low as 18% to 20% on vaguely phrased prompts, with specificity nearly doubling stability. If your tracked prompt set is full of “best CRM” rather than “HIPAA-compliant CRM for small clinics,” you’re measuring a noisier signal than you need to.

    The Lag Between Doing the Work and Seeing It in GEO Ranking Data

    Most GEO experiments get killed before they resolve.

    Edit-to-citation lag varies by an order of magnitude across engines, from a median of about two days on Perplexity to roughly a month on Gemini, with a meaningful share of edits never reflected at all. Broader timeline estimates converge on first signals at 4 to 8 weeks and meaningful citation patterns at 3 to 6 months, with one 2026 breakdown putting consistent citation at 8 to 12 weeks of active work.
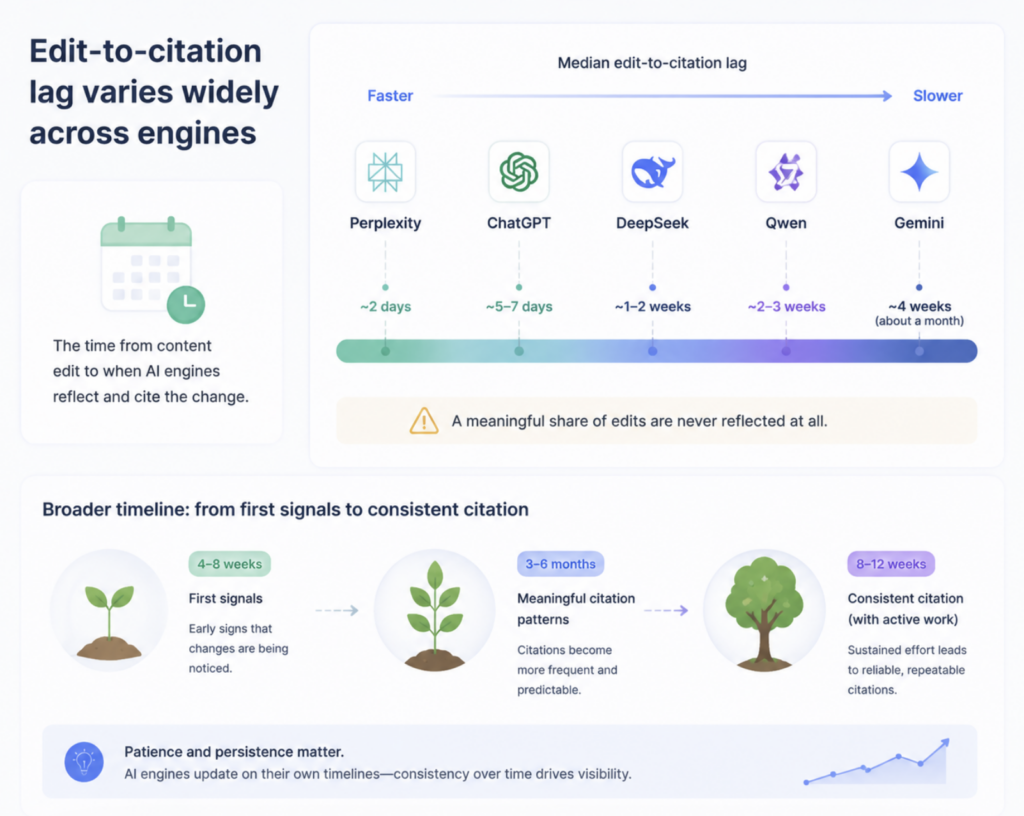
    Platform updates add a second trap. On days when a model refresh shipped, brand-set churn spiked to 2.7 times baseline and took four to six days to settle. A team that reads that spike as a strategy failure and rolls back its changes has just destroyed its own trend line.

    Two operating rules follow. Don’t evaluate a GEO change on a window shorter than six weeks. And when churn spikes across every category at once rather than in the one you touched, wait a week before concluding anything.

    Ranking Higher and Getting Mentioned More Are Not the Same Win

    This is the part a position-only dashboard hides.

    Analysis of 541,213 LLM responses across 20 brands and six platforms found a brand’s citation rate was 53.1% when the brand was named in the response and 10.6% when it wasn’t. The proposed mechanism is that the model chooses which brands to name from trained memory first, then retrieves sources to support those choices. Citations behave like a bibliography, not a brainstorm.

    If that’s directionally right, then climbing from position 4 to position 2 inside answers you already appear in is a different achievement from getting named in answers where you’re currently absent. The first is an ordering problem. The second is a memory problem.

    Research from Topify’s own team, currently under academic review, points the same way: traditional SEO metrics predict where a brand lands inside an AI answer but not how often the brand gets named at all. Ranking and mention frequency separate.

    That’s the gap most rank trackers still can’t show you.

    What a GEO Rank Tracker Has to Show You Besides Position

    Everything above adds up to a fairly specific tool requirement. Position alone is a noisy, partial, single-platform metric. To act on GEO ranking data you need the mention layer, the citation layer, and the competitive axis in the same view, sampled often enough to see through the churn.

    Topify is built around that combination. It tracks seven metrics in parallel, visibility, sentiment, position, volume, mentions, intent, and CVR, so a position drop can be checked against whether your mention rate fell with it or held steady. Those are two different problems with two different fixes, and a position-only chart can’t distinguish them.

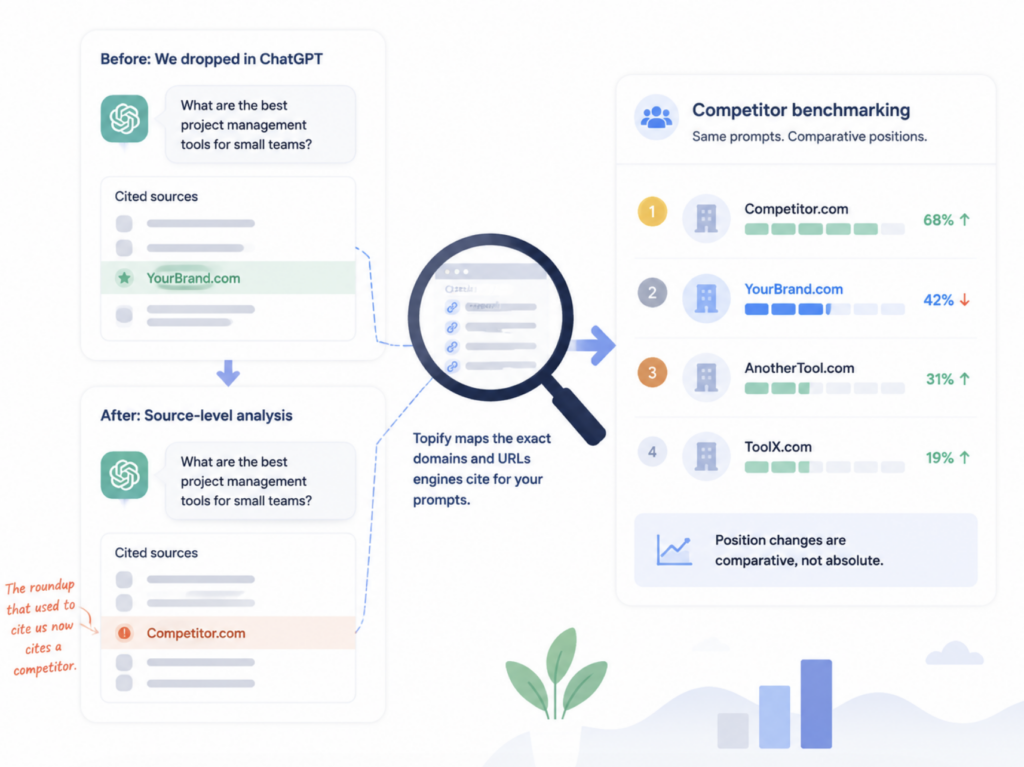
    The citation layer is where attribution usually gets settled. Topify’s citation analysis surfaces the exact domains and URLs the platforms pulled for a given prompt, which turns “our rank moved” into “a review aggregator that used to list us dropped us in week six.” Pair that with competitor benchmarking on the same prompt set and you can tell whether you slipped or a rival simply landed three new placements. Coverage spans ChatGPT, Gemini, Perplexity, DeepSeek, Doubao, and Qwen, which matters if any part of your audience searches outside the US.

    Entry pricing starts at $99 per month for 100 tracked prompts and 9,000 AI answer analyses, which is roughly the sampling density the volatility data suggests you need.

    How to Run a 90-Day GEO Rank Test That Survives Scrutiny

    The method matters more than the tool. Five decisions do most of the work.

    Freeze your prompt set. Pick 50 to 200 prompts that mirror real buyer questions and don’t change them mid-quarter. Swapping prompts destroys the trend line you’re trying to read.

    Sample repeatedly, then report frequency. Run each prompt several times per platform per window and report the share of runs your brand appeared in, not a yes or no from a single check. Practitioners generally land on 5 to 10 runs per prompt per engine.

    Hold conditions constant. Same time of day, clean sessions, fixed geography. Otherwise you’re measuring your own setup drift.

    Change one variable at a time. The single most common reason teams can’t explain their own GEO ranking data is that they shipped four things in the same sprint.

    Wait out the lag before you judge. Six weeks minimum, longer on model-led platforms.

    Run that for a quarter and you’ll have something defensible: a baseline, a noise floor, and a short list of changes with dates attached. You can set up a tracked prompt set in Topify and let the first 30 days establish the baseline before you change anything.

    Conclusion

    Ninety days of data doesn’t make AI search predictable. It makes it legible. The honest read is that recommendation lists turn over every three to eleven days depending on platform, roughly a third of what a GEO rank tracker shows on a given day is sampling noise, and the changes that reliably move real position are off-site: review presence, earned mentions, and fresh third-party sources.

    Start by measuring properly. Freeze a prompt set, sample it repeatedly for 30 days without touching anything, and find out what your brand’s natural variance actually looks like. Only then will a rank change mean something when you report it.

    FAQ

    Q: What’s the difference between a GEO rank tracker and a traditional SEO rank tracker? 

    A: An SEO rank tracker measures where a page appears in a results list. A GEO rank tracker measures whether a brand appears inside a generated answer, in what order relative to competitors, which sources the engine cited, and how the brand was described. The output is probabilistic, so it has to be sampled repeatedly rather than checked once.

    Q: How often should I check my GEO rankings? 

    A: Daily or near-daily on the platforms your buyers use, with weekly review of the aggregate trend. Median brand-list persistence runs three to seven days on the most-used platforms, so weekly manual checks miss entire appearance windows.

    Q: My position improved but my mention rate didn’t. What does that mean? 

    A: You got better ordering inside answers you were already appearing in, without expanding into new prompts. Position work responds to on-page and comparative content. Mention rate responds to off-site brand presence. They need different fixes.

    Q: How many prompts do I need to track for the data to be meaningful? 

    A: Fifty is a workable floor for a single category, and 100 to 200 covers a mid-sized product line with room for competitor prompts. What matters more than raw count is repeated sampling per prompt and keeping the set frozen across the measurement window.
    Read More

  • We Ran One Prompt 500 Times. Here’s What a GEO Rank Tracker Sees

    We Ran One Prompt 500 Times. Here’s What a GEO Rank Tracker Sees

    You checked ChatGPT three times last week to see whether your brand came up in your category. First run, you were there. Second run, gone. Third run, you were back but listed fourth instead of second.

    So which number goes in the monthly report? That question is the entire problem with treating AI search like a ranking board, and it’s the reason a GEO rank tracker has to work differently from anything in your SEO stack.

    The Setup: One Prompt, 500 Runs, Five Engines

    We took a single high-intent commercial prompt, the kind a real buyer types when they’re two weeks from a purchase decision, and ran it 100 times each across ChatGPT, Gemini, Perplexity, Claude, and Google AI Overviews. Same wording. Same day. No personalization, no session history.

    For every response we logged three things: whether the target brand appeared at all, where it sat in the ordering when it did appear, and which domains got cited underneath.

    The point wasn’t to measure one brand. It was to answer a more basic question: does “rank” survive contact with a system that generates a fresh answer every time?

    The short version is that it survives, but not in the shape most teams assume.

    A Single Check Isn’t a Rank. It’s an Anecdote

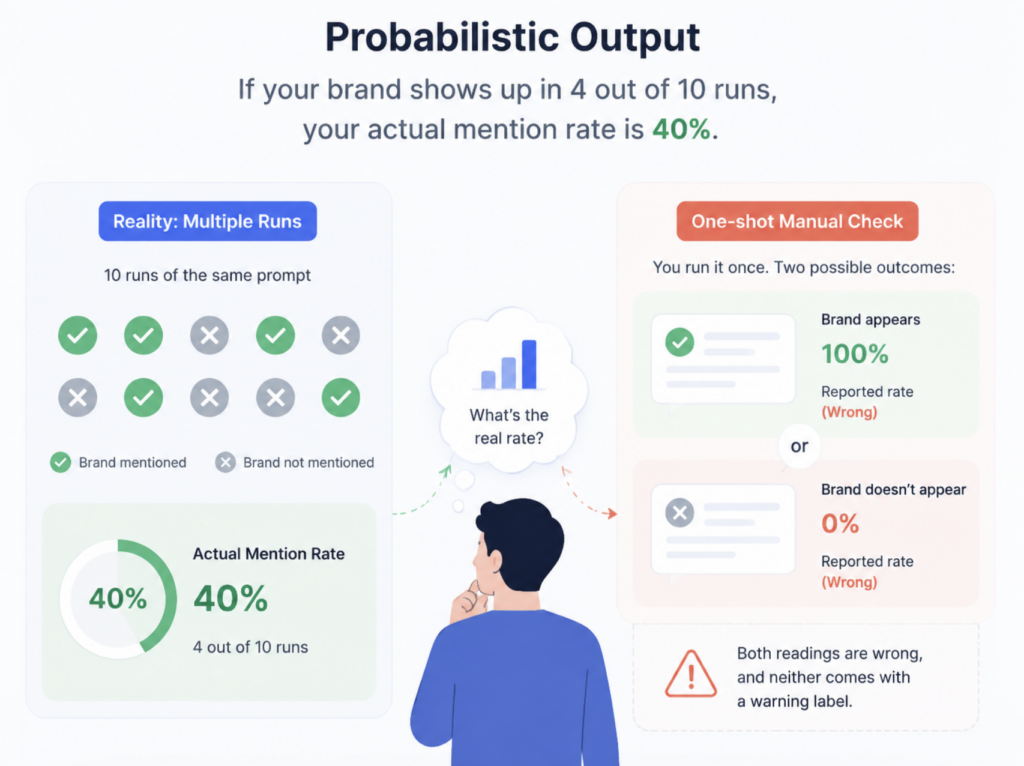
    Here’s the thing about probabilistic output. If your brand shows up in 4 out of 10 runs, your actual mention rate is 40%. A one-shot manual check reports either 0% or 100% depending on which run you happened to catch. Both readings are wrong, and neither comes with a warning label.

    This isn’t a quirk you can configure away. Even at temperature zero, the same prompt can produce different outputs across runs because of floating-point non-associativity combined with dynamic batching on the inference side. Variance is baked into the infrastructure.

    The measurement layer inherits that. As iPullRank puts it in their AI search manual, share of voice in generative search is a statistical distribution of presence over many trials, not a static percentage of positions held.

    One check is not a data point. It’s a coin flip you wrote down.

    The instability compounds over time, too. Independent analyses suggest 40 to 60% of AI citations rotate every month for mid-sized B2B brands, and that 73.4% of specific URLs get cited exactly once before vanishing from AI answers entirely.

    Mention Rate Moved a Lot. Position Barely Did.

    This was the finding that changed how we read the data.

    Across the 500 runs, whether the brand appeared swung far more than where it appeared. On three of the five engines, mention rate moved by double digits between the first 50 runs and the second 50. But in the runs where the brand did appear, its ordinal position clustered tightly, usually within a single slot of its median.

    Two different signals. Two different failure modes. Most dashboards collapse them into one number called “rank” and lose both.

    There’s academic backing for the split. Research on the structural gap between search engine and generative AI brand visibility found that traditional SEO strength predicts a brand’s ranking position inside an AI answer reasonably well, but predicts its mention frequency poorly. Being strong enough to get listed and being retrieved often enough to get listed are governed by different mechanics.

    Semrush’s study of 1,094 subject areas in ChatGPT points the same direction from another angle. Only 21% of the most-cited domains in a category were also the most-mentioned brand, and the two signals correlate slightly negatively at -0.229.

    That matters operationally. If your mention rate is falling but your position holds, you have a retrieval problem and you need more citable surface area. If your mention rate is stable but your position slides, you have a framing problem and competitors are being described as the better fit.

    Same “rank drop.” Opposite fixes.

    Five Engines, Five Different Answers to the Same Question

    Run-to-run variance was real. Cross-engine variance was bigger.

    The gap between what ChatGPT said and what Perplexity said, given identical input, exceeded the gap between any single engine’s best and worst run. That tracks with the published research. One analysis of 50 buyer-intent prompts found that ChatGPT, Perplexity, and Gemini named the same brand only 21% of the time, with over half of all brand mentions coming from just one engine.

    The citation layer diverges even harder. Across 680 million AI citations analyzed in early 2026, only 11% of domains were cited by both ChatGPT and Perplexity. Yext’s look at 6.8 million citations found very little overlap in what each model cites, with each engine weighting source types on its own logic.

    So tracking one engine isn’t partial coverage. It’s a systematic bias, and it points in a direction you can’t predict from the engine you did measure.

    The corollary is worse for reporting: a blended cross-engine average hides exactly the thing you’d act on. A brand at 60% on Gemini and 5% on ChatGPT averages to a perfectly unremarkable 32%.

    What This Means for Your GEO Rank Tracker

    Work backward from the variance and the tool requirements write themselves.

    RequirementSingle-check approachSampling-based GEO rank tracker
    Sample size1 run per promptDozens of runs per prompt, reported as a rate
    Metric structureOne blended “rank” scoreMention rate and position tracked separately
    Engine coverageOne engine, extrapolatedEach engine reported independently
    CadenceMonthly or ad hocWeekly minimum, daily for volatile categories
    Competitor contextAbsentSame prompt set, same sampling, side by side

    Search Engine Land’s overview of the category makes the same point about methodology: variable outputs mean tracking requires consistent monitoring and statistical sampling rather than spot checks.

    Cadence deserves its own note. Monthly monitoring is effectively no monitoring when citation sets turn over at 40 to 60% in that same window. By the time you see the change, you can’t attribute it to anything.

    And frequency without competitor context still leaves you blind. If your citation rate holds flat at 15% while a rival climbs from 10% to 40%, your number didn’t move but your share collapsed.

    Where Topify Fits

    The reason we ran this test at all is that it maps directly onto how measurement should be built.

    Topify reports seven metrics separately rather than folding them into a single score: visibility, sentiment, position, volume, mentions, intent, and CVR. Visibility answers how often you appear across a defined prompt set. Position answers where you land when you do. Keeping them apart is what makes the mention-versus-position diagnosis possible in the first place, and it’s the difference between knowing your number dropped and knowing why.

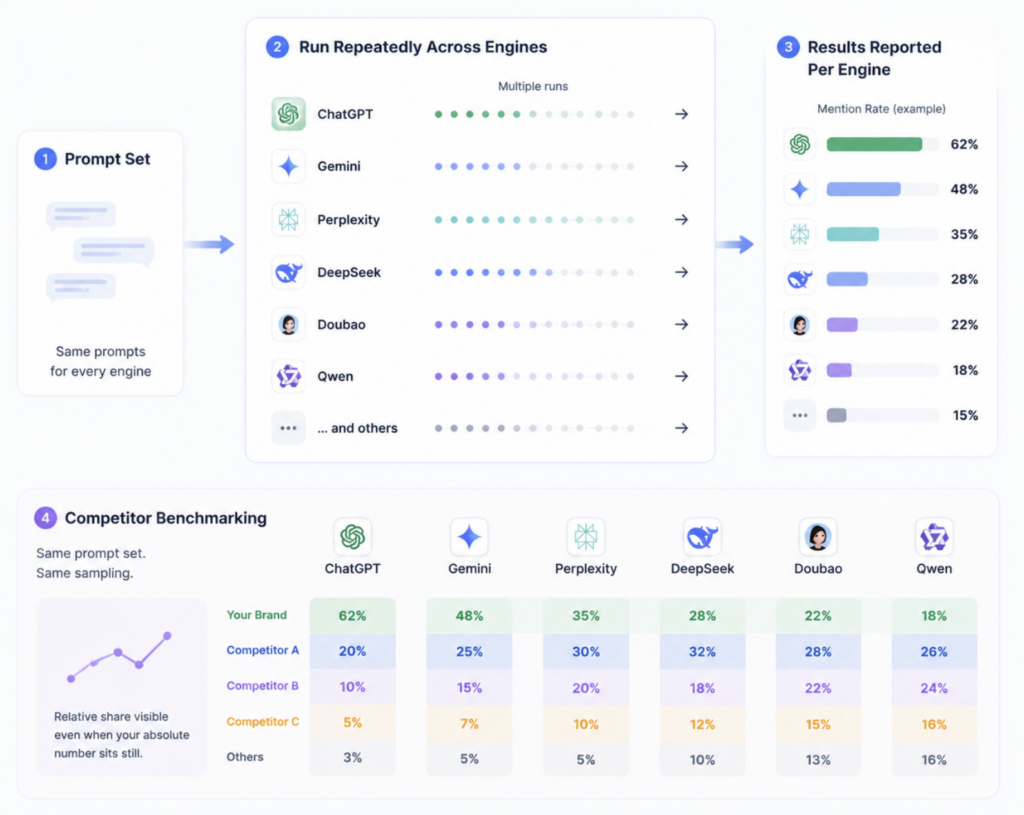
    Each prompt runs repeatedly across ChatGPT, Gemini, Perplexity, DeepSeek, Doubao, Qwen, and others, with results reported per engine instead of averaged into a single figure. Competitor benchmarking runs on the same prompt set and the same sampling, so relative share is visible even when your absolute number sits still.

    The citation reverse-engineering layer closes the loop. Seeing which exact domains and URLs each engine pulls from tells you where the retrieval gap lives, which is the actionable half of a falling mention rate. Our earlier breakdown of how a GEO rank tracker measures AI search position covers the metric definitions in more depth.

    Plans start at $99/month with 100 tracked prompts and 9,000 AI answer analyses, which is roughly the sampling volume this kind of question requires. You can get started with Topify on a 30-day trial.

    How to Read Your Own Rank Data Without Fooling Yourself

    Four habits separate teams who act on AI search data from teams who argue about it.

    Track prompt sets, not keywords. Buyers ask several related questions on the way to a decision, and winning one of them isn’t the same as owning the topic. Visibility that looks strong on a single prompt often thins out across the cluster.

    Read trend bands, not points. A 5-point week-over-week move on a sampled rate is usually noise. A 5-point move sustained across four weeks is a trend. Set that threshold before you look at the data, not after.

    Plot competitors on the same axis. Absolute visibility without relative share tells you almost nothing about whether you’re winning.

    Separate “absent” from “present but ranked low.” They look identical on a summary dashboard and they need completely different responses.

    Sample enough. Split the metrics. Check every engine.

    Conclusion

    Rank didn’t disappear when search became generative. It changed units. It stopped being a position you hold and became a probability you occupy, which means the number is only meaningful attached to a sample size.

    The three checks you ran in ChatGPT last week weren’t wrong. They were just three draws from a distribution you hadn’t measured yet. A GEO rank tracker built on repeated sampling, separated metrics, and per-engine reporting turns those draws into something you can put in a report and defend.

    Start by defining the ten prompts your buyers actually ask. Everything else follows from having a stable set to sample against.

    FAQ

    Q: How many times does a prompt need to run before the result is trustworthy? 

    A: Dozens, not a handful. The practical floor is enough runs that a single outlier can’t move the rate by more than a point or two. Most sampling-based platforms run each prompt many times per cycle for exactly this reason, and any tool reporting a rank off one query is reporting an anecdote.

    Q: Which matters more, mention rate or position? 

    A: Mention rate, in most cases. A brand that never appears can’t benefit from good placement. Once you’re appearing consistently, position becomes the lever that affects which option the buyer actually picks.

    Q: Can I just track ChatGPT and assume the rest follow? 

    A: No. Cross-engine agreement on brand recommendations runs around 21%, and domain-level citation overlap between major engines sits near 11%. Single-engine tracking produces a biased read in an unpredictable direction.

    Q: How often do AI rankings actually change? 

    A: Faster than SEO rankings. With a large share of citations rotating monthly, weekly tracking is the minimum viable cadence, and competitive categories often warrant daily sampling.

    Read More

  • Prompt Search for E-Commerce: How Shoppers Use AI to Find Products

    Prompt Search for E-Commerce: How Shoppers Use AI to Find Products

    Your product page ranks third for its main category term. The feed is clean, reviews are strong, and paid shopping sends steady traffic every week. Then someone opens ChatGPT and types “durable carry-on under $200 that actually fits budget airline sizers,” and gets five specific recommendations. Yours isn’t one of them.

    Nothing broke. The shopper just asked a question your keyword strategy was never built to answer. That’s prompt search, and in a growing number of categories it’s where product discovery now starts.

    Prompt Search Isn’t Keyword Search With More Words

    Keyword search asks the shopper to translate a need into terms a machine already indexes. “Running shoes men.” “Carry-on luggage.” The engine returns a list, and the shopper does the filtering.

    Prompt search flips who does the work. The shopper states a goal with constraints attached, and the system does the sorting before anything reaches the screen.

    Google’s own framing is that people now interact using conversational language, not keywords, and expect the system to read intent rather than match strings. Google’s search leadership has described seeing two, three, or four-sentence querieswhere people explain a problem instead of naming a product.

    The gap this creates is measurable. Semrush found that 65% to 85% of ChatGPT prompts have no matching keyword in its keyword database at all.

    That’s not a long-tail problem. It’s a coverage problem, and most keyword tools can’t see it.

    DimensionKeyword searchPrompt search
    Input2 to 4 termsGoal plus constraints, often a full sentence
    Who filtersThe shopperThe model
    Output10 links plus ads3 to 8 products, one synthesized recommendation
    What winsRanking positionBeing selected as evidence
    Measurable byRank trackersPrompt-level monitoring

    Shoppers Bring Constraints and Feelings, Not Keywords

    Here’s the thing about how people actually write shopping prompts: they’re shorter than most marketers assume, and more personal.

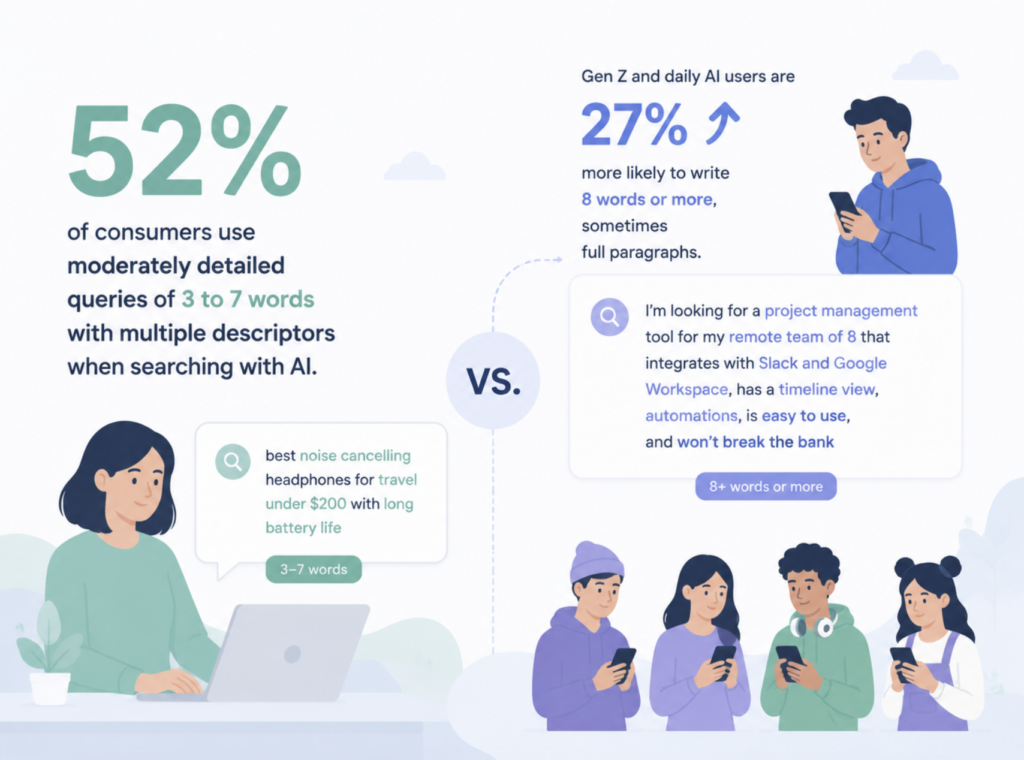
    Klaviyo’s consumer research found that 52% of consumers use moderately detailed queries of 3 to 7 words with multiple descriptors when searching with AI. Gen Z and daily AI users are 27% more likely to write 8 words or more, sometimes full paragraphs.

    The bigger shift is context. Klaviyo found 78% of people include emotional or personal context at least some of the time, asking for “something to cheer me up” or “a gift that feels thoughtful” rather than naming a product category.

    That’s goal-based shopping. The shopper describes the outcome and lets the model reverse-engineer the product.

    There’s a counterintuitive wrinkle worth knowing. A 2026 study covered by Search Engine Journal found that concise, keyword-style prompts produced more brand mentions than persona-heavy conversational ones, and that adding budget or feature constraints reduced the number of brands shown in ChatGPT and Perplexity while increasing it in Gemini and AI Overviews. Filler words changed nothing.

    So the constraint is the moment of truth. “Under $200” and “fits budget airline sizers” are exactly where products get screened out, and they’re the attributes most product pages state vaguely or not at all.

    One Prompt, a Dozen Hidden Searches

    A shopping prompt rarely triggers one retrieval. It triggers query fan-out: the model decomposes the request into sub-queries, retrieves separately for each, then synthesizes.

    The carry-on prompt above probably becomes something like: budget airline sizer dimensions by carrier, best carry-on under $200, spinner wheel durability complaints, warranty comparison across luggage brands, plus a few review-aggregation queries.

    Your brand isn’t competing for the prompt. It’s competing for the sub-queries.

    This is why single-page thinking fails in AI product discovery. Most ecommerce teams have one PDP built to win the parent phrase, and nothing that answers the definitional sub-query or the objection sub-query. The model needed four answers and found yours useful for zero of them.

    Fan-out also explains why results feel unstable. Run the same prompt twice and citations shift, because retrieval is sampled rather than fixed. Checking your brand in ChatGPT once and feeling relieved is an anecdote, not a measurement.

    AI Sends Less Traffic. It Sends Much Better Traffic.

    The volume argument against prompt search is getting weaker every quarter.

    Adobe Analytics, working from more than a trillion visits to U.S. retail sites, found AI-referred traffic to retail grew 138% year over year in May 2026 and 1,324% since October 2024, when it started tracking the category. Retail led every vertical in AI visit share growth in Q1 2026.

    The quality signal is stronger than the volume signal. Adobe reported shoppers arriving from AI referrals spend 53% more time on site and browse 23% more pages per visit. By March 2026, AI traffic converted 42% better than non-AI traffic, with revenue per visit running 37% above other sources. A year earlier, that comparison ran the other way.

    Scale is already there on the query side. Roughly 2% of ChatGPT queries involve shopping, which works out to about 50 million shopping queries per day against a base of 900 million weekly users. A Semrush survey found half of U.S. shoppers have bought something after researching it with AI.

    Bottom line: prompt search is a small channel producing pre-qualified buyers, which is the profile every acquisition team says it wants.

    Why AI Picks Three Products Out of Three Hundred

    Where a Google results page gives ten links and a wall of shopping ads, an AI assistant returns three to eight products. Selection is the whole game.

    Products surface based on structured merchant feeds, crawled web content, and third-party trust signals rather than paid placement. OpenAI’s shopping research model was trained to read trusted sites and cite reliable sources, synthesizing across many of them and refining as the shopper adds constraints.

    The industry settled into a clear division of labor in 2026. OpenAI stepped back from running checkout and refocused on product discovery, with merchants keeping their own checkout under the Agentic Commerce Protocol. Google moved the same direction, letting shoppers refine a query through conversation in AI Mode with agentic checkout handled on the merchant side.

    Discovery is the layer that got automated. That’s the layer to optimize.

    Three things tend to decide selection. First, machine readability: Adobe’s content visibility scoring flags pages where a large share of the content simply can’t be parsed by a model, and a page scoring 50% has half its content invisible. Second, attribute coverage, meaning the specific constraints shoppers name are stated explicitly in your product data rather than implied by a photo. Third, corroboration, since models weight independent reviews, editorial roundups, and community discussion more heavily than your own copy.

    Turning Prompt Search Into a Channel You Can Measure

    Most ecommerce teams find out they’re invisible in AI answers by accident, usually when a founder types the category into ChatGPT and sees three competitors. The problem with that discovery method is obvious: it’s one prompt, one run, one platform, no baseline.

    Measuring prompt search properly means treating prompts the way you once treated keywords. You need a defined set, repeated sampling over time, competitor comparison in the same runs, and visibility into which sources fed the answer.

    Topify is built around that workflow. Its High-Value Prompt Discovery surfaces the prompts that actually carry volume in your category and keeps surfacing new ones as recommendations shift, which matters more in retail than in most verticals because seasonality rewrites the prompt set every quarter. Comprehensive GEO Analytics then tracks seven metrics across ChatGPT, Gemini, Perplexity, and other major engines: visibility, sentiment, position, volume, mentions, intent, and CVR.

    The citation layer is where merchandising decisions come from. Topify reverse-engineers the exact domains and URLs AI platforms cite for your tracked prompts, so when a competitor takes over a “best under $200” prompt, you can see whether it won on its own PDP, a retailer listing, or a review site you’ve never pitched.

    Dynamic Competitor Benchmarking runs alongside it, flagging emerging rivals in real time rather than at quarter end.

    Pricing starts at $99 per month on the Basic plan with 100 tracked prompts, which is roughly the size of a serious starting prompt set for a single-category store. You can get started without rebuilding anything on your side.

    Where to Start If You Sell Products Online

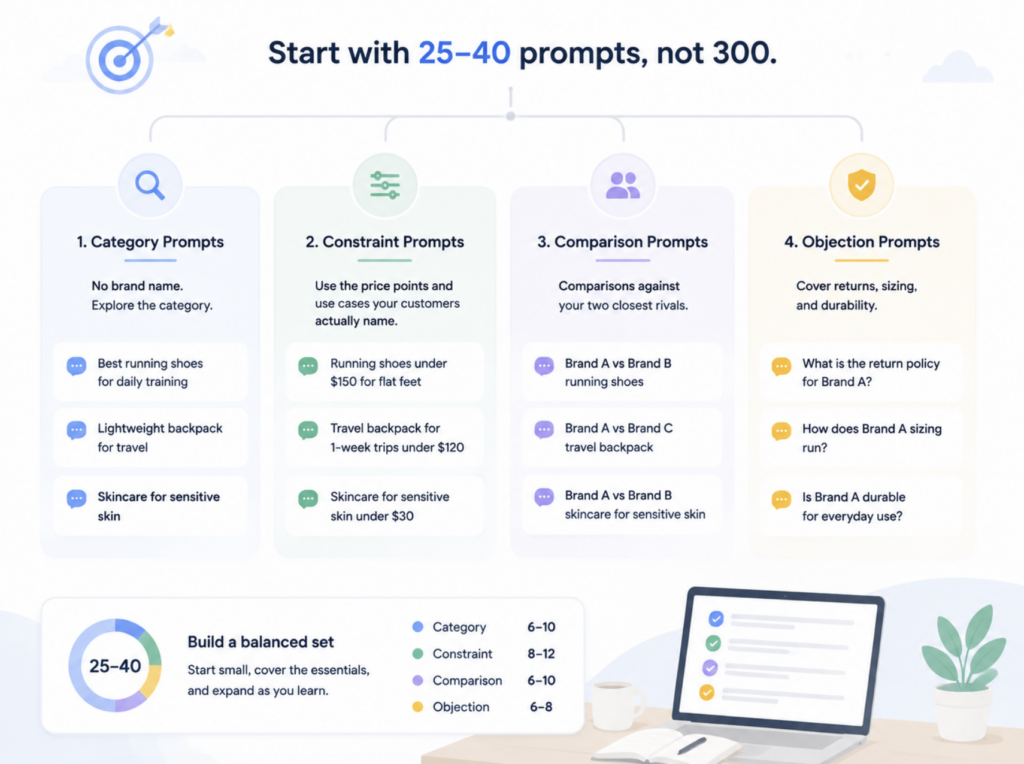
    Start with 25 to 40 prompts, not 300. Split them into category prompts with no brand name, constraint prompts using the price points and use cases your customers actually name, comparison prompts against your two closest rivals, and objection prompts covering returns, sizing, and durability.

    Run them weekly and record which brands appear, in what order, and which sources get cited.

    Then fix the readability gaps the citation data exposes. Put constraint answers in text on the page, not in images. Make sure your feed carries the attributes that show up in prompts. Get corroboration where the model already looks.

    Only 16% of brands currently track their AI search performance in any systematic way, which means the competitive bar in most categories is still low. That won’t hold for long.

    Conclusion

    The shopper who couldn’t find your carry-on didn’t reject your product. Your product never entered the consideration set, because the constraints in the prompt never matched anything readable in your data.

    Prompt search rewards a different kind of work than keyword search did. Less about ranking for terms, more about being the clearest, best-corroborated answer to a specific goal with specific limits attached. The channel is still small enough that a focused prompt set and a few weeks of citation data can move you from invisible to recommended.

    Pick 25 prompts your customers would actually type. Run them. See who’s there instead of you.

    FAQ

    Q: What is prompt search? 

    A: Prompt search is product discovery through conversational prompts in AI assistants like ChatGPT, Gemini, and Perplexity, where a shopper describes a goal with constraints and the system returns a short recommendation set instead of a page of links.

    Q: How is prompt search different from keyword search for e-commerce? 

    A: Keyword search matches terms and leaves filtering to the shopper. Prompt search interprets intent, expands the request into sub-queries through query fan-out, and returns three to eight products. Visibility depends on selection, not ranking position.

    Q: Which prompts should an ecommerce brand track? 

    A: Track four types: unbranded category prompts, constraint prompts built around real price points and use cases, comparison prompts naming your closest competitors, and objection prompts about returns, sizing, or durability. Keep branded prompts in a separate group so they don’t inflate your overall visibility numbers.

    Q: Does AI search traffic actually convert for retail? 

    A: Adobe’s 2026 data shows AI-referred retail traffic converting 42% better than non-AI traffic, with 37% higher revenue per visit and 53% more time on site. Volume stays modest relative to paid search and email, but intent runs higher.

    Read More

  • Why Prompt Search Volume Is the Metric Marketers Are Missing

    Why Prompt Search Volume Is the Metric Marketers Are Missing

    Your keyword report says the category term you own gets 8,000 searches a month, and you’re sitting at position three. Then a buyer opens ChatGPT and types twenty-three words about their team size, their budget, and the tool they already run. Not one of those words appears in your keyword tool. The answer names three vendors. Yours isn’t among them.

    Nothing in your reporting stack explains what happened, because that stack counts strings typed into a search box, not questions asked of a model. Prompt search volume is the number built to close that gap, and most dashboards still don’t have a row for it.

    Keyword Volume Stops Working When Nobody Types Keywords

    The shape of demand changed before the measurement did.

    Google’s average US query has held steady at 3.33 to 3.36 words for most of a year, then climbed past 3.51 words by May 2026 after AI Mode rolled out. That’s a modest move. Inside AI assistants, the move isn’t modest at all: SOCi’s 2026 Visibility Index found LLM queries average 23 words, roughly six times a traditional search query.

    Semrush’s database of over 239 million prompts shows the same pattern at scale. Prompts routinely run fifteen to twenty-five words and carry context, constraints, and qualifications that never survive the trip into a keyword field.

    Volume didn’t disappear. It changed shape.

    And the scale is no longer a rounding error. ChatGPT alone handles more than 2.5 billion prompts per day across roughly 900 million weekly active users. Every one of those prompts is demand your keyword tool has no way to see.

    What Prompt Search Volume Actually Measures

    Prompt search volume is the estimated number of times a given prompt, or a cluster of similar prompts, gets submitted to AI platforms in a month. Think of it as the AI-era counterpart to keyword search volume, with one difference that matters: no AI platform publishes this data.

    That means every number you see is modeled. Vendors build estimates from panel data, systematic prompt sampling, extrapolation from related keyword demand, and observed answer behavior. Methodologies differ, so two tools can disagree on the same topic.

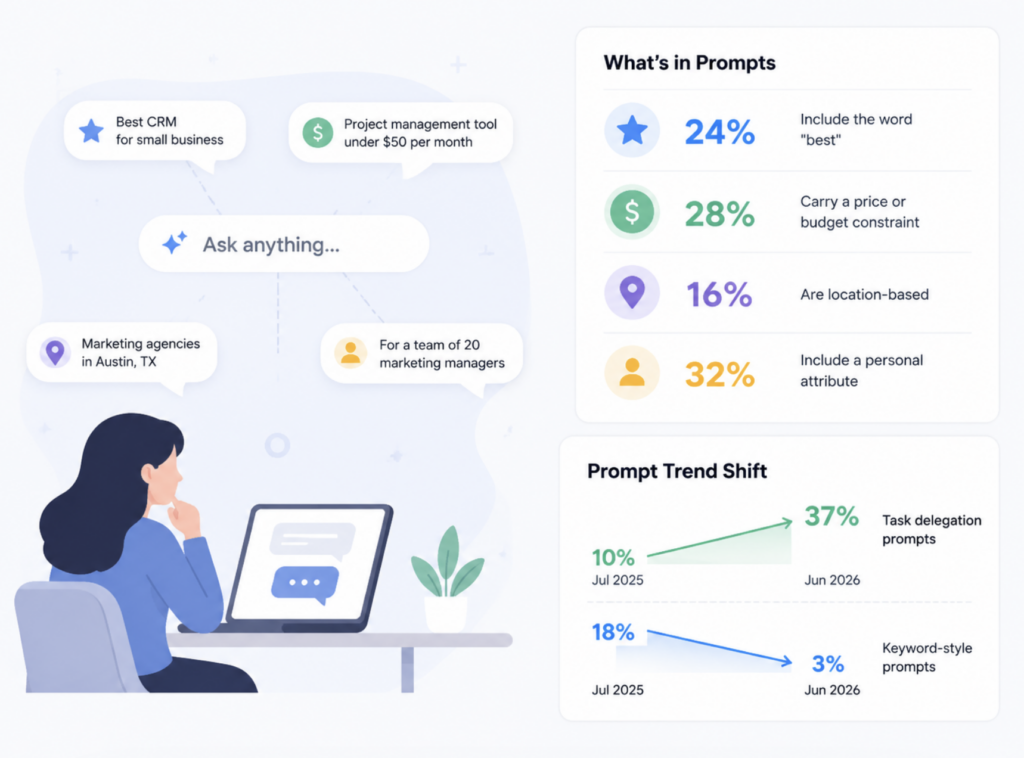
    What the data does reveal is composition, and composition is where the strategy lives. A Search Engine Land survey of how people actually prompt found that 24.5% of prompts include the word “best”, 28% mention price or budget, 16% are explicitly location-based, and 32% include personal attributes such as profession, life stage, or health condition.

    Those aren’t keywords. They’re qualifying conditions, and they decide which brands make the shortlist.

    The Long Tail Didn’t Get Longer. It Got Personal.

    Here’s the shift that breaks the old model. In an August 2025 survey, roughly half of free-text prompts were still SEO-keyword-shaped: short, ambiguous, brand-and-attribute driven. By January 2026, that share had fallen to about 30%.

    The other 70% grew longer and more contextualized.

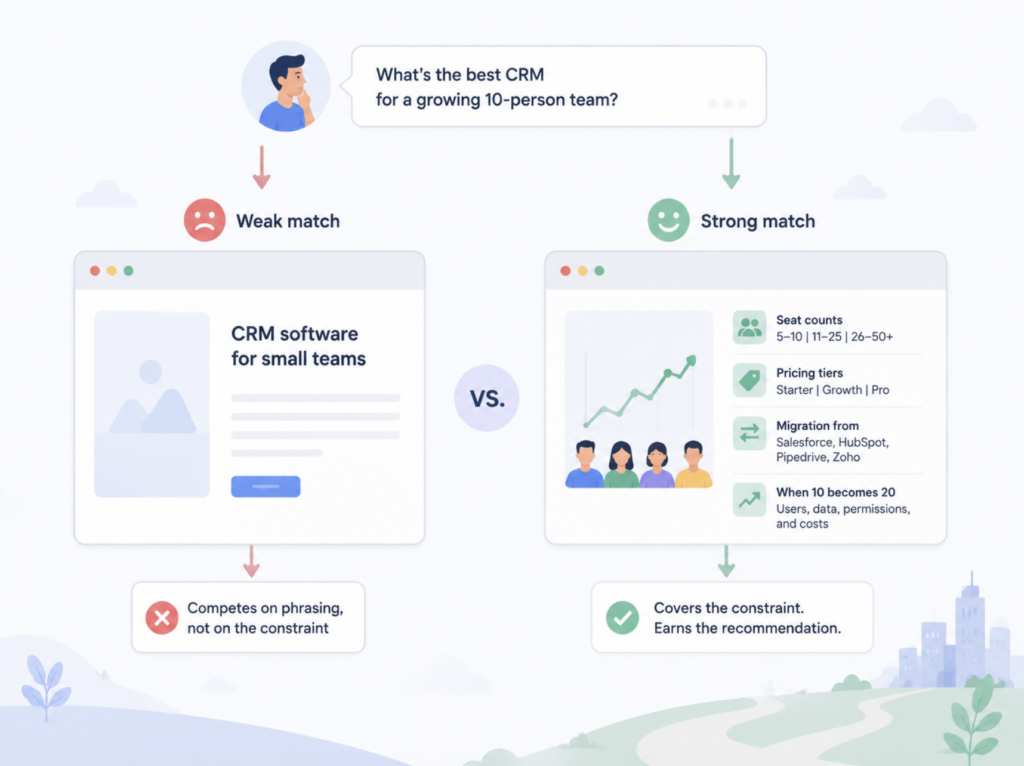
    You can’t win those prompts by matching phrasing, because the phrasing is close to one-of-a-kind. You win them by covering the constraint. A page that says “CRM software for small teams” competes weakly against a page that specifies seat counts, pricing tiers, migration paths from named incumbents, and what happens when a ten-person team doubles.

    That’s the practical difference between a keyword strategy and a prompt search strategy. One targets a phrase. The other targets a decision.

    Prompt Search Volume Tells You Where Demand Is Moving

    Keyword volume describes a channel that’s mature and measurable. Prompt search volume describes one that’s growing and partially blind. Running only the first is comfortable. Running only the second is reckless.

    DimensionKeyword search volumePrompt search volume
    Data sourceEngine-reported query and click logsModeled from panels, sampling, extrapolation
    Typical query shape3 to 4 words15 to 25 words with context
    RepeatabilityStable month over monthHigh share of one-off phrasings, clustered by topic
    What it predictsRanking opportunity on a results pageWhether your brand enters the answer at all
    How to read itAbsolute numbers are usableTrends beat absolute numbers

    The useful move is watching the ratio per topic. When a topic’s AI demand starts outrunning its Google demand, answer-first content moves up the queue for that topic and only that topic.

    Two more numbers make the case for paying attention. ChatGPT performs a live web search on roughly 31% of prompts, with the model’s own behind-the-scenes queries averaging 5.48 words. And according to Ahrefs data cited by Search Engine Land, AI search visitors convert at 23 times the rate of traditional organic visitors, even though the raw session count is far smaller.

    Fewer sessions, much higher intent. That’s a channel worth measuring properly.

    Where Prompt Search Data Gets Oversold

    Now the honest part, because vendors tend to skip it.

    Prompt volume estimates are directional. Treat a specific number the way you’d treat an analyst forecast: useful for ranking priorities, unreliable as a headline figure in a board deck.

    The bigger issue is answer variance. Growth Memo’s analysis of prompt tracking methodology found that only 2.3% of citations survive three runs of the same prompt. Run a prompt once and you’ve flipped a coin with the result hidden from you.

    So single-prompt testing tells you almost nothing. Repeated runs across a stable prompt set, tracked over weeks, tell you a lot.

    Three practical guardrails. Track trends inside one tool rather than comparing absolute numbers across vendors. Run each prompt multiple times before you record a result. Refresh monthly for stable categories and weekly for fast-moving ones like AI tooling, finance, and tech.

    How to Put Prompt Search Volume to Work in 30 Days

    Start by building a controlled prompt set instead of chasing a leaderboard. Pick five to ten topics you want AI systems to associate with your brand, then write prompts across the funnel for each: category discovery, comparison, objection, and purchase.

    Layer in the constraint patterns the data already surfaced. Budget, team size, location, and personal context show up in a large share of real prompts, so your set should reflect that instead of testing clean category terms nobody actually types.

    Then run the set consistently and record four things: whether you appear, which competitors appear, which sources get cited, and how your brand gets described.

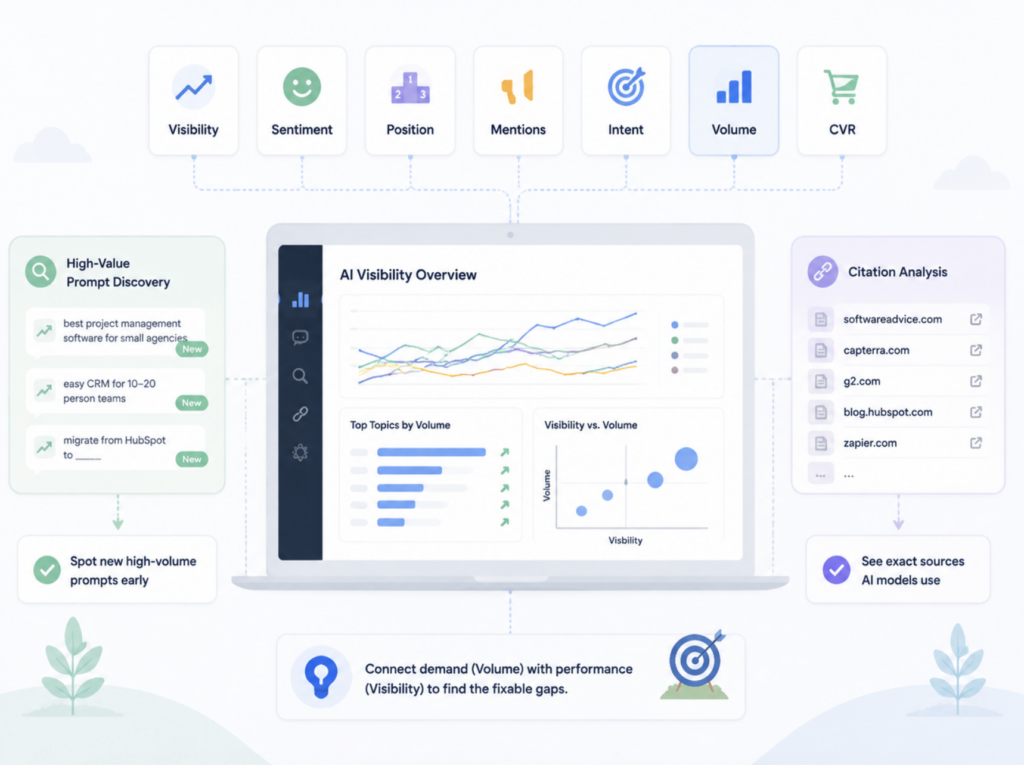
    This is where tooling stops being optional, because doing it by hand across four platforms and fifty prompts is a full-time job. Topify tracks volume as one of seven metrics alongside visibility, sentiment, position, mentions, intent, and CVR, so a spike in prompt demand for a topic sits next to whether you’re actually showing up for it. Its High-Value Prompt Discovery surfaces new high-volume prompts as AI recommendation patterns shift, and its citation analysis maps the exact domains and URLs the models pull from, which is usually where the fixable gap turns out to be.

    Coverage matters here too. Prompt demand splits across ChatGPT, Gemini, Perplexity, and regional engines including DeepSeek, Doubao, and Qwen, and a tool that only reads one platform will miss most of the picture. Plans start at $99 a month for 100 tracked prompts, and you can get started with a trial before committing budget.

    Bottom line on sequencing: map intent, cluster into topics, prioritize by prompt search volume, validate with repeated manual testing, then track visibility over time. Prompt volume is the prioritization input, not the whole program.

    Conclusion

    The buyer who skipped your brand in that ChatGPT answer didn’t type a keyword. They described a situation, and the model matched that situation to whichever sources covered it best. Prompt search volume is the first metric that puts a number on how often those situations come up in your category.

    It’s modeled data, it varies between vendors, and it deserves skepticism on any single figure. It’s also the only demand signal that maps to how a growing share of your market now asks questions. Run it alongside keyword volume, watch the ratio per topic, and move answer-first content to the front of the queue when AI demand starts winning.

    The teams that build this measurement habit now will be reading trend lines while everyone else is still guessing.

    FAQ

    Q: What is prompt search volume?
    A: It’s the estimated number of times a specific prompt, or a cluster of closely related prompts, is submitted to AI platforms like ChatGPT, Gemini, Perplexity, and Google AI Mode in a given month. It plays the same prioritization role that keyword search volume plays in traditional SEO.

    Q: Is prompt search volume data accurate?
    A: It’s directional rather than exact. AI platforms don’t publish prompt-level data, so every estimate is modeled from panels, sampling, and extrapolation. Use it to rank priorities and read trends over time, not to report precise monthly figures.

    Q: Does prompt search volume replace keyword research?
    A: Not yet, and probably not entirely. Google still handles the majority of global queries, and many AI prompts mirror underlying keyword demand. The workable approach in 2026 is running both side by side: keyword volume for SEO, prompt search volume for GEO and AEO.

    Q: How often should you track prompt search volume?
    A: Monthly works for most categories. Fast-moving verticals such as AI tools, finance, and tech benefit from weekly checks, while stable categories can be reviewed quarterly. Consistency inside one tool matters more than frequency.

    Read More

  • Prompt Search and Query Fan-Out: One Question, Many AI Lookups

    Prompt Search and Query Fan-Out: One Question, Many AI Lookups

    Your keyword list has 300 terms in it. Every one earned its place because a tool showed it had volume. Then an AI engine cites one of your pages, and you go looking for which term did it. Nothing matches. The query that surfaced your page was something like “NCLEX pass rates by nursing school,” a phrase no user typed and no keyword tool tracks. In one analysis of AI citations, 95% of the sub-queries that produced a citation had zero traditional search volume. The queries doing the work are the ones nobody targeted.

    What Prompt Search Actually Means Inside an AI Engine

    Prompt search is what happens when a person hands an AI system a full request instead of a search phrase. The difference isn’t length. It’s who does the decomposition.

    In keyword search, the user breaks a messy need into a short query, scans ten links, and reassembles the answer. In prompt search, the user states the whole need at once and the engine does the breaking apart, the retrieval, and the reassembly. That shift moves the work from the person to the model, and it moves the query from your keyword tool into a black box.

    The numbers make the gap concrete. ChatGPT’s internal searches average about 5.5 words, roughly 60% longer than a typical Google query, and they lean commercial rather than navigational.

    DimensionKeyword searchPrompt search
    Input2 to 4 word phraseFull sentence with constraints
    Who decomposes intentThe userThe model
    Queries issued per requestOneTwo to eleven, sometimes hundreds
    OutputTen ranked linksOne synthesized answer with citations
    Visible to your toolsYesAlmost never

    Query Fan-Out: How One Prompt Turns Into Nine Searches

    Google gave the mechanism its name at I/O 2025, describing how AI Mode breaks a question into subtopics and issues a set of queries simultaneously on the user’s behalf. Perplexity, ChatGPT, and Gemini all run some version of the same loop.

    The sequence has four stages. The model parses the prompt for intent and complexity. It generates sub-queries covering different facets. It dispatches them in parallel across web results, knowledge graphs, and specialized indexes like Google’s Shopping Graph. Then it merges the returns into one answer.

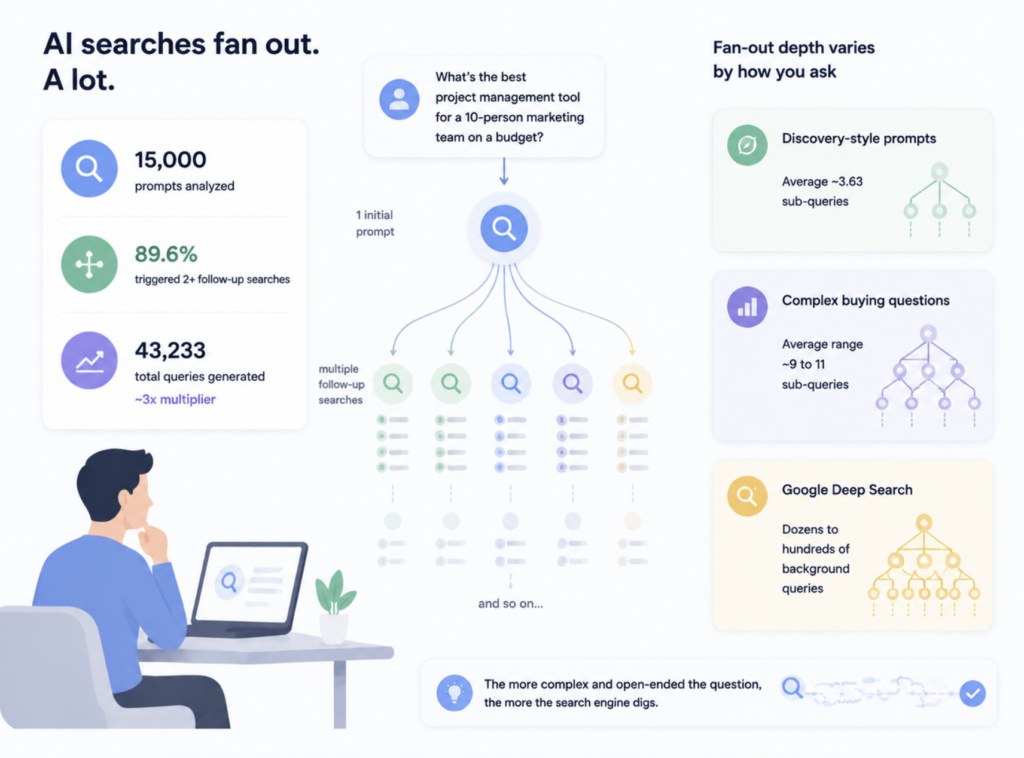
    Fan-out depth varies a lot by how the question is framed. Across a dataset of 15,000 prompts, 89.6% triggered two or more follow-up searches, and the total query set expanded to 43,233, close to a threefold multiplier. Discovery-style prompts average around 3.63 sub-queries, while some published studies put the range closer to nine or eleven for complex buying questions. Google’s Deep Search sits at the far end, capable of issuing dozens or even hundreds of background queries before it responds.

    Simple factual prompts skip the process entirely. “Capital of Spain” gets one lookup. “What’s the best project management tool for a 12-person creative agency” gets a swarm.

    The Fan-Out Queries You Won’t Find in Any Keyword Tool

    Here’s the part that breaks conventional keyword strategy. In the same 15,000-prompt dataset, 32.9% of all cited pages appeared in fan-out results only. They were never discovered through the original prompt.

    Pair that with the 95% zero-volume finding and the picture gets uncomfortable. Roughly a third of citation opportunities live in queries that a keyword tool will never show you, because they aren’t demand. They’re the model’s internal questions: “NCLEX pass rates by nursing school,” “project management tools for creative teams comparison,” “vegan breakfast Paris hotel.”

    Your keyword list isn’t just incomplete. It’s a sampling frame that structurally excludes the queries responsible for a third of your AI citations.

    That’s the gap most reporting still can’t see.

    Not Every Prompt Triggers a Search

    Fan-out only matters when the model decides to retrieve at all, and a lot of the time it doesn’t. The Nectiv study found 31% of prompts triggered at least one search. Clickstream analysis puts the figure at 34.5% as of February 2026, down from around 46% in late 2024.

    The rest comes from what the model already knows. One replication study attributes roughly 68% of ChatGPT citations to training data rather than live retrieval, with about 27% traceable to Bing’s index.

    Intent predicts the split fairly reliably. In a capture of 48 SaaS buying prompts, every “best X for Y” and “alternatives” question triggered a search, while definitional questions and most two-way comparisons were answered from memory. Gemini leaned hardest on memory. Perplexity searched every time.

    So there are two surfaces to optimize, not one. Retrieval-layer visibility responds to content you publish this quarter. Training-layer visibility responds to how widely and consistently your brand was described across the web months or years ago. Different levers, different timelines.

    Why Keyword Rankings Can’t Measure Prompt Search Performance

    Three measurement gaps show up as soon as a team tries to report on prompt search using existing tooling.

    The queries aren’t enumerable. Two users asking for the same thing will phrase it differently, and each phrasing spawns a different fan-out set. There’s no finite list to rank against.

    There’s often no click. A prompt returns one answer. Being the cited source matters more than being the tenth blue link, and your analytics won’t record the difference.

    Prompt volume estimates carry wide error bars. Most figures come from browser-extension panels, which skew toward desktop, Chrome, and tech-forward users, then get extrapolated. Industry practitioners have argued that prompt volume works as a directional signal, not a demand count, and analysts have raised similar concerns about panel representativeness. That’s a fair critique, and it’s worth holding onto.

    What replaces the ranking number isn’t a single metric. It’s a set: whether you’re mentioned, where you sit in the answer, how the model characterizes you, and which domains it cited to get there. That last one is the most actionable, because citation sources are observable in a way that fan-out queries usually aren’t.

    How to Make Content Survive Query Fan-Out

    Fan-out rewards breadth over single-keyword depth. Your page enters the candidate pool through whichever sub-query happens to match it, so covering one angle well gets you one entry ticket.

    In practice that means treating a topic as a set of facets rather than a keyword. Features, pricing, integrations, comparisons, use cases, alternatives, and limitations each pull a different sub-query. A product page that only sells is invisible to the sub-query asking about pricing tiers or migration paths.

    Self-contained passages help too. Models retrieve and quote at the passage level, so a paragraph that depends on three paragraphs of prior setup tends to lose to one that answers a question outright.

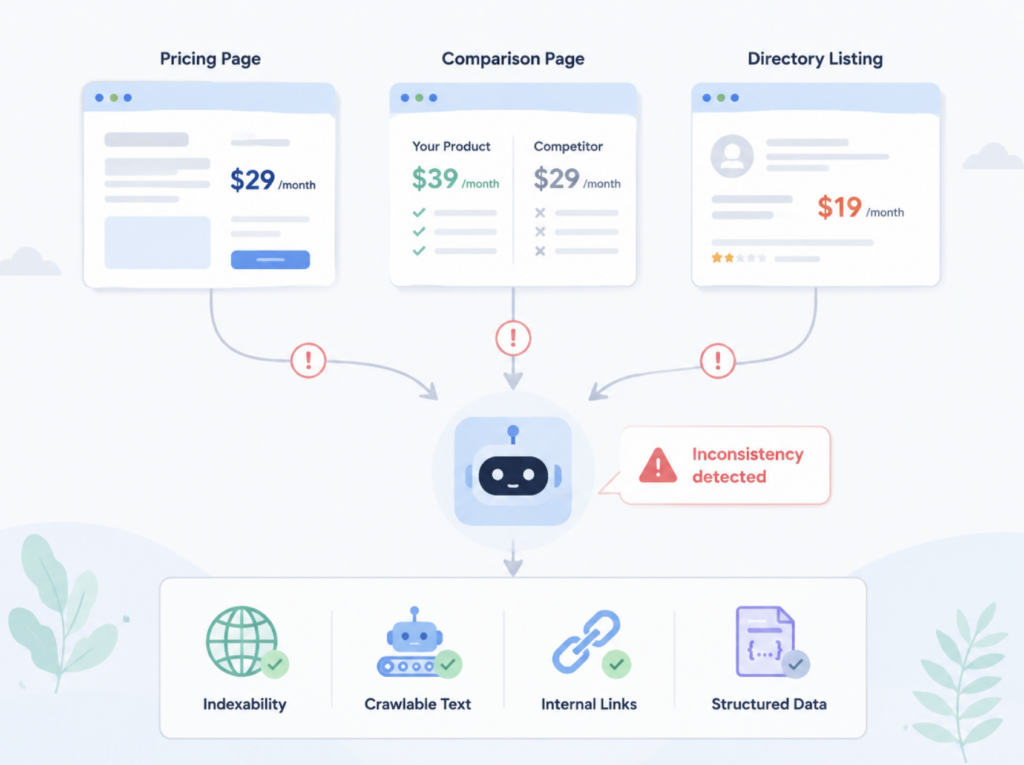
    Consistency across assets matters more than it used to. Fan-out gives an answer several independent ways to find a contradiction. If your pricing page says one thing, your comparison page says another, and a directory listing is two years stale, the model has three chances to notice and route around you. The same foundations Google documents for AI Modestill apply: indexability, crawlable text, internal links, and structured data that matches what’s visible on the page.

    And getting retrieved isn’t the finish line. In that 15,000-prompt dataset, ChatGPT cited only about 15% of the pages it pulled into the process. Discoverability and selectability are two separate problems, and most advice only addresses the first.

    Tracking Prompt Search at the Prompt Level

    If the unit of AI search is the prompt, the unit of measurement has to be the prompt as well. That means running the questions your buyers actually ask, across the engines they actually use, on a schedule, and recording what comes back.

    Topify is built around that unit. Its High-Value Prompt Discovery keeps surfacing new prompts as recommendation patterns shift, which addresses the enumeration problem directly: rather than guessing which fan-out queries exist, you widen the prompt set and watch which ones return your brand. Its citation analysis reverse-engineers the exact domains and URLs AI platforms reference, so when a competitor starts appearing in a category answer, you can trace which source moved and decide whether that’s a content gap, a review-site gap, or a Reddit gap. Seven metrics run underneath: visibility, sentiment, position, volume, mentions, intent, and conversion visibility rate, tracked across ChatGPT, Gemini, Perplexity, and other engines.

    Coverage is where prompt-level tracking earns its keep. Entry pricing starts at $99 per month for 100 tracked prompts across ChatGPT, Perplexity, and AI Overviews, which is enough to baseline a category and see whether the pattern holds before scaling the prompt set. Teams that want the mechanics behind the tracking can start with how AI search visibility is measured in ChatGPT, then get started with their own prompt list.

    Conclusion

    Prompt search doesn’t invalidate SEO. It changes the unit of analysis from a phrase you chose to a question the model asked itself. Query fan-out is why: one prompt becomes a handful of parallel lookups, most of them invisible to keyword tooling, and roughly a third of your citations come from queries you’d never have targeted.

    Three things worth doing this month. Write down the twenty questions your buyers actually ask, in their words, not in keyword form. Check which of those trigger retrieval versus memory, because the fix differs. Then audit whether your content covers the facets a fan-out would probe, pricing and comparisons and alternatives included, or only the one angle your keyword research pointed at.

    FAQ

    Q: What is query fan-out in simple terms? 

    A: It’s the technique AI search engines use to answer one question by silently running several related sub-queries in parallel, then merging the results into a single answer. Google introduced the term with AI Mode, but ChatGPT and Perplexity use comparable approaches.

    Q: How is prompt search different from keyword search? 

    A: Keyword search asks the user to compress a need into a short phrase and reassemble the answer from links. Prompt search takes the full request and lets the model decompose it, retrieve across sources, and return one synthesized answer. The decomposition work moves from the person to the engine.

    Q: Can I see the fan-out queries an AI engine ran on my prompt? 

    A: Partially. Perplexity and Google AI Mode surface some of the sub-queries in the interface, and reasoning traces occasionally expose them. Most remain hidden, which is why teams approximate them by tracking a wide prompt set and observing which brands and sources appear.

    Q: Should I build pages for fan-out queries that have zero search volume? 

    A: Not one page per query. Fan-out queries are facets of a topic, not standalone demand, so the better move is deepening existing pages to cover pricing, comparisons, use cases, and limitations. Breadth on one strong page usually beats thin pages chasing phantom volume.

    Read More

  • Prompt Search Intent Mapping: Understanding What Users Really Ask AI

    Prompt Search Intent Mapping: Understanding What Users Really Ask AI

    Your keyword file has thousands of terms in it. It took years to build, and it still predicts what people type into Google with decent accuracy. Then you pull a month of AI referral data and almost none of the phrasings match anything in that file. Depending on the dataset, somewhere between 65% and 85% of ChatGPT prompts have no matching keyword in standard keyword databases. That’s not a coverage gap you close by adding long-tail variants. Prompt search runs on a different unit of demand, and mapping it takes a different method.

    Prompt Search Isn’t Keyword Search With More Words

    Start with the size difference, because it sets up everything else. ChatGPT prompts average about 60 words against Google’s typical 3.4-word query. Even inside AI search specifically, prompts are getting longer: Semrush’s clickstream analysis found search-enabled prompt length nearly doubled from 4.7 to 8.7 words between early 2025 and early 2026.

    Google’s own data points the same direction. The average AI Mode query now runs triple the length of a traditional search query.

    Length is the symptom. Context is the actual change.

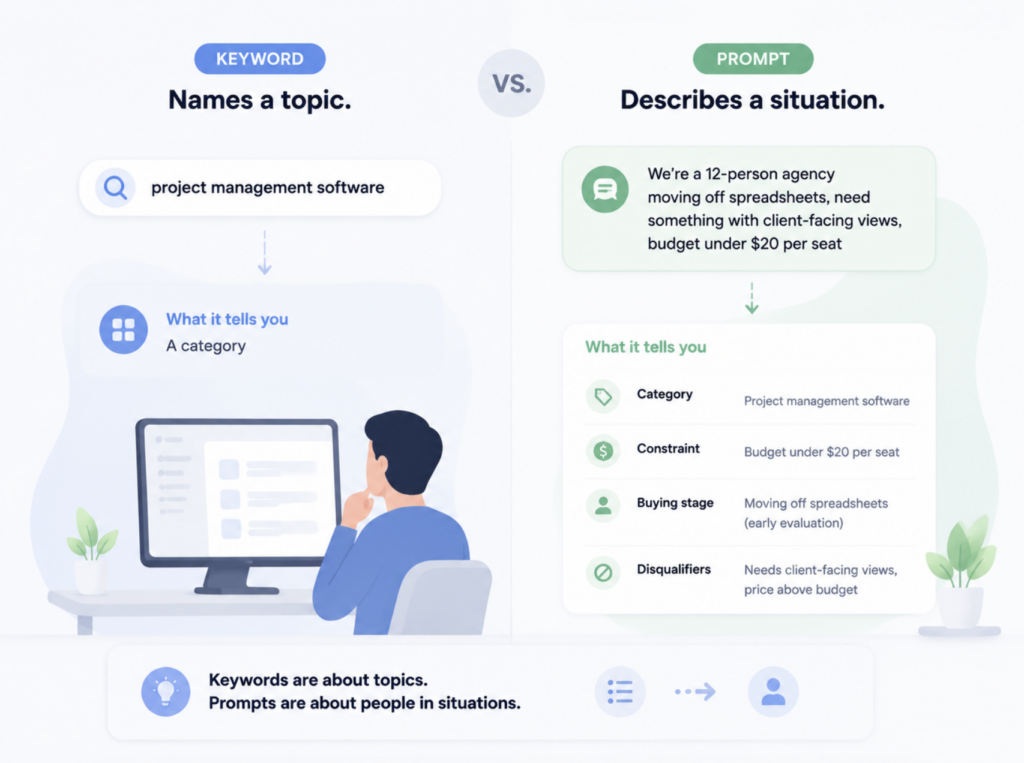
    A keyword names a topic. A prompt describes a situation. “project management software” tells you a category. “We’re a 12-person agency moving off spreadsheets, need something with client-facing views, budget under $20 per seat” tells you the category, the constraint, the buying stage, and the disqualifiers.

    That matters for mapping because intent stops being something you infer from a three-word string. In prompt search, the user hands it to you directly. The work shifts from guessing intent to organizing it.

    One Prompt Search, Many Hidden Queries: What Fan-Out Does to Intent

    Here’s the part most keyword-to-prompt migrations miss. AI systems rarely search the prompt you wrote. They decompose it. One query goes in, many related queries come out, and the results get synthesized into a single answer. Google runs this explicitly in AI Mode and AI Overviews, and most other engines use some version of it.

    Longer prompts feed that machinery better. NP Digital’s analysis of 10,000 AI-generated overviews found AI results appeared on 36.1% of queries that were 6 to 10 words long, against 12.4% for one and two-word queries. Separate data suggests queries of 8 words or more are 7 times more likely to generate an AI Overview.

    One estimate puts the multiplier at 10 to 16 times more retrieval events per AI query than its traditional search equivalent. The exact number depends on the model and the prompt, so treat it as a range rather than a constant. The direction is what counts.

    You’re not competing for a prompt. You’re competing for its fragments.

    This is the single biggest reason a prompt list copied from a keyword list underperforms. The keyword file assumes one query maps to one results page. Prompt search assumes one prompt maps to a cluster of sub-questions, each pulling from different source types. A definition sub-query wants a clean explanation. A comparison sub-query wants a table. Your content either matches one of those shapes or it doesn’t get pulled.

    The Three Intent Layers Inside Every Prompt

    The most useful classification of prompt intent doesn’t come from the SEO world. It comes from OpenAI’s study with NBER covering more than a million messages, which sorted usage into three buckets: 49% Asking, 40% Doing, and 11% Expressing. Among work-related messages, the balance flips, with about 56% classified as Doing.

    That split has direct commercial consequences, and most prompt maps ignore two of the three layers entirely.

    Intent layerWhat the user wantsWhat it means for your brand
    AskingInformation, judgment, a recommendationThe layer where brands get named and cited. Highest visibility value per prompt.
    DoingAn output produced: a draft, a plan, a comparison tableYour product may get used as raw material without ever being named. Watch for silent usage.
    ExpressingReflection, opinion, ventingRarely worth tracking, but useful sentiment signal in category conversations.

    Asking is where prompt search visibility lives. When someone asks which tool fits their situation, the model produces a shortlist, and that shortlist is the whole game.

    Doing is the layer teams overlook. When a user says “build me a vendor comparison table for warehouse automation,” the model still retrieves and synthesizes. Your brand either lands in that table or it doesn’t. Same visibility mechanics, different prompt phrasing, and most tracking lists contain zero prompts written this way.

    How to Build a Prompt Search Intent Map in Five Steps

    Step 1: Pull seeds from places keyword tools can’t see

    Keyword databases won’t have these phrasings. Your own systems will. Internal site search logs, sales call transcripts, support tickets, and Search Console queries filtered for who, how, which, and why all contain the natural language your buyers already use. Objection language from sales calls tends to produce the highest-intent prompts you’ll find anywhere.

    Step 2: Classify by intent, not by topic

    Topic clustering is a habit carried over from keyword research for GEO and AEO work, and it’s the wrong first cut here. Sort by what the user wants back: a recommendation, a process, a comparison, a verdict on a specific brand, or a finished output. Topic becomes your second-level tag.

    Step 3: Expand each prompt the way a model would

    Take each seed and write out the sub-questions a system would need to answer it. No tool reveals the actual synthetic queries, so approximation is the job. Read the follow-up suggestions in AI Mode, the sources cited under a Perplexity answer, and the People Also Ask boxes. Those are the shards already firing.

    Step 4: Tag branded against unbranded before you count anything

    A workable starting ratio is roughly 75% unbranded and 25% branded. You almost certainly show up when your own name is in the prompt, so branded results tell you about accuracy and positioning, not discoverability. Mixing them into one average inflates every number you report.

    Step 5: Score for influenceability, then cut hard

    A prompt earns a slot only if it’s competitively relevant, commercially meaningful, and something your content can plausibly move. A practical starting point is 20 to 40 prompts across 2 to 3 models, tracked for at least 30 days before you draw conclusions. Short and filtered beats long and unfocused.

    Phrasing Moves the Answer More Than Your Content Does

    This is the finding that breaks most intent maps built on keyword logic. An analysis of 37,804 AI responses across five engines found that how you phrase a prompt shifts brand density more than what you ask. Ranking and comparison formats surfaced roughly 20% more brand mentions than open-ended questions. Concise, keyword-style prompts pushed visibility up to 25% higher than persona-engineered ones, because heavy role framing widens the query into educational territory where fewer brands appear.

    Two consequences for your map.

    First, phrasing variants belong in separate rows. “Best CRM for small business” and “I run a 10-person business and need help picking a CRM, what should I consider” express the same intent and will produce different brand sets. Collapsing them into one entry hides the gap.

    Second, freeze your wording once measurement starts. Editing prompts mid-quarter resets your baseline, and you’ll misread the change as a visibility swing.

    Turning a Prompt Search Intent Map Into Something You Can Measure

    A static map decays fast. Prompts have no search volume, no rankings, and no stable position data, so the only signal available is repeated observation across engines over time. That’s a monitoring problem, not a spreadsheet problem.

    This is where a platform earns its place. Topify approaches prompt search from the discovery side first, continuously surfacing high-volume prompts relevant to your category rather than asking you to guess the full list upfront. In practice, that means the map keeps growing as AI recommendation patterns shift, instead of freezing on the day you built it.

    The measurement side runs on seven metrics across major AI platforms: visibility, sentiment, position, volume, mentions, intent, and CVR. The intent metric is what makes an intent map operational rather than descriptive, because you can see whether you’re winning Asking prompts and losing Doing prompts, or the reverse. CVR estimates how likely a given answer is to push a user toward interacting with your brand, which is the closest thing prompt search has to a conversion signal.

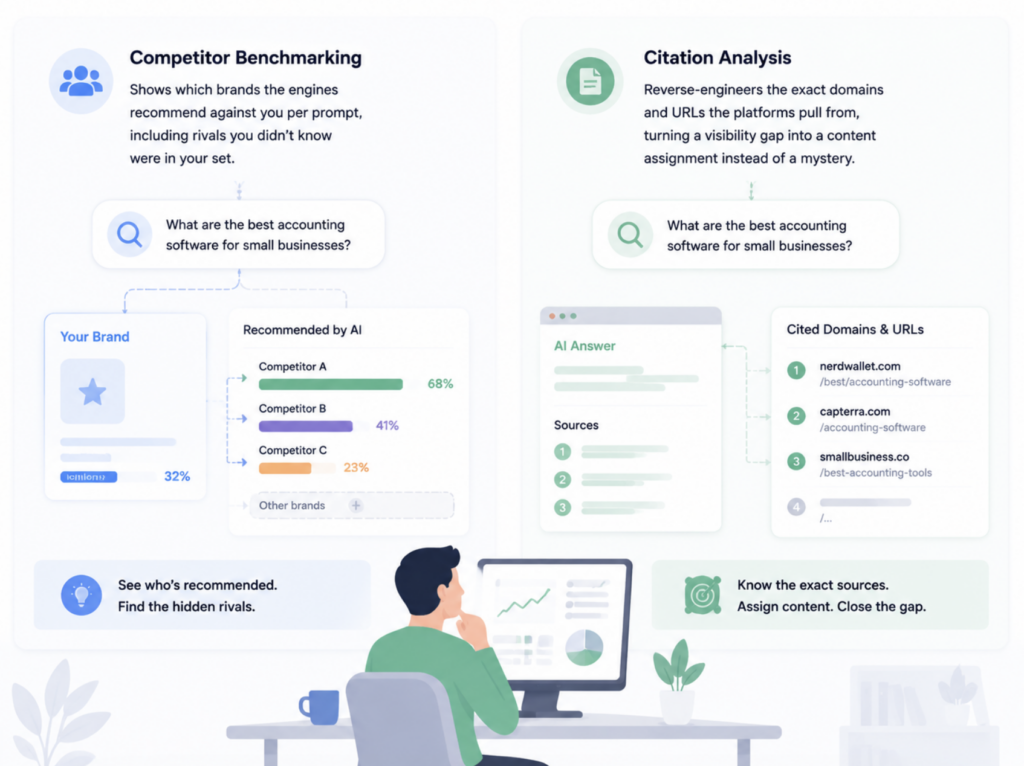
    Two more pieces matter for map maintenance. Competitor benchmarking shows which brands the engines recommend against you per prompt, including rivals you didn’t know were in your set. Citation analysis reverse-engineers the exact domains and URLs the platforms pull from, which turns a visibility gap into a content assignment instead of a mystery.

    Coverage spans ChatGPT, Gemini, Perplexity, DeepSeek, Doubao, Qwen, and others, which matters if your audience isn’t concentrated in one market. Plans start at $99 per month for 100 tracked prompts and $199 for 250, so a first map sized at 20 to 40 prompts fits comfortably inside an entry tier. You can get started with a baseline run before committing to a full taxonomy.

    Where Prompt Intent Maps Break Down

    Three failure patterns show up repeatedly.

    Branded inflation. Load the list with your own name and share of voice looks excellent while discoverability quietly erodes. This is the most common way a prompt program produces reassuring numbers and zero insight.

    Treating fan-out shards as keywords. Synthetic sub-queries shift by model, session, and user context. Building a separate page for each one produces thin content targeting phrases that may never repeat. Map the patterns, write for the cluster.

    Ignoring intent mix. Seer Interactive’s analysis of 49,353 queries found AI Overviews appearing on 36% of informational queries against 8% of commercial and 5% of transactional ones, while comparison-format queries triggered them 95.4% of the time. A map weighted toward transactional prompts will show almost no AI surface area, and the conclusion “AI search doesn’t matter for us” will be an artifact of your sampling, not a finding.

    One more, quieter than the rest: running each prompt once. Model outputs vary between runs. Without repeat runs and averaging, you’ll chase noise for a quarter.

    Conclusion

    The keyword file isn’t wrong, it’s just answering a question users stopped asking in that form. Prompt search gives you richer intent data than keywords ever did, since the user states their constraints outright, but it arrives without volume, rankings, or any of the scaffolding that made keyword strategy legible.

    Start narrow. Pull 20 to 40 seed prompts from sales calls and site search, sort them by Asking against Doing rather than by topic, hold your branded share near 25%, and run them across two or three engines for a full month before you interpret anything. The map that survives contact with real data is the one small enough to maintain.

    FAQ

    Q: What’s the difference between prompt search and keyword search? 

    A: A keyword names a topic in a few words. A prompt describes a situation, including constraints, context, and criteria, then gets decomposed by the AI system into multiple sub-queries before any answer is generated. Keyword search competes for a results page. Prompt search competes for fragments of a synthesized answer.

    Q: How many prompts should I track to start? 

    A: Most practitioners suggest 20 to 40 prompts across two or three models, tracked for at least 30 days. Larger lists are harder to keep clean, and prompt tracking costs scale with volume, so a filtered list generally outperforms an exhaustive one.

    Q: Should I track branded or unbranded prompts? 

    A: Both, but separately, at roughly 25% branded and 75% unbranded. Branded prompts reveal whether AI describes your pricing, features, and positioning accurately. Unbranded prompts reveal whether you’re discoverable at all when someone hasn’t heard of you.

    Q: Can I use keyword research tools for prompt search intent mapping? 

    A: Partially. Keyword tools give you topic coverage and question-form seeds, which is a reasonable starting layer. They won’t capture conversational phrasing, multi-constraint prompts, or the sub-queries fan-out generates, so pair them with internal sources like sales transcripts and site search logs.

    Read More

  • How to Track Your Brand Visibility Across Prompt Searches

    How to Track Your Brand Visibility Across Prompt Searches

    There’s a spreadsheet on your team’s shared drive with about a dozen prompts in it. Someone runs them through ChatGPT every Monday, screenshots the answers, and fills in a column marked “mentioned: yes/no.” Last week your brand showed up in four out of twelve. This week it’s two. Nobody can say whether something actually changed or whether the model just answered differently that morning. That gap is where most prompt search reporting collapses, usually right after someone in the meeting asks a follow-up question.

    Ten Prompts in a Spreadsheet Isn’t Tracking. It’s Sampling Noise.

    Manual spot-checking fails for a reason that has nothing to do with effort. AI answers are probabilistic, so the same question produces a different brand list nearly every time you ask it.

    SparkToro and Gumshoe.ai tested this directly. Running 2,961 prompts across ChatGPT, Claude, and Google’s AI surfaces, they found less than a 1-in-100 chance that the same prompt would return the same list of brands across repeated runs. Search Engine Journal

    Read that number again before you plan your next report.

    If a single run has roughly a 1% chance of reproducing itself, then a screenshot proves nothing about your position. It proves the model said something once. A company can’t credibly claim it “ranks number one in ChatGPT” based on an isolated response, which is what most internal AI visibility decks are quietly built on. Web Logix Group

    The fix isn’t more careful screenshotting. It’s changing the unit of measurement from a binary yes/no to a frequency: out of N runs of this prompt, on what percentage did the brand appear, and in what position.

    Prompt Search Isn’t Keyword Search Wearing a New Name

    A prompt search is a full natural-language question submitted to an AI system that returns a synthesized answer instead of a ranked list. That difference in output format changes what you can measure.

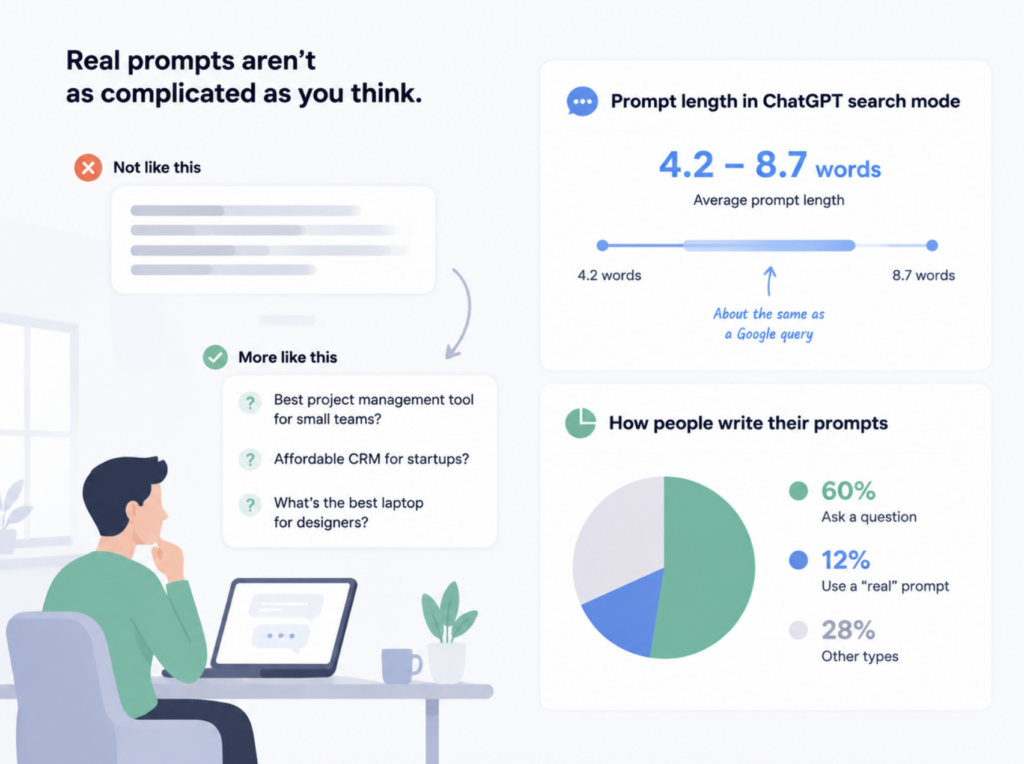
    Here’s the part most teams get backwards. Real prompts aren’t the elaborate templates you see in AI marketing threads. Semrush clickstream data puts the average prompt length in ChatGPT’s search mode at 4.2 to 8.7 words, roughly the same as a Google query. Survey work from Stella Rising found that only 12% of respondents wrote anything resembling a “real” prompt, while about 60% phrased their query as a question.

    So the prompts your buyers actually type look closer to keywords than you’d expect. The divergence happens after they hit enter.

    AI engines don’t retrieve against the string you typed. They expand it. Google’s query fan-out technique breaks one prompt into related searches across subtopics before synthesizing an answer. Research on AI Mode shows 59% of prompts trigger between five and eleven simultaneous sub-queries, with complex B2B queries averaging nine to eleven, while ChatGPT runs 2.3 to 2.8 sub-queries per prompt. Pepper

    Bottom line: one prompt search is not one query. It’s a bundle of them, and your brand has to survive the whole bundle to show up in the answer.

    Step 1: Build a Prompt Set That Matches How Buyers Actually Ask

    Start with coverage, not volume. A tracked prompt set should map to the decisions your buyers make, not to the questions that flatter your product.

    Four categories cover most of the ground:

    Prompt typeExample shapeWhat it tells you
    Category discovery“best [category] tools for [use case]”Whether you’re in the consideration set at all
    Comparison“[competitor] vs alternatives”Where you sit when a rival is the anchor
    Problem-led“how do I fix [problem]”Whether your content gets pulled into solution answers
    Brand-direct“is [your brand] any good”How AI describes you when you’re named

    Skip the brand-direct prompts as your starting point. They’re the easiest to win and the least informative, since a user who already knows your name isn’t the acquisition problem.

    The best source material is your own sales calls and support tickets. Pull the actual phrasing people use when they don’t know your category vocabulary yet. That phrasing is what feeds the fan-out.

    For scale, a set of 100 prompts tends to be enough to cover a single product line across four engines. Multi-product or multi-market brands generally need 250 or more before the coverage stops feeling arbitrary.

    Step 2: Define What Counts as Brand Visibility Before You Measure It

    Most teams measure mentions and stop. That’s the single biggest reason prompt search dashboards look impressive and change nothing.

    Visibility has three layers, and they answer different questions:

    • Mention rate. Out of N runs, how often does your brand appear at all?
    • Position. When you appear, are you first in the list or fourth? Users read AI answers top-down.
    • Citation. Which of your URLs did the engine actually pull from, if any?

    A brand can have a healthy mention rate and zero citations, which means AI knows your name but isn’t reading your content. That’s a very different problem from being absent, and it needs a different fix.

    Platform baselines matter here too. One 2026 analysis of 34,234 AI responses found ChatGPT cited brands 0.59% of the time while Perplexity sat at 13.05%. Comparing your ChatGPT mention rate against your Perplexity mention rate without adjusting for that gap will make ChatGPT look like a failure when it’s behaving normally. Leapd

    Sentiment belongs in the definition as well. Appearing in an answer that calls you “a budget option” isn’t the same win as appearing as “the enterprise standard,” even though both count as a mention.

    Step 3: Run Prompt Searches on a Schedule, Across Every Engine That Matters

    Frequency solves the variance problem. Nothing else does.

    Since a single run is close to meaningless, you need repeated sampling to turn noise into a rate. Weekly cadence works for most brands. Anything slower and you’ll miss the shifts that follow model updates or a competitor’s content push.

    Coverage solves the second problem. Engines don’t share source pools, and the overlap is far smaller than most teams assume. Analysis across hundreds of millions of citations found that only 11% of domains are cited by both ChatGPT and Perplexity, and Google AI Overviews and AI Mode cite the same URLs just 13.7% of the time. Leapd

    That means single-engine tracking isn’t a partial view. It’s a view of a different ecosystem than the one your buyer might be using.

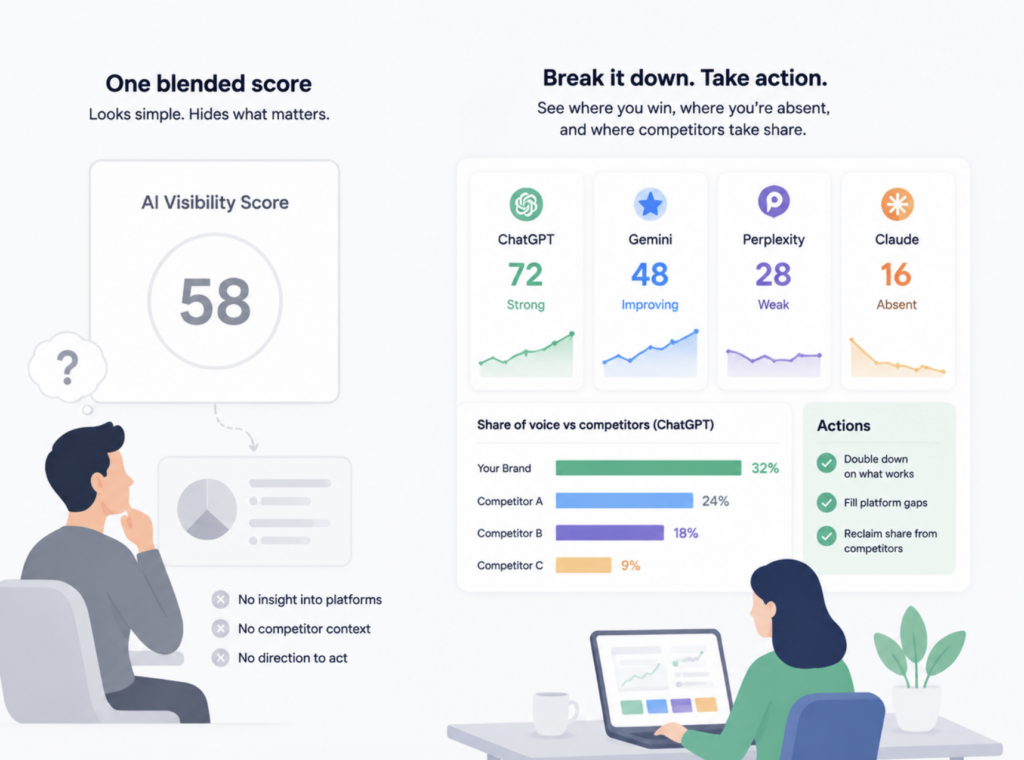
    If you collapse everything into one blended “AI visibility score,” you lose the ability to act on it. As one analysis of citation reporting put it, collapsing all AI visibility into one number removes your ability to see where you’re winning, where you’re absent, and where competitors are taking share.

    Track per engine, per prompt, per week. Then blend for the executive summary, never for the diagnosis.

    Step 4: Trace Each Mention Back to the Source That Produced It

    A visibility number without attribution is a mood ring. It tells you how things feel this week and nothing about what to do next.

    The actionable layer is the source. When your mention rate drops on a comparison prompt, the useful question is which domain the engine cited instead, and whether that domain mentions you at all.

    This matters more now that AI citations have decoupled from rankings. In mid-2025, 76% of AI Overview citations came from top-10 organic results. By early 2026, that had fallen to 38% in Ahrefs data. Your rank report is no longer a proxy for your citation footprint. Leapd

    Practically, source tracing gives you a content backlog. If three of your competitors show up through the same industry roundup and you don’t, that roundup is a placement target. If Reddit threads are feeding an entire prompt cluster, that’s a community presence problem, not a blog problem.

    Track it. Trace it. Fix the source.

    Four Mistakes That Make Prompt Search Data Useless

    Tracking only brand-name prompts. You’ll see great numbers and learn nothing, because the people asking those prompts already found you.

    Running one engine. With roughly 11% domain overlap between major platforms, one-engine tracking leaves most of your citation landscape unmeasured. Cross-platform work has documented citation volume differences of up to 615 times for the same brand between platforms.

    Sampling once and calling it data. One run per prompt per month produces a chart that moves for reasons you can’t explain. Repeat runs are what convert a yes/no into a defensible rate.

    Stopping at the mention. A mention count tells you the score. It doesn’t tell you which play to run. Without source attribution, every optimization decision is a guess.

    What Prompt-Level Tracking Looks Like When It’s Not Manual

    Everything above is doable by hand. The math is what kills it. One hundred prompts, four engines, five repeat runs, weekly, is 2,000 answers a week to capture, parse, and classify. That’s a full-time job before anyone looks at a single insight.

    This is where a purpose-built platform earns its cost. Topify handles the sampling layer, running prompt sets across ChatGPT, Gemini, Perplexity, AI Overviews, and regional engines including DeepSeek, Doubao, and Qwen, then reporting results as rates rather than snapshots.

    The part worth paying attention to is what happens after the data lands. Topify’s analytics cover seven metrics in one view: visibility, sentiment, position, volume, mentions, intent, and CVR. So when your mention rate on a comparison prompt drops, you can check whether position slipped, whether sentiment shifted, and which cited domains changed, without exporting anything. Its prompt discovery keeps surfacing new high-volume questions in your category as buyer language moves, which is the piece a static spreadsheet can never do. Competitor benchmarking runs on the same prompt set, so you’re comparing like for like instead of guessing at rival performance.

    Pricing starts at $99/month for 100 prompts across three engines, and $199/month for 250 prompts, with details on the Topify pricing page. You can get started with a single project before committing a whole team to the workflow.

    Conclusion

    The spreadsheet isn’t wrong. It’s just built on a unit of measurement that doesn’t hold up: a single answer treated as a fact, when the underlying system produces a different answer nearly every time it’s asked.

    Fixing this takes two decisions and one habit. Decide which prompts represent real buying questions, decide whether you’re measuring mentions, position, or citations, then commit to running the set on a schedule across more than one engine. Do that for 30 days and you’ll have something you can defend in a meeting.

    Start with 20 prompts you can name a business reason for. Expand once the pattern is visible.

    FAQ

    Q: How many prompts should I track to get reliable data?
    A: Around 100 prompts covers a single product line across the four main prompt types. What matters more than the count is repeat sampling. Ten prompts run five times weekly produces better data than 50 prompts run once a month, because AI answers vary run to run.

    Q: What’s the difference between prompt search tracking and keyword research?
    A: Keyword research measures search volume for phrases that return ranked links. Prompt search tracking measures how often your brand appears inside a synthesized answer, and in what position. The two overlap in phrasing, since real prompts average under nine words in search mode, but diverge in what happens after retrieval.

    Q: How often should I run prompt searches?
    A: Weekly is the practical default. AI engines update models and refresh their retrieval indexes frequently enough that monthly data misses the changes you’d want to react to. Give any new tracking set at least 30 days before drawing conclusions.

    Q: Why does the same prompt return different brands each time?
    A: Generative systems are probabilistic, and personalization adds session context, location, and history on top. Research on repeated brand recommendation prompts found the same list reappears less than 1% of the time. This is why prompt-level visibility should be reported as a percentage across runs, not as a single result.

    Read More

  • Prompt Search Optimization: How to Get Your Brand Cited in AI Answers

    Prompt Search Optimization: How to Get Your Brand Cited in AI Answers

    Most teams start prompt search work the same way. Someone exports the keyword list, pastes the top 20 terms into ChatGPT one at a time, screenshots the answers where the brand shows up, and calls it a baseline. Two weeks later the same 20 prompts return different answers, different competitors, different sources, and nothing in the report explains what moved.

    The data isn’t broken. The method is. A keyword list was never a prompt list, and one run was never a measurement.

    Your Keyword List Isn’t a Prompt Search List

    The first gap is linguistic. The average prompt runs about five times longer than a classic search keyword, which means the odds of two people typing the exact same thing are close to zero.

    Real user data shows how fast that gap is widening. In an August 2025 panel, roughly half of free-text prompts were still short and keyword-shaped. By January 2026 that share had dropped closer to 30%, with the rest growing longer and more contextual.

    What replaced them is more specific than any keyword tool records. Nearly a quarter of prompts include the word “best,” 28% carry a price or budget constraint, 16% are location-based, and 32% include a personal attribute like profession, team size, or health condition. Separate panel research found task delegation prompts jumped from 10% to 37% between July 2025 and June 2026, while keyword-style prompts fell from 18% to 3%.

    The prompts deciding your category are the ones your keyword tool never recorded.

    One Prompt Search Turns Into a Dozen Hidden Queries

    Here’s the thing about prompt search that trips up most SEO teams: the prompt you track is almost never the query the model actually runs.

    AI search engines decompose a single question into parallel sub-queries before retrieving anything. Published measurements put the range at roughly 9 to 11 sub-queries per prompt, with software and B2B buying questions fanning out hardest. One analysis of 60,000+ fan-out queries found software prompts averaged 11.7 sub-queries on Google, compared with 3.79 for local intent.

    Those sub-queries are invisible and mostly unsearchable. A study of 72,000+ AI-generated queries found that 95% of fan-out phrases show zero monthly search volume, yet they gatekeep which sources make the final answer.

    Which explains the ranking disconnect. Analysis of 173,902 URLs found 68% of pages cited in AI Overviews were not in the top 10 organic results. In SaaS specifically, 81% of brand appearances in ChatGPT answers came from brands outside Google’s top 10 for that keyword.

    You’re not competing for the prompt. You’re competing for a dozen queries nobody showed you.

    Being Mentioned and Being Cited Are Two Different Scoreboards

    Prompt search optimization gets muddy when teams treat “our brand appeared” and “our page was cited” as the same outcome. They behave differently on every platform.

    A 2026 study of 34,234 AI responses found ChatGPT cited brands 0.59% of the time while Perplexity sat at 13.05%, a 46x spread. The same analysis found only 11% of domains are cited by both engines. ChatGPT will happily name your brand in prose and link somewhere else entirely.

    Citation volume differs too. ChatGPT averages around 15 sources per response while Gemini cites 3, and on Gemini the overlap between brands mentioned and domains cited can fall to 30%.

    SignalWhat it tells youWhat it doesn’t
    Brand mentionWhether the model considers you part of the categoryWhether any page of yours influenced the answer
    Source citationWhich URL earned retrieval and attributionWhether the brand was recommended favorably
    Answer positionWhether you’re framed as first choice or footnoteWhether the framing is stable across runs
    SentimentHow the model characterizes youWhich source shaped that characterization

    Track one signal and you’ll optimize for the wrong thing. Track a mention rate that climbs while your citation rate flatlines, and someone else’s content is doing the work of describing you.

    How to Build a Prompt Search Set Your Buyers Would Recognize

    Prompt selection is where most programs quietly fail. A short, well-filtered set outperforms a long, unfocused one, so the goal is coverage of decisions, not coverage of keywords.

    Start from the buying journey, not the keyword export. Semrush’s study of 50,000 brands structured each category as five representative prompts: definition, comparison, alternatives, use case, and buying question. That shape is a workable default for any category you own.

    Seed from paid keywords. Competitor bids on three-word-plus commercial terms are already validated by someone’s budget. “CRM for construction companies” converts into “What’s the best CRM for construction companies?” without guessing.

    Borrow the phrasing from community threads. Reddit sits among the most-cited domains across engines, and its question style is closer to how people actually prompt than any template.

    Add the constraint layer. Budget, location, industry, and role appear in a large share of real prompts, and constraints change results in ways that vary by platform. On ChatGPT and Perplexity they tend to narrow the brand set. On Gemini and AI Overviews they can widen it by triggering more fan-out.

    Keep the wording plain. Controlled testing published in June 2026 found concise keyword-style prompts produce up to 25% more brand mentions than persona-heavy prompts, which tend to push answers toward education instead of recommendation.

    On volume: start with 20 to 40 prompts across 2 or 3 models and hold for at least 30 days. That’s enough to detect absence. To detect movement of a few percentage points, you need far more surface area, which is why mature programs monitor 200 to 500 prompts grouped into intent clusters rather than read individually.

    Measure Prompt Search Visibility as a Distribution, Not a Screenshot

    Every prompt is n = 1. Run it once and you’ve captured one sample from a probabilistic system, which is why last week’s screenshot keeps contradicting this week’s.

    The volatility is measurable. Citation patterns for the same prompts shift 40% to 60% month to month as models update and competitors publish. A 2026 paper argued that AI search visibility should be characterized as a distribution rather than a single-point outcome, because answers vary across runs, wording, and time.

    In practice that means three things. Repeat each prompt several times per platform per cycle instead of once. Fix your sampling conditions, including location and account state, so run-to-run differences reflect the model and not your setup. Report ranges and trend lines, not a number your CMO will treat as precise.

    Semrush’s category data shows why patience matters: across 1,094 tracked categories, only 15% had a clear brand winner. In the other 85%, no single brand showed up consistently across a topic’s related prompts. Category leadership in AI answers is still unclaimed in most markets.

    Where AI Answers Actually Pull Their Sources

    Once you can see which prompts you’re losing, the next question is what to change. The citation data is unusually blunt about this.

    An analysis of 25 million cited links across ChatGPT, Claude, and Gemini found 84% of AI citations trace back to earned media, with paid and advertorial content accounting for about 0.3%. Consolidated ranking of 680 million citations found Reddit is the top source across every major engine at roughly 40% frequency, Wikipedia accounts for 26% to 48% of ChatGPT’s top-10 citation share, and the top 15 domains capture 68% of all citation share.

    Three moves follow from that, in order.

    First, check whether machines can read you at all. A 2026 analysis of over a million citations reported that roughly 73% of sites carry technical barriers blocking AI crawler access, which makes every content decision downstream irrelevant.

    Second, work the sources your prompts already surface. If a comparison roundup or a subreddit thread is being cited for your category prompt, presence in that thread moves your visibility faster than a new landing page will.

    Third, make your own pages quotable. The GEO study from Princeton, Georgia Tech, and IIT Delhi found that adding statistics lifted visibility by 41%, while keyword stuffing lowered it. Models extract passages, so write passages worth extracting.

    Turning Prompt Search Data Into Weekly Decisions

    The operational problem is scale. Repeating 200 prompts across four engines with several runs each, then attributing every change to a source, isn’t manual work anyone sustains past month two.

    That’s the gap platforms like Topify are built for. It tracks brand performance across ChatGPT, Gemini, Perplexity, and other major engines using seven metrics: visibility, sentiment, position, volume, mentions, intent, and CVR. Prompt discovery surfaces high-volume prompts in your category as they emerge, so your tracked set expands with the market instead of freezing at whatever you brainstormed in the kickoff meeting.

    The part that matters most for citation work is source-level analysis. Topify maps the exact domains and URLs engines cite for your prompts, which turns “we dropped in ChatGPT” into “the roundup that used to cite us now cites a competitor.” Competitor benchmarking runs on the same prompt set, so position changes are comparative rather than absolute.

    Pricing starts at $99/month for 100 tracked prompts and 9,000 answer analyses, with the Pro tier at $199/month for 250 prompts. If you want a baseline before committing to a program, running a first prompt set takes less setup than most keyword audits.

    Conclusion

    Prompt search optimization isn’t SEO with a new vocabulary. Prompts are longer and more contextual than keywords, each one fans out into sub-queries you can’t see, and the answer changes between runs, which makes single-shot screenshots worse than useless.

    Build a prompt set around buying decisions instead of search volume. Track mentions and citations as separate signals. Measure across repeated runs and report ranges. Then spend your effort where 84% of citations actually come from: third-party sources that already show up in your category’s answers.

    With 85% of categories still lacking a consistent AI answer winner, the position is open. It goes to whoever measures the prompts first.

    FAQ

    Q: What is prompt search optimization? 

    A: It’s the practice of tracking the natural-language prompts buyers use in AI assistants, measuring whether your brand is mentioned and cited in the resulting answers, and optimizing the sources that feed those answers. The unit of measurement is a prompt and its variants, not a keyword and its ranking position.

    Q: How many prompts should I track to get a reliable read? 

    A: 20 to 40 prompts across two or three engines is enough to confirm whether your brand appears at all. Proving that visibility moved from 18% to 23% takes a much larger, stratified set, typically 150 or more prompts repeated on a fixed schedule.

    Q: If I rank #1 on Google, will AI engines cite me? 

    A: Often not. Analysis of 173,902 URLs found 68% of pages cited in AI Overviews weren’t in the organic top 10, and in SaaS, 81% of ChatGPT brand appearances came from brands outside Google’s top 10 for that keyword. Ranking and citation are separate selection mechanisms.

    Q: Why do my AI answers change every time I run the same prompt? 

    A: Because generative engines are probabilistic and their retrieval layer refreshes constantly. Citation patterns shift 40% to 60% month to month for identical prompts, so a defensible measurement needs repeated runs and confidence ranges rather than a single answer.

    Read More

  • GEO Score Checker for Automotive: Why AI Recommends the Dealer Down the Road Instead of You

    GEO Score Checker for Automotive: Why AI Recommends the Dealer Down the Road Instead of You

    A fleet manager opens ChatGPT and types: “Best Toyota dealer near Dallas with a reliable service department.” Three names come back. Yours isn’t one of them. A DIY mechanic asks Perplexity: “Top-rated aftermarket brake pads for a 2024 F-150.” The answer lists two brands. Neither is yours.

    This isn’t a reputation problem. It’s a technical visibility gap that most dealerships and auto parts brands don’t know they have.

    The GEO Score Checker measures exactly where that gap lives. It scores your website across four dimensions that determine whether AI platforms can find, understand, trust, and recommend your brand. No signup, no cost, results in 60 seconds.

    ✅ Free ⚡ Results in 60 seconds 🔒 No signup required

    The Four Numbers That Decide Whether AI Sends Shoppers Your Way

    AI doesn’t browse your lot. It reads your website’s technical signals, decides whether your content is trustworthy, and either includes you in its recommendation or skips you entirely. The GEO Score Checker breaks that decision into four measurable dimensions.

    Score DimensionWhat It MeasuresAutomotive Impact
    Bot AccessWhether AI crawlers (GPTBot, ClaudeBot, PerplexityBot) can reach your pagesA blocked robots.txt means your entire inventory is invisible to the fastest-growing discovery channel
    Structured DataWhether schema markup helps AI parse your contentWithout AutomotiveBusiness or Vehicle schema, AI can’t distinguish your dealership from a dry cleaner
    Content SignalsWhether AI considers your content authoritativeThin VDP descriptions and missing buying guides signal low expertise to AI models
    Visibility ScoreHow often your brand appears in AI-generated answersMeasures actual presence across ChatGPT, Perplexity, Gemini, and Google AI Overviews

    Here’s how each dimension plays out on the ground.

    Your Lot Has 200 Cars. AI Can’t See a Single One.

    Most dealership website platforms ship with a default robots.txt that blocks GPTBot and PerplexityBot. The IT team never changed it. The marketing team doesn’t know it exists. The result: a Bot Access score below 20, and zero chance of appearing in any AI-generated answer, regardless of how strong your inventory or reviews are.

    One line in a configuration file is erasing your dealership from the buying journey of nearly one in three shoppers who now use AI tools to research vehicles.

    A Parts Brand with Five-Star Reviews but Zero AI Mentions

    An aftermarket brake pad manufacturer ranks on page one of Google for dozens of product keywords. Customer reviews average 4.8 stars. But their Content Signals score sits at 35. Why? The site has product spec sheets but no installation guides, no comparison content, no technical articles that AI can cite as authoritative sources.

    AI models don’t pull from product listings. Research shows 76.6% of AI citations in automotive come from informational content like buying guides and comparisons, not inventory or catalog pages.

    Visible on Google AI Overviews, Invisible on ChatGPT

    A multi-location dealer group checks their Visibility Score and finds a 62 on Google AI Overviews but a 14 on ChatGPT. That split matters. ChatGPT holds 68.4% of AI-assisted car shopping activity, according to Ekho’s 2026 study. Being visible on one platform and absent from the dominant one means you’re missing the majority of AI-driven buyer traffic.

    Cross-platform data confirms this pattern broadly: only 11% of domains are cited by both ChatGPT and Perplexity, meaning most automotive brands are visible on one AI platform and invisible on another.

    How to Run Your Score

    1. Go to the GEO Score Checker
    2. Enter your dealership domain or parts brand URL
    3. Get your four-dimension breakdown in under 60 seconds
    4. Identify your weakest dimension and prioritize from there

    What Car Buyers and Fleet Managers Are Asking AI Right Now

    The shift isn’t coming. It’s already here. Cox Automotive’s 2025 Car Buyer Journey Study found that 19% of all vehicle buyers and 25% of new-vehicle buyers used AI websites or AI-generated overviews during their purchase process. Those buyers reported higher satisfaction, greater trust in dealers, and a faster process.

    Here’s what those AI conversations actually look like:

    AI Prompt ExamplePlatformSearch IntentWhat It Reveals
    “Best Honda dealers near me with transparent pricing”ChatGPTLocal dealer selectionOnly dealers with strong Content Signals and entity consistency get named
    “OEM vs aftermarket catalytic converter for 2023 Camry, pros and cons”PerplexityParts purchase decisionParts brands without comparison content are excluded from the answer
    “Which dealerships in Phoenix have the best service department ratings”GeminiService trust evaluationAI pulls from review aggregators and structured business data, not your homepage
    “Best all-season tires for a Subaru Outback under $150 each”ChatGPTProduct recommendationTire and parts brands need structured product data and authoritative guides to appear
    “Reliable used car dealers in Atlanta that offer certified pre-owned”PerplexityHigh-intent local queryDealers without CPO schema and detailed program pages are invisible to this query
    “What aftermarket exhaust brand has the best fitment for Jeep Wrangler JL”ChatGPTBrand-specific parts queryAI favors brands with technical installation content and community mentions

    The buyers asking these questions are high-intent. AI referral traffic in automotive converts at roughly 14-16%, compared to about 2-3% for traditional organic search. If your brand isn’t in the AI answer, you’re not losing impressions. You’re losing ready-to-buy customers.

    Three GEO Blind Spots That Keep Automotive Brands Out of AI Answers

    Automotive has industry-specific technical barriers that make GEO optimization harder than in most verticals. These aren’t content quality issues. They’re structural problems that sit between your brand and AI’s ability to process it.

    The Robots.txt Lockout No One Audits

    Dealership website platforms often default to blocking AI crawlers. GPTBot, ClaudeBot, PerplexityBot, and others are disallowed in robots.txt without the dealer ever requesting it. The platform vendor set it, and no one revisited the decision.

    This is the single fastest GEO fix in automotive. Unblocking these crawlers doesn’t require a website redesign or content overhaul. It requires editing a text file. But most dealers don’t know the file exists, and their Bot Access score reflects that gap.

    The problem compounds when inventory pages rely on client-side JavaScript rendering. Even with crawlers unblocked, if your vehicle detail pages only load through JS execution, AI crawlers that don’t render JavaScript will see an empty page. Your 200-unit lot reads as a blank screen.

    The Schema Gap That Makes AI Treat Your Dealership Like Any Other Business

    Over 60% of dealerships lack proper schema markup. Without AutomotiveBusiness, Vehicle, and FAQPage schema, AI platforms can’t distinguish your dealership from a restaurant or a law office sharing the same strip mall.

    Schema tells AI what your business is, what vehicles you carry, what services you offer, and how to verify that information. A dealership with complete Vehicle schema on every listing gives AI structured attributes to match against buyer queries: make, model, year, price, mileage, fuel type, condition. A dealership without it forces AI to guess from unstructured page text, and AI doesn’t guess in your favor.

    For parts brands, Product schema with detailed attributes (compatibility, fitment, material, warranty) is equally critical. When a buyer asks AI for “best brake pads for a 2024 F-150,” AI needs structured product data to match your part to that specific vehicle. A product page with only a title and price gives AI nothing to work with.

    The OEM Memory Bias That Buries Smaller Parts Brands

    AI models carry a built-in advantage for OEM brand names. During training, these models ingested millions of pages where factory-original parts were discussed, reviewed, and recommended. The result: when a buyer asks AI for a replacement part, AI defaults to the brand name it encountered most during training.

    Aftermarket and independent parts brands face a structural disadvantage that has nothing to do with product quality. The fix isn’t competing on brand recognition alone. It’s building the technical content and structured data signals that give AI a reason to cite you alongside, or instead of, the OEM option.

    One aftermarket retailer proved this is possible: after a focused GEO campaign, their AI visibility grew from under 1% to over 20% of tracked prompts, and AI referral revenue increased 344% in six months.

    That gap is measurable. And it starts with knowing your current score.

    From a One-Time Score to Continuous Visibility Tracking

    The GEO Score Checker gives you a snapshot: here’s where you stand right now across four dimensions. That snapshot is valuable. It tells you whether your robots.txt is blocking crawlers, whether your schema is missing, and whether AI platforms are citing you at all.

    But AI visibility isn’t static. Platforms update their retrieval algorithms. Competitors add structured data. New model training runs shift which brands get recommended. A score that reads 55 today could drop to 38 next quarter without any change on your end.

    Topify’s Comprehensive GEO Analytics platform turns that one-time check into continuous monitoring across every dimension the checker measures, and several it doesn’t.

    CapabilityFree GEO Score CheckerTopify Platform
    Check frequencyOne-time snapshotContinuous monitoring
    Dimensions tracked4 GEO scoresFull GEO analytics + sentiment + citations
    Historical trendsNoneFull trend history with alerts
    Competitor benchmarkingNot includedReal-time competitor tracking
    Platform breakdownAggregatedPer-platform (ChatGPT, Perplexity, Gemini, AI Overviews)
    Optimization actionsDirectional guidanceSpecific, prioritized execution steps

    A single score tells you where you stand. Continuous monitoring tells you which direction you’re moving, and whether your competitors are pulling ahead.

    Explore pricing or start a free trial with no credit card required.

    Conclusion

    AI is already influencing where nearly one in three car buyers shop and which parts brands they trust. The dealerships and parts brands that show up in those AI answers aren’t necessarily the biggest or the best reviewed. They’re the ones whose websites let AI crawlers in, speak AI’s language through structured data, and publish content that AI can cite with confidence.

    Start with a free check. Run your domain through the GEO Score Checker and see which of the four dimensions is holding you back. From there, dig deeper with the AI Robots Checker if Bot Access is your weak point, or the Brand Authority Checker to understand how AI perceives your brand’s expertise. If you want a full cross-platform picture before committing to ongoing monitoring, the AI Visibility Report delivers a detailed snapshot across ChatGPT, Perplexity, Gemini, and Google AI Overviews.

    Frequently Asked Questions

    Why does my dealership rank well on Google but never appear in ChatGPT or Perplexity answers?

    Google rankings and AI visibility are driven by different signals. Google uses backlinks and keyword relevance. AI platforms rely on crawler access, structured data, content authority, and cross-platform entity consistency. A dealership can rank first on Google while scoring below 30 on the GEO Score Checker because its robots.txt blocks AI crawlers entirely. The two systems don’t share a ranking pipeline.

    Do aftermarket parts brands have a realistic chance of competing with OEM names in AI recommendations?

    Yes, but not through brand awareness alone. AI models default to OEM names because training data skews toward factory-original content. Aftermarket brands that invest in structured Product schema, detailed fitment guides, and comparison content create the technical signals AI needs to cite them. One aftermarket retailer grew AI visibility from under 1% to over 20% of tracked prompts in six months by focusing on these signals.

    What’s the most common reason dealerships score low on Bot Access in the GEO Score Checker?

    The default robots.txt configuration on many dealership website platforms blocks GPTBot, ClaudeBot, and PerplexityBot. This single file prevents every AI crawler from indexing your site. It’s the fastest fix available: editing robots.txt to allow these bots can move your Bot Access score from under 20 to above 70 in one update.

    How is a GEO score different from a traditional SEO audit score?

    An SEO audit measures how well your site performs in link-based search engines: page speed, backlinks, keyword density, crawl errors. A GEO Score Checker measures how visible and citable your site is to AI answer engines specifically. It evaluates whether AI crawlers can access your pages, whether structured data helps AI understand your content, whether your content carries authority signals, and whether AI platforms actually mention your brand. You can score 90 on an SEO audit and 25 on a GEO check.

    Read More:

  • GEO Score Checker for Franchises: Why AI Skips Your Brand When Buyers Ask “Best Franchise to Own”

    GEO Score Checker for Franchises: Why AI Skips Your Brand When Buyers Ask “Best Franchise to Own”

    A prospective franchise buyer sits down, opens ChatGPT, and types: “What’s the best home services franchise under $150K?” The answer comes back in seconds. Three brands get named, with investment ranges, support structures, and estimated ROI. Your franchise isn’t one of them.

    This isn’t a branding problem. It’s a GEO problem. The technical signals that determine whether AI platforms recommend your franchise are measurable, and most franchise brands score poorly on all four of them.

    Topify‘s GEO Score Checker runs a free diagnostic across the four dimensions that control whether AI names your brand or skips it entirely.

    ✅ Free ⚡ Results in 60 seconds 🔒 No signup required

    The Four Numbers That Tell You Why AI Recommends Other Franchises Instead of Yours

    Every franchise brand gets scored across four GEO dimensions. The difference between being named in an AI answer and being invisible often comes down to these numbers.

    Score DimensionWhat It MeasuresFranchise Impact
    Bot AccessWhether AI crawlers (GPTBot, ClaudeBot, PerplexityBot) can reach your siteMany franchise sites use aggressive robots.txt rules that block AI bots while allowing Googlebot. The result: visible on Google, invisible to ChatGPT.
    Structured DataQuality and presence of schema markup (JSON-LD)Franchise sites rarely deploy LocalBusiness schema per location. AI extracts structured facts with high confidence but struggles to parse investment details from unstructured prose.
    Content SignalsAuthority markers: E-E-A-T, content depth, semantic relevanceFDD summaries, franchisee testimonials, and unit economics data often live behind gated pages or in PDFs that AI can’t index.
    Visibility ScoreActual brand presence across ChatGPT, Perplexity, Gemini, AI OverviewsA franchise can dominate Google’s local 3-pack in 200 markets and still appear in zero AI-generated “best franchise” recommendations.

    Your FDD Is Thorough, but GPTBot Can’t Read Your Site

    A franchise brand with 15 years of operating history and a 300-page FDD should score well on authority signals. In practice, many don’t. The disclosure documents sit behind registration walls. The unit economics data lives in PDFs. The AI crawlers that would use this information to build a recommendation get a 403 error instead.

    Bot Access scores below 30 typically mean AI platforms don’t even know your franchise exists as a recommendable option.

    200 Locations, Zero Structured Data per Location

    Research shows that 61% of pages cited by ChatGPT contain rich schema markup, compared to just 25% of traditional Google SERP pages. For franchise brands, the gap is worse. Corporate sites may carry Organization schema, but individual location pages almost never include LocalBusiness JSON-LD with service types, investment ranges, territory details, or franchisee contact information.

    AI systems prefer structured facts they can extract with certainty. When your location pages offer nothing but a phone number in the footer, AI skips to a competitor whose page hands it clean, labeled data.

    Strong Google Local Pack, Invisible on Perplexity

    Here’s the thing. A franchise brand can hold the top local 3-pack position in 150 cities and still score below 20 on Visibility. Google local rankings rely on GBP optimization, review volume, and NAP consistency. AI platforms don’t use any of those signals. They synthesize answers from crawlable content, structured data, and third-party citations. Two completely different systems, two completely different scorecards.

    How to check your franchise’s GEO score:

    1. Go to GEO Score Checker
    2. Enter your franchise brand name or corporate domain
    3. Get four-dimension scores in under 60 seconds
    4. Compare dimensions to identify your weakest signal

    What Prospective Franchisees Ask AI Before They Ever Call a Broker

    The franchise discovery process has shifted. Prospective buyers now arrive at discovery calls with AI-generated brand comparisons already in hand. Some upload FDD documents directly into ChatGPT for clause-by-clause analysis. The brands that appear in those early AI conversations shape the consideration set before a broker or franchise development rep ever gets a chance to pitch.

    AI Prompt ExamplePlatformSearch IntentWhat It Reveals
    “Best franchise to own under $100K with semi-absentee model”ChatGPTInvestment screeningAI names 3-5 brands. If yours isn’t listed, you’ve lost the prospect at the research stage.
    “Compare home services franchises: profit margins, training support, territory size”PerplexityBrand comparisonAI pulls structured data to build side-by-side tables. Brands without structured content get excluded.
    “Is [franchise brand] a good investment in 2026?”GeminiDue diligenceAI evaluates brand reputation from reviews, news, and third-party citations. Thin online presence triggers a cautious or negative summary.
    “Low-risk franchise opportunities for first-time business owners”ChatGPTCategory discoveryAI recommends brands with clear authority signals: published franchisee success stories, transparent unit economics, third-party validation.
    “What are the hidden costs of owning a [category] franchise?”PerplexityRisk assessmentAI cites sources that discuss fees, royalties, and real-world franchisee experiences. If your brand’s content doesn’t address these, competitors’ content fills the gap.

    According to McKinsey research, an estimated $750 billion in US revenue will flow through AI-powered search by 2028. For franchise brands, this means the “best franchise to buy” prompt is becoming the new top-of-funnel entry point, and the brands AI recommends at that stage capture disproportionate prospect attention.

    That matters more than it sounds. A franchise prospect who asks AI for a recommendation and doesn’t see your brand won’t search for you next. They’ll contact the brands AI named.

    The Local SEO Trap: Why a Decade of Google Optimization Doesn’t Help You in AI

    Franchise brands have spent the last ten years perfecting local SEO. Google Business Profiles are claimed and optimized across every market. Directory listings are synchronized. NAP data is consistent. Review generation programs run at scale. And all of it worked, for Google.

    The 2026 Local Visibility Index tells a different story for AI. Only 1.2% of franchise locations get recommended by ChatGPT when buyers ask “best [service] near me” or “[category] in [city].” The same locations appear in Google’s local 3-pack at a rate of 35.9%. That’s a 30x gap.

    The gap exists because AI recommendation engines use fundamentally different inputs than Google local search. Google’s local algorithm weighs proximity, GBP completeness, review volume, and citation consistency. AI platforms weigh crawlable content depth, structured data quality, third-party mentions in authoritative sources, and cross-platform citation consistency. Almost none of the franchise industry’s local SEO investment transfers.

    The Parent Brand vs. Location Entity Problem

    AI treats entity resolution differently than Google. When someone asks Google for “best cleaning franchise near me,” Google has years of local index data connecting the parent brand to each location. AI platforms don’t. They encounter a corporate site talking about the brand and 200 location pages with thin content, and they can’t confidently connect the two into a single recommendable entity.

    The result: the parent brand’s authority doesn’t flow down to individual locations, and the individual locations don’t have enough standalone authority to earn a recommendation. Both layers fail.

    FDD Uploads vs. Brand Content Citability

    Franchise attorneys have started warning buyers about relying too heavily on AI for due diligence, and for good reason. Prospects are uploading full FDD documents into ChatGPT and Claude, asking the model to flag risks, compare Item 19 financials, and generate questions for discovery calls. This practice is now common enough to have its own playbooks.

    The irony is that franchise brands don’t structure their own web content to compete with those AI-analyzed FDD summaries. A prospect gets a detailed, AI-generated breakdown of a competitor’s unit economics from an uploaded FDD, then visits your website and finds a brochure-style page with no structured investment data, no schema markup, and no content that AI can cite as a credible source. Your own content loses to a competitor’s legally mandated disclosure document.

    From a One-Time Score to Continuous Franchise GEO Monitoring

    Running your franchise through the GEO Score Checker gives you a clear picture of where you stand right now. But GEO signals change. AI models update their training data. Competitors optimize. New franchise prospects ask new prompts. A single score tells you the starting point, not the direction.

    Topify’s Comprehensive GEO Analytics picks up where the free checker leaves off, tracking all four GEO dimensions continuously across every major AI platform.

    CapabilityFree GEO Score CheckerTopify Platform
    Check frequencyOne-time snapshotContinuous monitoring
    Dimensions tracked4 GEO scoresFull GEO analytics + sentiment + citations
    Historical trendsNoneFull trend history with alerts
    Competitor benchmarkingNot includedReal-time competitor tracking
    Platform breakdownAggregatedPer-platform (ChatGPT, Perplexity, Gemini, AI Overviews)
    Optimization actionsDirectional guidanceSpecific, prioritized execution steps

    For franchise brands managing visibility across dozens or hundreds of locations, continuous tracking isn’t optional. It’s the difference between catching a Visibility Score drop in week one and discovering it three months later when prospect inquiries have already declined.

    Every plan includes a 7-day free trial with no credit card required. See pricing for details, or start a free trial to connect your franchise brand today.

    Conclusion

    Franchise buyers are making decisions inside AI chat windows before they ever call a broker, attend a discovery day, or visit a franchise expo booth. The brands AI recommends at that moment capture the consideration set. The brands it doesn’t mention lose prospects they’ll never know existed.

    That visibility gap is measurable. Check your franchise brand’s GEO score in 60 seconds, identify which of the four dimensions is holding you back, and start closing the gap between your Google presence and your AI presence.

    If your Bot Access score reveals crawler blocks, the AI Robots Checker can pinpoint exactly which directives are keeping GPTBot and ClaudeBot out. For brands concerned about how current their AI representation is, the Knowledge Freshness Checker tests whether AI models are working with outdated brand information. And if you want a quick cross-platform snapshot before committing to continuous monitoring, the AI Visibility Report shows where your brand stands across ChatGPT, Perplexity, and Gemini in a single view.

    Frequently Asked Questions

    Why does my franchise rank well on Google but not appear in ChatGPT recommendations?

    Google local rankings depend on GBP optimization, review volume, and NAP consistency. AI platforms use entirely different signals: crawlable content depth, structured data quality, and third-party citation authority. A brand can hold the local 3-pack in 150 cities and still score below 20 on AI Visibility because the inputs don’t overlap. The GEO Score Checker shows exactly which signals are missing.

    Does the GEO Score Checker evaluate each franchise location separately or just the corporate site?

    The checker evaluates whatever domain or brand name you enter. For franchise brands, running the check on both the corporate domain and a sample location page reveals how much brand authority actually transfers from parent to franchisee. In most cases, the gap between the two scores is where the real problem lives.

    What’s the most common reason franchise brands score low on Structured Data?

    Franchise corporate sites may carry basic Organization schema, but individual location pages almost never include LocalBusiness JSON-LD with territory details, service types, or investment information. Since AI systems extract structured facts with higher confidence than unstructured prose, missing schema at the location level is typically the single largest scoring drag for franchise brands.

    Can improving my GEO score actually increase franchise lead volume?

    Prospective franchisees increasingly start their research inside AI tools. When a buyer asks ChatGPT for “best fitness franchise under $200K” and your brand appears in the answer, that’s a qualified lead you didn’t pay for. Brands with Visibility Scores above 60 tend to appear in category-level AI recommendations consistently, which means their name enters the prospect’s consideration set before any broker or sales rep gets involved.

    Read More: