Blog

  • GEO Score Checker for Nonprofits: Why AI Recommends Other Organizations When Donors Ask Where to Give

    GEO Score Checker for Nonprofits: Why AI Recommends Other Organizations When Donors Ask Where to Give

    A donor opens ChatGPT and types: “Best nonprofits working on clean water access in East Africa.” Three organizations come back. Yours isn’t one of them.

    Your programs are strong. Your impact data is real. But the AI never saw any of it.

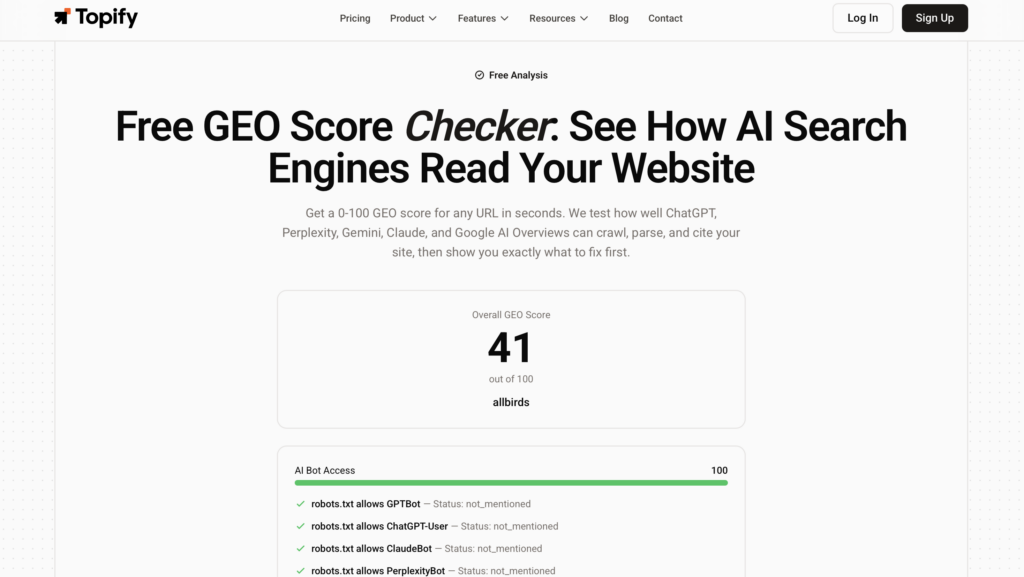
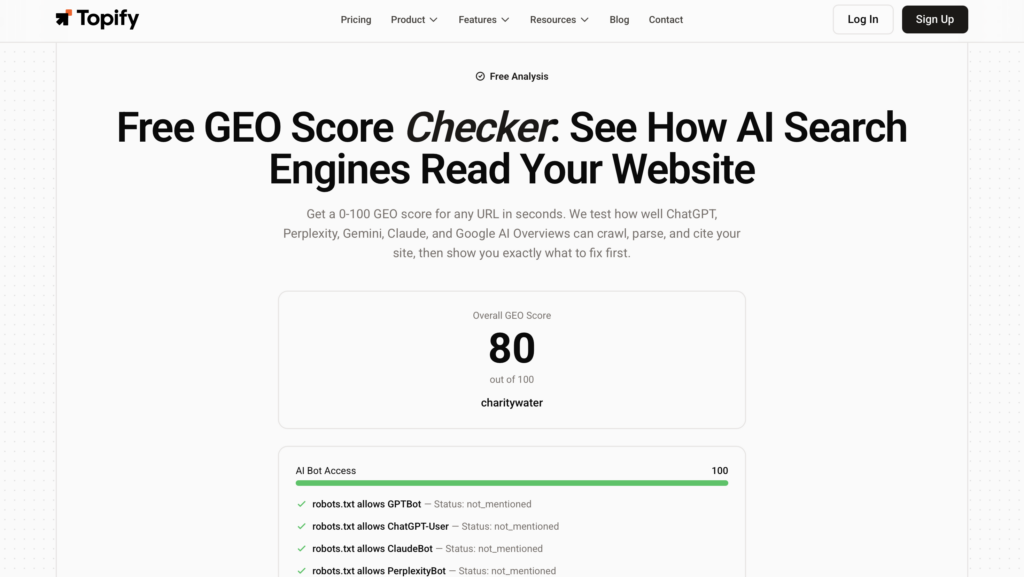
    That gap between mission quality and AI visibility is a GEO problem, not a marketing problem. And it’s measurable. Topify’s free GEO Score Checker scans your nonprofit’s website across four dimensions that determine whether AI platforms recommend you or skip you entirely.

    ✅ Free ⚡ Results in 60 seconds 🔒 No signup required
    The Four Numbers That Tell You Why AI Skips Your Nonprofit

    AI platforms don’t read your mission statement and decide you’re worthy. They look for technical signals, structured data, content authority, and cross-platform presence. The GEO Score Checker breaks this into four scores, each one diagnosable and fixable.

    Here’s how those four dimensions translate to nonprofit-specific outcomes:

    Score DimensionWhat It MeasuresNonprofit Impact
    Bot AccessWhether AI crawlers (GPTBot, ClaudeBot, PerplexityBot) can reach your contentIf your annual reports sit behind login walls or in unindexable PDFs, AI never processes your impact data
    Structured DataWhether your site uses schema markup (JSON-LD, Organization, NGO types) to tell AI what you areWithout it, AI can’t confirm you’re a registered nonprofit, what cause you serve, or where you operate
    Content SignalsWhether AI considers your content authoritative enough to citeThin program pages with vague language score lower than pages with specific outcomes, methodology, and third-party validation
    Visibility ScoreHow often your brand appears across ChatGPT, Perplexity, Gemini, and AI OverviewsA nonprofit visible on Perplexity but absent from ChatGPT loses different donor segments on each platform

    Your Annual Report Is a 40-Page PDF. AI Can’t Read It.

    Many nonprofits publish their strongest evidence of impact inside downloadable PDF reports. Those documents are often blocked from AI crawlers or too complex for AI to parse. The result: a Bot Access score under 30, and your most persuasive content is invisible to every AI platform.

    No Schema Means AI Guesses What You Are

    A PR News analysis found that most charity websites lack the structured data AI engines need to classify them accurately. Without NGO or Organization schema, your site asks AI to guess your cause area, your geographic scope, and your legitimacy. That guessing usually favors organizations that did the markup work.

    Strong Mission, Weak Authority Signals

    Your “About Us” page says you’ve served 200,000 families. But if that claim isn’t backed by structured content with named programs, published evaluation data, and external citations from rating platforms, AI treats it as unverified. Content Signals scores below 40 typically mean AI can’t distinguish your site from a less established organization.

    How to Run a GEO Check on Your Nonprofit Website

    1. Go to the GEO Score Checker
    2. Enter your nonprofit’s domain or brand name
    3. Get your four-dimension score breakdown in under 60 seconds
    4. Identify which dimension is pulling your overall score down

    The weakest score is usually the one that matters most. For nonprofits, that tends to be Bot Access or Structured Data.

    What Donors and Grant-Makers Ask AI Before They Choose a Partner

    Donors aren’t the only ones querying AI about your organization. Grant-makers, corporate CSR teams, and potential program partners are using AI platforms to shortlist collaborators. These prompts carry real budget decisions behind them.

    AI Prompt ExamplePlatformSearch IntentWhat It Reveals
    “Best nonprofits for youth education in Sub-Saharan Africa”ChatGPTIndividual donor discoveryWhether AI includes your org in cause-specific recommendation lists
    “Top-rated charities for disaster relief with low overhead”PerplexityDonor due diligenceWhether your financial transparency data reaches AI through structured signals
    “Nonprofit partners for corporate water sustainability program”GeminiCorporate partnership sourcingWhether AI surfaces your org for B2B collaboration queries
    “Which NGOs have the highest impact per dollar in maternal health”ChatGPTFoundation grant screeningWhether AI can extract and cite your cost-effectiveness data
    “Compare environmental nonprofits working on reforestation with verified outcomes”PerplexityComparative evaluationWhether your impact verification is structured enough for AI to rank you

    GoFundMe Pro reports that more than 900 million people now use ChatGPT weekly. The search behavior shift is structural: donors type a question, get a direct AI answer, and often never visit a website at all. NonProfit PROdocumented donors telling ChatGPT to donate directly on their behalf, bypassing the organization’s website entirely.
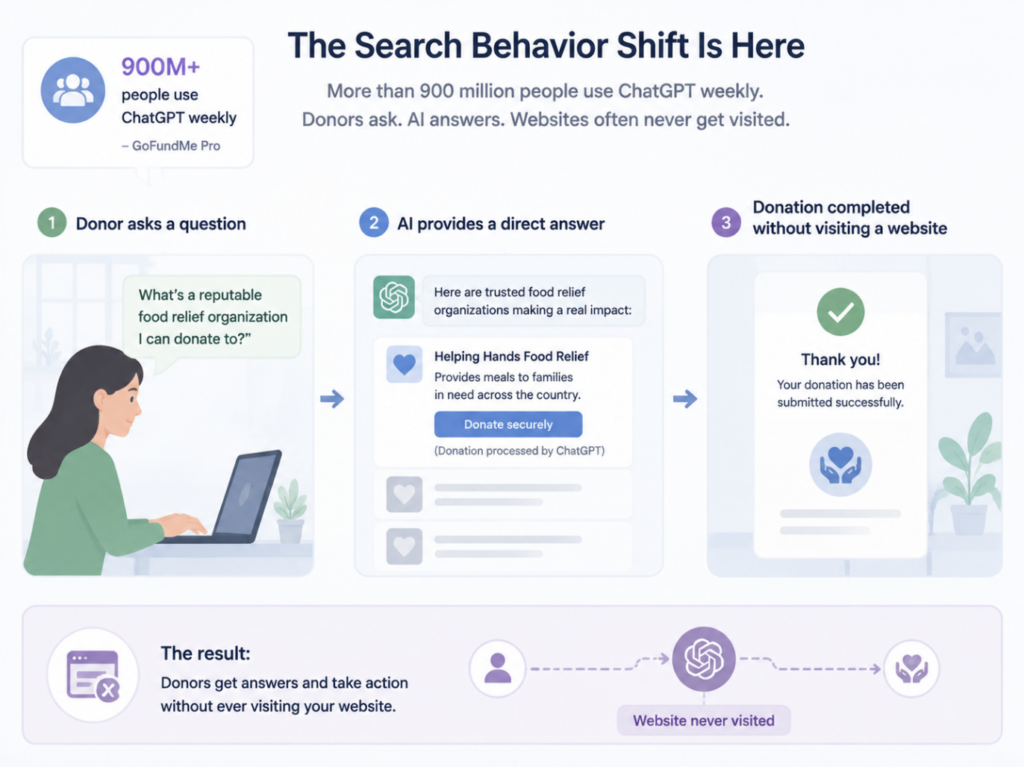
    If your nonprofit isn’t in those AI-generated answers, you’re not losing a click. You’re losing the donation.

    Where Nonprofit Websites Consistently Lose GEO Points

    Three patterns show up repeatedly when nonprofit sites run through a GEO audit. Each one is tied to how the sector traditionally builds and manages digital content.

    Impact Data Locked Behind Walls AI Can’t Open

    Nonprofits often gate their best content. Donor portals, password-protected dashboards, and downloadable PDFs full of outcome data are standard practice. The problem is that GPTBot, ClaudeBot, and PerplexityBot can’t log in. They can’t open most PDFs. And they can’t index what they can’t access.

    A nonprofit with a rich donor portal and a thin public website will score well on internal stakeholder satisfaction and poorly on Bot Access. The fix isn’t to open everything. It’s to publish a public-facing summary of key impact data in crawlable HTML, with structured markup.

    Trust Signals That Don’t Connect

    Charity Navigator scores, GuideStar Platinum seals, and independent evaluation reports are exactly the kind of third-party trust signals AI engines rely on when recommending nonprofits. But most organizations treat these as badge images in a website footer, not as structured data AI can parse.

    The disconnect matters. AI can pull your Charity Navigator rating from Charity Navigator’s own site. But if your website doesn’t reinforce that signal with matching schema markup and consistent entity data, AI has weaker confidence that the charity it found on the rating site is the same entity on your domain. Structured Data scores below 40 often trace back to this gap.

    Visible on One Platform, Missing on Another

    Cross-platform fragmentation hits nonprofits harder than most sectors. Perplexity cites web sources in real time, so a nonprofit with strong blog content might appear there. But ChatGPT draws more heavily from training data and structured knowledge, where many smaller nonprofits have limited presence. Gemini leans on Google’s own index, which favors schema-rich sites.

    The result: an organization can have decent visibility on one platform and near-zero on another. Donors who use different AI tools get different recommendation lists. A single GEO score check can reveal this split, but fixing it requires understanding which dimension is weakest on each platform.

    From a One-Time Score to Continuous Visibility Tracking

    A GEO Score Checker result tells you where you stand right now. That’s valuable for diagnosis. But donor behavior, AI model updates, and competitor activity change your visibility position week to week. A score that looks acceptable today can drop after a model retraining cycle without any change on your end.

    That’s the difference between a snapshot and a monitoring system.

    CapabilityFree GEO Score CheckerTopify Platform
    Check frequencyOne-time snapshotContinuous monitoring
    Dimensions tracked4 GEO scoresFull GEO analytics + sentiment + citations
    Historical trendsNoneFull trend history with alerts
    Competitor benchmarkingNot includedReal-time competitor tracking
    Platform breakdownAggregatedPer-platform (ChatGPT, Perplexity, Gemini, AI Overviews)
    Optimization actionsDirectional guidanceSpecific, prioritized execution steps

    Comprehensive GEO Analytics tracks all four GEO dimensions continuously, flags drops before they become donor-visible, and shows exactly where competitors are gaining citation share. For nonprofits managing multiple programs or regional chapters, per-platform breakdowns show which AI engine is surfacing which part of your organization.

    You can start a free trial with no credit card required, or review pricing to see which plan fits your team size.

    Conclusion

    Donors, grant-makers, and corporate partners are making giving decisions based on what AI tells them. If your nonprofit’s website can’t pass the technical signals AI uses to select recommendations, your impact data never enters the conversation.

    Check your GEO score now. It takes 60 seconds, costs nothing, and shows you exactly which of the four dimensions is keeping your organization out of AI-generated answers.

    For a deeper dive into GEO strategy, read The Complete Guide to Generative Engine Optimization (GEO), AI Search Visibility: What It Is and How to Improve It, or Free vs Paid AI Visibility Trackers: What You Actually Get.

    If your Bot Access score is low, the AI Robots Checker can pinpoint which crawlers your robots.txt is blocking. For a broader snapshot across platforms, the AI Visibility Report shows where your brand appears and where it doesn’t. And the Knowledge Freshness Checker reveals whether AI models are working with current information about your programs or outdated data from years ago.

    Frequently Asked Questions

    Does GEO scoring work differently for nonprofits than for commercial brands?

    The four scoring dimensions are the same, but the inputs that drive each score differ. Nonprofits typically struggle with Bot Access because impact data lives in PDFs and gated portals, and with Structured Data because few charity websites implement NGO-specific schema markup. Commercial brands more often struggle with Content Signals. Running the GEO Score Checker reveals which dimension is weakest for your specific site.

    Why does our nonprofit score low on Content Signals when we publish annual impact reports?

    Content Signals measure whether AI considers your published content authoritative enough to cite. If your reports are PDFs that crawlers can’t index, or if your public web pages summarize outcomes in vague terms without named programs, specific numbers, or external validation, AI treats that content as low-authority. The fix is publishing key findings in crawlable HTML with concrete data points.

    How do charity rating profiles on Charity Navigator or GuideStar affect our AI visibility?

    AI engines pull data from those platforms when generating nonprofit recommendations. But your own website needs to reinforce those signals with matching structured data. If Charity Navigator lists your 4-star rating and your site doesn’t confirm that entity relationship through schema markup, AI has lower confidence connecting the two. A strong rating profile plus weak on-site structured data still produces a mediocre Structured Data score.

    Our organization appears in Perplexity results but not in ChatGPT. Why the difference?

    Each AI platform sources information differently. Perplexity searches the live web in real time, so strong blog content and recent press coverage can surface there. ChatGPT relies more on training data and structured knowledge bases, where smaller or newer nonprofits have less representation. Comprehensive GEO Analytics breaks down your visibility per platform so you can target the specific gaps.

    Read More:
  • GEO Score Checker for Architecture and Engineering: Why Award-Winning Firms Don’t Make AI’s Shortlist

    GEO Score Checker for Architecture and Engineering: Why Award-Winning Firms Don’t Make AI’s Shortlist

    A real estate developer sits down with ChatGPT and types: “Recommend architecture firms experienced in mixed-use healthcare facilities with LEED certification in the Southeast.” The response names three firms. None of them is yours.

    Your portfolio includes exactly that project type. You’ve won regional AIA awards for it. But the AI never saw your work, because your website speaks in images and the AI reads code.

    That gap between what you’ve built and what AI can see is measurable. Topify’s GEO Score Checker quantifies it across four dimensions in under a minute, showing you exactly where the breakdown happens.

    ✅ Free ⚡ Results in 60 seconds 🔒 No signup required

    The Four Numbers That Tell You Why AI Skips Your Design Firm

    GEO stands for Generative Engine Optimization. It’s the discipline of making your brand visible inside AI-generated answers, not just on Google’s first page. The GEO Score Checker evaluates your site against four dimensions that AI platforms use to decide whether to recommend you.

    For architecture and engineering firms, each dimension translates into a specific business risk.

    Score DimensionWhat It MeasuresArchitecture & Engineering Impact
    Bot AccessWhether AI crawlers (GPTBot, ClaudeBot, PerplexityBot) can reach your siteMany AEC firm sites block these bots by default or use JavaScript rendering that returns empty pages to crawlers
    Structured DataQuality of schema markup and machine-readable metadataschema.org includes a dedicated Architect type, yet most firms don’t use it. Project types, specialisms, and certifications remain invisible to AI
    Content SignalsDepth, authority, and semantic relevance of your written contentPortfolio pages with 14 images and three words of body copy give AI nothing to index or cite
    Visibility ScoreHow often your brand appears in AI-generated answers across platformsMeasures actual presence in ChatGPT, Perplexity, Gemini, and Google AI Overviews

    Here’s the thing: a firm can score well on one dimension and fail on another. That pattern is especially common in AEC.

    Award-Winning Portfolio, Blocked Crawlers

    A mid-size firm redesigns its website with a gallery-first layout. The photography is editorial quality. But the site runs on a JavaScript framework that renders beautifully in browsers and returns an empty <div> to AI crawlers. Bot Access score: below 20. The AI literally cannot enter the building.

    Deep Project Experience, No Machine-Readable Specialisms

    A structural engineering practice has completed 200+ healthcare projects across three states. Their “Projects” page lists them with thumbnails and one-line captions. No schema markup tags these as healthcare projects. No structured data communicates LEED certifications, MEP coordination capabilities, or project scale. Structured Data score: below 30. When a procurement team asks AI for a structural engineer with healthcare experience, the model has no structured evidence to work with.

    Strong ArchDaily Presence, Zero ChatGPT Visibility

    A design studio gets featured regularly on ArchDaily and Dezeen. Perplexity, which retrieves heavily from web sources, occasionally surfaces the firm. But ChatGPT and Google AI Overviews rely more on structured site data and entity-level signals. Without that anchor on the firm’s own domain, the third-party citations float unattached. Visibility Score: 55 on Perplexity, under 15 on ChatGPT.

    That cross-platform fragmentation is the norm, not the exception, in this industry.

    How to Run Your Firm’s GEO Check

    1. Go to GEO Score Checker.
    2. Enter your firm’s brand name or domain.
    3. Get your four-dimension score in 60 seconds.
    4. Compare dimensions to find the weakest signal.

    The weakest dimension is where you start. A firm with strong Content Signals but a failing Bot Access score has a technical fix, not a content problem. A firm with good Bot Access but low Structured Data needs schema implementation, not more blog posts.

    What Project Owners Ask AI Before They Issue an RFQ

    The procurement shift isn’t theoretical. Forrester’s 2026 Buyers’ Journey Survey of nearly 18,000 global business buyers found that 94% used generative AI during their most recent purchase process. G2’s 2026 study found that 51% of B2B buyers now start research in an AI chatbot, up from 29% a year earlier.

    In architecture and engineering, the prompts are specific. They reflect how owners, developers, and facilities managers actually think about project procurement.

    AI Prompt ExamplePlatformSearch IntentWhat It Reveals
    “Architecture firms specializing in K-12 school design in the Midwest”ChatGPTVendor shortlisting by typology + regionWhether your firm’s school projects are tagged and described in machine-readable format
    “Best structural engineering consultants for high-rise residential in Miami”PerplexitySpecialist capability searchWhether third-party citations (ENR, local press) connect back to a structured entity on your site
    “Compare MEP engineering firms with healthcare facility experience”GeminiCompetitive comparisonWhether AI can pull your project types, certifications, and team size from structured data
    “Sustainable architecture firms with Passive House certification”ChatGPTCredential-filtered searchWhether your certifications exist in schema markup or only as a line in a PDF brochure
    “Landscape architecture firms that have worked on urban resilience projects”PerplexityNiche specialism searchWhether your project narratives include semantic keywords AI can match to the query

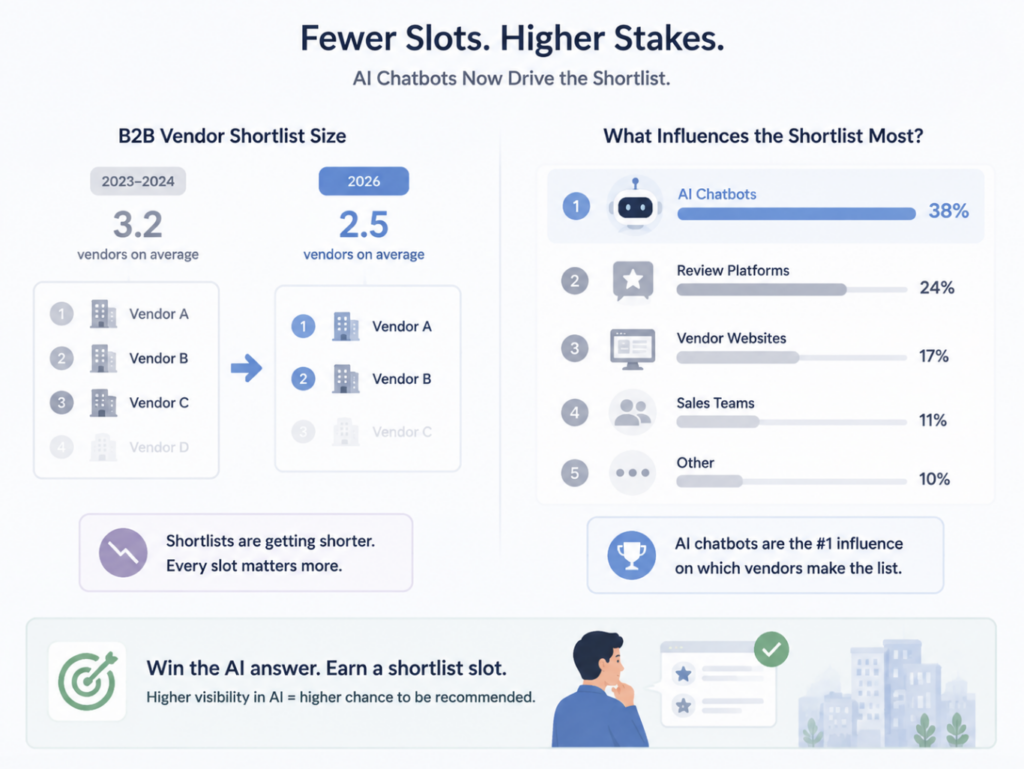
    The average B2B vendor shortlist has contracted from roughly 3.2 names to about 2.5 in 2026. Fewer slots, higher stakes. And AI chatbots are now the single biggest influence on which vendors make that list, ahead of review platforms, vendor websites, and sales teams.

    If your firm isn’t surfacing in these prompts, you’re not losing a click. You’re losing the chance to be considered at all.

    Where Architecture & Engineering Firms Consistently Lose GEO Points

    AEC firms face a set of AI visibility problems that are structurally different from SaaS companies or e-commerce brands. Three patterns show up repeatedly.

    The Portfolio Paradox

    Architecture is a visual discipline. Firms invest heavily in photography, renderings, and gallery layouts. The result is websites that impress human visitors and starve AI crawlers.

    AI crawlers parse HTML, text, metadata, and structure. They do not take a screenshot and give you credit for how the rendering looks. A project page with editorial photography but no project description, no location data, no typology tags, and no challenge-and-solution narrative is functionally invisible. The work exists. As far as AI is concerned, the page says almost nothing.

    This isn’t a design problem. It’s a translation problem. The firms that solve it don’t strip their visual identity. They add the text layer that AI needs alongside the visuals that clients expect.

    The Structured Data Gap

    Schema.org includes a dedicated Architect type. It’s not a workaround or generic classification. Combined with Service, CreativeWork, and Organization schemas, it creates a complete structured profile that AI platforms can read, categorize, and recommend.

    In practice, very few AEC firms implement it. Project specialisms, geographic reach, certifications, team credentials, and completed project types live in PDFs, image captions, or unstructured “About” text. None of that is machine-readable.

    When a procurement team asks AI for “an architect experienced in Victorian terrace extensions in Didsbury,” the model needs structured data to match that query to your firm. Without it, the model either skips you or guesses wrong.

    Unanchored Authority

    AEC firms earn authority through channels that AI models do recognize: features in ArchDaily, Dezeen, and Architectural Record, listings in AIA directories, awards from regional and national bodies, mentions in contractor and developer portfolios.

    But AI models treat these third-party signals as trust evidence only when the firm’s own site provides a structured entity that anchors them. Think of it as a hub-and-spoke model. The spokes (external mentions) need a hub (your site’s structured data) to connect to. Without the hub, the mentions float in the model’s training data without being reliably linked to your brand entity.

    That’s why a firm can have strong press coverage and still score below 40 on Visibility. The coverage exists. The connection to your brand doesn’t.

    From a One-Time Score to Continuous GEO Monitoring

    The GEO Score Checker gives you a snapshot. It tells you where your firm stands right now across four dimensions. That’s the starting point.

    But GEO signals change. AI platforms update their retrieval systems. Competitors add structured data. Your new project pages either strengthen or weaken your content signals. A single score can’t track that trajectory.

    CapabilityFree GEO Score CheckerTopify Platform
    Check frequencyOne-time snapshotContinuous monitoring
    Dimensions tracked4 GEO scoresFull GEO analytics + sentiment + citations
    Historical trendsNoneFull trend history with alerts
    Competitor benchmarkingNot includedReal-time competitor tracking
    Platform breakdownAggregatedPer-platform (ChatGPT, Perplexity, Gemini, AI Overviews)
    Optimization actionsDirectional guidanceSpecific, prioritized execution steps

    A single score tells you where you stand. Continuous monitoring tells you which direction you’re moving.

    Topify’s Comprehensive GEO Analytics tracks all four GEO dimensions over time, breaks down visibility by platform, and benchmarks you against competitors in your market. You can start a free trial with no credit card, or review pricing to find the plan that fits your firm’s size.

    Conclusion

    The AEC industry runs on reputation, relationships, and proven project experience. None of that has changed. What’s changed is where project owners start their research. When 94% of B2B buyers use AI in their procurement process, your firm’s digital signals need to be as strong as your built work.

    Run your GEO Score Checker now. It takes 60 seconds, costs nothing, and shows you exactly which of the four dimensions is holding your firm back from AI-generated shortlists.

    For deeper diagnostics, Topify’s AI Robots Checker can identify whether specific AI crawlers are being blocked by your robots.txt configuration. The Brand Authority Checker measures how AI models assess your firm’s overall authority signals, and the Knowledge Freshness Checker tests whether AI platforms have up-to-date information about your practice.

    Frequently Asked Questions

    Why do architecture firms with strong portfolios still score low on GEO? 

    Most architecture websites are built around high-resolution images with minimal supporting text. AI crawlers can’t interpret visual quality. They need descriptive project narratives, typology tags, and structured metadata to understand what a firm has built and where its expertise lies. A stunning gallery with no text context produces a near-zero Content Signals score.

    Does schema markup actually affect whether AI recommends my firm? 

    Yes. Schema.org provides a dedicated Architect type that lets AI platforms categorize your practice by specialism, project type, and service area. Without it, AI models have to infer your capabilities from unstructured text, and they frequently get it wrong or skip you entirely. Implementing schema is one of the fastest ways to improve your Structured Data score in the GEO Score Checker.

    How is GEO different from SEO for architecture firms? 

    SEO optimizes for Google’s link-based ranking algorithm. GEO optimizes for AI answer engines (ChatGPT, Perplexity, Gemini, Google AI Overviews) that assemble recommendations from structured data, entity signals, and corroborated third-party mentions. An AEC firm can rank well on Google for branded searches but remain invisible in AI-generated shortlists if its site lacks structured data and machine-readable project details.

    Can a one-time GEO score check really help, or do I need ongoing monitoring? 

    A one-time check identifies your weakest dimension and gives you a clear starting point. For firms actively improving their digital presence, Comprehensive GEO Analytics adds trend tracking, per-platform breakdowns, and competitor benchmarking so you can measure whether changes are actually moving your visibility scores.

    Read More:
  • GEO Score Checker for Manufacturing

    GEO Score Checker for Manufacturing

    A procurement engineer opens ChatGPT and types: “Best suppliers of food-grade stainless steel tubing with FDA and 3-A certification, under 12-week lead time.” Thirty seconds later, three manufacturers appear. Yours isn’t one of them. No lost RFQ lands in your CRM. No missed call shows up in your log. The deal simply happened somewhere your sales team couldn’t see.

    This isn’t a product quality problem. It’s a GEO problem. Your technical content, your certifications, your decades of capability data are sitting in places AI can’t reach. And right now, 68% of manufacturing procurement professionals use ChatGPT, Perplexity, or Google AI features during their vendor search process.

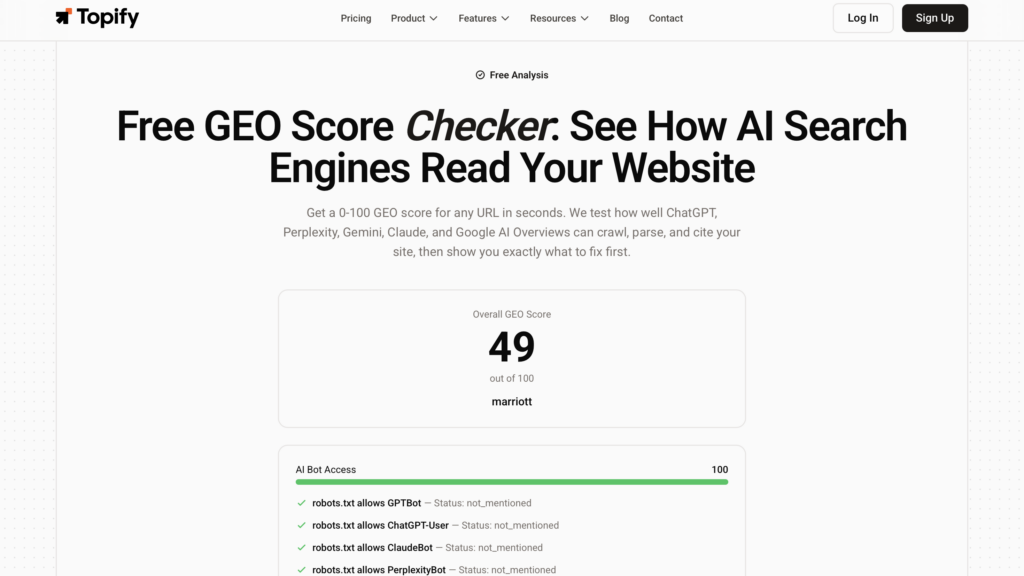
    The GEO Score Checker tells you exactly where your manufacturing brand stands in AI search, across four diagnostic dimensions, in under 60 seconds.

    ✅ Free ⚡ Results in 60 seconds 🔒 No signup required

    The Four Numbers That Tell You Why AI Skips Your Manufacturing Brand

    The GEO Score Checker returns a composite score from 0 to 100, built on four dimensions. Each one measures a different layer of your brand’s AI readiness. Here’s what they mean for a manufacturing company:

    Score DimensionWhat It MeasuresManufacturing Impact
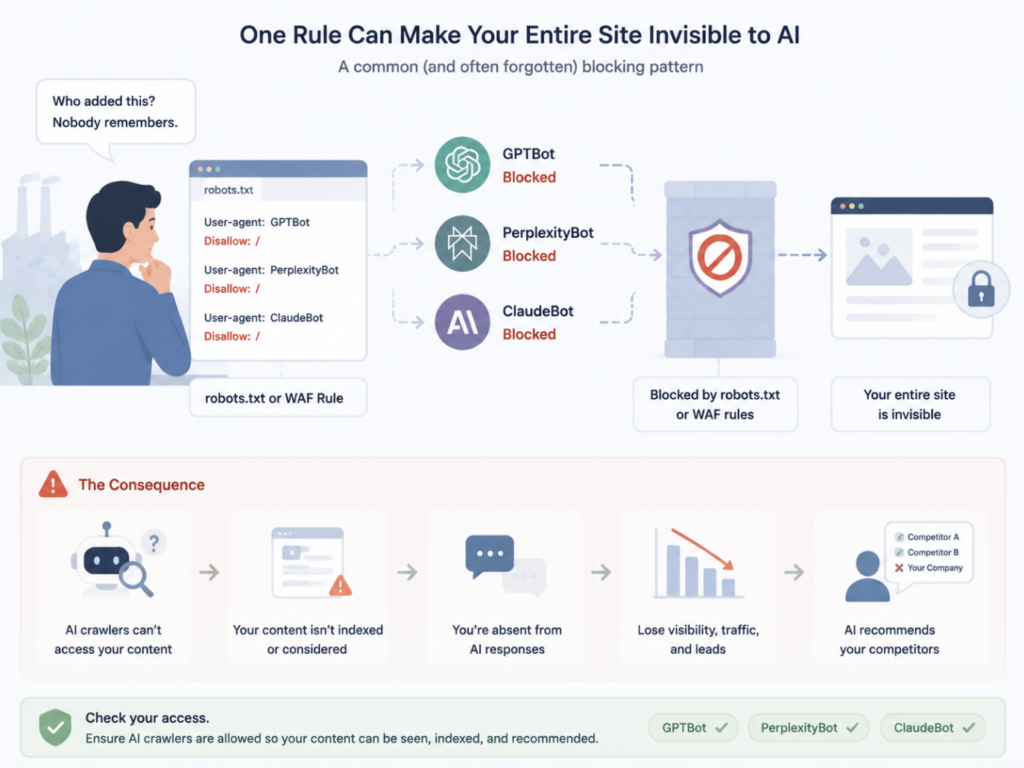
    Bot AccessWhether AI crawlers (GPTBot, ClaudeBot, PerplexityBot) can reach your siteMany industrial sites block these bots via robots.txt or WAF rules without realizing it. If crawlers can’t get in, your specs don’t exist to AI.
    Structured DataWhether your content carries machine-readable markup (JSON-LD, schema.org)Product pages without schema markup for part numbers, materials, certifications, and tolerances are invisible to AI’s structured understanding.
    Content SignalsWhether AI considers your content authoritative enough to citeTechnical depth, E-E-A-T signals, named-author expertise, and semantic relevance to procurement queries all factor in.
    Visibility ScoreHow often your brand actually appears in AI platform responsesMeasures real presence across ChatGPT, Perplexity, Gemini, and Google AI Overviews for queries relevant to your capabilities.

    A score below 40 means AI essentially doesn’t know your brand exists. Between 41 and 60, you’re visible but losing ground to competitors who’ve optimized. Above 80, AI is likely to recommend you when procurement teams ask.

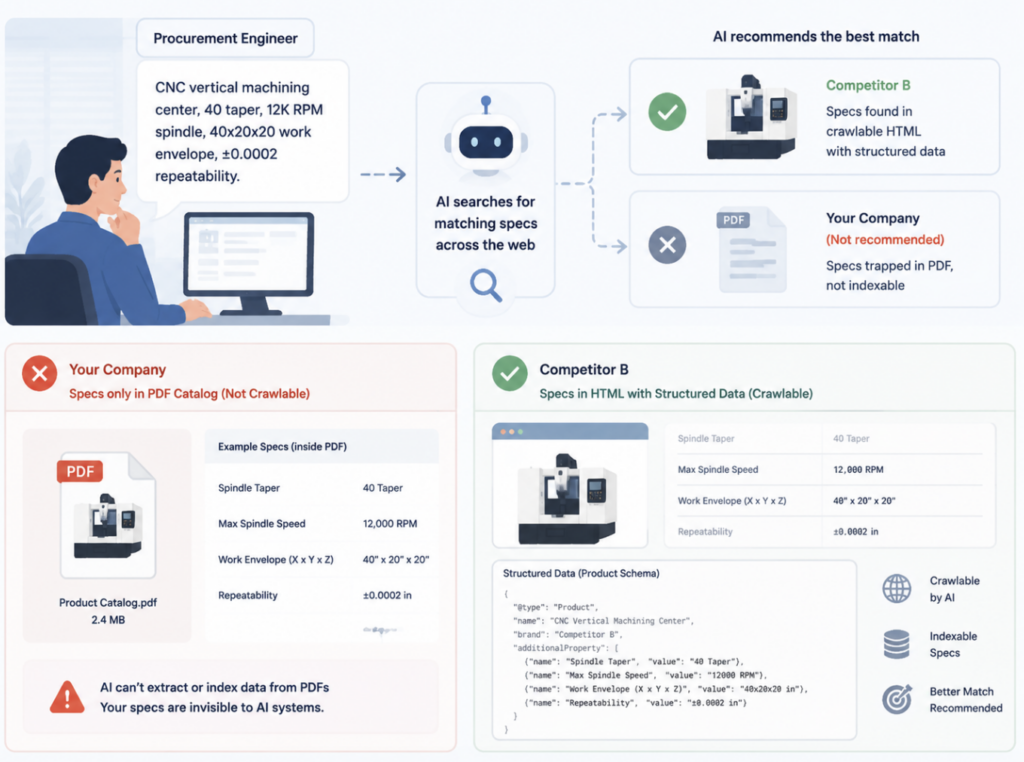
    Your Specs Are Locked in PDFs That AI Can’t Read

    This is the most common failure mode in manufacturing. You’ve invested years building detailed spec sheets, tolerance tables, material certificates, and capacity documents. The problem: they’re all in downloadable PDFs behind contact forms.

    PDFs don’t support schema markup. AI crawlers can’t reliably parse tables inside them. An audit of 500 industrial supplier websites found that only 12% had implemented basic AI optimization elements like structured data for specifications. That’s a Bot Access and Structured Data problem rolled into one.

    Your Product Pages Don’t Speak AI’s Language

    A procurement engineer asks for “CNC vertical machining center, 40 taper, 12K RPM spindle, 40x20x20 work envelope, ±0.0002 repeatability.” AI needs to match that query against structured, indexable data on your website. If your spindle speed, work envelope dimensions, and repeatability specs only exist as text inside a PDF catalog, AI will recommend the competitor whose specs live in crawlable HTML with Product schema markup.

    That gap between what you know and what AI can read is measurable. The Structured Data dimension of the GEO Score Checker catches it directly.

    You Show Up on Perplexity but Not ChatGPT

    Platform fragmentation is a hidden risk. Perplexity indexes the live web in real time, so it may surface your brand from a recent trade publication mention. ChatGPT relies more heavily on its training data and structured web content. A manufacturing brand can score well on one platform and be completely absent on another. The Visibility Score dimension breaks this down.

    How to run your check:

    1. Go to the GEO Score Checker
    2. Enter your brand name or domain
    3. Get your four-dimension score in 60 seconds
    4. Identify which dimension is pulling your overall score down

    What Procurement Teams Actually Ask AI Before They Send an RFQ

    The shift isn’t theoretical. Procurement engineers, plant managers, and sourcing leads are typing highly specific, technical queries into AI platforms and treating the responses as their initial shortlist. Forrester’s 2026 survey of 18,000 global business buyers confirmed that 94% used AI during their most recent purchase process.

    Here’s what those queries look like in manufacturing:

    AI Prompt ExamplePlatformSearch IntentWhat It Reveals
    “Best suppliers of precision CNC machining for aerospace aluminum parts with AS9100 certification”ChatGPTSupplier shortlisting with certification filterAI needs to match capability + certification + material in structured form
    “Compare injection molding manufacturers in the Midwest that handle short runs under 5,000 units”PerplexityRegional sourcing with volume filterBrands without crawlable capacity and location data won’t appear
    “Who makes custom hydraulic manifolds with lead times under 8 weeks?”GeminiUrgency-driven procurementAI prioritizes suppliers whose lead time data is explicitly stated on-page
    “Top sheet metal fabrication companies with ISO 9001 and ITAR compliance”ChatGPTCompliance-gated vendor searchCertification pages must be in crawlable HTML with Organization schema
    “Reliable suppliers of food-grade conveyor belts for pharmaceutical packaging lines”PerplexityApplication-specific sourcingAI matches industry application language, not just product categories
    “Industrial coating services for corrosion protection on offshore oil and gas components”GeminiEnvironment-specific capability searchBrands that publish application case studies with measurable results get cited

    The average B2B shortlist has shrunk to roughly 2.5 vendors, down from 3.2 a few years earlier. If your brand isn’t in that first AI-generated answer, the procurement engineer may never know you exist.

    That’s the core risk. You don’t lose a deal. You never enter the process.

    Where Manufacturing Brands Consistently Lose GEO Points

    Manufacturing has a unique AI visibility problem. Most industrial companies sit on deep technical expertise, but the way that expertise is packaged online actively prevents AI from finding it. Three patterns show up repeatedly.

    The PDF Trap: Rich Content in a Format AI Can’t Index

    A manufacturer’s most valuable content, detailed spec sheets, tolerance charts, material certifications, test reports, often lives exclusively in downloadable PDFs. These documents are comprehensive and accurate. They’re also functionally invisible to AI.

    PDFs can’t carry schema markup. They don’t build internal linking authority. Image-based PDF scans of older documents are completely unreadable to both Google and AI crawlers. The result: a distributor page with an HTML specification table will get cited over your original manufacturer documentation every time. A low Bot Access score on the GEO Score Checker often traces back to this exact issue.

    The Terminology Gap: Engineering Shorthand vs. AI Comprehension

    Your industry speaks its own language. ASTM standards, alloy grades, tolerance classes, surface finish callouts like “Ra 0.8.” But AI models trained on general web content don’t always connect “Ra 0.8 surface finish” to “suitable for hydraulic sealing applications.”

    This doesn’t mean dumbing down your content. It means bridging the gap. The Content Signals dimension of the GEO Score Checker evaluates whether your content carries enough semantic context for AI to match it against the natural-language queries procurement teams actually type.

    The Accidental Block: WAF and Robots.txt Misconfiguration

    Here’s a pattern that shows up in nearly every manufacturing site audit. Somewhere in the robots.txt file or Cloudflare WAF settings, a rule blocks GPTBot, PerplexityBot, or ClaudeBot. Nobody on the current team remembers adding it. Nobody realizes the consequence: your entire domain is invisible to one or more AI platforms.

    Topify‘s AI Robots Checker can identify these blocks instantly. But the GEO Score Checker’s Bot Access dimension is your first signal that something is wrong at the infrastructure level.

    From a One-Time Score to Continuous GEO Monitoring

    Running the GEO Score Checker gives you a snapshot of where your manufacturing brand stands today. That’s the right starting point. But AI visibility isn’t static. Crawl policies change. Competitors publish new structured content. AI models update their training data and indexing behavior.

    A single score tells you where you stand. Continuous monitoring tells you which direction you’re moving.

    Topify‘s Comprehensive GEO Analytics platform picks up where the free checker leaves off:

    CapabilityFree GEO Score CheckerTopify Platform
    Check frequencyOne-time snapshotContinuous monitoring
    Dimensions tracked4 GEO scoresFull GEO analytics + sentiment + citations
    Historical trendsNoneFull trend history with alerts
    Competitor benchmarkingNot includedReal-time competitor tracking
    Platform breakdownAggregatedPer-platform (ChatGPT, Perplexity, Gemini, AI Overviews)
    Optimization actionsDirectional guidanceSpecific, prioritized execution steps

    For manufacturing brands tracking multiple product lines, certifications, and regional capabilities, per-platform visibility data matters. A brand might score well in Perplexity’s live-web results but remain absent from ChatGPT’s synthesized answers, and only continuous tracking catches that divergence over time.

    You can explore pricing or start a free trial with no credit card required. All plans cover ChatGPT, Perplexity, Gemini, and Google AI Overviews.

    Conclusion

    In manufacturing, the first stage of vendor discovery has quietly moved off the search engine and into a conversation with an AI model. The brands that show up in those conversations aren’t necessarily the most capable. They’re the ones whose capabilities are structured, crawlable, and machine-readable.

    The gap between what you can do and what AI can see is the gap the GEO Score Checker is built to measure. Run your manufacturing brand through it now and find out which of the four dimensions is costing you procurement visibility.

    If your Bot Access score comes back low, the AI Robots Checker can pinpoint exactly which crawlers you’re blocking. For a deeper look at how current AI models perceive your brand’s authority, the Brand Authority Checker adds another layer of diagnosis. And the Knowledge Freshness Checker tells you whether the information AI has about your brand is up to date or months behind.

    Frequently Asked Questions

    Why do manufacturing websites score lower on GEO than other industries?

    Most manufacturing sites were built as digital brochures. Critical specifications, certifications, and capability data live inside downloadable PDFs or behind contact forms, making them inaccessible to AI crawlers. The GEO Score Checkerquantifies this gap across all four dimensions so you can see exactly where AI loses access to your content.

    Does adding schema markup to product pages actually help AI recommend my brand?

    Yes. AI platforms rely on structured data to match technical queries (materials, tolerances, certifications, capacities) to specific suppliers. Without Product and Organization schema in crawlable HTML, AI has no structured way to verify that your brand meets a buyer’s spec requirements. The Structured Data dimension measures this directly.

    How is GEO different from traditional SEO for manufacturing companies?

    Traditional SEO optimizes for ranking in a list of search results. GEO optimizes for being named in an AI-generated answer. In manufacturing, that distinction matters because procurement engineers increasingly ask AI for supplier shortlists rather than scrolling through ten blue links. A high Google ranking doesn’t guarantee AI citation, and vice versa.

    Can I track whether my GEO score improves after making changes?

    The free GEO Score Checker provides a point-in-time snapshot you can re-run manually. For ongoing tracking with historical trend data, competitor benchmarks, and per-platform breakdowns, Comprehensive GEO Analytics monitors your scores continuously and alerts you to changes.

    Read more:

  • GEO Score Checker for Travel and Hospitality

    GEO Score Checker for Travel and Hospitality

    A traveler opens ChatGPT and types: “Best boutique hotels in Barcelona near the metro with rooftop terrace.” The model responds in seconds with five specific recommendations, complete with neighborhood context and price ranges. Your property checks every box. It doesn’t appear.

    This isn’t a review problem or a pricing problem. It’s a visibility problem at the technical layer where AI decides which brands exist and which ones don’t. Topify’s research across hospitality brands consistently shows that the gap between a hotel’s actual guest experience and its AI discoverability is wider than in almost any other industry. A property with thousands of five-star reviews can score below 30 on AI readiness simply because the signals AI models need to find it were never configured.

    The GEO Score Checker measures exactly where those signal failures happen, across four dimensions that determine whether AI trip planners can see, understand, trust, and recommend your property.

    ✅ Free ⚡ Results in 60 seconds 🔒 No signup required

    The Four Numbers That Tell You Why AI Skips Your Hotel

    AI trip planners don’t browse your website the way a guest does. They parse technical signals, structured data, authority markers, and cross-platform citation patterns. The GEO Score Checker translates those signals into four scores, each tied to a specific layer of AI discoverability.

    Score DimensionWhat It MeasuresTravel & Hospitality Impact
    Bot AccessWhether AI crawlers can reach your websiteHotels using pre-2020 robots.txt templates often block GPTBot and ClaudeBot without knowing it, making the property invisible to ChatGPT and Claude trip planning
    Structured DataWhether AI can parse your property attributesWithout Hotel-specific schema (room types, amenities, star rating, geo coordinates), AI can’t match your property to queries like “family-friendly hotel near Central Park with pool”
    Content SignalsWhether AI considers your content authoritativeGuest reviews, editorial mentions in travel publications, and destination guide citations build the trust signals AI models weigh before recommending a property
    Visibility ScoreHow often your brand appears across AI platformsA hotel might surface in Perplexity but be absent from ChatGPT and Gemini, creating a fragmented presence that undercuts booking potential

    Here’s how each dimension plays out in real hospitality scenarios.

    Your Website Says “No Guests Allowed” to AI Crawlers

    A four-star resort in Bali runs a modern, visually rich website built on a JavaScript-heavy framework. The site loads beautifully for human visitors. But the robots.txt file, copied from a developer template years ago, blocks GPTBot, ClaudeBot, and PerplexityBot. When a traveler asks any AI assistant for Bali resort recommendations, this property simply doesn’t exist in the answer pool.

    A low Bot Access score in hospitality often traces back to this exact scenario. The fix is straightforward, but you can’t fix what you don’t measure.

    AI Can’t Tell a Boutique Hotel from a Bed-and-Breakfast

    Many hotel websites implement only generic LocalBusiness schema rather than the specific Hotel or LodgingBusiness type. That means AI models can see a business name and address but can’t parse room types, amenity lists, star ratings, check-in times, or price ranges. When a traveler asks for “a quiet hotel in Kyoto with onsen and garden view under $300,” the model needs structured property data to make that match. Hotels without it get skipped in favor of those whose schema speaks the model’s language.

    A Structured Data score below 40 typically means the property’s website is treating AI the way a brochure treats a reader: lots of atmosphere, very little parseable fact.

    Strong Reviews, Weak Authority Signals

    A boutique hotel in Lisbon has 2,000 reviews averaging 4.8 stars on Google. But its website contains no FAQ content, no destination guides, no editorial coverage mentions, and no third-party citations beyond OTA listings. The Content Signals score reflects this gap. AI models don’t just count reviews. They look for corroborating evidence across independent sources: travel blog mentions, media features, destination authority content, and structured FAQ responses that match how travelers actually phrase questions.

    One feature in a respected travel publication creates more AI visibility signal than dozens of website updates.

    Run a Check in 60 Seconds

    1. Go to the GEO Score Checker
    2. Enter your hotel brand name or domain
    3. Get four dimension scores in under a minute
    4. Compare dimensions to identify your weakest signal layer

    The score tells you where AI trip planners lose sight of your property and which layer needs attention first.

    What Travelers Actually Ask AI Before They Book

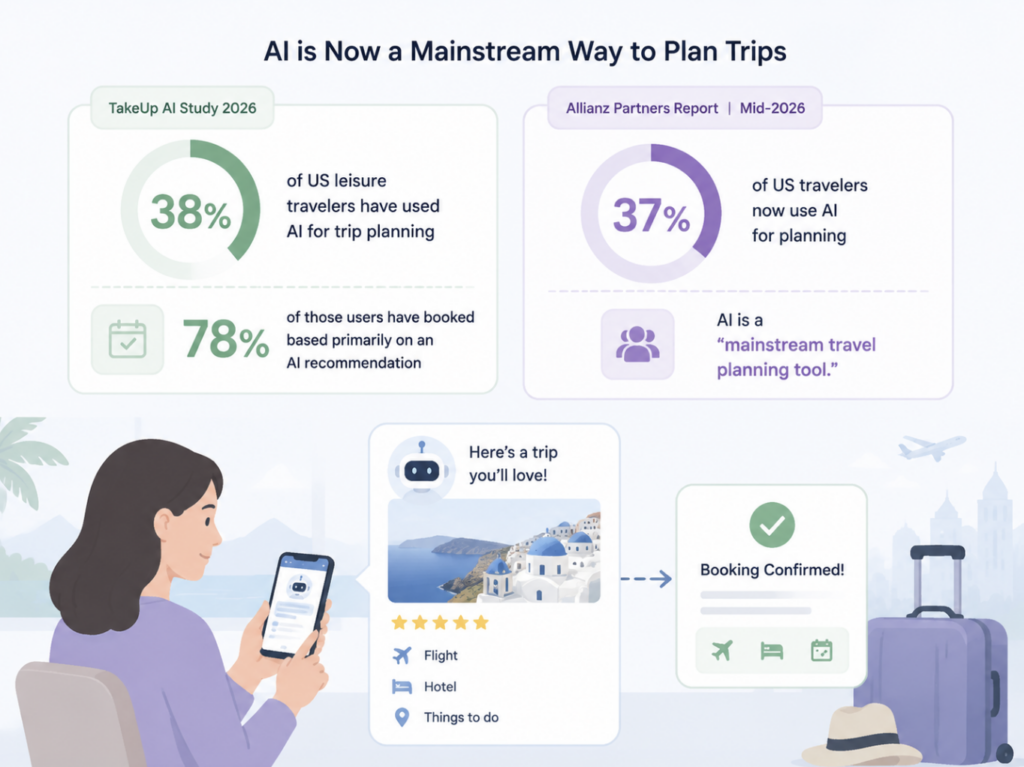
    The shift in traveler behavior is measurable. A 2026 TakeUp AI study found that 38% of surveyed US leisure travelers have used AI for trip planning, and 78% of those users have booked based primarily on an AI recommendation. Allianz Partners reported in mid-2026 that 37% of US travelers now use AI for planning, calling it a “mainstream travel planning tool.”

    These travelers aren’t typing keywords. They’re describing experiences.

    AI Prompt ExamplePlatformSearch IntentWhat It Reveals
    “Plan a 5-day family trip to Orlando with hotel near theme parks under $200/night”ChatGPTFull itinerary with budget-constrained lodgingAI must match property attributes (location, price, family amenities) from structured data
    “Best luxury resorts in the Maldives with overwater villas and all-inclusive packages”PerplexityHigh-end comparison shoppingAI pulls from editorial sources, schema-enriched property pages, and review aggregators
    “Recommend a quiet hotel in Tokyo for a solo business traveler near Shinjuku station”GeminiHyper-local, persona-specific matchWithout geo coordinates and amenity-level schema, properties outside the AI’s data set get excluded
    “Where should I stay in Lisbon for a romantic anniversary weekend?”ChatGPTExperience-driven, emotionally framedAI leans on editorial coverage, curated lists, and sentiment-rich review data to generate recommendations
    “Compare boutique hotels vs Airbnb in Tulum for a group of 6”PerplexityFormat comparison with group sizingHotels without clear occupancy data and group-friendly amenity schema lose to vacation rental platforms with better structured listings

    The pattern across these prompts is consistent. Travelers give AI a complex, multi-attribute query. The model assembles an answer from whichever brands have the structured, authoritative, crawlable data to fill it. Brands that don’t surface in these answers lose the booking opportunity before the traveler even knows they exist.

    Three GEO Blind Spots That Cost Hotels Direct Bookings

    Blind Spot 1: The Robots.txt Time Capsule

    OpenAI operates three separate crawlers: GPTBot (training data), OAI-SearchBot (real-time ChatGPT search), and ChatGPT-User (user-initiated browsing). Anthropic runs ClaudeBot and Claude-SearchBot. Perplexity has PerplexityBot. Google uses Google-Extended for Gemini training, and Googlebot itself feeds AI Overviews.

    Most hotel websites were last audited for crawler access before any of these bots existed. A RevPARGenius study found that 94.3% of hotel websites are invisible to AI search. A significant portion of those have robots.txt files that inadvertently block AI crawlers, sometimes because a developer template from 2018 disallowed everything except Googlebot and Bingbot.

    Blocking real-time retrieval crawlers is, in 2026, self-imposed invisibility.

    Blind Spot 2: Schema That Stops at the Lobby

    AI models process hotel data through a hierarchy: Thing > Place > LocalBusiness > LodgingBusiness > Hotel. Each level adds specificity. A property marked only as LocalBusiness gives AI a name and an address. A property marked as Hotel with full schema gives AI room types, amenity arrays, star ratings, check-in/check-out times, price ranges, aggregate ratings, and geo coordinates.

    Research from the hospitality GEO space shows that 79% of hotel links in Google AI Mode point to Google Business Profile, and GBP data is directly enriched by Schema.org markup from hotel websites. Hotels with incomplete schema have weaker entity signals and get bypassed by AI models assembling travel recommendations.

    The gap between LocalBusiness and Hotel schema is the gap between being a pin on a map and being a bookable recommendation.

    Blind Spot 3: The OTA Proxy Problem

    Here’s the paradox. Hotels invest heavily in OTA listings: Booking.com, Expedia, TripAdvisor. Those OTAs implement rich structured data at scale. AI models love that data. But when Lighthouse’s 2026 study showed that AI has become a primary channel for hotel discovery, it also revealed a distribution shift. Booking.com and Expedia are already embedded in ChatGPT’s app ecosystem. Radisson and Motel 6 launched dedicated ChatGPT apps in July 2026.

    For hotels without their own AI-ready infrastructure, the OTA becomes the proxy. AI recommends the property, but routes the booking through the OTA. The hotel pays commission on a guest it should have captured directly. The brand gets mentioned, but the direct booking link never appears.

    A strong Visibility Score on the GEO Score Checker doesn’t just mean your brand name shows up in AI answers. It means the AI links to your domain, not an intermediary’s.

    Where Low Scores Typically Trace Back

    Hospitality ScenarioGEO Score SignalCommon Root CauseAction Direction
    Property never appears in ChatGPT travel queriesBot Access: below 30robots.txt blocks GPTBot, OAI-SearchBot, or Bingbot (ChatGPT’s search substrate)Audit and update crawler permissions
    AI recommends competitors with fewer reviewsStructured Data: below 40Website uses LocalBusiness schema instead of Hotel; missing amenity, room, and rating markupImplement full Hotel schema with JSON-LD
    Brand appears on Perplexity but not ChatGPT or GeminiVisibility Score: uneven across platformsInconsistent entity data across Google Business Profile, OTA listings, and websiteAlign NAP data and brand entity across all surfaces
    AI links to OTA listing instead of hotel websiteContent Signals: below 50Hotel website lacks FAQ content, destination guides, and editorial mentions that build direct-link authorityPublish authoritative, crawlable content on the hotel domain

    From a One-Time Score to Continuous GEO Monitoring

    A GEO Score Checker result tells you where your hotel stands right now. But AI visibility in travel isn’t static. Models update their training data, new competitors launch schema-optimized websites, OTA algorithms shift, and seasonal travel patterns change which prompts travelers use. A property that scores well in January might drop by summer if a competitor publishes a better-structured destination guide or earns a feature in a major travel publication.

    That’s where the snapshot ends and continuous tracking begins.

    CapabilityFree GEO Score CheckerTopify Platform
    Check frequencyOne-time snapshotContinuous monitoring
    Dimensions tracked4 GEO scoresFull GEO analytics + sentiment + citations
    Historical trendsNoneFull trend history with alerts
    Competitor benchmarkingNot includedReal-time competitor tracking
    Platform breakdownAggregatedPer-platform (ChatGPT, Perplexity, Gemini, AI Overviews)
    Optimization actionsDirectional guidanceSpecific, prioritized execution steps

    Comprehensive GEO Analytics tracks all four GEO dimensions over time, across every major AI platform, with competitor benchmarking and actionable optimization priorities. For hospitality brands managing visibility across multiple properties or destinations, the platform turns a one-time diagnosis into ongoing competitive intelligence.

    You can start a free trial with no credit card required, or review pricing to find the tier that fits your portfolio.

    Conclusion

    AI trip planning has moved from novelty to mainstream. Nearly four in ten US travelers now start with an AI assistant, and the majority of those who do book based on what the AI recommends. The hotels that appear in those answers aren’t necessarily the best properties. They’re the ones whose technical signals, structured data, content authority, and cross-platform visibility are configured for AI discoverability.

    Start with a baseline. Run your property through the GEO Score Checker and see which of the four dimensions is holding you back. From there, you can fix crawler access issues with Topify’s AI Robots Checker, verify whether AI models have current information about your brand using the Knowledge Freshness Checker, and get a cross-platform snapshot with the AI Visibility Report.

    Frequently Asked Questions

    Why does my hotel have thousands of great reviews but still score low on the GEO Score Checker? 

    Reviews contribute to Content Signals, but they’re only one input. AI models also weigh structured schema markup, crawler accessibility, editorial third-party mentions, and entity consistency across platforms. A property with excellent reviews but blocked AI crawlers or missing Hotel schema will score low because the model can’t access or parse the evidence it needs to recommend you.

    Can OTA listings substitute for optimizing my own hotel website for AI visibility? 

    OTA listings help, but they create a dependency. AI models often pull structured data from OTAs and link to the OTA booking page rather than your direct site. That means you pay commission on bookings AI could have sent directly. Optimizing your own domain with proper Hotel schema, open crawler access, and authoritative content builds direct-link equity that OTAs can’t replace.

    How is GEO different from traditional hotel SEO? 

    Traditional SEO optimizes for keyword rankings on Google’s search results page. GEO optimizes for inclusion in AI-generated answers across ChatGPT, Perplexity, Gemini, and Google AI Overviews. The ranking factors overlap (structured data, authority signals) but GEO adds crawler permissions for AI bots, cross-platform visibility tracking, and content structured for conversational query matching. The GEO Score Checker measures these AI-specific dimensions directly.

    Do large hotel chains have an inherent advantage in AI visibility over independent properties? 

    Chains benefit from higher baseline brand recognition in AI training data, but the technical signals that drive real-time AI recommendations are property-level: schema markup, crawler access, review sentiment, and local editorial mentions. An independent hotel with properly implemented Hotel schema and strong destination authority content can outperform a chain property that relies solely on brand recognition without maintaining its technical AI infrastructure.

    Read More:
  • GEO Score Checker for Retail and E-Commerce: Why AI Shopping Assistants Recommend Your Competitors

    GEO Score Checker for Retail and E-Commerce: Why AI Shopping Assistants Recommend Your Competitors

    A shopper opens ChatGPT and types: “best wireless earbuds under $100 for working out.” Three brands come back. Yours isn’t one of them. Your product has 4.7 stars, competitive pricing, and a page-one Google ranking. None of that mattered. The AI built its recommendation list from a completely different set of signals, and your store didn’t send the right ones.

    This isn’t a product problem. It’s a GEO problem: your website’s technical signals aren’t structured for how AI systems discover and recommend products. The GEO Score Checker measures exactly where that breakdown happens, scoring your site across four dimensions that determine whether AI shopping assistants include you or skip you.

    ✅ Free ⚡ Results in 60 seconds 🔒 No signup required

    The Four Numbers That Decide Whether AI Recommends Your Products

    AI shopping platforms don’t browse your store the way a human does. They evaluate four distinct signal layers before deciding whether to surface your brand in a recommendation. The GEO Score Checker translates those layers into scores you can act on.

    Score DimensionWhat It MeasuresRetail / E-Commerce Impact
    Bot AccessWhether AI crawlers can reach your product pagesIf GPTBot or PerplexityBot is blocked in your robots.txt, your entire catalog is invisible to ChatGPT Shopping and Perplexity Buy
    Structured DataWhether AI can parse your product attributesIncomplete Product schema (missing GTIN, return policy, shipping details) means AI can’t confidently compare your products against competitors
    Content SignalsWhether AI considers your content authoritativeThin product descriptions, missing buying guides, and absent FAQ content reduce your authority score for purchase-intent queries
    Visibility ScoreHow often your brand appears in AI answersMeasures actual presence across ChatGPT, Perplexity, Gemini, and Google AI Overviews for relevant shopping queries

    Each dimension scores 0-100. A score below 40 in any single dimension typically means AI platforms will skip your products for that category of shopping query entirely.

    When AI Crawlers Can’t Reach Your Product Pages

    A mid-size apparel brand ranks in Google’s top three for “best linen shirts for summer.” But their Shopify theme’s default robots.txt blocks OAI-SearchBot. Result: zero presence in ChatGPT Shopping, regardless of how strong their SEO is. The Bot Access score catches this instantly.

    For e-commerce stores, blocking an AI crawler isn’t a minor technical issue. It’s a binary switch. Either your product pages are in the AI’s index, or they don’t exist.

    When Your Product Data Doesn’t Speak AI’s Language

    AI shopping assistants don’t just read your product title and price. They parse structured data fields: brand object, GTIN, availability status, return policy, shipping details, aggregate ratings. Research from 2026 shows that 65% of pages cited by AI systems include structured data, and AI parsing success drops from 94% to 23% when schema is rendered through client-side JavaScript instead of static HTML.

    Most e-commerce platforms ship with incomplete Product schema out of the box. The Structured Data score flags exactly which fields are missing or misconfigured.

    When Strong Reviews Don’t Translate to AI Authority

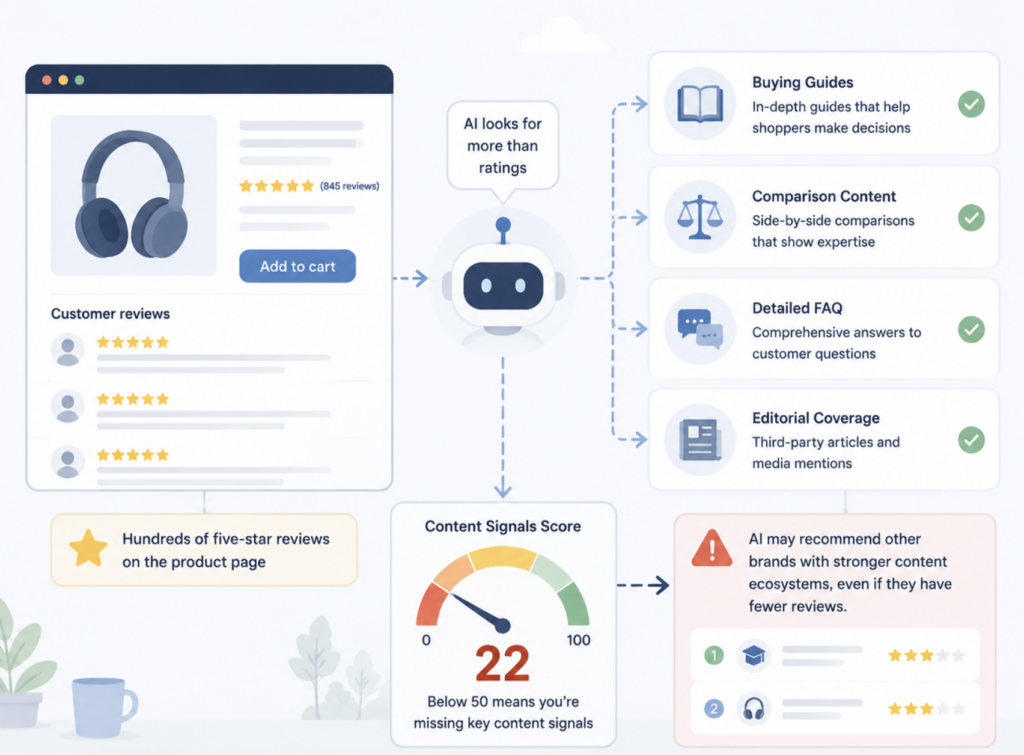
    Your product page has hundreds of five-star reviews. But AI systems weigh more than just aggregate ratings. They look for buying guides, comparison content, detailed FAQ sections, and editorial coverage that positions your brand as an authority in its category. A Content Signals score below 50 often means your store relies on product pages alone, without the surrounding content ecosystem that AI uses to validate recommendations.

    Your product page has hundreds of five-star reviews. But AI systems weigh more than just aggregate ratings. They look for buying guides, comparison content, detailed FAQ sections, and editorial coverage that positions your brand as an authority in its category. A Content Signals score below 50 often means your store relies on product pages alone, without the surrounding content ecosystem that AI uses to validate recommendations.

    Here’s how to run your check:

    1. Go to the GEO Score Checker
    2. Enter your brand name or domain
    3. Get your four-dimension score breakdown in 60 seconds
    4. Identify your weakest dimension and prioritize fixes there first

    What Shoppers Ask AI Before They Add to Cart

    The way consumers research products has fundamentally shifted. Recent data from MarTech shows that 46% of AI users now start purchase research on a standalone AI platform, up from 25% in 2024. Traditional search as a starting point dropped from 43% to 24% over the same period.

    That shift means your brand’s consideration set is being formed inside AI conversations, not on search results pages.

    AI Prompt ExamplePlatformSearch IntentWhat It Reveals
    “Best running shoes for flat feet under $150”ChatGPTProduct comparison with constraintsAI builds a shortlist of 3-5 brands. Missing brands lose the sale before any website visit.
    “Compare Dyson V15 vs Shark Stratos for pet hair”PerplexityHead-to-head evaluationAI cites product specs from structured data. Incomplete schema means your product gets a weaker comparison card.
    “What’s the best moisturizer for sensitive skin”GeminiCategory discoveryAI pulls from buying guides and editorial reviews. Brands without supporting content get skipped.
    “Affordable standing desk with good reviews”ChatGPTBudget-conscious purchaseAI filters by price, ratings, and availability. Missing Offer schema fields disqualify products from the recommendation.
    “Is the Stanley tumbler worth it or are there better alternatives”PerplexityBrand-specific alternative searchAI compares your product against a named competitor. Low Visibility Score means you won’t show up as the alternative.

    These aren’t hypothetical queries. Product.ai’s 2026 Trust in AI Commerce Report found that 43% of U.S. online shoppers used AI for product research in the past 90 days.

    The brands that AI recommends in these conversations capture buyers before a single ad impression runs. The brands it skips never entered the consideration set.

    Three Blind Spots That Cost E-Commerce Brands AI Shelf Space

    Retail brands often assume that strong Google rankings translate to AI visibility. They don’t. AI shopping assistants evaluate products through a different lens, and three specific technical gaps account for most of the missed recommendations.

    Incomplete Product Schema Erodes AI Confidence

    AI shopping platforms need structured data fields that most e-commerce stores don’t provide. Name, image, and price aren’t enough anymore. In 2026, AI systems expect a complete Product schema including brand as a nested object, GTIN or MPN, availability with exact ISO values, return policy, shipping details, and aggregate ratings with review counts.

    When fields are missing, AI doesn’t display an error. It just recommends a competitor whose data is complete. Your Structured Data score quantifies this gap.

    Platform Fragmentation Creates Invisible Revenue Leaks

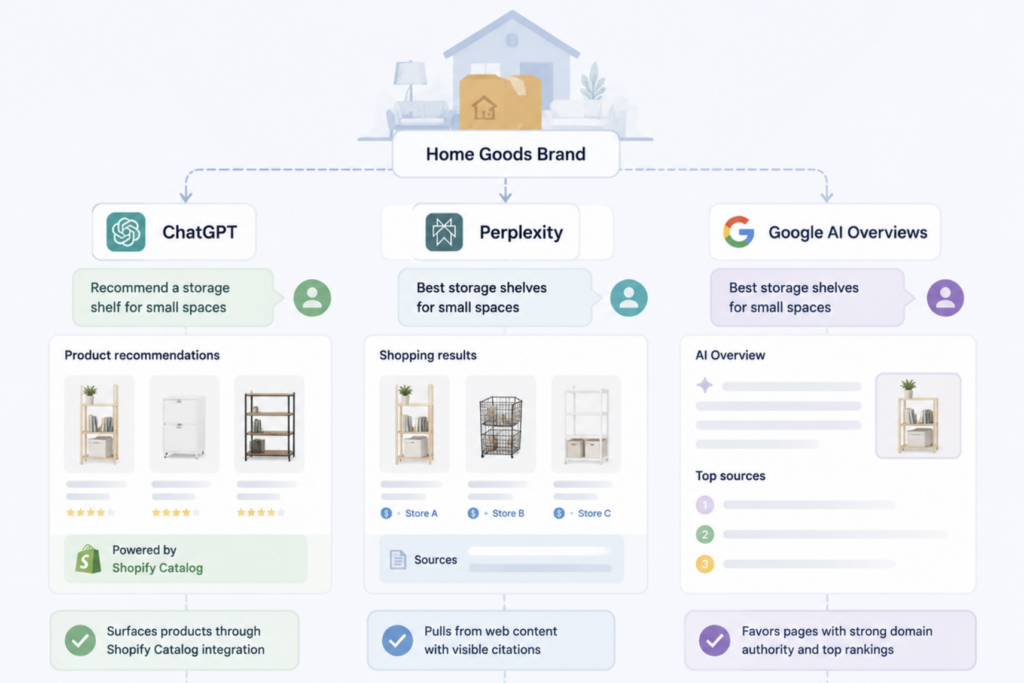
    A home goods brand might appear consistently in Perplexity Shopping results but be completely absent from ChatGPT’s product recommendations. Each AI platform uses different data sources, different ranking logic, and different merchant integrations. ChatGPT surfaces products through Shopify Catalog integration. Perplexity pulls from web content with visible citations. Google AI Overviews favor pages with strong domain authority and existing top-five rankings.

    Being visible on one platform doesn’t mean you’re visible on all of them. And since AI-referred shoppers convert at rates 4-5x higher than traditional organic visitors, each platform gap represents a measurable revenue loss.

    JavaScript-Rendered Schema Is Invisible to AI Crawlers

    Here’s the thing: AI crawlers don’t execute JavaScript. If your product schema loads through client-side rendering, AI systems never parse it. Static HTML with server-side rendered JSON-LD achieves a 94% AI parsing success rate. JavaScript-rendered schema drops to 23%. For e-commerce brands running headless storefronts or heavy client-side frameworks, this single technical issue can make an entire product catalog invisible to AI discovery.

    The Bot Access and Structured Data dimensions of your GEO score together reveal whether this is happening to your store.

    From a One-Time Score to Continuous AI Shelf Monitoring

    Running the GEO Score Checker gives you a clear snapshot of where your store stands right now. But AI shopping algorithms update continuously. Your competitors are optimizing their schema, publishing buying guides, and unblocking AI crawlers. A score from today doesn’t tell you whether you’re gaining or losing ground next month.

    That’s where Topify’s platform picks up. Comprehensive GEO Analytics tracks all four GEO dimensions over time, across every major AI shopping platform.

    CapabilityFree GEO Score CheckerTopify Platform
    Check frequencyOne-time snapshotContinuous monitoring
    Dimensions tracked4 GEO scoresFull GEO analytics + sentiment + citations
    Historical trendsNoneFull trend history with alerts
    Competitor benchmarkingNot includedReal-time competitor tracking
    Platform breakdownAggregatedPer-platform (ChatGPT, Perplexity, Gemini, AI Overviews)
    Optimization actionsDirectional guidanceSpecific, prioritized execution steps

    A single score tells you where you stand. Continuous monitoring tells you which direction you’re moving, and whether your competitors are pulling ahead.

    You can start a free trial with no credit card required, or check pricing to find the plan that fits your catalog size.

    Conclusion

    AI shopping assistants are forming consumer shortlists before your website gets a single visit. If your product pages can’t be crawled, your schema can’t be parsed, or your content doesn’t signal authority, you won’t make the list. That’s not a branding failure. It’s a technical signal gap you can measure and fix.

    Start with your GEO Score Checker results. Find your weakest dimension. Fix the technical foundation first (bot access, structured data), then build the content signals that earn AI trust.

    For deeper diagnostics, the AI Robots Checker helps you audit exactly which AI crawlers your robots.txt is blocking, and the Knowledge Freshness Checker shows whether AI models are working with outdated information about your brand. If you want a cross-platform snapshot before committing to ongoing monitoring, the AI Visibility Report gives you a quick read on where your brand currently appears.

    Frequently Asked Questions

    Why does my product rank on Google but not appear in AI shopping recommendations? 

    Google rankings are based on backlinks, domain authority, and keyword relevance. AI shopping assistants use a different signal set: structured product schema, AI crawler access, content authority, and cross-platform citation patterns. A page-one Google ranking doesn’t automatically translate to AI visibility. The GEO Score Checker measures the four dimensions AI actually evaluates.

    What’s the most common reason e-commerce brands score low on GEO? 

    Incomplete Product schema is the single most frequent issue. Most e-commerce platforms ship with basic schema that covers name, image, and price, but omits fields AI systems now expect: GTIN, return policy, shipping details, and properly nested brand objects. Fixing schema alone often produces the fastest improvement in AI recommendation rates.

    Does GEO replace SEO for online stores? 

    No. GEO and SEO target different discovery channels, and both drive revenue. SEO earns organic Google rankings. GEO earns inclusion in AI-generated product recommendations on ChatGPT, Perplexity, Gemini, and Google AI Overviews. Strong SEO builds the domain authority that supports GEO, so the two reinforce each other.

    How often should I check my e-commerce GEO score? 

    Run the free checker after any major site change: platform migration, theme update, robots.txt edit, or schema overhaul. For ongoing tracking across product launches and seasonal campaigns, Comprehensive GEO Analytics provides continuous monitoring with alerts when scores shift.

    Read More:
  • GEO Score Checker for Public Sector: Why Citizens Can’t Find Your Services in AI Search

    GEO Score Checker for Public Sector: Why Citizens Can’t Find Your Services in AI Search

    A resident types “Am I eligible for rental assistance in my county?” into ChatGPT. The answer cites a nonprofit blog, a news article from 2023, and a Reddit thread. The actual program page, the one with current eligibility criteria, application deadlines, and a working portal, doesn’t appear anywhere in the response.

    That’s not a content quality problem. It’s a technical visibility gap between public service websites and the AI platforms citizens are turning to for answers. And it’s diagnosable.

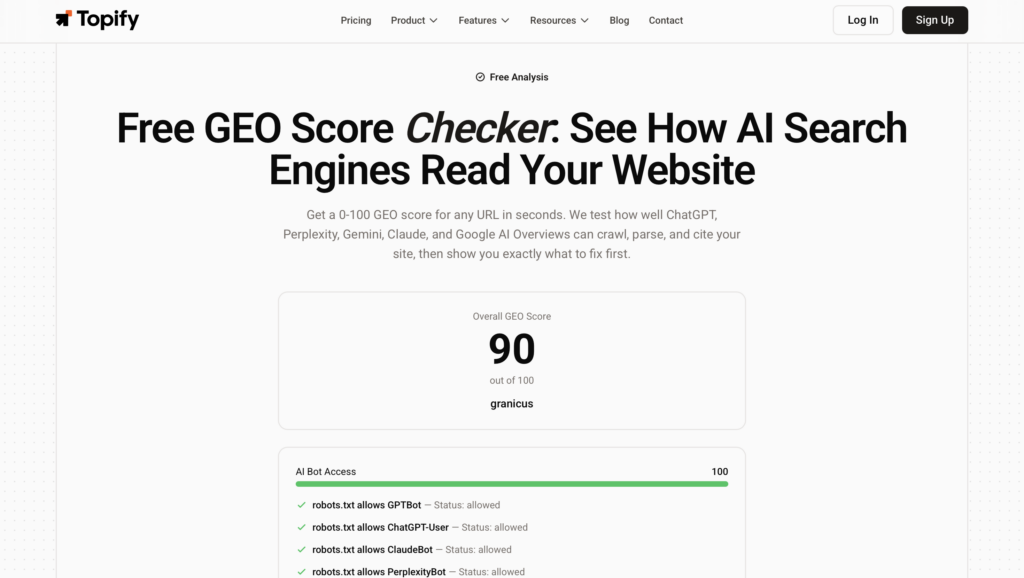
    Topify‘s GEO Score Checker measures exactly where that gap sits, scoring your site across four dimensions that determine whether AI search engines can find, read, trust, and recommend your public service content.

    ✅ Free ⚡ Results in 60 seconds 🔒 No signup required

    The Four Scores That Reveal Why AI Skips Your Public Service Website

    Public service organizations invest heavily in making information accessible to citizens. Plain language rewrites, multilingual pages, mobile-responsive design. But none of that matters to ChatGPT or Perplexity if their crawlers can’t reach the page in the first place.

    The GEO Score Checker evaluates four dimensions. Each one maps to a specific breakdown point in how AI platforms process public service content.

    Score DimensionWhat It MeasuresPublic Sector Impact
    Bot AccessWhether AI crawlers (GPTBot, ClaudeBot, PerplexityBot) can reach your pagesMany public service sites block AI crawlers by default, making program pages invisible to AI search
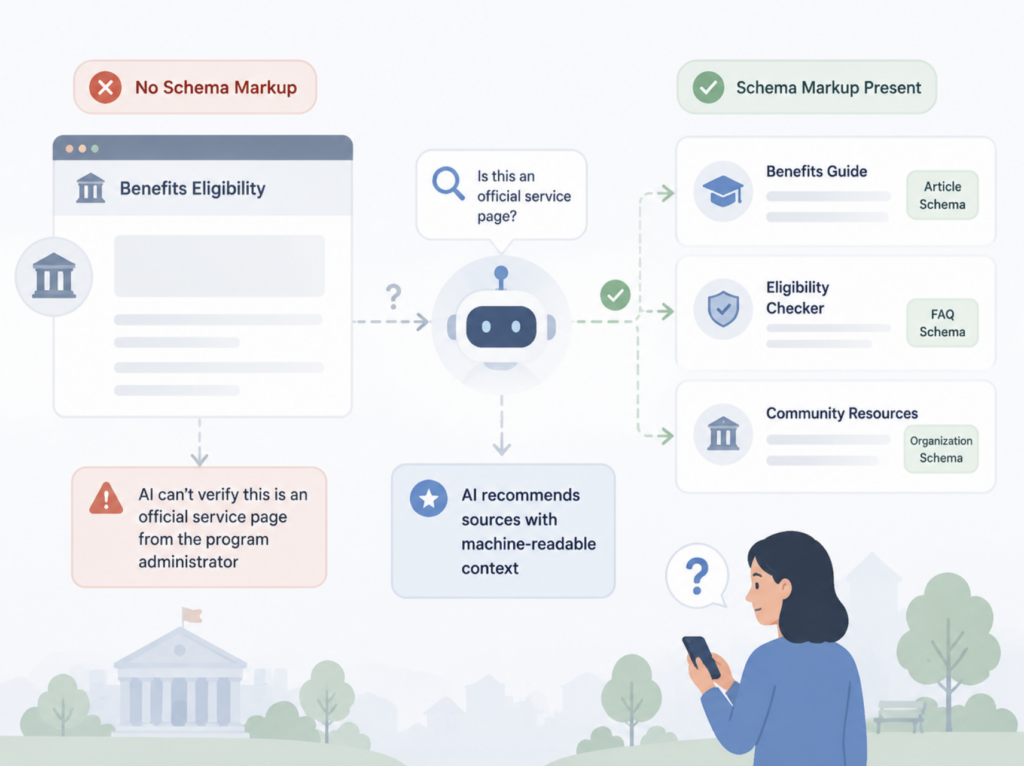
    Structured DataWhether your content uses schema markup that AI can parseWithout GovernmentService or FAQPage schema, AI can’t distinguish a benefits page from a blog post
    Content SignalsWhether AI considers your content authoritative and semantically clearBureaucratic language, PDF-heavy publishing, and thin program descriptions weaken authority signals
    Visibility ScoreHow often your organization appears in AI-generated answersMeasures actual presence across ChatGPT, Perplexity, Gemini, and Google AI Overviews

    A Benefits Portal That Ranks on Google but Doesn’t Exist in ChatGPT

    A social services organization maintains a comprehensive benefits eligibility page. It ranks in the top three on Google for multiple high-intent queries. But when a citizen asks ChatGPT the same question, the page doesn’t appear at all. The GEO Score Checker reveals a Bot Access score below 20: the site’s robots.txt blocks GPTBot and ClaudeBot entirely. Google’s traditional crawler gets through. AI search crawlers don’t.

    A Public Health Site with Strong Content but No Structured Data

    A public health department publishes detailed, plain-language guides on immunization schedules, clinic hours, and community health programs. The content is high quality. But its Structured Data score is 15. There’s no JSON-LD markup identifying the organization, its services, or the factual claims on each page. AI systems can’t verify what the content represents, so they pull from sources that do provide that machine-readable context.

    Emergency Service Information Trapped in PDF Documents

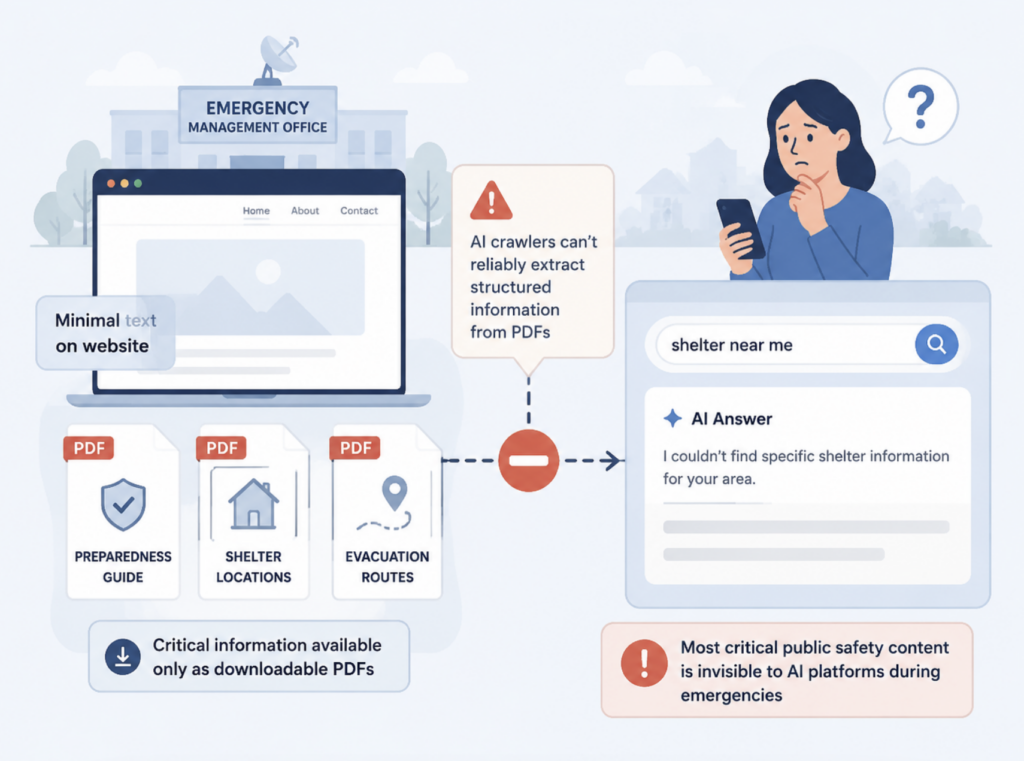
    An emergency management office publishes its preparedness guides, shelter locations, and evacuation routes exclusively as downloadable PDFs. The website itself has minimal text. Content Signals score: 22. AI crawlers can’t reliably extract structured information from PDF files, which means the most critical public safety content is invisible to the AI platforms citizens use during emergencies.

    How to Run the Check

    1. Go to GEO Score Checker.
    2. Enter your organization’s domain or brand name.
    3. Get your four-dimension score breakdown in under 60 seconds.
    4. Compare dimensions to identify your weakest point. That’s where citizens are losing access.

    What Citizens Ask AI Before They Ever Visit Your Website

    The shift isn’t theoretical. Citizens are already using AI search to navigate public services. They don’t type keyword strings. They ask full questions, the same way they’d ask a caseworker or a neighbor.

    AI Prompt ExamplePlatformSearch IntentWhat It Reveals
    “Am I eligible for food assistance if I work part-time?”ChatGPTBenefits eligibility screeningWhether AI cites the official program page or a third-party summary
    “What documents do I need to renew my driver’s license?”PerplexityProcess navigationWhether the issuing authority’s site provides parseable, step-by-step content
    “Free mental health services near me for uninsured adults”GeminiService discoveryWhether local public health providers appear in AI recommendations
    “How do I apply for small business permits in [city]?”ChatGPTRegulatory navigationWhether the permitting office’s own content surfaces over generic legal blogs
    “What are the income limits for childcare subsidies?”PerplexityEligibility verificationWhether AI returns current figures from the program source or outdated third-party data
    “Where is the nearest emergency shelter during a hurricane?”ChatGPTCrisis responseWhether emergency management content is AI-accessible when it matters most

    When AI answers these prompts with outdated, incomplete, or third-party information instead of official program content, the accuracy problem becomes a trust problem. Pew Research reported public trust at 19% in 2025. Every inaccurate AI answer about a public service reinforces that distrust.

    This isn’t a marketing metric. It’s an accessibility gap with real consequences.

    Where Public Service Websites Consistently Lose GEO Points

    The visibility failures in public services aren’t random. They follow patterns tied to how these organizations build, manage, and publish web content.

    AI Crawler Blocking as a Default Security Posture

    Many public service IT teams treat AI crawlers the same way they treat unknown bots: block by default. A blanket Disallow: / for GPTBot and ClaudeBot in robots.txt keeps the site secure from an infrastructure perspective. But it also prevents AI search platforms from indexing public-facing program pages that citizens need to find.

    Here’s the thing: AI providers now separate their training crawlers from their search crawlers. Blocking GPTBot (training) doesn’t require blocking OAI-SearchBot (search). The same applies to ClaudeBot versus Claude-SearchBot. A nuanced robots.txt policy can protect sensitive infrastructure while keeping public service content visible to AI search.

    PDF-Heavy Content Strategies

    Public service organizations publish a disproportionate amount of critical information as PDFs: application forms, eligibility guidelines, program handbooks, emergency preparedness guides. AI crawlers can access some PDF content, but they can’t reliably extract structured data, tables, or conditional eligibility logic from document files. If your most important citizen-facing information exists only in downloadable documents, your Content Signals score will reflect that gap.

    Missing Service-Level Schema Markup

    Most public service websites lack GovernmentService, GovernmentOrganization, or even basic Organization schema. Without structured data, AI systems treat a benefits eligibility page the same as any other text on the web. They can’t verify that this is an official service page from the organization that administers the program. The result: AI recommends sources that do provide machine-readable context, even when those sources are less authoritative.

    Cross-Platform Visibility Gaps

    A public transit authority might appear in Google AI Overviews (because Google already indexes its search results) but be completely absent from ChatGPT and Perplexity. Each AI platform crawls and indexes independently. A GEO Score Checker Visibility Score below 40 often reveals this fragmentation, where citizens get different answers depending on which AI platform they use.

    Public Service ScenarioGEO Score SignalLikely CausePriority Action
    Benefits page invisible to ChatGPTBot Access: < 25robots.txt blocks GPTBot and OAI-SearchBotUpdate robots.txt to allow AI search crawlers on public pages
    AI cites third-party sites over your program pageStructured Data: < 20No GovernmentService or FAQPage schemaAdd JSON-LD markup identifying services, eligibility, and contact info
    Emergency info can’t be found during a crisisContent Signals: < 30Critical content locked in PDFsPublish HTML versions of all citizen-facing emergency content
    Visible on Google AI Overviews but absent from PerplexityVisibility Score: < 35Inconsistent crawler access across platformsAudit robots.txt for each AI search bot independently

    From a One-Time Score to Continuous AI Visibility Monitoring

    The GEO Score Checker gives you a snapshot: here’s where your public service site stands right now across four dimensions. That’s the starting point.

    But AI search visibility isn’t static. Platforms update their crawling behavior, structured data standards evolve, and your content changes with every program update, budget cycle, or policy revision. A score that’s adequate today can slip within weeks.

    A single score tells you where you stand. Continuous monitoring tells you which direction you’re moving.

    CapabilityFree GEO Score CheckerTopify Platform
    Check frequencyOne-time snapshotContinuous monitoring
    Dimensions tracked4 GEO scoresFull GEO analytics + sentiment + citations
    Historical trendsNoneFull trend history with alerts
    Competitor benchmarkingNot includedReal-time competitor tracking
    Platform breakdownAggregatedPer-platform (ChatGPT, Perplexity, Gemini, AI Overviews)
    Optimization actionsDirectional guidanceSpecific, prioritized execution steps

    Topify’s Comprehensive GEO Analytics tracks all four GEO dimensions continuously, with per-platform breakdowns that show exactly where citizen-facing content is gaining or losing AI visibility. For public service organizations managing hundreds of program pages across multiple departments, the platform-level view replaces guesswork with data.

    You can start a free trial with no credit card required, or review pricing to find the right fit for your organization’s scale.

    Conclusion

    AI search is becoming a primary channel for citizens navigating public services. When your program pages aren’t visible in AI-generated answers, citizens don’t just miss your website. They miss accurate information about services they may be entitled to. That’s an accessibility failure, not a marketing problem.

    Start by running your organization’s domain through the GEO Score Checker. The four-dimension breakdown will tell you exactly where the gap sits: crawler access, structured data, content authority, or platform visibility.

    From there, you can check specific crawler configurations with the AI Robots Checker, verify whether AI models hold current information about your services using the Knowledge Freshness Checker, or get a cross-platform visibility snapshot through the AI Visibility Report.

    Frequently Asked Questions

    Why would a public service website score low on GEO when it already ranks well on Google? 

    Google Search and AI search engines use different crawling and ranking systems. A site can rank #1 on Google while being completely invisible to ChatGPT or Perplexity, typically because robots.txt blocks AI-specific crawlers or the site lacks structured data that AI platforms rely on to verify and cite content. The GEO Score Checker identifies exactly which dimension is causing the disconnect.

    Does publishing content as PDFs hurt AI visibility for public services? 

    In most cases, yes. AI crawlers can access some PDF content, but they can’t reliably parse tables, conditional eligibility criteria, or structured service information from document files. Public service organizations that publish critical citizen-facing information exclusively as PDFs typically score below 30 on Content Signals. Publishing HTML versions alongside PDFs is the most direct fix.

    Is AI search visibility relevant for public services that don’t sell anything? 

    AI search visibility for public services isn’t a commercial metric. It’s an accessibility indicator. When citizens ask AI about benefits eligibility, permit processes, or emergency resources, the organizations that score higher on GEO dimensions are the ones AI cites. For public services, that means the difference between citizens finding accurate program information and citizens acting on outdated or incorrect third-party content.

    How does the GEO Score Checker differ from a traditional SEO audit for a public service website? 

    Traditional SEO audits measure how well your pages perform in Google’s link-based ranking system. The GEO Score Checker measures four AI-specific dimensions: whether AI crawlers can access your site, whether your content has machine-readable structure, whether AI considers your content authoritative, and whether you actually appear in AI-generated answers. These are different systems with different technical requirements. A site can pass every SEO audit and still score below 40 on GEO.

    Read More:

  • GEO Score Checker for Food and Beverage Distributors

    GEO Score Checker for Food and Beverage Distributors

    A restaurant chain’s procurement lead types a prompt into ChatGPT: “Which broadline food distributors in the Southeast offer next-day delivery on frozen proteins with FSMA-compliant cold chain tracking?” The AI returns three names, a brief comparison, and a confidence note for each. Your company, the one with 5,000 SKUs and 40 years of regional coverage, isn’t mentioned.

    The problem isn’t your service. It’s the technical signals your website sends to AI platforms. And the gap is measurable.

    Topify‘s GEO Score Checker breaks your AI readiness into four scored dimensions, so you can see exactly where the breakdown starts. It takes 60 seconds and costs nothing.

    ✅ Free ⚡ Results in 60 seconds 🔒 No signup required

    The Four Numbers That Tell You Why AI Skips Your Distribution Brand

    GEO stands for Generative Engine Optimization. It measures how well your website communicates with AI platforms like ChatGPT, Perplexity, Gemini, and Google AI Overviews. For food and beverage distributors, each of the four scored dimensions maps to a specific business risk.

    Score DimensionWhat It MeasuresF&B Distribution Impact
    Bot AccessWhether AI crawlers (GPTBot, ClaudeBot, PerplexityBot) can reach your siteGated order portals and login walls often block crawlers from indexing product pages, service area info, and compliance documentation
    Structured DataWhether your site uses schema markup AI can parseProduct specs, certifications (SQF, FSMA 204), temperature requirements, and case sizes need to be machine-readable, not buried in PDF catalogs
    Content SignalsWhether AI views your content as authoritativeThin product listings without context lose to distributors publishing category guides, sourcing transparency pages, and operator-facing thought leadership
    Visibility ScoreHow often your brand appears in AI-generated answersThe composite measure of whether AI platforms actually name your company when operators ask for distributor recommendations

    Those four scores, each on a 0-100 scale, tell a complete story. A distributor scoring 75 on Bot Access but 25 on Structured Data knows exactly where to focus: the crawlers can reach the site, but once there, they can’t make sense of the product data.

    Your Product Catalog Has 5,000 SKUs. AI Sees Zero.

    This is the most common failure mode for food distributors. The catalog exists as a downloadable PDF, or behind a login gate that requires an active account. GPTBot doesn’t have a customer number. Neither does ClaudeBot. Every SKU page locked behind authentication is a page AI will never index.

    A distributor with a rich, open product taxonomy scores higher on Bot Access and Structured Data than a competitor with twice the product range but everything behind a portal. That’s the paradox: the distributor with the deepest catalog can be the least visible to AI.

    The Distributor That Wins the “Strategic Partner” Label

    AI platforms don’t just decide whether to mention you. They decide how to describe you. A distributor with published case studies, operator testimonials, and category expertise content gets framed as a “strategic partner.” One with only transactional product pages gets labeled a “logistics provider.”

    That framing difference shows up in your Content Signals score. If it’s below 40, AI likely doesn’t have enough editorial evidence to position you as anything more than a commodity supplier.

    How to Run the Check

    1. Go to GEO Score Checker
    2. Enter your brand name or domain
    3. Get your four-dimension score breakdown in under 60 seconds
    4. Compare dimensions to find your weakest signal

    The score won’t tell you everything, but it will tell you which of the four areas is costing you the most AI visibility right now.

    What Operators and Procurement Teams Ask AI Before They Send an RFQ

    The foodservice vendor switching window is narrow. Only about 20% of operators change distributors in a given year, according to industry estimates reported by NRN. AI search is compressing the discovery phase into that window. If your brand isn’t visible during the brief period when a buyer is actively evaluating, you don’t get a second chance until next cycle.

    Here’s what those buyers are actually typing:

    AI Prompt ExamplePlatformSearch IntentWhat It Reveals
    “Best regional food distributors for independent restaurants in the Midwest”ChatGPTVendor discoveryOperators want AI to narrow a broad category by geography and customer type
    “Which food distributors offer next-day delivery on fresh produce with lot-level traceability?”PerplexityCapability filteringCompliance and logistics speed are decision criteria AI checks against structured evidence
    “Compare broadline vs. specialty food distributors for a 12-unit fast casual chain”GeminiModel comparisonAI builds a side-by-side using whatever structured data it can extract from each distributor’s site
    “Food distribution companies with strong sustainability sourcing programs”ChatGPTValues alignmentESG and sourcing transparency content directly feeds Content Signals scores
    “Who are the top cold chain food distributors with FSMA 204 compliance documentation?”PerplexityRegulatory verificationAI looks for structured compliance data, not a PDF buried three clicks deep
    “Alternatives to [major national distributor] for mid-size restaurant groups”ChatGPTCompetitor displacementThe highest-intent prompt: the buyer is actively looking to switch, and AI decides who makes the shortlist

    That last prompt type is where the stakes are highest. A buyer asking for alternatives has already decided to move. AI will recommend whichever distributors have the strongest combination of third-party mentions, structured product data, and authoritative content. If your GEO signals are weak, you miss the one moment the buyer was ready to find you.

    Three GEO Blind Spots That Keep F&B Distributors Off AI Shortlists

    Most food and beverage distributors invest heavily in the systems their existing customers use: order portals, EDI integrations, account management dashboards. Those investments are critical for retention. They do nothing for AI-mediated acquisition.

    PDF Catalogs and Gated Portals Block the Crawlers

    A distributor’s product catalog is often its most valuable content asset, and the one most thoroughly hidden from AI. PDF catalogs are functionally invisible to AI crawlers. Gated ordering portals that require login block GPTBot, ClaudeBot, and PerplexityBot entirely.

    The fix isn’t to make your ordering system public. It’s to create a parallel layer of open, crawlable product information: category pages with structured data markup (Product schema with attributes like brand, weight, temperature class, certifications), service area descriptions, and capability summaries. This is the layer AI evaluates. Without it, your Bot Access and Structured Data scores stay low regardless of how comprehensive your actual catalog is.

    Regional Coverage Without Third-Party Corroboration

    AI platforms weight third-party mentions heavily when building supplier recommendations. A distributor that’s well-known in its region but has minimal coverage in trade publications, industry directories, or operator forums will score low on Content Signals.

    Here’s the thing: AI doesn’t take your word for it. If your website says “We serve the entire Southeast with next-day delivery,” but no third-party source confirms that claim, AI treats it as unverified. Distributors with mentions in trade media, foodservice buying guides, and industry association directories get stronger corroboration signals.

    Platform Fragmentation: Visible on Perplexity, Absent from ChatGPT

    Regional distributors often show an uneven visibility pattern across AI platforms. Perplexity retrieves live web data and may surface your site directly. ChatGPT leans more on training data and corroborated mentions, so a distributor without broad editorial coverage can be completely absent.

    This fragmentation is measurable. Your Visibility Score in GEO Score Checker reflects aggregate presence, but the real diagnostic comes from checking whether your brand appears consistently across platforms or only on one or two.

    From a One-Time Score to Continuous Distribution Visibility Tracking

    Running your GEO Score Checker gives you a snapshot: here’s where you stand today across four dimensions. That snapshot is useful for identifying your weakest signal and prioritizing fixes.

    But GEO signals aren’t static. AI platforms update their indexes, competitors publish new content, and your own site changes with seasonal catalogs, new service area announcements, and compliance updates. A score that’s accurate today may not reflect your position next quarter.

    That’s the gap Comprehensive GEO Analytics fills. It tracks all four GEO dimensions continuously across ChatGPT, Perplexity, Gemini, and Google AI Overviews, with historical trends and alerts when your visibility shifts.

    CapabilityFree GEO Score CheckerTopify Platform
    Check frequencyOne-time snapshotContinuous monitoring
    Dimensions tracked4 GEO scoresFull GEO analytics + sentiment + citations
    Historical trendsNoneFull trend history with alerts
    Competitor benchmarkingNot includedReal-time competitor tracking
    Platform breakdownAggregatedPer-platform (ChatGPT, Perplexity, Gemini, AI Overviews)
    Optimization actionsDirectional guidanceSpecific, prioritized execution steps

    The checker tells you where you stand. The platform tells you which direction you’re moving, and whether your competitors are gaining ground.

    Plans start at $99/month with a 7-day free trial, no credit card required. See pricing or start a free trial.

    Conclusion

    Food and beverage distributors have spent decades building service networks, product depth, and operator relationships. None of that matters to an AI platform that can’t crawl your catalog, can’t parse your certifications, and can’t find a third-party source that corroborates your coverage claims.

    The distributors that show up in AI-generated shortlists over the next two years will be the ones that close the gap between what they actually offer and what AI can verify.

    Start with a free GEO Score Checker scan to see which of the four dimensions needs attention first. For deeper diagnostics, Topify’s AI Robots Checker can pinpoint exactly which AI crawlers your site is blocking, and the Knowledge Freshness Checker shows whether AI models are working with current or outdated information about your brand.

    Frequently Asked Questions

    Why does my food distribution website score low on Structured Data even though we list thousands of products?

    Product listings alone don’t generate a strong Structured Data score. AI crawlers look for schema markup (JSON-LD Product, Organization, and Service types) that explicitly tags attributes like certifications, temperature classes, and delivery capabilities. If your specs exist only in PDF catalogs or image-based line sheets, AI treats those pages as if they have no product data at all.

    How does the vendor switching cycle in foodservice affect my GEO strategy? 

    Only about 20% of foodservice operators evaluate new distribution partners in any given year. That makes the timing of your AI visibility critical. If your GEO scores are low during the quarter when a prospect is actively searching, you won’t appear on their AI-generated shortlist, and there’s no second window until the next evaluation cycle. Continuous monitoring through Comprehensive GEO Analytics ensures you’re not blind to visibility drops during peak switching periods.

    Can a regional distributor compete with national broadliners in AI search results? 

    Yes, but through different signals. National distributors have brand recognition and broad editorial coverage. Regional distributors can win on specificity: detailed service area pages, local operator case studies, and structured data that highlights niche capabilities (organic sourcing, allergen-free handling, same-day metro delivery). AI platforms recommend based on relevance to the buyer’s query, not brand size alone.

    What’s the difference between a GEO score and a traditional SEO ranking? 

    SEO measures where your website appears in a Google search results page. Your GEO score measures whether AI platforms can access, understand, and recommend your brand when buyers ask questions in ChatGPT, Perplexity, or Gemini. A distributor can rank well on Google for “food distribution services” but score below 30 on GEO because its site blocks AI crawlers or lacks the structured data those platforms need to generate a recommendation.

    Read More:

  • Prompt Search in 2026: How Users Query AI Differently

    Prompt Search in 2026: How Users Query AI Differently

    Your keyword research says “best CRM” gets 40,000 searches a month. Clean data. Clear intent. But when a prospect actually opens ChatGPT, they type something closer to “I run a 12-person B2B agency and we need a CRM that integrates with HubSpot, handles deal tracking, and costs under $50 per seat.” That’s 27 words, loaded with constraints your keyword tool never saw. The gap between what traditional search data captures and what users actually type into AI platforms is widening every quarter. And that gap is where brand visibility gets won or lost.

    What Separates a Prompt Search from a Keyword Search

    The difference isn’t just length. It’s structure.

    A Google search is a signal. You type “running shoes flat feet” and the engine infers the rest. An AI prompt is a briefing. You explain your situation, set constraints, and expect a tailored answer. The input changes from a fragment to a paragraph, and the output changes from a list of links to a synthesized recommendation.

    The data backs this up. A Semrush study of ChatGPT usage found that the average ChatGPT prompt runs about 23 wordswhen web search isn’t activated. Google’s average query length, by comparison, sits at roughly 3.4 words according to Semrush data. That’s nearly a 7x difference. And when users do activate ChatGPT’s search feature, their prompts drop to about 4.2 words, closer to Google’s norm, but the conversational framing stays.

    An analysis of 13,252 publicly shared ChatGPT conversations found that opening messages average 103 words. Users aren’t just asking questions. They’re describing scenarios, listing preferences, and setting context before the first response even loads.

    That matters for brands because prompt search isn’t about matching a keyword. It’s about matching a situation.

    Three Platforms, Three Prompt Patterns: ChatGPT vs. Perplexity vs. Google AI Mode

    Not all prompt search behavior looks the same. Each platform trains users into different querying habits, and those habits shape which brands get surfaced.

    ChatGPT leans conversational and personal. Users treat it like a consultant. Over half of real ChatGPT prompts use personal pronouns like “I,” “my,” or “me.” Sessions average just 1.7 messages, but those messages are dense. The typical user front-loads context rather than asking follow-ups. When ChatGPT does trigger a web search, it averages 2.17 searches per prompt, with internal queries running 5.48 words on average, 61% longer than a typical Google query.

    Perplexity attracts a different behavior: iterative research. Users report replacing Google for 70% to 99% of their research and knowledge queries while still defaulting to Google for navigation and shopping. Perplexity’s interface encourages progressive refinement. You start broad, then scope down with follow-ups. The platform transparently shows its sub-searches and cited sources, which trains users to write more structured, research-spec-style prompts.

    Google AI Mode is the most revealing shift. After launching in May 2025, it hit 1 billion monthly active users within a year. The average AI Mode query is three times longer than a traditional Google search. Follow-up queries have risen over 40% per month, and planning queries are growing 80% faster than AI Mode usage overall. Similarweb data shows that even in traditional Google Search, average query length has climbed from 3.33 words to 3.51 words since AI Mode launched.

    Here’s a side-by-side breakdown:

    DimensionChatGPTPerplexityGoogle AI Mode
    Avg. prompt length~23 words (without search)Structured research queries3x traditional Google search
    Primary behaviorSingle-turn, context-denseIterative refinementConversational follow-ups
    Search trigger rate31% of promptsEvery query triggers retrievalBuilt into every interaction
    User framing stylePersonal (“I need…”)Analytical (“Compare X vs. Y…”)Natural language, often voice
    Follow-up patternLow (1.7 msgs avg.)High (progressive scoping)Growing 40%+ per month

    The takeaway: a brand that shows up in ChatGPT’s single-turn answers may be invisible in Perplexity’s iterative chains or Google AI Mode’s follow-up conversations. Prompt search visibility is platform-specific.

    Why Keyword Research Tools Can’t Track Prompt Search Patterns

    Traditional keyword tools were built to index Google’s search bar. They capture short phrases, estimate monthly volumes, and cluster by head terms. That model breaks down when prompts become paragraphs.

    The core issue is structural. When someone types “best CRM for small teams” into Google, the engine matches it against its index and returns ranked pages. When the same person types a version of that query into ChatGPT, the model doesn’t just match. It decomposes. This is called query fan-out: the AI breaks one prompt into multiple sub-queries, runs them in parallel, retrieves sources for each, and synthesizes a single answer.

    Google described this behavior explicitly when it launched AI Mode, calling it a “query fan-out technique” that issues multiple related searches at once across subtopics and data sources. In practice, one user prompt can generate 8 to 16 sub-queries behind the scenes. ChatGPT averages 2.17 fan-out searches per prompt, with some triggering up to four.

    That means the unit of optimization has shifted. It’s no longer one keyword per page. It’s one topic cluster per prompt.

    And it gets more complex. SparkToro’s January 2026 research, conducted with Gumshoe.ai across 2,961 prompt runs, found that AI tools produce a different brand recommendation list more than 99% of the time. Even when 142 participants wrote their own prompts for the same underlying intent, the average semantic similarity was only 0.081. In other words, people with identical needs phrase their prompts in vastly different ways, and each variation can surface a different set of brands.

    No keyword tool captures that.

    What Prompt Search Behavior Means for Brand Visibility

    The SparkToro finding sounds alarming at first. If AI recommendations change with every query, what’s the point of tracking them?

    Here’s the thing. The brand lists vary, but the brand clusters don’t. SparkToro’s own follow-up analysis noted that despite massive prompt variation, AI tools often returned similar clusters of brands across different phrasings. The wording and order shifted, but the pool of recommended brands overlapped significantly. The question for marketers isn’t “which exact prompt should I optimize for?” It’s “am I showing up reliably across the full semantic neighborhood of this intent?”

    That reframes the visibility challenge. Brands need to understand which prompt patterns, not which exact keywords, drive their inclusion in AI answers. A prompt like “recommend a project management tool for remote teams” and “what’s the best PM software for distributed startups under 20 people” may look different to a keyword tool. To an AI platform, they overlap heavily, but not entirely. The second prompt’s constraints (startup, under 20 people) may pull in a different subset of brands.

    This is where prompt-level visibility tracking becomes non-negotiable. Topify‘s High-Value Prompt Discovery surfaces the actual prompts driving AI recommendations in your category, across ChatGPT, Perplexity, Google AI Mode, and other platforms. Instead of guessing which keywords matter, you see which prompt patterns your brand appears in and which ones you’re missing.

    In practice, that means a SaaS brand can discover that it’s consistently recommended when users ask about “CRM with email automation” but disappears when the prompt adds “for agencies” or “under $30 per seat.” That’s the kind of prompt-level gap that traditional keyword tools can’t reveal, but that directly impacts pipeline.

    How to Track and Adapt to Prompt Search Trends

    Knowing that prompt behavior matters is step one. Acting on it requires a system.

    Start by mapping your prompt terrain. Use Topify’s Prompt Discovery to identify which AI prompts mention your brand, your competitors, or your product category. This surfaces the actual language users type, not the cleaned-up keyword variants from traditional tools. You’ll often find prompt patterns you never anticipated, like industry-specific use cases or constraint combinations that don’t show up in Google Search Console.

    Monitor cross-platform visibility at the prompt level. A brand that ranks well in ChatGPT’s recommendations may be absent from Perplexity or Google AI Mode. Topify’s Comprehensive GEO Analytics tracks seven metrics (visibility, sentiment, position, volume, mentions, intent, and CVR) across major AI platforms. The platform-specific view matters because each engine’s fan-out logic, citation preferences, and retrieval patterns differ.

    Analyze what AI cites, not just what it recommends. Topify’s Source Analysis shows which domains and URLs AI platforms reference when generating answers. If a competitor’s blog post is the cited source behind your category’s top prompts, that’s a content gap you can close. If your own product page gets cited for the wrong prompts, that’s a positioning issue to fix.

    Iterate based on prompt clusters, not individual keywords. Group the prompts where your brand appears (and where it doesn’t) by intent and constraint patterns. Then map your content to those clusters. The brands that win in prompt search aren’t the ones optimizing for one keyword. They’re the ones that cover the full fan-out surface of their category’s most common prompts.

    Conclusion

    Prompt search is the new first touchpoint for brand discovery. In 2026, AI Mode alone has a billion monthly users asking queries three times longer than traditional searches, and ChatGPT processes billions of prompts daily with conversational inputs that no keyword tool was designed to capture. The brands that adapt aren’t just optimizing for AI. They’re tracking the actual language their audience uses across platforms, identifying the prompt patterns where they’re visible or invisible, and closing the gaps before competitors do. The shift from keywords to prompts isn’t coming. It’s already here, and it’s measurable.

    FAQ

    Q: What is prompt search? 

    A: Prompt search refers to the behavior of querying AI platforms like ChatGPT, Perplexity, and Google AI Mode using natural language prompts instead of short keyword strings. These prompts tend to be longer, more context-rich, and more personal than traditional search queries, often including constraints, preferences, and situational details.

    Q: How do prompt search patterns differ between ChatGPT and Google AI Mode? 

    A: ChatGPT prompts tend to be single-turn and context-dense, averaging 23 words without web search activated. Users often describe personal scenarios upfront. Google AI Mode prompts are three times longer than traditional Google searches, with follow-up queries growing over 40% per month. AI Mode encourages multi-turn conversations, while ChatGPT users typically front-load their context in one message.

    Q: Can traditional SEO tools track prompt search behavior? 

    A: Not effectively. Traditional keyword research tools capture short-phrase queries from Google’s index and estimate search volume. They don’t cover the longer, conversational prompts users type into AI platforms, the query fan-out behavior where one prompt becomes multiple sub-queries, or the cross-platform variation in how AI engines surface brands for similar intents.

    Q: How can brands optimize for prompt-based AI search? 

    A: Focus on three areas. First, discover the actual prompts driving recommendations in your category using prompt-level tracking tools like Topify. Second, build content that covers full topic clusters rather than single keywords, since AI platforms decompose prompts into sub-queries. Third, monitor your visibility across multiple AI platforms, because prompt behavior and citation patterns vary significantly between ChatGPT, Perplexity, and Google AI Mode.

    Read More

  • The Rise of Prompt Search: How AI Is Replacing the Search Bar

    The Rise of Prompt Search: How AI Is Replacing the Search Bar

    Your keyword rankings are stable. Your domain authority is climbing. Your content calendar is running on schedule. Then a prospect types a 23-word question into ChatGPT, gets a direct recommendation for your competitor, and never visits Google at all. Nothing in your SEO dashboard flagged it. Nothing in your analytics even registered the lost opportunity.

    That’s the gap prompt search has opened. And for most marketing teams, it’s completely invisible.

    From Keywords to Prompts: What Actually Changed in Search

    For two decades, search worked on a simple contract: users compressed their intent into short keyword phrases, and search engines matched those fragments against indexed pages. Type “best CRM small business,” get a ranked list of links. The system rewarded brevity because the algorithm needed it.

    Prompt search flips that contract. Instead of trimming context to fit a search box, users now write full questions with constraints, preferences, and background information baked in. A Semrush study found that the average ChatGPT prompt runs about 23 words, compared to roughly 4 words for a typical Google query. Some analyses put the ChatGPT average even higher, around 60 words, once you include detailed research and multi-step requests.

    The difference isn’t just length. It’s structure. A keyword query like “project management tool” carries almost no context. A prompt like “What project management tool should I use for a remote team of 15 people with a tight budget and Slack integration?” tells the AI who’s asking, what they need, and what constraints matter. The AI doesn’t match keywords to pages. It interprets intent, weighs context, and synthesizes an answer from multiple sources.

    That shift has a direct consequence for brands: if your content was built to match keyword fragments, it may not surface when an AI system processes a context-rich prompt.

    Why Prompt Search Breaks Traditional Keyword Research

    The mechanical reason is a process called query fan-out. When a user submits a prompt to ChatGPT, Perplexity, or Google’s AI Mode, the system doesn’t search for the exact phrase. It breaks the prompt into multiple sub-queries, runs them in parallel, retrieves pages for each, and synthesizes the results into a single answer.

    A Nectiv study analyzing 8,500+ ChatGPT prompts found that 31% triggered at least one web search, with an average of 2.17 searches per prompt. NoGood’s testing showed that a single prompt can generate 8 to 15 sub-queries behind the scenes, each pulling from different sources.

    Here’s what that looks like in practice. A user asks: “How do I reduce customer acquisition costs?” ChatGPT might fan out into sub-queries like “CAC reduction strategies for SaaS,” “customer acquisition cost benchmarks by industry,” and “CAC vs LTV optimization.” The final answer combines passages from six different websites, none of which necessarily ranked first for the original query.

    Traditional keyword research can’t capture this. Your keyword tool shows volume for “reduce customer acquisition costs.” It doesn’t show you the five hidden sub-queries that actually determine which brands get cited. And those sub-queries change depending on the phrasing, context, and constraints the user includes in their prompt.

    That’s the core problem. Keyword research tells you what humans type into Google. Query fan-out tells you what the AI types into Google after it reads what the human asked. Different layer, different leverage.

    The Numbers Behind the Shift to Prompt Search

    The scale of this shift is no longer speculative. It’s measurable across every major platform.

    ChatGPT reached over 1 billion monthly active users in early 2026, processing roughly 2.5 billion prompts per day. Perplexity scaled to 1.2 to 1.5 billion monthly queries. Google’s AI Overviews now appear on roughly 15% of all Google searches, with higher rates for informational and research queries.

    The behavioral data is equally clear. Bain & Company’s 2025 research found that 80% of consumers rely on AI-written results for at least 40% of their searches, reducing organic web traffic by 15% to 25%. Gartner predicted that traditional search volume would drop 25% by 2026 as users shifted to AI chatbots. About 37% of consumers now start searches with AI tools, and that figure is higher among younger demographics.

    The commercial impact is where it gets interesting. The Opollo AI Search Benchmark Report, analyzing 312 B2B technology companies, found that AI-referred traffic converts at 14.2%, compared to Google organic’s 2.8%. That’s a 5x gap. Fewer visitors, but dramatically more valuable ones.

    Yet only 23% of marketers currently invest in measuring AI visibility, even though 54% plan to implement GEO within the next 3 to 6 months. The gap between awareness and action is wide.

    What Prompt Search Means for Your Content Strategy

    The strategic shift is straightforward, even if the execution isn’t. Content built for keyword matching needs to evolve into content built for intent coverage.

    Here’s what that looks like in practice:

    DimensionKeyword-Optimized ContentPrompt-Ready Content
    Query it targetsShort phrase (“best CRM”)Full question with context and constraints
    Optimization goalRank for one keywordCover multiple sub-queries an AI might generate
    Content structureSingle topic, keyword densityMulti-angle coverage with clear, extractable answers
    Success metricGoogle ranking positionWhether AI cites the content in generated answers
    Update cadenceQuarterly refreshContinuous, since AI favors pages updated within 30 days

    The practical starting point is prompt mapping. Rather than building a keyword list, you build a prompt set that mirrors how real users ask questions in AI search. SurfacedBy’s research breaks this into four categories:

    Discovery prompts: Broad category questions where no brand is named. (“What’s the best way to track my brand’s visibility in AI search?”)

    Constraint prompts: Questions that add budget, company size, use case, or technical requirements. (“What AI visibility tool works for a 10-person marketing team under $200/month?”)

    Comparison prompts: Questions that force tradeoffs between named options. (“How does X compare to Y for AI search monitoring?”)

    Follow-up prompts: Second and third questions in a conversation that narrow the recommendation. (“Does it also track Perplexity and Google AI Overviews?”)

    Your content needs to address all four types, not just the head term. That means structuring articles so that each sub-section answers a distinct question an AI might fan out into. If your page answers the most relevant sub-queries with clear, direct passages at the top of each section, you’re more likely to get cited.

    How to Track Prompt Search Visibility Before Competitors Do

    Here’s the thing: you can’t optimize what you can’t measure. And traditional SEO tools weren’t built to measure prompt-level visibility. They’ll tell you where you rank on Google for “best CRM.” They won’t tell you whether ChatGPT mentions your brand when a user asks, “Which CRM should a 15-person remote team use if we need Slack integration and spend under $50/seat?”

    That’s a fundamentally different measurement problem. It requires tracking real prompts across multiple AI platforms, monitoring which brands get cited, and understanding the sentiment and position of those citations.

    Topify was built for exactly this shift. Its High-Value Prompt Discovery feature surfaces the specific prompts your audience is asking across ChatGPT, Perplexity, and Google AI Overviews, so you’re optimizing for the questions that actually drive AI recommendations, not just the keywords that drive Google rankings.

    The platform’s Visibility Tracking monitors whether your brand appears in AI-generated answers at the prompt level. You can see which prompts trigger a mention, which don’t, and how your citation rate compares to competitors. Source Analysis then shows which domains and URLs the AI platforms are actually citing, so you can identify exactly where your content gaps are.

    In practice, this means a marketing team can go from “we think we’re doing well in AI search” to “we know we’re cited in 34% of high-intent prompts in our category, up from 18% last quarter, and competitor X just passed us on Perplexity.” That’s the difference between guessing and operating.

    For teams just getting started, the first step is simple: take your top 10 keywords and rewrite them as the prompts your buyers would actually type into ChatGPT. Then check whether you show up. If the answer is no, or you don’t know, that’s where Topify’s prompt-level tracking fills the gap.

    Conclusion

    Search didn’t die. It evolved. The search bar trained users to think in fragments. AI search is training them to think in full sentences, with context, constraints, and follow-ups. That’s prompt search, and it’s already reshaping which brands get discovered, recommended, and chosen.

    The marketers who’ll win this transition aren’t the ones with the best keyword rankings. They’re the ones who understand which prompts matter, track their visibility at the prompt level, and build content that answers the sub-queries AI actually runs behind the scenes. The data is clear, the shift is measurable, and the tools to act on it exist today.

    FAQ

    Q: What is prompt search? 

    A: Prompt search refers to the way users interact with AI platforms like ChatGPT, Perplexity, and Google AI Mode by typing full, natural-language questions instead of short keyword fragments. These prompts typically include context, constraints, and specific intent, and the AI interprets them to generate synthesized answers rather than a list of links.

    Q: Does prompt search mean keywords are dead? 

    A: No. Keywords still indicate where demand exists. But keywords alone no longer capture how AI search engines process and respond to user queries. The shift is from optimizing for a keyword to covering the full set of sub-queries an AI might generate from a single prompt. The two approaches work together, not as replacements.

    Q: How does query fan-out work in AI search? 

    A: When you submit a prompt to an AI search platform, the system breaks it into multiple narrower sub-queries, searches the web for each one in parallel, and then synthesizes the results into a single answer. This process, called query fan-out, means that the pages cited in an AI answer often weren’t optimized for the original prompt at all. They were pulled in because they answered one of the hidden sub-queries.

    Q: How can I track my brand’s visibility in prompt search results? 

    A: You need a platform that monitors AI-generated answers at the prompt level across multiple AI engines. Topify, for example, tracks which prompts mention your brand in ChatGPT, Perplexity, and Google AI Overviews, and shows how your visibility compares to competitors. The key is moving beyond keyword rankings to prompt-level citation tracking.

    Read More

  • Prompt Search vs. Keyword Search: What Changes for Marketers

    Prompt Search vs. Keyword Search: What Changes for Marketers

    Your team has been optimizing for “best CRM software” for months. Rankings are solid. Traffic is steady. Then a potential buyer opens ChatGPT and types, “Which CRM works best for a 50-person SaaS company that already uses HubSpot for email but needs better pipeline reporting?” That prompt triggers multiple internal searches, pulls from dozens of sources, and returns a synthesized answer naming three to five brands. Yours isn’t one of them.

    The gap between what keyword search rewards and what prompt search surfaces is widening fast. According to a January 2026 study, 37% of consumers now start their searches with AI instead of Google. And the queries they’re typing into ChatGPT, Perplexity, and Gemini look nothing like the two-to-four-word keyword fragments that traditional SEO was built to capture.

    What Prompt Search Actually Does (and Why It’s Not Just Longer Keywords)

    The difference between prompt search and keyword search isn’t just word count. It’s architecture.

    In keyword search, a user types a fragment like “best project management tool.” Google matches that fragment against an index of pages, ranks them by signals like backlinks and domain authority, and returns a list of ten blue links. The user clicks, scans, and decides.

    In prompt search, the user types something closer to a full thought: “What project management tool works best for remote teams of 15 to 20 people who need Slack integration and Gantt charts?” The AI doesn’t match against an index. It reasons across sources, synthesizes information, and delivers a single narrative answer, often naming specific brands and explaining why each fits.

    The numbers confirm this behavioral shift. A Semrush study found that the average ChatGPT prompt is 23 words long, compared to just 4.2 words for a typical Google search. Google’s own AI Mode sits in between at 7.22 words per query. Users aren’t just asking longer questions. They’re providing context, constraints, and intent that traditional keyword research never captures.

    That shift matters because AI platforms don’t just read the prompt literally. ChatGPT, for example, averages about two fan-out queries per prompt, breaking a single user question into multiple sub-searches before assembling a response. Google’s Gemini averages nine. And here’s the kicker: 91% of ChatGPT’s fan-out queries are unique, meaning the AI almost never fires the same search string twice for the same prompt. Your content either covers enough ground to get pulled into those sub-queries, or it doesn’t exist in the answer.

    Five Gaps Between Keyword Search and Prompt Search That Marketers Can’t Ignore

    The structural differences go deeper than query length. Here’s where keyword search and prompt search diverge in ways that directly affect marketing strategy.

    DimensionKeyword SearchPrompt Search
    Query structure2-5 word fragments (“best CRM software”)Full sentences with context, constraints, and intent
    Ranking logicPageRank, backlinks, domain authorityAI reasoning, source authority, entity clarity, content structure
    Result format10 blue links the user must evaluateSynthesized paragraph naming 3-5 brands with explanations
    Intent signalSingle keyword-level intentMulti-layered intent embedded in one prompt (use case + budget + tech stack + team size)
    Optimization leverKeyword density, link building, meta tagsTopical coverage, structured claims, third-party validation, citation-worthy content

    The result format gap is particularly consequential. In keyword search, ranking on page one means you’re one of ten options a user sees. In prompt search, the AI typically mentions three to five brands per answer. If you’re not in that short list, you’re not on page two. You’re nowhere.

    A Semrush study of 50,000 brands across 1,094 categories in ChatGPT found that only 15% of categories have a clear brand “owner,” a single brand that shows up consistently across related prompts. In the other 85%, no brand dominates. That’s both a risk and an opportunity: the race for prompt search visibility is still wide open in most categories.

    The Invisible Cost of Ignoring Prompt Search

    Marketers who treat prompt search as a future trend are already losing ground.

    ChatGPT crossed 900 million weekly active users as of February 2026. Perplexity surpassed 100 million monthly active users by April 2026. These aren’t niche platforms. They’re mass-market search tools processing billions of queries daily.

    The zero-click problem makes this worse. On traditional Google, 68% of searches already end without a click in 2026. On Google’s AI Mode, that number jumps to 93%. Only 1% of users click on links inside an AI Overview. Prompt search doesn’t just change how brands get discovered. It compresses the entire discovery-to-decision funnel into a single AI-generated answer.

    Here’s what that means in practice. A marketer investing solely in keyword SEO might still rank well on Google. But when 43% of U.S. online shoppers are using AI assistants for product research, and 74% of users choose the top-mentioned brand in an AI answer, ranking on Google alone doesn’t guarantee that the brand shows up where buying decisions are actually forming.

    The traffic won’t come back through a different door. It simply never reaches your site.

    How to Shift from Keyword Thinking to Prompt Thinking

    Adapting to prompt search doesn’t mean abandoning keyword SEO. It means layering a new set of practices on top of it. Here are four concrete shifts.

    Move from keyword research to prompt research

    Traditional keyword tools show you what people type into Google. They don’t show you the full-sentence prompts users are asking ChatGPT or Perplexity.

    The fix: start with the questions your customers actually ask. Sales calls, support tickets, Reddit threads, and community forums are rich sources of real prompts. The vocabulary people use when they “talk” to an AI is closer to how they’d ask a colleague than how they’d type a Google search.

    Topify‘s High-Value Prompt Discovery surfaces the actual prompts driving AI answers in your category, across ChatGPT, Perplexity, Gemini, and Google AI Overviews. Instead of guessing which keywords matter, you see which prompts are generating brand mentions and recommendations right now.

    Build content that answers sub-queries, not just head terms

    Because AI search engines decompose prompts into multiple fan-out queries, a single page optimized for one head keyword often misses the retrieval net entirely. ChatGPT’s fan-out queries share only 13% word overlap with the original prompt, meaning the AI is searching for related concepts your keyword-focused content may never mention.

    The practical response: build topic clusters, not keyword pages. Cover the definition, the comparison, the use case, the objections, and the alternatives. Each distinct angle becomes a potential entry point for AI retrieval.

    Strengthen third-party signals

    AI systems tend to pull brand mentions from third-party sources rather than brand-owned content. An analysis of over 23,000 AI citations found that 91% came from third-party sources, not brand websites. Reddit alone accounts for roughly 40% of AI citations across major platforms.

    That means PR mentions, industry roundups, expert reviews, and community discussions carry more weight in prompt search than they ever did in keyword search. If the only place your brand is discussed in depth is your own blog, AI systems have less reason to recommend you.

    Track visibility where it actually matters

    This is where most teams hit a wall. Google Analytics, Search Console, and rank trackers can’t tell you whether your brand appears in an AI-generated answer. They were built for keyword search, not prompt search.

    Topify’s Visibility Tracking monitors how often your brand gets mentioned across ChatGPT, Perplexity, Gemini, and Google AI Overviews. Its Source Analysis shows which domains AI platforms are citing when they recommend brands in your category, so you can identify exactly where to build presence. And its Competitor Monitoring lets you see which rivals are being recommended in prompts where your brand should be.

    The shift isn’t theoretical. It’s measurable, if you have the right instruments.

    Why Traditional SEO Dashboards Can’t Track Prompt Search

    Most marketing teams still rely on dashboards built for keyword search: rankings, click-through rates, organic sessions, and conversion paths that start with a Google query.

    None of these metrics capture what happens in prompt search.

    When a user asks ChatGPT for a recommendation and gets a direct answer, there’s no click to track. No session to attribute. No landing page to measure. The brand either showed up in the answer or it didn’t, and the user either followed up or moved on. Traditional SEO tools are blind to this entire layer.

    The gap is especially wide for competitive intelligence. In keyword search, you can check where your competitors rank for target keywords. In prompt search, you need to know which competitors are being named in AI responses to prompts your buyers actually ask, across multiple platforms, with enough frequency to be statistically meaningful.

    Topify was built for this exact problem. It combines Visibility, Sentiment, Position, and Source data across AI platforms into a single view. In practice, that means you can spot a drop in ChatGPT mentions, trace it back to a competitor gaining ground on a specific prompt cluster, and see which sources the AI started citing instead of yours, all from one dashboard. If you’re ready to see where your brand stands in AI search, you can get started here.

    Conclusion

    The shift from keyword search to prompt search isn’t coming. It’s here. Over 900 million people use ChatGPT weekly. Almost 40% of consumers start searches with AI. And the prompts they type bear little resemblance to the keywords marketers have been optimizing for.

    The brands that win in this new environment aren’t the ones with the highest domain authority or the most backlinks. They’re the ones AI systems choose to name when a user asks a specific, nuanced question. Building that kind of visibility starts with understanding which prompts matter in your category, tracking how AI engines currently answer them, and creating the kind of content that earns a mention in a synthesized, three-to-five-brand response.

    Keyword search isn’t going away. But if it’s the only layer in your strategy, you’re optimizing for a channel that’s handling a shrinking share of how people find, evaluate, and choose brands.

    FAQ

    Q: What is prompt search? 

    A: Prompt search refers to the way users query AI-powered platforms like ChatGPT, Perplexity, and Google Gemini using natural-language sentences or questions instead of short keyword fragments. Unlike traditional search, prompt search involves full context (use case, constraints, preferences) and returns a synthesized answer rather than a list of links.

    Q: Is prompt search replacing keyword search? 

    A: Not entirely, but the two are diverging fast. Google still processes billions of keyword searches daily, and traditional SEO remains valuable. However, a growing share of product research and discovery is shifting to AI platforms where prompt-based queries dominate. The smartest approach is optimizing for both.

    Q: How do I find what prompts users are asking about my brand? 

    A: Start with real customer language from sales calls, support tickets, and community forums. Then use tools like Topify’s High-Value Prompt Discovery, which surfaces the actual AI prompts driving brand mentions and recommendations in your category across ChatGPT, Perplexity, Gemini, and Google AI Overviews.

    Q: Can I optimize for prompt search and keyword search at the same time? 

    A: Yes, and you should. The foundation is similar: create high-quality, authoritative content that clearly answers real questions. The difference is scope. Keyword SEO focuses on matching specific terms. Prompt search optimization requires broader topical coverage, structured claims, third-party validation, and cross-platform visibility tracking to ensure AI systems include your brand in synthesized answers.

    Read More