Category: Article

  • Does Claude Fable 5 Recommend Your Brand? Here’s a Free Check

    Does Claude Fable 5 Recommend Your Brand? Here’s a Free Check

    A prospect used to open Google, type your category, and scan a page of links until they found you. Now they open Claude, ask for the best option in your space, and read a short answer that names three brands. If yours isn’t one of them, the conversation is over before you knew it started. Your keyword rankings won’t flag this, because they were never built to measure what a model chooses to say out loud.

    Why Claude Fable 5 Changes Who Gets Recommended

    Claude Fable 5 is Anthropic’s most capable widely released model, built for long-horizon, autonomous research work. It doesn’t hand back ten blue links and let the user sort it out. It reasons across sources, cross-checks them, and returns a shortlist of named brands.

    That matters more every month. Claude’s share of AI answers grew 64x over the tracked period, overtaking Perplexity in March 2026. The audience asking Claude “who should I use” is no longer a rounding error.

    Here’s the part most teams miss. The shift isn’t from ranking lower to ranking higher. It’s from being listed to being named.

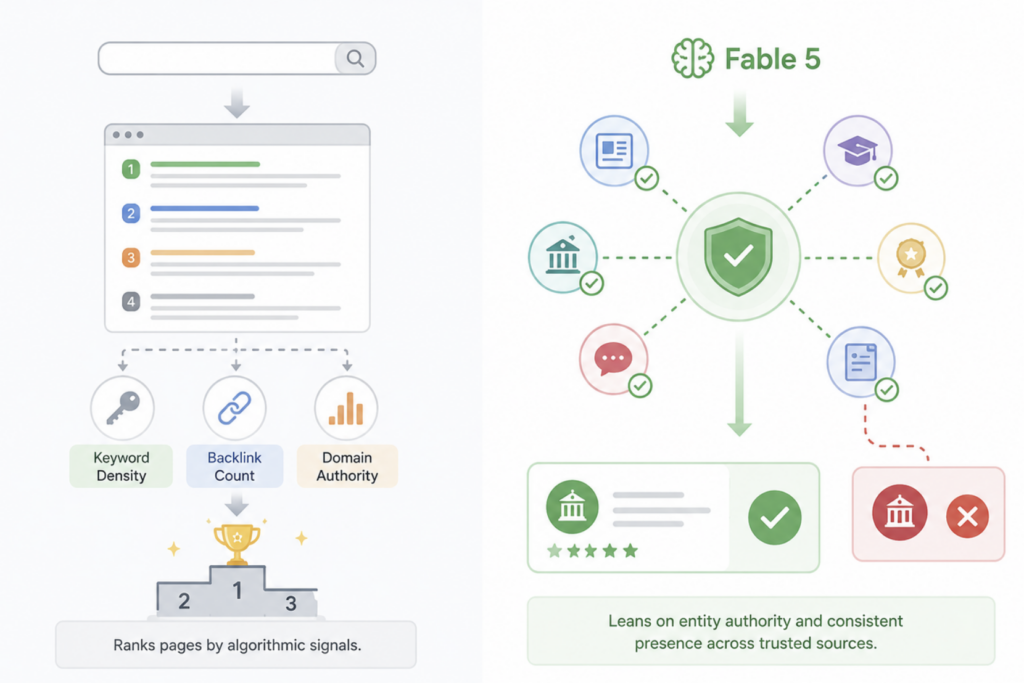
    Fable 5 also decides differently than a search engine. It leans on entity authority and how consistently your brand shows up across trusted third-party sources, not on keyword density or raw backlink counts. If the model can’t corroborate your brand across several reliable domains, its verification loop tends to drop you as unconfirmed. A high Google ranking doesn’t buy you a seat at that table.
    The Blind Spot: Your SEO Metrics Can’t See AI Brand Visibility

    Most marketing teams are measuring the wrong surface. Rank trackers tell you where a page sits in a list of links. They say nothing about whether your brand appears inside an AI-generated answer.

    The gap is wider than it looks. A 2026 local visibility study found AI platforms recommend a tiny slice of the businesses that win in traditional search: 1.2% through ChatGPT and 11% through Gemini, against 35.9% appearing in Google’s local 3-pack. By that measure, AI visibility runs three to 30 times harder to earn than a strong local ranking.

    The click is disappearing too. Up to 83% of AI-generated answer queries get resolved on the results page without a visit to any website. So even a page that ranks well can go completely unseen if the model summarizes the answer and never cites you.

    And the two disciplines have quietly decoupled. Strong search rankings no longer predict AI visibility; the correlation between the two has fallen sharply in a single year. Good SEO is not automatically good GEO.

    You can’t optimize what you can’t see.

    What “Does Claude Recommend Your Brand” Actually Means

    Treat “recommended” as a scale, not a yes-or-no. A model can name you often but describe you as the budget option. It can mention you once and bury you at the bottom of a five-brand list. AI brand visibility is really a bundle of signals, and each one moves independently.

    DimensionWhat it measures
    Mention frequencyHow often your brand surfaces in model answers
    Sentiment and contextWhether you’re framed as a leader or an also-ran
    Comparative positionWhere you land in a ranked list of options
    Citation densityHow many high-authority sources tie you to your category
    Source authorityThe quality of the domains the model relies on to cite you
    Entity consistencyHow cleanly your brand data reads across the web
    Answer relevanceHow directly you match the specific question asked

    This is also why a single flattering answer can mislead you. Fable 5 builds its picture of your brand from repeated corroboration. Industry estimates put the bar around 250 unique mentions for a model to form a stable understanding of who you are. One mention today doesn’t make you a trusted entity tomorrow.

    How to Check for Free in Under Three Minutes

    You don’t need a contract or a sales call to find out where you stand. Topify runs a free GEO score check that takes about three minutes and no signup.

    The flow is simple. You enter your domain, and the tool returns a GEO score with a baseline read on how visible your brand is across AI answers. It’s the fastest way to turn a vague worry (“are we even showing up?”) into a number you can act on.

    Run it. Read the score. Then decide what’s worth doing next.

    Think of the score as a diagnostic, not a verdict. A low number doesn’t mean your brand is broken; it usually means the corroborating signals AI models look for aren’t in place yet. That’s fixable, but only once you know it’s the problem.

    From a One-Time Score to Ongoing AI Brand Visibility Tracking

    A single score is a snapshot, and AI search doesn’t hold still. Across major platforms, 40% to 60% of cited sources change from one month to the next. A source that anchored your visibility in June can quietly drop out in July, and your score falls without any change on your end.

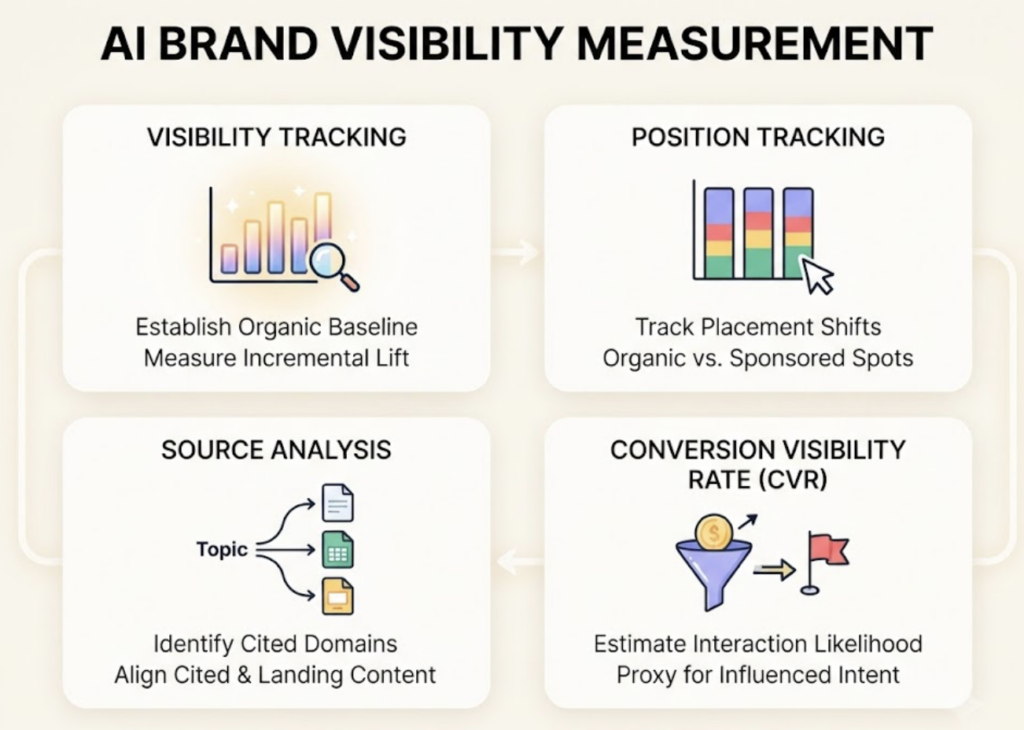
    That volatility is the argument for continuous monitoring over one-off audits. This is where Topify’s Comprehensive GEO Analytics picks up after the free check. It tracks your brand across ChatGPT, Perplexity, Gemini, and Claude, and it separates the signals that a rank tracker collapses into one: mention frequency, sentiment, and comparative position, each monitored over time rather than sampled once.

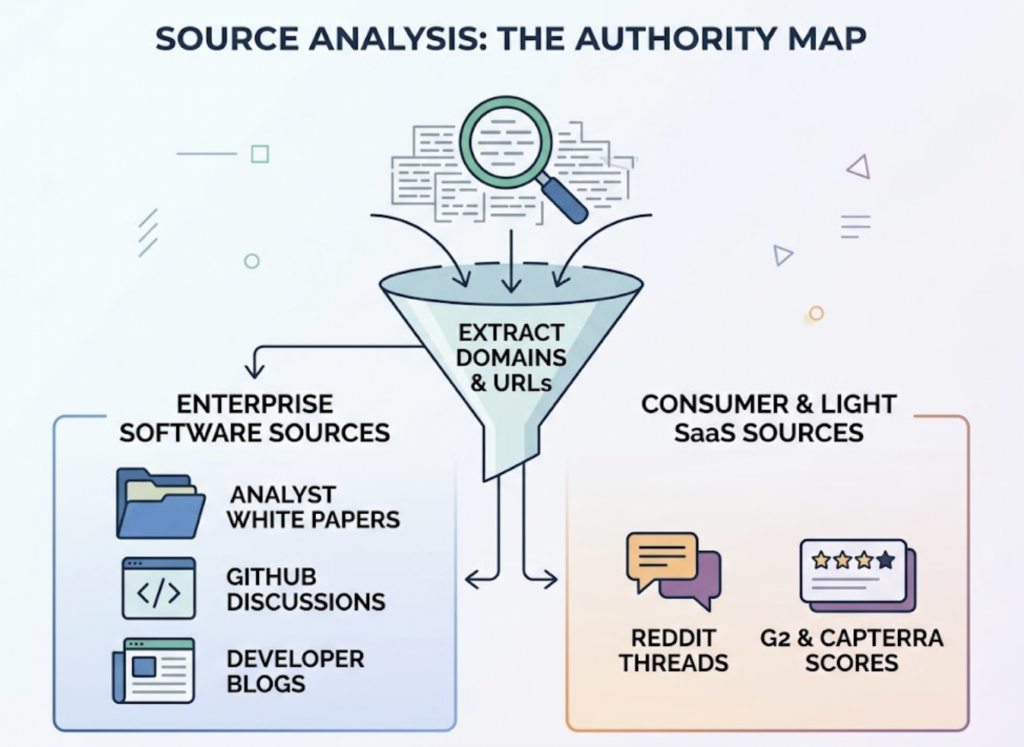
    The Source Analysis layer is what makes a score drop diagnosable. Instead of telling you your visibility fell, it reverse-engineers the exact domains and URLs the models cite in your category. In practice, that means you can catch a dip in Claude mentions, trace it to a specific third-party source that stopped referencing your brand, and know precisely which relationship or piece of content to rebuild. Competitor benchmarking sits alongside it, so you can see which rival the model started naming in your place and why.
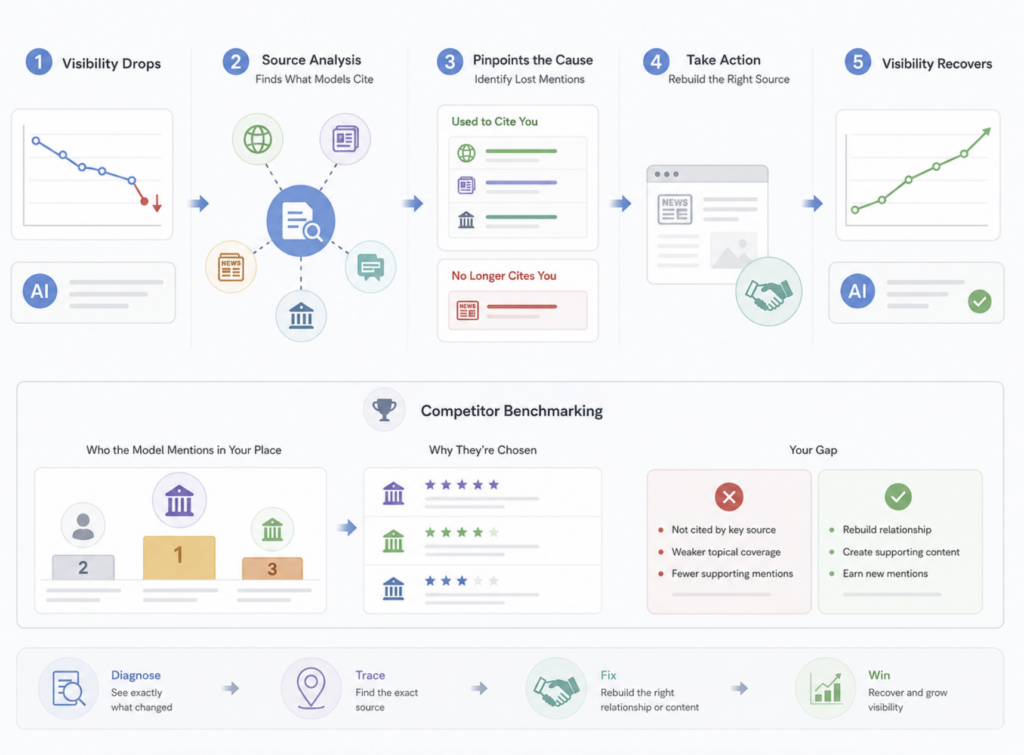
    That’s the difference between knowing you slipped and knowing what to fix. A dashboard full of numbers is easy to build. Connecting a number to a cause is the harder problem, and it’s the one that actually changes what your team does on Monday.

    What to Do With the Results

    A GEO score is only useful if it points somewhere. Once you have yours, a few moves tend to matter most.

    Start with your source footprint. If the models aren’t citing you, the fix is usually more corroboration across trusted third-party domains, not another page on your own site. Trade media, niche communities, and professional directories carry weight that a company blog can’t.

    Then structure content for extraction. AI models pull cleanly from tables, lists, and direct fact statements, and far less easily from long narrative prose. Rewriting a dense explainer into scannable, fact-first blocks often lifts citability on its own.

    Finally, watch position, not just presence. Being named fifth in a list of five is barely better than being absent, so track where you land relative to competitors and treat slippage as an early warning. If you want to start tracking rather than guessing, get started with Topify and set a baseline you can measure against.

    Conclusion

    Your prospects are already asking Claude Fable 5 which brand to choose. The only open question is whether the model names you, how it describes you, and where you sit against your competitors, none of which your ranking reports can answer. Run the free GEO score check first to see where you actually stand. If the number gives you a reason to worry, that’s the moment to move from a one-time snapshot to ongoing AI brand visibility tracking, while the answer box in your category is still up for grabs.

    FAQ

    Does Claude Fable 5 actually recommend specific brands? 

    Yes. When a user asks for the best option in a category, Fable 5 reasons across sources and returns a shortlist of named brands rather than a page of links. Whether your brand appears depends on how consistently AI models can corroborate it across trusted third-party sources.

    How is checking AI brand visibility different from checking my Google ranking? 

    A Google ranking tells you where a page sits in a list. AI brand visibility tells you whether your brand is mentioned inside an AI answer, how it’s described, and where it ranks against competitors. Since up to 83% of AI answers end without a click, ranking well and being cited are now two separate things.

    Can I check if Claude recommends my brand for free? 

    Yes. Topify’s free GEO score check returns a baseline read on your AI visibility in about three minutes with no signup, so you can see where you stand before committing to anything.

    How often should I track my brand’s visibility in Claude and other AI tools? 

    Often enough to catch change, because 40% to 60% of the sources AI models cite shift month to month. A one-time score gets stale fast, so continuous monitoring is the only way to spot a drop early and trace it to a cause.
    Read More

  • How to Get Your Brand Cited by Claude Fable 5

    How to Get Your Brand Cited by Claude Fable 5

    You’ve spent months getting your content cited in ChatGPT and Perplexity answers. The tactics worked: clean headings, a few stats, a page that ranked. Then Claude Fable 5 launched, and the same content stopped surfacing. Fable 5 doesn’t skim and summarize. It reads across dozens of sources, cross-checks them against each other, and drops anything it can’t verify. The bar for getting cited just moved, and most of the old playbook doesn’t clear it.

    Why Claude Fable 5 Rewrites the Rules for Getting Cited

    Claude Fable 5 isn’t a bigger version of the chat model you already optimized for. It’s a long-horizon reasoning model that behaves less like a search box and more like a junior analyst. Before it answers, it explores multiple approaches, checks its own reasoning, and hunts for edge cases.

    That changes what “getting cited” means. Older models often paraphrased whatever ranked well. Fable 5 treats each source as raw material to be verified, not a fact to be trusted on sight.

    Here’s the gap most brands miss. Ranking in search gets you into the model’s reading pool. It doesn’t get you into the answer.

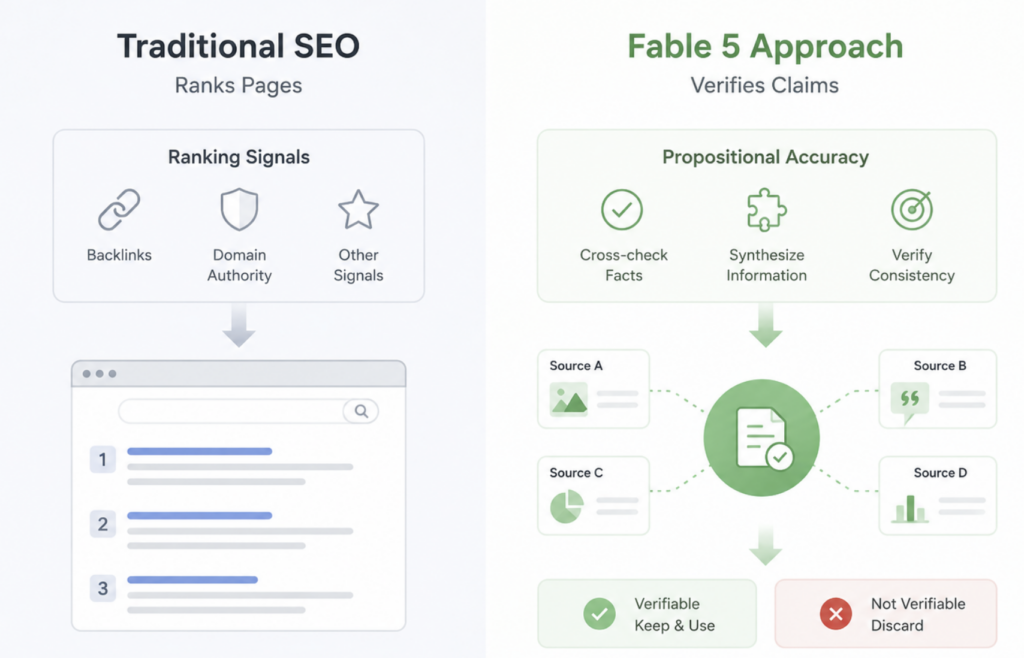
    Traditional SEO leans on ranking signals like backlinks and domain authority. Fable 5 leans on propositional accuracy: whether a specific claim holds up when checked against everything else it just read. Content that appears in results but carries no verifiable data tends to get read and then quietly discarded.

    How Claude Fable 5 Decides Which Sources to Cite

    To optimize for Fable 5, you have to understand what its reasoning loop is actually filtering for. Three patterns show up consistently in how frontier models handle citations.

    The first is consensus. When a claim shows up across multiple independent, high-authority domains, the model treats it as closer to ground truth. Research on citation behavior found that when multiple independent models cite the same work, perceived accuracy runs 95.6% higher. A single “rank #1” page rarely carries that weight on its own.

    The second is how the model resolves conflict. When Fable 5 hits contradictory data, it doesn’t just pick the top result. It applies a weighted consensus that favors positions repeated across trusted, independent sources. Being loud in one place loses to being consistent across many.

    The third is structure. Models cite passages, not pages. They pull the specific chunk of text that satisfies a logical need in their response, and they strongly prefer chunks that are easy to parse.

    That’s the real unit of GEO now: the passage, not the URL.

    Step 1: Structure Content So Claude Fable 5 Can Extract and Trust It

    Your first job is to make content agent-readable. That means shifting from keyword-dense copy to data-dense architecture, where every section answers a concrete question and backs it with something checkable.

    Start with your headings. Write them as the questions a user would actually ask. “What are the core benefits of X?” gives the model a clean retrieval target. “The Benefits” gives it nothing to match against.

    Then serialize your data. Comparative prose is hard for a model to extract cleanly, and it tends to lose the pieces. Structured formats hold together far better: analysis of citation patterns suggests tables, numbered steps, and lists get pulled with markedly higher reliability than the same information buried in paragraphs.

    There’s a sequencing trick here too, sometimes called baseline-expand. Confirm the facts the model already believes, then extend them with something new. A passage that first aligns with established knowledge, then adds proprietary data or original research, gives Fable 5 a reason to cite you specifically instead of a generic source.

    Practical version: lead each section with the accepted answer, then add the number, benchmark, or finding only you can provide.

    Step 2: Build Cross-Source Corroboration Around Your Claims

    One authoritative page on your own domain isn’t enough anymore. Because Fable 5 validates by cross-referencing, a claim that lives in exactly one place looks unverified, no matter how strong that page is.

    The fix is what you might call echo-and-expand. Your key brand claims and proprietary data should show up across several independent channels, not just your homepage. Think third-party technical blogs, industry directories, expert forums, and analyst mentions. Each independent echo raises the odds your claim survives the model’s cross-check.

    Anchor those echoes to domains the model weights heavily. Established industry journals, .edu and .gov sources, and recognized reference sites act as truth anchors in a reasoning loop.

    The trade-off is that this takes longer than publishing one great page. But it’s what separates a claim Fable 5 repeats from one it ignores.

    Bottom line: if your most important stat exists in only one location on the web, you’ve built a single point of failure into your AI visibility.

    Step 3: Track Whether Claude Fable 5 Is Actually Citing Your Brand

    Here’s the problem with everything above. You can’t see it working. Fable 5’s answers are generated on the fly, vary between sessions, and shift as its safety classifiers and rerouting logic evolve. Spot-checking by asking the model a few questions yourself isn’t a strategy. It’s a guess.

    This is where measurement stops being optional. To manage citation authority, you need continuous telemetry on what the model pulls into its context and what it says about you.

    For teams tracking this at scale, Topify is built around reverse-engineering AI citations rather than guessing at them. In practice, that means three connected views. Visibility tracking monitors how often your brand gets mentioned across Claude, Perplexity, and ChatGPT, so you can tell whether a content change moved the needle. Source analysis reverse-engineers the exact domains and URLs the model pulls into its context, which shows you whether Fable 5 is citing your page or a third party echoing your claim. Competitor benchmarking flags when a rival captures a citation slot in a reasoning thread you used to own, so you can react while it still matters.

    The shift is from rank-tracking to share of citation. Google rankings tell you where a page sits. Citation analytics tell you whether the model is actually building its answer on you. If you want the full picture of how these tools compare, this breakdown of AI citation tracking platforms in 2026 is a useful starting point.

    You can get started with Topify on a single brand before scaling the workflow across clients.

    The Mistakes That Keep Brands Out of Fable 5’s Answers

    Most brands that stay invisible to Fable 5 make the same handful of errors.

    They optimize only for ChatGPT and assume it transfers. It doesn’t. A deep-research model applies a stricter verification bar, so surface-level content that passed before now fails.

    They publish claims with no corroboration. A bold stat on one page, echoed nowhere else, reads as unverified and gets skipped during cross-check.

    They treat GEO as a one-time project. Fable 5’s citation patterns move week to week, so a single optimization pass ages fast.

    And they measure the wrong thing. Watching your keyword rank tells you nothing about whether the model mentions you. Rank and mention are separate signals, and only one of them shows up in the answer.

    Fix those four, and you’ve cleared most of the field.

    Conclusion

    Getting cited by Claude Fable 5 isn’t about ranking higher. It’s about becoming a verifiable, structured, corroborated source the model can trust inside a multi-step reasoning loop. Structure your content for extraction. Echo your key claims across independent, high-authority domains. Then measure share of citation continuously, because a model this dynamic can’t be tracked by hand. Start with one high-value topic, confirm whether Fable 5 is pulling you into its answers, and expand from there. The brands that treat citation authority as a measurable channel, not a lucky break, are the ones that show up.

    FAQ

    Does Claude Fable 5 actually cite sources in its answers? 

    Yes. Fable 5 reads and cross-checks multiple sources during its reasoning process, and it favors claims corroborated across independent, high-authority domains. Its citations reflect what survived verification, not just what ranked.

    How is getting cited by Fable 5 different from ranking on Google? 

    Google rewards ranking signals like backlinks and domain authority. Fable 5 rewards propositional accuracy: whether a specific claim holds up when checked against everything else it read. You can rank well and still never be cited.

    How long until content changes show up in Fable 5’s citations? 

    There’s no fixed window, and it varies by topic and how quickly independent sources pick up your claims. Because citation patterns shift week to week, continuous tracking beats a single before-and-after check.

    Can I track my brand’s citations across Fable 5 and other AI models? 

    Yes. Platforms like Topify monitor mentions and source citations across Claude, Perplexity, and ChatGPT in one place, so you can compare share of citation across models instead of spot-checking each one manually.

    Read More

  • How Claude Fable 5 Changes AI Search Visibility

    How Claude Fable 5 Changes AI Search Visibility

    You run a brand query through an AI assistant one week and your company shows up in the answer. You run the same query a month later, after the model behind that assistant gets swapped for a newer one, and you’re gone. Your site didn’t change. The model did.

    That’s the part most brands still miss. AI search visibility isn’t a fixed property of your content. It’s a function of whichever model is reading your content on a given day, and those models are changing faster than most marketing teams can track.

    Claude Fable 5 is the clearest example yet.

    What Claude Fable 5 Actually Is, and Why a Model Jump Matters

    Claude Fable 5 is Anthropic’s first Mythos-class model made available to the public. It launched on June 9, 2026, priced at $10 per million input tokens and $50 per million output tokens, roughly double the rate of Opus 4.8.

    The specs aren’t the interesting part for marketers. What matters is what “Mythos-class” does to how answers get built. Fable 5 is tuned for long-horizon, multi-step reasoning instead of quick lookups, and the capability gap over the previous flagship is wide.

    BenchmarkClaude Fable 5Claude Opus 4.8
    SWE-Bench Pro80.3%69.2%
    FrontierCode29.3%13.4%

    Those numbers, compiled in benchmark testing published by Truefoundry in 2026, represent an 11.1-point jump on SWE-Bench Pro and a 15.9-point jump on FrontierCode. A model that reasons this differently selects sources differently.

    And source selection is where your visibility lives or dies.

    How Deeper Reasoning Rewrites What AI Search Surfaces

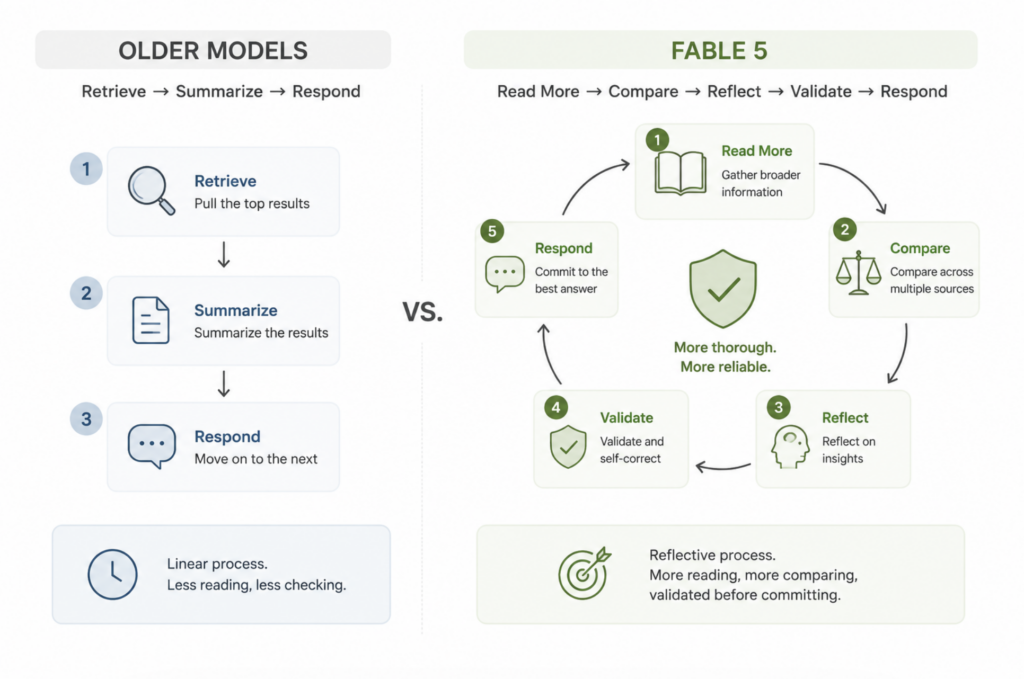
    Older models leaned closer to retrieval: pull the top results, summarize them, move on. Fable 5 moves past straight next-token prediction toward reflection and self-correction. It reads more, compares more, and validates before it commits to an answer.

    That changes the math on AI search visibility. When a model synthesizes rather than retrieves, ranking number one on a traditional results page no longer guarantees you show up in the AI’s answer.

    This gap has a name: ranking–mention separation. Traditional SEO signals like keyword density and backlink volume predict where you land on a search engine results page. They don’t reliably predict whether a reasoning model will cite you.

    Here’s the thing. The stronger the model’s reasoning, the wider that gap tends to get. Fable 5 evaluates information density, clarity, and structural authority, not the classic ranking factors that decades of SEO work were built around.

    The Source-Selection Shift: Who Gets Cited When Models Get Smarter

    Smarter models are pickier about sources. Fable 5’s preference for structurally sound, internally consistent content means it effectively runs its own fact-check before choosing what to reference.

    A few patterns separate how reasoning-heavy models pick citations from how retrieval-first models did it:

    What the model rewardsRetrieval-first modelsReasoning models like Fable 5
    Content densityKeyword coverageOne-shot clarity, high information density
    Source typeWhatever ranksStable, credible references: primary docs, encyclopedic, authoritative
    StructureLoosely weightedHeavy weight on internal consistency

    There’s a concentration effect on top of this. AI citation research indicates that a small set of top domains accounts for a disproportionate share of all citations across many AI surfaces, which makes visibility more winner-takes-most than a search results page ever was.

    If your content is fragmented, or takes several clicks to parse, a model optimized for one-shot understanding tends to skip it. Clean structure isn’t a nice-to-have anymore. It’s the entry ticket.

    Why One-Time Optimization Fails When Models Change This Fast

    Fable 5’s own timeline makes the case better than any argument could. It launched June 9, got suspended three days later over a safeguard issue, and came back on July 1. Nineteen days, one full cycle of appear, vanish, reappear.

    Now picture your brand’s visibility riding on top of that. A model update or a safety-policy tweak can reshuffle which sources get cited, with no warning to you.

    That’s the obsolescence trap. Optimization tuned to one model version risks going stale the moment that version changes.

    Static audits can’t catch this. By the time you rerun a quarterly SEO check, the model behind the answer may already be two iterations ahead. Visibility management has to move from a one-time effort to a continuous, telemetry-based process.

    Tracking AI Search Visibility Across Models, Not Just One

    The fix isn’t optimizing harder for Fable 5. It’s building a way to see visibility shift in real time, across every model your audience actually uses.

    That’s the problem Topify is built for. Topify tracks how AI systems mention and cite brands across ChatGPT, Gemini, Perplexity, Claude, and other major engines, so a change in any single model shows up as a measurable movement rather than a mystery you notice too late.

    Its Comprehensive GEO Analytics covers seven metrics: visibility, sentiment, position, volume, mentions, intent, and CVR. Two of them earn their keep the moment a model like Fable 5 lands. Source Analysis reverse-engineers the exact domains an AI cites for your brand keywords, so you can tell whether Fable 5’s stricter source selection dropped you or a competitor. Competitor Benchmarking shows how a model shift changes share of voice, catching the moment a rival starts winning citations you used to own. Together they turn a model swap from an invisible event into a line on a chart.

    The point isn’t a one-time report. It’s telemetry.

    Where to Start Before the Next Model Lands

    You don’t need to predict the next release. You need a baseline you can measure against when it arrives.

    Start with three moves. Establish your current visibility across the major AI engines. Lock in the core prompts where your brand should appear. Track which domains those answers cite today. A free GEO score check gives you a starting read without a signup.

    When the next Mythos-class model ships, you’ll see the shift in your own numbers instead of hearing about it from a client.

    Conclusion

    Claude Fable 5 isn’t the endpoint. It’s a signal. Each jump in reasoning capability quietly rewrites which brands AI search chooses to mention and cite, and the jumps are coming faster.

    The brands that stay visible won’t be the ones that optimized perfectly for one model. They’ll be the ones watching every model, all the time.

    FAQ

    Does Claude Fable 5 have its own search engine? 

    No. Fable 5 is a foundation model, not a search product. Your visibility changes because models like it get integrated into AI assistants and agents that synthesize answers, and those systems decide which sources to cite.

    How is Claude Fable 5 different from Opus 4.8 for AI search visibility? 

    Fable 5 weights deep reasoning and validation more heavily than lighter, faster models. It tends to prefer stable, high-density sources, so it can cite a different set of domains than Opus 4.8 for the same query.

    Do I need to re-optimize my content for every new model? 

    Not for every change. What you need is a baseline visibility measurement that flags when a model update meaningfully moves your citation frequency, so you only act when it actually matters.

    How can I track brand mentions in AI answers across models? 

    Use a cross-model GEO analytics platform that monitors mentions, citations, and share of voice across ChatGPT, Gemini, Perplexity, and Claude, rather than checking each tool by hand.

    Read More

  • AI Citation Share and the Three Levels of AI Visibility

    AI Citation Share and the Three Levels of AI Visibility

    Your brand name shows up in a ChatGPT answer, and the team calls it a win. Then you read the rest of the response. The link under the claim points to a competitor’s blog. The “here’s what I’d recommend” line names them, not you. You were in the room, but someone else closed the deal. Being seen by an AI model, being used as its evidence, and being named as its pick are three separate outcomes. Most tracking collapses them into one, which is why so many brands look visible and still lose the answer.

    Being Seen by AI Isn’t One Thing

    For years, visibility had a simple test: did you rank, yes or no. AI search broke that binary. A model can name your brand, cite a competitor’s page as its source, and recommend a third option, all inside the same paragraph.

    Researchers have started separating these signals. One widely used framework splits AI brand presence into three types: a mention is a plain reference with no evaluation, a citation is a source attribution that signals authority, and a recommendation is an active endorsement. Each one reflects a different decision the model made about you.

    That’s the gap most dashboards still can’t see.

    The three form a funnel. Reach at the top, proof in the middle, endorsement at the bottom. Move up a level and the commercial value climbs with it. The trouble is that the layers don’t move together, so a brand can be strong at one and absent at the next.

    Level 1: Mentions, Where AI Visibility Starts

    A mention means the model knows your brand exists and will say your name when the topic comes up. It’s the floor, not the ceiling.

    The problem is that mentions are cheap. On ChatGPT, nearly every ecommerce brand gets named, around 99.3% inclusion in one analysis, which makes appearing in an answer a low-signal event. When almost everyone shows up, showing up proves nothing.

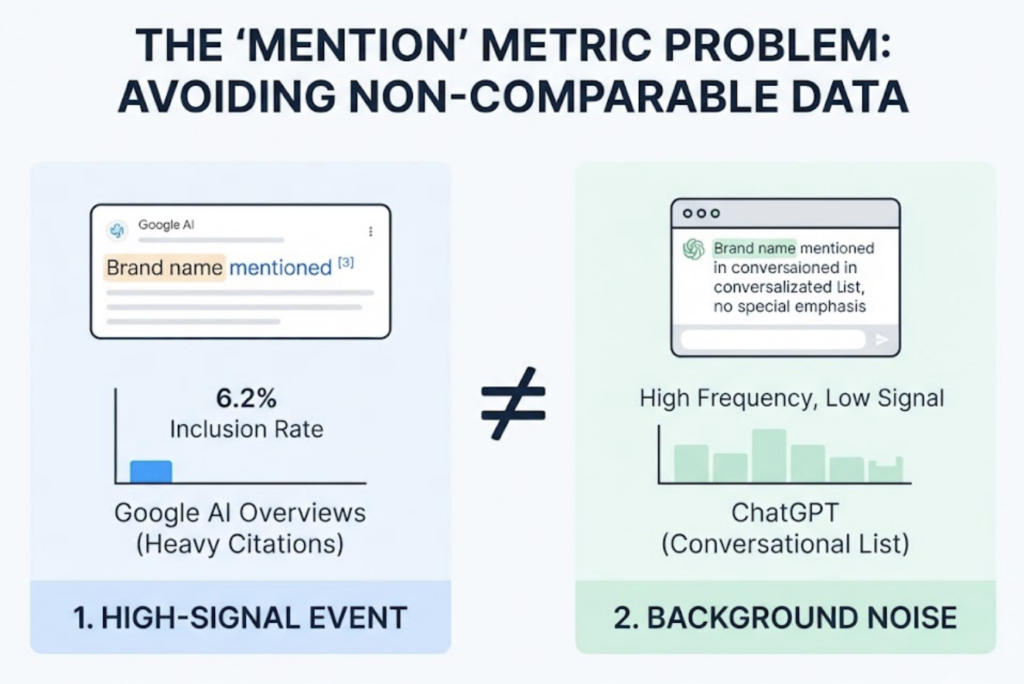
    A mention on one engine also isn’t the same data type as a mention on another. Google’s AI Overviews include a brand in only about 6.2% of responses and lean citation-heavy, so inclusion there is a high-signal event, while inclusion on ChatGPT is close to background noise. Counting both as one “mention” metric compares things that aren’t comparable.

    Mentions also tend to come from training data rather than live retrieval, so they rarely drive traffic and carry no proof the model trusts you. A brand can rack up thousands of neutral mentions and still convert nobody.

    Reach gets you noticed. It doesn’t get you chosen.

    Level 2: Citations and Your AI Citation Share

    A citation is a different kind of signal. Here the model actively pulls your domain in as a source, footnotes it, links it, and stakes part of its answer on your content. That’s a decision about trust, not just recognition.

    The metric for this layer is AI citation share: the percentage of AI answers, across a defined query set, that cite your domain relative to all citations in the pool. The term was coined as the replacement for share of voice and framed as the AI-era market share metric. “Share of citation” and “citation share” point to the same thing.

    The math is straightforward. Citation slots earned divided by total slots tracked, times 100. Run 30 queries across four engines, earn 14 citations while competitors earn 52, and your citation share lands at 21%.

    What counts as a strong number depends on the category. In emerging categories with a handful of credible brands, 20 to 30% is leadership territory, while in crowded categories 5 to 10% can be solid if the query set is large. The trend line matters more than the absolute figure.

    AI Citation Share vs. Share of Voice

    Old share of voice counted impressions, and multiple brands could sit on the same magazine page without displacing each other. Citation share doesn’t work that way.

    AI answers typically cite between three and eight sources per query, so the field is narrow. If you’re cited, a competitor usually isn’t. That makes citation share a zero-sum, competitive metric, not a vanity count.

    It also decouples from search rank. One analysis found 80% of the sources AI cites don’t appear in Google’s top 10 for the same query, which means your SERP position and your AI citation rate measure different realities. Ranking well and being cited well are two separate jobs.

    Level 3: Recommendations, When AI Picks You First

    The top of the funnel is the recommendation. Ask “what’s the best tool for X” and the model names you, unprompted, as the answer. This is the highest-intent signal, because the user asked for a decision and the AI made one.

    The commercial gap between layers is real. AI-referred traffic in one dataset converted at 14.2% versus 2.8% for standard organic, roughly a 5x premium, and that premium accrues to recommended brands, not merely mentioned ones.

    Recognition and recommendation also aren’t the same. An athleisure analysis put it bluntly: New Balance was identified correctly 100% of the time but recommended in only 3.4% of “best athleisure” answers, while Lululemon, with a far weaker Knowledge Graph, appeared in 92.5%. The difference came from third-party citations, not brand recognition.

    Position inside the answer matters too. First-position citations earn four to five times the click-through of fifth-position ones. Being recommended last is closer to being mentioned than being chosen.

    Why AI Citation Share Is the Layer Most Brands Skip

    Recommendations are the goal, but they’re a lagging indicator. You can’t optimize an endorsement directly. Citation share is the lever you can actually pull.

    Here’s the mechanism. Once a model consistently cites your domain as evidence, the odds it promotes you to a recommendation climb. Proof compounds into preference. Skip the citation layer and you’re trying to earn endorsements with nothing underneath them.

    The data backs the sequence. Adding statistics to content improved AI visibility by 41% in the Princeton and Georgia Tech GEO study, the single most effective technique they tested. Pages built on original research get cited at 38 to 65% versus 6 to 15% for standard posts. And branded web mentions correlate 0.66 to 0.71 with AI citation rates, which is why earned authority tends to move the middle layer more than on-page tweaks.

    There’s also a timing argument. Citation concentrates around a small set of sources, so early movers who lock in citation share build positions that compound while later entrants face an established base the engines already trust.

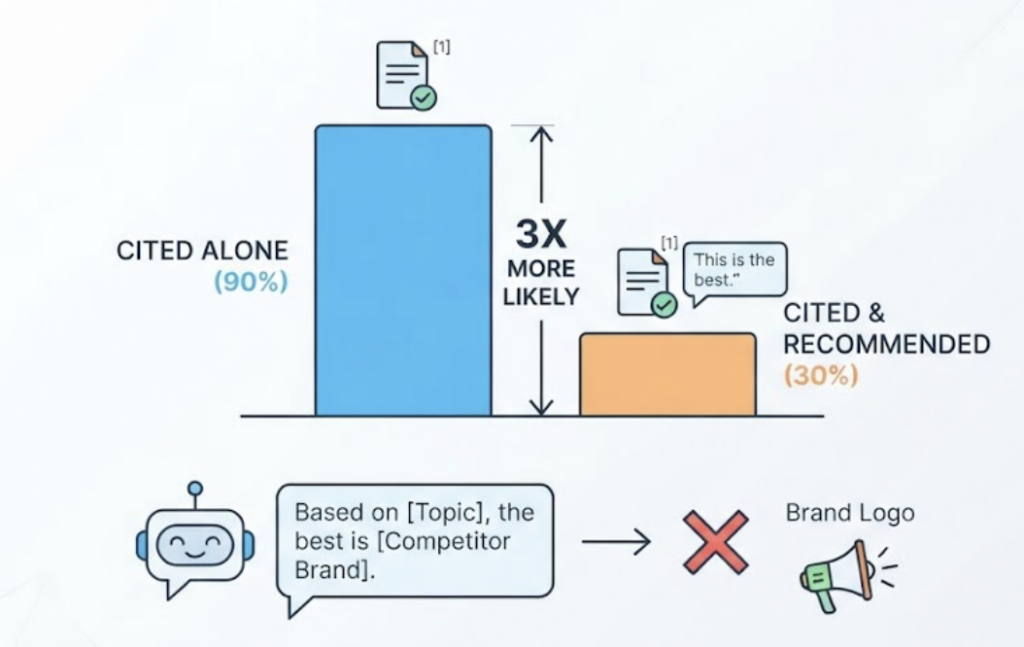
    Most tools stop at Level 1. They report mention counts and call it visibility, which leaves the citation layer, where the real leverage lives, unmeasured. Brands are three times more likely to be cited alone than to earn both a citation and a recommendation, a split that’s invisible if you only track one signal. A brand with strong citations but weak mentions is quietly feeding evidence to answers that recommend someone else.

    How to Track All Three Levels of AI Visibility

    Measuring the funnel means capturing all three signals at once, per platform, and watching how they move against competitors. A single blended number hides more than it reveals.

    That’s the job Topify is built for. Its Comprehensive GEO Analytics reports seven metrics side by side, including mentions, position, and CVR, so the awareness layer, the recommendation layer, and the conversion signal sit in one view instead of three tools. You see not just whether you appear, but whether you’re cited and whether you’re picked.

    For the middle layer specifically, Topify reverse-engineers the exact domains and URLs AI platforms pull from. In practice, that means you can watch your citation share in a category, spot the competitor domain absorbing the authority you’re missing, and trace a drop in ChatGPT mentions back to a source that stopped referencing you.

    Coverage spans ChatGPT, Gemini, Perplexity, DeepSeek, and other engines, which matters because citation patterns diverge sharply across platforms. A 40% share on one engine and 5% on another isn’t noise. It’s an authority gap on a specific model’s evaluation, and it tells you exactly where to spend.

    Start by tracking 15 to 25 buyer-intent queries, run each more than once, and read the trend rather than any single snapshot. Get started with Topify and build the baseline before you optimize anything.

    Conclusion

    Being named by AI is where visibility starts, not where it ends. Mentions give you reach, citations give you proof, and recommendations give you the sale, in that order. AI citation share is the metric sitting between recognition and endorsement, and it’s the one you can influence directly by making your content the source AI trusts. Audit where you stand across all three levels before you decide what to fix. If your brand shows up but never gets cited, you already know which layer needs the work.

    FAQ

    Q: What is AI citation share? 

    A: It’s the percentage of AI-generated answers, across a defined query set, that cite your domain as a source relative to all citations in that set. It’s the AI-era replacement for share of voice, measuring whether engines trust your content enough to build answers on it rather than just naming your brand.

    Q: How is AI citation share different from a mention? 

    A: A mention names your brand with no attribution. A citation means the AI actively used your content as evidence and linked to it. Mentions signal awareness; citations signal authority, and only citations reliably show the model treats your content as trustworthy.

    Q: How do you measure AI citation share across ChatGPT and Perplexity? 

    A: Track a fixed set of 15 to 25 category queries, run each more than once per engine, then divide your brand’s citation slots by the total slots earned across every response. Measure per platform, since engines cite very differently and a blended average hides the gaps.

    Q: Which level matters most, mentions, citations, or recommendations? 

    A: Recommendations carry the most commercial value, but they’re a result you can’t optimize directly. Citation share is the leading indicator you can move, and it’s what tends to pull a brand up into recommendations over time.

    Read More

  • How to Measure AI Citation Share: A Step-by-Step Framework

    How to Measure AI Citation Share: A Step-by-Step Framework

    You can open ChatGPT, type your category question, and count how many times your brand name shows up. That number feels like progress. It isn’t. A mention count tells you AI noticed your brand. It says nothing about whether AI trusted your content enough to use it as a source, or how that stacks up against every other source the model pulled from. Without a denominator, a raw count is a vanity metric. AI citation share is the number that survives a stakeholder review.

    What AI Citation Share Actually Measures

    AI citation share is the percentage of AI citations that point to your domain, measured across a defined set of category-relevant prompts. In plain terms, it’s your slice of the evidence AI engines rely on when they assemble an answer.

    The word “citation” carries the weight here. A citation is a source the model links to or draws from as verifiable evidence. That’s an evidence check, not a recognition check. It’s a different event from your brand name appearing in a sentence.

    Here’s the distinction that trips up most teams. An AI answer can name your brand in prose without citing your website, or cite your URL without naming the brand in the body. These are separate outcomes, and lumping them together hides what’s actually happening in the answer.

    Mentions tell you AI noticed you. Citations tell you AI trusted you.

    AI Citation Share vs. Share of Voice vs. Mention Count

    These three metrics get used interchangeably, and that’s a mistake. Each answers a different question.

    MetricWhat it tracksStrategic goal
    Mention CountHow often your brand name appearsBuilding awareness and presence in the conversation
    Share of VoiceYour footprint relative to competitors in the textMeasuring dominance across brand mentions
    AI Citation ShareHow often your domain is used as evidenceEstablishing your site as a trusted source

    Share of voice is competitive and mention-based. You divide your brand mentions by total mentions across your brand and a chosen competitor set. Citation share is different. Its denominator isn’t mentions, it’s the total pool of sources cited across all domains for your prompt set.

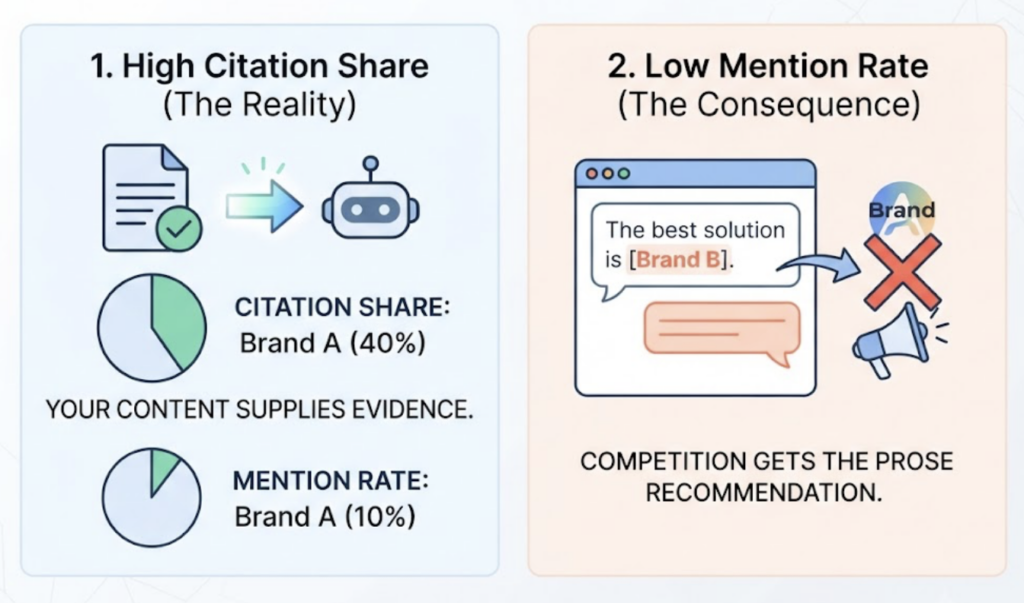
    That gap matters more than it looks. A brand can carry high citation share and low mention rate at the same time. When that happens, you’re effectively subsidizing the competition: your content supplies the evidence, and the model recommends someone else in the prose. Tracking only mentions would leave you blind to that leak.

    Why Citation Share Is the Metric Worth Tracking

    Discovery is moving into the answer itself. AI search visits grew an estimated 42.8% year over year between Q1 2025 and Q1 2026, climbing from 15.6 billion to 27.4 billion. Yet only 14% of marketers track AI citations, even as 43% call AI search optimization a core 2026 priority. The work has outrun the measurement.

    Citation share also connects to money in a way mention counts don’t. AI-referred visitors convert 4.4x better than standard organic traffic, because a user who arrives after an AI cited you as a source has already been pre-qualified. The model answered their question and pointed at your page.

    There’s a structural reason to care too. A CXL study of 100 AI Overview citations found that 55% of cited snippets came from the top 30% of a page. Citations aren’t random. They reward specific, extractable content, which means citation share is a metric you can actually move.

    The Step-by-Step Framework to Measure AI Citation Share

    Measuring AI citation share well means trading one-time snapshots for a repeatable protocol. Here’s the framework.

    Step 1: Define Your Prompt Perimeter

    Select 30 to 50 high-intent, category-specific prompts. The goal is to mirror how buyers actually phrase questions to an LLM, which tends to be conversational and long-tail, not the short-tail keywords you’d feed a traditional rank tracker.

    Anchor these prompts to real buyer questions: comparisons, “best tool for,” alternatives, and how-to queries in your category. This prompt set becomes part of the metric’s definition, so lock it down before you start counting.

    Step 2: Track Every Platform That Matters

    Different engines have different sourcing personalities, and a single-platform view is a biased one. ChatGPT tends to behave like an encyclopedia curator, favoring institutional and well-structured sources. Perplexity leans toward community and real-time validation. Google AI Overviews prioritizes structured, front-loaded answers.

    Your share will move from one engine to the next, so measure each separately, then roll them up. A blended number that hides a zero on one platform is worse than no number at all.

    Step 3: Capture Citations, Not Mentions

    For every answer, log the actual cited domains and URLs, not just whether your brand name appeared. This is where the mention-citation gap becomes visible.

    Record each cited source, tag whether it belongs to you, a competitor, or a third party, and note which prompt produced it. That raw log is what makes the next step possible.

    Step 4: Calculate Share Against the Total Citation Pool

    The formula is straightforward:

    AI Citation Share = (Total citations to your domain ÷ Total citations across all domains in your prompt set) × 100

    A quick example. Say you run 40 prompts across three platforms and collect 500 total citations. Your domain accounts for 60 of them. Your AI citation share is 12%. If your top competitor holds 90 citations, theirs is 18%, and you now have a like-for-like gap to close.

    Normalize against the total citation pool rather than raw counts, since answer lengths and citation density vary across platforms. A percentage keeps the number comparable.

    Step 5: Benchmark Against Competitors and Track Over Time

    A single reading is a snapshot of a moving target. Cited domain sets drift 40% to 60% month over month in active categories. The volatility runs deeper than most teams expect: one citation dataset found that the typical brand loses half its AI citations in about 31 days.

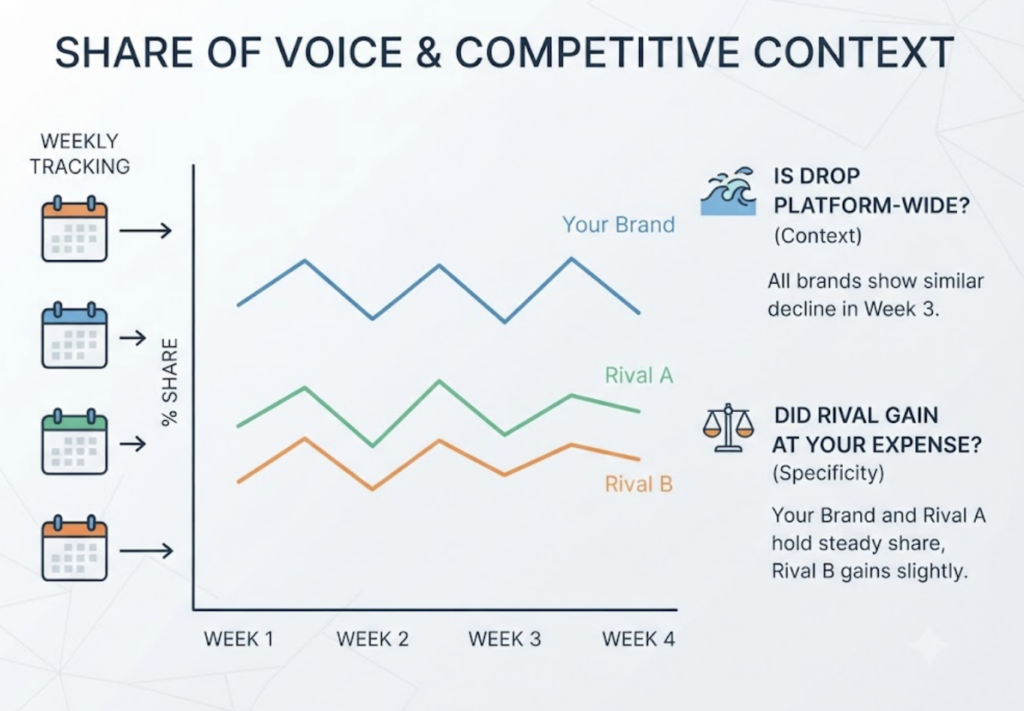
    Always measure your share alongside your top three competitors. That context tells you whether a drop is platform-wide or specific to you, and whether a rival’s gain came at your expense. Weekly tracking is the practical minimum for spotting real trends instead of noise.

    Common Mistakes That Distort Your AI Citation Share

    Even a good framework gets undone by a few recurring errors.

    Platform isolation. Measuring one engine (usually ChatGPT) and calling it “AI” gives you a skewed picture. Multi-platform coverage isn’t optional.

    The mention fallacy. Treating unlinked brand names as citations inflates your perceived authority. A name in prose and a linked source are different events, and only one of them signals trust.

    Small sample sizes. Tracking fewer than 20 prompts produces statistically unreliable data. Aim for 30 to 50 to get a representative read.

    Static snapshots. A one-time audit ignores the fact that AI sourcing is probabilistic and shifts fast. The number you pulled last month is likely already stale.

    Scaling AI Citation Share Measurement with Topify

    Manual tracking works until it doesn’t. Once you’re running 40-plus prompts across three or four engines every week, logging citations by hand hits a complexity ceiling fast. That’s the point where most teams either give up or automate.

    Topify is built for that automation layer. Its Reverse-Engineer AI Citations feature analyzes the exact domains and URLs that AI platforms cite, then shows whether your brand or your competitors dominate those references across a prompt set. In practice, you can see a drop in your citation share, trace it to a specific competitor page that started getting cited instead of yours, and act on the gap, all in one view.

    The competitor benchmarking runs on the same prompt set, so your share always sits next to your rivals’ rather than floating in isolation. And because coverage spans ChatGPT, Gemini, Perplexity, and other major engines, you avoid the single-platform bias that quietly distorts hand-tracked numbers.

    For teams moving from spreadsheets to a repeatable system, that’s the difference between a monthly guess and a weekly trend line. You can get started and baseline your citation share before your next reporting cycle.

    Conclusion

    Counting brand mentions feels productive, but it measures the wrong thing. AI citation share tells you how much of the evidence layer you actually own, which is what decides whether AI recommends you or your competitor. Start by defining a 30 to 50 prompt set, track citations across every engine your buyers use, calculate your share against the full citation pool, and watch the trend rather than any single reading. The brands that win AI search aren’t the ones mentioned most. They’re the ones cited most, consistently, over time.

    FAQ

    Q: How do you calculate AI citation share? 

    A: Divide the total citations pointing to your domain by the total citations across all domains in your prompt set, then multiply by 100. If your domain earns 60 of 500 total citations, your AI citation share is 12%. Always normalize as a percentage so the metric stays comparable across platforms.

    Q: What’s the difference between AI citation share and share of voice? 

    A: Share of voice is usually mention-based, measuring how often your brand name appears relative to competitors. AI citation share is source-based, measuring how often your domain is cited as evidence relative to the total citation pool. A brand can score high on one and low on the other, which is why they should be tracked separately.

    Q: How many prompts do I need to measure AI citation share reliably? 

    A: Aim for 30 to 50 category-relevant prompts. Anything under 20 tends to produce statistically unreliable data, since AI answers fluctuate by phrasing, model version, and sampling randomness.

    Q: How often should I measure AI citation share? 

    A: Weekly at minimum. Cited domain sets drift 40% to 60% month over month, and the typical brand loses half its citations within about a month, so a one-time audit goes stale quickly. Continuous tracking is what turns the metric into a usable trend.

    Read More

  • How to Increase Your AI Citation Share: 7 Tactics That Actually Work

    How to Increase Your AI Citation Share: 7 Tactics That Actually Work

    You ran the AI visibility report. Your brand shows up in maybe two out of ten answers for the queries that matter, while a competitor you rarely think about gets cited in seven. The report gave you the number. It didn’t tell you why, or what to fix first.

    That’s the frustrating part of citation share work. The gap is easy to measure and painful to close, because the levers that move it aren’t the ones traditional SEO trained you to pull. The good news: citation behavior follows patterns. Once you can see which sources AI reaches for and why, raising your share stops being guesswork.

    What AI Citation Share Actually Measures (and Why Rankings Don’t)

    AI citation share is the percentage of AI-generated answers that cite your domain as a source, measured across a defined set of category-relevant queries. It’s a share, not a rank. If a topic generates 100 citations across ChatGPT, Perplexity, and Google AI Overviews, and your domain accounts for 12 of them, your citation share is 12%.

    This is a different metric from the two most teams already track. Share of Voice counts how often your brand gets mentioned across media. Search rankings track your position in a list of blue links. Neither one tells you whether an AI engine treats your page as evidence worth quoting.

    Here’s the distinction that matters most. A brand mention inside AI-generated narrative is often a residue of training data. A citation is a receipt: the engine retrieved your page in real time and attributed a specific claim to it. Being mentioned is not the same as being cited.

    MetricWhat it tracksWhat moves it
    Search RankingsPosition in the results listBacklinks, domain authority, on-page SEO
    Share of VoiceBrand mention volume across mediaPR, social reach, ad spend
    AI Citation ShareShare of AI answers that cite your domainExtractability, semantic relevance, entity coherence

    The reason rankings don’t predict citations is structural. Up to 80% of the sources AI platforms cite don’t appear in the top 10 of traditional search for the same query. Different pipeline, different winners.

    Tactic 1: Find Out Which Sources AI Already Cites in Your Category

    Don’t start by producing more content. Start by reverse-engineering the current citation landscape.

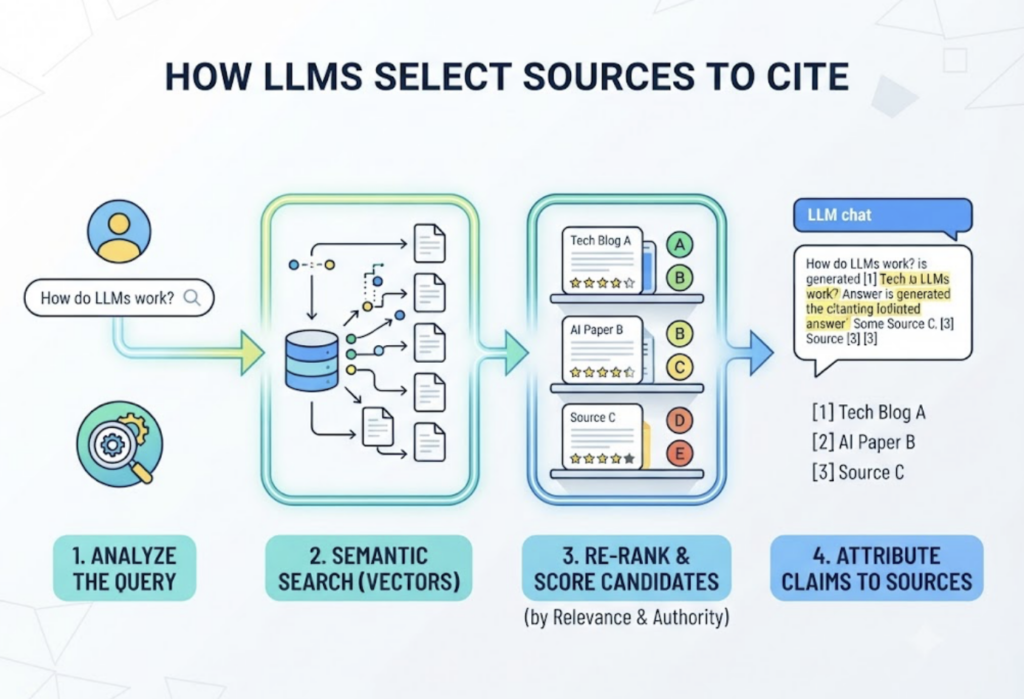
    LLMs don’t rank pages the way Google does. They run a retrieval pipeline: analyze the query, pull semantically close content using vector embeddings, re-rank candidates on structural and authority signals, then attribute claims to the sources they kept. If you want to understand how LLMs choose which sources to cite, you have to look at the sources they’re already citing in your space.

    Pull the domains and URLs that AI engines reference for your top category prompts. Look for concentration. In most categories, a small set of pages absorbs the majority of citations, and they usually share a structure worth copying.

    This is where a citation-source view earns its keep. Topify includes a Source Analysis function that reverse-engineers the exact domains and URLs AI platforms cite, so you can see whether you or your competitors dominate those references before you write a single new sentence. Map the landscape first. Everything after this tactic is a response to what you find.

    Tactic 2: Structure Content the Way LLMs Extract It

    Extractability is the single biggest lever most teams ignore. An engine can only cite what it can pull cleanly out of your page without losing the meaning.

    Lead with the answer. Put the core response in the first 40 to 75 words of a section, using a simple pattern: define the entity, answer the question directly, then add supporting evidence. Burying the answer under three paragraphs of setup is how good content goes uncited.

    Then break the body into small, self-contained blocks. Two to four lines each, written so a model can quote the block without needing the surrounding context to make sense.

    Format for machines as well as people. Comparison tables, numbered lists, and clear bullet points give engines discrete, quotable units. Structured formats like tables can lift citation rates by up to 2.5x over the same information delivered as prose. Same facts, very different pickup.

    Tactic 3: Earn Citations From Sources AI Already Trusts

    LLMs build evidence graphs to resolve contradictions between sources. When two pages disagree, the engine leans toward the one that’s corroborated elsewhere and broadly recognized.

    That produces a systematic bias toward third-party, earned media. Industry publications, well-cited research, and active community forums tend to get pulled more often than a brand’s own marketing pages making the same claim. The engine reads independent corroboration as a trust signal.

    So a real citation strategy isn’t only about your own site. It’s about getting your data, definitions, and point of view embedded in the sources AI already reaches for. A single stat cited in a respected industry report can do more for your citation share than ten blog posts on your own domain.

    Tactic 4: Write for the Prompt, Not Just the Keyword

    Keywords are how people searched Google. Prompts are how people talk to AI, and they carry more intent, more context, and usually a follow-up.

    Match that. Use question-style headings that mirror the exact phrasing a user would type, and answer each one as a clean, standalone unit. Applying FAQPage schema to genuine question-and-answer pairs helps here, because engines frequently pull from structured segments that offer a clear, extractable factual unit.

    Then anticipate the second question. Someone asking how to increase AI citation share will almost certainly wonder how citation share differs from share of voice, or how long improvements take to show up. Cover the chain, not just the entry point, and you become the source that answers the whole conversation.

    Tactic 5: Keep Your Facts Fresh and Consistent Everywhere

    Contradictory or stale information gets down-weighted. If your homepage says one thing, a directory listing says another, and a two-year-old post says a third, the engine has no stable version of your brand to trust.

    Entity coherence fixes this. Define your brand, your category, and your key facts the same way across every platform you appear on: your site, press releases, industry profiles, and social. Consistency lets the model validate your authority instead of hedging around it.

    Freshness compounds the effect. Update your highest-priority pages on a regular cadence so the numbers, product details, and claims stay current. Facts drift, and so does model behavior.

    Tactic 6: Measure Your AI Citation Share Before and After Every Change

    You can’t improve what you don’t baseline. And manual spot-checks won’t cut it, because AI responses are probabilistic: ask the same question twice and you may get two different source sets.

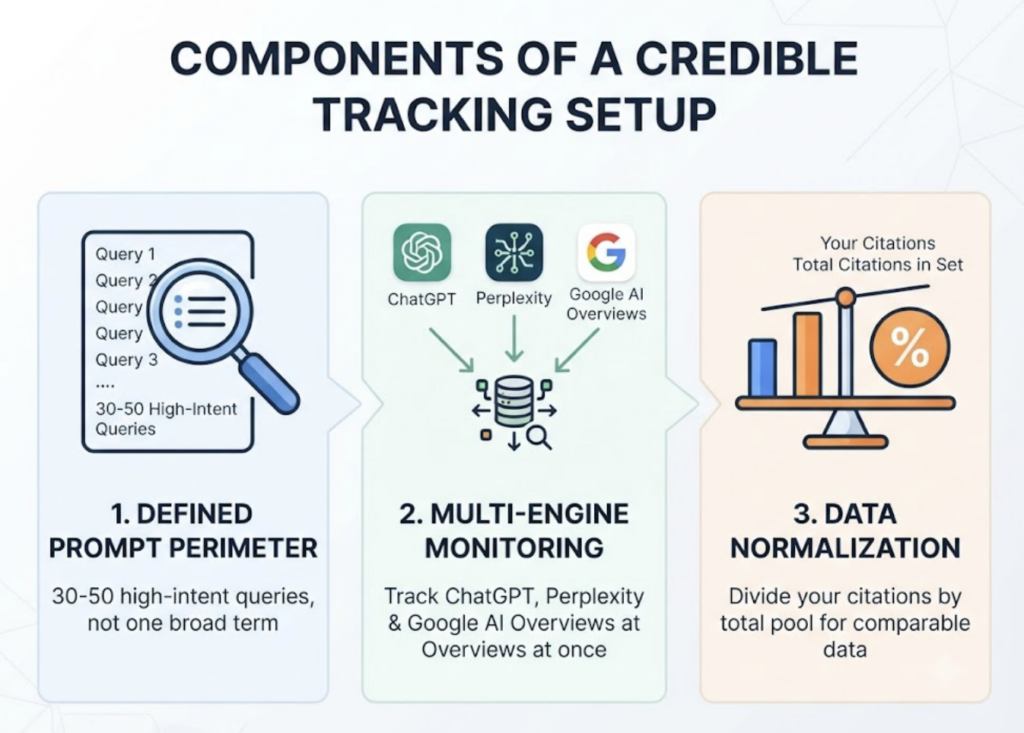
    A credible tracking setup does three things. It uses a defined prompt perimeter of 30 to 50 high-intent queries rather than one broad term. It monitors ChatGPT, Perplexity, and Google AI Overviews at once, since each engine sources differently. And it normalizes the data by dividing your citations by the total pool of citations in the set, so the number holds up across platforms.

    This is measurement work, not intuition. Topify’s Visibility Tracking quantifies your citation share across major AI platforms, and its Competitor Benchmarking shows how much of the pool each rival is taking. Run the baseline, ship a change, then re-measure so you can attribute movement to the specific tactic that caused it. Ship. Measure. Attribute.

    Tactic 7: Take the Gaps Your Competitors Left Open

    Not every prompt in your category is contested. Some high-intent questions get thin, generic AI answers because nobody has published a genuinely citable source yet.

    Those gaps are the fastest wins. Find the prompts where the current citations are weak, off-topic, or dominated by a single aging page, and build the answer-first, well-structured resource that engine has been waiting for. You’re not fighting an entrenched competitor there. You’re filling a vacuum.

    Prioritize by data, not by hunch. The prompts with high intent and weak incumbent citations should sit at the top of your content queue, ahead of the ones where a strong competitor already owns the reference.

    Conclusion

    Low citation share is rarely a content-volume problem. It’s a signal that you’re not showing up at the citation layer, where extractability, corroboration, and consistency decide who gets quoted. The teams that win treat their content as a source to be reused, not a page to be ranked.

    Start narrow and sequence it. Baseline your share against your top three competitors, reverse-engineer the pages AI already cites, fix structure and consistency on your highest-intent pages, then re-measure every couple of weeks to account for model drift. If you want the tracking and source analysis in one place, you can get started with Topify and see where your share stands before you change anything.

    FAQ

    Q: What’s the difference between AI citation share and share of voice? 

    A: Share of voice measures how often your brand is mentioned across media. AI citation share measures how often AI engines cite your domain as a source in their answers. A mention is often a byproduct of training data, while a citation is a real-time retrieval that treats your page as evidence.

    Q: How long does it take to improve AI citation share? 

    A: It varies by category and how competitive the citation landscape is. Structural fixes like answer-first formatting and tables tend to show up faster than authority-based gains, which depend on earning references from trusted third-party sources. Because models update frequently, treat improvement as an ongoing cadence rather than a one-time project.

    Q: Do I need to track every AI platform separately? 

    A: Yes, at least the major ones. ChatGPT, Perplexity, and Google AI Overviews use different sourcing logic, so a source that dominates one may barely appear in another. Tracking them together and normalizing by the total citation pool gives you a share number you can compare across platforms.

    Q: Is low citation share a content problem or an authority problem? 

    A: Usually both, in that order. Extractability and structure are the first fixes because engines can’t cite what they can’t cleanly parse. Once your pages are citable, corroboration and entity consistency across trusted external sources determine how often you actually get chosen.

    Read More

  • Should You Buy ChatGPT Ads? A Decision Framework

    Should You Buy ChatGPT Ads? A Decision Framework

    The proposal is sitting in your budget deck: test ChatGPT ads this quarter. Your CMO wants an answer by Friday. The pitch sounds compelling, a brand-new ad surface with billions of daily prompts and no minimum spend since May. But you’ve also seen the numbers floating around: click-through rates under 1%, CPMs that started at $60, and a platform that rewrites its own rules every few weeks. Say yes too early and you’re funding OpenAI’s learning curve. Say no and a competitor might lock in cheap early inventory while you wait for case studies.

    The answer isn’t yes or no. It’s a framework, and it starts with data you probably haven’t looked at yet.

    ChatGPT Ads Are Real Now. The Playbook Isn’t.

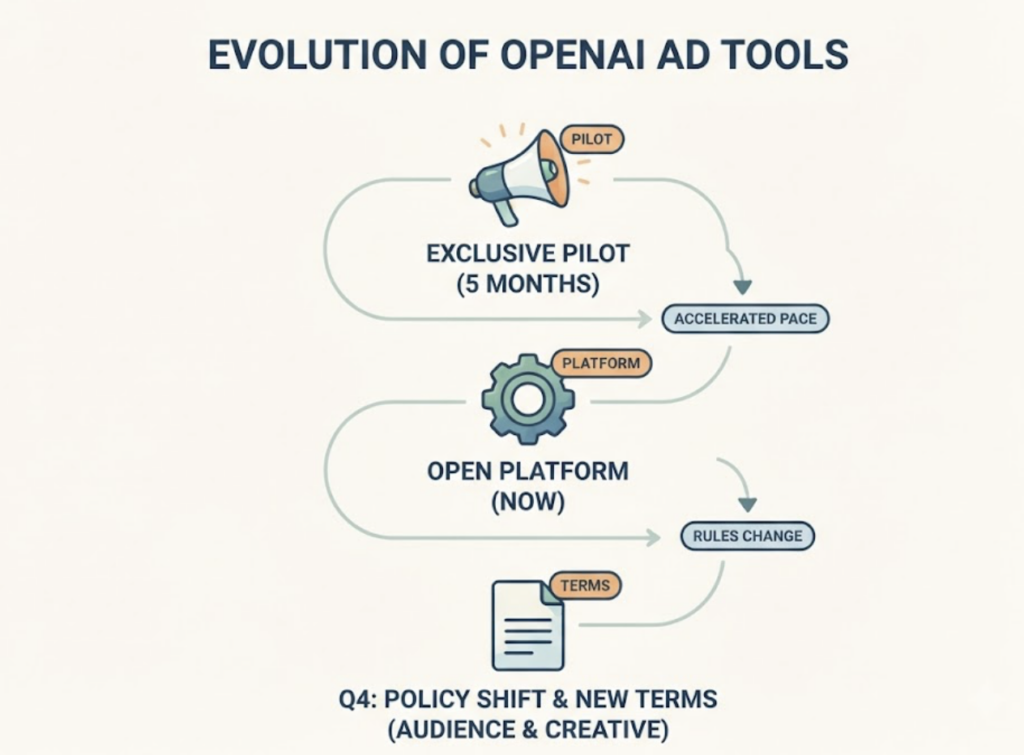
    OpenAI moved fast. Ads launched in the US on February 9, 2026, limited to logged-in users on the Free tier and the $8-per-month Go tier. The initial pilot was managed-service only, with a $200,000 minimum commitment at a fixed $60 CPM. That gate kept everyone but enterprise brands out.

    Then the gate came down. April brought CPC bidding and a reduced $50,000 minimum. On May 5, 2026, OpenAI opened a beta self-serve Ads Manager, eliminated minimum spend entirely, and shipped conversion tracking through a pixel and Conversions API. By June, auto-generated product feed ads lowered the barrier further, and the pilot had expanded to Canada, Australia, and New Zealand, with the UK, Mexico, Brazil, Japan, and South Korea announced next.

    Five months from exclusive pilot to open platform. That pace tells you two things. OpenAI is confident in advertiser demand, and the rules you plan around today will probably change by Q4. In mid-June, OpenAI published new Ad Tools Terms covering first-party audience uploads and AI-generated creative, features announced in policy before they’re live in the product.

    One structural fact hasn’t changed, and it matters more than any pricing update: subscribers on Plus, Pro, Business, and Enterprise tiers never see ads. Whoever you reach through ChatGPT ads, it won’t be them.

    What ChatGPT Ads Actually Cost in 2026

    The pricing has settled into a relevance-weighted second-price auction, and the benchmarks look like this:

    MetricMid-2026 Benchmark
    CPM$25 to $60
    CPC$3 to $5 typical, $8 to $18 in SaaS and financial services
    CTRRoughly 0.91% to 1.5%
    Minimum spendNone since May 5

    The gap between the $60 listed CPM and the roughly $25 observed CPM reflects how quickly the auction matured once self-serve buying opened. Vertical density drives the spread on CPC. E-commerce brands often clear near the $3 floor, while SaaS and fintech advertisers compete on higher conversion values and pay accordingly.

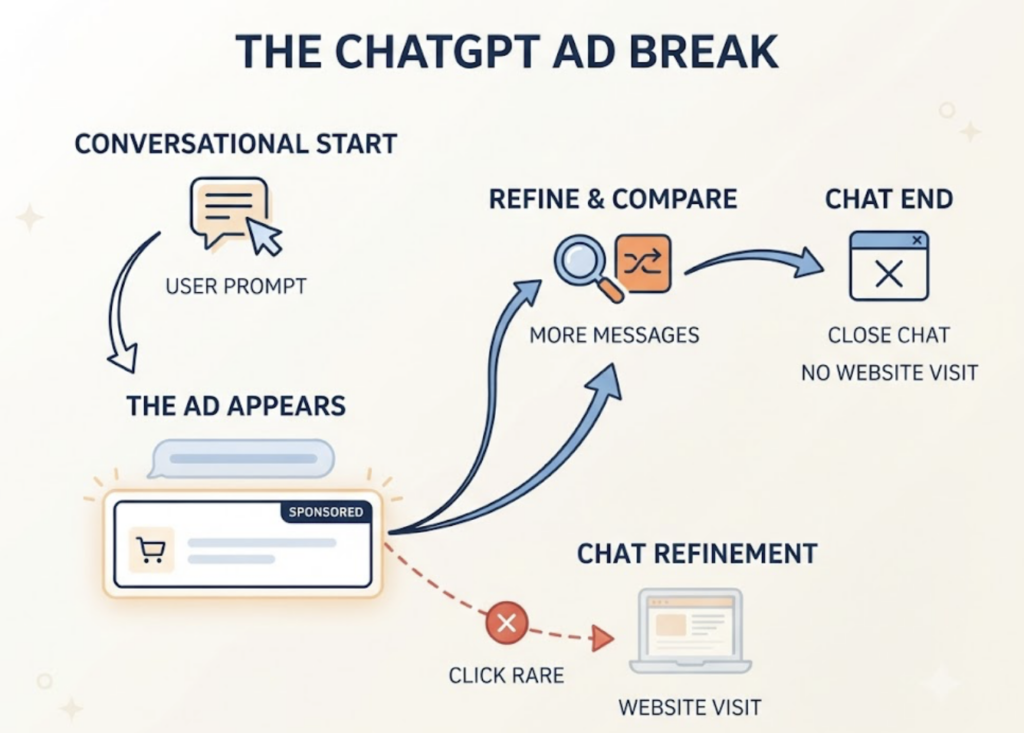
    The CTR deserves a closer look, because it’s structural rather than fixable. Ads appear in a clearly labeled chat_card below the AI’s response, never inside it. Users get their complete answer first, then see the sponsored placement. A 0.91% click-through rate isn’t a creative problem you can optimize away. It’s the design.

    Targeting works differently too. There’s no demographic audience sculpting the way Meta offers. Delivery is intent-first, shaped by the current conversation thread, opted-in personalization history, and prior ad interactions. Advertisers write “context hints” describing the questions and situations users bring to ChatGPT, not exact-match keywords. Chats, names, emails, and precise locations stay inside OpenAI. You never see them.

    The Decision Framework: Four Questions Before You Buy ChatGPT Ads

    The brands getting this decision wrong tend to skip straight to creative and budget. The brands getting it right answer four questions first.

    1. Does Your Audience Actually Live on Free and Go Tiers?

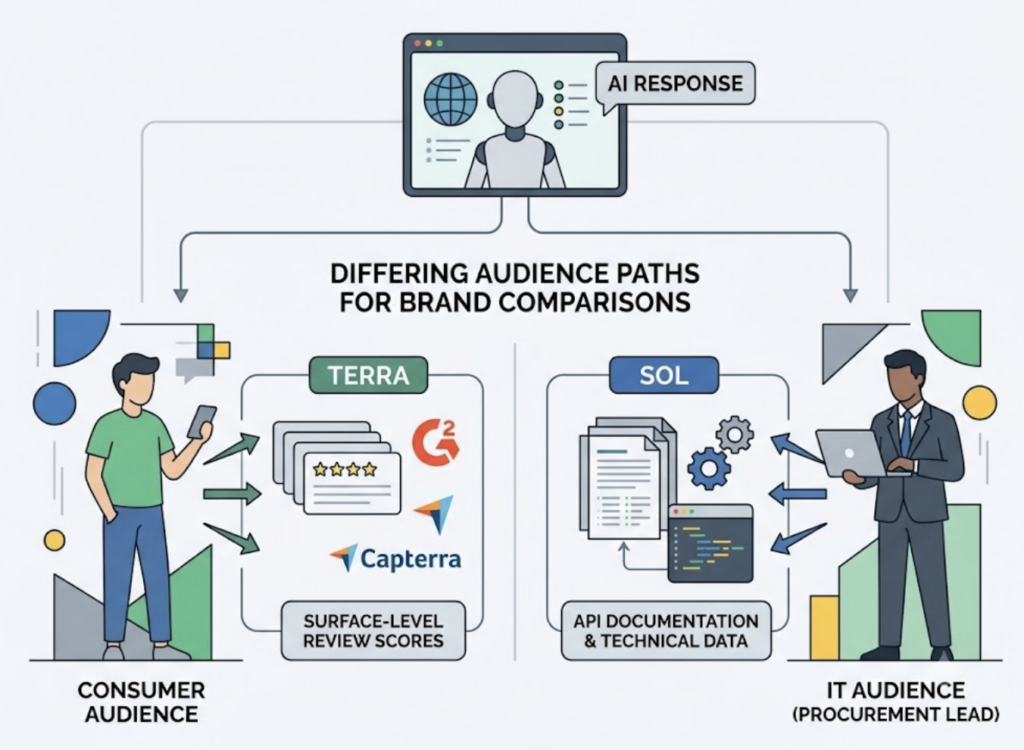
    Ads reach Free and Go users only. That skews the reachable audience toward consumers, students, and casual users, not the professionals paying $20 or more per month for Plus and above.

    If you sell consumer products, meal kits, travel, or entry-level software, your buyers are probably in the ad-eligible pool. If you sell to CTOs, procurement leads, or enterprise buyers, they’re likely on paid tiers where your ads simply don’t exist. For those brands, paid placement isn’t a weaker option. It’s a nonexistent one, and organic AI visibility becomes the only discovery channel inside ChatGPT.

    2. What’s Your Organic Baseline in ChatGPT’s Answers?

    This is the question most teams never ask, and it’s the one that should drive the budget decision.

    OpenAI mandates that ads don’t influence organic answers. The AI decides which brands to cite independently of ad spend. So before you pay for the box below the answer, you should know whether you already appear inside the answer itself, where every user on every tier can see you.

    Measuring that used to mean manually prompting ChatGPT and screenshotting results. Platforms like Topify now do it systematically. Its Visibility Tracking runs your target prompts across ChatGPT, Gemini, Perplexity, and other engines on a schedule, showing how often your brand appears in organic answers, in what position, and with what sentiment. Source Analysis goes a layer deeper, revealing which domains the AI cites when it recommends brands in your category, which tells you exactly where to earn coverage.

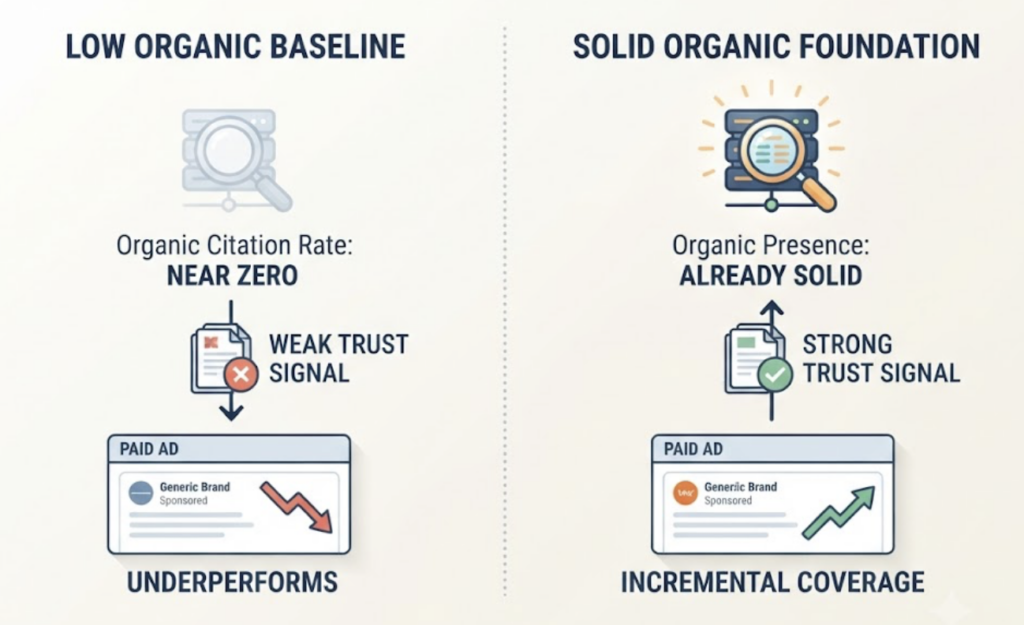
    The baseline changes the math. If your organic citation rate is near zero, paid ads tend to underperform, because a sponsored card for a brand the AI never mentions carries a weak trust signal. If your organic presence is already solid, ads become incremental coverage for the Free-tier audience rather than a lifeline.

    You can run a first visibility check before your Friday deadline. There are also free GEO tools for a quick initial read before committing to full tracking.

    3. Are Competitors Buying Ads, or Winning Organically?

    A competitor showing up in ChatGPT’s answers could be running paid placements, earning organic citations, or both. Those are very different threats.

    If a rival dominates the organic citation slot, buying an ad doesn’t displace them. Your sponsored card sits below an answer that still recommends them by name. Topify’s Competitor Monitoring makes this visible by tracking which brands AI engines recommend for your target prompts, in what order, and how that shifts over time. In practice, this tells you whether an ad would be a defensive counter-measure or money spent watching a competitor’s organic authority from the cheap seats.

    4. Can You Measure Beyond the Click?

    With CTRs under 1%, last-click attribution in GA4 will make almost any ChatGPT campaign look like a failure. That doesn’t mean it is one, but it means you need better plumbing before you spend.

    At minimum, implement the OpenAI pixel and Conversions API from day one, and confirm your robots.txt allows OAI-SearchBot so organic citation isn’t accidentally blocked while you’re paying for placement. Then watch direct traffic and branded search lift as secondary proxies. Users who see your brand in an AI conversation often don’t click the card. They search for you later.

    If you can’t commit to that measurement setup, you’re not ready to evaluate the channel honestly, and an unmeasurable test is worse than no test.

    Paid Placement vs. Organic AI Visibility: The Trade-Off

    Put side by side, the two paths into ChatGPT look like this:

    DimensionOrganic AI CitationPaid Sponsored Placement
    Audience reachedAll users, Free through EnterpriseFree and Go tiers only
    PlacementInside the AI’s answerLabeled card below the answer
    Trust signalHigh, reads as expert recommendationMedium, reads as advertisement
    Cost modelContent and optimization investment$25 to $60 CPM, $3 to $5 CPC
    DurationCompounding earned assetStops the moment spend stops
    Primary metricVisibility share, citation positionCPM, CPC, CTR

    The duration row is the one budget meetings underweight.

    Ad spend rents visibility. Organic citations build it. A brand that spends six months earning citations from the sources ChatGPT trusts keeps that presence whether or not it ever buys an ad. A brand that spends the same budget on sponsored cards goes dark on day one of a paused campaign.

    This is where the cost comparison gets concrete. Topify’s tracking plans start at $99 per month for 100 prompts monitored across ChatGPT, Perplexity, and AI Overviews, with roughly 9,000 AI answer analyses included. At a $25 observed CPM, that same $99 buys about 4,000 ad impressions to Free-tier users, with under 1% of them clicking. One is a measurement layer that informs every channel decision you make. The other is a rounding error of rented reach. For most teams, the baseline data comes first, then the ad test, not the other way around.

    When ChatGPT Ads Make Sense (and When They Don’t)

    The framework resolves into fairly clean scenarios.

    A test is justified if your buyers skew consumer or SMB and plausibly sit on Free/Go tiers, your organic visibility baseline is already measurable and nonzero, your vertical’s CPCs sit near the $3 to $5 floor, and your pixel and Conversions API are wired before the first dollar goes out. Product feed advertisers in e-commerce fit this profile best right now.

    Hold off and invest in GEO first if your buyers are on ad-free paid tiers, your brand has near-zero organic citations, or your CPCs land in the $8 to $18 range where a sub-1% CTR makes the math brutal. In those cases, the budget does more work earning the citations that reach every user than renting a card that reaches a fraction of them.

    Either way, size it honestly. Treat ChatGPT ads as an experimental line item with its own KPIs, not a core channel with revenue targets. The platform is being built in public, formats and geographies are still in motion, and the advertisers winning right now are the ones running cheap, well-instrumented tests while their organic visibility compounds in the background.

    Conclusion

    The Friday answer for your CMO isn’t “buy” or “pass.” It’s “here’s our organic baseline, here’s who we can actually reach, and here’s the test budget that follows from both.” Brands with strong organic citations and Free-tier audiences should test now while CPMs sit near $25 and inventory competition is thin. Brands invisible to ChatGPT’s organic answers should fix that first, because no ad card compensates for an AI that never mentions you.

    Start with the measurement. Run your brand’s visibility baseline across ChatGPT and the other engines, see where you stand against competitors, and let that data decide whether the ad budget is an accelerant or a distraction.

    FAQ

    Q: How much do ChatGPT ads cost in 2026? 

    A: Observed CPMs run $25 to $60, with CPC bids typically $3 to $5 and no minimum spend since the self-serve Ads Manager launched on May 5, 2026. SaaS and financial services verticals often see CPCs of $8 to $18 due to competitive density.

    Q: Do ChatGPT ads influence the AI’s answers? 

    A: No. OpenAI mandates that organic answers are generated independently of ad spend. Sponsored placements appear in a labeled card below the response, and buying ads doesn’t earn your brand citations inside the answer itself.

    Q: Can ChatGPT Plus or Enterprise users see ads? 

    A: No. Ads are served only to Free and Go tier users. Subscribers on Plus, Pro, Business, and Enterprise tiers operate in an ad-free environment, which means organic visibility is the only way to reach them inside ChatGPT.

    Q: What’s the difference between ChatGPT ads and GEO? 

    A: ChatGPT ads are paid placements below AI answers, reaching Free/Go users for as long as you spend. Generative engine optimization (GEO) is the practice of earning organic citations inside AI answers across all user tiers, which compounds over time and persists without ongoing ad spend.

    Read More

  • ChatGPT Ads Launch as Perplexity Kills Ads: Two Futures of AI Search

    ChatGPT Ads Launch as Perplexity Kills Ads: Two Futures of AI Search

    Your team probably has one playbook for AI search. As of February 2026, you need two. Within nine days of each other, the two most-watched AI answer engines made opposite bets: OpenAI switched ChatGPT ads on for millions of free users, while Perplexity shut its ad program down for good. Same market, same month, contradictory conclusions about what users will tolerate.

    If you’re deciding where next quarter’s visibility budget goes, this isn’t trivia. It determines which platforms you can pay your way into, and which ones you can only earn your way into.

    One Month, Two Opposite Bets on the Future of AI Search

    The timeline is unusually compressed. ChatGPT ads went live on February 9, 2026, for Free and Go tier users. Nine days later, on February 18, Perplexity confirmed it was discontinuing the ad experiments it had been running since late 2024.

    That leaves the three dominant AI search platforms running three different commercial models. ChatGPT now mixes ad revenue with tiered subscriptions. Perplexity is pure subscription plus enterprise sales. Google keeps extending its existing ad infrastructure into AI Overviews and AI Mode.

    The scale on each side is real. ChatGPT’s ad program reportedly reached $100M in annualized revenue within two monthson the back of 800M+ weekly active users, with OpenAI targeting $2.5B annually. Perplexity walked away from monetizing 780 million monthly queries through ads.

    These aren’t two isolated product decisions. They’re two live experiments on the same question: how much commercial influence can an answer engine carry before users stop believing it?

    Why Perplexity Walked Away From Ad Revenue

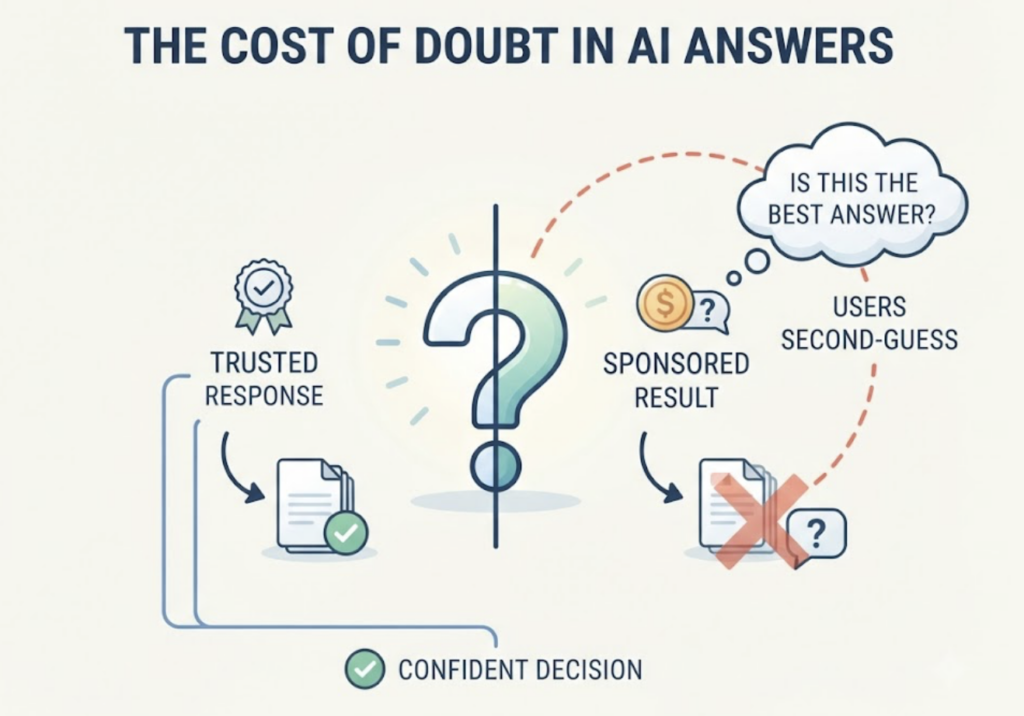
    Perplexity’s stated reason is blunt. One executive told the Financial Times that with ads, “a user would just start doubting everything.” The company’s position is that perception matters as much as fact: even clearly labeled sponsored placements can make users second-guess whether they got the best possible answer.

    The experiment also never scaled. Fewer than 0.5% of brands that applied to advertise were ever admitted, and Taz Patel, the executive leading the ads effort, left before the program wound down.

    The replacement model is already producing numbers. Perplexity reached roughly $200M in annual recurring revenue by late 2025 and is now targeting $500M in annualized subscription revenue, selling $20 to $200 per month plans to finance professionals, lawyers, doctors, and executives who pay specifically for answers that nobody sponsored.

    That last detail matters more than the revenue figure. Perplexity is deliberately concentrating the buyers most brands want to reach inside a platform where placement can’t be bought.

    Inside ChatGPT Ads: How OpenAI Structured the Opposite Bet

    OpenAI’s implementation is designed to look nothing like old search ads. Sponsored results appear in clearly labeled, visually separated boxes below the organic answer, never inside the response text. OpenAI states that ads don’t influence what ChatGPT actually says, and targeting runs on conversation topics, chat history, and prior ad interactions.

    The commercial mechanics moved fast. ChatGPT ads launched as a managed service with roughly $60 CPMs and $200k minimums, then shifted to a self-serve CPC model with $3 to $5 bid floors by May 2026 to open up inventory. In three months, it went from exclusive brand program to something closer to a performance channel.

    Here’s the structural catch: paying subscribers on Plus, Pro, Business, Enterprise, and Education tiers see no ads at all. The users who pay for ChatGPT, disproportionately professionals with buying authority, sit entirely outside the ad inventory.

    And user sentiment is not neutral. An Ipsos survey found that 63% of users say ads in AI search results make them trust those results less. OpenAI is betting that clean labeling and answer-integrity guarantees can hold that skepticism at bay while ad spend scales.

    The Two-Tier Split: Where Your Buyers Actually Are

    Put the two bets side by side and a two-track market emerges.

    Ad-Supported TierTrust-First Tier
    PlatformsChatGPT Free/Go, Google AI Overviews and AI ModePerplexity, Claude, ChatGPT paid tiers
    MonetizationCPM/CPC ads plus subscriptionsSubscriptions and enterprise sales
    How brands get inPaid placement plus organic citationOrganic citation only
    Typical intentGeneral discovery, transactional queriesDeep research, professional decisions

    The money is flowing toward the ad side. US advertisers are projected to grow AI search ad spend from $1B in 2025 to $25.9B by 2029, around 13.6% of all search ad spending.

    But the audience quality skews the other way. The trust-first tier concentrates high-intent professional users, Perplexity’s paying researchers, Claude’s ad-free user base, and every ChatGPT subscriber, into environments with zero paid slots. If you sell to CFOs, general counsel, physicians, or technical decision-makers, a large share of their AI queries happen where no ad budget can follow.

    One more wrinkle: even inside ChatGPT, ads don’t touch the organic answer. Buying placement gets you a labeled box below the response. It doesn’t change whether the model mentions your brand in the answer itself. Organic authority drives the actual recommendation in both tiers.

    What ChatGPT Ads Mean for Your GEO Strategy

    The practical conclusion is that “AI search” is no longer one channel. It’s two channels with different economics, and organic citation is the only asset that works in both.

    That makes measurement the first move, not media buying. Before committing spend to ChatGPT ads, you need a baseline: how often do AI engines already mention your brand, in what position, with what sentiment, and citing which sources? Most teams can’t answer any of those four questions today.

    This is where a dedicated tracking layer earns its place. Topify monitors brand visibility across ChatGPT, Perplexity, Gemini, and other major AI platforms, scoring seven metrics including visibility, sentiment, position, and mentions. In practice, that means you can see whether Perplexity’s ad-free answers recommend you or your competitor, and whether your ChatGPT organic presence justifies layering paid placement on top. Its Source Analysis goes a step further by reverse-engineering the exact domains and URLs each AI engine cites, so you know which third-party sites function as gatekeepers for your category. If you want to gauge your starting point before committing to a platform, Topify’s free GEO tools cover the initial audit at no cost.

    The point isn’t tooling for its own sake. It’s that ad decisions made without an organic baseline are guesses with a budget attached.

    Playbook: Winning Both Tracks Without Betting on One

    A workable dual-track approach looks like this.

    Measure your organic citation share first. Track how often you appear in AI answers across both tiers for your priority prompts. This number is your universal currency; it counts on Perplexity, on Claude, and in ChatGPT’s organic answers where ads can’t reach.

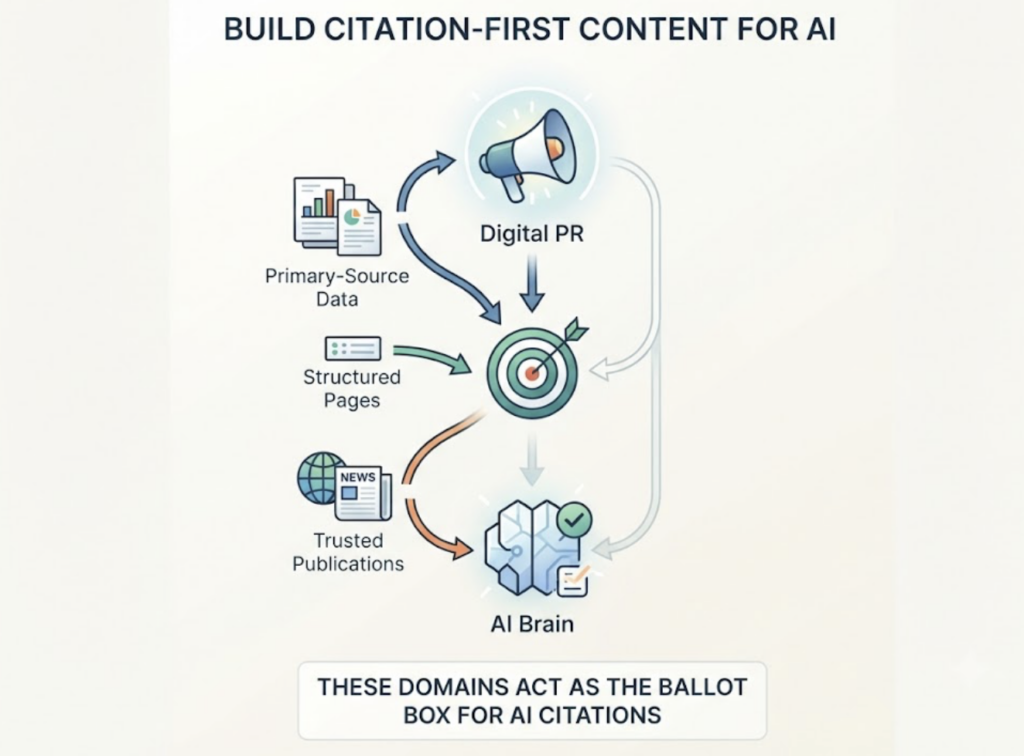
    Build citation-first content for the trust tier. AI engines in the ad-free tier cite what their retrieval systems judge authoritative. That tends to mean primary-source data, structured pages that extraction systems can parse, and third-party coverage in publications those engines already trust. Digital PR that earns mentions on the domains your Source Analysis flags is worth more here than any on-page tweak, because those domains are effectively the ballot box for who gets cited.

    Test ChatGPT ads small and compare honestly. The self-serve CPC model lowers the entry cost. Run a contained test and measure it against the cost of earning equivalent organic mentions, not against legacy Google benchmarks.

    Review monthly, not annually. Competitor benchmarking matters here because AI citation patterns shift every few weeks. A rival gaining citation share in the trust tier won’t show up in your ad dashboard at all.

    Conclusion

    February 2026 didn’t settle the ads-in-AI debate. It split the market so both answers could coexist. OpenAI is betting that labeled, walled-off ChatGPT ads can monetize scale without burning trust. Perplexity is betting its entire business that they can’t.

    Brands don’t get to pick a winner. Your buyers are already spread across both tiers, and the only visibility asset that transfers between them is organic citation. Start by measuring where you stand on each track, then decide whether ad spend adds to that foundation. Buying placement is optional. Being cited isn’t.

    FAQ

    Q: Does ChatGPT show ads to all users?
    A: No. ChatGPT ads appear only for Free and Go tier users. Plus, Pro, Business, Enterprise, and Education subscribers see an ad-free experience, which means paying professional users sit outside the ad inventory entirely.

    Q: Why did Perplexity remove ads?
    A: Perplexity concluded that ads erode trust even when clearly labeled, with executives arguing users need to believe they’re getting the best possible answer. The company shifted to a pure subscription and enterprise model targeting $500M in annualized revenue.

    Q: Can you buy placement in Perplexity or Claude answers?
    A: No. Neither platform sells ad placement, so the only way to appear in their answers is organic citation, earned through authoritative content and coverage on sources their retrieval systems trust.

    Q: How do you track brand visibility across ad-free AI search engines?
    A: Use an AI visibility platform that queries engines like Perplexity and ChatGPT at scale and reports mention frequency, position, sentiment, and cited sources. That baseline shows where you’re already visible organically and where paid or earned efforts should focus.

    Read More

  • ChatGPT Ads Attribution: Why Old Tools Can’t Measure This Channel

    ChatGPT Ads Attribution: Why Old Tools Can’t Measure This Channel

    Your first ChatGPT ads campaign has been live for six weeks. OpenAI’s Ads Manager shows healthy impressions and a reasonable engagement rate. Then you open GA4 to check conversions, and the channel barely exists. A few stray sessions, almost no attributed revenue, and a Direct traffic line that’s quietly grown 18% with no explanation. The spend is real. The results probably are too. But nothing in your analytics stack can connect the two.

    That gap isn’t a tracking misconfiguration. It’s a structural mismatch between how conversational ads work and how attribution was built.

    Your Analytics Stack Was Built for Clicks. ChatGPT Ads Don’t Work That Way

    Every legacy attribution model, from last-click to data-driven, rests on one assumption: a click is the gateway to value. A user searches, clicks an ad, lands on your site with a referrer and UTM parameters intact, and the conversion path begins. GA4, MMPs, and marketing mix dashboards all inherit this click-to-convert paradigm.

    ChatGPT ads break the assumption at the first step. Since OpenAI began testing ads on February 9, 2026 for US users on the Free and Go tiers, sponsored placements have appeared in labeled boxes beneath conversational answers. The user’s natural next move isn’t a click. It’s another message. They refine requirements, compare options inside the dialogue, and often close the chat entirely before visiting anyone’s website.

    The channel operates on what’s better described as an exposure-to-context paradigm. The ad influences a decision that completes somewhere your pixels can’t see.

    Two mechanical failures compound the problem. First, a significant share of AI-referred traffic arrives with no referrer header, so analytics platforms dump it into Direct. Second, UTM passthrough in conversational interfaces is inconsistent, meaning even genuine ad clicks frequently lose their utm_source tagging before landing. Your paid channel data isn’t just incomplete. It’s actively miscategorized.

    Where ChatGPT Ads Attribution Breaks: Three Structural Gaps

    Gap 1: The Influence Happens Before Any Click Exists

    In traditional search, the click starts the decision process. In ChatGPT, the click, if it happens at all, is an optional action at the end of one. The user has already evaluated alternatives, narrowed a shortlist, and formed a preference inside the conversation. By the time they convert, the original ad exposure is untraceable.

    This inverts the value of your click data. A 1% CTR on ChatGPT ads doesn’t mean 99% of your spend was wasted. It means 99% of the influence happened in a layer you’re not measuring.

    Gap 2: Exposure Without Referral Data

    ChatGPT ads behave more like display than search, but with a harsher measurement penalty. Ads are matched to conversation context rather than a persistent user profile, and users routinely see an ad, close the chat, then search your brand name or type your URL directly hours later. Marketers have started calling this Dark Social 2.0: a measurable lift in Direct traffic with no digital breadcrumbs proving causality.

    The scale makes it hard to ignore. Independent rollout tracking in late May put sponsored placements in 49% of US ChatGPT responses, up from a limited February pilot. That’s a lot of untagged influence flowing into your Direct bucket.

    Gap 3: Paid and Organic Mentions Blur Together

    OpenAI’s stated policy is that ads don’t influence the answers ChatGPT gives, and placements are clearly labeled. In practice, users don’t cleanly separate an organic citation from a sponsored box in the same response. Your reporting has to.

    Here’s the problem: if ChatGPT was already recommending your brand organically in 30% of relevant conversations, some portion of your “ad-driven” lift would have happened anyway. Without measuring organic AI visibility before and during the campaign, you can’t calculate incrementality. You’re paying for outcomes you may have been getting for free.

    That’s the number most teams running ChatGPT ads today genuinely cannot produce.

    What the Ads Manager Shows You, and What It Hides

    OpenAI moved fast on the buying side. By May 2026, advertisers had access to a self-serve Ads Manager with CPC and CPM bidding and no minimum spend, a sharp drop from the $60 CPM premium placements of the February launch window. The measurement side hasn’t kept pace.

    Metric LayerLegacy Search/SocialChatGPT Ads TodayWhat’s Missing
    VisibilityKeyword rankingsImpressionsBrand share of voice across AI answers
    InteractionCTR with full click pathCTR, roughly 0.68% to 1.57% in early reportsInfluenced non-click intent
    AttributionLast-click, UTM, data-driven modelsNone to limited API-basedAssisted conversion mapping
    Pricing efficiencyCPC tied to conversion valueCPM/CPCROAS at the conversation level

    Read the right column carefully. Every missing layer sits between exposure and conversion, exactly where conversational ads do their work. Impressions tell you the ad ran. Nothing tells you what it changed.

    Measuring the Missing Layer: AI Visibility as Your Attribution Baseline

    If clicks can’t carry attribution for this channel, something else has to. The most workable answer emerging in 2026 is treating organic AI visibility as the baseline against which paid activity gets measured.

    The logic is straightforward. Before spending, you establish how often your brand appears in ChatGPT responses across the prompts that matter to your category, in what position, and with what sentiment. During and after the campaign, you track the delta. Visibility movement that correlates with spend fluctuations, cross-referenced against your Direct traffic lift, becomes your incrementality estimate. It’s not perfect attribution. It’s evidence, which is more than the current setup gives you.

    This is where a dedicated measurement layer earns its place. Topify tracks brand presence across ChatGPT, Gemini, Perplexity, and other AI platforms through seven metrics, and four of them map directly onto the gaps above. Visibility Tracking establishes the organic baseline that makes incrementality math possible. Position Tracking shows whether your brand’s placement within answers is shifting, which matters when sponsored boxes and organic mentions coexist in the same response. Source Analysis reveals which domains AI cites when recommending your category, so you can see whether your ad landing pages and your cited content are pulling in the same direction. And CVR, Topify’s Conversion Visibility Rate, estimates how likely an AI answer is to push a user toward brand interaction, which is the closest available proxy for the influenced-but-unclicked intent that CTR ignores.

    In practice, the workflow looks like this: a performance team maps 100 high-intent prompts before launch, records a 22% organic mention rate, runs six weeks of ChatGPT ads, and watches visibility climb to 31% while branded search volume rises in parallel. That 9-point delta, tied to spend timing, is a defensible incrementality story to bring to a CMO. A curated set of free GEO tools can handle a first-pass baseline check before committing to a full monitoring setup.

    A Practical ChatGPT Ads Measurement Setup for 2026

    You can build a workable framework in three steps, none of which require waiting for OpenAI to ship better attribution APIs.

    Step 1: Calibrate a 30-day baseline before aggressive spend. Map your brand’s organic presence across high-intent AI conversations for a full month. Frequency, position, and sentiment all matter, because a campaign that lifts mentions but degrades sentiment isn’t a win.

    Step 2: Run synthetic attribution. Use Direct traffic lift as your secondary proxy, but never in isolation. Cross-reference it against the visibility delta from your AI monitoring data. When both move together with spend, you have a causal argument. When Direct rises but visibility doesn’t, look for another explanation before crediting the ads.

    Step 3: Unify the reporting. Combine Ads Manager output (impressions, spend, CTR) with visibility trends into a single “total AI-influenced reach” view. Reporting CPC-based conversions alone will systematically understate the channel and get your budget cut for the wrong reason.

    Teams that get started with baseline tracking before their first major flight tend to have an easier time defending the spend later, simply because they have a before-and-after comparison competitors lack.

    Conclusion

    The attribution gap in ChatGPT ads won’t close on its own. Conversational interfaces structurally separate exposure from conversion, and no amount of UTM discipline fixes a channel where the decisive influence happens before any click. The teams getting ahead of this aren’t waiting for perfect tracking. They’re building an organic AI visibility baseline, measuring deltas against spend, and reporting influence instead of just clicks. Set up the baseline before your next campaign flight, not after the CMO asks a question your dashboard can’t answer.

    FAQ

    Q: Can you track ChatGPT ads conversions in GA4?
    A: Only partially. Clicks with intact UTM parameters will attribute normally, but referral stripping and non-click influence mean most of the channel’s impact lands in Direct or organic buckets. GA4 alone will significantly undercount ChatGPT ads performance.

    Q: How do you measure ChatGPT advertising ROI without click attribution?
    A: Establish an organic AI visibility baseline before spending, then track the visibility delta and Direct traffic lift against spend timing. The correlation between these signals serves as your incrementality estimate.

    Q: What’s the difference between paid and organic visibility in ChatGPT?
    A: Organic visibility is when ChatGPT mentions or recommends your brand within its answer content. Paid placement is a labeled sponsored box beneath the answer. OpenAI states ads don’t influence answer content, so the two layers move independently and need separate measurement.

    Q: Should brands run ChatGPT ads if attribution is this limited?
    A: The reach case is strong, with sponsored placements now appearing in roughly half of US responses. The practical approach is to run the channel with a measurement framework built for it, rather than skipping it or flying blind.

    Read More

  • How to Track Your Brand Mentions in ChatGPT 5.6 and GPT’s New Models

    How to Track Your Brand Mentions in ChatGPT 5.6 and GPT’s New Models

    The mention baseline your team built over the past year of GPT-5.5 monitoring stopped meaning anything on July 9, 2026. That’s when OpenAI publicly released GPT-5.6 after a two-week government review period, replacing a single model with three tiers named Sol, Terra, and Luna. Different retrieval behavior, a refreshed knowledge base, and a new user distribution across tiers mean the question “does ChatGPT mention my brand” now has at least three different answers. This guide walks through how to rebuild your tracking system for the new model family, starting today.

    GPT-5.6 Just Reset Your Brand’s AI Visibility Baseline

    Model generation changes don’t just improve text quality. They reshuffle training data, retrieval strategies, and recommendation logic, which are the exact mechanisms that decide whether your brand gets named in an AI answer.

    The GPT-5.6 rollout came with unusual friction. OpenAI launched a limited preview on June 26 restricted to government-approved partners, then received clearance for a full public release after additional testing by the Department of Commerce. Fourteen days later, the models reached everyone.

    Your GPT-5.5 mention data is now a historical record, not a benchmark.

    What makes this generation different for brand tracking is the tier structure. GPT-5.6 isn’t one interface. It’s three models with different reasoning depth and different cost profiles, per pricing confirmed by OpenAI:

    ModelPositioningInput Cost per 1M TokensOutput Cost per 1M Tokens
    GPT-5.6 SolFlagship, maximum reasoning, built for long-horizon agentic work and complex analysis$5.00$30.00
    GPT-5.6 TerraBalanced default, performance comparable to GPT-5.5 at roughly half the cost$2.50$15.00
    GPT-5.6 LunaLow-latency, lowest-cost tier for high-volume basic tasks$1.00$6.00

    Pricing shown is subject to change; refer to OpenAI’s official pricing page for current rates.

    An enterprise buyer running deep research through Sol and a free user getting a quick summary from Terra are querying two different neural networks. Your brand’s visibility can diverge sharply between them.

    What Changed in ChatGPT 5.6 That Affects Brand Mentions

    The naming system itself changes who sees what. The number marks the generation, while Sol, Terra, and Luna mark persistent capability tiers. Free and Go users default to Terra. Plus, Pro, Business, and Enterprise subscribers can select Sol at medium and higher reasoning effort, with a Sol Pro option reserved for Pro and Enterprise plans.

    In practice, that splits your audience. When a consumer and an IT procurement lead ask ChatGPT the same brand comparison question, Sol may dig through your API documentation and recent technical discussions, while Terra tends to synthesize surface-level review scores from sites like G2 or Capterra.

    Terra’s economics create a second-order effect that matters even more. Because Terra roughly matches GPT-5.5 performance at half the API cost, third-party applications, CRMs, and vertical SaaS platforms have a strong incentive to migrate their language layer to it. Your brand’s exposure surface extends well beyond the ChatGPT interface into every product that embeds the API.

    There’s also a shift in what a “mention” even is. GPT-5.6 powers a new agent that works across connected apps and filesto produce documents, spreadsheets, and presentations. Sam Altman told CNBC the model is 54% more token efficient on agentic coding tasks, which gives it room to compare more options, fetch more sources, and verify claims before writing. If an agent drafting a 30-page vendor evaluation skips your brand because your data isn’t extraction-friendly, that lost mention never shows up in any chat log you can spot-check.

    Step 1: Establish Your New Mention Baseline Across Sol, Terra, and Luna

    Start by defining a prompt universe that reflects how buyers actually ask, not how your brand describes itself. Three categories cover most commercial intent.

    Category queries test unprompted recall: “recommend a scalable expense platform for a fast-growing B2B software team.” Comparison queries test head-to-head framing: “compare Competitor A and Competitor B for high-concurrency workloads,” where the useful signal is whether the model introduces your brand as a third option. Pain-point queries map directly to buying triggers: “how do I fix database sync failures caused by cross-region latency, and what enterprise tools handle this.”

    A working set runs 100 to 250 prompts. Then comes the part most teams underestimate: every prompt needs to run against all three tiers, because the same question produces materially different answers at different reasoning depths.

    Luna, constrained by minimal reasoning budget, tends to output the most conservative, high-frequency brand lists. Terra balances name recognition against feature fit. Sol, especially at higher effort settings, pulls recent technical reviews and community discussions into its answer, consistent with the deep-retrieval behavior OpenAI describes in its Sol preview documentation.

    LLM outputs are also non-deterministic, so a single run per prompt proves nothing. At the scale of hundreds of prompts, multiple samples, three tiers, and a weekly cadence, manual checking is arithmetic you lose. Platforms like Topify handle this with automated Visibility Tracking, parsing thousands of AI answers per month (up to 9,000 on the entry plan) so the noise averages out and a statistically usable baseline emerges.

    Step 2: Compare Pre- and Post-5.6 Visibility Data

    With a fresh baseline in hand, run it against your GPT-5.5 era numbers. The comparison needs four dimensions, not one.

    Visibility rate tells you whether the brand entered the model’s consideration set at all. Position tells you whether you’re the lead recommendation or an afterthought at the end of a list, and the commercial gap between those two placements is enormous. Sentiment decodes the framing around your mention: endorsement, neutral description, or a caveat. Citation share reveals which sources produced the mention in the first place.

    If your mention rate dropped 20% overnight, the model changed, not your brand.

    That distinction matters because the instinct after a data cliff is internal blame: the content team, the last PR cycle, the product page. Generation changes are the more likely cause, and the fix is different.

    Here’s how the layered view plays out. Suppose an enterprise finance platform led most GPT-5.5 comparisons as “the most comprehensive option.” After the switch to Sol, Position Tracking shows it slipping to second while Sentiment Analysis flags a decline. Digging into the answer context reveals Sol picked up developer forum threads about API latency and started appending a caveat: strong feature set, but a potential concern for high-frequency API users. That’s a specific, fixable narrative problem. You can update technical documentation and address the community discussion before the caveat hardens into machine consensus. Without tier-level position and sentiment data, you’d never know which thread to pull.

    Step 3: Trace Which Sources GPT-5.6 Actually Cites

    Mention changes have causes, and the causes live in the citation layer. New model generations typically refresh both the training corpus (GPT-5.6’s knowledge reportedly extends to February 2026) and the weighting of live retrieval sources.

    Traditional SEO signals won’t guide you here. Industry analyses of citation behavior suggest the domains LLMs cite overlap very little with Google’s first page, with ChatGPT’s overlap against top-10 organic results reported as low as roughly 2%, and even search-leaning Perplexity around a third. Holding your SERP position is not a strategy for holding AI visibility.

    Source Analysis inverts the problem. Instead of guessing what the model reads, you extract the actual domains and URLs behind each brand mention. The pattern that emerges is usually a new authority map: for enterprise software, GPT-5.6 tends to weight GitHub discussions, analyst white papers, and in-depth developer blogs. For consumer and lightweight SaaS categories, Reddit threads and structured review scores on G2 or Capterra often do the heavy lifting.

    Once the map is visible, budget allocation gets simple. If Terra’s answers for your core category query lean on five specific review sites and you appear on two, the next quarter’s priority isn’t more blog volume. It’s closing the three missing placements through outreach, partnerships, or fresher data those sites can use. Cover the sources the model trusts, and the next retrieval cycle works in your favor.

    Common Mistakes When Tracking Brand Mentions in a New Model

    Three failure patterns show up repeatedly when teams respond to a model transition.

    The first is testing only the flagship tier. Sol’s benchmark results are impressive (Sol Ultra scores 91.9% on Terminal-Bench 2.1), and it’s tempting to treat it as the definitive judge of your brand. But Terra carries the free-user base and the third-party API ecosystem. A brand that wins Sol’s deep analysis while staying invisible in Terra’s everyday answers has won a small audience of power users and lost the mainstream.

    The second is replacing continuous monitoring with a one-time audit. A big launch-week test produces a satisfying report, and then the tracking stops. Model outputs drift constantly as OpenAI fine-tunes, caches reset, and competitors publish. Without a time series, you can’t tell whether next week’s ranking dip is random noise or a real share shift caused by a competitor’s PR push.

    The third is misattributing drops to your own content quality. When visibility shrinks on key prompts, the reflex is to question the content team’s output. More often, the new model has reweighted its sources, demoting a press release site you relied on and promoting a developer forum you’ve ignored. Unless you connect the mention drop to a specific citation change, the internal blame cycle burns morale and points optimization at the wrong target.

    Why Manual Spot-Checks Break Down at GPT-5.6 Scale

    The old habit of opening a few browser tabs and typing your category keywords worked, barely, when there was one model behind one interface. The math no longer allows it.

    A minimally useful monitoring program covers 100 prompts. Non-determinism requires around 5 samples per prompt. Three tiers multiply that again, and a weekly cadence adds the time axis. That’s tens of thousands of long-form answers per month to collect, read, and score for position, sentiment, and hidden citations. No team does that by hand.

    This is where structured monitoring platforms earn their place. Topify’s Comprehensive GEO Analytics breaks every AI answer into seven metrics: Visibility, Mentions, Position, Sentiment, Volume, Intent, and CVR, which estimates how likely an answer is to drive actual brand engagement. Instead of a raw mention count, you get a profile of how the algorithm perceives your brand and where the leverage points are.

    Coverage matters as much as depth. Buyer journeys don’t stay inside one model family, and Topify tracks the GPT-5.6 lineup alongside Gemini, Perplexity, DeepSeek, and Doubao from a single dashboard. That cross-platform view is often where teams find arbitrage: a category where competitors dominate ChatGPT but nobody has claimed Perplexity yet.

    The entry cost is modest relative to the stakes. The Basic plan runs $99 per month with 100 tracked prompts, 9,000 monthly AI answer analyses, and a 30-day trial, which is enough to run the full three-step process in this guide before committing budget. You can get started here and have a Sol-Terra-Luna baseline within the trial window.

    Conclusion

    GPT-5.6 isn’t an incremental update for brand teams. The Sol, Terra, and Luna split means AI visibility is now tier-specific, the third-party migration to Terra extends your exposure surface beyond ChatGPT itself, and agent workflows turn mentions into something that happens inside documents you’ll never see.

    The response is a process, not a panic: rebuild your prompt baseline across all three tiers this week, compare the four core metrics against your GPT-5.5 history, and trace mention changes back to specific citation shifts before touching your content budget. Teams that establish the new baseline in the first month of a model generation get a reference point their competitors won’t have.

    FAQ

    Q: Does GPT-5.6 use different sources than GPT-5.5? 

    A: Yes, and the difference is significant. Beyond the refreshed knowledge cutoff, GPT-5.6’s upgraded retrieval and tool-calling behavior favors technically substantive, well-structured sources with independent verification signals over thin marketing pages. The citation set that earned your brand mentions under GPT-5.5 may be largely replaced, which is why source-level analysis should come before any content changes.

    Q: Which GPT-5.6 model should I track first, Sol, Terra, or Luna? 

    A: Track Sol and Terra in parallel. Sol drives the recommendations that paid subscribers, executives, and research agents see. Terra serves free users and the growing set of third-party apps built on its cheaper API. Missing either one gives you a distorted picture. Luna is a secondary check for latency-sensitive, high-volume use cases.

    Q: How often should I check brand mentions after a model update? 

    A: Run high-density sampling for roughly the first two weeks after a major release to establish the new baseline, then shift to weekly monitoring. Because model outputs are stochastic, single spot-checks carry no statistical weight; trend lines over time are what separate real ranking shifts from noise.

    Q: Can I track brand mentions in ChatGPT for free? 

    A: You can query ChatGPT manually at no cost, but manual checks can’t control for context, can’t sample at volume, and can’t reach Sol if you’re on a free plan. For decision-grade data across tiers, a platform trial is the practical free option; Topify’s Basic plan includes a 30-day trial covering position, sentiment, and citation tracking.

    Read More