Category: Article

  • One Bad AI Summary Can Undo Years of Brand Trust. Catch It First

    One Bad AI Summary Can Undo Years of Brand Trust. Catch It First

    A prospect opens ChatGPT before your sales call. They type your company name, get a confident paragraph back, and form an opinion in about eight seconds. No one on your team saw it happen.

    That paragraph might be right. It might also describe a product you discontinued two years ago, or borrow a competitor’s feature and hand it to you by mistake. Either way, it’s now part of how that prospect thinks about your brand, and you have no record that the moment ever occurred.

    This is the new shape of ai reputation management. It’s not about what people say about you. It’s about what a model says on your behalf, to someone you’ll never meet, in a format that looks like fact and disappears the moment the chat window closes.

    Why AI Has Become Your Brand’s First Impression

    Search used to hand people a list of links and let them decide. Generative search skips that step. It hands people a conclusion.

    That shift has moved fast. Roughly 43% of U.S. online shoppers used an AI assistant for product research in the past 90 days, and the share starting their research directly on a standalone AI platform like ChatGPT or Perplexity has nearly doubled since 2024, according to the same report. Traditional search, over that period, gave up ground.

    Here’s the part that should worry a brand manager more than the adoption curve. Sixty-six percent of AI users say they trust the accuracy of what these platforms tell them. People aren’t treating AI answers as a rough starting point. They’re treating them as verified.
    That’s the gap most brands still can’t see.

    What “One Bad Summary” Actually Looks Like

    It rarely arrives as a single dramatic lie. It’s usually smaller and stranger than that.

    Research tracking AI-generated brand answers found that 72% of brands had at least one factual error somewhere in their AI-generated coverage, ranging from outdated pricing to features credited to the wrong product tier. A separate analysis puts a number on the fallout: 35% of brands report that an inaccurate AI response has already damaged their reputation, a meaningful figure given that ChatGPT alone now serves roughly 800 million people every week.

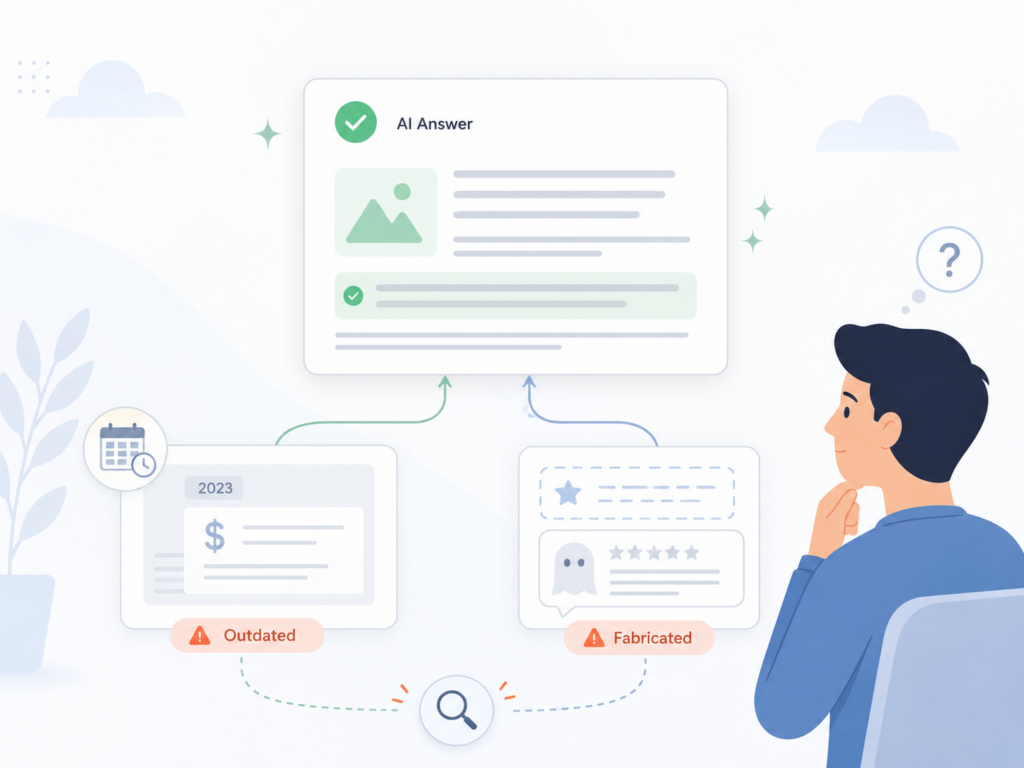
    The errors also aren’t uniform across platforms. One breakdown of AI brand errors found that ChatGPT tends to fabricate plausible-sounding specifics when training data is thin, Perplexity tends to surface outdated information because older pages often outrank newer ones, and Gemini tends to blend two similar companies together when synthesizing comparison articles. A brand that looks clean on ChatGPT can still be quietly wrong on Perplexity.

    There’s also a useful way to categorize what’s actually going wrong. One framework separates AI brand errors into three types: outright fabrication with no basis in any source, staleness where a once-true fact never got overwritten, and framing errors where the facts are close but the tone skews negative for reasons no one can point to. That third type is the one social listening tools were never built to catch, because there’s no post to flag and no comment to moderate. There’s just a sentence, generated fresh each time someone asks.

    Why Traditional Monitoring Tools Miss This Entirely

    Tools like Google Alerts or a standard media monitoring dashboard were built for a web made of indexable pages. Something gets published, it gets crawled, and your alert fires.

    An AI answer isn’t published anywhere. It’s generated on demand, phrased slightly differently each time, and gone the moment the session ends. There’s no URL to flag, no page to screenshot, no crawler that will ever find it for you.

    That means the first sign of a problem usually isn’t a spike in your dashboard. It’s a confused email from a prospect, or a sales rep mentioning that a deal went quiet right after the buyer said they’d “looked into it more.” By the time you hear about it secondhand, the AI has probably already said the same wrong thing to dozens of other people.

    What Actually Catching It Looks Like

    Catching a bad AI summary before it spreads means treating your presence inside AI answers as a metric, not a feeling. That starts with a sentiment score.

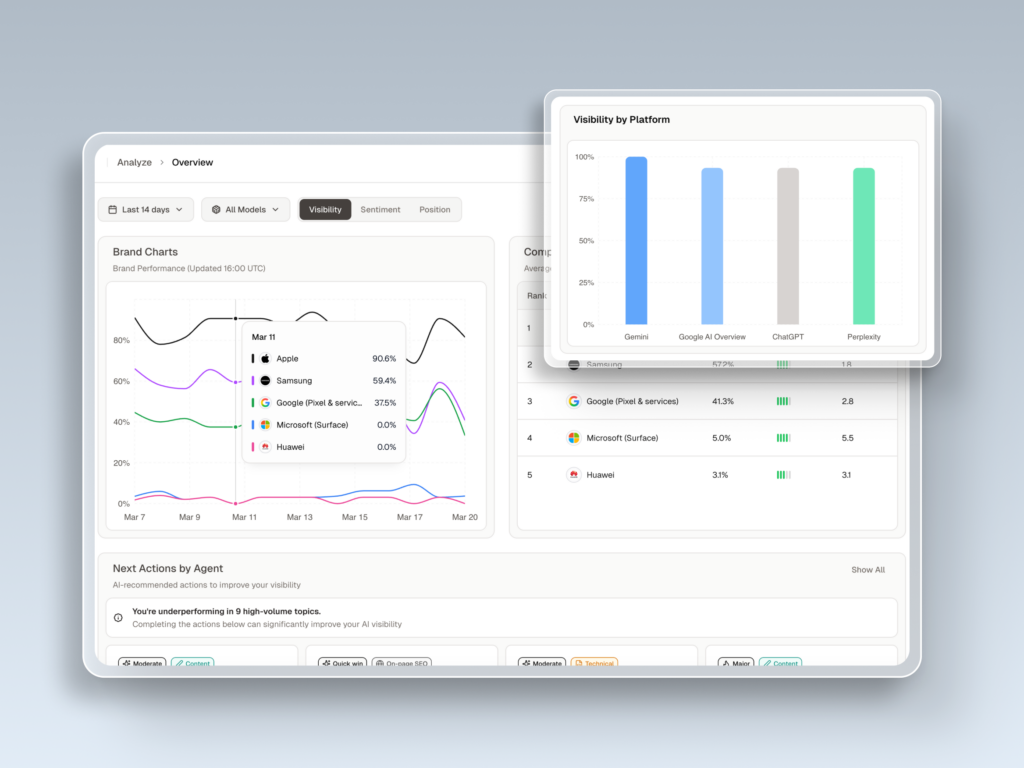
    Topify’s Sentiment Analysis scores every AI mention of your brand on a 0 to 100 scale across ChatGPT, Gemini, Perplexity, and other major platforms, pulling from the actual language the model uses rather than a manual spot-check. A score sitting at 78 that slides to 61 over two weeks is a signal, not a coincidence, and it typically shows up well before a support ticket or a lost deal does.

    Sentiment on its own tells you the tone is shifting. It doesn’t tell you how far the problem has spread. That’s what Visibility Tracking is for: confirming how many prompts, and which platforms, are actually surfacing the summary in question. A negative framing that shows up once on a niche prompt is an annoyance. The same framing showing up across your five highest-intent category prompts is a fire.
    A negative sentiment score without a reason attached is just a number to feel bad about.

    Tracing the Summary Back to Where It Came From

    Finding out a summary is wrong is only half the job. Finding out why the model believes it is the half that actually lets you fix it.

    This is where source-level analysis earns its place in the workflow. Topify’s AI Citation Tracking shows the specific domains and URLs each AI platform is pulling from when it generates an answer about your brand, at both the domain level and the individual page level. If a model keeps repeating a claim from a three-year-old forum thread or a review site that never updated its listing, that’s traceable, and it’s addressable in a way a vague sense of “our AI reputation feels off” never is.

    Fixing the source doesn’t guarantee an instant correction inside the model. It does mean the next time that page gets crawled or referenced, the story it’s telling is the current one, not the outdated one the AI has been repeating on autopilot.

    Making This a Habit, Not a Fire Drill

    None of this works as a once-a-quarter check-in. AI answers shift as models update, as new pages get indexed, and as competitors publish content that reframes the category.

    The brands treating this well have folded it into the same rhythm they already use for review monitoring or social listening: a standing view of sentiment, visibility, and source data, checked on a schedule rather than after someone forwards a screenshot. Topify’s GEO platform is built around that rhythm, running daily prompt checks across every major AI provider so shifts in tone or coverage show up as a trend line instead of a surprise.

    The cost of setting this up is smaller than most teams assume. A basic monitoring tier typically covers ChatGPT, Perplexity, and Google AI Overviews tracking for well under what a single missed enterprise deal costs, which makes the “we’ll deal with it if it comes up” approach a genuinely expensive bet.

    Conclusion

    Brand trust took years to build and a few confidently worded sentences to put at risk. The sentences themselves aren’t the real threat. Not knowing they exist is.

    Catching a bad AI summary early doesn’t require predicting every way a model might get your brand wrong. It requires a standing view of sentiment, visibility, and sources, so the first person to notice a problem is you, not a prospect who already decided to look elsewhere.

    FAQ

    How do I know if ChatGPT or another AI is saying something wrong about my brand? 

    Manually testing a handful of prompts gives you a snapshot, but it misses the fact that answers shift by platform, by prompt phrasing, and over time. Ongoing monitoring tools that score sentiment and track visibility across ChatGPT, Gemini, and Perplexity catch drift that a one-time check never will.

    Can damage from a bad AI summary actually be reversed? 

    Often, yes, though not instantly. Since models retrieve from current sources rather than a fixed record, publishing accurate, well-structured content and earning fresh citations tends to shift what the model repeats over subsequent crawls and updates.

    Is this the same thing as traditional online reputation management? 

    Related, but not identical. Traditional reputation management tracks reviews, articles, and social posts you can find and link to. AI reputation management tracks synthesized answers that are generated fresh each time, which is why it needs its own monitoring layer rather than an add-on to existing tools.

    Does every brand actually have an AI reputation problem? 

    Not every brand has a crisis, but most have blind spots. Given that a large share of brands show at least one factual error somewhere in their AI-generated coverage, the realistic assumption is that something is off; the open question is just how visible and how damaging it currently is.
    Read More

  • Reputation Management Didn’t Die. It Became AI Reputation Management

    Reputation Management Didn’t Die. It Became AI Reputation Management

    A software company has a 4.8 rating on G2. Its PR team hasn’t had a real crisis in two years. Then someone on the sales floor asks ChatGPT what it thinks of the product, and the answer is vague, three years out of date, and quietly favors a competitor.

    Nothing on the review sites moved. But the reputation did.

    That’s the gap most brands still can’t see. Reputation management didn’t disappear. It moved into a room nobody’s monitoring yet.

    Reputation Used to Mean Reviews and Press. Now It Means AI Answers

    Traditional reputation management was built around a simple assumption: people validate a brand by reading things, reviews, press coverage, forum threads, star ratings. So the tools followed that assumption, watching Google, Yelp, and social mentions for anything that could dent the score.

    That assumption is breaking down. More than a third of consumers now start their searches with AI tools instead of Google, and the shift is accelerating fast enough that Gartner projects traditional search volume will drop 25% by 2026as answer engines take over more of the research phase.

    That’s not a niche behavior anymore. People aren’t reading ten links and forming their own opinion. They’re asking one question and getting one paragraph back, and that paragraph is doing the work reviews and press clippings used to do.

    AI Reputation Management: Same Job, Different Battlefield

    AI reputation management isn’t a new discipline invented to sell software. It’s the same job, monitor how a brand is perceived, catch problems early, correct the record, applied to a channel that didn’t exist five years ago.

    The mechanics are different, though, and that difference matters. Traditional reputation management deals with a list: ten blue links, ranked, each one clickable and separately arguable. AI reputation management deals with a synthesis: one confident paragraph that blends dozens of sources into a single verdict, with no link for the brand to contest.

    You can respond to a bad review. You can’t easily respond to a sentence buried inside a model’s training weights.

    Why Your Star Rating Doesn’t Save You From a Bad AI Summary

    Here’s the part most brand teams miss: AI models don’t check your current review score before answering. They generate an answer based on whatever mix of sources they were trained on or retrieved at query time, and that mix can be stale, thin, or just wrong.

    The scale of this problem is bigger than most teams assume. A widely cited 2025 study from Columbia’s Tow Center for Digital Journalism tested AI search engines across sixteen hundred queries and found that most responses contained factual errors, with error rates ranging from roughly a third on one platform to the large majority on another. Separately, a comparison across 29 large language models found hallucination rates spanning from the mid-teens to over half, even among leading systems.

    Your brand’s reputation score didn’t change. The sources AI trusts to describe you did.

    That’s the mechanism behind the gap in the opening example. The 4.8-star brand and the vague ChatGPT answer aren’t contradicting each other. They’re describing two different information supply chains, and only one of them is being watched.

    What AI Reputation Management Actually Requires

    Mapping the old reputation management playbook onto AI search means rebuilding three capabilities most brands don’t currently have.

    Monitoring. You need to know how your brand is actually described across ChatGPT, Gemini, and Perplexity, not just whether it’s mentioned, but in what tone. This is the job of AI sentiment tracking, scoring each mention on a consistent scale rather than eyeballing a handful of screenshots.

    Attribution. A vague or negative answer usually traces back to a specific source, an outdated press release, a stale forum thread, a third-party comparison page nobody at the company has seen. Finding that source is what separates a real fix from a guess.

    Comparison. Reputation isn’t absolute. A brand described as “reliable but expensive” looks fine until the next answer calls a competitor “the industry standard.” AI reputation management means watching that relative position too, not just your own scorecard in isolation.

    How Topify Turns This Into a Repeatable Process

    Topify was built around this exact gap. Its Sentiment Analysis module scores every AI mention of a brand on a 0-100 scale across ChatGPT, Gemini, Perplexity, and other major platforms, so a drop from the high 70s to the low 60s over two weeks becomes a signal worth investigating rather than an anecdote someone happened to notice.

    From there, Source Analysis traces a negative or outdated mention back to the specific domain the model is drawing from, whether that’s a five-year-old review or a competitor’s comparison page, so the team knows exactly what to fix rather than guessing at a general “brand perception” problem. Competitor Monitoring adds the relative view, showing whether a brand’s sentiment and position are moving up or down against the same rivals AI is comparing it to.

    None of this replaces the traditional reputation playbook. It extends the same monitor-diagnose-fix loop into a channel that most users treat as objective truth once they see it, according to Topify’s own usage data, which is exactly why a stale or wrong AI answer carries more weight than a stray one-star review ever did.

    From Reactive PR to Continuous AI Monitoring

    The old model of reputation management was mostly reactive. Something goes wrong, a crisis team assembles, damage gets contained, everyone moves on until the next incident.

    AI reputation management doesn’t really allow for that rhythm. Models get retrained, retrieval indexes refresh, and a brand’s AI reputation can drift quietly over weeks with no single triggering event to react to. That pushes the discipline toward continuous tracking rather than incident response, closer to a dashboard you check weekly than a fire alarm you wait to hear.

    Brands that treat this as a one-time audit will keep getting surprised by answers they didn’t know existed.

    Conclusion

    Reputation management isn’t a relic of the review-and-press era. It’s the same discipline, applied to a new place where people now form first impressions of a brand: a single AI-generated answer. The tools have to change because the format of the “evidence” changed, from a ranked list of links to one confident paragraph with no visible sources.

    The brands that get ahead of this aren’t the ones with the highest star rating. They’re the ones who know, in real time, what ChatGPT is actually saying about them, and why.

    FAQ

    Is AI reputation management the same thing as GEO? 

    They overlap but aren’t identical. Generative Engine Optimization (GEO) focuses on getting AI models to mention and recommend a brand in the first place. AI reputation management focuses on the tone and accuracy of what gets said once the brand is already mentioned.

    How often does AI-generated brand sentiment actually change? 

    It varies by how frequently a model refreshes its retrieval sources and training data, but shifts of several points on a 0-100 sentiment scale within a two-week window aren’t unusual, often tied to a specific new source entering the mix.

    Can you actually fix a negative or outdated ChatGPT answer about your brand? 

    Not by asking the model directly. The realistic path is identifying the source content the model is likely drawing from and publishing clearer, more current information that outweighs it over time, the same content-based logic that underlies traditional SEO, just aimed at a different kind of index.

    Read More

  • How to Catch AI Hallucinations About Your Brand Before They Spread

    How to Catch AI Hallucinations About Your Brand Before They Spread

    A customer emails support asking why your pricing page doesn’t match what ChatGPT just told them. Someone checks, finds nothing wrong on the website, then realizes the AI invented a discount tier that never existed. That’s usually how brands find out about a hallucination: after someone already acted on it. Nearly half of consumers look for confirmation after seeing an AI answer, but when what they find doesn’t match, most don’t file a complaint. They just quietly go with a competitor instead.

    Your Brand Doesn’t Find Out About an AI Hallucination Until a Customer Does

    Most companies still monitor AI mentions the way they monitor reviews: reactively. Someone screenshots a wrong answer, forwards it to marketing, and only then does anyone start checking other platforms.

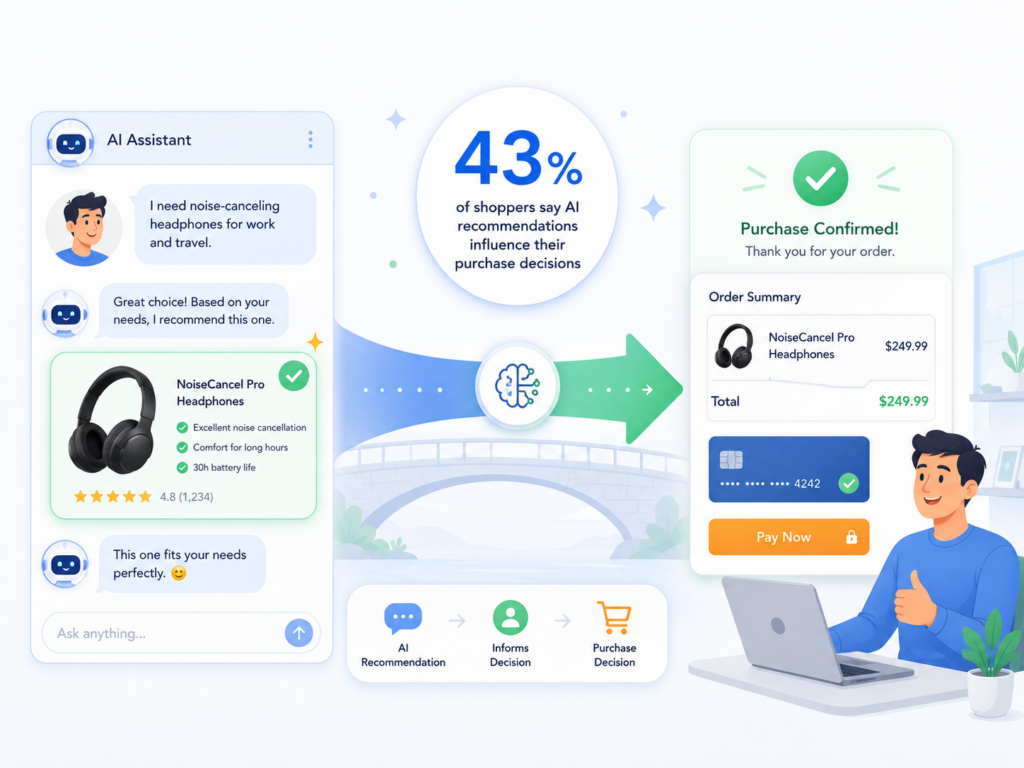
    That gap matters more than it used to. Forty-three percent of shoppers bought a product an AI chatbot recommended in the past three months, which means a wrong answer isn’t a footnote anymore. It’s sitting inside a purchase decision.

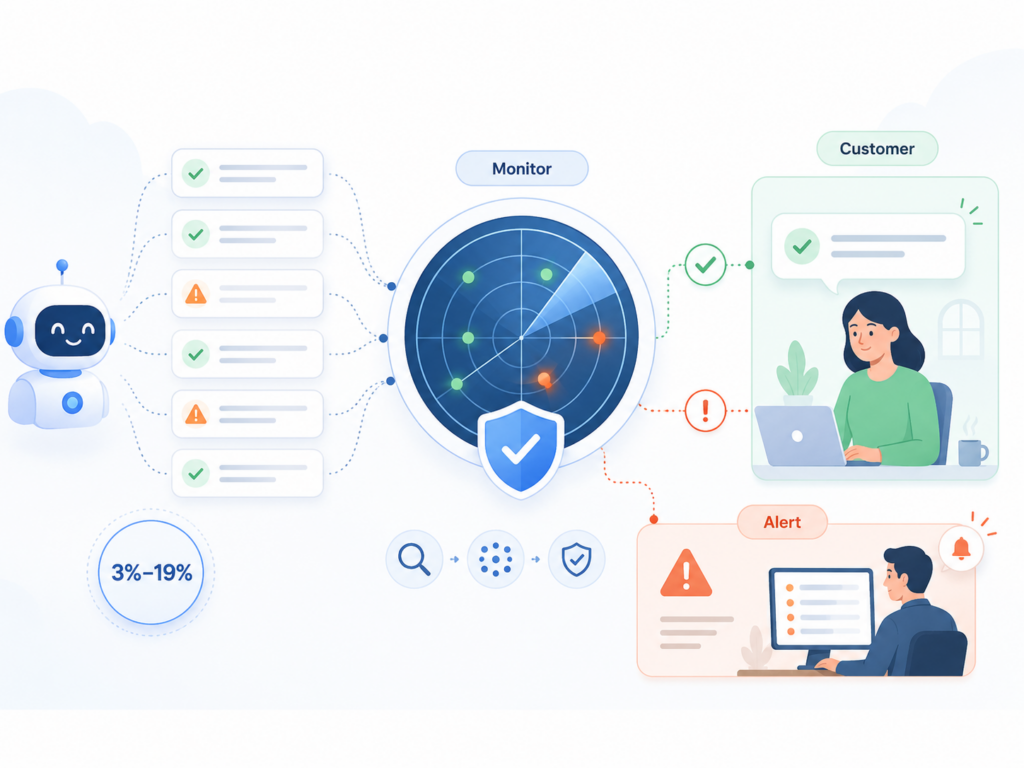
    Hallucinations aren’t rare edge cases either. A 2026 benchmark across five frontier models found hallucination rates between 3.1% and 19.1% depending on the model and the task, and citation accuracy came out as the worst-performing category. Citations are exactly what AI platforms lean on when they describe your brand.

    What Makes a Brand Hallucination Different From a Ranking Problem

    Not showing up in an AI answer is a visibility problem. Showing up with the wrong facts is a trust problem, and the two require completely different fixes.

    A ranking gap gets solved with better content and better prompts. A hallucination means the AI is actively telling people something false about your pricing, your policies, or your leadership, and repeating it with total confidence. There’s no “we’re still indexing you” excuse.

    The stakes are already visible in court records. In Walters v. OpenAI, ChatGPT fabricated a detailed embezzlement complaint against a radio host who had no connection to the case, complete with a fake case number. The suit was eventually dismissed, but the underlying lesson holds regardless of the legal outcome: a model can generate something specific, wrong, and reputation-damaging without any prompt asking it to.

    Step 1: Map Every Prompt Where Your Brand Could Get Mentioned

    You can’t monitor for hallucinations if you’re only watching your own brand name. Most of the risk sits in category questions, comparison prompts, and “is X worth it” queries where an AI is synthesizing from multiple, sometimes conflicting, sources.

    Start by listing the prompt types that actually drive traffic and decisions in your category: product comparisons, pricing questions, “alternatives to” searches, and common support questions. Then check what AI platforms are actually saying in response to each one, not just whether your brand appears.

    This is closer to prompt discovery than keyword research. You’re not optimizing for what people type into Google. You’re identifying the conversational questions where an AI might fill in a gap in its training data with something invented.

    Step 2: Watch Sentiment and Source Shifts, Not Just Mentions

    A hallucination rarely arrives as an isolated, obvious lie. It usually shows up first as a small shift: the AI’s tone about your brand turns slightly more negative, or the sources it’s citing change from your own site to a stale forum thread or an outdated review.

    Tracking mention count alone misses this. What catches it is watching sentiment and source data together, so a drop in tone lines up with a specific citation you can actually go check. That pairing is the difference between “something feels off” and “here’s the exact page the AI is pulling from, and here’s why it’s wrong.”

    In practice, this looks like running sentiment tracking and source analysis side by side across the same set of platforms, so a dip in one flags exactly where to look in the other. Topify builds this pairing into its GEO analytics, scoring brand sentiment from 0 to 100 and separately surfacing the exact domains and URLs that ChatGPT, Perplexity, and Gemini are citing when they answer questions about you.

    Step 3: Set Alert Thresholds Before a Small Error Turns Into a Pattern

    An early-warning system needs a trigger, not just a dashboard someone checks when they remember to. Without a threshold, teams either get alert fatigue from noise or miss the signal entirely because nobody’s watching that week.

    A reasonable starting point: flag anything where a factual claim about your brand appears identically across two or more platforms, or where sentiment drops by a meaningful margin within a short window. Both patterns suggest the error has already propagated past a single bad answer.

    The goal isn’t zero hallucinations. Even the best-performing frontier models still hallucinate somewhere between 3% and 19% of the time depending on the task, so some error rate is the baseline you’re working with, not a bug you’ll ever fully eliminate. The goal is catching the pattern before a customer does.

    The Mistakes That Turn One Bad Answer Into a Reputation Problem

    The most common mistake is treating a single wrong answer as the whole problem instead of asking whether it’s systemic. If the same error shows up on three platforms, fixing it once won’t fix it everywhere.

    The second mistake is confusing a correction job with a positioning job. As one AI reputation guide puts it, “ChatGPT says we have no API” is a correction task, but “ChatGPT describes us as expensive and dated” needs an entirely different playbook built around sentiment and content, not fact-checking.

    The third mistake is waiting on the platform’s own feedback tools to fix it. No major AI platform currently offers a direct brand-correction channel, and community reports from brand managers confirm that the fastest fix comes from updating the source content itself, not from thumbs-down clicks.

    Putting the System Together with Topify

    None of the three steps above work as one-off checks. A prompt list goes stale within weeks, sentiment shifts happen gradually, and thresholds only mean something if they’re being watched continuously.

    Topify’s Comprehensive GEO Analytics runs these as one connected system instead of three separate habits: prompt discovery surfaces where your brand could be mentioned, sentiment and source tracking watch for the early signals of a hallucination, and competitor benchmarking shows whether an issue is brand-specific or category-wide. Pricing starts at $99 a month on the Basic plan, which covers ChatGPT, Perplexity, and AI Overview tracking across 100 prompts, enough for most teams to get an early-warning baseline running without a big commitment upfront.

    Teams that get this right treat it the same way they’d treat uptime monitoring: quiet most of the time, and worth every minute of setup the one time it catches something before a customer does.

    Conclusion

    An AI hallucination about your brand doesn’t wait for a good time to show up, and by the time a customer flags it, the wrong answer has usually already influenced a decision. Mapping your prompts, watching sentiment and sources together, and setting real alert thresholds turns that into something you catch early instead of something you clean up late. Start with the prompts your customers are already asking, and build the monitoring habit before you need it.

    FAQ

    Q: How do I know if ChatGPT or another AI is hallucinating about my brand? 

    A: Search the prompts your customers actually ask, not just your brand name, across ChatGPT, Perplexity, and Google AI Overviews. Compare specific claims, like pricing, features, or leadership, against your actual website. A mismatch on a specific fact, not just a difference in tone, is the clearest sign of a hallucination.

    Q: Can I get OpenAI or Google to correct a hallucination about my company? 

    A: Not directly. Neither OpenAI nor Google currently offers a formal brand-correction process, and thumbs-down feedback alone rarely changes an answer. The most reliable fix is updating the source content, your website, Wikipedia, and other cited pages, so the AI has accurate material to draw from going forward.

    Q: How is an AI hallucination different from bad brand sentiment? 

    A: A hallucination is a factual error, like a wrong price or a fabricated policy. Bad sentiment is the AI’s tone or framing, such as describing your brand as outdated when it isn’t. They require different fixes: hallucinations get corrected at the source, sentiment gets addressed through content and positioning.

    Q: How often do AI models actually hallucinate? 

    A: It depends heavily on the task. Frontier models in 2026 hallucinate on roughly 3% to 19% of factual and citation-heavy queries, and the rate climbs much higher on narrow or specialized topics. That baseline error rate is one reason continuous monitoring matters more than a one-time check.

    Read More

  • People Trust AI Hallucinations About Brands More Than Facts

    People Trust AI Hallucinations About Brands More Than Facts

    A customer asks ChatGPT about your pricing before they ever land on your site. The answer sounds specific and confident: a number, a feature comparison, a claim about what you offer. It’s also wrong. Nobody at your company said it, and nobody caught it before that customer read it as fact.

    That’s the part most people get wrong about AI hallucination and brand information. They assume a mistake this visible would get flagged fast. It doesn’t. AI-generated answers carry an authority that ads and search snippets never had, and consumers extend that authority to information the model simply invented.

    Where AI Hallucinations About Brands Actually Come From

    Large language models don’t look up your website every time someone asks about you. They generate an answer based on patterns learned during training, then fill any gaps with whatever sounds statistically plausible. Sometimes that means outdated facts. Sometimes it means details that never existed at all.

    The scale of this is bigger than most brand teams assume. NP Digital’s February 2026 accuracy report tested 600 prompts across six major models and found ChatGPT topped the field with only 59.7% fully correct responses. Grok came in last at 39.6%.

    That’s not a rare glitch in an obscure model. That’s the best-performing AI assistant getting roughly two out of every five brand-related answers wrong.

    There’s also a meaningful difference between a stale fact and an invented one. A model quoting last year’s pricing is working from outdated training data, which is bad but at least traceable. A model inventing a product feature that never existed, or citing a customer review that was never written, is fabricating a detail from nothing because the pattern of a typical answer called for one. Both look identical to the person reading them.

    Why Consumers Don’t Fact-Check What AI Tells Them About a Brand

    Here’s the thing about automation bias: it gets stronger exactly when a system feels competent and the user is trying to save time. Researchers describe it as a documented tendency to over-trust and under-scrutinize an automated system’s output, and it’s most pronounced with tools that speak fluently and never hedge.

    AI assistants rarely hedge. They deliver a wrong answer with the same tone as a right one, no uncertainty markers, no “I’m not fully sure.” That confident delivery is doing more persuasive work than the actual accuracy of the content.

    A 2026 UC San Diego study puts a number on the effect. It found AI-generated summaries hallucinated 60% of the timein ways that still influenced purchase decisions, and users exposed to AI-powered summaries were roughly 30% more likely to trust incorrect outputs than they were to trust the same wrong information from a traditional source.

    Trust in AI search is actually declining overall. Fractl’s Q2 2026 survey of over 1,000 U.S. consumers found the share who rate AI as more helpful than traditional search dropped from 82% in 2025 to 54% in 2026. But general skepticism toward AI as a category doesn’t stop someone from believing a specific, confidently worded answer about your specific brand in the moment they’re reading it. Skepticism in the abstract and scrutiny in the moment are two different things, and most people only have one of them.

    Pew Research’s 2026 study captures that gap directly. Half of U.S. adults now use AI chatbots regularly, yet only 29% of those users say they have “a lot” or “some” trust in the information the chatbot gives them. That means roughly seven in ten people using these tools every day hold little or no trust in what they’re reading, and they keep reading it anyway because checking every claim isn’t practical mid-conversation.

    How One AI Hallucination Turns Into Your Brand’s Permanent Record

    A single wrong answer rarely stays a single wrong answer. Models draw on patterns across the web, including other AI-generated content that’s already circulating, so an error can get reinforced rather than corrected the next time someone asks a similar question.

    The accuracy problem extends to sourcing itself. When the Tow Center for Digital Journalism tested eight AI search toolson 1,600 queries asking them to identify the correct source of a real article, the tools collectively got it wrong more than 60% of the time. If AI struggles this much to accurately attribute information it’s citing, misattributing details about a lesser-known brand is the easier failure mode, not the harder one.

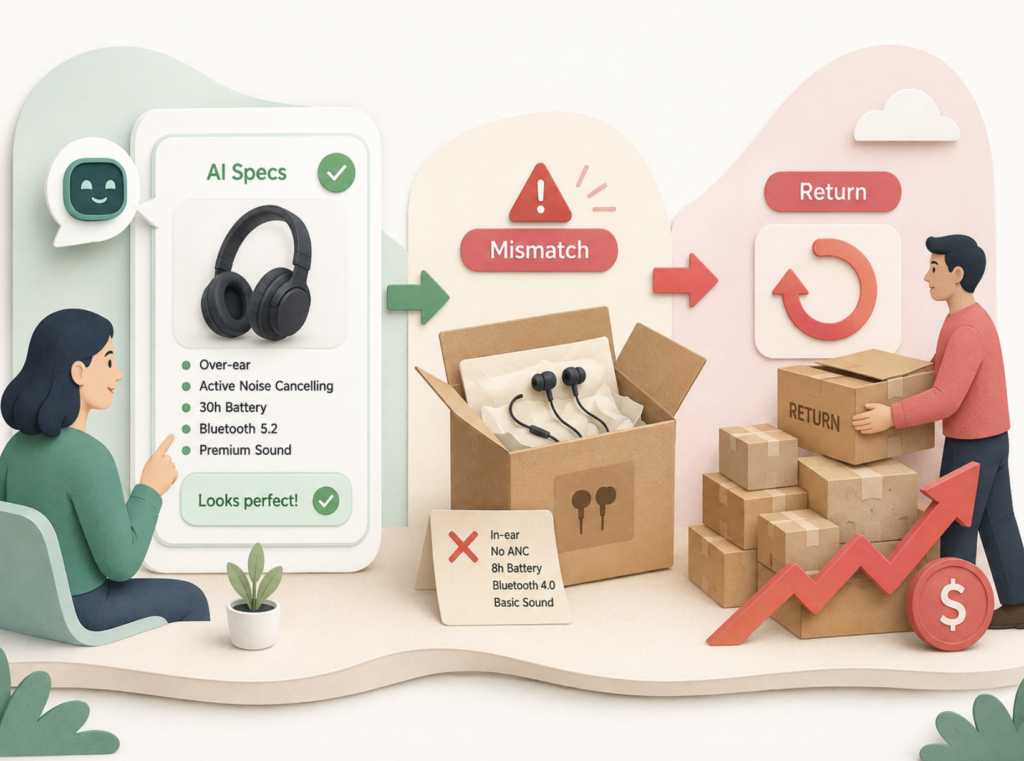
    The financial consequences are already showing up. A March 2026 report documented hallucinated product specifications causing a 25% spike in returns for one electronics brand, as customers received products that didn’t match what an AI assistant had described to them.

    This isn’t a marketing team’s edge case either. 47.1% of marketers now encounter AI-generated errors several times a week, and 36.5% report that hallucinated or inaccurate AI content has already made it into their own published workflows undetected.

    How to Catch an AI Hallucination About Your Brand Before Customers Do

    Manually asking ChatGPT about your brand once a month won’t catch this. Errors show up differently across ChatGPT, Gemini, Perplexity, and the rest, they shift as models update, and a single spot check tells you nothing about what’s happening on the platform you didn’t test.

    This is the gap Topify is built to close. Its Sentiment Analysis tracks how AI systems describe your brand across major platforms and flags when that description drifts from your actual positioning, whether that’s a pricing error, an outdated feature list, or a tone that doesn’t match your messaging.

    Source Analysis goes a step further and traces the problem to its root. Instead of just telling you an answer is wrong, it identifies the specific domains and URLs the AI is citing, so you can see whether an outdated third-party listing or a stale forum post is the actual source feeding the model’s mistake. In practice, that means you can trace a hallucinated claim about your product back to the exact webpage keeping it alive, rather than guessing.

    Visibility Tracking rounds this out by showing whether your brand is even being mentioned in the first place, since a hallucination usually starts as a gap: the model has too little reliable information about you, so it improvises to fill the space. Seeing where you’re invisible is often the earliest warning sign of where you’re about to be misrepresented.

    Teams that want to see where they stand can get started with Topify and run a baseline check across platforms before deciding what needs fixing first.

    What to Do Once You’ve Found One

    Catching a hallucination is only half the job. The fix usually isn’t a takedown request. It’s giving AI systems a better, more authoritative source to pull from than the one that’s currently wrong.

    That typically means publishing clear, specific, and current information on your own domain about the exact facts that keep getting misstated, whether that’s pricing, specs, or leadership details. Models tend to shift once a strong, well-cited alternative source becomes available, though the correction isn’t instant. Newer model updates show this is possible at scale: GPT-5.3 Instant reduced hallucinations by 26.8% on high-stakes queries once web search was enabled, which suggests accuracy responds to better source material, not just model upgrades.

    Treat this as a recurring check, not a one-time fix. Test the same core brand queries every quarter, track whether accuracy is improving or slipping, and escalate anything that touches pricing or safety claims immediately rather than waiting for the next audit cycle.

    Conclusion

    The uncomfortable part of AI hallucination and brand accuracy isn’t that models make mistakes. It’s that consumers extend AI the kind of unquestioning trust they stopped giving ads years ago, and that trust doesn’t require the model to be right, just confident. Brands that wait to notice this the way a customer does, by stumbling across a bad answer, are always a step behind. The ones that track it systematically get to correct the record before it becomes the default answer everyone remembers.

    FAQ

    Q: What exactly is an AI hallucination about a brand? 

    A: It’s when an AI chatbot generates factually incorrect information about a company and presents it as fact, such as wrong pricing, discontinued products listed as current, or fabricated features and reviews.

    Q: How common are AI hallucinations about brands? 

    A: More common than most teams assume. Even the best-performing model in a 2026 accuracy study only got 59.7% of brand-related answers fully correct, and audits regularly find factual errors in the majority of brands tested.

    Q: Why do people believe AI more than they should? 

    A: Automation bias. People tend to trust confident, fluent systems without double-checking them, especially when they’re trying to save time, and AI assistants rarely signal uncertainty even when they’re wrong.

    Q: Can a brand actually fix an AI hallucination once it starts spreading? 

    A: Yes, though it takes time. Publishing clear, authoritative, current information about the specific fact in question gives models a better source to draw from, and tracking the correction over multiple quarters shows whether it’s taking hold.

    Read More

  • Is AI Hallucination About Brands Getting Worse or Better in 2026?

    Is AI Hallucination About Brands Getting Worse or Better in 2026?

    A brand manager types their own product name into ChatGPT this month and gets back a pricing tier that hasn’t existed since 2024. It’s not a rare glitch. It’s the kind of error that shows up when you actually go looking for it.

    That’s the tension behind the headline question. Model-level benchmarks keep improving. Brand-level accuracy tells a messier story.

    Why “Better or Worse” Is the Wrong First Question

    Most people assume hallucination is a single number that goes up or down over time. It isn’t.

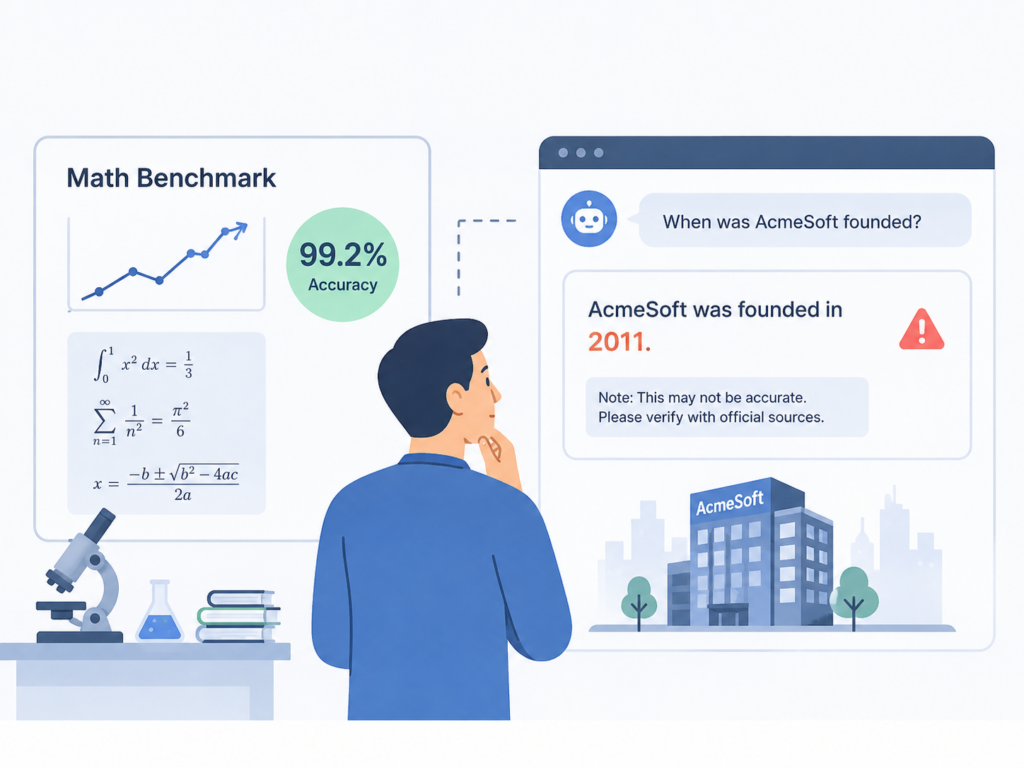
    A model can post record-low error rates on a math benchmark and still invent a founding date for a mid-size SaaS company. The two numbers don’t move together, because they’re measuring completely different failure modes.

    Hallucination is not evenly distributed. It concentrates wherever training data is thin, conflicting, or stale, and brand information happens to sit exactly in that zone.

    So the real question isn’t “is AI hallucination getting better or worse.” It’s “better or worse for what, and for whose brand.”

    What the 2026 Benchmarks Actually Show

    On the numbers that get quoted most often, 2026 looks like a genuine win. Grounded summarization tasks measured by Vectara’s HHEM leaderboard fell from a 2.5% to 8.5% range in 2024 down to roughly 1% for top models this year, a drop of about 95%.

    That’s the good news. The catch is in the task type.

    The Stanford HAI 2026 AI Index Report tested 26 top models on a harder scenario: does the model hold its answer steady when a false claim is framed as something the user personally believes, rather than something a third party believes. Under that framing, GPT-4o’s accuracy dropped from 98.2% to 64.4%. DeepSeek R1 fell from over 90% to 14.4%.

    Here’s the pattern that matters for brands. The tasks that improved most (structured summarization with a source document right in front of the model) look nothing like the tasks people run when they ask an AI assistant “what does this company do” from memory.

    Task type2024 rate2026 rateSource
    Grounded summarization (source document provided)2.5% to 8.5%~1%Vectara HHEM
    Open-ended factual recall, no source providedNot standardized3% to 19% depending on taskHHEM and 2026 benchmark aggregates
    User-belief framed false claimsNot tested at scale22% to 94% across 26 modelsStanford HAI 2026 AI Index

    Brand queries fall almost entirely into that second and third row. Nobody hands an AI assistant a source document before asking it to describe a competitor’s pricing.

    Why Brands Are a Structurally Hard Case for AI Accuracy

    A model doesn’t fail on brand facts because it’s careless. It fails because brand information behaves differently from the encyclopedic facts these systems were built to handle.

    Pricing changes quarterly. Product tiers get renamed. A company that pivoted its positioning last year still has three-year-old blog posts outranking its current homepage.

    An AI visibility report from Metricus found that 72% of brands it audited had at least one factual error surface in AI-generated responses. The errors weren’t ambiguous. They were wrong founding dates, discontinued products listed as current, and features attributed to the wrong pricing tier.

    The same report traced the errors to three root causes: conflicting information across indexed sources, information gaps the model fills with plausible-sounding guesses, and stale training data reflecting the brand as it used to be.

    That’s less about model quality and more about how messy a brand’s own footprint is across the web.

    The Small Brand Penalty

    Scale changes the odds. Research from Muck Rack found that AI models strongly favor content published in the past 12 months. When a brand has no recent coverage, older sources fill the void by default.

    A large enterprise typically has a steady stream of press mentions, review updates, and fresh content refreshing what the model sees. A smaller or newer brand often doesn’t. When the model needs to answer a question and finds a gap instead of a source, it doesn’t say “I don’t know.” It generates something plausible instead.

    That’s the small brand penalty. Not more errors because the model dislikes small brands, but more errors because there’s less recent, consistent material to anchor the answer.

    How to Tell If You’re Being Misrepresented, Not Just Mentioned

    Two very different risks get lumped under “AI visibility” and they need separate answers.

    The first is absence: your brand doesn’t come up when it should. That’s frustrating, but it’s a visibility gap, not a hallucination.

    The second is misrepresentation: your brand comes up, and what’s said about it is wrong. This one is more dangerous because it looks like the AI is doing its job. Nobody double-checks an answer that arrives with total confidence.

    Legal precedent is starting to catch up with this distinction. In the widely cited Air Canada case, a tribunal ruled the airline liable for its chatbot’s fabricated refund policy, treating the bot’s output as an extension of the company’s own voice. The airline had to honor the incorrect policy and later pulled the chatbot altogether.

    Regulation is moving the same direction. The EU AI Act’s Article 50 transparency requirements, enforceable from August 2, 2026, require AI-generated content to be labeled appropriately, a sign that accuracy accountability for AI outputs is becoming a compliance question, not just a reputational one.

    Consumers already feel the risk. Forbes and Gartner research cited by Firney found that over 70% of consumers are worried about AI-generated misinformation, well before most of them can name a specific incident.

    Manually testing this is possible but limited. Typing a handful of prompts into ChatGPT once a month tells you what happened in that moment, on that platform, with that exact phrasing. It won’t tell you whether the error is a one-off or a pattern, and it definitely won’t tell you which source is feeding the mistake.

    Turning AI Accuracy Into a Trackable Metric

    If misrepresentation is the risk that matters most, the fix has to work at the same scale as the problem. That means moving past occasional spot checks toward something closer to continuous measurement.

    Topify approaches this through two connected functions. Sentiment Analysis scores how AI platforms describe a brand on a 0-100 scale, catching not just whether the tone is positive or negative but whether the description has drifted from what’s actually true. Source Analysis goes one layer deeper, tracing exactly which domains an AI model pulled its answer from, so a brand can see whether the error originated from an outdated review site, a stale Wikipedia entry, or a competitor’s comparison page.

    That combination changes what a correction looks like in practice. Instead of “we noticed ChatGPT said something wrong,” it becomes “this specific outdated page is the source, here’s the correction path, and here’s the sentiment score before and after the fix goes live.”

    For a multi-product SaaS brand with pricing tiers that shift often, that means catching a stale price point before it costs a lead. For a newer brand still building its content footprint, it means knowing exactly where the information gaps are before an AI model fills them on its own.

    Either way, the goal isn’t chasing a lower hallucination percentage in the abstract. It’s knowing, with actual data, whether your brand specifically is being described accurately this month compared to last month.

    Conclusion

    The honest answer to the headline question is: it depends which brand you are. Model-level hallucination on structured, source-grounded tasks has genuinely improved, dropping by something like 95% since 2024 on the benchmarks that measure it best. But brand-level accuracy, especially for smaller companies or fast-changing product lines, hasn’t moved nearly as much, because the underlying problem isn’t model capability. It’s messy, inconsistent, and stale source material.

    Guessing which category your brand falls into isn’t a great strategy. Building a baseline is. Once you know how your brand is actually being described across AI platforms this quarter, you have something to compare against next quarter, and a source to point to when something needs fixing.

    FAQ

    Is the AI hallucination rate actually improving in 2026? 

    On grounded, source-provided tasks, yes, with reported drops of roughly 95% since 2024 according to Vectara’s leaderboard. On open-ended factual recall, the kind of query most brand-related questions fall into, rates still run between 3% and 19% depending on the benchmark and task.

    How do I check if ChatGPT is wrong about my brand? 

    Manual prompting across ChatGPT, Perplexity, and Gemini can surface obvious errors, but it only captures a single moment and phrasing. A recurring audit that tracks sentiment and traces citation sources over time catches patterns that one-off checks miss.

    Why does AI make up false information about smaller or newer brands more often? 

    AI models favor recently published, consistent content. Larger brands tend to generate a steadier stream of that material. When a smaller brand has content gaps, the model fills them with plausible-sounding guesses instead of leaving the answer blank.

    Can a brand be held legally responsible for what an AI says about it? 

    Precedent is still developing, but the Air Canada ruling established that a company can be held liable for its own chatbot’s fabricated claims, on the reasoning that the AI’s output counts as the company’s voice. Regulatory frameworks like the EU AI Act are adding separate transparency obligations on top of that.

    Read More

  • AI Is Making Up Prices and Features for Your Ecommerce Brand

    AI Is Making Up Prices and Features for Your Ecommerce Brand

    A customer messages your support team with a screenshot. ChatGPT told them your product is 30% off this week. It isn’t. Now they’re asking why your site won’t honor “the price you advertised,” and your agent has no idea what they’re even talking about, because your brand never said that anywhere.

    This is what AI hallucination looks like when it hits an ecommerce brand: not an abstract AI safety debate, but a support ticket, a chargeback, or a one-star review over something you never actually did.

    Why AI Hallucination Brand Risk Is a Real Ecommerce Problem

    Large language models don’t retrieve facts the way a database does. They predict the next most likely word based on patterns, and when the exact price, spec, or policy isn’t sitting in front of them, they fill the gap with something plausible. That’s the entire mechanism behind an ai hallucination brand incident: not malice, just probability doing its job badly.

    Ecommerce sits right in the blast radius. Prices and promotions change weekly. Stock levels shift daily. Product specs get added or dropped between SKUs. Every one of those is a moving target that AI models struggle to track in real time, which is exactly the kind of task where hallucination rates spike.

    The scale of exposure keeps growing too. Roughly 43% of U.S. online shoppers used an AI assistant for product research in the past 90 days, and among AI users, 20% relied on it for their most recent purchase over $50. ChatGPT alone now handles an estimated 50 million shopping queries a day. Every one of those queries is a chance for the model to get something about your brand wrong, in front of a customer who’s ready to buy.

    Wrong Prices: When AI Quotes a Discount You Never Offered

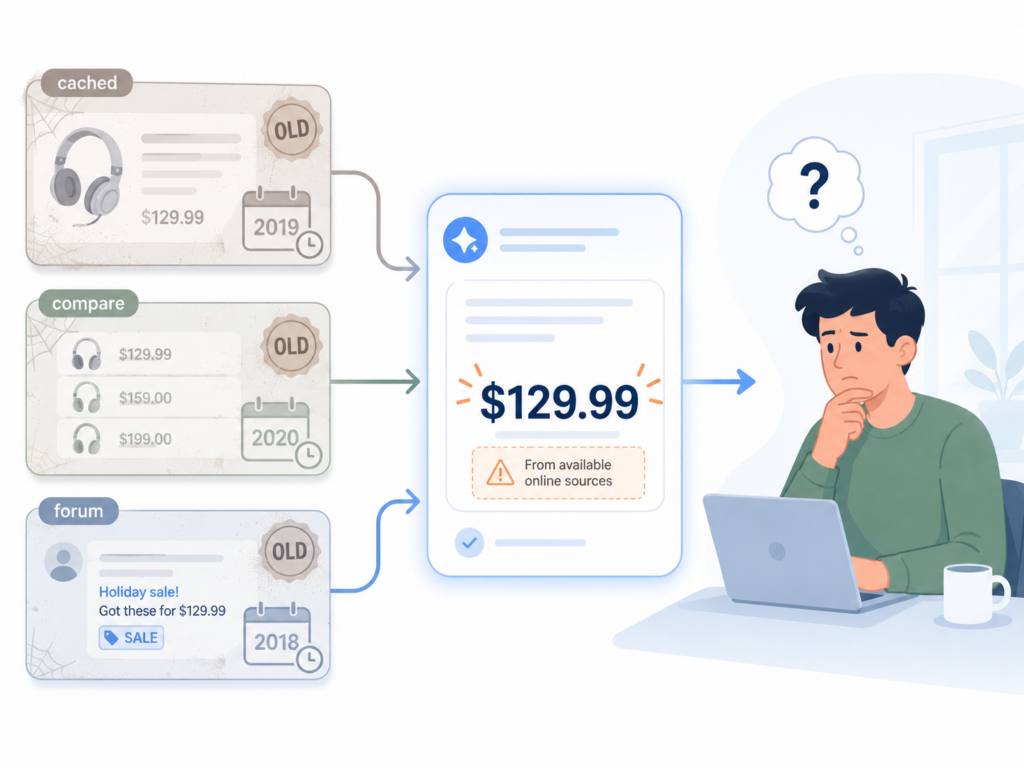
    Price hallucinations tend to follow a pattern. The model pulls from an outdated cached page, a stale comparison site, or a forum post about last season’s sale, then presents it as current fact. The customer has no way to know the number came from six months ago instead of today.

    This isn’t hypothetical. A UK retailer’s after-hours support bot was talked into inventing discount codes during a single conversation, escalating from 25% off to 80% off. A customer used the fabricated code on an order worth more than £8,000 and threatened legal action when the store wouldn’t honor it. The business ultimately canceled and refunded the order to avoid the fight.

    Courts have already made clear that “the bot said it, not us” doesn’t hold up. In Moffatt v. Air Canada, a tribunal ruled the airline liable after its chatbot invented a bereavement fare policy that didn’t exist. The precedent applies just as directly to a shopping assistant that makes up a price. Whatever the model says about your brand, you’re the one who answers for it.

    The FTC has started treating this as a consumer protection issue, not just a brand annoyance. Its March 2026 complaint against OpenAI over ChatGPT’s Instant Checkout feature cited a 22% rise in disputed charges reported by Shopify merchants in the 90 days after the feature launched. That’s real chargeback volume tied directly to AI getting checkout details wrong.

    Fake Features: AI Inventing Specs Your Product Doesn’t Have

    Feature hallucinations usually show up when a product page is thin on detail. If your listing doesn’t explicitly say “not waterproof,” the model may borrow a spec from a similar-looking competitor product and hand it to the customer as fact.

    The cost lands squarely on your return rate. Inaccurate item descriptions already account for about 14% of ecommerce returns, and some retailers put the figure closer to 22% when features, size, and color mismatches are combined. Returns tied to “product not as described” were already expensive before AI started adding its own version of the description on top of yours.

    Here’s the part that makes this worse than a typo on your own site: you don’t control the wording, and you often don’t even know it exists until a customer complains. A shopper who orders based on a feature AI invented isn’t disappointed in the AI. They’re disappointed in you.

    Bad Reviews: When AI Summarizes Sentiment That Isn’t There

    The most researched form of AI hallucination in shopping isn’t about specs or prices. It’s about how AI reframes what other people said about your product.

    A University of California, San Diego study tested this directly. Researchers had AI models summarize the same set of product reviews people had already read, then asked a separate group of participants whether they’d buy based on the summary. The results were stark: 83.7% said yes after reading the AI summary, compared to 52.3% who read the original human-written reviews. The AI summaries consistently reframed the tone to sound more positive than the source material.

    Here’s the part that should worry any brand watching this trend: the researchers found the AI hallucinated 60% of the timewhen asked about details not present in its training data. That means the summary swaying your customer’s decision might be built partly on invented detail, and it’s swaying them harder than the truth would.

    This cuts both ways. Right now, a favorably distorted summary might be quietly inflating your conversion rate. The same mechanism can just as easily flip and summarize your weakest reviews as your defining trait, with no warning and no way for you to correct it before a shopper reads it.

    How to Catch AI Hallucination Before It Costs You a Customer

    You can’t fix what you can’t see. The first step isn’t correcting AI, it’s finding out what AI is actually telling people about your brand right now, across every platform they might be asking.

    That’s the gap Topify is built to close. Its Sentiment Analysis tracks how AI platforms describe your brand over time, on a 0 to 100 scale, so a shift toward inaccurate or off-brand language shows up as a trend line instead of a surprise complaint. If ChatGPT starts describing your premium product as “budget-friendly,” or a price detail drifts from what’s actually on your site, you see the change before it reaches a hundred customers.

    Sentiment alone tells you something’s wrong. Source Analysis tells you where it came from. Topify traces the specific domains AI platforms are citing when they talk about your brand, which turns “the AI is wrong somewhere” into “this outdated comparison site is the source, and here’s who to contact to get it fixed.” That’s the difference between guessing and actually closing the loop.

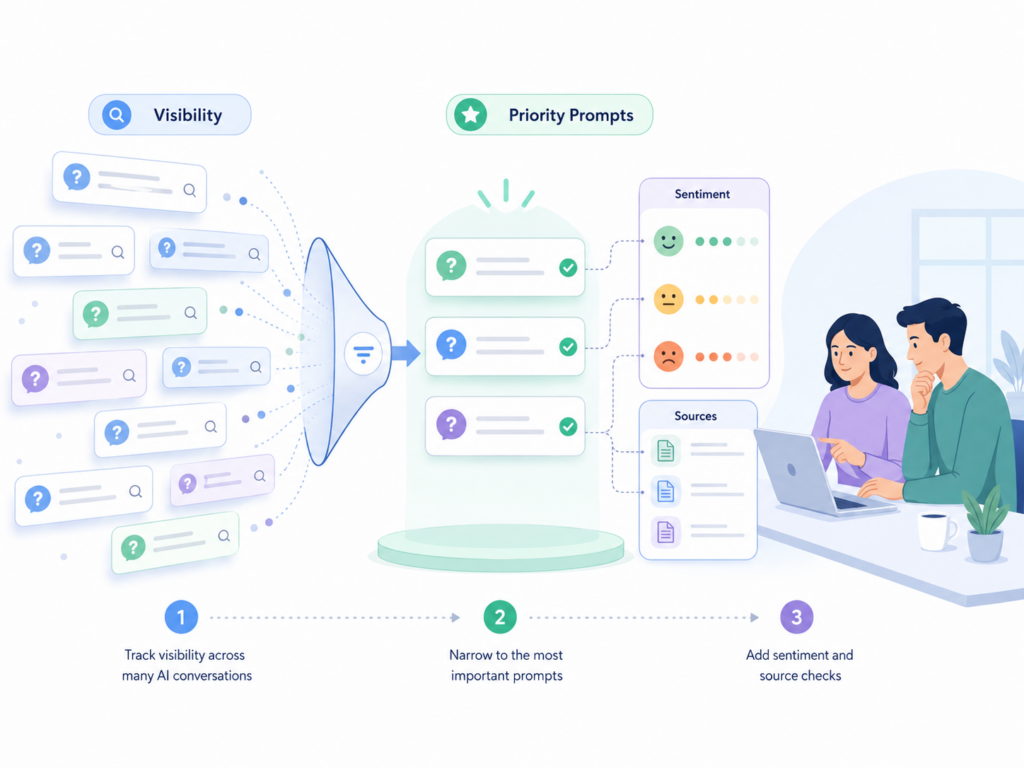
    Visibility Tracking rounds this out by showing which prompts and questions actually surface your brand in the first place, so you know where to focus the monitoring instead of trying to watch every possible AI conversation at once. In practice, most teams start there, narrow down to the prompts that matter for their category, then layer in sentiment and source checks on top.

    None of this requires a rebuild of your product pages overnight. It requires knowing, on an ongoing basis, what’s actually being said, so you can get started fixing the source instead of reacting to the fallout one customer at a time.

    Conclusion

    AI hallucination isn’t a rare glitch anymore. It’s a predictable byproduct of how these models fill gaps in price, feature, and review data, and ecommerce brands sit directly in the path of that gap-filling. The brands that get hurt aren’t the ones with the most AI mentions. They’re the ones who find out what AI said about them only after a customer already acted on it.

    The fix starts with visibility into what’s actually being said, not a reaction plan for after it goes wrong.

    FAQ

    Q: What is AI hallucination in the context of a brand? 

    A: It’s when an AI model like ChatGPT, Gemini, or Perplexity generates false information about a brand, such as a price, product feature, or review summary, that has no basis in the brand’s actual data. The model isn’t lying on purpose. It’s predicting plausible-sounding text to fill a gap where accurate information wasn’t available.

    Q: Why are ecommerce brands more exposed to this than other industries? 

    A: Prices, promotions, and stock levels change constantly, and product specs vary across similar-looking SKUs. That volatility makes it harder for AI models to stay current, and easier for them to substitute an outdated or borrowed detail for the real one.

    Q: Can a brand hold an AI platform accountable for hallucinated information? 

    A: Courts have generally held companies responsible for what their own chatbots tell customers, as seen in the Air Canada bereavement fare case. For third-party AI platforms like ChatGPT or Gemini, there’s currently no direct mechanism to force a correction, which is why monitoring what’s being said matters more than trying to litigate after the fact.

    Q: How can a brand find out what AI is saying about it? 

    A: Ongoing monitoring across the AI platforms shoppers actually use is the only reliable method, since these answers change from one query to the next and aren’t indexed anywhere a brand can simply search. Tools built for AI visibility, sentiment, and source tracking exist specifically to make this monitorable instead of anecdotal.

    Read More

  • How to Fix AI Hallucinations About Your Brand

    How to Fix AI Hallucinations About Your Brand

    A customer forwards you a ChatGPT screenshot claiming your company shut down last year, or got acquired, or dropped the feature they were about to buy. None of it is true. Your first instinct is to find someone to complain to, maybe even a lawyer. That instinct is understandable, and it’s also the slowest possible way to fix the problem.

    AI hallucination brand incidents are not rare edge cases anymore. Long-tail factual questions, which is exactly what “tell me about [your company]” is to a model that has never seen your brand at scale, hallucinate at 15 to 40 percent even on frontier models. If your brand isn’t a household name, you’re squarely in that long tail.

    Why AI Invents Facts About Your Brand in the First Place

    Models don’t check a master database before answering. They predict the most statistically likely next words based on training data and whatever pages they retrieved live. When your brand barely shows up in that mix, the model fills the gap with something that sounds plausible.

    That’s a technical explanation, not an excuse. OpenAI’s own SimpleQA benchmark, which tests short factual recall from memory, put o3’s hallucination rate at 51 percent and o4-mini’s at 79 percent on that exact kind of query. Frontier models have gotten dramatically better on easy, grounded tasks. Top models now fabricate facts less than 1 percent of the time on simple summarization, down from 15 to 20 percent two years ago. Open-ended brand questions aren’t the easy case.

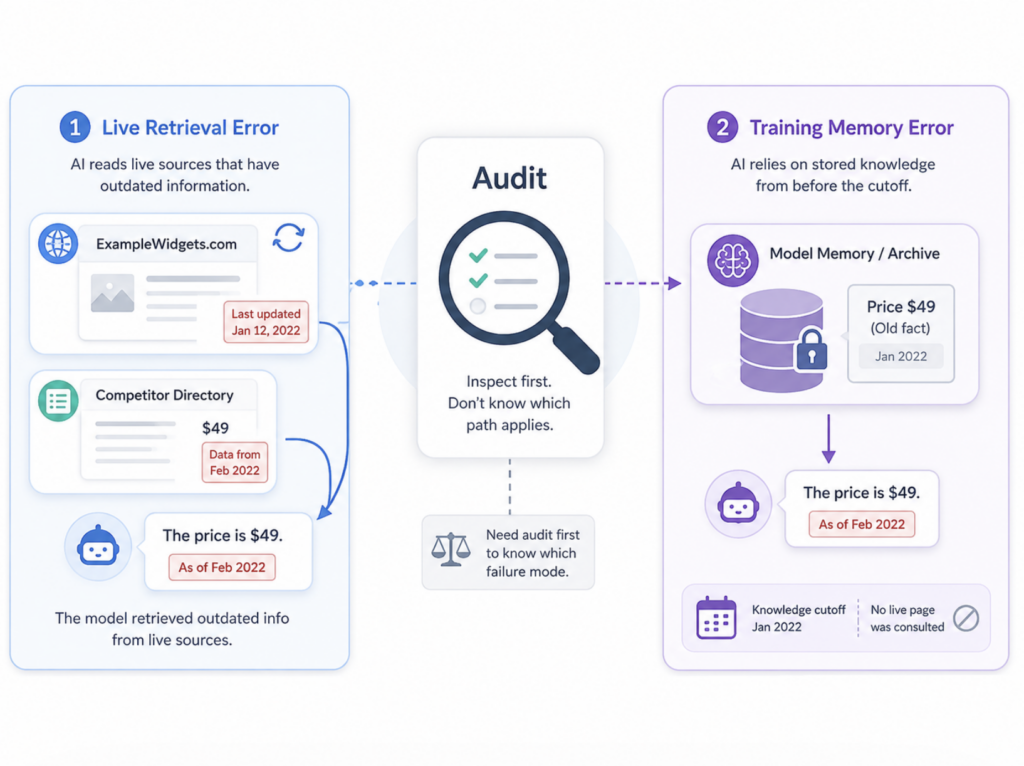
    There are really two different failure modes here, and they need different fixes. A live retrieval error happens when the model reads a real page, yours or a competitor’s directory listing, and repeats something outdated from it. A training-memory error happens when the model absorbed something wrong before its knowledge cutoff and has no live page to correct it. You can’t tell which one you’re dealing with until you audit.

    A Lawsuit Won’t Update What ChatGPT Says Tomorrow

    Suing the AI company feels like the obvious move when the fabrication is bad enough to hurt your reputation. It’s worth understanding what that path actually looks like before you spend six figures on it.

    The most developed case so far is Walters v. OpenAI. Radio host Mark Walters sued after ChatGPT told a journalist he’d embezzled funds from a gun rights nonprofit, a claim that was entirely invented. In May 2025, a Georgia judge dismissed the case, ruling that Walters hadn’t shown OpenAI acted with negligence or actual malice. The court leaned heavily on the fact that OpenAI’s terms of use repeatedly warn that ChatGPT may produce inaccurate information, and that a reasonable reader should know not to treat chatbot output as verified fact.

    That’s the pattern so far across this first wave of cases. Courts are skeptical of holding AI companies liable for what their models happen to invent, largely because disclaimers do a lot of legal work. There’s also no formal channel for correcting a business fact the way you’d request a correction from a newspaper. As one legal analysis put it plainly, there’s no fact-correction submission route for business information at all.

    None of this means legal counsel is never the right call. A fabricated criminal accusation or a claim that causes measurable, provable financial damage is a different situation than a wrong founding year. But for the vast majority of brand hallucinations, waiting on a legal outcome that could take two years just leaves the wrong answer live in the meantime. The faster path runs through your own content, not the courtroom.

    Find Every Source Feeding the Wrong Answer

    Before fixing anything, you need to know exactly what’s broken and where it’s coming from. Skipping this step is the single biggest reason corrections don’t stick.

    Test the same set of prompts across ChatGPT, Claude, Perplexity, Gemini, and Copilot. Use the actual questions a prospect would type, not just your brand name in isolation. Screenshot every answer, and when the model cites sources, open every linked page and find the specific sentence driving the claim.

    This is where most teams get the diagnosis wrong. A wrong price on your pricing page is a five-minute fix. A fabricated claim with no traceable source at all is a training-memory problem that no amount of editing your website will resolve overnight. Sort your list of errors by which category they fall into before you decide what to do next.

    Inconsistent facts across the web make this worse. If your homepage, your LinkedIn page, and a three-year-old directory listing all say something slightly different, the model has to guess which version is authoritative, and it often guesses wrong. Entity salience, meaning how confidently a system recognizes your company as a distinct, well-documented entity, depends on repetition and consistency across trusted sources.

    This is also exactly the kind of gap Topify’s Source Analysis feature is built to close. Instead of manually opening a dozen tabs across five AI platforms, it reverse-engineers which domains and URLs each model is actually citing when it talks about your brand, so you can see the pattern instead of guessing at it.

    Fix the Evidence AI Is Actually Reading

    Once you know the source, correct it there, not in a chat window. Arguing with the model inside a single conversation only fixes that one conversation. The next user who asks the same question gets the same wrong answer, because nothing about the model’s underlying knowledge changed.

    Start with your own pages. Update the specific page that’s out of date, and make sure the correct fact appears in plain language near the top, not buried in a paragraph. A four-step correction process that’s held up well in practice: identify the exact false claim and its correct replacement, update every signal the model can read including your schema markup and any llms.txt feed, prompt crawlers to re-index the corrected pages, then keep checking until the fix actually shows up in answers.

    Third-party sources matter just as much as your own site, sometimes more. Claim and correct your Bing Places listing, since it directly feeds what ChatGPT says about local and business details. Update your Google Business Profile too. Where a platform offers direct feedback, like ChatGPT’s thumbs-down or Perplexity’s citation flag, use it. It won’t fix things instantly, but it adds another signal on top of the source-level fix.

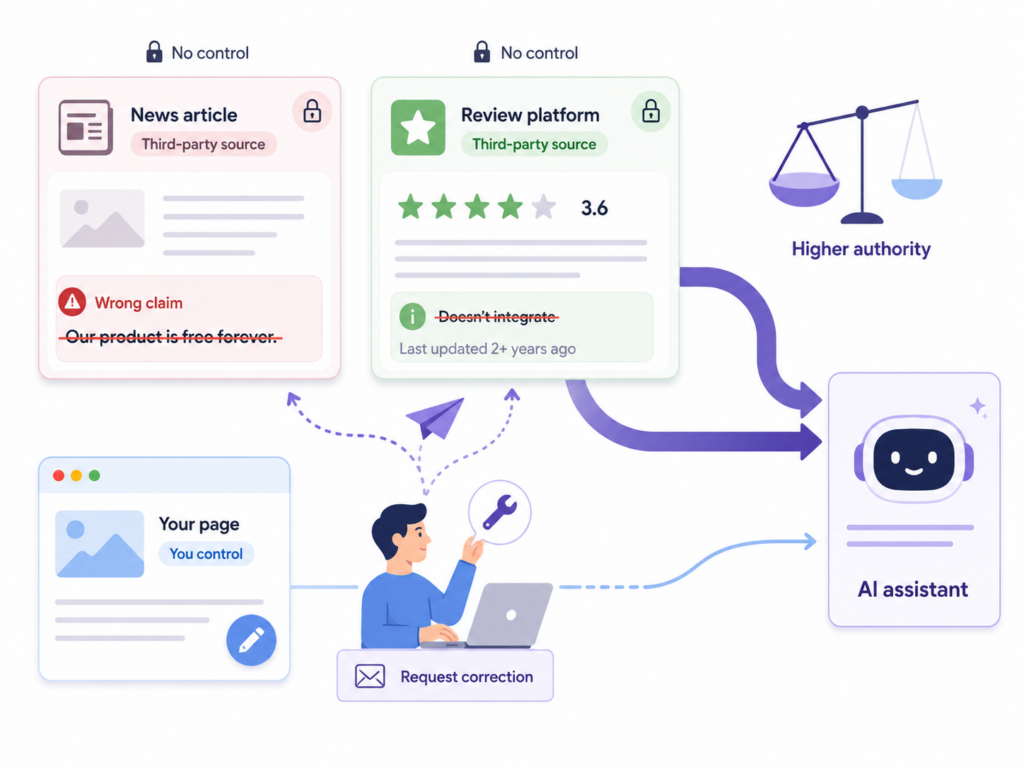
    If the wrong claim is repeated on a high-authority third-party site you don’t control, like an old news article or a review platform, reach out and request a correction the same way you would for any factual error in the press. It’s slower than editing your own page, but those pages often carry more weight with the model than your own marketing copy does.

    Re-Test the Exact Prompts That Triggered the Hallucination

    Correcting the source and assuming the problem is solved is the most common mistake in this whole process. Models don’t refresh instantly, and a training-memory error can persist for months after the source is fixed, simply because no new training run has happened yet.

    Go back to the exact prompts from your original audit and run them again, on a schedule, not just once. Live retrieval errors tend to clear up within days to a few weeks once the source page updates and gets re-crawled. Training-memory errors can outlast that by a wide margin, and there’s genuinely no way to force a model provider to retrain on your schedule.

    This is the point where manual tracking starts to break down. Checking the same twenty prompts across five platforms by hand, every week, isn’t a task most marketing teams have the bandwidth for. Topify’s High-Value Prompt Discoverysurfaces the exact prompts your audience is actually asking, across ChatGPT, Perplexity, Gemini, and other major platforms, so re-testing becomes a standing process instead of a one-time scramble you have to remember to repeat.

    Set Up Monitoring So the Correction Actually Holds

    Here’s the part that surprises most brands: a hallucination you fixed six months ago can come back. Models get retrained, the web gets re-crawled, and an old, uncorrected copy of a page can resurface from an archive or a scraper site that never got the update.

    Global losses tied to AI hallucinations reached $67.4 billion in 2024, and incorrect AI outputs now contribute to roughly 30 percent of AI-related reputational incidents tracked across organizations. That’s not a one-time cleanup problem. It’s an ongoing category of risk that needs the same kind of standing measurement you’d give to site traffic or brand sentiment.

    This is where a comprehensive GEO analytics approach earns its keep. Topify tracks Visibility, Sentiment, and Position together across major AI platforms, so a hallucination doesn’t just get caught once during an audit, it gets flagged the moment it reappears. Basic plans start at $99 a month with tracking across ChatGPT, Perplexity, and AI Overviews, which is a fairly small line item next to the cost of a single lost enterprise deal because a prospect trusted a fabricated claim.

    When It’s Serious Enough to Call a Lawyer

    Objectively, most hallucinations don’t rise to this level. But a handful do. A fabricated criminal accusation, a false claim your product caused physical harm, or a pattern of repeated defamatory statements after you’ve documented good-faith attempts to correct the source are all situations where legal counsel belongs in the conversation.

    Even then, treat it as running in parallel with the content-side fix, not instead of it. The Air Canada chatbot case, where a tribunal ordered the airline to honor incorrect bereavement-fare information its own chatbot gave a customer, shows that legal exposure for AI-generated claims is real. It also involved a company-owned chatbot, a meaningfully different situation from a third-party model hallucinating about you with no contract between you and the user at all.

    Conclusion

    Suing an AI company over what it says about your brand is slow, expensive, and unlikely to change tomorrow’s answer even if you win. Fixing the actual source data, correcting it everywhere it lives, and re-testing until the fix sticks is slower to feel satisfying but far more likely to work. Set up recurring checks now, because the same hallucination has a real chance of coming back once a model gets retrained.

    FAQ

    Q: Why does ChatGPT make up information about my company? 

    A: Models predict likely text rather than checking a verified database. When your brand has thin or inconsistent coverage across the web, the model fills gaps with plausible-sounding guesses instead of admitting it doesn’t know.

    Q: Can I sue an AI company for false information about my business? 

    A: You can, but the first wave of cases, including Walters v. OpenAI, has favored AI providers so far, largely because of disclaimers stating the tools can be inaccurate. Legal action tends to make sense only for serious, provable harm, not routine factual errors.

    Q: How long does it take for an AI correction to show up in answers? 

    A: Live retrieval errors, where the model reads a page directly, can clear up within days to a few weeks after you fix the source and it gets re-crawled. Training-memory errors baked into the model before its knowledge cutoff can take months, since they only clear on the provider’s next training cycle.

    Q: Does reporting a wrong answer through ChatGPT’s feedback button actually fix it? 

    A: It can help, but it’s not a guaranteed fix on its own. Treat feedback buttons as one signal alongside correcting the underlying source content, not a replacement for it.

    Read More

  • How to Detect if AI Is Hallucinating Facts About Your Brand

    How to Detect if AI Is Hallucinating Facts About Your Brand

    You’ve spent two years positioning your product as enterprise-grade. Then a customer mentions that ChatGPT described you as “great for solo founders on a budget.” Gemini says something different again. Neither matches your messaging, and neither is technically a lie. It’s a guess, delivered with total confidence, and nobody on your team was watching for it.

    Why AI Gets Your Brand Facts Wrong in the First Place

    Large language models don’t look things up every time they answer a question. When they’re asked something from memory rather than pulled from a live source, they generate the most statistically likely answer, not the verified one.

    That distinction matters more than most people realize. On grounded tasks, where the model has a document in front of it, frontier models hallucinate on roughly 1 to 2.5 percent of summaries in 2026, down sharply from a few years ago. Ask the same model a closed-book factual question from memory, and the error rate climbs fast.

    Task typeTypical hallucination rate in 2026
    Grounded summarization1.0% to 2.5%
    RAG-based retrieval4% to 9%
    Long-tail factual recall15% to 40%
    Multi-turn conversationUp to 19%

    Brand facts fall closer to the risky end of that range. Your pricing, your founding story, your feature list: these are exactly the closed-book questions where the model is reconstructing an answer from scattered, sometimes outdated, mentions across the web rather than checking a source in real time.

    This isn’t a bug that gets patched. It’s how the underlying mechanism works, and it means every brand is exposed by default.

    The Manual Check: Prompting AI Platforms Yourself

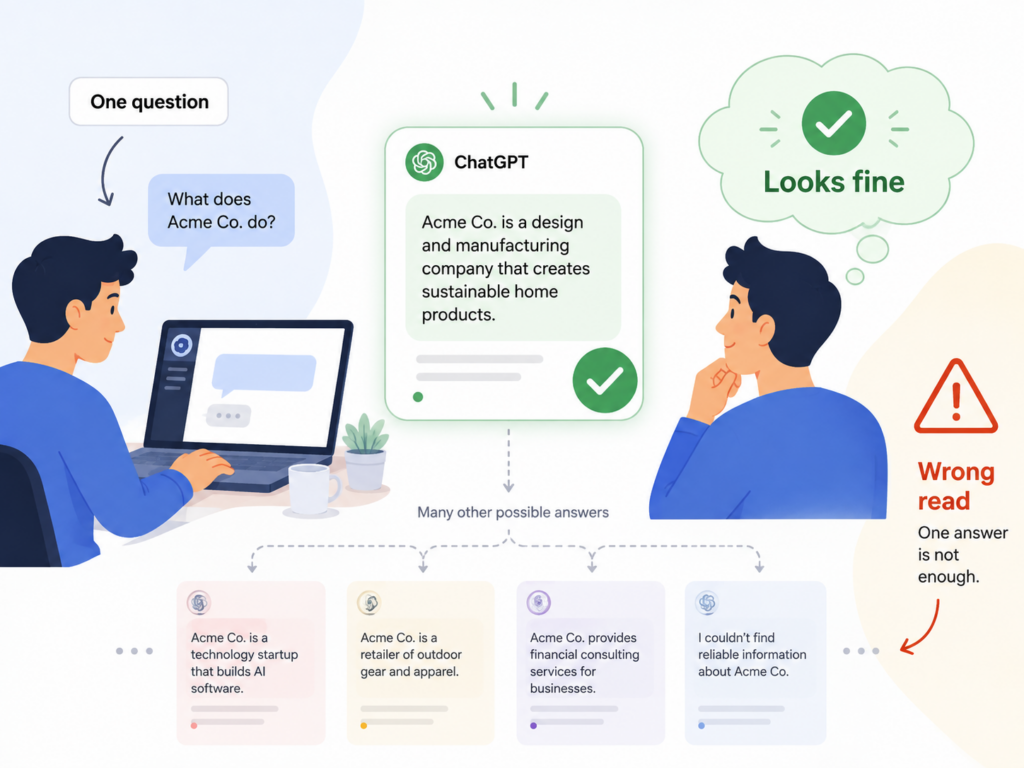
    The first thing most people do after hearing about AI hallucination is ask ChatGPT one question about their brand, get a reasonable-sounding answer, and assume it’s fine. That’s the wrong way to read the result.

    A single clean answer tells you nothing about the other 40 prompts a prospect might type. A proper manual audit means running a structured set of questions across every platform your audience actually uses:

    • Factual prompts: pricing, founding date, headquarters, core features
    • Comparison prompts: how you’re positioned against named competitors
    • Recommendation prompts: whether the model suggests you for relevant use cases
    • Sentiment prompts: how the model characterizes your brand overall

    Run each set on ChatGPT, Gemini, Perplexity, Google AI Overviews, and Claude, and record the exact response, not a paraphrase. Different platforms pull from different training data and different live sources, so the same question routinely produces different answers depending on where you ask it.

    The manual version of this works. It’s also slow, easy to under-sample, and gives you a single snapshot that starts going stale the moment a new article gets indexed.

    What Counts as a Hallucination vs a Simple Outdated Fact

    Not every wrong answer is an AI hallucination in the strict sense, and the distinction changes what you do about it.

    An outdated fact means the AI found a real source, it’s just old: last year’s pricing page, a team bio for someone who left two years ago, a press release from a pivot you’ve since moved past. A true hallucination is different. It’s the model inventing a detail with no source behind it at all, a feature that doesn’t exist, a partnership that never happened, a founder story that’s simply made up.

    The fix differs accordingly. Outdated facts get corrected by updating and re-indexing the source. Fabricated ones require finding out why the model felt confident enough to invent something in the first place, which usually points to a gap: there’s no clear, authoritative answer available anywhere for the model to have found.

    Why Sentiment Shifts Are Often the First Warning Sign

    Most brand hallucinations don’t announce themselves as an obviously wrong sentence. They show up first as a change in tone.

    Before a factual error gets caught, it often nudges how an AI platform talks about you. A model that starts describing your product as “budget-friendly” when you’re positioned as premium isn’t lying outright. It’s drawing on a source that misrepresents you, and the sentiment drift is the visible symptom.

    That’s the gap most brands can’t see with a one-off prompt test. Catching a sentiment shift early means you can investigate the source before it hardens into a repeated, confidently stated wrong answer.

    This is where continuous monitoring earns its keep over manual spot checks. Topify’s Sentiment Analysis feature tracks how AI platforms characterize your brand over time and flags meaningful swings, so a drift in tone becomes a signal to dig deeper rather than something you notice by accident three months later.

    Tracking Down Where the Wrong Information Came From

    Once you’ve confirmed a hallucination, the next question is where it came from. AI systems mostly don’t invent claims from nothing. They synthesize from whatever’s out there, and if the answer is wrong, some source in that mix is the reason why.

    The starting point is often closer to home than expected. A surprising share of brand misinformation traces back to the brand’s own website: an old pricing table buried in a forgotten blog post, a service description that never got updated after a pivot, a press page still showing a 2023 announcement front and center.

    Beyond your own site, the model may be pulling from a stale review, a competitor’s comparison page, or an old news article that got republished with outdated numbers still intact. Web mentions correlate with AI citations at roughly three times the strength of backlinks, which means the sources shaping what AI says about you are broader than your typical SEO backlink profile.

    This is the specific job Topify’s Source Analysis handles: it surfaces the exact domains and URLs an AI platform is citing when it talks about your brand, so instead of guessing, you get a direct path from the wrong answer back to the page responsible for it.

    Building a Recurring Check Instead of a One-Time Audit

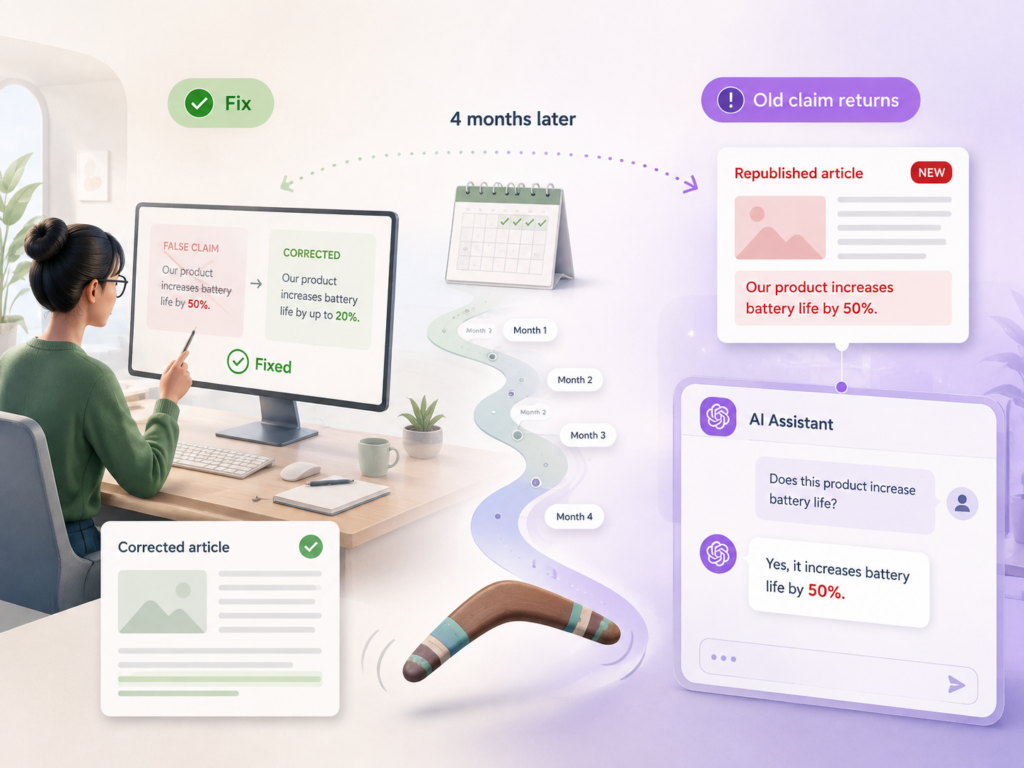
    Here’s the part that catches people off guard: a fix that worked last quarter can quietly come undone. One monitoring specialist described correcting a client’s misinformation, only to watch ChatGPT start repeating the same wrong claim four months later after the model ingested a newly republished article with the old, incorrect details.

    That’s not an edge case. It’s the normal lifecycle of AI-indexed information. Models get updated, new articles get crawled, and old errors resurface without warning. A single audit tells you where things stood on the day you ran it, nothing about the day after.

    Treating this as an ongoing operational check rather than a project with an end date is the only version of this that actually holds. That’s what Visibility Tracking, Sentiment Analysis, and Source Analysis are built to do together inside Topify: a fixed set of brand prompts running on a schedule, sentiment and factual drift flagged automatically, and a direct line back to the source whenever something changes. You find out an error resurfaced the week it happens, not the week a prospect mentions it on a sales call.

    Conclusion

    AI hallucination about your brand isn’t a rare glitch. It’s a structural side effect of how these models answer closed-book questions, and it’s already shaping what prospects hear before they ever talk to your team. A manual prompt audit is the right place to start. Ongoing, cross-platform monitoring is what keeps a fixed error from quietly coming back.

    FAQ

    Q: How often does AI actually get brand facts wrong? 

    A: It depends heavily on the type of question. Grounded, document-based tasks see hallucination rates near 1 to 2.5 percent, but closed-book factual recall, the category most brand questions fall into, can run anywhere from 15 to 40 percent depending on the model and platform.

    Q: Can I ask OpenAI or Google to correct a specific false fact about my brand? 

    A: Not directly. None of the major AI providers offer a correction portal for a specific claim. Feedback buttons like thumbs-down can flag an issue, but the more reliable fix is correcting and re-indexing the source the model is pulling from.

    Q: How long does it take for a correction to show up in AI answers? 

    A: Meaningful corrections typically take two to six months, since it involves updating multiple sources, waiting for AI systems to recrawl or retrain on the new data, and confirming the fix actually held rather than assuming it did.

    Q: What’s the difference between AI hallucination and normal brand misinformation? 

    A: Misinformation usually traces back to a real, findable source that’s simply wrong or outdated. A true hallucination is the model generating a detail, like a feature or partnership, that has no source behind it at all.

    Read More

  • llms.txt Is Only One Layer. Here’s the Full AI Crawler Permission Stack.

    llms.txt Is Only One Layer. Here’s the Full AI Crawler Permission Stack.

    A content team ships an llms.txt file, checks the box, and moves on. Three months later, ChatGPT still can’t accurately summarize the product page, and server logs show zero requests to the file they spent an afternoon writing.

    That’s not a bug. It’s the current state of llms.txt in practice.

    What llms.txt Actually Controls, and What It Doesn’t

    llms.txt is a Markdown file at the root of a domain that gives AI systems a curated map of a site’s most useful content. It’s a navigation aid, not a gate.

    The data on how AI systems actually treat it is blunt. A study across 300,000 domains found adoption sitting around 10%, and among the fifty most AI-cited domains, only one had the file at all. Monitoring across a 90-day window turned up only a handful of hundred requests to /llms.txt out of over 500 million AI bot events, with GPTBot, ClaudeBot, PerplexityBot, OAI-SearchBot, and Google-Extended overwhelmingly crawling HTML pages directly instead.

    Google has been explicit about where it stands. Google’s Gary Illyes confirmed the company doesn’t support llms.txt and has no plans to, and John Mueller compared it to the discredited keywords meta tag. Separate testing found that eight out of nine sites saw no measurable traffic change after adding the file, and Mueller noted server logs show AI crawlers don’t even check for it.

    None of that means llms.txt is worthless. It costs almost nothing to publish and gives agentic tools a cleaner entry point if adoption grows. But it does mean llms.txt sits in a specific, narrow slot: a declaration of what a site would like AI systems to prioritize, with zero enforcement power behind it.

    The Five-Layer Permission Stack Behind Every AI Crawler Visit

    llms.txt is one layer in a stack that runs from soft declarations to hard technical enforcement. Understanding the full stack matters more than optimizing any single file.

    Layer 1: robots.txt. Standardized as RFC 9309, robots.txt tells crawlers what they’re asked not to fetch. It carries no legal force and doesn’t authenticate anything. Compliance depends entirely on whether a given bot chooses to honor it, and well-behaved crawlers generally do while others historically haven’t.

    Layer 2: llms.txt. As covered above, this is a content curation layer, not a permission layer. It suggests what to read first. It restricts nothing.

    Layer 3: CDN and WAF enforcement. This is where declarations turn into actual blocking. Cloudflare’s shift illustrates the pace of change here. In September 2026, Cloudflare will start blocking “mixed-use” crawlers, ones that blend search, agent, and training traffic, by default on any page carrying ads, unless the site owner overrides it. That follows a year of escalating economics: Cloudflare’s own data showed Anthropic’s crawler fetching roughly 38,000 pages for every referral visit it sent back, and OpenAI’s ratio landing around 1,091 crawls per referral. By June 2026, training-related crawlers made up 50.6% of all bot traffic on Cloudflare’s network, with search-related bots down to just 10.7%.

    Layer 4: Bot identity verification. Declaring rules is one thing. Knowing who’s actually knocking is another. Server logs and User-Agent verification catch crawlers that spoof legitimate identities or ignore declared rules entirely, and they’re the only way to confirm whether Layer 1 and Layer 2 are having any real effect.

    Layer 5: Licensing and legal terms. Terms of service, TDM opt-out clauses, and active litigation now form the outer boundary. Courts have kept public, logged-out scraping legal in cases like hiQ and Meta v. Bright Data, while training-specific disputes like Reddit v. Perplexity are actively testing where those lines sit. This is the layer where “allowed” gets defined in ways no text file can settle on its own.

    Declaring intent isn’t the same as enforcing it.

    Where Most Teams Get the Stack Wrong

    The most common mistake is treating Layer 2 as if it were Layer 3. A team writes a careful llms.txt, feels covered, and never checks whether their CDN is already blocking the same crawlers by default.

    That gap is widening fast. Analysis across Cloudflare’s network found GPTBot is now the most blocked AI crawler by robots.txt directive, and close to 90% of all AI crawler traffic serves training or mixed purposes rather than pure search. Separately, roughly 2.5 million sites now disallow AI training outright, and GPTBot alone is blocked by an estimated 19% of sites.

    Layer conflicts are common and mostly unresolved. If a CDN already blocks GPTBot at the network edge, an llms.txt file that welcomes it does nothing. The technical layer wins by default because it executes; the declaration layer only requests.

    There’s also a data-quality problem inside Layer 2 itself. One estimate put the share of llms.txt files that amount to little more than generic plugin stubs at nearly 40%, which suggests a lot of teams are checking a box rather than building something a machine-reading system could actually use.

    Getting the Permission Layer Right Doesn’t Guarantee AI Visibility

    Here’s the part that trips up even careful teams. Every layer in this stack governs access. None of them govern outcome.

    A site can configure robots.txt correctly, publish a genuinely useful llms.txt, keep its CDN rules aligned, and verify bot identities in its logs, and still never get mentioned when someone asks an AI assistant for a recommendation in its category. Permission is the entry ticket. It says nothing about whether the AI system finds the content worth citing once it’s inside.

    What actually drives citation is a separate set of factors: content structure, topical authority, and how often a brand’s name shows up across the sources an AI model actually pulls from when it forms an answer. That’s a visibility problem, not a permissions problem, and it needs its own monitoring layer.

    This is where Topify fits into the stack, not as a sixth permission layer, but as the measurement layer sitting on top of it. Once the technical access questions are settled, the open question becomes whether ChatGPT, Perplexity, or Google AI Overviews are actually citing the site, how often, and against which competitors. Topify’s Source Analysis tracks the exact domains and URLs AI platforms cite, which is the only reliable way to tell whether a permission configuration is translating into real mentions rather than just theoretical access.

    How to Audit Your Own Permission Stack in Practice

    A working audit runs through all five layers, in order, rather than stopping at whichever one is easiest to configure.

    Start with robots.txt. Confirm it explicitly addresses the AI user-agents that matter for the goal, whether that’s allowing search-oriented bots like OAI-SearchBot and PerplexityBot for citation eligibility, or blocking training-oriented bots like GPTBot and Google-Extended to keep content out of model training.

    Check llms.txt only after that, and only if there’s a genuine use case for agent-driven navigation. Skip generating a full Markdown mirror of every page. Indexable duplicate mirrors dilute crawl budget and can actively suppress the original pages in search results.

    Verify the CDN and WAF layer independently of what robots.txt claims. A rule declared in one place can be silently overridden or duplicated at the network edge, and the only way to know is to check both configurations side by side.

    Pull server logs and filter by known AI crawler user-agents to see what’s actually happening, not what the configuration implies should be happening. A honeypot link inside llms.txt that only an automated reader would follow is a simple way to confirm whether anything is reading the file at all.

    Finally, track outcomes, not just access. Set up ongoing monitoring for whether the brand shows up in AI answers, which sources get cited instead, and how that shifts as the permission layers change. This is the step most audits skip, and it’s the one that actually connects configuration work to business results.

    Conclusion

    llms.txt is real, cheap to publish, and worth having if a site already has its content fundamentals in order. What it isn’t is a permission system. It sits at the declaration end of a five-layer stack that runs through robots.txt, CDN and WAF enforcement, bot identity verification, and licensing terms, with real access control concentrated in the middle three layers, not the file getting most of the attention.

    Getting that stack configured correctly answers one question: can AI systems reach the content at all. It doesn’t answer the more important one: once they can, do they actually recommend the brand. That second question needs its own audit trail, separate from anything a text file at the root of a domain can provide.

    FAQ

    What is llms.txt used for? 

    It’s a Markdown file that gives AI systems a curated list of a site’s most relevant content, meant to help agentic tools navigate faster. It doesn’t restrict access or function as a security control.

    Is llms.txt the same as robots.txt? 

    No. robots.txt tells crawlers what they may not access and is broadly, though not universally, respected. llms.txt does the opposite: it suggests what to read first and carries no restrictive power at all.

    Does Google support llms.txt? 

    No. Google has stated on record that it doesn’t support the format and has no plans to, comparing it to the deprecated keywords meta tag.

    How do I check if AI crawlers are reading my llms.txt file? 

    Filter server access logs for requests to /llms.txt by known AI user-agents, or embed a unique link inside the file that only an automated reader would follow and monitor for traffic to that link.

    Read More

  • Should You Ship llms.txt? A Verdict by Site Type

    Should You Ship llms.txt? A Verdict by Site Type

    Two SaaS companies launched llms.txt the same month last year. One saw its AI Mode citations shift within days. The other checked its server logs three months later and found exactly zero requests for the file. Same standard, same effort, wildly different outcomes.

    That gap is the real story behind llms.txt, and it’s why the “should you ship it” debate keeps going in circles. The people saying yes and the people saying no are usually talking about different kinds of websites.

    What llms.txt Actually Promises to Do

    llms.txt is a plain-text Markdown file you place at your site’s root, something like example.com/llms.txt. It gives large language models a curated map of your content instead of forcing them to parse a full HTML page just to find your value proposition.

    It’s not a replacement for robots.txt. Robots.txt controls access. llms.txt is closer to a briefing document, one that tells an agent what your site is, who it’s for, and which pages matter most.

    That distinction matters because the two files serve completely different jobs, and confusing them is where a lot of the hype started. Search engines like Google use robots.txt to decide what to crawl at all. llms.txt only helps once something is already reading your site, which is a much narrower promise than most marketing posts about it suggest.

    The Real Question Isn’t “Should I?” It’s “Does My Site Even Need Guiding?”

    Most of the debate skips a more basic question: does an AI system actually struggle to understand your site without help?

    A ten-page marketing site with a clear homepage doesn’t need a curated map. An agent can read the whole thing in seconds. A 400-page documentation set with nested API references and versioned guides is a different story. That’s a genuine navigation problem, and it’s exactly the kind of problem llms.txt was built to solve.

    That’s the filter worth applying before anything else: content volume, structural complexity, and whether AI agents are already interacting with your site in a way that depends on navigation, not just crawling.

    Here’s the part most guides bury: llms.txt fixes a discovery problem, not a content quality problem. If your product pages are thin or your docs are outdated, a tidy index just helps an agent find the weak content faster.

    The Verdict, by Site Type

    Site TypeVerdictWhy
    Documentation & developer platformsShip itCoding agents like Cursor, GitHub Copilot, and Claude Code actively fetch llms.txt from docs sites during real sessions
    SaaS with heavy technical docsShip itSame agent-routing benefit as pure docs sites, plus it’s cheap to maintain alongside existing documentation workflows
    Small marketing sites and blogs (under 1,000 pages)Skip or deferThe homepage and nav already summarize the site well enough that a curated map adds little
    Large ecommerce (10,000+ pages)SkipMaintenance cost of keeping the file accurate outpaces the upside; product data and structured markup do more of the real work
    Small ecommerce (under 1,000 pages)Optional experimentCheap enough to test, but treat it as a minor bet, not a strategy
    News and publisher sitesSkip for nowNo major consumer AI search engine, including ChatGPT search, Perplexity, or Google AI Overviews, has confirmed it reads llms.txt for answering user queries

    Documentation sites are the one category where the evidence is unambiguous. Anthropic, Stripe, Vercel, Cloudflare, and Supabase all ship llms.txt on their developer docs, largely because Mintlify’s late-2024 rollout across hosted docs sites put thousands of platforms on the standard overnight. Coding agents fetch these files as a matter of routine, not as a hopeful bet on future adoption.

    Everyone else is placing a smaller, cheaper bet on a standard that hasn’t been confirmed by the platforms that matter most for organic visibility.

    Where Most Teams Get llms.txt Wrong

    The biggest mistake is treating llms.txt as an AI visibility strategy instead of a small technical convenience. It isn’t a ranking signal, and Google has said so directly.

    Google’s own search advocates have been unusually blunt about this. Gary Illyes confirmed Google doesn’t support llms.txt and has no plans to, and John Mueller went further, saying flat out that “for non-developer sites, I don’t think this makes much sense.” That’s the same Google whose Chrome Lighthouse tool has started auditing for llms.txt presence, which tells you the confusion isn’t just coming from marketers.

    The numbers back up the skepticism. A study of 300,000 domains found llms.txt adoption sitting at 10.13% after roughly eighteen months of industry conversation, and a separate June 2026 sample of the top 1,000 sites put confirmed adoption at 8.7%. Adoption isn’t accelerating the way early advocates predicted.

    Crawler behavior tells the sharper story. An analysis of 137,000 domains found that 97% of llms.txt files received zero crawler hits at all, and of the hits that did land, only 1% came from AI-related bots. A separate 90-day monitoring window across 500 million AI bot visits found roughly 408 requests actually targeting llms.txt files, close to 0.1% of total AI bot traffic.

    That’s a single-sentence gut check worth sitting with: the file most teams built for AI crawlers isn’t the thing AI crawlers are reading.

    A 90-day before-and-after study across ten sites in finance, B2B SaaS, ecommerce, insurance, and pet care found eight of the ten saw no measurable change in AI traffic after implementation, and one site actually declined by 19.7%. The two sites that did see gains had unrelated changes running in parallel, like PR campaigns and restructured comparison pages, so llms.txt wasn’t the cause.

    None of this means the file is worthless everywhere. It means the sites seeing zero return are usually the ones that never needed it in the first place.

    How to Know If It’s Actually Working

    Here’s the honest gap in almost every llms.txt guide: they tell you how to build the file, then stop. Nobody tells you how to check whether it changed anything.

    The right question after shipping llms.txt isn’t “is it live.” It’s whether AI platforms are actually citing your domain more often, and whether the specific pages you flagged as priority are the ones showing up in AI answers. That’s a citation-tracking problem, not a file-formatting problem.

    This is exactly where Topify‘s Source Analysis comes in. It tracks the exact domains and URLs that AI platforms cite across ChatGPT, Perplexity, Gemini, and Google AI Overviews, which means you can see whether your llms.txt-linked pages are actually showing up as sources or whether the file is just sitting unread at your root. Pair that with AI Volume Analytics to check whether the topics your llms.txt prioritizes are even the ones generating meaningful AI search demand in the first place.

    For ecommerce brands weighing the maintenance cost, that visibility matters even more. Shopify reported AI-driven traffic to its stores grew 8x year over year, with AI-powered search orders up nearly 13x. That’s real upside, but it’s upside you can only capture if you’re measuring whether your AI visibility work, llms.txt included, is actually moving the needle instead of guessing.

    Conclusion

    There’s no universal answer to whether you should ship llms.txt, and anyone giving you one is skipping the part where site type changes everything. Documentation-heavy and developer-facing sites have a real, demonstrated case: coding agents use these files today, not hypothetically. Everyone else is looking at a low-cost, low-evidence bet that Google’s own search team has publicly called into question.

    Before you spend an afternoon on it, run through three checks: does your site have enough structural complexity that an agent would actually benefit from a map, is agent traffic a real part of your growth plan, and do you have the bandwidth to keep the file accurate as your site changes. If two of those three are no, your time is better spent on content structure and citation tracking than on a file most crawlers still aren’t reading.

    FAQ

    Q: What is an llms.txt file, exactly?
    A: It’s a plain-text Markdown file placed at a site’s root, typically at /llms.txt, that gives AI systems a curated index of the site’s most important pages instead of asking them to parse full HTML.

    Q: Is llms.txt the same as robots.txt?
    A: No. Robots.txt tells crawlers what they’re allowed to access at all. llms.txt only helps an AI agent navigate content it can already reach, which makes it a convenience layer, not an access control.

    Q: Does llms.txt actually work for AI search visibility?
    A: For consumer AI search like ChatGPT search, Perplexity, or Google AI Overviews, the evidence so far shows little to no measurable effect. For AI coding agents reading documentation sites, it demonstrably works, since tools like Cursor and Claude Code fetch these files during real coding sessions.

    Q: Do I need llms.txt for my blog or small marketing site?
    A: Usually not as a priority. If your homepage and navigation already summarize the site clearly, a curated map adds little. That time is typically better spent on content structure and technical SEO fixes.

    Read More